# Port Documentation
> Port is the platform for building your AI software factory: one governed layer where humans and AI agents build, govern, and operate the agentic SDLC. API base URLs: EU https://api.port.io, US https://api.us.port.io.
- [Port Documentation](/index.md)
## Getting started
### overview
Set up your Port account, connect your first integration, and build a working software catalog in a few guided onboarding steps.
- [Getting started](/getting-started/overview.md): Set up your Port account, connect your first integration, and build a working software catalog in a few guided onboarding steps.
### agentic-sdlc-pillars
An overview of the six pillars that make up a software factory in Port - context lake, workflows, Port AI, agent management, interface builder, and governance.
- [The pillars of your software factory](/getting-started/agentic-sdlc-pillars.md): An overview of the six pillars that make up a software factory in Port - context lake, workflows, Port AI, agent management, interface builder, and governance.
### build-more-workflows
Explore more workflow examples and keep building on top of your context lake.
- [Build more workflows](/getting-started/build-more-workflows.md): Explore more workflow examples and keep building on top of your context lake.
### build-your-first-workflow
Build your first AI-powered workflow in minutes, using any use-case Port AI suggests for your context lake.
- [Build your first workflow](/getting-started/build-your-first-workflow.md): Build your first AI-powered workflow in minutes, using any use-case Port AI suggests for your context lake.
### connect-your-git
Connect your Git provider so Port can start populating your context lake with repositories and pull requests.
- [Set up your Git provider](/getting-started/connect-your-git.md): Connect your Git provider so Port can start populating your context lake with repositories and pull requests.
### craft-an-initial-prompt
Choose a use-case, craft an initial prompt, and let Port AI build the initial structure of your platform.
- [Craft a prompt](/getting-started/craft-an-initial-prompt.md): Choose a use-case, craft an initial prompt, and let Port AI build the initial structure of your platform.
### docs-ai-assistant
Use Port's AI assistant to ask documentation questions, generate resource definitions, debug JSON/YAML, and get help with blueprints and actions.
- [Docs AI assistant](/getting-started/docs-ai-assistant.md): Use Port's AI assistant to ask documentation questions, generate resource definitions, debug JSON/YAML, and get help with blueprints and actions.
### invite-users
Invite colleagues to your Port platform to collaborate on workflows and catalog management.
- [Invite your team](/getting-started/invite-users.md): Invite colleagues to your Port platform to collaborate on workflows and catalog management.
### set-up-your-context-lake
Connect additional tools and populate your context lake with services, users, and ownership data.
- [Set up your context lake](/getting-started/set-up-your-context-lake.md): Connect additional tools and populate your context lake with services, users, and ownership data.
### view-dashboards
Explore the dashboard Port auto-created for your use-case, now populated with real data from your tools.
- [View your dashboards](/getting-started/view-dashboards.md): Explore the dashboard Port auto-created for your use-case, now populated with real data from your tools.
## context-lake
### business-context
#### organization-hierarchy
Model your organization hierarchy with team blueprints. Create views showing groups, teams, and services at each tier level.
- [Visualize organization hierarchy](/context-lake/business-context/organization-hierarchy.md): Model your organization hierarchy with team blueprints. Create views showing groups, teams, and services at each tier level.
#### overview
Add business context to your Port catalog so agents and workflows can prioritize by cost, criticality, ownership, SLAs, and risk.
- [Business context](/context-lake/business-context/overview.md): Add business context to your Port catalog so agents and workflows can prioritize by cost, criticality, ownership, SLAs, and risk.
#### ownership
Assign users and teams as owners of catalog entities. Sync ownership from integrations, configure the ownership property and $team meta-property, and visualize who owns what in your portal.
- [Manage ownership in Port](/context-lake/business-context/ownership.md): Assign users and teams as owners of catalog entities. Sync ownership from integrations, configure the ownership property and $team meta-property, and visualize who owns what in your portal.
### consuming-the-lake
#### govern-data-access
##### examples
Examples of catalog RBAC configurations including making entities immutable, property-level permissions, and team ownership-based access control.
- [Examples](/context-lake/consuming-the-lake/govern-data-access/examples.md): Examples of catalog RBAC configurations including making entities immutable, property-level permissions, and team ownership-based access control.
##### overview
Set Port catalog RBAC so you control who reads, creates, updates, or deletes entities and properties by role, team, or policy.
- [Govern data access](/context-lake/consuming-the-lake/govern-data-access/overview.md): Set Port catalog RBAC so you control who reads, creates, updates, or deletes entities and properties by role, team, or policy.
#### other-consumption-methods
##### overview
Use the Port n8n node and related methods so external automation can query your Context Lake without direct access to every tool.
- [Other consumption methods](/context-lake/consuming-the-lake/other-consumption-methods/overview.md): Use the Port n8n node and related methods so external automation can query your Context Lake without direct access to every tool.
##### port-n8n-node
Install and configure Port's custom n8n node to integrate Port AI agents and API into your n8n automation workflows.
- [Port n8n node](/context-lake/consuming-the-lake/other-consumption-methods/port-n8n-node.md): Install and configure Port's custom n8n node to integrate Port AI agents and API into your n8n automation workflows.
#### overview
See how you consume Port's Context Lake: query entities, use Port MCP, apply catalog RBAC, and trigger external automation.
- [Consumption methods](/context-lake/consuming-the-lake/overview.md): See how you consume Port's Context Lake: query entities, use Port MCP, apply catalog RBAC, and trigger external automation.
#### port-mcp-server
The Port MCP server does not use Port AI capabilities. You can install and use it without enabling Port AI features or accepting the Port AI Terms.
- [Port MCP server](/context-lake/consuming-the-lake/port-mcp-server.md): The Port MCP server does not use Port AI capabilities. You can install and use it without enabling Port AI features or accepting the Port AI Terms.
#### search-and-query
##### advanced
Advanced search options including attach_title_to_relation and exclude_calculated_properties query parameters for customizing search results.
- [Advanced](/context-lake/consuming-the-lake/search-and-query/advanced.md): Advanced search options including attach_title_to_relation and exclude_calculated_properties query parameters for customizing search results.
##### examples
Search and query examples for catalog pages, dashboard widgets, automations, and dynamic action permissions with practical JSON rules.
- [Examples](/context-lake/consuming-the-lake/search-and-query/examples.md): Search and query examples for catalog pages, dashboard widgets, automations, and dynamic action permissions with practical JSON rules.
##### operators
- [Comparison operators](/context-lake/consuming-the-lake/search-and-query/operators/comparison-operators.md): Comparison operators for search rules including equals, contains, greater/less than, between, isEmpty, and property existence checks.
- [Relation operators](/context-lake/consuming-the-lake/search-and-query/operators/relation-operators.md): Relation operators for searching entities by relationships including relatedTo, containsAny, and direction/depth controls for traversing relations.
##### overview
Apply Port's search and query syntax to filter entities in pages, dashboards, scorecards, RBAC, actions, and API search endpoints.
- [API access & search](/context-lake/consuming-the-lake/search-and-query/overview.md): Apply Port's search and query syntax to filter entities in pages, dashboards, scorecards, RBAC, actions, and API search endpoints.
##### structure-and-syntax
Search query structure with combinators (and/or), rules, property operators, and meta-properties like $blueprint and $identifier.
- [Structure & syntax](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax.md): Search query structure with combinators (and/or), rules, property operators, and meta-properties like $blueprint and $identifier.
### data-model
#### configure-data-model
Learn how Port's data model uses blueprints, properties, and relations so you can define and manage your catalog schema.
- [Data model](/context-lake/data-model/configure-data-model.md): Learn how Port's data model uses blueprints, properties, and relations so you can define and manage your catalog schema.
#### define-your-ontology
Learn how blueprint descriptions, relation titles, property types, and enum values turn a schema into a semantic knowledge graph that AI agents can reason over and act on.
- [Define your ontology](/context-lake/data-model/define-your-ontology.md): Learn how blueprint descriptions, relation titles, property types, and enum values turn a schema into a semantic knowledge graph that AI agents can reason over and act on.
#### iac
##### pulumi-managed-blueprint
Comprehensive blueprint with properties, relations and mirror properties
- [Pulumi-Managed Blueprint Example](/context-lake/data-model/iac/pulumi-managed-blueprint.md): Comprehensive blueprint with properties, relations and mirror properties
##### terraform-managed-blueprint
Comprehensive blueprint with properties, relations and mirror properties
- [Terraform-Managed Blueprint Example](/context-lake/data-model/iac/terraform-managed-blueprint.md): Comprehensive blueprint with properties, relations and mirror properties
#### setup-blueprint
##### default-blueprints
Reference for default Port blueprints including service, workload, environment, user, and team. Describes each blueprint's purpose and properties.
- [Default blueprints](/context-lake/data-model/setup-blueprint/default-blueprints.md): Reference for default Port blueprints including service, workload, environment, user, and team. Describes each blueprint's purpose and properties.
##### overview
Create Port blueprints to model your assets, then add properties and relations using Port AI, the UI, API, Terraform, or Pulumi.
- [Set up blueprints](/context-lake/data-model/setup-blueprint/overview.md): Create Port blueprints to model your assets, then add properties and relations using Port AI, the UI, API, Terraform, or Pulumi.
##### properties
- [Aggregation property](/context-lake/data-model/setup-blueprint/properties/aggregation-property.md): Learn how to use aggregation properties to calculate metrics based on relations in your catalog, such as counting entities or averaging values.
- [Array](/context-lake/data-model/setup-blueprint/properties/array.md): Array is a data type used to save lists of data
- [Boolean](/context-lake/data-model/setup-blueprint/properties/boolean.md): Boolean is a primitive data type that has one of two possible values - true and false
- [Calculation property](/context-lake/data-model/setup-blueprint/properties/calculation-property.md): Calculation property allows you to construct new data from existing properties of an entity
- [Examples](/context-lake/data-model/setup-blueprint/properties/calculation-property/examples.md): Examples of calculation properties including math operations, string concatenation, conditional logic, and date formatting in Port blueprints.
- [Datetime](/context-lake/data-model/setup-blueprint/properties/datetime.md): Datetime is a data type used to reference a date and time
- [Email](/context-lake/data-model/setup-blueprint/properties/email.md): Email is a data type used to save Email addresses
- [Embedded URL](/context-lake/data-model/setup-blueprint/properties/embedded-url.md): Learn how to use embedded URL properties to display external webpages like dashboards, diagrams, and architecture views within entity pages.
- [Authentication](/context-lake/data-model/setup-blueprint/properties/embedded-url/authentication.md): Learn how to configure SSO authentication for embedded URL properties to display protected webpages within Port entity pages.
- [Enum](/context-lake/data-model/setup-blueprint/properties/enum.md): Enum is a data type used to define a named set of constant values.
- [Labeled URL](/context-lake/data-model/setup-blueprint/properties/labeled-url-object.md): Labeled URL is an object type used to store URLs with custom display labels
- [Markdown](/context-lake/data-model/setup-blueprint/properties/markdown.md): Learn how to use the Markdown property type to display formatted Markdown content within entity pages in Port.
- [Meta-Properties](/context-lake/data-model/setup-blueprint/properties/meta-properties.md): Reference for meta-properties that exist on every entity by default, including identifier, title, team, timestamps, and created/updated by fields.
- [Mirror property](/context-lake/data-model/setup-blueprint/properties/mirror-property.md): Mirror Property allows you to map data from related entities to your entity
- [Number](/context-lake/data-model/setup-blueprint/properties/number.md): Number is a primitive data type used to save numeric data
- [JSON](/context-lake/data-model/setup-blueprint/properties/object.md): JSON is a data type used to save structured data as key-value pairs.
- [Properties](/context-lake/data-model/setup-blueprint/properties/overview.md): Configure Port blueprint properties from the Data model page or catalog so you can create, edit, and hide the fields your entities store.
- [Owning teams](/context-lake/data-model/setup-blueprint/properties/owning-teams.md): Owning Teams defines which team owns a blueprint's entities. It can be added once per blueprint, creates a relation to the Team blueprint, and sets the blueprint's ownership.
- [Protobuf](/context-lake/data-model/setup-blueprint/properties/proto.md): Protobuf is a data type used to save Protocol Buffers definitions.
- [String](/context-lake/data-model/setup-blueprint/properties/string.md): Configure string properties on Port blueprints, including enum values, formats, and validation rules. String is a primitive data type used to save text data.
- [Swagger UI](/context-lake/data-model/setup-blueprint/properties/swagger.md): Learn how to use the Swagger UI property to display OpenAPI and AsyncAPI specification files within entity pages in Port.
- [Team](/context-lake/data-model/setup-blueprint/properties/team.md): Team is a data type used to reference teams that exist in Port
- [Timer](/context-lake/data-model/setup-blueprint/properties/timer.md): Timer is a data type used to define an expiration date/lifespan of a specific entity
- [URL](/context-lake/data-model/setup-blueprint/properties/url.md): URL is a data type used to save links to websites
- [User](/context-lake/data-model/setup-blueprint/properties/user.md): User is a data type used to reference users that exist in Port
- [YAML](/context-lake/data-model/setup-blueprint/properties/yaml.md): YAML is a data type used to save object definitions in YAML.
##### relate-blueprints
Learn how to create relations between blueprints to define logical connections between assets in your software catalog.
- [Relate Blueprints](/context-lake/data-model/setup-blueprint/relate-blueprints.md): Learn how to create relations between blueprints to define logical connections between assets in your software catalog.
### extend-the-context-lake
You can extend the Context Lake beyond native integrations by connecting external MCP servers and publishing skills.
- [Extend the context lake](/context-lake/extend-the-context-lake.md): You can extend the Context Lake beyond native integrations by connecting external MCP servers and publishing skills.
### ingestion
#### catalog-auto-discovery
Learn how to use AI-powered auto discovery to identify and create missing entities in your catalog based on related data from multiple sources.
- [Auto discovery](/context-lake/ingestion/catalog-auto-discovery.md): Learn how to use AI-powered auto discovery to identify and create missing entities in your catalog based on related data from multiple sources.
#### configure-mapping
##### common-jq-use-cases
Common JQ patterns for integration mappings, self-service action backends, and filters.
- [Common jq use-cases](/context-lake/ingestion/configure-mapping/common-jq-use-cases.md): Common JQ patterns for integration mappings, self-service action backends, and filters.
##### configuration-methods
Configure an integration's mapping using either the visual form editor or the code-based YAML editor.
- [Configuration methods](/context-lake/ingestion/configure-mapping/configuration-methods.md): Configure an integration's mapping using either the visual form editor or the code-based YAML editor.
##### entity-cleanup
When you remove a resource type from your integration mapping or decommission an integration, the associated entities in Port are not automatically deleted. This documentation explains how to properly clean up stale entities to keep your software catalog accurate and up to date.
- [Clean up stale entities](/context-lake/ingestion/configure-mapping/entity-cleanup.md): When you remove a resource type from your integration mapping or decommission an integration, the associated entities in Port are not automatically deleted. This documentation explains how to properly clean up stale entities to keep your software catalog accurate and up to date.
##### overview
Edit Port integration mapping with JQ to select source data, map properties and relations, and tune sync in YAML or forms.
- [Configure mapping](/context-lake/ingestion/configure-mapping/overview.md): Edit Port integration mapping with JQ to select source data, map properties and relations, and tune sync in YAML or forms.
#### ingest-data-into-port
##### api
- [Advanced](/context-lake/ingestion/ingest-data-into-port/api/advanced.md): Advanced API query parameters including delete_dependents for cascading deletes and create_missing_related_entities for automatic entity creation.
- [CI/CD](/context-lake/ingestion/ingest-data-into-port/api/ci-cd.md): Overview of CI/CD integrations for keeping your software catalog up to date with build versions, job statuses, and other CI/CD data.
- [Azure Pipelines](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/azure-pipelines.md): Learn how to create, update, and query Port entities directly from Azure Pipelines using Port's API.
- [Examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/azure-pipelines/examples.md): Examples of creating and updating Port entities from Azure Pipelines, including CI job tracking and Docker image reporting.
- [CircleCI workflows](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/circleci-workflow.md): Learn how to create, update, and query Port entities directly from CircleCI workflows using Port's API.
- [Examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/circleci-workflow/examples.md): Examples of creating and updating Port entities from CircleCI workflows, including CI job tracking and Docker image reporting.
- [Codefresh Workflow Template](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/codefresh-workflow-template.md): Learn how to use Port's Codefresh workflow template to create, update, and query entities directly from Codefresh pipelines.
- [Examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/codefresh-workflow-template/examples.md): Basic create/update example
- [GitHub Workflow](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/github-workflow.md): Learn how to use Port's GitHub action to create, update, and query entities directly from GitHub workflows.
- [Examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/github-workflow/examples.md): Examples of using Port's GitHub action to create entities, import dependencies, and report CI job status from GitHub workflows.
- [Gitlab CI Pipelines](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/gitlab-pipelines.md): Learn how to create, update, and query Port entities directly from GitLab CI pipeline jobs using Port's API.
- [Examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/gitlab-pipelines/examples.md): Examples of creating and updating Port entities from GitLab CI pipelines, including CI job tracking and Docker image reporting.
- [Jenkins Deployment](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/jenkins-deployment.md): Learn how to create, update, and query Port entities directly from Jenkins pipelines using Port's API.
- [Examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/jenkins-deployment/examples.md): Examples of creating and updating Port entities from Jenkins pipelines, including CI job tracking and Docker image reporting.
- [Ingest via API](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview.md): Authenticate with Port's REST API to ingest entities and update your catalog from scripts, CI pipelines, or custom systems.
##### custom-integration
- [Implement an API client](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/api-client.md): Build an async third-party API client for a custom-coded Ocean integration using Ocean's HTTP client.
- [Define configuration files](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/configuration-files.md): Configure .port/spec.yaml, default blueprints, and default mapping for a custom-coded Ocean integration.
- [Configuration validation](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/configuration-validation.md): How Ocean validates integration configuration from .port/spec.yaml at startup.
- [Ocean and event contexts](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/contexts.md): Use the ocean and event context objects when implementing a custom-coded Ocean integration.
- [Deploy a custom-coded Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/deploy.md): Build and deploy a custom-coded Ocean integration image with Docker or Helm.
- [Development guidelines](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/guidelines.md): Practices for custom-coded Ocean integrations - async HTTP, raw data shape, logging, and performance.
- [Implement incremental sync](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/incremental-sync.md): Add @ocean.on_incremental_resync handlers that fetch only changes since the last incremental cursor.
- [Kinds and selectors](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/kinds-and-selectors.md): Add custom mapping selector fields for Ocean kinds using integration.py.
- [Implement live events](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/live-events.md): Implement AbstractWebhookProcessor classes that return raw updated or deleted objects for live events.
- [Write your own Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/overview.md): Build flow for a custom-coded Ocean integration, from configuration files through resyncs, incremental sync, live events, testing, and deploy.
- [Handle resyncs](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/resyncs.md): Implement @ocean.on_resync handlers that yield batches of raw third-party data.
- [Test and run locally](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/testing.md): Map spec.yaml to environment variables, run a custom-coded Ocean integration locally, and trigger a resync.
- [Getting started](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/getting-started.md): Install the Ocean CLI, scaffold a custom-coded Ocean integration, and run it locally.
- [Custom-coded Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/overview.md): Build a custom-coded Python Ocean integration when the no-code option is not enough, and let Port apply your mapping to the raw data you extract.
- [Configuration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/configuration.md): Prerequisites, resource mapping, and advanced configuration for the no-code Ocean custom integration
- [Hosted by Port](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port.md): Install the no-code Ocean custom integration hosted by Port
- [Build your integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/build-your-integration.md): Interactive guide to configure and install your integration
- [Custom authentication](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/custom-authentication.md): Configure OAuth2, JWT, and other dynamic token-based authentication flows
- [Setup](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup.md): Install the no-code Ocean custom integration in your own infrastructure
- [No-code Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview.md): Connect any REST API to Port with the no-code Ocean custom integration so you can map endpoints to blueprints and ingest with config only.
- [Create a custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/overview.md): Build a custom Port integration when no native option exists. Define blueprints, then ingest via Ocean, webhooks, the API, or IaC.
##### native-integrations
- [Available integrations](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations.md): Browse all available Port native integrations. Each card links to the integration's documentation.
- [Claude AI metrics](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/claude.md): Ingest Claude AI (Enterprise) and Claude Platform usage, analytics, and skill adoption into Port to track AI tool adoption across your organization.
- [Cursor metrics](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/cursor.md): Learn how to ingest Cursor team, model, and skill usage into Port to track AI adoption and cost patterns across your engineering organization using the no-code Ocean custom integration framework.
- [GitHub Copilot metrics](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/github-copilot.md): Ingest GitHub Copilot usage and metrics into Port to track AI coding tool adoption across your engineering organization.
- [OpenAI metrics](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/openai.md): Learn how to ingest OpenAI usage metrics, costs, and model information into Port using the no-code Ocean custom integration framework.
- [APM & alerting](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting.md): Overview of APM and alerting integrations for syncing monitoring data from tools like Datadog, Prometheus, and Azure Monitor to Port.
- [Azure Monitor](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/azure-monitor.md): Learn how to ingest Azure Monitor alerts, activity logs, and metrics into Port using the no-code Ocean custom integration framework.
- [Datadog](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog.md): Sync Datadog monitors, services, SLOs, and host data into Port's software catalog, and use it across scorecards, dashboards, and automations.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog/examples.md): Mapping examples for Datadog resources including monitors, services, SLOs, and dashboards using the Datadog integration.
- [Dynatrace](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/dynatrace.md): Sync Dynatrace monitoring data, problems, and services into Port's software catalog.
- [New Relic](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/newrelic.md): Sync New Relic monitoring data, alerts, and services into Port's software catalog.
- [Prometheus](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/prometheus.md): Learn how to ingest Prometheus alerts, rules, and scrape targets into Port using the no-code Ocean custom integration framework.
- [Sentry](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/sentry.md): Sync Sentry projects, issues, and error tracking data into Port's software catalog.
- [Argo CD](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/argocd.md): Sync Argo CD applications, deployments, and clusters into Port's software catalog.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/argocd/example.md): Mapping examples for ArgoCD resources including clusters, projects, applications, and deployment history.
- [n8n](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/automation-platforms/n8n.md): Learn how to ingest n8n users, projects, and workflows into Port using the no-code Ocean custom integration framework.
- [Zapier](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/automation-platforms/zapier.md): Learn how to ingest Zapier apps and zaps into Port using the no-code Ocean custom integration framework.
- [Jenkins](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/jenkins.md): Sync Jenkins jobs, builds, and pipelines into Port's software catalog.
- [Octopus Deploy Integration](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/octopus-deploy.md): Sync Octopus Deploy projects, releases, and deployments into Port's software catalog.
- [Ingest additional resources](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/octopus-deploy/mapping-extra-resources.md): Learn how to map additional Octopus Deploy resources like runbooks, tasks, teams, environments, and workers into Port.
- [Cloud cost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost.md): Overview of cloud cost integrations for syncing cost and usage data from tools like Kubecost and OpenCost to Port.
- [Kubecost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost.md): Sync Kubecost cost allocation and Kubernetes spend data into Port's software catalog.
- [Advanced configuration for Kubecost objects](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost/advanced.md): Advanced configuration options for Kubecost integration including allocation queries, filters, and cloud cost aggregation parameters.
- [OpenCost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/opencost.md): Sync OpenCost Kubernetes cost and resource spend data into Port's software catalog.
- [Cloud providers](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers.md): Overview of cloud provider integrations for syncing AWS, Azure, and GCP resources to your Port software catalog.
- [Installation](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/installation.md): Install the Port AWS integration using Port-hosted or self-hosted deployment. Covers single account and multi-account setups via ECS, EC2, EKS (IRSA), or one-off Docker runs.
- [Live events](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/live-events.md): How AWS live events work, which resource kinds are supported, and troubleshooting.
- [AWS](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/Overview.md): Learn how to sync AWS resources like EC2, S3, Lambda, EKS, and more to Port using the AWS integration with flexible deployment options.
- [AWS resource and property reference](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference.md): Reference guide for AWS resource types, actions, and properties supported by the AWS integration including EC2, S3, ECS, Lambda, and more.
- [Amazon DynamoDB](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-dynamodb.md): Reference for Amazon DynamoDB resources including tables with supported actions, permissions, and mapping configurations.
- [Amazon Elastic Compute Cloud (EC2)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elastic-compute-cloud.md): Reference for Amazon EC2 resources including instances and volumes with supported actions, permissions, and mapping configurations.
- [Amazon Elastic Container Registry (ECR)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elastic-container-registry.md): Reference for Amazon ECR repository resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [Amazon Elastic Container Service (ECS)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elastic-container-service.md): Reference for Amazon ECS resources including clusters, services, and task definitions with supported actions and mapping configurations.
- [Amazon Elastic Kubernetes Service (EKS)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elastic-kubernetes-service.md): Reference for Amazon EKS cluster resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [Amazon ElastiCache](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elasticache.md): Reference for Amazon ElastiCache resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [Amazon Managed Streaming for Apache Kafka (MSK)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-managed-streaming-for-apache-kafka.md): Reference for Amazon MSK cluster resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [Amazon MemoryDB](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-memorydb.md): Reference for Amazon MemoryDB user resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [Amazon Relational Database Service (RDS)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-relational-database-service.md): Reference for Amazon RDS DB instance resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [Amazon Simple Email Service (SES)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-simple-email-service.md): Reference for Amazon SES resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [Amazon Simple Queue Service (SQS)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-simple-queue-service.md): Reference for Amazon SQS resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [Amazon Simple Storage Service (S3)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-simple-storage-service.md): Reference for Amazon S3 bucket resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [AWS Account](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-account.md): Reference for AWS Account information resources for resyncing account data without AWS Organizations permissions.
- [AWS CodeBuild](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-codebuild.md): Reference for AWS CodeBuild resources including projects and build runs with supported actions, permissions, and mapping configurations.
- [AWS CodeDeploy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-codedeploy.md): Reference for AWS CodeDeploy resources including applications, deployment groups, deployments, and deployment targets with supported actions and mapping configurations.
- [AWS CodePipeline](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-codepipeline.md): Reference for AWS CodePipeline resources including pipelines, stages, actions, and executions with supported actions, permissions, and mapping configurations.
- [AWS Lambda](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-lambda.md): Reference for AWS Lambda resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [AWS Organizations](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-organizations.md): Reference for AWS Organizations account resources including supported actions, permissions, and mapping configurations for the AWS integration.
- [AWS Legacy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws.md): Sync AWS resources into Port's software catalog using the AWS Legacy integration.
- [AWS exporter](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter.md): Deprecated AWS exporter documentation - learn about the legacy serverless application for syncing AWS resources to Port.
- [Event-based updates](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/event-based-updates.md): Learn how to configure real-time event-based updates for the deprecated AWS exporter using EventBridge and CloudTrail.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/examples.md): Examples of mapping AWS resources like ECS clusters, S3 buckets, Lambda functions, and more using the deprecated AWS exporter.
- [Connect ECR repository to a service](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/examples/connect-ecr-repo-to-service-using-tags.md): Learn how to connect AWS ECR repositories to existing services in Port using resource tags for the deprecated AWS exporter.
- [Installation](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/installation.md): Installation guide for the deprecated AWS exporter using Terraform or manual SAM deployment methods.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/examples.md): Base mapping examples for AWS resources including accounts and generic cloud resources using the AWS Ocean integration.
- [Mapping extra resources](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/examples/mapping_extra_resources.md): Learn how to map additional AWS resources to Port including ECS, Lambda, SQS, DynamoDB, and other Cloud Control API supported resources.
- [Live events setup](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/live-events.md): Learn how to set up real-time event processing for AWS resources using EventBridge and CloudTrail to keep your Port catalog updated.
- [Multi account support](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/multi_account.md): Learn how to configure the AWS Ocean integration to ingest resources from multiple AWS accounts using cross-account IAM roles.
- [Azure](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure.md): Sync Azure cloud resources into Port's software catalog.
- [Azure Resource Graph (Beta)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure/azure-resource-graph.md): Learn how to sync Azure resources to Port using the Azure Resource Graph integration for high-volume, multi-subscription data ingestion.
- [Resource Templates](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure/resource_templates.md): Base mapping templates for Azure resources including subscriptions, resource groups, and generic cloud resources using the Azure integration.
- [Advanced Templates](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure/resource_templates/advanced.md): Advanced mapping templates for Azure resources including storage accounts, AKS clusters, virtual machines, and Service Bus resources.
- [Mapping Extra Resources](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure/resource_templates/mapping_extra_resources.md): Learn how to map additional Azure resources to Port that are not covered in the standard templates by using the Azure REST API reference.
- [GCP](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/gcp.md): Sync Google Cloud (GCP) resources into Port's software catalog.
- [Cloud Function Sync protocol](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/gcp/cloud-function-sync.md): Sync resources from any HTTP endpoint using the GCP Cloud Function Sync protocol
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/gcp/examples.md): Base mapping examples for GCP resources including projects and generic cloud resources using the GCP integration.
- [Map Extra Resources](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/gcp/examples/mapping_extra_resources.md): Learn how to map additional GCP resources to Port including compute instances, BigQuery datasets, and other Asset Inventory supported resources.
- [Code quality & security](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security.md): Overview of code quality and security integrations for syncing data from tools like SonarQube, Snyk, Wiz, Mend.io, and Checkmarx to Port.
- [Aikido](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/aikido.md): Sync Aikido security findings and vulnerabilities into Port's software catalog.
- [ArmorCode](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/armorcode.md): Sync ArmorCode security findings and ASPM data into Port's software catalog.
- [BrowserStack](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/browserstack.md): Learn how to ingest BrowserStack Automate test data including plans, projects, and builds into Port using the no-code Ocean custom integration.
- [Checkmarx One](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/checkmarx.md): Sync Checkmarx One scan results and security findings into Port's software catalog.
- [Resource mapping examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/checkmarx/examples.md): Mapping examples for Checkmarx resources including projects, scans, SAST, SCA, KICS, and API security findings with blueprints and configurations.
- [Mend.io](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/mend.md): Sync Mend.io projects and SCA security findings into Port's software catalog.
- [Snyk](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/snyk.md): Sync Snyk vulnerabilities, projects, and security findings into Port's software catalog.
- [SonarQube](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/sonarqube.md): Sync SonarQube code quality metrics, issues, and projects into Port's software catalog.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/sonarqube/examples.md): Mapping examples for SonarQube resources including projects and analysis results with blueprints and configurations.
- [Wiz](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/wiz.md): Sync Wiz cloud security issues and findings into Port's software catalog.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/wiz/examples.md): Mapping examples for Wiz resources including projects, cloud resources, issues, and control findings with blueprints and configurations.
- [Kafka](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/event-processing/kafka.md): Sync Kafka clusters, topics, and brokers into Port's software catalog.
- [LaunchDarkly](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/feature-management/launchdarkly.md): LaunchDarkly integration in Port
- [Git](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git.md): Overview of Git provider integrations for syncing repositories, pull requests, and other data from GitHub, GitLab, Bitbucket, and Azure DevOps.
- [Azure DevOps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/azure-devops.md): Sync Azure DevOps repositories, pull requests, and pipelines into Port's software catalog.
- [Advanced](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/azure-devops/advanced.md): Advanced Azure DevOps integration configuration including createMissingRelatedEntities, deleteDependentEntities, and custom settings.
- [Capabilities](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/azure-devops/capabilities.md): Azure DevOps integration capabilities including file content enrichment for READMEs, CODEOWNERS, and documentation in entity properties.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/azure-devops/examples.md): Azure DevOps integration examples for repositories, pull requests, pipelines, and members with blueprint definitions and mapping configurations.
- [GitOps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/azure-devops/gitops.md): Manage Port entities as code using port.yml files in Azure DevOps repositories. Define entities declaratively and sync via push events.
- [Mapping Extensions](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/azure-devops/mapping_extensions.md): Extend Azure DevOps mapping with additional data sources beyond JQ. Includes file content enrichment and custom resource extraction.
- [Bitbucket app (deprecated)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-app.md): Deprecated Bitbucket Cloud app integration - use the newer Bitbucket Cloud integration instead for syncing repositories and pull requests.
- [Advanced](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-app/advanced.md): Advanced Bitbucket App configuration including createMissingRelatedEntities and deleteDependentEntities flags.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-app/examples.md): Bitbucket App integration examples for repositories, file contents, and pull requests with blueprint definitions and mapping configurations.
- [GitOps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-app/gitops.md): Manage Port entities as code using port.yml files with Bitbucket App. Define entities declaratively and sync via push events.
- [Bitbucket Cloud](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-cloud.md): Sync Bitbucket Cloud repositories, pull requests, and projects into Port's software catalog.
- [Advanced](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-cloud/advanced.md): Advanced Bitbucket Cloud configuration including createMissingRelatedEntities and deleteDependentEntities flags.
- [Capabilities](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-cloud/capabilities.md): Bitbucket Cloud integration capabilities including repository, pull request, and file ingestion with automatic blueprint creation.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-cloud/examples.md): Bitbucket Cloud integration examples for repositories, pull requests, projects, and files with blueprint definitions and mapping configurations.
- [GitOps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-cloud/gitops.md): Manage Port entities as code using port.yml files in Bitbucket Cloud repositories. Define entities declaratively and sync automatically.
- [Bitbucket (self-hosted)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-server.md): Sync Bitbucket (self-hosted) repositories, pull requests, and projects into Port's software catalog.
- [GitOps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-server/gitops.md): Manage Port entities as code using port.yml files in Bitbucket Server repositories. Define entities declaratively and sync via webhooks.
- [GitHub (Ocean)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean.md): Sync GitHub repositories, pull requests, workflows, and deployments into Port's software catalog using the GitHub Ocean integration.
- [Capabilities](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/capabilities.md): Advanced capabilities of the GitHub Ocean integration including parallel processing, file content ingestion, and custom query filtering.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/examples.md): Mapping examples for GitHub Ocean resources including repositories, pull requests, issues, deployments, releases, and team members.
- [GitOps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/gitops.md): Manage Port entities as code using port.yml files in GitHub repositories. Define entities declaratively and sync via push events.
- [Key changes](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/migration/key-changes.md): Overview of key changes between legacy GitHub app and GitHub Ocean including multi-org support, authentication, and mapping syntax updates.
- [Migration steps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/migration/migration-steps.md): Customer checklist and step-by-step guide for migrating from the legacy GitHub app to GitHub Ocean before the October 15, 2026 cutover.
- [GitLab v2](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2.md): Sync GitLab projects, merge requests, and pipelines into Port's software catalog using the v2 integration.
- [Advanced](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/advanced.md): Advanced GitLab v2 configuration including createMissingRelatedEntities, deleteDependentEntities, and custom integration flags.
- [Capabilities](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/capabilities.md): GitLab v2 integration capabilities including file content enrichment for READMEs, CODEOWNERS, and documentation in entity properties.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/examples.md): Mapping examples for GitLab v2 resources including groups, projects, issues, merge requests, pipelines, and releases with blueprints and configurations.
- [GitOps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/gitops.md): Manage Port entities as code using port.yml files in GitLab v2 repositories. Define entities declaratively and sync via push events.
- [Mapping extensions](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/mapping_extensions.md): Extend GitLab v2 mapping with additional data sources beyond JQ. Includes file content enrichment and external API lookups.
- [Migration guide to the v2 integration](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/migration.md): Migrate from GitLab v1 to v2 integration. Replace group tokens with service account authentication and update mapping configurations.
- [GitLab](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab.md): Sync GitLab projects, merge requests, and pipelines into Port's software catalog.
- [Advanced](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab/advanced.md): Advanced configuration options for the GitLab integration including delete dependents and entity creation flags.
- [Capabilities](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab/capabilities.md): Advanced capabilities of the GitLab integration including file ingestion, folder mapping, and live events configuration.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab/examples.md): Mapping examples for GitLab resources including projects, merge requests, pipelines, issues, and groups with blueprints and configurations.
- [GitOps](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab/gitops.md): Manage Port entities as code using port.yml files in GitLab repositories. Define entities declaratively and sync via push events.
- [Mapping Extensions](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab/mapping_extensions.md): Extend GitLab mapping with additional data sources beyond JQ. Includes file content enrichment and custom resource extraction.
- [GitOps using Port CRDs](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitops-using-port-crd.md): Learn how to use GitOps with Port's Kubernetes CRDs to export custom entities from your K8s clusters to the catalog.
- [Working with monorepos](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/working-with-monorepos.md): Learn how to configure Git integrations to create separate entities for each microservice in a monorepo.
- [Microsoft Entra ID](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/identity-providers/azure-ad.md): Learn how to ingest Microsoft Entra ID (Azure AD) users, groups, applications, and service principals into Port.
- [Okta](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/identity-providers/okta.md): Sync Okta users, groups, and applications into Port's software catalog.
- [Incident management](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management.md): Overview of incident management integrations for syncing data from tools like PagerDuty, OpsGenie, and Incident.io to Port.
- [FireHydrant](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/firehydrant.md): Sync FireHydrant incidents, services, and on-call data into Port's software catalog.
- [Incident.io](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/incident-io.md): Learn how to ingest Incident.io incidents, alerts, schedules, and teams into Port using the no-code Ocean custom integration framework.
- [Jira Service Management (JSM)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/jira-service-management.md): Learn how to ingest Jira Service Management service desks, customer requests, and organizations into Port using the no-code Ocean custom integration.
- [Opsgenie](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/opsgenie.md): Sync Opsgenie alerts, incidents, services, and on-call schedules into Port's software catalog.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/opsgenie/examples.md): Mapping examples for OpsGenie resources including users, teams, services, alerts, and incidents with blueprints and configurations.
- [PagerDuty](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/pagerduty.md): Sync PagerDuty services, incidents, and on-call schedules into Port's software catalog.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/pagerduty/examples.md): Mapping examples for PagerDuty resources including users, teams, services, incidents, and schedules with blueprints and configurations.
- [Rootly](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/rootly.md): Learn how to ingest Rootly incidents, services, teams, and on-call data into Port using the no-code Ocean custom integration framework.
- [ServiceNow](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/servicenow.md): Sync ServiceNow incidents, services, and CMDB data into Port's software catalog.
- [Statuspage](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/statuspage.md): Sync Statuspage pages, components, and incidents into Port's software catalog.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/statuspage/examples.md): Mapping examples for Statuspage resources including status pages, components, incidents, and maintenance windows with blueprints and configurations.
- [Komodor](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/komodor.md): Sync Komodor Kubernetes services, deployments, and health data into Port's software catalog.
- [Kubernetes](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes.md): Sync Kubernetes workloads, namespaces, and resources into Port's software catalog.
- [Advanced](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/advanced.md): Advanced configuration options for the Kubernetes exporter including resync intervals, state keys, and delete behavior parameters.
- [Basic example](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/basic-example.md): Basic Example
- [Custom CRDs](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/custom-crds.md): Learn how to export and map custom Kubernetes CRDs like ArgoCD resources to Port using the K8s exporter.
- [Port Entity CRD](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/port-crd.md): Learn how to use Port's Kubernetes Custom Resource Definitions to define and sync entities from K8s cluster manifests to your catalog.
- [Templates](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates.md): Pre-built configuration templates for common Kubernetes exporter use cases and third-party tools like ArgoCD and Istio.
- [FluxCD](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/fluxcd.md): FluxCD quickstart
- [Kubernetes (advanced)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/full-kubernetes-exporter.md): Advanced Kubernetes installation
- [Istio](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/istio.md): Istio quickstart
- [Knative](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/knative.md): Knative quickstart
- [Kyverno](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/kyverno.md): Kyverno quickstart
- [Red Hat Openshift](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/openshift.md): Openshift quickstart
- [Trivy Operator](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/trivy.md): Trivy quickstart
- [Amplication](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/amplication.md): Sync Amplication services and generated resources into Port's software catalog.
- [Backstage](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/backstage.md): Ingest Backstage entities into your context lake so that agents, workflows, and your team members can access and act on them.
- [Slack](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/slack.md): Learn how to ingest Slack users, channels, and user groups into Port using the no-code Ocean custom integration framework.
- [Project management](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management.md): Overview of project management integrations for syncing data from tools like Jira, Linear, and other project tracking systems to Port.
- [Jira Server (self-hosted)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira-server.md): Sync Jira Server (self-hosted) projects and issues into Port's software catalog.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira-server/examples.md): Mapping examples for Jira Server resources including projects, users, and issues with default blueprints and configurations.
- [Jira](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira.md): Sync Jira projects, issues, and teams into Port's software catalog.
- [Capabilities](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira/capabilities.md): Advanced capabilities of the Jira integration including JQL filtering, field selection, live events, and sprints ingestion.
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira/examples.md): Mapping examples for Jira Cloud resources including issues, epics, sprints, boards, teams, and components with blueprints and configurations.
- [Linear](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/linear.md): Sync Linear teams, issues, labels, documents, users, projects, initiatives, workflow states, cycles, and team memberships into Port's software catalog.
- [Terraform Cloud & Terraform Enterprise](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/terraform-cloud.md): Terraform integration in Port
- [Examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/terraform-cloud/examples.md): Mapping examples for Terraform Cloud resources including organizations, workspaces, runs, and state versions with blueprints and configurations.
- [Actions processing](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/actions-processing.md): How Ocean integrations claim, queue, and execute integration action runs from Port, including partitioning, rate limiting, flow control, and actionsProcessor configuration.
- [Advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration.md): Configure Ocean integration endpoints, health checks, proxies, custom CA certificates, SSL verification, HTTP timeouts and retries, and the outbound IP blocker for self-hosted deployments.
- [Connection probe](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/connection-probe.md): Use the ocean probe command to check that an Ocean integration can connect to the third-party tool and has the permissions required for each kind.
- [Event listeners and resync triggers](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners.md): How Ocean event listeners (POLLING, KAFKA, WEBHOOK, ONCE, WEBHOOKS_ONLY, ACTIONS_ONLY) receive resync requests from Port, and how scheduled resyncs work.
- [Identity propagation](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/identity-propagation.md): Run Ocean integration actions in workflows as the user who triggered them, using an OAuth broker, a token vault, and Port-signed identity tokens.
- [Live events processing](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/live-events-processing.md): How Ocean receives, queues, routes, authenticates, and retries live events from third-party tools before sending the updated data to Port.
- [Ocean framework overview](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/overview.md): How Ocean, the open source framework behind Port integrations, runs an integration, triggers resyncs, processes live events, and executes actions.
- [Install a native integration](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview.md): Install Port native integrations to sync GitHub, Kubernetes, Jira, and more into your catalog with hosted or self-hosted options.
- [Full resync](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync.md): How Port full resync fetches, maps, and ingests integration data, including reconciliation and monitoring sync status.
- [Incremental sync](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/incremental-sync.md): How Port incremental sync fetches only created or updated records between full resyncs.
- [Live events](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/live-events.md): How Port live events process webhook and watch API changes in real time, including scalable self-hosted infrastructure with Redis Streams and ocean-gateway.
- [Sync interactions](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/sync-interactions.md): How Port handles overlapping full resyncs, apply mapping runs, incremental syncs, and live events when more than one sync-related process runs at the same time.
##### other
- [Integrate assets using GitOps](/context-lake/ingestion/ingest-data-into-port/other/gitops.md): Overview of GitOps integration options for managing Port entities using your Git repositories as the source of truth, including how to build a custom GitOps integration using Port's API.
- [IaC](/context-lake/ingestion/ingest-data-into-port/other/iac.md): Overview of Infrastructure-as-Code methods for ingesting data and defining your software catalog alongside IaC configurations using Terraform or Pulumi.
- [Pulumi](/context-lake/ingestion/ingest-data-into-port/other/iac/pulumi.md): Learn how to use Port's Pulumi provider to manage blueprints and entities as infrastructure-as-code in Python, TypeScript, JavaScript, or Go.
- [Terraform](/context-lake/ingestion/ingest-data-into-port/other/iac/terraform.md): Learn how to use Port's Terraform provider to manage blueprints, entities, and other Port resources as infrastructure-as-code.
- [Manual entity management](/context-lake/ingestion/ingest-data-into-port/other/manual-entity-management.md): Not every catalog entity has a single clean source of truth. Manual entity management helps you fill gaps, correct edge cases, and enrich data that automation cannot reliably provide.
- [Migrate Blueprint Data](/context-lake/ingestion/ingest-data-into-port/other/migrate-data.md): Learn how to migrate entity data between blueprints when evolving your software catalog structure, including property transformations and relation updates.
- [Other ingestion methods](/context-lake/ingestion/ingest-data-into-port/other/other-ingestion-methods-overview.md): Explore Port's other ingestion options: IaC, GitOps, S3 buckets, Port MCP, and manual updates when continuous sync is not ideal.
- [Port MCP](/context-lake/ingestion/ingest-data-into-port/other/port-mcp.md): You can ingest entities into your catalog using Port MCP tools. This is useful when an agent or an IDE workflow needs to create or update entities as part of a multi-step SDLC automation.
- [S3 Bucket](/context-lake/ingestion/ingest-data-into-port/other/s3-integrations.md): Learn how to ingest data from external sources into Port using Airbyte or Fivetran with S3 as an intermediate storage layer.
##### webhook
- [Examples](/context-lake/ingestion/ingest-data-into-port/webhook/examples.md): Examples of using Port's webhook integration to ingest resources from various tools like Jira, OpsGenie, SonarQube, and Sentry.
- [Codecov](/context-lake/ingestion/ingest-data-into-port/webhook/examples/codecov.md): Ingest CodeCov coverage into your catalog
- [Falco Sidekick](/context-lake/ingestion/ingest-data-into-port/webhook/examples/falco.md): Ingest Falco alerts into your catalog
- [Grafana](/context-lake/ingestion/ingest-data-into-port/webhook/examples/grafana.md): Ingest Grafana alerts into your catalog
- [JFrog](/context-lake/ingestion/ingest-data-into-port/webhook/examples/jfrog.md): Ingest JFrog artifacts, Docker tags and builds into your catalog
- [Prometheus](/context-lake/ingestion/ingest-data-into-port/webhook/examples/prometheus.md): Ingest Prometheus alerts into your catalog
- [Split](/context-lake/ingestion/ingest-data-into-port/webhook/examples/split.md): Ingest Split IO Impressions into your catalog
- [StackHawk](/context-lake/ingestion/ingest-data-into-port/webhook/examples/stackhawk.md): Ingest StackHawk application vulnerabilities into Port
- [Ingest via Webhooks](/context-lake/ingestion/ingest-data-into-port/webhook/ingest-via-webhooks-overview.md): Use Port's generic webhook to ingest events from any service, map payloads with JQ, and create, update, or delete entities.
#### integrations-vs-mcp
Port gives you two ways to connect external tools: integrations and MCP connectors. They solve different problems and are designed to complement each other — in many cases, you can benefit from both connected for the same tool.
- [Integrations vs. MCP connectors](/context-lake/ingestion/integrations-vs-mcp.md): Port gives you two ways to connect external tools: integrations and MCP connectors. They solve different problems and are designed to complement each other — in many cases, you can benefit from both connected for the same tool.
#### overview
Choose how you ingest into Port's Context Lake: native integrations, MCP connectors, APIs, webhooks, or custom integrations.
- [Overview](/context-lake/ingestion/overview.md): Choose how you ingest into Port's Context Lake: native integrations, MCP connectors, APIs, webhooks, or custom integrations.
### overview
See how Port's context lake unifies data from your engineering tools into one queryable layer that humans and AI agents can use.
- [Context Lake](/context-lake/overview.md): See how Port's context lake unifies data from your engineering tools into one queryable layer that humans and AI agents can use.
## Workflows
### overview
Build Port workflows for humans, automations, and AI agents. Trigger runs from forms, catalog events, schedules, or Port MCP.
- [Workflows & tools](/workflows/overview.md): Build Port workflows for humans, automations, and AI agents. Trigger runs from forms, catalog events, schedules, or Port MCP.
### build-workflows
#### configure-and-test
##### data-flow
Pass data between workflow nodes using outputs and variables, reference trigger inputs, and use JQ expressions for data transformation.
- [Data flow](/workflows/build-workflows/configure-and-test/data-flow.md): Pass data between workflow nodes using outputs and variables, reference trigger inputs, and use JQ expressions for data transformation.
##### reusable-workflows
Share logic across workflows by triggering child workflows from parent workflows, enabling reusable approval flows and shared provisioning sequences.
- [Reusable workflows](/workflows/build-workflows/configure-and-test/reusable-workflows.md): Share logic across workflows by triggering child workflows from parent workflows, enabling reusable approval flows and shared provisioning sequences.
##### setup-checklist
Resolve a saved workflow's missing integrations and secrets from the workflow editor.
- [Setup checklist](/workflows/build-workflows/configure-and-test/setup-checklist.md): Resolve a saved workflow's missing integrations and secrets from the workflow editor.
##### test-workflows
Test your workflow directly from the builder by running the entire workflow or individual nodes with mock data before publishing.
- [Test workflows](/workflows/build-workflows/configure-and-test/test-workflows.md): Test your workflow directly from the builder by running the entire workflow or individual nodes with mock data before publishing.
#### iac
Manage Port workflows as code with the Terraform or Pulumi providers, defining workflow nodes and connections.
- [Manage workflows with IaC](/workflows/build-workflows/iac.md): Manage Port workflows as code with the Terraform or Pulumi providers, defining workflow nodes and connections.
#### nodes
##### action-nodes
- [AI](/workflows/build-workflows/nodes/action-nodes/ai.md): Invoke Port AI or AI agents directly from workflows to perform intelligent operations and automated decision-making.
- [Configuration and outputs](/workflows/build-workflows/nodes/action-nodes/configuration-and-outputs.md): Learn common action node configuration fields, outputs, and how to chain action nodes together in workflows.
- [Claude managed agents](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/claude-managed-agents.md): The Claude managed agents integration action allows workflows to create new agents or trigger agent sessions directly using your installed Claude Managed Agents integration.
- [Cursor cloud agents](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/cursor-cloud-agents.md): The Cursor cloud agents integration action allows workflows to launch new Cursor cloud agents or send follow-up prompts to existing ones directly using your installed Cursor Cloud Agents integration.
- [Azure DevOps Pipelines](/workflows/build-workflows/nodes/action-nodes/integration-actions/git/azure-devops.md): Trigger Azure DevOps pipelines and manage pull requests from Port workflows using your installed Azure DevOps integration.
- [GitHub](/workflows/build-workflows/nodes/action-nodes/integration-actions/git/github.md): Trigger GitHub Actions workflows, manage pull requests, and create issues from Port workflows using your installed GitHub integration.
- [GitLab](/workflows/build-workflows/nodes/action-nodes/integration-actions/git/gitlab.md): Trigger GitLab CI/CD pipelines, create and update merge requests, post merge request comments, and set comment reactions from Port workflows using your installed GitLab integration.
- [PagerDuty](/workflows/build-workflows/nodes/action-nodes/integration-actions/incident-management/pagerduty.md): Trigger, acknowledge, and resolve PagerDuty incidents from Port workflows using your installed PagerDuty integration.
- [Overview](/workflows/build-workflows/nodes/action-nodes/integration-actions/overview.md): Trigger operations in connected platforms like GitHub directly from workflows using Port's existing integrations.
- [Jira](/workflows/build-workflows/nodes/action-nodes/integration-actions/project-management/jira.md): Create Jira issues and change issue status from Port workflows using your installed Jira integration.
- [Linear](/workflows/build-workflows/nodes/action-nodes/integration-actions/project-management/linear.md): Create, update, delegate to agent, archive, delete, comment on, and react to Linear issues, and add documents from Port workflows.
- [Kafka](/workflows/build-workflows/nodes/action-nodes/kafka.md): Publish messages to Port's dedicated Kafka topic from workflows to process events with your own consumers.
- [Port execution agent](/workflows/build-workflows/nodes/action-nodes/port-execution-agent.md): Execute workflow webhook actions inside your private network without exposing public endpoints using the Port execution agent.
- [Upsert entity](/workflows/build-workflows/nodes/action-nodes/upsert-entity.md): Create or update entities in Port's software catalog from workflows using the upsert entity action node.
- [Webhook](/workflows/build-workflows/nodes/action-nodes/webhook.md): Send HTTP requests to external endpoints from workflows, supporting synchronous and asynchronous operations with custom headers and payloads.
##### flow-nodes
- [Condition nodes](/workflows/build-workflows/nodes/flow-nodes/condition.md): Add branching logic to workflows using condition nodes that evaluate JQ expressions and route execution to different paths.
- [Input nodes](/workflows/build-workflows/nodes/flow-nodes/input.md): Add human-in-the-loop steps to workflows using input nodes for approvals, manual gates, and decision points that require user responses.
#### quickstart
Create your first workflow in Port using the visual editor, JSON editor, or AI-assisted builder to send a webhook notification.
- [Quickstart](/workflows/build-workflows/quickstart.md): Create your first workflow in Port using the visual editor, JSON editor, or AI-assisted builder to send a webhook notification.
#### triggers
##### event-trigger
Configure workflows to run automatically when entities are created, updated, or deleted in your software catalog.
- [Event trigger](/workflows/build-workflows/triggers/event-trigger.md): Configure workflows to run automatically when entities are created, updated, or deleted in your software catalog.
##### schedule-trigger
Configure workflows to run automatically on a recurring cron schedule.
- [Schedule trigger](/workflows/build-workflows/triggers/schedule-trigger.md): Configure workflows to run automatically on a recurring cron schedule.
##### self-service-trigger
- [Advanced input configurations](/workflows/build-workflows/triggers/self-service-trigger/advanced-input-configurations.md): Configure advanced user input features including visibility controls, input dependencies, and dynamic default values using JQ expressions.
- [Configuration](/workflows/build-workflows/triggers/self-service-trigger/configuration.md): Configure self-service trigger nodes with user inputs, permissions, and UI contexts to create on-demand workflow executions.
- [Contexts](/workflows/build-workflows/triggers/self-service-trigger/contexts.md): Surface self-service triggers in additional UI locations like entity creation flows and action menus using the contexts configuration.
- [Share a pre-filled workflow URL](/workflows/build-workflows/triggers/self-service-trigger/send-link-to-workflow.md): Generate shareable URLs with pre-filled workflow inputs using JSURL encoding. Useful for bookmarks, documentation, and programmatic links.
- [Array](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/array.md): Configure array inputs for workflow forms to accept lists of values like tags, services to deploy, or email recipients.
- [Datetime](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/datetime.md): Configure datetime inputs for workflow forms to accept date and time values for scheduling, expiration, or maintenance windows.
- [Email](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/email.md): Configure email inputs for workflow forms to accept and validate email addresses for contacts or notifications.
- [Entity](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/entity.md): Configure entity inputs for workflow forms to let users select entities from your software catalog like services or environments.
- [Markdown](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/markdown.md): Configure markdown inputs for workflow forms to accept formatted content like release notes, runbooks, or descriptions.
- [Number](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/number.md): Configure number inputs for workflow forms to accept numeric values like replica counts, port numbers, or resource limits.
- [Object](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/object.md): Configure object inputs for workflow forms to accept JSON objects for configuration data, metadata, or key-value pairs.
- [Structure and fields](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/structure-and-fields.md): Define user inputs for self-service workflows including input structure, common fields, and required vs optional configurations.
- [Team](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/team.md): Configure team inputs for workflow forms to let users select Port teams for ownership assignment or notifications.
- [Text](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/text.md): Configure text inputs for workflow forms to accept string values like service names, version tags, or commit SHAs.
- [Toggle](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/toggle.md): Configure toggle inputs for workflow forms to accept boolean true/false values for feature flags or operation modes.
- [URL](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/url.md): Configure URL inputs for workflow forms to accept and validate URL strings for repository links, API endpoints, or documentation.
- [User](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/user.md): Configure user inputs for workflow forms to let users select Port users for ownership, reviewers, or on-call assignment.
- [YAML](/workflows/build-workflows/triggers/self-service-trigger/user-inputs/yaml.md): Configure YAML inputs for workflow forms to accept YAML-formatted content like Kubernetes manifests or configuration files.
### actions-and-automations
#### create-self-service-experiences
Create self-service actions that let developers trigger workflows from Port, such as scaffolding services, provisioning resources, and running day-2 operations, with forms, guardrails, and approvals.
- [Self-service actions](/workflows/actions-and-automations/create-self-service-experiences.md): Create self-service actions that let developers trigger workflows from Port, such as scaffolding services, provisioning resources, and running day-2 operations, with forms, guardrails, and approvals.
##### send-link-to-action
Generate shareable URLs with pre-filled action inputs using JSURL encoding. Useful for bookmarks, documentation, and programmatic links.
- [Share a pre-filled action URL](/workflows/actions-and-automations/create-self-service-experiences/send-link-to-action.md): Generate shareable URLs with pre-filled action inputs using JSURL encoding. Useful for bookmarks, documentation, and programmatic links.
##### set-self-service-actions-rbac
Control who can execute self-service actions using role-based permissions. Configure manual approval workflows and ownership-based restrictions.
- [Set actions RBAC](/workflows/actions-and-automations/create-self-service-experiences/set-self-service-actions-rbac.md): Control who can execute self-service actions using role-based permissions. Configure manual approval workflows and ownership-based restrictions.
- [Dynamic permissions](/workflows/actions-and-automations/create-self-service-experiences/set-self-service-actions-rbac/dynamic-permissions.md): Control action execution and approval using runtime data from your catalog. Define queries and JQ conditions for ownership, manager approval, and on-call rules.
- [Examples](/workflows/actions-and-automations/create-self-service-experiences/set-self-service-actions-rbac/dynamic-permissions/examples.md): Dynamic permissions examples including blocking duplicate entities, requiring manager approval, and enforcing ownership-based execution rules.
##### setup-the-backend
Configure self-service action backends to execute logic when triggered. Supports GitHub, GitLab, Azure DevOps, Jenkins, webhooks, and more.
- [Set up backend](/workflows/actions-and-automations/create-self-service-experiences/setup-the-backend.md): Configure self-service action backends to execute logic when triggered. Supports GitHub, GitLab, Azure DevOps, Jenkins, webhooks, and more.
##### setup-ui-for-action
Configure self-service action frontend including title, icon, operation type (create, day-2, delete), and user form inputs.
- [Set up frontend](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action.md): Configure self-service action frontend including title, icon, operation type (create, day-2, delete), and user form inputs.
- [Advanced input configurations](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/advanced-form-configurations.md): Advanced input settings allow you to create more customizable experiences for users who perform self-service actions. This is done by creating adaptive inputs that change according to data about the entity, the user, and other inputs.
- [User Inputs](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs.md): Define user inputs for self-service actions with various types, validation rules, default values, and conditional visibility using jqQuery.
- [Array](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/array.md): Array is an input for lists of data
- [Datetime](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/datetime.md): Datetime is an input used to reference a date and time
- [Email](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/email.md): Email is an input used to save Email addresses
- [Entity](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/entity.md): Entity is an input used to reference existing entities from the software catalog when triggering actions
- [Number](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/number.md): Number is a basic input for numeric data
- [Object](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/object.md): Object is a basic input for JSON data
- [Secret](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/secret.md): A secret input encrypts its value before sending it to your backend and never stores or logs it. Choose Port-managed encryption or your own public key.
- [Team](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/team.md): Team is an input used to reference teams that exist in Port
- [Text](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/text.md): Text is a basic input for textual information
- [Toggle (Boolean)](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/toggle.md): Toggle is a basic input that has one of two possible values - true and false
- [URL](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/url.md): URL is an input used to save links to websites
- [User](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/user.md): User is an input used to reference users that exist in Port
- [Yaml](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/yaml.md): Yaml is an input used to save object definitions in YAML
#### define-automations
Create Port automations that trigger actions automatically based on catalog events like entity creation, updates, timers, or external webhooks. Configure triggers, conditions, and backend handlers.
- [Define automations](/workflows/actions-and-automations/define-automations.md): Create Port automations that trigger actions automatically based on catalog events like entity creation, updates, timers, or external webhooks. Configure triggers, conditions, and backend handlers.
##### examples
Automation examples including Slack/Teams notifications on entity changes, TTL enforcement, PagerDuty incident creation, and scorecard-based alerts.
- [Examples](/workflows/actions-and-automations/define-automations/examples.md): Automation examples including Slack/Teams notifications on entity changes, TTL enforcement, PagerDuty incident creation, and scorecard-based alerts.
##### migrate-from-changelog-destination
Step-by-step guide for migrating from the legacy changelogDestination feature to Port Automations.
- [Migrate from changelog destination](/workflows/actions-and-automations/define-automations/migrate-from-changelog-destination.md): Step-by-step guide for migrating from the legacy changelogDestination feature to Port Automations.
##### setup-action
Configure automation backends including webhook, GitHub, GitLab, and Kafka. Define JSON payloads with jq expressions and access trigger event data.
- [Set up backend](/workflows/actions-and-automations/define-automations/setup-action.md): Configure automation backends including webhook, GitHub, GitLab, and Kafka. Define JSON payloads with jq expressions and access trigger event data.
##### setup-trigger
Configure automation triggers for entity events (create, update, delete, timer expiration) or action run status changes. Supports JQ conditions for filtering.
- [Set up trigger](/workflows/actions-and-automations/define-automations/setup-trigger.md): Configure automation triggers for entity events (create, update, delete, timer expiration) or action run status changes. Supports JQ conditions for filtering.
#### overview
Understand Port's legacy actions and automations so you can run self-service and event-based logic, or move new work to workflows.
- [Overview](/workflows/actions-and-automations/overview.md): Understand Port's legacy actions and automations so you can run self-service and event-based logic, or move new work to workflows.
#### reflect-action-progress
Once a self-service action or automation has been executed, an actionRun object will be created in Port.
- [Interact with action runs](/workflows/actions-and-automations/reflect-action-progress.md): Once a self-service action or automation has been executed, an actionRun object will be created in Port.
#### setup-backend
Configure backends for self-service actions including GitHub workflows, GitLab pipelines, Azure DevOps, Jenkins, webhooks, and Kafka topics.
- [Backend types](/workflows/actions-and-automations/setup-backend.md): Configure backends for self-service actions including GitHub workflows, GitLab pipelines, Azure DevOps, Jenkins, webhooks, and Kafka topics.
##### azure-pipeline
The Azure backend can trigger Azure pipelines for both self-service actions and automations, using incoming webhook triggers.
- [Azure pipeline](/workflows/actions-and-automations/setup-backend/azure-pipeline.md): The Azure backend can trigger Azure pipelines for both self-service actions and automations, using incoming webhook triggers.
- [Trigger pipelines in non-default branch](/workflows/actions-and-automations/setup-backend/azure-pipeline/trigger-non-default-branch.md): Configure Port self-service actions to trigger Azure DevOps pipelines from non-default branches using refName parameter.
- [Azure DevOps troubleshooting](/workflows/actions-and-automations/setup-backend/azure-pipeline/troubleshooting.md): Common questions and solutions for Azure DevOps integration and pipelines in Port.
##### create-update-entity
In some cases, we don't want to run complex logic via a workflow or pipeline, but rather want our backend to simply create or update an entity in our software catalog.
- [Create/update entity](/workflows/actions-and-automations/setup-backend/create-update-entity.md): In some cases, we don't want to run complex logic via a workflow or pipeline, but rather want our backend to simply create or update an entity in our software catalog.
##### github-ocean
The GitHub Ocean backend allows you to run GitHub integration actions for your self-service actions and automations, including triggering GitHub Actions workflows and managing pull requests, using the GitHub Ocean integration.
- [GitHub workflow via Ocean](/workflows/actions-and-automations/setup-backend/github-ocean.md): The GitHub Ocean backend allows you to run GitHub integration actions for your self-service actions and automations, including triggering GitHub Actions workflows and managing pull requests, using the GitHub Ocean integration.
##### github-workflow
The GitHub backend allows you to trigger GitHub workflows for your self-service actions and automations, using Port's GitHub application.
- [GitHub workflow](/workflows/actions-and-automations/setup-backend/github-workflow.md): The GitHub backend allows you to trigger GitHub workflows for your self-service actions and automations, using Port's GitHub application.
##### gitlab-pipeline
The GitLab backend allows you to trigger GitLab pipelines for your self-service actions and automations.
- [GitLab pipeline](/workflows/actions-and-automations/setup-backend/gitlab-pipeline.md): The GitLab backend allows you to trigger GitLab pipelines for your self-service actions and automations.
- [GitLab SaaS](/workflows/actions-and-automations/setup-backend/gitlab-pipeline/saas.md): Trigger GitLab SaaS or reachable self-hosted GitLab pipelines directly from Port using webhook URLs with trigger tokens, without an execution agent.
- [Self-hosted GitLab](/workflows/actions-and-automations/setup-backend/gitlab-pipeline/self-hosted.md): Choose direct webhooks for reachable self-hosted GitLab endpoints, or use the Port execution agent for private endpoints with Kafka or HTTP polling.
##### jenkins-pipeline
The Jenkins backend allows you to trigger Jenkins pipelines for your self-service actions and automations, using webhooks.
- [Jenkins pipeline](/workflows/actions-and-automations/setup-backend/jenkins-pipeline.md): The Jenkins backend allows you to trigger Jenkins pipelines for your self-service actions and automations, using webhooks.
##### kafka
Port manages a Kafka topic per customer that publishes the execution run requests.
- [Kafka topic](/workflows/actions-and-automations/setup-backend/kafka.md): Port manages a Kafka topic per customer that publishes the execution run requests.
##### security
Port IP addresses for firewall allow lists. Covers webhook outbound IPs and Ocean integration source IPs for EU and US regions.
- [Security](/workflows/actions-and-automations/setup-backend/security.md): Port IP addresses for firewall allow lists. Covers webhook outbound IPs and Ocean integration source IPs for EU and US regions.
##### send-slack-message
The Send Slack message backend type allows you to send a message to a Slack channel, using a webhook URL.
- [Send Slack message](/workflows/actions-and-automations/setup-backend/send-slack-message.md): The Send Slack message backend type allows you to send a message to a Slack channel, using a webhook URL.
##### webhook
The webhook backend allows you to trigger your own custom webhooks, for both self-service actions and automations.
- [Webhook](/workflows/actions-and-automations/setup-backend/webhook.md): The webhook backend allows you to trigger your own custom webhooks, for both self-service actions and automations.
- [Circle CI Actions](/workflows/actions-and-automations/setup-backend/webhook/circle-ci.md): Port's Circle CI integration allows you to trigger new pipelines in Circle CI directly from Port.
- [Triggering Cloud Build using webhooks](/workflows/actions-and-automations/setup-backend/webhook/cloudbuild-pipeline.md): This page will guide you through the process of triggering your Cloud Build pipelines from Port, using Webhook Actions.
- [Software templates](/workflows/actions-and-automations/setup-backend/webhook/examples/software-templates.md): Use Cookiecutter with Port webhooks to scaffold new service repositories from software templates via self-service actions.
- [Terraform: No-Code resource provisioning](/workflows/actions-and-automations/setup-backend/webhook/examples/terraform-no-code-resource-provisioning.md): Expose Terraform-based cloud resource provisioning as no-code self-service actions. Example covers S3 bucket lifecycle operations.
- [Debug webhooks locally](/workflows/actions-and-automations/setup-backend/webhook/local-debugging-webhook.md): Debug webhook self-service actions locally using smee.io to receive Port webhook payloads on your development machine.
- [Port execution agent](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent.md): Port execution agent forwards action invocations to private endpoints using Kafka or HTTP polling, without exposing public URLs.
- [Control the payload](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/control-the-payload.md): Port offers two ways to control the payload sent to your backend:
- [Argo workflow](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/examples/trigger-an-argo-workflow.md): This example helps internal developer teams to trigger an Argo Workflow using Port's self service actions. We will create a blueprint for argoWorkflow that will be connected to a backend action. We will then add some configuration files (invocations.json) to control the payload and trigger your Argo Workflows directly from Port using the sync execution method.
- [CircleCI pipline](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/examples/trigger-circleCI-pipeline.md): This example helps internal developer teams to trigger CircleCI pipelines using Port's self service actions. In particular, you will create a blueprint for circleCI Project that will be connected to a backend action. You will then add some configuration files (invocations.json) to control the payload and trigger your CircleCI pipeline directly from Port using the sync execution method.
- [OpsGenie incident](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/examples/trigger-opsgenie-incident.md): This example helps internal developer teams to trigger Opsgenie incidents using Port's self service actions. In particular, you will create a blueprint for opsgenieIncident that will be connected to a backend action. You will then add some configuration files (invocations.json) to control the payload and trigger your Opsgenie incident directly from Port using the sync execution method.
- [Terraform Cloud run](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/examples/trigger-terraform-cloud-run.md): This example helps internal developer teams to trigger an Terraform Cloud run using Port's self service actions. We will create a blueprint for Terraform Cloud Workspace that will be connected to a backend action. We will then add some configuration files (invocations.json) to control the payload and trigger your Terraform Cloud run directly from Port using the sync execution method.
- [Windmill job](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/examples/trigger-windmill-job.md): This example helps internal developer teams to trigger Windmill job using Port's self service actions. In particular, you will create a blueprint for windmillJob that will be connected to a backend action. You will then add some configuration files (invocations.json) to control the payload and trigger your Windmill job directly from Port using async/sync execution method.
- [ArgoCD](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/installation-methods/argocd.md): Install the Port execution agent in Kubernetes using ArgoCD with Helm capabilities. Includes manifest examples and configuration steps.
- [Docker](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/installation-methods/docker.md): Run the Port execution agent as a Docker container with Kafka streaming to forward action invocations to private endpoints.
- [Helm](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/installation-methods/helm.md): Install the Port execution agent in Kubernetes using Helm. Configure Kafka credentials and optional GitLab pipeline triggers.
- [Usage](/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/usage.md): Configure actions to use the Port execution agent by setting type to WEBHOOK and agent to true. Supports Kafka and HTTP polling streamers.
- [Validate webhook signatures](/workflows/actions-and-automations/setup-backend/webhook/signature-verification.md): Verify webhook signatures using x-port-timestamp and x-port-signature headers to ensure requests are from Port and not tampered with.
- [Terraform cloud actions](/workflows/actions-and-automations/setup-backend/webhook/terraform-cloud.md): Port's Terraform Cloud integration allows you to trigger Terraform Cloud runs directly from Port.
### concepts
Learn the core building blocks of workflows including nodes (triggers, actions, conditions), edges, and how multiple triggers work together.
- [Concepts and structure](/workflows/concepts.md): Learn the core building blocks of workflows including nodes (triggers, actions, conditions), edges, and how multiple triggers work together.
### expose-as-tool
Make any workflow invokable by AI agents through the Port MCP server. Learn how to configure tool names, write descriptions agents can use, and control who can invoke the workflow.
- [Expose workflows as tools](/workflows/expose-as-tool.md): Make any workflow invokable by AI agents through the Port MCP server. Learn how to configure tool names, write descriptions agents can use, and control who can invoke the workflow.
### permissions-and-rbac
#### manage-workflows
Create a workflow and set who can build it and who can run it, through Port AI, the UI, and the API.
- [Manage a workflow](/workflows/permissions-and-rbac/manage-workflows.md): Create a workflow and set who can build it and who can run it, through Port AI, the UI, and the API.
#### permissions
Control who can see and execute workflows using team-based, role-based, or dynamic permission rules on self-service triggers.
- [Workflow execute permissions](/workflows/permissions-and-rbac/permissions.md): Control who can see and execute workflows using team-based, role-based, or dynamic permission rules on self-service triggers.
#### workflow-catalog
Workflows are represented as entities in the _workflow system blueprint, enabling team ownership and catalog-level access control.
- [Workflow catalog and ownership](/workflows/permissions-and-rbac/workflow-catalog.md): Workflows are represented as entities in the _workflow system blueprint, enabling team ownership and catalog-level access control.
### track-workflow-execution
#### track-and-manage-runs
Monitor workflow executions, view run status and logs, cancel running workflows, and interact with workflow runs through the API.
- [Track & manage runs](/workflows/track-workflow-execution/track-and-manage-runs.md): Monitor workflow executions, view run status and logs, cancel running workflows, and interact with workflow runs through the API.
#### workflow-run-page
View and debug individual workflow executions with visual status indicators showing node success, failure, and data flow through the graph.
- [Workflow run page](/workflows/track-workflow-execution/workflow-run-page.md): View and debug individual workflow executions with visual status indicators showing node success, failure, and data flow through the graph.
### use-cases-and-examples
Real-world workflow examples for common use cases including scaffolding microservices, deployments, automated catalog updates, and agent-triggered rollbacks.
- [Use-cases & examples](/workflows/use-cases-and-examples.md): Real-world workflow examples for common use cases including scaffolding microservices, deployments, automated catalog updates, and agent-triggered rollbacks.
## port-ai
### ai-invocations
Track, debug, and collect feedback on every Port AI interaction using AI invocation records.
- [AI invocations](/port-ai/ai-invocations.md): Track, debug, and collect feedback on every Port AI interaction using AI invocation records.
### api-interaction
Port AI can be accessed programmatically through Port's API, enabling integration into custom applications and workflows.
- [Port AI API interaction](/port-ai/api-interaction.md): Port AI can be accessed programmatically through Port's API, enabling integration into custom applications and workflows.
### context-engineering
Context engineering is the practice of constructing an optimal information environment that provides the right amount of directions, tools, and knowledge for AI systems to successfully solve problems.
- [Context engineering](/port-ai/context-engineering.md): Context engineering is the practice of constructing an optimal information environment that provides the right amount of directions, tools, and knowledge for AI systems to successfully solve problems.
### interfaces
#### port-cli
Run Port from the shell. Coding agents print JSON, pipe it through jq, and batch updates. Platform engineers export, compare, and migrate organizations.
- [Port CLI](/port-ai/interfaces/port-cli.md): Run Port from the shell. Coding agents print JSON, pipe it through jq, and batch updates. Platform engineers export, compare, and migrate organizations.
### limits-and-quotas
Rate limits, monthly quotas, error handling, and technical limitations for Port AI across all interfaces.
- [Limits and quotas](/port-ai/limits-and-quotas.md): Rate limits, monthly quotas, error handling, and technical limitations for Port AI across all interfaces.
### llm-providers-management
#### overview
Manage and configure LLM providers that power Port AI, including Port's managed infrastructure and bring-your-own-LLM options.
- [LLM provider management](/port-ai/llm-providers-management/overview.md): Manage and configure LLM providers that power Port AI, including Port's managed infrastructure and bring-your-own-LLM options.
#### providers
##### anthropic-compatible
Configure any Anthropic Messages API-compatible endpoint as an LLM provider in Port, including custom gateways and proxies.
- [Anthropic compatible setup](/port-ai/llm-providers-management/providers/anthropic-compatible.md): Configure any Anthropic Messages API-compatible endpoint as an LLM provider in Port, including custom gateways and proxies.
##### anthropic
Configure Anthropic as an LLM provider in Port to use Claude models directly through Anthropic's API.
- [Anthropic setup](/port-ai/llm-providers-management/providers/anthropic.md): Configure Anthropic as an LLM provider in Port to use Claude models directly through Anthropic's API.
##### aws-bedrock
Configure AWS Bedrock as an LLM provider in Port using IAM-based authentication to access Claude and other models.
- [AWS Bedrock setup](/port-ai/llm-providers-management/providers/aws-bedrock.md): Configure AWS Bedrock as an LLM provider in Port using IAM-based authentication to access Claude and other models.
##### azure-anthropic
Configure Azure Anthropic as an LLM provider in Port to use Claude models hosted in your Azure deployment.
- [Azure Anthropic setup](/port-ai/llm-providers-management/providers/azure-anthropic.md): Configure Azure Anthropic as an LLM provider in Port to use Claude models hosted in your Azure deployment.
##### azure-openai
Configure Azure OpenAI as an LLM provider in Port by storing your Azure credentials and registering your OpenAI deployment.
- [Azure OpenAI setup](/port-ai/llm-providers-management/providers/azure-openai.md): Configure Azure OpenAI as an LLM provider in Port by storing your Azure credentials and registering your OpenAI deployment.
##### openai-compatible
Configure any OpenAI-compatible endpoint as an LLM provider in Port, including LiteLLM proxies and custom gateways.
- [OpenAI compatible setup](/port-ai/llm-providers-management/providers/openai-compatible.md): Configure any OpenAI-compatible endpoint as an LLM provider in Port, including LiteLLM proxies and custom gateways.
##### openai
Configure OpenAI as an LLM provider in Port by storing your API key and registering your OpenAI account.
- [OpenAI setup](/port-ai/llm-providers-management/providers/openai.md): Configure OpenAI as an LLM provider in Port by storing your API key and registering your OpenAI account.
##### overview
Step-by-step setup guides for each LLM provider supported by Port, including OpenAI, Anthropic, Azure, AWS Bedrock, and Vertex AI.
- [Provider guides overview](/port-ai/llm-providers-management/providers/overview.md): Step-by-step setup guides for each LLM provider supported by Port, including OpenAI, Anthropic, Azure, AWS Bedrock, and Vertex AI.
##### vertex-anthropic
Configure Vertex Anthropic as an LLM provider in Port to use Claude models hosted on Google Vertex AI.
- [Vertex Anthropic setup](/port-ai/llm-providers-management/providers/vertex-anthropic.md): Configure Vertex Anthropic as an LLM provider in Port to use Claude models hosted on Google Vertex AI.
##### vertex-gemini
Configure Vertex Gemini as an LLM provider in Port using service account or Express Mode authentication.
- [Vertex Gemini setup](/port-ai/llm-providers-management/providers/vertex-gemini.md): Configure Vertex Gemini as an LLM provider in Port using service account or Express Mode authentication.
#### selecting-llm-provider
Learn how to select specific LLM providers and models for Port AI requests, including default provider configuration and validation.
- [Selecting LLM provider](/port-ai/llm-providers-management/selecting-llm-provider.md): Learn how to select specific LLM providers and models for Port AI requests, including default provider configuration and validation.
#### setup-and-configuration
Technical guide for setting up LLM providers in Port, including permissions, secrets management, validation, and troubleshooting.
- [Setup & configuration](/port-ai/llm-providers-management/setup-and-configuration.md): Technical guide for setting up LLM providers in Port, including permissions, secrets management, validation, and troubleshooting.
### overview
Use Port AI to query your software catalog in natural language, get contextual answers, and run actions through MCP tools.
- [Port AI](/port-ai/overview.md): Use Port AI to query your software catalog in natural language, get contextual answers, and run actions through MCP tools.
### port-ai-assistant
Use the Port AI Assistant for instant AI chat with ask, plan, and build modes, per-tool approval settings, and no configuration required.
- [Port AI Assistant](/port-ai/port-ai-assistant.md): Use the Port AI Assistant for instant AI chat with ask, plan, and build modes, per-tool approval settings, and no configuration required.
### port-ai-plugin
Install Port's Agent Skills and plugin to bring Port's context and MCP tools into your coding agent.
- [Port AI plugin](/port-ai/port-ai-plugin.md): Install Port's Agent Skills and plugin to bring Port's context and MCP tools into your coding agent.
### security-and-data-controls
Learn about Port AI's security practices, data privacy, RBAC enforcement, and controls for responsible AI usage.
- [AI security and data controls](/port-ai/security-and-data-controls.md): Learn about Port AI's security practices, data privacy, RBAC enforcement, and controls for responsible AI usage.
### tools-and-approvals
Control which tools Port AI can use, how they are approved, and which MCP connectors are attached to an API request.
- [Tools and approvals](/port-ai/tools-and-approvals.md): Control which tools Port AI can use, how they are approved, and which MCP connectors are attached to an API request.
## agent-management
### AGENTS
This is a hidden guide for AI agents to understand how to maintain and update the AI interfaces documentation in Port Docs.
- [AGENTS.md - AI Documentation Maintenance Guide](/agent-management/AGENTS.md): This is a hidden guide for AI agents to understand how to maintain and update the AI interfaces documentation in Port Docs.
### ai-gateway
What AI gateways do in the agentic SDLC, where they stop, and how Port governs agents, keys, and tools running through them.
- [AI Gateway](/agent-management/ai-gateway.md): What AI gateways do in the agentic SDLC, where they stop, and how Port governs agents, keys, and tools running through them.
### ai-registry
#### agent-registry
Maintain a centralized agent registry in your Context Lake for AI agents deployed across cloud platforms such as AWS Bedrock and Azure AI Foundry.
- [Agent registry](/agent-management/ai-registry/agent-registry.md): Maintain a centralized agent registry in your Context Lake for AI agents deployed across cloud platforms such as AWS Bedrock and Azure AI Foundry.
#### managing-ai-primitives
Short map of Port AI building blocks in the AI registry: skills, agents, MCP, context, and controls.
- [Managing AI primitives](/agent-management/ai-registry/managing-ai-primitives.md): Short map of Port AI building blocks in the AI registry: skills, agents, MCP, context, and controls.
#### mcp-connectors
Set up MCP connectors as a Port gateway: approve servers, choose exposed tools, and let agents call them under RBAC and audit.
- [MCP connectors](/agent-management/ai-registry/mcp-connectors.md): Set up MCP connectors as a Port gateway: approve servers, choose exposed tools, and let agents call them under RBAC and audit.
##### github-mcp-connector
Set up the GitHub MCP connector to give Port AI access to GitHub repositories, issues, and pull requests through OAuth authentication.
- [GitHub MCP connector](/agent-management/ai-registry/mcp-connectors/github-mcp-connector.md): Set up the GitHub MCP connector to give Port AI access to GitHub repositories, issues, and pull requests through OAuth authentication.
##### use-in-workflows
Connect an MCP connector with organization-level OAuth so it can be called from an automated workflow AI node, and verify it end to end.
- [Use in workflows](/agent-management/ai-registry/mcp-connectors/use-in-workflows.md): Connect an MCP connector with organization-level OAuth so it can be called from an automated workflow AI node, and verify it end to end.
#### mcp-registry
The MCP registry is an organizational catalog of MCP servers your teams are allowed to use. Platform teams define which servers are approved, developers discover what is available, and new servers enter through a governed request flow instead of ad hoc installs.
- [MCP registry](/agent-management/ai-registry/mcp-registry.md): The MCP registry is an organizational catalog of MCP servers your teams are allowed to use. Platform teams define which servers are approved, developers discover what is available, and new servers enter through a governed request flow instead of ad hoc installs.
#### prompts
Prebuilt prompts for the Port MCP server that help AI agents query and act on your Port catalog.
- [Prompts](/agent-management/ai-registry/prompts.md): Prebuilt prompts for the Port MCP server that help AI agents query and act on your Port catalog.
#### skills
##### enrich-port-ai-with-skills
Skills give Port AI domain-specific instructions at runtime. Instead of repeating the same prompts or hoping the model infers your process, you package expert workflows as skills that Port AI loads when a task matches.
- [Enrich Port AI with skills](/agent-management/ai-registry/skills/enrich-port-ai-with-skills.md): Skills give Port AI domain-specific instructions at runtime. Instead of repeating the same prompts or hoping the model infers your process, you package expert workflows as skills that Port AI loads when a task matches.
##### overview
Package Port AI skills with reusable instructions so agents load the right steps when they handle specialized tasks in your org.
- [Skills](/agent-management/ai-registry/skills/overview.md): Package Port AI skills with reusable instructions so agents load the right steps when they handle specialized tasks in your org.
##### skills-registry
A skills registry is a central library of reusable skills that everyone across the organization can publish and consume. Instead of each squad maintaining its own prompts and instructions, approved skills live in one catalog in Port, discovered and installed through the UI, Port MCP, or a CLI command.
- [Skills registry](/agent-management/ai-registry/skills/skills-registry.md): A skills registry is a central library of reusable skills that everyone across the organization can publish and consume. Instead of each squad maintaining its own prompts and instructions, approved skills live in one catalog in Port, discovered and installed through the UI, Port MCP, or a CLI command.
##### skills-usage-analytics
Analyze how teams adopt and use skills across Cursor and Claude by ingesting skill usage metrics into Port.
- [Skills usage analytics](/agent-management/ai-registry/skills/skills-usage-analytics.md): Analyze how teams adopt and use skills across Cursor and Claude by ingesting skill usage metrics into Port.
### custom-agents
#### build-an-ai-agent
Build an AI agent in Port to assist your developers with finding information and completing tasks.
- [Build agents](/agent-management/custom-agents/build-an-ai-agent.md): Build an AI agent in Port to assist your developers with finding information and completing tasks.
#### interact-with-ai-agents
Learn how to invoke and interact with Port AI agents programmatically through API calls, automations, and workflow integrations.
- [Interact with agents](/agent-management/custom-agents/interact-with-ai-agents.md): Learn how to invoke and interact with Port AI agents programmatically through API calls, automations, and workflow integrations.
#### overview
Build Port custom agents for domain tasks that automate incidents, deployments, and monitoring as machine-to-machine operations.
- [Port custom agents](/agent-management/custom-agents/overview.md): Build Port custom agents for domain tasks that automate incidents, deployments, and monitoring as machine-to-machine operations.
### external-agents
#### claude-managed-agents
Manage Claude agents and trigger sessions directly from Port workflows.
- [Claude managed agents](/agent-management/external-agents/claude-managed-agents.md): Manage Claude agents and trigger sessions directly from Port workflows.
#### cursor-cloud-agents
Manage Cursor cloud agents and trigger runs directly from Port workflows.
- [Cursor cloud agents](/agent-management/external-agents/cursor-cloud-agents.md): Manage Cursor cloud agents and trigger runs directly from Port workflows.
#### overview
Surface external AI agents in Context Lake, track ownership in a registry, and start sessions from Port workflows you already run.
- [External agents](/agent-management/external-agents/overview.md): Surface external AI agents in Context Lake, track ownership in a registry, and start sessions from Port workflows you already run.
### overview
Govern AI agents, skills, and MCP access in Port so you can discover what exists, control permissions, and operate agents safely.
- [Agent management](/agent-management/overview.md): Govern AI agents, skills, and MCP access in Port so you can discover what exists, control permissions, and operate agents safely.
### port-mcp-server
#### available-tools
Reference for all tools exposed by the Port MCP Server, organized by developer and builder roles with detailed capabilities.
- [Available tools](/agent-management/port-mcp-server/available-tools.md): Reference for all tools exposed by the Port MCP Server, organized by developer and builder roles with detailed capabilities.
#### installation
Install and configure the Port MCP server so AI agents and LLMs can interact with your Port developer portal using natural language. Covers OAuth and client-credentials authentication for local and CI use.
- [Installation](/agent-management/port-mcp-server/installation.md): Install and configure the Port MCP server so AI agents and LLMs can interact with your Port developer portal using natural language. Covers OAuth and client-credentials authentication for local and CI use.
#### overview
Learn how the Port MCP server lets Claude, Cursor, and Copilot query your catalog and run governed actions from your IDE.
- [Port MCP server](/agent-management/port-mcp-server/overview.md): Learn how the Port MCP server lets Claude, Cursor, and Copilot query your catalog and run governed actions from your IDE.
#### token-based-authentication
Connect to the Port MCP server from CI/CD pipelines and headless agents using OAuth client credentials, without interactive user consent.
- [Machine authentication for the Port MCP server](/agent-management/port-mcp-server/token-based-authentication.md): Connect to the Port MCP server from CI/CD pipelines and headless agents using OAuth client credentials, without interactive user consent.
## interface-builder
### external-interfaces
Build your own external interface for Port: a custom web UI, tool, or integration that signs users in through Port and calls the Port API within that person's own role and permissions, backed by Port's context lake and governance layer.
- [External interfaces](/interface-builder/external-interfaces.md): Build your own external interface for Port: a custom web UI, tool, or integration that signs users in through Port and calls the Port API within that person's own role and permissions, backed by Port's context lake and governance layer.
### global-search
Search across entities, actions, blueprints, and tech docs using Cmd+K. Configure which blueprints appear in global search results.
- [Global search](/interface-builder/global-search.md): Search across entities, actions, blueprints, and tech docs using Cmd+K. Configure which blueprints appear in global search results.
### notifications
#### slack-app
Use Port's Slack app to interact with your developer portal and AI features directly from Slack, including notifications and catalog queries.
- [Slack Application](/interface-builder/notifications/slack-app.md): Use Port's Slack app to interact with your developer portal and AI features directly from Slack, including notifications and catalog queries.
### overview
Design Port catalog pages and dashboards where teams view live context and launch governed workflows from the same surface.
- [Interface builder](/interface-builder/overview.md): Design Port catalog pages and dashboards where teams view live context and launch governed workflows from the same surface.
### port-interface
#### customization
Customize your portal with organization branding, logos, announcement banners, and accessibility settings like high contrast mode.
- [Customization & accessibility](/interface-builder/port-interface/customization.md): Customize your portal with organization branding, logos, announcement banners, and accessibility settings like high contrast mode.
#### dashboards
##### custom-widgets
Add custom widgets including iframes for external content, markdown for formatted text, and action buttons to trigger self-service workflows.
- [Custom widgets](/interface-builder/port-interface/dashboards/custom-widgets.md): Add custom widgets including iframes for external content, markdown for formatted text, and action buttons to trigger self-service workflows.
##### data-widgets
Build data visualizations with number charts, pie charts, line charts, tables, and entity widgets. Supports aggregations, filtering, and conditional formatting.
- [Data widgets](/interface-builder/port-interface/dashboards/data-widgets.md): Build data visualizations with number charts, pie charts, line charts, tables, and entity widgets. Supports aggregations, filtering, and conditional formatting.
##### overview
Choose Port dashboard widgets for charts, tables, actions, and personal views to show catalog data on home and entity pages.
- [Overview](/interface-builder/port-interface/dashboards/overview.md): Choose Port dashboard widgets for charts, tables, actions, and personal views to show catalog data on home and entity pages.
##### personal-widgets
Add personal widgets to your home page showing your assigned entities, recently viewed items, and recently used actions.
- [Personal widgets](/interface-builder/port-interface/dashboards/personal-widgets.md): Add personal widgets to your home page showing your assigned entities, recently viewed items, and recently used actions.
#### page
##### catalog-page
Customize Port catalog pages with table views, filters, grouping, sorting, and widgets. Configure initial filters, hide properties, save views, and control page visibility by team or role.
- [Catalog page](/interface-builder/port-interface/page/catalog-page.md): Customize Port catalog pages with table views, filters, grouping, sorting, and widgets. Configure initial filters, hide properties, save views, and control page visibility by team or role.
##### dashboard-page
Create dashboard pages with customizable widgets to display aggregated entity data, charts, and visualizations in your software catalog. Apply dashboard filters and save filter presets to switch between views.
- [Dashboard page](/interface-builder/port-interface/page/dashboard-page.md): Create dashboard pages with customizable widgets to display aggregated entity data, charts, and visualizations in your software catalog. Apply dashboard filters and save filter presets to switch between views.
##### entity-page
Customize entity pages with Overview, Related entities, Runs, and Audit log tabs. Add widgets and configure property visibility.
- [Entity page](/interface-builder/port-interface/page/entity-page.md): Customize entity pages with Overview, Related entities, Runs, and Audit log tabs. Add widgets and configure property visibility.
##### folders
Organize your software catalog by grouping pages into folders. Supports nesting up to 3 levels and drag-and-drop reordering.
- [Folders](/interface-builder/port-interface/page/folders.md): Organize your software catalog by grouping pages into folders. Supports nesting up to 3 levels and drag-and-drop reordering.
##### page-permissions
Control who can view or edit catalog and dashboard pages using role-based permissions for users and teams.
- [Page permissions](/interface-builder/port-interface/page/page-permissions.md): Control who can view or edit catalog and dashboard pages using role-based permissions for users and teams.
##### private-pages
Create personal catalog and dashboard pages in a dedicated Private sidebar section. Configure who can create private pages, change visibility between organization and private, and manage permissions on your own pages.
- [Private pages](/interface-builder/port-interface/page/private-pages.md): Create personal catalog and dashboard pages in a dedicated Private sidebar section. Configure who can create private pages, change visibility between organization and private, and manage permissions on your own pages.
#### plugins
A plugin is a self-contained web UI, built from HTML, JavaScript, or a framework such as React, that you develop locally and upload to Port. Plugins power custom widgets that render inside dashboards and entity pages using the same catalog data and permissions as the rest of the platform.
- [Plugins](/interface-builder/port-interface/plugins.md): A plugin is a self-contained web UI, built from HTML, JavaScript, or a framework such as React, that you develop locally and upload to Port. Plugins power custom widgets that render inside dashboards and entity pages using the same catalog data and permissions as the rest of the platform.
## governance
### governance-across-pillars
#### overview
Port's access controls live in each pillar, not one screen. See how catalog, workflow, AI agent, and interface permissions fit together.
- [Governance across pillars](/governance/governance-across-pillars/overview.md): Port's access controls live in each pillar, not one screen. See how catalog, workflow, AI agent, and interface permissions fit together.
#### scope-building-permissions-across-teams-and-users
Scope who can build, run, and approve workflows and scorecards using team-based and dynamic RBAC, the same model that governs your catalog.
- [Scope building permissions across teams and users](/governance/governance-across-pillars/scope-building-permissions-across-teams-and-users.md): Scope who can build, run, and approve workflows and scorecards using team-based and dynamic RBAC, the same model that governs your catalog.
### overview
Scope what humans and agents can see and do in Port with scorecards, pillar permissions, and audit trails on every action.
- [Governance layer](/governance/overview.md): Scope what humans and agents can see and do in Port with scorecards, pillar permissions, and audit trails on every action.
### standards-and-compliance
#### concepts-and-structure
Understand scorecard concepts including levels, rules, conditions, and filters. Learn how scorecards are structured and how entities are evaluated against defined standards.
- [Concepts and structure](/governance/standards-and-compliance/concepts-and-structure.md): Understand scorecard concepts including levels, rules, conditions, and filters. Learn how scorecards are structured and how entities are evaluated against defined standards.
#### examples
##### automation-use-cases
Automate responses to scorecard rule changes including Slack/Teams notifications and GitHub issue creation. Includes automation configurations and GitHub workflow examples.
- [Automation use-cases](/governance/standards-and-compliance/examples/automation-use-cases.md): Automate responses to scorecard rule changes including Slack/Teams notifications and GitHub issue creation. Includes automation configurations and GitHub workflow examples.
##### extend-data-model
Extend scorecard blueprints with custom properties like SLA tracking and due dates. Build automated workflows for compliance monitoring, reminders, and exception handling.
- [Extend the default scorecards](/governance/standards-and-compliance/examples/extend-data-model.md): Extend scorecard blueprints with custom properties like SLA tracking and due dates. Build automated workflows for compliance monitoring, reminders, and exception handling.
##### scorecard-use-cases
Practical scorecard examples including ownership scorecards, relation existence checks, DORA metrics tracking, and agent dispatch guardrails. Ready-to-use JSON configurations you can implement immediately.
- [Scorecard use-cases](/governance/standards-and-compliance/examples/scorecard-use-cases.md): Practical scorecard examples including ownership scorecards, relation existence checks, DORA metrics tracking, and agent dispatch guardrails. Ready-to-use JSON configurations you can implement immediately.
#### manage-scorecard-groups
Define engineering standards once and apply them across multiple blueprints with scorecard groups. Create, edit, and delete groups using the API or Terraform.
- [Manage scorecard groups](/governance/standards-and-compliance/manage-scorecard-groups.md): Define engineering standards once and apply them across multiple blueprints with scorecard groups. Create, edit, and delete groups using the API or Terraform.
#### manage-scorecards
Create, edit, and delete Port scorecards using the UI, API, or Terraform. Includes step-by-step instructions and code examples for managing scorecards programmatically.
- [Manage scorecards](/governance/standards-and-compliance/manage-scorecards.md): Create, edit, and delete Port scorecards using the UI, API, or Terraform. Includes step-by-step instructions and code examples for managing scorecards programmatically.
#### manage-using-3rd-party-apps
Integrate Port scorecards with Jira, GitHub, and Slack for automated issue tracking and notifications. Overview of available third-party app integrations.
- [Manage using 3rd-party apps](/governance/standards-and-compliance/manage-using-3rd-party-apps.md): Integrate Port scorecards with Jira, GitHub, and Slack for automated issue tracking and notifications. Overview of available third-party app integrations.
##### github
Automatically create and close GitHub issues for violated scorecard rules using the Port message sender. Sync scorecard compliance with GitHub issue tracking.
- [Open/close GitHub issues](/governance/standards-and-compliance/manage-using-3rd-party-apps/github.md): Automatically create and close GitHub issues for violated scorecard rules using the Port message sender. Sync scorecard compliance with GitHub issue tracking.
##### jira
Automatically create and close Jira issues for violated scorecard rules using the Port message sender. Sync scorecard compliance with Jira task tracking.
- [Open/close JIRA issues](/governance/standards-and-compliance/manage-using-3rd-party-apps/jira.md): Automatically create and close Jira issues for violated scorecard rules using the Port message sender. Sync scorecard compliance with Jira task tracking.
##### slack
Send Slack reports and reminders for scorecard compliance using the Port message sender GitHub action. Includes examples of scorecard reports and reminders.
- [Send Slack messages](/governance/standards-and-compliance/manage-using-3rd-party-apps/slack.md): Send Slack reports and reminders for scorecard compliance using the Port message sender GitHub action. Includes examples of scorecard reports and reminders.
#### overview
Create scorecard rules and maturity levels that continuously measure services, teams, and resources against engineering standards.
- [Standards and compliance](/governance/standards-and-compliance/overview.md): Create scorecard rules and maturity levels that continuously measure services, teams, and resources against engineering standards.
## platform-administration
### audit-log
View a complete record of changes in your Port organization. Track entity, blueprint, action, automation, integration, and AI agent-triggered run modifications with filtering and export.
- [Audit log](/platform-administration/audit-log.md): View a complete record of changes in your Port organization. Track entity, blueprint, action, automation, integration, and AI agent-triggered run modifications with filtering and export.
### multi-org-management
#### manage-port-across-environments
Learn how to manage Port resources across multiple environments using IaC (Terraform), Git-based resource definitions, or Port CLI.
- [Manage Port across environments](/platform-administration/multi-org-management/manage-port-across-environments.md): Learn how to manage Port resources across multiple environments using IaC (Terraform), Git-based resource definitions, or Port CLI.
#### multi-org-sso
This page covers how to configure SSO when your Port company has multiple organizations, such as separate environments for development and production. It addresses common questions about IdP application registration, team synchronization, and RBAC across organizations.
- [Multi-org SSO setup](/platform-administration/multi-org-management/multi-org-sso.md): This page covers how to configure SSO when your Port company has multiple organizations, such as separate environments for development and production. It addresses common questions about IdP application registration, team synchronization, and RBAC across organizations.
#### multi-organization
Manage multiple Port organizations with cross-organization access. Create organizations, switch between them, and share users.
- [Multiple organization membership](/platform-administration/multi-org-management/multi-organization.md): Manage multiple Port organizations with cross-organization access. Create organizations, switch between them, and share users.
### overview
Administer your Port organization: users and teams, SSO and SCIM, secrets, audit logs, usage, and multi-organization setup.
- [Platform administration](/platform-administration/overview.md): Administer your Port organization: users and teams, SSO and SCIM, secrets, audit logs, usage, and multi-organization setup.
### plan-management
Learn about Port's plan types.
- [Plan management](/platform-administration/plan-management.md): Learn about Port's plan types.
### secrets-management
#### port-secrets
Manage Port API credentials (client ID, client secret) and organization secrets. Use secrets in integrations and automations with the {{ .secrets.SECRET_NAME }} template syntax.
- [Credentials & secrets](/platform-administration/secrets-management/port-secrets.md): Manage Port API credentials (client ID, client secret) and organization secrets. Use secrets in integrations and automations with the {{ .secrets.SECRET_NAME }} template syntax.
### security
Port security practices including SOC2 Type II, ISO 27001, GDPR compliance, data encryption, access controls, and infrastructure security.
- [Security & compliance](/platform-administration/security.md): Port security practices including SOC2 Type II, ISO 27001, GDPR compliance, data encryption, access controls, and infrastructure security.
### sso-authentication
#### manage-your-oauth-apps
An OAuth app lets an external interface sign people into your Port organization, in their own role and permissions. This page covers creating, updating, and revoking OAuth apps. For the concept and how access works, see External interfaces.
- [Manage your OAuth apps](/platform-administration/sso-authentication/manage-your-oauth-apps.md): An OAuth app lets an external interface sign people into your Port organization, in their own role and permissions. This page covers creating, updating, and revoking OAuth apps. For the concept and how access works, see External interfaces.
#### SCIM
SCIM provisioning is not self-serve. To enable it for your organization, contact Port support.
- [SCIM](/platform-administration/sso-authentication/SCIM.md): SCIM provisioning is not self-serve. To enable it for your organization, contact Port support.
#### self-serve-sso
Set up SSO in Port, connect your identity provider, verify domains, and configure group filters and session settings as an admin.
- [Manage your SSO connection](/platform-administration/sso-authentication/self-serve-sso.md): Set up SSO in Port, connect your identity provider, verify domains, and configure group filters and session settings as an admin.
#### sso-providers
Port offers several SSO integrations, allowing you to easily assign permissions and roles using your users and teams.
- [SSO providers](/platform-administration/sso-authentication/sso-providers.md): Port offers several SSO integrations, allowing you to easily assign permissions and roles using your users and teams.
##### ldap
Integrate any LDAP system with Port SSO
- [LDAP](/platform-administration/sso-authentication/sso-providers/ldap.md): Integrate any LDAP system with Port SSO
##### oidc
Integrate any SSO with Port using OIDC application
- [OIDC](/platform-administration/sso-authentication/sso-providers/oidc.md): Integrate any SSO with Port using OIDC application
- [Entra ID (AzureAD)](/platform-administration/sso-authentication/sso-providers/oidc/azure-ad.md): Integrate AzureAD with Port using OIDC
- [Okta](/platform-administration/sso-authentication/sso-providers/oidc/okta.md): Integrate Okta with Port
- [Onelogin](/platform-administration/sso-authentication/sso-providers/oidc/onelogin.md): Integrate Onelogin with Port
##### saml
Integrate any SSO with Port using SAML application
- [SAML](/platform-administration/sso-authentication/sso-providers/saml.md): Integrate any SSO with Port using SAML application
- [Entra ID (AzureAD)](/platform-administration/sso-authentication/sso-providers/saml/azure-ad.md): Integrate Entra ID (AzureAD) with Port using SAML
- [Google Workspace](/platform-administration/sso-authentication/sso-providers/saml/google-workspace.md): Integrate Google Workspace with Port using SAML
- [JumpCloud](/platform-administration/sso-authentication/sso-providers/saml/jumpcloud.md): Integrate JumpCloud with Port using SAML
- [Okta](/platform-administration/sso-authentication/sso-providers/saml/okta.md): Integrate Okta with Port using SAML
### usage-dashboard
Track portal usage metrics including user activity, entity counts, action execution, integration usage, and AI interactions. Updated daily.
- [Portal usage dashboard](/platform-administration/usage-dashboard.md): Track portal usage metrics including user activity, entity counts, action execution, integration usage, and AI interactions. Updated daily.
### users-and-teams
#### manage-users-teams
Manage users, teams, roles, and permissions in Port. Invite users, assign roles, create teams, and configure granular access controls.
- [Manage users & teams](/platform-administration/users-and-teams/manage-users-teams.md): Manage users, teams, roles, and permissions in Port. Invite users, assign roles, create teams, and configure granular access controls.
#### user-membership-reference
A complete reference for how users are added to organizations in Port — SSO, SCIM, invitations, member statuses, and edge cases.
- [User membership reference](/platform-administration/users-and-teams/user-membership-reference.md): A complete reference for how users are added to organizations in Port — SSO, SCIM, invitations, member statuses, and edge cases.
#### view-as-different-user
Test permissions by viewing the portal as a different user. Validate dynamic filters, role-based access, and page visibility without switching accounts.
- [View as a different user](/platform-administration/users-and-teams/view-as-different-user.md): Test permissions by viewing the portal as a different user. Validate dynamic filters, role-based access, and page visibility without switching accounts.
## Guides
Step-by-step tutorials and walkthroughs for specific Port use cases. These guides show you how to implement common scenarios with Port. For API reference and concept documentation, see the reference sections in /context-lake/ and /api-reference/.
- [Guides](/guides.md): Step-by-step tutorials and walkthroughs for specific Port use cases. These guides show you how to implement common scenarios with Port. For API reference and concept documentation, see the reference sections in /context-lake/ and /api-reference/.
### All guides
#### add-tags-to-aws-resources
Enable agents and developers to add tags to AWS S3 buckets and ECR repositories through governed Port workflows.
- [Add tags to AWS resources](/guides/all/add-tags-to-aws-resources.md): Enable agents and developers to add tags to AWS S3 buckets and ECR repositories through governed Port workflows.
#### ai-powered-github-workflow-documentation
Enable agents and developers to automatically generate and maintain human-readable documentation for GitHub Actions workflows using Port's AI agents and automation system.
- [Auto-generate GitHub workflow documentation](/guides/all/ai-powered-github-workflow-documentation.md): Enable agents and developers to automatically generate and maintain human-readable documentation for GitHub Actions workflows using Port's AI agents and automation system.
#### ai-powered-incident-management
Enable agents and developers to implement an AI-powered incident management lifecycle in Port, from triage and orchestration to incident updates, RCA, and postmortems.
- [AI-powered incident management](/guides/all/ai-powered-incident-management.md): Enable agents and developers to implement an AI-powered incident management lifecycle in Port, from triage and orchestration to incident updates, RCA, and postmortems.
#### apply-labels-to-github-pr-based-on-sonar-scans
Enable agents and developers to automatically label your GitHub pull request based on SonarQube scan reports.
- [Auto-label your GitHub PRs with Sonar Scans](/guides/all/apply-labels-to-github-pr-based-on-sonar-scans.md): Enable agents and developers to automatically label your GitHub pull request based on SonarQube scan reports.
#### approval-workflow-for-gitlab-deployment
Enable agents and developers to govern GitLab deployments with Port workflows and ServiceNow approvals.
- [Approval workflows for service deployment](/guides/all/approval-workflow-for-gitlab-deployment.md): Enable agents and developers to govern GitLab deployments with Port workflows and ServiceNow approvals.
#### assign-pr-reviewers-with-claude
Enable agents and developers to automatically assess pull request risk, assign reviewers, comment, and auto-approve low-risk changes using a Claude managed agent triggered from a Port workflow.
- [Assign PR reviewers with a Claude managed agent](/guides/all/assign-pr-reviewers-with-claude.md): Enable agents and developers to automatically assess pull request risk, assign reviewers, comment, and auto-approve low-risk changes using a Claude managed agent triggered from a Port workflow.
#### auto-assign-bugs-to-owners
Enable agents and developers to automatically assign Jira bugs to owning teams and services with Port automations and AI.
- [Auto-assign bugs to owners with AI](/guides/all/auto-assign-bugs-to-owners.md): Enable agents and developers to automatically assign Jira bugs to owning teams and services with Port automations and AI.
#### auto-enhance-pr-descriptions-with-ai
Enable agents and developers to automatically enhance PR descriptions with AI-generated, template-compliant content using a Port workflow, an AI agent, and coding assistants.
- [Auto-enhance PR descriptions with AI](/guides/all/auto-enhance-pr-descriptions-with-ai.md): Enable agents and developers to automatically enhance PR descriptions with AI-generated, template-compliant content using a Port workflow, an AI agent, and coding assistants.
#### auto-remediate-insecure-cloud-resources-with-ai
Enable agents and developers to automatically detect and remediate insecure cloud resources using Port workflows and Claude Code to generate infrastructure-as-code patches.
- [Auto-remediate insecure cloud resources with AI](/guides/all/auto-remediate-insecure-cloud-resources-with-ai.md): Enable agents and developers to automatically detect and remediate insecure cloud resources using Port workflows and Claude Code to generate infrastructure-as-code patches.
#### automate-slack-alert-for-overdue-prs
Enable agents and developers to keep pull request reviews moving with automated Slack alerts for overdue pull requests.
- [Automate Slack Alert for Overdue PRs](/guides/all/automate-slack-alert-for-overdue-prs.md): Enable agents and developers to keep pull request reviews moving with automated Slack alerts for overdue pull requests.
#### automate-user-role-update
Enable agents and developers to maintain governed Port access by assigning the Admin role when users join an administrators team.
- [Automate admin role assignment](/guides/all/automate-user-role-update.md): Enable agents and developers to maintain governed Port access by assigning the Admin role when users join an administrators team.
#### automatically-approve-action-using-automation
Enable agents and developers to govern routine requests with automated approvals for Port self-service actions.
- [Automate self-service action approvals](/guides/all/automatically-approve-action-using-automation.md): Enable agents and developers to govern routine requests with automated approvals for Port self-service actions.
#### automatically-resolve-tickets
Enable agents and developers to resolve Jira tickets with coding agents through governed Port workflows or an n8n workflow enriched by Port context.
- [Automatically resolve tickets with Port](/guides/all/automatically-resolve-tickets.md): Enable agents and developers to resolve Jira tickets with coding agents through governed Port workflows or an n8n workflow enriched by Port context.
#### automatically-set-relations-between-entities-with-automation
Enable agents and developers to link service entities to owning teams through Port automations without custom integration code.
- [Automatically set relations between entities with automation](/guides/all/automatically-set-relations-between-entities-with-automation.md): Enable agents and developers to link service entities to owning teams through Port automations without custom integration code.
#### avoid-duplicate-skills-in-your-org-registry
Catch duplicate skills before they reach the registry: flag a similar skill while it's being published, score uniqueness during certification, and surface both on your dashboards.
- [Avoid duplicate skills in your org registry](/guides/all/avoid-duplicate-skills-in-your-org-registry.md): Catch duplicate skills before they reach the registry: flag a similar skill while it's being published, score uniqueness during certification, and surface both on your dashboards.
#### azure-resource-tagging-initiative
Enable agents and developers to track and enforce Azure resource tagging compliance using Port scorecards, dashboards, and self-service actions.
- [Track Azure resource tagging compliance](/guides/all/azure-resource-tagging-initiative.md): Enable agents and developers to track and enforce Azure resource tagging compliance using Port scorecards, dashboards, and self-service actions.
#### build-ai-agent-registry
Enable agents and developers to build a centralized AI Agent Registry in Port to discover, govern, and manage AI agents deployed across AWS Bedrock and Azure AI Foundry.
- [Build an AI Agent Registry](/guides/all/build-ai-agent-registry.md): Enable agents and developers to build a centralized AI Agent Registry in Port to discover, govern, and manage AI agents deployed across AWS Bedrock and Azure AI Foundry.
#### build-github-dashboards-in-port
Enable agents and developers to build GitHub dashboards in Port for dependency security, identity and access, repository activity, and engineering metrics.
- [Build GitHub dashboards in Port](/guides/all/build-github-dashboards-in-port.md): Enable agents and developers to build GitHub dashboards in Port for dependency security, identity and access, repository activity, and engineering metrics.
#### build-port-with-mcp
Use the Port MCP server with your assistant to create blueprints, actions, automations, and scorecards from described outcomes.
- [Build and configure Port using the MCP server](/guides/all/build-port-with-mcp.md): Use the Port MCP server with your assistant to create blueprints, actions, automations, and scorecards from described outcomes.
#### build-port-workflows-with-mcp
Use AI and Port's MCP server to build Port workflows through natural language conversations, designing multi-step node graphs without hand-writing workflow JSON.
- [Build workflows with AI](/guides/all/build-port-workflows-with-mcp.md): Use AI and Port's MCP server to build Port workflows through natural language conversations, designing multi-step node graphs without hand-writing workflow JSON.
#### bundle-skills-into-plugins-in-your-org-registry
Group related skills into installable plugins: ingest the plugins already in your GitHub repo, get an AI-driven suggestion when a certified skill belongs in one, and apply it through a self-service workflow.
- [Bundle skills into plugins](/guides/all/bundle-skills-into-plugins-in-your-org-registry.md): Group related skills into installable plugins: ingest the plugins already in your GitHub repo, get an AI-driven suggestion when a certified skill belongs in one, and apply it through a self-service workflow.
#### calculate-blast-radius-with-ai
Enable agents and developers to calculate deployment blast radius and production risk using AI, service dependencies, and Port workflows.
- [Calculate blast radius with AI](/guides/all/calculate-blast-radius-with-ai.md): Enable agents and developers to calculate deployment blast radius and production risk using AI, service dependencies, and Port workflows.
#### certify-skills-to-meet-industry-and-org-standards
Certify skills against deterministic and non-deterministic standards, starting with description quality, the one property that decides whether an agent ever calls a skill at all.
- [Certify skills to meet industry and org standards](/guides/all/certify-skills-to-meet-industry-and-org-standards.md): Certify skills against deterministic and non-deterministic standards, starting with description quality, the one property that decides whether an agent ever calls a skill at all.
#### connect-github-codeowners-with-service-team-and-user
Enable agents and developers to connect GitHub CODEOWNERS with Port repositories, teams, and users for governed ownership context.
- [Connect GitHub CODEOWNERS with Repository, Team & User](/guides/all/connect-github-codeowners-with-service-team-and-user.md): Enable agents and developers to connect GitHub CODEOWNERS with Port repositories, teams, and users for governed ownership context.
#### connect-github-pr-with-jira-issue
Enable agents and developers to trace delivery work by connecting GitHub pull requests to Jira issues in Port.
- [Connect GitHub Pull Request with Jira Issue](/guides/all/connect-github-pr-with-jira-issue.md): Enable agents and developers to trace delivery work by connecting GitHub pull requests to Jira issues in Port.
#### copy-pipeline-template-to-target-repo
Enable agents and developers to copy pipeline template from one repository to another using Port Actions.
- [Copy Pipeline Template to Target Repo](/guides/all/copy-pipeline-template-to-target-repo.md): Enable agents and developers to copy pipeline template from one repository to another using Port Actions.
#### create-an-ec2-instance
Enable agents and developers to create an EC2 instance in Port using GitHub Actions or GitLab CI.
- [Create an AWS EC2 instance](/guides/all/create-an-ec2-instance.md): Enable agents and developers to create an EC2 instance in Port using GitHub Actions or GitLab CI.
#### create-cloud-resource-using-iac
Enable agents and developers to create cloud resources using Infrastructure as Code (IaC) in Port for efficient and automated deployments.
- [Create cloud resources using IaC](/guides/all/create-cloud-resource-using-iac.md): Enable agents and developers to create cloud resources using Infrastructure as Code (IaC) in Port for efficient and automated deployments.
#### create-engineering-intelligence-pulse
Enable agents and developers to run a weekly Engineering Intelligence assessment that ranks the engineering improvements worth making, records each one with its evidence, and publishes a brief to Slack.
- [Create the Engineering Intelligence Pulse](/guides/all/create-engineering-intelligence-pulse.md): Enable agents and developers to run a weekly Engineering Intelligence assessment that ranks the engineering improvements worth making, records each one with its evidence, and publishes a brief to Slack.
#### create-github-copilot-ai-usage-dashboard-custom-plugin
Enable agents and developers to track GitHub Copilot adoption, acceptance rates, and AI-generated insights with a Port custom plugin.
- [Measure GitHub Copilot adoption and usage with plugins](/guides/all/create-github-copilot-ai-usage-dashboard-custom-plugin.md): Enable agents and developers to track GitHub Copilot adoption, acceptance rates, and AI-generated insights with a Port custom plugin.
#### create-incident-io-incident
Enable agents and developers to initiate incident.io response through governed Port self-service actions.
- [Create an incident.io Incident](/guides/all/create-incident-io-incident.md): Enable agents and developers to initiate incident.io response through governed Port self-service actions.
#### create-jira-issue-from-datadog-alert
Enable agents and developers to create Jira issues from Datadog and other alerts through governed Port workflows and Jira webhooks.
- [Create a Jira issue from a monitoring alert](/guides/all/create-jira-issue-from-datadog-alert.md): Enable agents and developers to create Jira issues from Datadog and other alerts through governed Port workflows and Jira webhooks.
#### create-jira-issue-gitlab
Enable agents and developers to create Jira issues through a governed Port self-service action backed by GitLab CI.
- [Create a Jira issue using GitLab CI](/guides/all/create-jira-issue-gitlab.md): Enable agents and developers to create Jira issues through a governed Port self-service action backed by GitLab CI.
#### create-new-aws-account-gitlab
Enable agents and developers to provision AWS accounts through a governed Port workflow that validates the request with AI and provisions it with GitLab CI/CD and Terraform.
- [Automate AWS account creation with GitLab](/guides/all/create-new-aws-account-gitlab.md): Enable agents and developers to provision AWS accounts through a governed Port workflow that validates the request with AI and provisions it with GitLab CI/CD and Terraform.
#### create-organizational-hierarchy-views
Enable agents and developers to model and visualize hierarchy tiers in your organization.
- [Create organizational hierarchy views](/guides/all/create-organizational-hierarchy-views.md): Enable agents and developers to model and visualize hierarchy tiers in your organization.
#### create-roi-dashboard
Enable agents and developers to create a dashboard that tracks the ROI of actions in Port.
- [Create an actions ROI dashboard](/guides/all/create-roi-dashboard.md): Enable agents and developers to create a dashboard that tracks the ROI of actions in Port.
#### create-slack-channel-for-reported-incident-with-port-workflows
Learn how to automatically create a Slack channel and GitHub issue when a PagerDuty incident is reported, using Port Workflows for real-time team communication and incident documentation.
- [Auto-create Slack channel & GitHub issue for PagerDuty incidents](/guides/all/create-slack-channel-for-reported-incident-with-port-workflows.md): Learn how to automatically create a Slack channel and GitHub issue when a PagerDuty incident is reported, using Port Workflows for real-time team communication and incident documentation.
#### create-slack-channel-for-reported-incident
Enable agents and developers to coordinate PagerDuty response by creating a Slack channel and GitHub issue automatically through Port.
- [Auto-create Slack channel & GitHub issue for PagerDuty incidents](/guides/all/create-slack-channel-for-reported-incident.md): Enable agents and developers to coordinate PagerDuty response by creating a Slack channel and GitHub issue automatically through Port.
#### create-survey-intelligence
Enable agents and developers to deploy the Survey Intelligence plugins (Survey Builder, Survey Forms, and Survey Analytics) to run engineering surveys and turn responses into insights.
- [Create Survey Intelligence](/guides/all/create-survey-intelligence.md): Enable agents and developers to deploy the Survey Intelligence plugins (Survey Builder, Survey Forms, and Survey Analytics) to run engineering surveys and turn responses into insights.
#### deploy-azure-resource-with-terraform
Enable agents and developers to deploy Azure storage accounts with Terraform from Port using GitHub Actions, Azure DevOps, or Jenkins.
- [Deploy Azure resource with Terraform](/guides/all/deploy-azure-resource-with-terraform.md): Enable agents and developers to deploy Azure storage accounts with Terraform from Port using GitHub Actions, Azure DevOps, or Jenkins.
#### deploy-s3-bucket-crossplane
Enable agents and developers to provision S3 buckets through governed Port workflows backed by Crossplane.
- [Deploy S3 Bucket using Crossplane](/guides/all/deploy-s3-bucket-crossplane.md): Enable agents and developers to provision S3 buckets through governed Port workflows backed by Crossplane.
#### enrich-tasks-with-ai
Enable agents and developers to enrich tasks with AI-powered context using Port workflows, providing developers with automated insights, related issues, and potential collaborators.
- [Enrich tasks with AI-powered context](/guides/all/enrich-tasks-with-ai.md): Enable agents and developers to enrich tasks with AI-powered context using Port workflows, providing developers with automated insights, related issues, and potential collaborators.
#### ensure-production-readiness
Enable agents and developers to ensure production readiness in Port, optimizing your deployments for reliability and performance.
- [Ensure production readiness](/guides/all/ensure-production-readiness.md): Enable agents and developers to ensure production readiness in Port, optimizing your deployments for reliability and performance.
#### find-internal-documentation-with-ai
Enable agents and developers to find internal documentation with AI.
- [Find internal documentation with AI](/guides/all/find-internal-documentation-with-ai.md): Enable agents and developers to find internal documentation with AI.
#### generate-zendesk-ticket-summaries-with-ai
Summarize Zendesk tickets using workflows that fetches ticket comments and side conversations, then uses Port AI to produce a structured summary.
- [Summarize Zendesk tickets with AI](/guides/all/generate-zendesk-ticket-summaries-with-ai.md): Summarize Zendesk tickets using workflows that fetches ticket comments and side conversations, then uses Port AI to produce a structured summary.
#### heal-unhealthy-k8s-pods
Build a single Port workflow that detects unhealthy Kubernetes workloads, diagnoses them with Port AI, and applies targeted fixes automatically.
- [Auto-heal unhealthy Kubernetes pods with Port workflows](/guides/all/heal-unhealthy-k8s-pods.md): Build a single Port workflow that detects unhealthy Kubernetes workloads, diagnoses them with Port AI, and applies targeted fixes automatically.
#### iam-permissions-guide
Enable agents and developers to request time-bound AWS IAM permissions through governed Port workflows and automated revocation.
- [IAM permission management](/guides/all/iam-permissions-guide.md): Enable agents and developers to request time-bound AWS IAM permissions through governed Port workflows and automated revocation.
#### implement-rbac-for-ai-agents-with-n8n-and-port
Enable agents and developers to enforce role-based tool access for AI agents using Port and n8n.
- [RBAC for AI agents with n8n and Port](/guides/all/implement-rbac-for-ai-agents-with-n8n-and-port.md): Enable agents and developers to enforce role-based tool access for AI agents using Port and n8n.
#### incident-blueprint
Enable agents and developers to implement the incident blueprint pattern for self-healing incident workflows.
- [Implement the incident blueprint pattern](/guides/all/incident-blueprint.md): Enable agents and developers to implement the incident blueprint pattern for self-healing incident workflows.
#### ingest-claude-code-security-reviews
Enable agents and developers to ingest Claude Code security review findings and visualize them in Port dashboards.
- [Ingest Claude Code security reviews](/guides/all/ingest-claude-code-security-reviews.md): Enable agents and developers to ingest Claude Code security review findings and visualize them in Port dashboards.
#### ingest-cloud-resources-using-apm-integrations
Enable agents and developers to ingest cloud resources monitored by Datadog, Dynatrace, or New Relic into Port.
- [Ingest cloud resources using APM integrations](/guides/all/ingest-cloud-resources-using-apm-integrations.md): Enable agents and developers to ingest cloud resources monitored by Datadog, Dynatrace, or New Relic into Port.
#### ingest-data-via-airbyte-and-s3
Enable agents and developers to ingest HiBob or Okta data into Port using Airbyte, Amazon S3, and a custom webhook integration.
- [Ingest data via Airbyte and S3](/guides/all/ingest-data-via-airbyte-and-s3.md): Enable agents and developers to ingest HiBob or Okta data into Port using Airbyte, Amazon S3, and a custom webhook integration.
#### ingest-dotnet-framework-versions
Enable agents and developers to ingest .NET framework versions from .csproj files and track them across your repositories using Port.
- [Ingest .NET framework versions from repositories](/guides/all/ingest-dotnet-framework-versions.md): Enable agents and developers to ingest .NET framework versions from .csproj files and track them across your repositories using Port.
#### ingest-gitlab-vulnerabilities-into-your-context-lake
Enable agents and developers to centralize GitLab SAST, DAST, dependency, and container findings by team and service in Port's context lake.
- [Ingest GitLab security vulnerabilities into your context lake](/guides/all/ingest-gitlab-vulnerabilities-into-your-context-lake.md): Enable agents and developers to centralize GitLab SAST, DAST, dependency, and container findings by team and service in Port's context lake.
#### ingest-linearb-metrics-into-your-context-lake
Enable agents and developers to consolidate LinearB engineering metrics into Port's Engineering Intelligence platform, leveraging Port's native analytics alongside imported data for a unified view of engineering performance.
- [Ingest LinearB metrics into your context lake](/guides/all/ingest-linearb-metrics-into-your-context-lake.md): Enable agents and developers to consolidate LinearB engineering metrics into Port's Engineering Intelligence platform, leveraging Port's native analytics alongside imported data for a unified view of engineering performance.
#### ingest-prompts-skills-from-github-using-gitops
Enable agents and developers to ingest AI prompts and skills from GitHub using GitOps by mapping repo files to Port blueprints.
- [Ingest prompts and skills from GitHub using GitOps](/guides/all/ingest-prompts-skills-from-github-using-gitops.md): Enable agents and developers to ingest AI prompts and skills from GitHub using GitOps by mapping repo files to Port blueprints.
#### ingest-repository-files-into-your-context-lake
Enable agents and developers to parse package manifests, API specifications, SBOMs, SARIF files, and security scan results from repositories into Port.
- [Ingest repository files into your context lake](/guides/all/ingest-repository-files-into-your-context-lake.md): Enable agents and developers to parse package manifests, API specifications, SBOMs, SARIF files, and security scan results from repositories into Port.
#### ingest-slack-data-via-airbyte-s3-and-webhook
Enable agents and developers to ingest Slack channels, users, and memberships into Port using Airbyte or Fivetran, S3, and a webhook integration.
- [Ingest Slack data into Port](/guides/all/ingest-slack-data-via-airbyte-s3-and-webhook.md): Enable agents and developers to ingest Slack channels, users, and memberships into Port using Airbyte or Fivetran, S3, and a webhook integration.
#### ingest-swarmia-metrics-into-your-context-lake
Enable agents and developers to consolidate Swarmia DORA and pull request metrics into Port's Engineering Intelligence platform, leveraging Port's native analytics alongside imported data for a unified view of engineering performance.
- [Ingest Swarmia metrics into your context lake](/guides/all/ingest-swarmia-metrics-into-your-context-lake.md): Enable agents and developers to consolidate Swarmia DORA and pull request metrics into Port's Engineering Intelligence platform, leveraging Port's native analytics alongside imported data for a unified view of engineering performance.
#### ingest-vulnerability-alerts-from-orca-security-using-a-custom-webhook-integration
Enable agents and developers to investigate Orca Security vulnerabilities by ingesting historical and real-time alerts into Port.
- [Ingest vulnerability alerts from Orca Security](/guides/all/ingest-vulnerability-alerts-from-orca-security-using-a-custom-webhook-integration.md): Enable agents and developers to investigate Orca Security vulnerabilities by ingesting historical and real-time alerts into Port.
#### interact-with-pagerduty-incidents
Learn how to create, trigger, reassign, and resolve PagerDuty incidents from Port using a single native workflow, and keep your catalog in sync.
- [Interact with PagerDuty incidents](/guides/all/interact-with-pagerduty-incidents.md): Learn how to create, trigger, reassign, and resolve PagerDuty incidents from Port using a single native workflow, and keep your catalog in sync.
#### interact-with-servicenow
Enable agents and developers to create, update, trigger, and delete ServiceNow records and incidents using Port workflows.
- [Interact with ServiceNow records & incidents](/guides/all/interact-with-servicenow.md): Enable agents and developers to create, update, trigger, and delete ServiceNow records and incidents using Port workflows.
#### keep-azure-catalog-upto-date-with-incremental-syncing
Enable agents and developers to keep your Azure catalog up to date by syncing only changed resources into Port using GitHub Actions or a local script.
- [Keep your Azure catalog up to date with incremental syncing](/guides/all/keep-azure-catalog-upto-date-with-incremental-syncing.md): Enable agents and developers to keep your Azure catalog up to date by syncing only changed resources into Port using GitHub Actions or a local script.
#### let-developers-enrich-services-using-gitops
Enable agents and developers to enrich service context through Git-managed repository metadata ingested into Port.
- [Enrich services using GitOps](/guides/all/let-developers-enrich-services-using-gitops.md): Enable agents and developers to enrich service context through Git-managed repository metadata ingested into Port.
#### lock-and-unlock-services-in-port
Enable agents and developers to govern deployments with Port service locks and automated GitHub workflow checks.
- [Lock and unlock services](/guides/all/lock-and-unlock-services-in-port.md): Enable agents and developers to govern deployments with Port service locks and automated GitHub workflow checks.
#### manage-and-surface-technical-docs
Enable agents and developers to manage and surface technical documentation in Port by ingesting markdown from a Git source, displaying it on service or repository pages, and adding the TechDocs plugin.
- [Manage and surface technical documentation in Port](/guides/all/manage-and-surface-technical-docs.md): Enable agents and developers to manage and surface technical documentation in Port by ingesting markdown from a Git source, displaying it on service or repository pages, and adding the TechDocs plugin.
#### manage-and-visualize-cloud-resources
Enable agents and developers to manage and visualize AWS, Azure, and GCP cloud resources in Port using integrations, self-service actions, and dashboards.
- [Manage and visualize cloud resources](/guides/all/manage-and-visualize-cloud-resources.md): Enable agents and developers to manage and visualize AWS, Azure, and GCP cloud resources in Port using integrations, self-service actions, and dashboards.
#### manage-and-visualize-jira-issues
Enable agents and developers to monitor and manage Jira issues using dashboards, labels, and self-service actions in Port.
- [Manage and visualize your Jira issues](/guides/all/manage-and-visualize-jira-issues.md): Enable agents and developers to monitor and manage Jira issues using dashboards, labels, and self-service actions in Port.
#### manage-and-visualize-pagerduty-incidents
Enable agents and developers to manage your PagerDuty incidents with self-service actions and monitor them using dashboards in Port.
- [Manage and visualize your PagerDuty incidents](/guides/all/manage-and-visualize-pagerduty-incidents.md): Enable agents and developers to manage your PagerDuty incidents with self-service actions and monitor them using dashboards in Port.
#### manage-and-visualize-your-launchdarkly-feature-flags
Enable agents and developers to manage and visualize your LaunchDarkly feature flags using dashboards and self-service actions in Port.
- [Manage and visualize your LaunchDarkly feature flags](/guides/all/manage-and-visualize-your-launchdarkly-feature-flags.md): Enable agents and developers to manage and visualize your LaunchDarkly feature flags using dashboards and self-service actions in Port.
#### manage-argocd-applications
Enable agents and developers to sync, restart, and self-heal Argo CD applications from Port using governed workflows, Port AI diagnosis, and GitHub Actions backends.
- [Manage Argo CD applications](/guides/all/manage-argocd-applications.md): Enable agents and developers to sync, restart, and self-heal Argo CD applications from Port using governed workflows, Port AI diagnosis, and GitHub Actions backends.
#### manage-clusters
Enable agents and developers to provision and manage Kubernetes clusters through governed Port workflows backed by Crossplane and Argo CD.
- [Create and manage Kubernetes clusters](/guides/all/manage-clusters.md): Enable agents and developers to provision and manage Kubernetes clusters through governed Port workflows backed by Crossplane and Argo CD.
#### manage-developer-environments
Enable agents and developers to create, extend, and tear down developer environments through governed Port workflows backed by GitHub Actions.
- [Manage developer environments](/guides/all/manage-developer-environments.md): Enable agents and developers to create, extend, and tear down developer environments through governed Port workflows backed by GitHub Actions.
#### manage-firehydrant-incidents
Enable agents and developers to manage FireHydrant incidents through governed Port actions while keeping incident context synchronized.
- [Manage FireHydrant incidents](/guides/all/manage-firehydrant-incidents.md): Enable agents and developers to manage FireHydrant incidents through governed Port actions while keeping incident context synchronized.
#### manage-humanitec-applications
Enable agents and developers to ingest Humanitec resources into Port and manage Humanitec applications with self-service actions.
- [Manage Humanitec applications](/guides/all/manage-humanitec-applications.md): Enable agents and developers to ingest Humanitec resources into Port and manage Humanitec applications with self-service actions.
#### manage-incident-lifecycle
Enable agents and developers to create governed self-service actions to acknowledge, escalate, and resolve PagerDuty incidents from Port.
- [Manage incident lifecycle](/guides/all/manage-incident-lifecycle.md): Enable agents and developers to create governed self-service actions to acknowledge, escalate, and resolve PagerDuty incidents from Port.
#### manage-kubernetes-namespaces
Enable agents and developers to create and manage Kubernetes namespaces through Port with automated workflows, approval processes, and chained self-service actions.
- [Manage Kubernetes namespaces](/guides/all/manage-kubernetes-namespaces.md): Enable agents and developers to create and manage Kubernetes namespaces through Port with automated workflows, approval processes, and chained self-service actions.
#### manage-mcp-registry
Enable agents and developers to build a governed MCP server registry in Port using workflows, MCP connectors, a dashboard, and an AI assistant, so teams can request, review, and discover approved MCP servers.
- [Manage MCP server registry](/guides/all/manage-mcp-registry.md): Enable agents and developers to build a governed MCP server registry in Port using workflows, MCP connectors, a dashboard, and an AI assistant, so teams can request, review, and discover approved MCP servers.
#### manage-pagerduty-on-call-schedules
Enable agents and developers to manage and track PagerDuty on-call schedules across teams and services with dashboards and Port workflows.
- [Manage PagerDuty on-call schedules](/guides/all/manage-pagerduty-on-call-schedules.md): Enable agents and developers to manage and track PagerDuty on-call schedules across teams and services with dashboards and Port workflows.
#### manage-pull-requests
Enable agents and developers to manage GitHub pull requests from Port using a workflow that dispatches a GitHub Actions pipeline to close, merge, or approve PRs.
- [Manage GitHub pull requests](/guides/all/manage-pull-requests.md): Enable agents and developers to manage GitHub pull requests from Port using a workflow that dispatches a GitHub Actions pipeline to close, merge, or approve PRs.
#### manage-your-eks-clusters
Enable agents and developers to create, request, deploy to, tag, and delete Amazon EKS clusters using Port workflows.
- [Manage EKS clusters](/guides/all/manage-your-eks-clusters.md): Enable agents and developers to create, request, deploy to, tag, and delete Amazon EKS clusters using Port workflows.
#### manage-your-kubernetes-deployment
Restart Kubernetes deployments, change replica counts, and delete pods with a self-service Port workflow that dispatches GitHub Actions through the GitHub Ocean integration.
- [Manage your Kubernetes deployments](/guides/all/manage-your-kubernetes-deployment.md): Restart Kubernetes deployments, change replica counts, and delete pods with a self-service Port workflow that dispatches GitHub Actions through the GitHub Ocean integration.
#### map-external-users-and-teams-to-port-accounts
Enable agents and developers to link external user and team identities to Port accounts for accurate ownership, access, and workflow routing.
- [Map external tool users and teams to Port accounts](/guides/all/map-external-users-and-teams-to-port-accounts.md): Enable agents and developers to link external user and team identities to Port accounts for accurate ownership, access, and workflow routing.
#### map-prs-to-services-in-monorepo
Enable agents and developers to automatically map pull requests to services in a monorepo using file path analysis.
- [Map PRs to services in a monorepo](/guides/all/map-prs-to-services-in-monorepo.md): Enable agents and developers to automatically map pull requests to services in a monorepo using file path analysis.
#### measure-ai-feedback
Enable agents and developers to collect and analyze feedback on AI tools using Port actions, automations, and AI agents to measure effectiveness and guide adoption decisions.
- [Measure AI feedback](/guides/all/measure-ai-feedback.md): Enable agents and developers to collect and analyze feedback on AI tools using Port actions, automations, and AI agents to measure effectiveness and guide adoption decisions.
#### measure-pipeline-reliability
Enable agents and developers to measure CI/CD pipeline reliability at service and team level, including failure rates, failure trends, and failing pipeline identification, using Port's integrations and dashboards.
- [Measure pipeline reliability](/guides/all/measure-pipeline-reliability.md): Enable agents and developers to measure CI/CD pipeline reliability at service and team level, including failure rates, failure trends, and failing pipeline identification, using Port's integrations and dashboards.
#### measure-pr-delivery-metrics
Enable agents and developers to measure PR and MR delivery metrics at service and team level, including cycle time, throughput, stale PRs/MRs, and reviewer coverage, using Port's GitHub Ocean or GitLab integration and dashboards.
- [Measure PR delivery metrics](/guides/all/measure-pr-delivery-metrics.md): Enable agents and developers to measure PR and MR delivery metrics at service and team level, including cycle time, throughput, stale PRs/MRs, and reviewer coverage, using Port's GitHub Ocean or GitLab integration and dashboards.
#### measure-pull-request-standards
Enable agents and developers to implement working agreements and measure pull request standards using Port scorecards and aggregation properties, tracking team performance based on PR metrics like review time, approval count, and merge latency.
- [Measuring pull request standards](/guides/all/measure-pull-request-standards.md): Enable agents and developers to implement working agreements and measure pull request standards using Port scorecards and aggregation properties, tracking team performance based on PR metrics like review time, approval count, and merge latency.
#### measure-reliability-and-stability
Enable agents and developers to measure reliability and stability of your delivery pipeline by tracking workflow failure rates and PRs blocked by failing CI/CD using Port's GitHub integration.
- [Measure delivery reliability and stability](/guides/all/measure-reliability-and-stability.md): Enable agents and developers to measure reliability and stability of your delivery pipeline by tracking workflow failure rates and PRs blocked by failing CI/CD using Port's GitHub integration.
#### measure-sprint-health-with-jira
Enable agents and developers to evaluate sprint health using Jira metrics, Port dashboards, and scorecards.
- [Measure sprint health with Jira](/guides/all/measure-sprint-health-with-jira.md): Enable agents and developers to evaluate sprint health using Jira metrics, Port dashboards, and scorecards.
#### measure-standards
Enable agents and developers to measure standards compliance across your software delivery, tracking quality, security, and organizational alignment using Port's GitHub integration and scorecards.
- [Track standards adherence](/guides/all/measure-standards.md): Enable agents and developers to measure standards compliance across your software delivery, tracking quality, security, and organizational alignment using Port's GitHub integration and scorecards.
#### measure-the-roi-of-skills-in-your-org-registry
Measure whether skills in your registry are worth their cost by connecting real Claude skill-usage and spend data to a Skill ROI scorecard and dashboard.
- [Measure the ROI of skills in your org registry](/guides/all/measure-the-roi-of-skills-in-your-org-registry.md): Measure whether skills in your registry are worth their cost by connecting real Claude skill-usage and spend data to a Skill ROI scorecard and dashboard.
#### migrate-project-from-github-to-gitlab
Enable agents and developers to migrate repositories from GitHub to GitLab using a Port workflow and GitHub Actions.
- [Migrate repositories from GitHub to GitLab using Port workflows](/guides/all/migrate-project-from-github-to-gitlab.md): Enable agents and developers to migrate repositories from GitHub to GitLab using a Port workflow and GitHub Actions.
#### monitor-integrations
Enable agents and developers to monitor and manage your Port Ocean integrations for improved visibility and performance tracking.
- [Monitor integrations](/guides/all/monitor-integrations.md): Enable agents and developers to monitor and manage your Port Ocean integrations for improved visibility and performance tracking.
#### move-port-configurations-between-environments-with-port-ai-and-github-mcp
Enable agents and developers to back up Port blueprints and actions to GitHub from one environment and import them into another environment using Port AI and GitHub MCP.
- [Sync Port configurations between environments using Port AI and MCP](/guides/all/move-port-configurations-between-environments-with-port-ai-and-github-mcp.md): Enable agents and developers to back up Port blueprints and actions to GitHub from one environment and import them into another environment using Port AI and GitHub MCP.
#### notify-users-upon-approval-of-action
Enable agents and developers to close the request feedback loop with automated Slack notifications for approved or declined Port actions.
- [Notify users upon approval of self-service actions](/guides/all/notify-users-upon-approval-of-action.md): Enable agents and developers to close the request feedback loop with automated Slack notifications for approved or declined Port actions.
#### nudge-pr-reviewers-with-port-workflows
Enable agents and developers to keep pull request reviews moving with automated reminders from Port Workflows.
- [Nudge Pull Request Reviewers (Port Workflows)](/guides/all/nudge-pr-reviewers-with-port-workflows.md): Enable agents and developers to keep pull request reviews moving with automated reminders from Port Workflows.
#### onboard-developers-from-internal-docs-using-port-mcp
Enable agents and developers to set up onboarding guidance in Port and Cursor using Port MCP, a connected Notion MCP connector, and a custom onboarding skill.
- [Onboard developers using internal docs and Port MCP](/guides/all/onboard-developers-from-internal-docs-using-port-mcp.md): Enable agents and developers to set up onboarding guidance in Port and Cursor using Port MCP, a connected Notion MCP connector, and a custom onboarding skill.
#### owasp-top-10-scorecard
Enable agents and developers to build an OWASP Top 10 security scorecard in Port using vulnerability data from Snyk.
- [Build an OWASP Top 10 Scorecard](/guides/all/owasp-top-10-scorecard.md): Enable agents and developers to build an OWASP Top 10 security scorecard in Port using vulnerability data from Snyk.
#### prepare-work-items-with-ai
Enable agents and developers to use Port AI to enrich work items with context lake data, prepare them for human review, and route approved tickets to coding agents.
- [Prepare work items with AI](/guides/all/prepare-work-items-with-ai.md): Enable agents and developers to use Port AI to enrich work items with context lake data, prepare them for human review, and route approved tickets to coding agents.
#### promote-to-production-workflow
Enable agents and developers to build a "Promote to production" flow using Port Workflows and GitHub Actions, with safety checks, deployment tracking, automated PagerDuty incident creation, and team notifications.
- [Promote to production workflow](/guides/all/promote-to-production-workflow.md): Enable agents and developers to build a "Promote to production" flow using Port Workflows and GitHub Actions, with safety checks, deployment tracking, automated PagerDuty incident creation, and team notifications.
#### provision-azure-resources-with-ado-mcp
Build a Port workflow that reads real Terraform module source from Azure DevOps via MCP, then triggers a Claude Code pipeline to open a pull request that follows your module conventions.
- [Provision Azure resources from Terraform with Azure DevOps MCP](/guides/all/provision-azure-resources-with-ado-mcp.md): Build a Port workflow that reads real Terraform module source from Azure DevOps via MCP, then triggers a Claude Code pipeline to open a pull request that follows your module conventions.
#### provision-cloud-resources-with-agentic-iac-workflow
Build a self-service workflow that fetches service context, drafts an IaC implementation plan with AI, and opens a real pull request against your GitOps repository.
- [Provision cloud resources with an agentic IaC workflow](/guides/all/provision-cloud-resources-with-agentic-iac-workflow.md): Build a self-service workflow that fetches service context, drafts an IaC implementation plan with AI, and opens a real pull request against your GitOps repository.
#### query-dora-metrics-using-port-mcp
Enable agents and developers to query DORA performance data from their IDE using Port MCP.
- [Query DORA metrics using Port MCP](/guides/all/query-dora-metrics-using-port-mcp.md): Enable agents and developers to query DORA performance data from their IDE using Port MCP.
#### remediate-ci-cd-failures-with-port-cursor-workflow
Enable agents and developers to automatically remediate failed CI workflow runs by orchestrating Port, Cursor automations, and Slack notifications.
- [Remediate CI/CD failures with Port AI & Cursor](/guides/all/remediate-ci-cd-failures-with-port-cursor-workflow.md): Enable agents and developers to automatically remediate failed CI workflow runs by orchestrating Port, Cursor automations, and Slack notifications.
#### remediate-vulnerability-with-ai
Use a Port workflow with AI and a coding agent (Claude Code, GitHub Copilot, or Gemini) to enrich critical security vulnerabilities and trigger automated fixes
- [Remediate vulnerabilities with AI](/guides/all/remediate-vulnerability-with-ai.md): Use a Port workflow with AI and a coding agent (Claude Code, GitHub Copilot, or Gemini) to enrich critical security vulnerabilities and trigger automated fixes
#### remediate-vulnerability-with-n8n-and-port
Enable agents and developers to use Port as a context lake for n8n workflows to enrich vulnerability management with service metadata, ownership, and dependencies.
- [Remediate security vulnerability with n8n and Port AI](/guides/all/remediate-vulnerability-with-n8n-and-port.md): Enable agents and developers to use Port as a context lake for n8n workflows to enrich vulnerability management with service metadata, ownership, and dependencies.
#### report-a-bug
Enable agents and developers to report bugs in Jira through a governed Port workflow.
- [Report a bug](/guides/all/report-a-bug.md): Enable agents and developers to report bugs in Jira through a governed Port workflow.
#### respond-to-new-relic-alerts
Enable agents and developers to respond to New Relic alerts by creating Jira issues or PagerDuty incidents through Port.
- [Respond to New Relic alerts](/guides/all/respond-to-new-relic-alerts.md): Enable agents and developers to respond to New Relic alerts by creating Jira issues or PagerDuty incidents through Port.
#### rollback-argocd-deployment
Enable agents and developers to deploy or roll back Argo CD workloads through a governed Port workflow backed by GitHub Actions.
- [Roll back an ArgoCD deployment via GitHub Actions](/guides/all/rollback-argocd-deployment.md): Enable agents and developers to deploy or roll back Argo CD workloads through a governed Port workflow backed by GitHub Actions.
#### route-scorecard-failures-to-jira-issues
Turn failing scorecard rules into routed Jira issues with Port workflows and Port AI.
- [Route scorecard failures to Jira issues with AI](/guides/all/route-scorecard-failures-to-jira-issues.md): Turn failing scorecard rules into routed Jira issues with Port workflows and Port AI.
#### scaffold-a-new-service-with-port-workflows
Enable agents and developers to scaffold new services through governed Port Workflows.
- [Scaffold a new service](/guides/all/scaffold-a-new-service-with-port-workflows.md): Enable agents and developers to scaffold new services through governed Port Workflows.
#### scaffold-a-new-service
Enable agents and developers to scaffold production-ready services through governed Port self-service actions.
- [Scaffold a new service with Actions](/guides/all/scaffold-a-new-service.md): Enable agents and developers to scaffold production-ready services through governed Port self-service actions.
#### scaffold-repositories-using-cookiecutter
Enable agents and developers to scaffold GitHub, Bitbucket, and Azure DevOps repositories using Cookiecutter templates via Port self-service actions.
- [Scaffold repositories using Cookiecutter](/guides/all/scaffold-repositories-using-cookiecutter.md): Enable agents and developers to scaffold GitHub, Bitbucket, and Azure DevOps repositories using Cookiecutter templates via Port self-service actions.
#### self-heal-scorecards-with-ai
Enable agents and developers to use Port's AI capabilities to detect scorecard degradation and automatically use a coding agent like GitHub Copilot to fix it.
- [Auto-fix services when scorecards degrade](/guides/all/self-heal-scorecards-with-ai.md): Enable agents and developers to use Port's AI capabilities to detect scorecard degradation and automatically use a coding agent like GitHub Copilot to fix it.
#### send-slack-message-to-user
Enable agents and developers to send Slack messages to users using Port's Slack app and Port Workflows.
- [Send Slack messages to users using Port Workflows](/guides/all/send-slack-message-to-user.md): Enable agents and developers to send Slack messages to users using Port's Slack app and Port Workflows.
#### setup-branch-protection-rules
Enable agents and developers to enforce repository governance by evaluating GitHub branch protection rules with Port scorecards.
- [Enforce branch protection rules with scorecards](/guides/all/setup-branch-protection-rules.md): Enable agents and developers to enforce repository governance by evaluating GitHub branch protection rules with Port scorecards.
#### setup-delivery-performance-scorecard
Enable agents and developers to set up Delivery Performance scorecards in Port to grade services, teams, groups, and organizations on PR/MR throughput, cycle time, and stale PR/MR management using Bronze, Silver, and Gold maturity levels.
- [Set up delivery performance scorecards](/guides/all/setup-delivery-performance-scorecard.md): Enable agents and developers to set up Delivery Performance scorecards in Port to grade services, teams, groups, and organizations on PR/MR throughput, cycle time, and stale PR/MR management using Bronze, Silver, and Gold maturity levels.
#### setup-dora-metrics-jira
Enable agents and developers to configure DORA metrics using Jira issues as the deployment and incident source instead of GitHub and PagerDuty.
- [Set up deployments and incidents using Jira issues](/guides/all/setup-dora-metrics-jira.md): Enable agents and developers to configure DORA metrics using Jira issues as the deployment and incident source instead of GitHub and PagerDuty.
#### setup-dora-metrics
Set up DORA metrics in Port: model deployments and incidents, then build a dashboard tracking all four delivery metrics.
- [Track DORA metrics](/guides/all/setup-dora-metrics.md): Set up DORA metrics in Port: model deployments and incidents, then build a dashboard tracking all four delivery metrics.
#### setup-engineering-intelligence-data-model
Enable agents and developers to build Port's Engineering Intelligence data model across organizations, teams, services, and repositories.
- [Create foundational Engineering Intelligence data model](/guides/all/setup-engineering-intelligence-data-model.md): Enable agents and developers to build Port's Engineering Intelligence data model across organizations, teams, services, and repositories.
#### setup-incident-manager-ai-agent
Enable agents and developers to set up an Incident Manager AI agent to help developers track and manage incidents efficiently.
- [Set up the Incident Manager AI agent](/guides/all/setup-incident-manager-ai-agent.md): Enable agents and developers to set up an Incident Manager AI agent to help developers track and manage incidents efficiently.
#### setup-pci-dss-code-compliance
Enable agents and developers to measure PCI DSS code security compliance using Snyk data and Port scorecards.
- [PCI DSS code security scorecard](/guides/all/setup-pci-dss-code-compliance.md): Enable agents and developers to measure PCI DSS code security compliance using Snyk data and Port scorecards.
#### setup-pipeline-reliability-scorecard
Enable agents and developers to set up Pipeline Reliability scorecards in Port to grade services, teams, groups, and organizations on CI/CD workflow failure rates and reliability trends using Bronze, Silver, and Gold maturity levels.
- [Set up pipeline reliability scorecards](/guides/all/setup-pipeline-reliability-scorecard.md): Enable agents and developers to set up Pipeline Reliability scorecards in Port to grade services, teams, groups, and organizations on CI/CD workflow failure rates and reliability trends using Bronze, Silver, and Gold maturity levels.
#### setup-platform-request-triage-ai-agent
Enable agents and developers to set up a Platform Request Triage AI agent to help developers submit and track requests to the platform team.
- [Set up the Platform Request Triage AI agent](/guides/all/setup-platform-request-triage-ai-agent.md): Enable agents and developers to set up a Platform Request Triage AI agent to help developers submit and track requests to the platform team.
#### setup-pr-enricher-ai-agent
Enable agents and developers to set up a Pull Request Enricher using Port Workflows to automatically comment on pull requests with additional context.
- [Enrich pull requests using AI](/guides/all/setup-pr-enricher-ai-agent.md): Enable agents and developers to set up a Pull Request Enricher using Port Workflows to automatically comment on pull requests with additional context.
#### setup-prd-agent-for-ticket-triage
Enable agents and developers to turn thin tickets into clear specifications and route them to AI coding agents or people through governed Port workflows.
- [Set up a PRD agent for ticket triage](/guides/all/setup-prd-agent-for-ticket-triage.md): Enable agents and developers to turn thin tickets into clear specifications and route them to AI coding agents or people through governed Port workflows.
#### setup-production-readiness-scorecard
Build Bronze to Gold production readiness checks on services so you can enforce ownership, documentation, and repository hygiene.
- [Set up a service production readiness scorecard](/guides/all/setup-production-readiness-scorecard.md): Build Bronze to Gold production readiness checks on services so you can enforce ownership, documentation, and repository hygiene.
#### setup-service-explorer-ai-agent
Enable agents and developers to set up a Service Explorer AI agent with MCP to help developers discover services, understand ownership, and access documentation for quick onboarding.
- [Set up the Service Explorer AI agent](/guides/all/setup-service-explorer-ai-agent.md): Enable agents and developers to set up a Service Explorer AI agent with MCP to help developers discover services, understand ownership, and access documentation for quick onboarding.
#### setup-skills-registry
Model every skill your org has written outside a developer's local machine as a Port entity, assign it to groups, and let people discover and install it through the UI, Port MCP, or the Port API.
- [Set up a skills registry](/guides/all/setup-skills-registry.md): Model every skill your org has written outside a developer's local machine as a Port entity, assign it to groups, and let people discover and install it through the UI, Port MCP, or the Port API.
#### setup-slack-reminders
Enable agents and developers to deliver scheduled Slack reminders through Port automations.
- [Slack reminders for scorecards](/guides/all/setup-slack-reminders.md): Enable agents and developers to deliver scheduled Slack reminders through Port automations.
#### setup-task-manager-ai-agent
Enable agents and developers to set up a Task Manager AI agent to help developers track and manage tasks efficiently.
- [Set up the Task Manager AI agent](/guides/all/setup-task-manager-ai-agent.md): Enable agents and developers to set up a Task Manager AI agent to help developers track and manage tasks efficiently.
#### ship-skills-through-one-golden-path
Give every developer one standard way to propose a new skill: submit its SKILL.md, get a pull request opened automatically, and track the review from a single dashboard.
- [Ship new skills through one golden path](/guides/all/ship-skills-through-one-golden-path.md): Give every developer one standard way to propose a new skill: submit its SKILL.md, get a pull request opened automatically, and track the review from a single dashboard.
#### smart-pr-reviewer-assignment-using-port-ai
Enable agents and developers to automatically assign qualified PR reviewers using Port AI, CODEOWNERS, ownership data, and capacity constraints.
- [Smart PR reviewer assignment using AI](/guides/all/smart-pr-reviewer-assignment-using-port-ai.md): Enable agents and developers to automatically assign qualified PR reviewers using Port AI, CODEOWNERS, ownership data, and capacity constraints.
#### standardize-ai-coding-rules
Author AI coding rules in a source-of-truth git repo, provision them to subscribed repositories with a Port workflow, then ingest the files and grade compliance with a scorecard.
- [Standardize AI coding rules across repositories](/guides/all/standardize-ai-coding-rules.md): Author AI coding rules in a source-of-truth git repo, provision them to subscribed repositories with a Port workflow, then ingest the files and grade compliance with a scorecard.
#### streamline-iac-with-ai
Enable agents and developers to use Port AI agents with AI coding assistants to streamline Infrastructure as Code (IaC) by automatically provisioning cloud resources like S3 buckets.
- [Streamline IaC with AI](/guides/all/streamline-iac-with-ai.md): Enable agents and developers to use Port AI agents with AI coding assistants to streamline Infrastructure as Code (IaC) by automatically provisioning cloud resources like S3 buckets.
#### surface-resource-actions-from-jira-with-ai
Enable agents and developers to use Port's AI agent to analyze Jira issues and surface relevant self-service actions for cloud resources and permissions.
- [Surface resource actions from Jira with AI](/guides/all/surface-resource-actions-from-jira-with-ai.md): Enable agents and developers to use Port's AI agent to analyze Jira issues and surface relevant self-service actions for cloud resources and permissions.
#### sync-port-properties-to-github-external-custom-properties
Sync Port property values to GitHub external custom properties, so you can search repositories and build GitHub rulesets on top of business context that lives in Port.
- [Sync Port properties to GitHub external custom properties](/guides/all/sync-port-properties-to-github-external-custom-properties.md): Sync Port property values to GitHub external custom properties, so you can search repositories and build GitHub rulesets on top of business context that lives in Port.
#### sync-service-entities-to-incident-io
Enable agents and developers to use Port service context during incidents by synchronizing entities to incident.io.
- [Sync Port services to incident.io](/guides/all/sync-service-entities-to-incident-io.md): Enable agents and developers to use Port service context during incidents by synchronizing entities to incident.io.
#### terraform-plan-and-apply-aws-resource
Enable agents and developers to plan and apply AWS infrastructure through governed Port self-service actions backed by Terraform.
- [Provision Cloud Resource using Terraform Plan and Apply](/guides/all/terraform-plan-and-apply-aws-resource.md): Enable agents and developers to plan and apply AWS infrastructure through governed Port self-service actions backed by Terraform.
#### track-ai-adoption-and-impact
Enable agents and developers to track AI adoption across engineering teams and assess the impact of AI usage on delivery metrics like PR throughput and cycle time using Port's GitHub Ocean integration.
- [Track AI adoption and impact](/guides/all/track-ai-adoption-and-impact.md): Enable agents and developers to track AI adoption across engineering teams and assess the impact of AI usage on delivery metrics like PR throughput and cycle time using Port's GitHub Ocean integration.
#### track-ai-coding-assistants-costs
Enable agents and developers to build a unified dashboard to analyze and compare AI coding tool costs across Cursor, Claude, and GitHub Copilot using data already ingested into Port.
- [Track AI coding assistants costs](/guides/all/track-ai-coding-assistants-costs.md): Enable agents and developers to build a unified dashboard to analyze and compare AI coding tool costs across Cursor, Claude, and GitHub Copilot using data already ingested into Port.
#### track-ai-driven-pull-requests
Enable agents and developers to track and monitor AI-driven pull requests in your development workflow using Port's context lake and automation capabilities.
- [Track AI-driven pull requests](/guides/all/track-ai-driven-pull-requests.md): Enable agents and developers to track and monitor AI-driven pull requests in your development workflow using Port's context lake and automation capabilities.
#### track-and-show-mtbf-for-services
Enable agents and developers to track Mean Time Between Failures (MTBF) for your Pagerduty services to measure reliability and identify improvement opportunities.
- [Track and show MTBF for services](/guides/all/track-and-show-mtbf-for-services.md): Enable agents and developers to track Mean Time Between Failures (MTBF) for your Pagerduty services to measure reliability and identify improvement opportunities.
#### track-gitlab-project-maturity-with-scorecards
Enable agents and developers to enforce GitLab repository maturity standards using file-search signals and Port scorecards.
- [Enforce code maturity with GitLab file search](/guides/all/track-gitlab-project-maturity-with-scorecards.md): Enable agents and developers to enforce GitLab repository maturity standards using file-search signals and Port scorecards.
#### track-health-of-jira-projects
Enable agents and developers to identify project risks by evaluating Jira issue hygiene and operational readiness with Port scorecards.
- [Set up Jira project health scorecards](/guides/all/track-health-of-jira-projects.md): Enable agents and developers to identify project risks by evaluating Jira issue hygiene and operational readiness with Port scorecards.
#### track-leaked-github-secrets-in-port
Enable agents and developers to send leaked application secrets from GitHub to Port using Gitleaks.
- [Track leaked GitHub secrets in Port](/guides/all/track-leaked-github-secrets-in-port.md): Enable agents and developers to send leaked application secrets from GitHub to Port using Gitleaks.
#### track-slos-and-slis-for-services
Enable agents and developers to track SLOs and SLIs for your services using Port.
- [Track SLOs and SLIs for your services](/guides/all/track-slos-and-slis-for-services.md): Enable agents and developers to track SLOs and SLIs for your services using Port.
#### track-team-work-allocation-with-jira
Enable agents and developers to measure and visualize work allocation across Roadmap, Tech Debt, and Support categories at the team level using Jira labels and Port dashboards.
- [Track team work allocation with Jira](/guides/all/track-team-work-allocation-with-jira.md): Enable agents and developers to measure and visualize work allocation across Roadmap, Tech Debt, and Support categories at the team level using Jira labels and Port dashboards.
#### triage-incidents-with-dynatrace-mcp
Triage incidents using AI, Dynatrace MCP, GitHub MCP, and Slack - fetch live telemetry with DQL, correlate code context, and post a structured root-cause summary from Port AI.
- [Triage incidents with Dynatrace MCP](/guides/all/triage-incidents-with-dynatrace-mcp.md): Triage incidents using AI, Dynatrace MCP, GitHub MCP, and Slack - fetch live telemetry with DQL, correlate code context, and post a structured root-cause summary from Port AI.
#### triage-incidents-with-mcp
Triage incidents with live Sentry errors, GitHub code context, and Slack summaries, either on demand in Port AI or automatically when a new incident is created.
- [Triage incidents using external MCP tools](/guides/all/triage-incidents-with-mcp.md): Triage incidents with live Sentry errors, GitHub code context, and Slack summaries, either on demand in Port AI or automatically when a new incident is created.
#### trigger-ai-coding-assistants-from-port
Learn how to trigger GitHub Copilot, Claude Code, and Google Gemini Assistant from Port using governed workflows.
- [Trigger AI coding assistants from Port](/guides/all/trigger-ai-coding-assistants-from-port.md): Learn how to trigger GitHub Copilot, Claude Code, and Google Gemini Assistant from Port using governed workflows.
#### trigger-datadog-incident-with-port-workflows
Trigger a Datadog incident from a Port self-service workflow and sync it to your software catalog.
- [Trigger Datadog incident (Workflows)](/guides/all/trigger-datadog-incident-with-port-workflows.md): Trigger a Datadog incident from a Port self-service workflow and sync it to your software catalog.
#### trigger-datadog-incident
Enable agents and developers to initiate Datadog incident response through a governed Port self-service action.
- [Trigger Datadog Incident](/guides/all/trigger-datadog-incident.md): Enable agents and developers to initiate Datadog incident response through a governed Port self-service action.
#### trigger-n8n-workflows-from-port
Enable agents and developers to trigger existing n8n workflows from Port without changing n8n runtime or logic.
- [Trigger n8n workflows from Port](/guides/all/trigger-n8n-workflows-from-port.md): Enable agents and developers to trigger existing n8n workflows from Port without changing n8n runtime or logic.
#### trigger-spacelift-stack
Enable agents and developers to trigger a Spacelift stack in Port to automate infrastructure workflows.
- [Trigger a Spacelift stack](/guides/all/trigger-spacelift-stack.md): Enable agents and developers to trigger a Spacelift stack in Port to automate infrastructure workflows.
#### visualize-and-manage-azure-devops-deployments
Enable agents and developers to monitor and manage your Azure DevOps deployments using dashboards and self-service actions in Port.
- [Visualize and manage your Azure DevOps deployments](/guides/all/visualize-and-manage-azure-devops-deployments.md): Enable agents and developers to monitor and manage your Azure DevOps deployments using dashboards and self-service actions in Port.
#### visualize-and-manage-git-deployments
Enable agents and developers to ingest, visualize, and manage GitHub and GitLab deployments with dashboards and self-service actions in Port.
- [Visualize and manage Git deployments](/guides/all/visualize-and-manage-git-deployments.md): Enable agents and developers to ingest, visualize, and manage GitHub and GitLab deployments with dashboards and self-service actions in Port.
#### visualize-and-manage-servicenow-incidents
Enable agents and developers to monitor and manage your ServiceNow incidents using dashboards and Port workflows.
- [Visualize and manage your ServiceNow incidents](/guides/all/visualize-and-manage-servicenow-incidents.md): Enable agents and developers to monitor and manage your ServiceNow incidents using dashboards and Port workflows.
#### visualize-and-manage-statuspage-incidents
Enable agents and developers to monitor and manage your Statuspage incidents and components using dashboards and self-service actions in Port.
- [Visualize and manage your Statuspage incidents and components](/guides/all/visualize-and-manage-statuspage-incidents.md): Enable agents and developers to monitor and manage your Statuspage incidents and components using dashboards and self-service actions in Port.
#### visualize-claude-metrics
Enable agents and developers to create dashboards to monitor Claude API usage, track costs, analyze model performance, and measure workspace-level metrics.
- [Visualize Claude metrics](/guides/all/visualize-claude-metrics.md): Enable agents and developers to create dashboards to monitor Claude API usage, track costs, analyze model performance, and measure workspace-level metrics.
#### visualize-claude-skills-adoption
Visualize how Claude Skills are adopted, shared and reused across your organization, which skills become part of regular workflows, and where skill-related spend is concentrated, using Port's Claude integration and dashboards.
- [Visualize Claude Skills adoption and usage](/guides/all/visualize-claude-skills-adoption.md): Visualize how Claude Skills are adopted, shared and reused across your organization, which skills become part of regular workflows, and where skill-related spend is concentrated, using Port's Claude integration and dashboards.
#### visualize-cursor-metrics
Enable agents and developers to visualize Cursor adoption, suggestion acceptance, and engineering impact at the user, team, and organization level using Port's native Cursor integration and dashboards.
- [Visualize Cursor metrics](/guides/all/visualize-cursor-metrics.md): Enable agents and developers to visualize Cursor adoption, suggestion acceptance, and engineering impact at the user, team, and organization level using Port's native Cursor integration and dashboards.
#### visualize-github-copilot-metrics
Enable agents and developers to visualize GitHub Copilot adoption, suggestion acceptance, and engineering impact at the user, team, and organization level using Port's GitHub Copilot integration and dashboards.
- [Visualize GitHub Copilot metrics](/guides/all/visualize-github-copilot-metrics.md): Enable agents and developers to visualize GitHub Copilot adoption, suggestion acceptance, and engineering impact at the user, team, and organization level using Port's GitHub Copilot integration and dashboards.
#### visualize-jira-lead-time
Enable agents and developers to monitor Jira lead time at the project, service, and team levels using Port dashboards.
- [Visualize lead time using Jira](/guides/all/visualize-jira-lead-time.md): Enable agents and developers to monitor Jira lead time at the project, service, and team levels using Port dashboards.
#### visualize-okta-security-insights
Enable agents and developers to build a security analytics dashboard for Okta identity and access management using Port's integration.
- [Visualize Okta security insights](/guides/all/visualize-okta-security-insights.md): Enable agents and developers to build a security analytics dashboard for Okta identity and access management using Port's integration.
#### visualize-service-argocd-runtime
Enable agents and developers to visualize ArgoCD service runtime in Port, enhancing monitoring and management of your Kubernetes applications.
- [Visualize your services' Kubernetes runtime using ArgoCD](/guides/all/visualize-service-argocd-runtime.md): Enable agents and developers to visualize ArgoCD service runtime in Port, enhancing monitoring and management of your Kubernetes applications.
#### visualize-service-k8s-runtime
Enable agents and developers to visualize Kubernetes service runtime in Port, improving monitoring and management of your cloud-native applications.
- [Visualize your services' k8s runtime](/guides/all/visualize-service-k8s-runtime.md): Enable agents and developers to visualize Kubernetes service runtime in Port, improving monitoring and management of your cloud-native applications.
#### visualize-your-wiz-vulnerabilities
Enable agents and developers to monitor Wiz issues and gain security insights using dashboards.
- [Visualize your Wiz security issues](/guides/all/visualize-your-wiz-vulnerabilities.md): Enable agents and developers to monitor Wiz issues and gain security insights using dashboards.
#### work-item-blueprint
Enable agents and developers to connect Jira issues with services, teams, pull requests, and deployments for autonomous ticket resolution.
- [Implement the work item blueprint pattern](/guides/all/work-item-blueprint.md): Enable agents and developers to connect Jira issues with services, teams, pull requests, and deployments for autonomous ticket resolution.
## glossary
Read precise definitions of Port terms such as blueprint, entity, and scorecard so you apply them correctly in setup and support.
- [Glossary](/glossary.md): Read precise definitions of Port terms such as blueprint, entity, and scorecard so you apply them correctly in setup and support.
## solutions
### agentic-resource-management
#### common-use-cases
This is a catalog of common use cases we see deliver value across our customers.
- [Common use cases](/solutions/agentic-resource-management/common-use-cases.md): This is a catalog of common use cases we see deliver value across our customers.
#### getting-started
This walkthrough shows how to build an agentic workflow that provisions a new cloud resource using Infrastructure as Code (IaC). A developer or agent expresses the intent to create a resource, and the workflow fetches context, generates an implementation plan, creates a resource request, and opens a pull request against your GitOps repository.
- [Getting started](/solutions/agentic-resource-management/getting-started.md): This walkthrough shows how to build an agentic workflow that provisions a new cloud resource using Infrastructure as Code (IaC). A developer or agent expresses the intent to create a resource, and the workflow fetches context, generates an implementation plan, creates a resource request, and opens a pull request against your GitOps repository.
#### golden-paths
Golden paths are the foundation of resource management. They are how you deliver engineering velocity without giving up governance, for both developers and AI agents.
- [Golden paths](/solutions/agentic-resource-management/golden-paths.md): Golden paths are the foundation of resource management. They are how you deliver engineering velocity without giving up governance, for both developers and AI agents.
#### governance-at-scale
As an organization scales, golden path workflows for day-0 and day-2 actions are no longer enough on their own. Thousands of resources across dozens of teams need oversight that doesn't depend on any one person watching every request. A few patterns help you keep control without becoming the bottleneck.
- [Governance at scale](/solutions/agentic-resource-management/governance-at-scale.md): As an organization scales, golden path workflows for day-0 and day-2 actions are no longer enough on their own. Thousands of resources across dozens of teams need oversight that doesn't depend on any one person watching every request. A few patterns help you keep control without becoming the bottleneck.
#### multi-cloud
Golden paths and guardrails are only as good as their coverage. If they only reach one cloud, the gaps in every other environment keep the too-slow / too-loose tension alive.
- [Multi-cloud single pane of glass](/solutions/agentic-resource-management/multi-cloud.md): Golden paths and guardrails are only as good as their coverage. If they only reach one cloud, the gaps in every other environment keep the too-slow / too-loose tension alive.
#### overview
Give developers and agents Port golden paths for infrastructure so you provision and decommission under platform team standards.
- [Resource management](/solutions/agentic-resource-management/overview.md): Give developers and agents Port golden paths for infrastructure so you provision and decommission under platform team standards.
### autonomous-ticket-resolution
#### agentic-initiatives
Run one coding agent across every service that needs the same change, from a single governed initiative, tracked per service and as a portfolio.
- [Agentic initiatives](/solutions/autonomous-ticket-resolution/agentic-initiatives.md): Run one coding agent across every service that needs the same change, from a single governed initiative, tracked per service and as a portfolio.
##### getting-started
Build an agentic initiative that fans a coding agent out across every service failing a scorecard rule, with per-service tracking and portfolio-level progress.
- [Getting started with agentic initiatives](/solutions/autonomous-ticket-resolution/agentic-initiatives/getting-started.md): Build an agentic initiative that fans a coding agent out across every service failing a scorecard rule, with per-service tracking and portfolio-level progress.
#### code-review
Enrich PRs with service context, assign smart reviewers, send review nudges, and track security review outputs in your catalog.
- [Review the results](/solutions/autonomous-ticket-resolution/code-review.md): Enrich PRs with service context, assign smart reviewers, send review nudges, and track security review outputs in your catalog.
#### getting-started-with-atr
Build your first end-to-end Autonomous Ticket Resolution workflow. A Jira ticket arrives thin, gets enriched with catalog context, is scored for AI readiness, and is delegated to Cursor with one click.
- [Getting started with your first Autonomous Ticket Resolution agentic workflow](/solutions/autonomous-ticket-resolution/getting-started-with-atr.md): Build your first end-to-end Autonomous Ticket Resolution workflow. A Jira ticket arrives thin, gets enriched with catalog context, is scored for AI readiness, and is delegated to Cursor with one click.
#### overview
Follow Port's autonomous ticket flow from triage to shipping, letting AI route enriched work while you retain key decision gates.
- [Autonomous ticket resolution](/solutions/autonomous-ticket-resolution/overview.md): Follow Port's autonomous ticket flow from triage to shipping, letting AI route enriched work while you retain key decision gates.
#### roi-dashboard
Measure the impact of Autonomous Ticket Resolution (ATR) in Port with an ROI dashboard covering tickets resolved, time saved, and cost impact.
- [Measure ATR's impact](/solutions/autonomous-ticket-resolution/roi-dashboard.md): Measure the impact of Autonomous Ticket Resolution (ATR) in Port with an ROI dashboard covering tickets resolved, time saved, and cost impact.
#### safe-release
Deploy code safely with PR enrichment, smart reviewer assignment, security review tracking, and automated review nudges.
- [Release safely with control](/solutions/autonomous-ticket-resolution/safe-release.md): Deploy code safely with PR enrichment, smart reviewer assignment, security review tracking, and automated review nudges.
#### turn-tickets-into-actionable-work
Enrich Jira tickets with context, evaluate AI delegation eligibility, and produce routing decisions with supporting documentation.
- [Turn tickets into actionable work](/solutions/autonomous-ticket-resolution/turn-tickets-into-actionable-work.md): Enrich Jira tickets with context, evaluate AI delegation eligibility, and produce routing decisions with supporting documentation.
##### overview
Transform thin tickets into actionable work items with service context, blast radius, PRDs, and AI routing decisions.
- [Ticket preparation](/solutions/autonomous-ticket-resolution/turn-tickets-into-actionable-work/overview.md): Transform thin tickets into actionable work items with service context, blast radius, PRDs, and AI routing decisions.
##### routing-decision
Determine AI delegation eligibility with deterministic scorecards and LLM confidence scoring. Route work safely between agents and humans.
- [Routing decision](/solutions/autonomous-ticket-resolution/turn-tickets-into-actionable-work/routing-decision.md): Determine AI delegation eligibility with deterministic scorecards and LLM confidence scoring. Route work safely between agents and humans.
##### work-item-blueprint-pattern
Create a dedicated Port entity for AI-assisted development that tracks workflow state separately from Jira/Linear/ADO tickets.
- [Work item blueprint pattern](/solutions/autonomous-ticket-resolution/turn-tickets-into-actionable-work/work-item-blueprint-pattern.md): Create a dedicated Port entity for AI-assisted development that tracks workflow state separately from Jira/Linear/ADO tickets.
#### why-port
Port provides catalog context, deterministic routing scorecards, entity persistence, and measurable outcomes for autonomous ticket resolution workflows.
- [Why Port?](/solutions/autonomous-ticket-resolution/why-port.md): Port provides catalog context, deterministic routing scorecards, entity persistence, and measurable outcomes for autonomous ticket resolution workflows.
### engineering-intelligence
#### ai-adoption
Track AI tool adoption rates, measure ROI, and correlate usage with delivery performance improvements across teams.
- [AI adoption and impact](/solutions/engineering-intelligence/ai-adoption.md): Track AI tool adoption rates, measure ROI, and correlate usage with delivery performance improvements across teams.
##### ai-adoption-survey
Run a recurring AI Adoption & Impact pulse survey to complement usage telemetry with self-reported signal on velocity, time saved, quality, and focus.
- [AI adoption survey](/solutions/engineering-intelligence/ai-adoption/ai-adoption-survey.md): Run a recurring AI Adoption & Impact pulse survey to complement usage telemetry with self-reported signal on velocity, time saved, quality, and focus.
##### ai-impact
Correlate AI tool adoption with delivery performance, incident frequency, and code quality to measure real engineering outcomes.
- [AI impact](/solutions/engineering-intelligence/ai-adoption/ai-impact.md): Correlate AI tool adoption with delivery performance, incident frequency, and code quality to measure real engineering outcomes.
##### ai-tools
Monitor Copilot, Cursor, and AI tool usage rates, suggestion acceptance, and adoption distribution across teams for ROI analysis.
- [Track AI adoption](/solutions/engineering-intelligence/ai-adoption/ai-tools.md): Monitor Copilot, Cursor, and AI tool usage rates, suggestion acceptance, and adoption distribution across teams for ROI analysis.
##### skills-usage
Track Claude Skills adoption, depth of usage, and whether knowledge stays personal or becomes reusable across your organization.
- [Skills usage](/solutions/engineering-intelligence/ai-adoption/skills-usage.md): Track Claude Skills adoption, depth of usage, and whether knowledge stays personal or becomes reusable across your organization.
#### conversational-insights
Query and analyze your context lake with AI — through Port agents, MCP-connected tools, or dashboards and reports.
- [Conversational insights](/solutions/engineering-intelligence/conversational-insights.md): Query and analyze your context lake with AI — through Port agents, MCP-connected tools, or dashboards and reports.
#### devex-surveys
Run developer experience surveys, collect qualitative feedback, and turn developer sentiment into actionable improvement initiatives.
- [DevEx surveys](/solutions/engineering-intelligence/devex-surveys.md): Run developer experience surveys, collect qualitative feedback, and turn developer sentiment into actionable improvement initiatives.
#### getting-started
Four-phase Engineering Intelligence journey from baseline metrics through continuous improvement with scorecards, AI agents, and automations.
- [Getting started](/solutions/engineering-intelligence/getting-started.md): Four-phase Engineering Intelligence journey from baseline metrics through continuous improvement with scorecards, AI agents, and automations.
#### measure-and-track-standards
Measure DORA metrics, delivery performance, pipeline reliability, and production readiness - then enforce standards with scorecards.
- [Measure and track standards](/solutions/engineering-intelligence/measure-and-track-standards.md): Measure DORA metrics, delivery performance, pipeline reliability, and production readiness - then enforce standards with scorecards.
##### delivery-performance
Track PR throughput, cycle time, and stale PRs — then enforce delivery standards with scorecards graded by maturity tier.
- [Delivery performance](/solutions/engineering-intelligence/measure-and-track-standards/delivery-performance.md): Track PR throughput, cycle time, and stale PRs — then enforce delivery standards with scorecards graded by maturity tier.
##### dora-metrics
Measure the four DORA metrics per service and team, then enforce delivery maturity with DORA scorecards.
- [DORA metrics](/solutions/engineering-intelligence/measure-and-track-standards/dora-metrics.md): Measure the four DORA metrics per service and team, then enforce delivery maturity with DORA scorecards.
##### pipeline-reliability
Track CI/CD pipeline health and failure trends — then enforce reliability standards with scorecards and automated remediation.
- [Reliability](/solutions/engineering-intelligence/measure-and-track-standards/pipeline-reliability.md): Track CI/CD pipeline health and failure trends — then enforce reliability standards with scorecards and automated remediation.
##### production-readiness
Score services on ownership, documentation, monitoring, security compliance, and infrastructure hygiene with Bronze/Silver/Gold maturity levels.
- [Production readiness](/solutions/engineering-intelligence/measure-and-track-standards/production-readiness.md): Score services on ownership, documentation, monitoring, security compliance, and infrastructure hygiene with Bronze/Silver/Gold maturity levels.
#### overview
Track DORA, delivery, reliability, and developer experience in Port, then find bottlenecks and improve from catalog-linked data.
- [Engineering Intelligence](/solutions/engineering-intelligence/overview.md): Track DORA, delivery, reliability, and developer experience in Port, then find bottlenecks and improve from catalog-linked data.
#### why-port
Port combines engineering intelligence with orchestration on a unified catalog. Close the loop from insight to execution to measured impact.
- [Why Port?](/solutions/engineering-intelligence/why-port.md): Port combines engineering intelligence with orchestration on a unified catalog. Close the loop from insight to execution to measured impact.
### overview
Browse Port solutions for resource management, incidents, engineering intelligence, and ticket resolution with humans and agents.
- [Solutions overview](/solutions/overview.md): Browse Port solutions for resource management, incidents, engineering intelligence, and ticket resolution with humans and agents.
### self-healing-incidents
#### act-on-response
Execute pre-authorized actions inside boundaries the system enforces structurally, so autonomy scales without breaking accountability.
- [Act on response](/solutions/self-healing-incidents/act-on-response.md): Execute pre-authorized actions inside boundaries the system enforces structurally, so autonomy scales without breaking accountability.
#### detect-incidents
Score confidence from converging signals instead of a single threshold, and declare only once that confidence clears a threshold set in advance.
- [Detect incidents](/solutions/self-healing-incidents/detect-incidents.md): Score confidence from converging signals instead of a single threshold, and declare only once that confidence clears a threshold set in advance.
#### diagnose-incidents
Reconstruct what changed and quantify impact on the incident record, so remediation targets the real cause instead of the first plausible one.
- [Diagnose incidents](/solutions/self-healing-incidents/diagnose-incidents.md): Reconstruct what changed and quantify impact on the incident record, so remediation targets the real cause instead of the first plausible one.
#### learn-from-incidents
Turn divergence between expected and observed outcomes into a proposed change, reviewed by a human, before the next incident.
- [Learn from incidents](/solutions/self-healing-incidents/learn-from-incidents.md): Turn divergence between expected and observed outcomes into a proposed change, reviewed by a human, before the next incident.
#### overview
Follow five incident stages in Port so agents detect, diagnose, recommend, act, and learn inside gates your team defines up front.
- [Self-healing incidents](/solutions/self-healing-incidents/overview.md): Follow five incident stages in Port so agents detect, diagnose, recommend, act, and learn inside gates your team defines up front.
#### recommend-response
Score response options against explicit criteria and present a ranked, explainable set, instead of collapsing straight to a single answer.
- [Recommend response](/solutions/self-healing-incidents/recommend-response.md): Score response options against explicit criteria and present a ranked, explainable set, instead of collapsing straight to a single answer.
## troubleshooting
Resolve Port problems using guides for Ocean integrations, actions, the execution agent, and GitHub, GitLab, or Azure DevOps.
- [Troubleshooting](/troubleshooting.md): Resolve Port problems using guides for Ocean integrations, actions, the execution agent, and GitHub, GitLab, or Azure DevOps.
### actions
Diagnose self-service actions in Port that are stuck in progress, including action backend configuration and Port execution agent setup for Git providers.
- [Actions troubleshooting](/troubleshooting/actions.md): Diagnose self-service actions in Port that are stuck in progress, including action backend configuration and Port execution agent setup for Git providers.
### azure-devops
Diagnose Azure DevOps Ocean integration bugs in Port - deleted repositories not reflected, syncs that run with no result, builds not fully ingesting, and inconsistent file ingestion.
- [Azure DevOps integration troubleshooting](/troubleshooting/azure-devops.md): Diagnose Azure DevOps Ocean integration bugs in Port - deleted repositories not reflected, syncs that run with no result, builds not fully ingesting, and inconsistent file ingestion.
### general
Answers to common general questions about Port - account setup, organization management, exporting catalog data, embedding content, and security.
- [General troubleshooting](/troubleshooting/general.md): Answers to common general questions about Port - account setup, organization management, exporting catalog data, embedding content, and security.
### github
Diagnose GitHub Ocean integration bugs in Port - stale data with live events, entities not deleted, partial PR ingestion, workflow run deletion, missing team relations, and migration from the legacy integration.
- [GitHub integration troubleshooting](/troubleshooting/github.md): Diagnose GitHub Ocean integration bugs in Port - stale data with live events, entities not deleted, partial PR ingestion, workflow run deletion, missing team relations, and migration from the legacy integration.
### gitlab
Diagnose GitLab Ocean integration bugs in Port, including projects not visible after setting up a group access token and version compatibility issues.
- [GitLab integration troubleshooting](/troubleshooting/gitlab.md): Diagnose GitLab Ocean integration bugs in Port, including projects not visible after setting up a group access token and version compatibility issues.
### ocean-integrations
Diagnose common Ocean integration issues in Port - installation failures, validation errors, mapping problems, and connectivity between the integration and Port's API.
- [Ocean integrations troubleshooting](/troubleshooting/ocean-integrations.md): Diagnose common Ocean integration issues in Port - installation failures, validation errors, mapping problems, and connectivity between the integration and Port's API.
### port-agent
Diagnose Port execution agent failures - 401 authentication errors, Kafka consumer group authorization, action execution timeouts, and TLS certificate issues on startup.
- [Port execution agent troubleshooting](/troubleshooting/port-agent.md): Diagnose Port execution agent failures - 401 authentication errors, Kafka consumer group authorization, action execution timeouts, and TLS certificate issues on startup.
## Optional
- [Port agent guide: API authentication, endpoints, and terminology for building with Port](https://docs.port.io/AGENTS.md): Quick reference for agents: authentication, regional base URLs, common API request patterns, and correct Port terminology.
- [Port implementation guides by platform pillar](https://docs.port.io/llms/guides.txt): Browse every surviving Port guide grouped under Context lake, Workflows, Port AI, Agent management, Interface builder, Governance, or Platform administration.
- [Port MCP server](https://docs.port.io/ai-interfaces/port-mcp-server/overview): Connect AI assistants to Port context, actions, search, and governed MCP connectors.
- [Port MCP server installation](https://docs.port.io/ai-interfaces/port-mcp-server/installation): Configure Claude, Cursor, VS Code, Codex, and other MCP clients with Port.
- [Port REST API reference (all endpoints)](https://docs.port.io/api-reference/port-api): Full Port REST API: authentication, base URLs, and every endpoint (entities, blueprints, actions, scorecards, workflows). Individual endpoints are omitted from this index to keep it concise; browse them at this page, or use the machine-readable OpenAPI spec at https://docs.port.io/apispec-port-api.yaml. For a single combined OpenAPI spec across all services (Port API, AI, workflow, asset, integration), use https://docs.port.io/unified-services.yaml.
---
# Full Documentation Content
# AGENTS.md - AI Documentation Maintenance Guide
This is a hidden guide for AI agents to understand how to maintain and update the AI interfaces documentation in Port Docs.
## File Structure[](#file-structure "Direct link to File Structure")
The AI interfaces documentation files are located in:
* `/docs/agent-management/` - Main documentation files
* `/src/data/mcpTools.js` - MCP tool definitions (JSON file)
* `/src/components/ToolsList/` - React component that displays tools from `mcpTools.js`
## Common Tasks[](#common-tasks "Direct link to Common Tasks")
### Update MCP Tools[](#update-mcp-tools "Direct link to Update MCP Tools")
To add, update, or remove MCP tools:
1. **Update the file**: `src/data/mcpTools.js`
2. **Ask for clarification**: Determine if the tool is for `builder` only or for both `developer` and `builder` roles
3. The `ToolsList` component automatically reads from this file and displays tools in the documentation
**Tool naming conventions:**
* List tools (`list_blueprints`, `list_entities`, etc.): Support optional `identifiers` parameter to get detailed info for specific items
* Upsert tools (`upsert_blueprint`, `upsert_entity`, etc.): Create or update resources (creates if not exists, updates if exists)
* Delete tools: Remove resources
### Set Feature Beta Status[](#set-feature-beta-status "Direct link to Set Feature Beta Status")
When asked to mark a feature as **open beta** or **closed beta**, use the appropriate component:
#### For Open Beta Features[](#for-open-beta-features "Direct link to For Open Beta Features")
Use the `BetaFeatureNotice` component:
```
import BetaFeatureNotice from '/docs/generalTemplates/_beta_feature_notice.md'
```
**Location**: Place this after the page title (H1) and before the main content.
#### For Closed Beta Features[](#for-closed-beta-features "Direct link to For Closed Beta Features")
Use the `ClosedBetaFeatureNotice` component:
```
import ClosedBetaFeatureNotice from '/docs/generalTemplates/_closed_beta_feature_notice.md'
```
**Location**: Place this after the page title (H1) and before the main content.
**ID**: Use a specific feature identifier (e.g., `"slack-app"`). Check `/docs/generalTemplates/_closed_beta_feature_notice_defs.js` for available IDs and their custom messages. You might need to create a new definition, ask the user for this.
### Add New LLM Model[](#add-new-llm-model "Direct link to Add New LLM Model")
To add a new LLM model to the documentation:
1. **Identify the model name and providers**: Determine the exact model identifier (e.g., `gpt-5`) and which providers support it (e.g., Anthropic, AWS Bedrock).
2. **Update the main documentation file**: Edit `docs/port-ai/llm-providers-management/overview.md`:
3. **Note about API reference files**: The API reference files in `docs/api-reference/` (like `general-purpose-ai-interactions.api.mdx`, `invoke-a-specific-agent.api.mdx`, etc.) are auto-generated from OpenAPI specifications. These will be updated automatically when the backend API is updated. You don't need to manually edit these files.
### Update MCP Installation Instructions[](#update-mcp-installation-instructions "Direct link to Update MCP Installation Instructions")
The MCP installation instructions are maintained in a reusable component that is imported into the installation page.
**Location**: `/docs/generalTemplates/_mcp-installation.md`
**Usage**: This component is imported in `docs/agent-management/port-mcp-server/installation.md`.
**What you could update**:
* Add new client support
* Update client instructions
* Update disclaimers/warnings/admonitions
### Update Monthly Limits[](#update-monthly-limits "Direct link to Update Monthly Limits")
When asked to update the monthly quota/limit for AI invocations:
1. **Identify all locations**: Search for mentions of monthly limits/quota in the AI interfaces documentation:
* `docs/port-ai/limits-and-quotas.md` - Contains rate limits section and example JSON responses
2. **Update text descriptions**: Replace the quota number in all text descriptions (e.g., "20 AI invocations per month" → "50 AI invocations per month")
3. **Update example JSON**: Update the `monthlyLimit` value in example JSON responses to match the new limit. Also update `remainingQuota` to be one less than the limit (e.g., if limit is 50, remainingQuota should be 49)
4. **Files to check**:
* `docs/port-ai/limits-and-quotas.md` - Lines with "Monthly quota" section and JSON examples
5. **Search pattern**: Look for patterns like:
* "20 AI invocations per month"
* `"monthlyLimit": 20`
* "Default quota: 20"
**Note**: The API reference files in `docs/api-reference/` are auto-generated from OpenAPI specifications and will be updated automatically when the backend API is updated. You don't need to manually edit these files.
### Update cross-page links[](#update-cross-page-links "Direct link to Update cross-page links")
When documentation pages move, update links to their new public URLs while preserving any heading anchors. Keep the surrounding content unchanged unless the move requires a content update.
## Other Tasks[](#other-tasks "Direct link to Other Tasks")
For other tasks not listed above, ask for clarification from the user. Once understood, add a new section to the "Common Tasks" section of this file.
---
# AI Gateway
Every agent your organization runs eventually calls a model. Multiply that across the agents you ship, and the traffic behind those calls becomes infrastructure in its own right. That infrastructure needs the same routing, cost control, and governance you expect from anything else in your stack.
This page covers what an AI gateway is, why the agentic SDLC makes it urgent, where the gateway layer runs out of road, and how Port picks up from there.
## What is an AI gateway?[](#what-is-an-ai-gateway "Direct link to What is an AI gateway?")
An AI gateway is a single layer that every model call passes through before it reaches a provider such as OpenAI, Anthropic, AWS Bedrock, Azure, or Databricks. It exists so routing, cost control, and safety logic live in one place, instead of being copy-pasted into every app and agent that calls an LLM.
LiteLLM, Vercel AI Gateway, and Bifrost are three established options doing this today. Different implementations, same core job: one control point standing in front of many providers.
A gateway typically gives you:
* **A unified API.** One interface across every provider, instead of a different integration per model.
* **Routing and failover.** Traffic keeps flowing when a model or provider degrades.
* **Budgets and rate limits.** Spend gets capped before it becomes a surprise.
* **Guardrails.** Safety and compliance checks enforced in-line, on every call.
* **Observability.** Logs, traces, and cost data per request.
* **An MCP / tool gateway.** One front door for the external tools agents reach for.
## Why the agentic SDLC makes this urgent[](#why-the-agentic-sdlc-makes-this-urgent "Direct link to Why the agentic SDLC makes this urgent")
API gateways have existed for years. What has changed is who is making the calls.
**Agents multiply call volume.** A single task can fan out into dozens of model calls chained across tools, where a human doing the same task might have made one API call, if any. Traffic that used to scale with headcount now scales with how many agents you have turned loose.
**Tool and MCP sprawl compounds it.** Agents do not just call models. They reach for external tools and data sources constantly, and each one is a new integration point with its own access surface.
**Cost stops being predictable.** Usage now scales with agent autonomy, not release cadence. A single agent given more latitude can generate a month's typical spend in a day, with no code deploy to flag it.
**Mistakes propagate faster.** An ungoverned agent can act on a bad model response, call the wrong tool, or write to the wrong system before a human ever sees it. There is no code review step in the loop the way there is for a human-written pull request.
An AI gateway is the layer that makes this survivable: one place to route, cap, and guard traffic instead of trusting every agent and app to do it correctly on its own.
## What gateways still miss[](#what-gateways-still-miss "Direct link to What gateways still miss")
A gateway solves the traffic problem. It does not solve the organizational one. Four gaps show up consistently once agents are running through it at scale.
### Traffic, not organization[](#traffic-not-organization "Direct link to Traffic, not organization")
A gateway sees the key that called the model. It does not see the team that owns that key, or the cost behind it. That gap matters twice over. Without ownership, an orphaned key (left behind after the agent it belonged to was retired) keeps spending indefinitely, because nothing flags that it should have been revoked. Without team attribution, "which team is driving this month's spend" turns into a manual reconciliation instead of a query anyone can run themselves.
### Config-driven, not workflow-driven[](#config-driven-not-workflow-driven "Direct link to Config-driven, not workflow-driven")
Budgets, guardrails, and access are things you set in a config file or through an API. There is no built-in path for a developer to request a change, or for security to approve one. Agentic development moves at the pace of iteration, not release cycles. A developer testing a new agent needs a budget increase today, not after a config PR gets reviewed, so without a request path, they either wait or find a way around the guardrail entirely.
### A runtime view, cut off from everything else[](#a-runtime-view-cut-off-from-everything-else "Direct link to A runtime view, cut off from everything else")
A gateway can tell you which agents and MCP servers are live right now. It cannot tell you whose repo any of them came from. An agent's behavior is inseparable from the code and tools it is built from, so when that runtime view is not connected to the service or repo that owns it, an incident means cross-referencing two separate systems by hand, under time pressure.
### Dashboards without enforcement[](#dashboards-without-enforcement "Direct link to Dashboards without enforcement")
A gateway's built-in UI shows spend and usage, but it stops at visibility. There is no mechanism to turn "this agent has no guardrail" into a standard the org actually enforces. As the number of agents, tools, and keys needing governance grows faster than any team can review by hand, a dashboard that only shows the problem becomes one more thing nobody has time to act on.
## How Port closes the gap[](#how-port-closes-the-gap "Direct link to How Port closes the gap")
Port does not replace the gateway. It sits on top of it, turning gateway data into something the rest of the org can see, act on, and enforce.
### One catalog, fully connected[](#one-catalog-fully-connected "Direct link to One catalog, fully connected")
Port pulls every key, budget, guardrail, agent, and MCP server the gateway manages into the same [software catalog](/context-lake/overview/.md) as the rest of your engineering org, related to the team and service that actually owns each one. An agent is just another artifact your org ships. It belongs next to the service and repo it comes from, not off in a system only one team ever opens. This is also what turns cost attribution from a manual exercise into a standing report: because every key is tied to a team, "who's driving spend" is a query, not a reconciliation project.
See [External agents](/agent-management/external-agents/overview/.md) and the [agent registry](/agent-management/ai-registry/agent-registry/.md) for how Port inventories agents alongside the rest of your catalog.
### Internal tools carry the same risk[](#internal-tools-carry-the-same-risk "Direct link to Internal tools carry the same risk")
A gateway governs which MCP servers an agent can reach, but MCPs are not the only tools an agent calls. Port exposes your organization's own [self-service actions](/workflows/actions-and-automations/overview/.md) and golden paths as tools too, and those need the same governance question an MCP does. They are already org-approved business logic, but approved to exist is not the same as safe for any agent to invoke unsupervised. As agents take on more of the SDLC, the tools they reach for are increasingly internal, not external APIs, so governance that stops at MCPs misses the fastest-growing category of what agents can actually do. Port's governed [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md) and [Port MCP server](/agent-management/port-mcp-server/overview/.md) apply the same access-scoping logic here, regardless of whether the tool is an MCP server or an internal workflow.
### Gateway operations become self-service[](#gateway-operations-become-self-service "Direct link to Gateway operations become self-service")
Issuing a key, requesting a budget increase, testing a guardrail, or invoking a registered agent can each become a governed Port action, complete with approvals and an audit trail, instead of a direct call to the proxy. Agent development iterates fast enough that any manual step (filing a ticket for a key, pinging platform on Slack) becomes the actual bottleneck in the loop, not the model call itself.
### Complete governance across the whole AI stack[](#complete-governance-across-the-whole-ai-stack "Direct link to Complete governance across the whole AI stack")
Port [scorecards](/governance/standards-and-compliance/overview/.md) extend the same standards you already apply to services and pipelines to the gateway's agents, guardrails, and keys, so an ungoverned agent gets caught by the same mechanism as an undocumented service. Two pieces make this hold up as agents scale:
* **Unified agent creation.** Every agent gets scaffolded through Port, so the right traffic rules apply from the moment it exists, not bolted on afterward. See [Build an AI agent](/agent-management/custom-agents/build-an-ai-agent/.md) and [External agents](/agent-management/external-agents/overview/.md).
* **Dynamic policies.** Budget caps, tool access, and creation permissions can flex based on context (who is asking, what they are doing) instead of a static rule that either blocks legitimate work or lets risky work through. See [dynamic permissions](/workflows/actions-and-automations/create-self-service-experiences/set-self-service-actions-rbac/dynamic-permissions/examples/.md) for the same pattern on self-service actions.
Once agents outnumber the services they support, governance has to be built into how they are created, not a step someone remembers to run.
## Related capabilities[](#related-capabilities "Direct link to Related capabilities")
| You need to… | Port capability |
| -------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------- |
| Inventory agents alongside services and teams | [External agents](/agent-management/external-agents/overview/.md) and [agent registry](/agent-management/ai-registry/agent-registry/.md) |
| Govern which MCP servers and skills agents may use | [AI registry](/agent-management/ai-registry/skills/overview/.md) |
| Connect IDEs and agents to your catalog | [Port MCP server](/agent-management/port-mcp-server/overview/.md) |
| Enforce standards on agents, keys, and guardrails | [Scorecards](/governance/standards-and-compliance/overview/.md) |
The gateway routes the traffic. Port governs what runs through it.
---
# Agent registry
An agent registry is a governed inventory of external AI agents — both **code-first** agents built with SDKs and **cloud-managed** agents on platforms without a native Port connector — stored as entities in your Context Lake. Each registry entity tracks platform, status, model, region, and ownership so your organization can discover what exists instead of rebuilding agents in every squad.
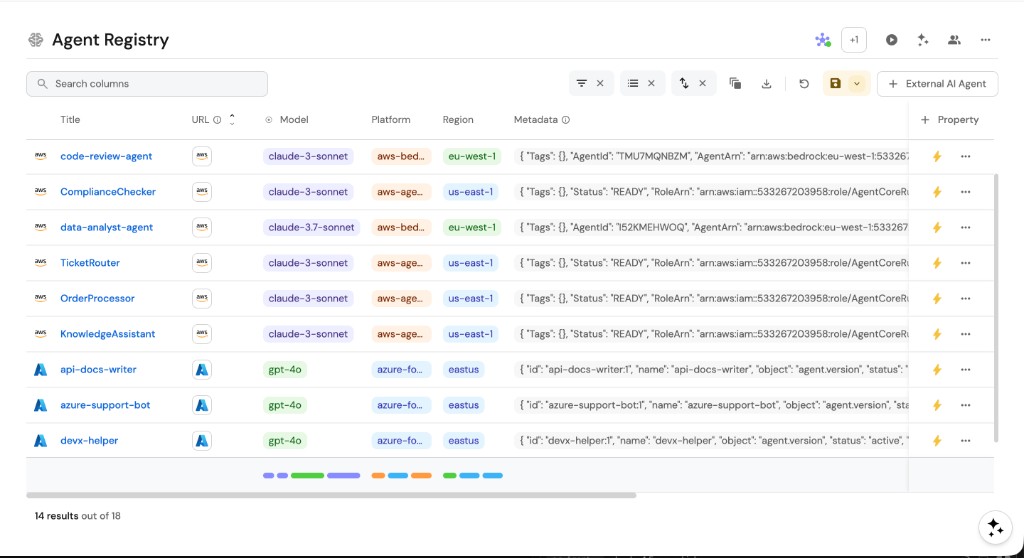
Port's built-in [`_ai_agent`](/context-lake/data-model/setup-blueprint/default-blueprints/.md) blueprint can represent agents in your Context Lake. A dedicated registry blueprint (for example `aiAgent`) adds the metadata platform teams need for governance: approval status, owning team, deployment region, and which cloud platform hosts the agent.
## What it solves[](#what-it-solves "Direct link to What it solves")
| Challenge | How a registry helps |
| -------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
| **No cross-platform visibility** | View Bedrock, Azure AI Foundry, and other cloud agents in one place in your Context Lake instead of checking each vendor console. |
| **Duplicate agents** | Developers can search the registry before building a new agent and reuse what already exists. |
| **Governance and compliance** | Track which models, regions, and statuses each agent uses for audit and policy reviews. |
## When to use a registry vs a native connector[](#when-to-use-a-registry-vs-a-native-connector "Direct link to When to use a registry vs a native connector")
| Approach | Best for |
| ------------------------- | ------------------------------------------------------------------------------------------------------------------------------- |
| **Native connector** | Platforms with a dedicated Port integration that syncs agents, sessions, and related resources automatically. |
| **Custom agent registry** | Multi-cloud visibility when you ingest agents from Bedrock, Azure AI Foundry, or other APIs through a custom Ocean integration. |
## Set up your registry[](#set-up-your-registry "Direct link to Set up your registry")
For blueprint JSON, integration mapping, and step-by-step setup for AWS Bedrock and Azure AI Foundry, see the guide [Build an AI Agent Registry](/guides/all/build-ai-agent-registry/.md).
## Where to go next[](#where-to-go-next "Direct link to Where to go next")
* [Managing AI primitives](/agent-management/ai-registry/managing-ai-primitives/.md) — skills, MCP, managed agents, context lake, and AI data controls in the AI registry.
* [External agents overview](/agent-management/external-agents/overview/.md) — how Port connects to agents hosted outside Port.
* [Skills registry](/agent-management/ai-registry/skills/skills-registry/.md) — govern reusable skills alongside your agent inventory.
* [MCP registry](/agent-management/ai-registry/mcp-registry/.md) — govern which MCP servers teams may use.
---
# Managing AI primitives
Port does not replace your coding agents. It gives them the same catalog, governance, and tooling context your teams already use so work can move from ticket to production safely.
Use these docs when you need skills, MCP access, managed agents, or guardrails:
* [Skills](/agent-management/ai-registry/skills/overview/.md) - reusable prompts and tool bundles your platform team can publish.
* [Skills usage analytics](/agent-management/ai-registry/skills/skills-usage-analytics/.md) - measure which skills teams adopt in Cursor and Claude.
* [Build an AI agent](/agent-management/custom-agents/build-an-ai-agent/.md) - configure a Port-managed agent against your catalog.
* [Interact with AI agents](/agent-management/custom-agents/interact-with-ai-agents/.md) - trigger and track runs from Slack, the UI, or workflows.
* [Port MCP server](/agent-management/port-mcp-server/overview/.md) - connect MCP clients to Port actions, entities, and scorecards.
* [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md) - managed connectors for external MCP servers.
* [Context Lake](/context-lake/overview/.md) - unified engineering context for accurate answers and actions.
* [Security and data controls for Port AI](/port-ai/security-and-data-controls/.md) - how Port handles AI-related data and access.
For the full ATR story, start with [Autonomous ticket resolution overview](/solutions/autonomous-ticket-resolution/overview/.md).
---
# MCP connectors
MCP Connectors turn Port into a unified MCP gateway, routing requests from developers and AI agents to external MCP servers while applying Port's governance, RBAC, and audit controls. Platform engineers configure which MCP servers are available and which tools are exposed. Developers and AI agents access everything through a single interface.
[YouTube video player](https://www.youtube.com/embed/6VBhFq5SJ0s)
## Why MCP connectors?[](#why-mcp-connectors "Direct link to Why MCP connectors?")
Organizations building AI agents need access to tools beyond Port's native integrations. For example, internal documentation, custom systems, third-party platforms. Without MCP Connectors, teams either run parallel MCP systems (creating confusion) or build their own gateway infrastructure (recreating governance from scratch).
MCP Connectors solve three critical challenges:
* **Unified developer experience**: Connect once to Port's MCP gateway instead of managing multiple separate integrations. Developers access Port's native tools and all approved external MCPs through one interface.
* **Governance and control**: Platform engineers choose which MCPs are approved, which tools are exposed, and who can access them. Complete audit trails and RBAC enforcement apply to all tool invocations.
* **Holistic data access**: Port AI uses the [Context Lake](/context-lake/overview/.md) for structured organizational data and MCP Connectors for ephemeral or time-series data that doesn't belong in your data model. Refer to the following [article](https://www.port.io/blog/why-ai-agents-need-a-context-lake) to learn more about why agents need both types of data.
## Integrations vs. MCP connectors[](#integrations-vs-mcp-connectors "Direct link to Integrations vs. MCP connectors")
MCP connectors complement Port integrations rather than replace them — they serve different purposes and work best together. See [Integrations vs. MCP connectors](/context-lake/ingestion/integrations-vs-mcp/.md) for guidance on when to use each and when to use both.
## Setting up MCP connectors[](#setting-up-mcp-connectors "Direct link to Setting up MCP connectors")
Admins configure which MCP connectors are available organization-wide and control which tools each connector exposes.
### Prerequisites[](#prerequisites "Direct link to Prerequisites")
* Admin role in Port.
* Account credentials for the external tool you want to connect.
### Add a connector[](#add-a-connector "Direct link to Add a connector")
1. Go to the [connectors](https://app.port.io/settings/data-sources) page in Port.
2. Click on the `+ Connector` in the top-right corner.
3. Select the **MCP Servers** tab.
4. Choose from the available MCP servers (like Notion, Linear, Slack, GitLab, etc) or select **Custom Server** to add your own.
5. Fill in the connector details:
* **Name** (required): A recognizable name for developers and AI agents.
* **Description**: When this MCP should be used and for which use cases. This helps AI agents determine when to use this connector.
* **URL** (required): The remote MCP server endpoint.
* **Icon**: Select an icon to visually identify the connector.
* **Team**: Assign ownership to a specific team.
* **Headers**: Custom headers to include with requests (e.g., for API key authentication).
6. Click **Connect** and complete the authentication flow if required.
7. Under **Allowed Tools**, select which tools to expose to your organization using `+ Add Tool`. Only the tools you add will be visible to users. **Consider carefully before enabling write or delete capabilities** - users and AI agents will be able to perform these actions based on their permissions in the external tool.
8. Click `Publish` to make the connector available to users.
Any remote MCP server
You can connect any remote MCP server and not just the ones listed in the UI. Select **Custom Server** to add tools like Confluence, Kiro, or any other MCP-compatible service that provides a remote endpoint.
**Advanced OAuth settings**
For MCP servers that require manual OAuth configuration, you can expand the **Advanced OAuth Settings** section and provide:
* **OAuth Client ID** and **OAuth Client Secret**: From the OAuth application you created in the external service.
* **OAuth Scope**: The permissions to request during authentication.
* **OAuth grant type**: Choose **Authorization code** for per-user or one-time organization consent, or **Client credentials** when the upstream server supports machine-to-machine OAuth for automated workflows.
MCP connectors can also be added from the MCP connector catalog page. When adding from the catalog, an additional property is available:
**Expose Port Connector**: Determines whether this entity is used as an active MCP connector. When enabled, the connector's tools are available to users through the AI assistant and Port MCP server. When disabled, the entity exists in the catalog but is not used as an MCP connector.
In-chat configuration
When a user asks for a tool that maps to an MCP server not yet configured for the organization, the Port AI assistant can offer to configure it inline by opening the same setup wizard. Users with permission to add MCP connectors see a configure option in chat. Users without that permission are told to ask an admin.
### Supported server types[](#supported-server-types "Direct link to Supported server types")
Port supports several types of remote MCP servers. All require **Name** and **URL**. Additional configuration depends on the authentication method:
* **Dynamic client registration** (e.g., Notion, Slack): Servers that support [OAuth 2.0 Dynamic Client Registration](https://datatracker.ietf.org/doc/html/rfc7591). Port automatically registers as an OAuth client - no additional configuration required.
* **Manual client registration** (e.g., GitHub, GitLab): Servers that require you to create an OAuth application first. Configure **OAuth Client ID**, **OAuth Client Secret**, and optionally **OAuth Scope** under Advanced OAuth Settings. Choose **Authorization code** for per-user or one-time organization consent, or **Client credentials** when the upstream server supports machine-to-machine OAuth and you need a fully headless connection for automated workflows.
* **API-based authentication**: Servers that use API keys or tokens. Add authentication credentials via **Headers** (e.g., `Authorization: Bearer `).
* **No authentication** (e.g., GitMCP): Publicly accessible servers - no additional configuration required.
### Advanced MCP server configurations[](#advanced-mcp-server-configurations "Direct link to Advanced MCP server configurations")
Some MCP servers require more detailed configuration than just a URL and authentication headers. For example, servers that use manual OAuth client registration require you to first create an OAuth application in the external service and then paste the credentials into Port.
See [GitHub MCP connector](/agent-management/ai-registry/mcp-connectors/github-mcp-connector/.md) for a step-by-step example of this setup.
### Reference organization secrets[](#reference-organization-secrets "Direct link to Reference organization secrets")
When configuring authentication (via headers or Advanced OAuth Settings), you can reference your organization's secrets using the following syntax:
```
{{ .secrets["YOUR_SECRET_KEY"] }}
```
**In headers:**
```
{ "Authorization": "{{ .secrets[\"YOUR_SECRET_KEY\"] }}" }
```
**In Advanced OAuth Settings inputs:**
Use the same syntax in the **OAuth Client ID** and **OAuth Client Secret** fields to reference stored secrets:
```
{{ .secrets["YOUR_SECRET_KEY"] }}
```
## Authenticate to connectors[](#authenticate-to-connectors "Direct link to Authenticate to connectors")
Once your admin has configured MCP connectors, you need to authenticate your personal account to use them.
Connectors configured with the **client credentials** grant type are the exception: clicking **Connect** authenticates them without a browser consent screen, and the resulting tokens are stored for the whole organization.
### From the MCP Servers menu[](#from-the-mcp-servers-menu "Direct link to From the MCP Servers menu")
1. Open the [MCP Servers](https://app.port.io/organization/home?openModal=mcpServers) modal and select the **External MCP** tab.
2. You will see the MCP servers your admin has made available.
3. Click **Connect** on one and complete the OAuth authentication flow.
4. The MCP server is now available in all Port AI interfaces.
### From Port AI assistant[](#from-port-ai-assistant "Direct link to From Port AI assistant")
1. Open the Port AI chat interface.
2. Click the **+** button to see available MCP servers.
3. Under **Need to Connect**, you will see servers that require authentication.
4. Click on one to initiate authentication.
5. Complete the OAuth flow.
6. After authenticating, the server appears under **Connectors** with the number of enabled tools (e.g., "9 of 10").
The assistant can prompt you
When a task needs an MCP server that is configured for your organization but that you have not connected yet, the Port AI assistant surfaces a **Connect** card directly in the chat. Click **Connect** on the relevant server to complete the OAuth flow without leaving the conversation.
### Manage your tools[](#manage-your-tools "Direct link to Manage your tools")
After authenticating, you can toggle which tools are active for your account:
1. In the Port AI chat, click the **+** button.
2. Under **Connectors**, click the arrow next to an authenticated server.
3. Toggle individual tools on or off based on your needs.
You can only toggle tools that your admin has enabled. Tools not added by the admin will not appear.
## Using MCP connectors[](#using-mcp-connectors "Direct link to Using MCP connectors")
After authenticating, you can use natural language to interact with external tools through any Port AI interface.
**Example queries:**
* "Search Notion for our API authentication documentation"
* "Find the deployment runbook in Confluence"
* "Show me open Jira tickets for the payments service"
* "What alerts fired in the last hour?"
### IDE access[](#ide-access "Direct link to IDE access")
If you've connected your IDE to [Port's MCP server](/agent-management/port-mcp-server/installation/.md), your authenticated MCP connectors are automatically available alongside Port's native tools.
Connector tools are exposed with a prefixed name: `{connector_identifier}_{tool_name}`. For example, a Notion connector with identifier `notion_pms` that exposes `notion-create-view` appears in your IDE as `notion_pms_notion-create-view`. You can see the exact tool names for each connector in the [MCP Servers](https://app.port.io/organization/home?openModal=mcpServers) modal, under the **External MCP** tab.
If connector tools appear in Port AI but not in your IDE, work through the troubleshooting steps in the FAQ below.
## Security and permissions[](#security-and-permissions "Direct link to Security and permissions")
* **Per-user authentication**: Each user authenticates with their own account. Data access respects individual permissions in the external tool.
* **RBAC enforcement**: Port's role-based access controls apply to all MCP connector access.
* **Audit logging**: All tool invocations are logged as part of [AI invocations](/port-ai/ai-invocations/.md).
For more details, see [AI Security and Data Controls](/port-ai/security-and-data-controls/.md).
## Limitations[](#limitations "Direct link to Limitations")
* **Self-hosted MCP servers**: Only remote MCP servers are supported. Self-hosted MCP servers cannot be connected as MCP connectors.
* **AI agents**: MCP connectors on [AI agent](/agent-management/custom-agents/overview/.md) entities work in interactive chat when the user connects to each server. They do not run in automations or `AI_AGENT` workflow nodes. For automated external MCP, use workflow `type: "AI"` nodes with `mcpServers`. See [use MCP connectors in workflows](/agent-management/ai-registry/mcp-connectors/use-in-workflows/.md), [build an AI agent](/agent-management/custom-agents/build-an-ai-agent/.md), and [external MCP connectors in workflows](/workflows/build-workflows/nodes/action-nodes/ai/.md#external-mcp-connectors-in-workflows).
* **Automated workflows**: Workflow `AI` nodes run with an organization automation token. Per-user OAuth connectors are not supported. Use [organization-level OAuth](/agent-management/ai-registry/mcp-connectors/use-in-workflows/.md) or [shared header authentication](/agent-management/ai-registry/mcp-connectors/.md#which-authentication-method-should-i-use-for-mcp-connectors).
* **Remote MCP OAuth flows**: OAuth for MCP connectors supports both interactive and headless paths. Per-user and organization-level **authorization code** flows require browser consent. Organization-level **client credentials** lets Port exchange the connector's OAuth Client ID and Client Secret with the upstream MCP server without browser consent, when the upstream server supports that grant. Port stores and refreshes tokens where supported. See [use in workflows](/agent-management/ai-registry/mcp-connectors/use-in-workflows/.md).
## FAQ[](#faq "Direct link to FAQ")
1What happens if my authentication expires?
2Can AI agents use MCP connectors?
3A user says MCP connectors aren't visible - what should I check?
4Connector tools work in Port AI but not in my IDE - what should I check?
5How do I confirm which Port organization my MCP client is using?
6How are MCP connector tool names formatted?
7Which authentication method should I use for MCP connectors?
8Do I need to provide a token endpoint when connecting to servers like AWS AgentCore?
---
# GitHub MCP connector
This page covers setting up the GitHub MCP connector. The GitHub MCP connector relies on the general [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md) features - refer to that page for an overview of how MCP connectors work.
The GitHub MCP server uses manual OAuth client registration, which means you need to create a GitHub OAuth app before configuring the connector in Port.
## Setup steps[](#setup-steps "Direct link to Setup steps")
### 1. Create a GitHub OAuth app[](#1-create-a-github-oauth-app "Direct link to 1. Create a GitHub OAuth app")
In your GitHub organization settings, create a new OAuth app with the following fields:
* **Application name**: Any recognizable name, e.g. `Port MCP Connector`.
* **Homepage URL**: `https://app.port.io`
* **Authorization callback URL (EU region)**: `https://api.port.io/v1/mcp/oauth2/callback`
US region
If your Port organization is on the US region, use `https://api.us.port.io/v1/mcp/oauth2/callback` as the callback URL instead.
After registering the app, copy the **Client ID** and generate a **Client Secret** (copy it immediately - it is only shown once).
For more information on creating a GitHub OAuth app, see the [GitHub documentation](https://docs.github.com/en/apps/oauth-apps/building-oauth-apps/creating-an-oauth-app).
### 2. Configure the connector in Port[](#2-configure-the-connector-in-port "Direct link to 2. Configure the connector in Port")
In Port, open the GitHub MCP connector (go to **Connectors** > **MCP Servers** > **GitHub**), expand **Advanced OAuth Settings**, and fill in:
* **OAuth Client ID**: The client ID from step 1.
* **OAuth Client Secret**: The client secret from step 1.
* **OAuth Scope**: `repo,read:org` (minimum required scope).
Save and publish the connector.
### 3. Authenticate and use[](#3-authenticate-and-use "Direct link to 3. Authenticate and use")
Follow the standard [MCP connector authentication steps](/agent-management/ai-registry/mcp-connectors/.md#authenticate-to-connectors). Users will be redirected through the GitHub OAuth flow when they first connect.
---
# Use in workflows
Workflow `type: "AI"` nodes call external tools through [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md). These nodes run with an **organization automation token**, not the triggering user's session, so a per-user OAuth connector is not callable from a workflow. The workflow-usable OAuth paths are **organization-level OAuth**: either one-time admin consent (authorization code) or a fully headless client credentials exchange.
This page uses the `atlassian` MCP connector as the running example. You can substitute any OAuth-based MCP connector your admin has registered and published.
Prefer shared headers when available
If the connector supports API keys, [shared header authentication](/agent-management/ai-registry/mcp-connectors/.md#which-authentication-method-should-i-use-for-mcp-connectors) is usually simpler for automated workflows. Use organization-level OAuth when the connector requires OAuth.
We will:
* Get an organization access token.
* Connect the connector at the organization level (authorization code or client credentials, depending on how the connector is configured).
* Validate that the connection is `usable`.
* Create a workflow with one `type: "AI"` node scoped to a single connector tool.
* Trigger the workflow and verify the tool's response.
Which grant type does your connector use?
**Client credentials** connectors are connected from the Port UI, once, by an admin. Port stores those tokens at the organization level, so connecting them takes two clicks and no API calls - see [step 2](#client-credentials).
**Authorization code** connectors store tokens per user, so connecting as yourself in the UI does not make the connector callable from a workflow. Those connectors need the API flow in [step 2](#authorization-code), run with your organization credentials.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
Before you start, make sure you have:
* A [registered and published](/agent-management/ai-registry/mcp-connectors/.md) MCP connector with at least one tool enabled under **Allowed Tools**.
* Admin access in the same Port organization, including the organization's `Client ID` and `Client Secret`.
* `curl` and `jq` installed.
* The **identifier** of the MCP connector, as set when it was registered. Find it on the **MCP servers** catalog page at `app.port.io//_mcp_servers` in the **Identifier** column.
## Step 1: Set your region and get an organization access token[](#step-1-set-your-region-and-get-an-organization-access-token "Direct link to Step 1: Set your region and get an organization access token")
Set the API base URL for your region, then set your organization credentials and connector identifier. Later commands reuse `$API_BASE`, `$CLIENT_ID`, `$CLIENT_SECRET`, and `$CONNECTOR`.
* EU region
* US region
EU region
```
API_BASE='https://api.port.io'
```
US region
```
API_BASE='https://api.us.port.io'
```
Set your variables
```
CLIENT_ID=''
CLIENT_SECRET=''
CONNECTOR='atlassian'
```
Replace `` and `` with your organization credentials from the **Credentials** page, and set `CONNECTOR` to your MCP connector identifier if it differs from `atlassian`.
Exchange your organization credentials for an access token. This token is organization-level, not personal.
Get an organization access token
```
TOKEN=$(curl -s -X POST "$API_BASE/v1/auth/access_token" \
-H 'Content-Type: application/json' \
-d "{\"clientId\":\"$CLIENT_ID\",\"clientSecret\":\"$CLIENT_SECRET\"}" \
| jq -r '.accessToken')
```
You can also generate this token in the Port UI: open the [Credentials](https://app.port.io/organization/home?openModal=credentials) modal, select the **Organization** tab, and click **Generate API token**. See [Create an access token](/api-reference/create-an-access-token/).
## Step 2: Connect at the organization level[](#step-2-connect-at-the-organization-level "Direct link to Step 2: Connect at the organization level")
Follow the option below that matches the connector's **OAuth grant type**.
### Client credentials[](#client-credentials "Direct link to Client credentials")
Connect the connector from the Port UI:
1. Open the [MCP Servers](https://app.port.io/organization/home?openModal=mcpServers) modal and select the **External MCP** tab.
2. Click **Connect** on the connector.
There is no consent screen. Port exchanges the connector's OAuth Client ID and Client Secret with the upstream server and stores the resulting tokens for the whole organization, so one admin connecting once is enough for every workflow.
### Authorization code[](#authorization-code "Direct link to Authorization code")
Paste this whole block to get a short-lived session token for the connector and open the upstream provider's consent screen in your browser.
Get a session token and open the consent screen
```
SESSION_TOKEN=$(curl -s "$API_BASE/v1/mcp/oauth2/servers/$CONNECTOR/session-token" \
-H 'Accept: application/json' \
-H "Authorization: Bearer $TOKEN" \
| jq -r '.sessionToken')
AUTH_URL=$(curl -s -o /dev/null -w '%{redirect_url}' \
"$API_BASE/v1/mcp/oauth2/authenticate?server_id=$CONNECTOR&session_token=$SESSION_TOKEN")
if [ -z "$AUTH_URL" ]; then
echo "No redirect URL returned. Check that TOKEN and SESSION_TOKEN are valid and not expired." >&2
elif command -v open >/dev/null 2>&1; then
open "$AUTH_URL"
elif command -v xdg-open >/dev/null 2>&1; then
xdg-open "$AUTH_URL"
else
echo "Open this URL in a browser: $AUTH_URL"
fi
```
In the browser, confirm the authorization and approve the permissions for the MCP app. Port then stores the OAuth connection at the organization level. Upstream actions in the external tool are attributed to the account you consent with, not to each workflow triggerer. This consent is needed once; Port refreshes the token where supported.
The `server_id` is the Port-side identifier of the registered connector (for example `atlassian`), not the upstream MCP URL. See [Get OAuth2 session token](/api-reference/get-o-auth-2-session-token/) and [Initiate OAuth2 authentication](/api-reference/initiate-o-auth-2-authentication/).
## Step 3: Validate the connection[](#step-3-validate-the-connection "Direct link to Step 3: Validate the connection")
Confirm the connector is connected and callable before wiring it into a workflow. This check applies to the **authorization code** flow above.
Client credentials connectors
This endpoint reports whether the *calling* identity has connected the connector, so a client credentials connector that an admin connected in the UI can still report `usable: false` here. Its tokens are stored for the organization and the workflow AI node will use them, so verify with the smoke test in [step 5](#step-5-trigger-the-workflow-and-verify) instead.
Check the connector is usable
```
curl -s "$API_BASE/v1/mcp/user/servers?includeTools=true" \
-H "Authorization: Bearer $TOKEN" \
| jq --arg id "$CONNECTOR" '.servers[] | select(.identifier==$id) | {identifier, usable, error, toolNames: [.tools[].name]}'
```
Look for `usable: true`, which means the organization-level OAuth connection is live and callable by an AI node. If `error` is populated, recheck steps 1 and 2. The `toolNames` are the prefixed tool names you scope to in the workflow node's `tools` array.
MCP tool names follow the `{identifier}_{upstream}` convention, for example `atlassian_atlassianUserInfo`, `atlassian_getJiraIssue`, or `atlassian_searchConfluenceUsingCql`. The prefix is the connector identifier. Use these exact prefixed names in the `tools` array.
## Step 4: Create a workflow AI node that calls the connector[](#step-4-create-a-workflow-ai-node-that-calls-the-connector "Direct link to Step 4: Create a workflow AI node that calls the connector")
We will create the simplest possible workflow: a self-serve trigger feeding one `type: "AI"` node that calls a single Atlassian tool through the `atlassian` connector, with a structured `outputSchema`.
Save the workflow definition to a file:
**Smoke-test workflow JSON (click to expand)**
mcp-atlassian-smoke-test.json
```
{
"identifier": "mcp-atlassian-smoke-test",
"title": "MCP Atlassian smoke test",
"description": "Calls the Atlassian MCP connector from a workflow AI node.",
"icon": "Atlassian",
"nodes": [
{
"identifier": "trigger",
"title": "Trigger",
"config": {
"type": "SELF_SERVE_TRIGGER",
"userInputs": { "properties": {} }
}
},
{
"identifier": "ai-call",
"title": "Call Atlassian MCP",
"config": {
"type": "AI",
"userPrompt": "Call the atlassian_atlassianUserInfo tool once and return the authenticated user name and email as JSON.",
"systemPrompt": "Call atlassian_atlassianUserInfo exactly once, then return the JSON schema immediately. Do not call other tools. Do not loop.",
"tools": ["atlassian_atlassianUserInfo"],
"mcpServers": [{ "identifier": "atlassian" }],
"outputSchema": {
"type": "object",
"properties": {
"name": { "type": "string" },
"email": { "type": "string" }
},
"required": ["name", "email"]
}
}
}
],
"connections": [
{ "sourceIdentifier": "trigger", "targetIdentifier": "ai-call" }
]
}
```
Create the workflow with the [Create a workflow](/api-reference/create-a-workflow/) API:
Create the workflow
```
curl -s -X POST "$API_BASE/v1/workflows" \
-H "Authorization: Bearer $TOKEN" \
-H 'Content-Type: application/json' \
-d @mcp-atlassian-smoke-test.json | jq
```
Key fields:
* `mcpServers: [{ "identifier": "atlassian" }]` references the connector by its Port-side identifier. This must equal `$CONNECTOR` from step 1, so update it if you swapped connectors.
* `tools: ["atlassian_atlassianUserInfo"]` scopes the AI node to one tool, using the `{identifier}_{upstream}` naming convention from step 3. Use explicit tool lists in workflows, not defaults.
* `systemPrompt` caps the AI to one tool call and forces an immediate return, which prevents runaway loops in automated runs.
* `outputSchema` forces a structured JSON response so downstream nodes can parse fields directly.
See [external MCP connectors in workflows](/workflows/build-workflows/nodes/action-nodes/ai/.md#external-mcp-connectors-in-workflows) and [MCP servers in API requests](/port-ai/tools-and-approvals/.md#mcp-servers-in-api-requests) for the full node shape and patterns.
## Step 5: Trigger the workflow and verify[](#step-5-trigger-the-workflow-and-verify "Direct link to Step 5: Trigger the workflow and verify")
Trigger a run, then poll it until the status is `COMPLETED` or `FAILED` (about 60 seconds max):
Trigger and poll the run
```
RUN_ID=$(curl -s -X POST "$API_BASE/v1/workflows/mcp-atlassian-smoke-test/runs" \
-H "Authorization: Bearer $TOKEN" \
-H 'Content-Type: application/json' \
-d '{}' | jq -r '.workflowRun.identifier')
for i in $(seq 1 12); do
STATUS=$(curl -s "$API_BASE/v1/workflows/runs/$RUN_ID" -H "Authorization: Bearer $TOKEN" | jq -r '.workflowRun.status')
[[ "$STATUS" == "COMPLETED" || "$STATUS" == "FAILED" ]] && break
sleep 5
done
curl -s "$API_BASE/v1/workflows/runs/$RUN_ID" \
-H "Authorization: Bearer $TOKEN" | jq '.workflowRun.status, .workflowRun.result, .workflowRun.nodeRuns'
```
A successful run returns `status: "COMPLETED"` and `result: "SUCCESS"`, and the `ai-call` node output contains the tool's response. That confirms the AI node reached the connector and returned real data. If the status is `FAILED`, inspect `nodeRuns` for the error. See [Trigger a workflow run](/api-reference/trigger-a-workflow-run/) and [Get a workflow run by identifier](/api-reference/get-a-workflow-run-by-identifier/).
## Next steps[](#next-steps "Direct link to Next steps")
* Swap the smoke-test tool for a real one, such as `atlassian_getJiraIssue` or `atlassian_searchConfluenceUsingCql`, and wire the AI node into a larger workflow with downstream nodes that parse the `outputSchema` fields.
* Scope the `tools` array to the minimum set the workflow needs, and keep the `systemPrompt` constrained to prevent loops in automated runs.
* If the connector supports API keys, compare this approach with [shared header authentication](/agent-management/ai-registry/mcp-connectors/.md#which-authentication-method-should-i-use-for-mcp-connectors) to pick the right method for automated callers.
* If a connector only needs to be callable from interactive Port AI chat (not workflows), use the per-user [authenticate to connectors](/agent-management/ai-registry/mcp-connectors/.md#authenticate-to-connectors) flow instead.
---
# MCP registry
The MCP registry is an organizational catalog of MCP servers your teams are allowed to use. Platform teams define which servers are approved, developers discover what is available, and new servers enter through a governed request flow instead of ad hoc installs.
Port's built-in [`_mcp_server`](/context-lake/data-model/setup-blueprint/default-blueprints/.md#mcp-server) blueprint stores connectors you configure under **Connectors**. An MCP registry blueprint (for example `mcpRegistry`) adds approval status, ownership, installation guidance, and labels so you can answer: *which MCPs are approved in our org?*

## What you set up[](#what-you-set-up "Direct link to What you set up")
| Piece | Purpose |
| ----------------------------- | ----------------------------------------------------------------------------------------------------------- |
| **MCP registry blueprint** | Catalog entity per MCP server with approval status, type, labels, install docs, and optional tool metadata. |
| **Request MCP server action** | Self-service form for developers to propose a new server; creates a `pending` registry entry. |
| **Catalog views** | Browse and filter approved servers; optional scorecards or dashboards for governance. |
For a full step-by-step implementation (blueprint JSON, action JSON, and optional GitHub tool extraction), see the guide [Manage MCP server registry](/guides/all/manage-mcp-registry/.md).
## Create the MCP registry blueprint[](#create-the-mcp-registry-blueprint "Direct link to Create the MCP registry blueprint")
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Create a blueprint (for example identifier `mcpRegistry`, title **MCP registry**).
3. Add properties that support governance and discovery, for example:
* **Approval status** (`approved`, `pending`, `rejected`).
* **Server type** (`internal` or `external`).
* **Description** and **installation instructions** (markdown).
* **Labels** (array) for capabilities such as `database`, `java`, or `filesystem`.
* **Repository URL**, **command**, and **endpoint** when relevant.
4. Add relations such as **owning team** and **requested by** (user).
Start from the guide JSON
The [Manage MCP server registry](/guides/all/manage-mcp-registry/.md) guide includes copy-paste blueprint definitions for `mcpRegistry` and an optional `mcpToolSpecification` blueprint if you sync tools from MCP servers automatically.
## Add a self-service action to request a new MCP[](#add-a-self-service-action-to-request-a-new-mcp "Direct link to Add a self-service action to request a new MCP")
Give developers a **Request new MCP server** action that creates a registry entity in `pending` status.
1. Go to the [self-service](https://app.getport.io/self-serve) page in Port.
2. Create an action with operation **CREATE** on your registry blueprint.
3. Collect inputs such as server name, type, repository URL, description, labels, command, endpoint, and business justification.
4. Map the action to an **upsert entity** invocation that sets `status` to `pending` and relates **requested by** to the triggering user.
After submission, platform teams review the entity, update status to `approved` or `rejected`, and enrich installation instructions for approved servers.
 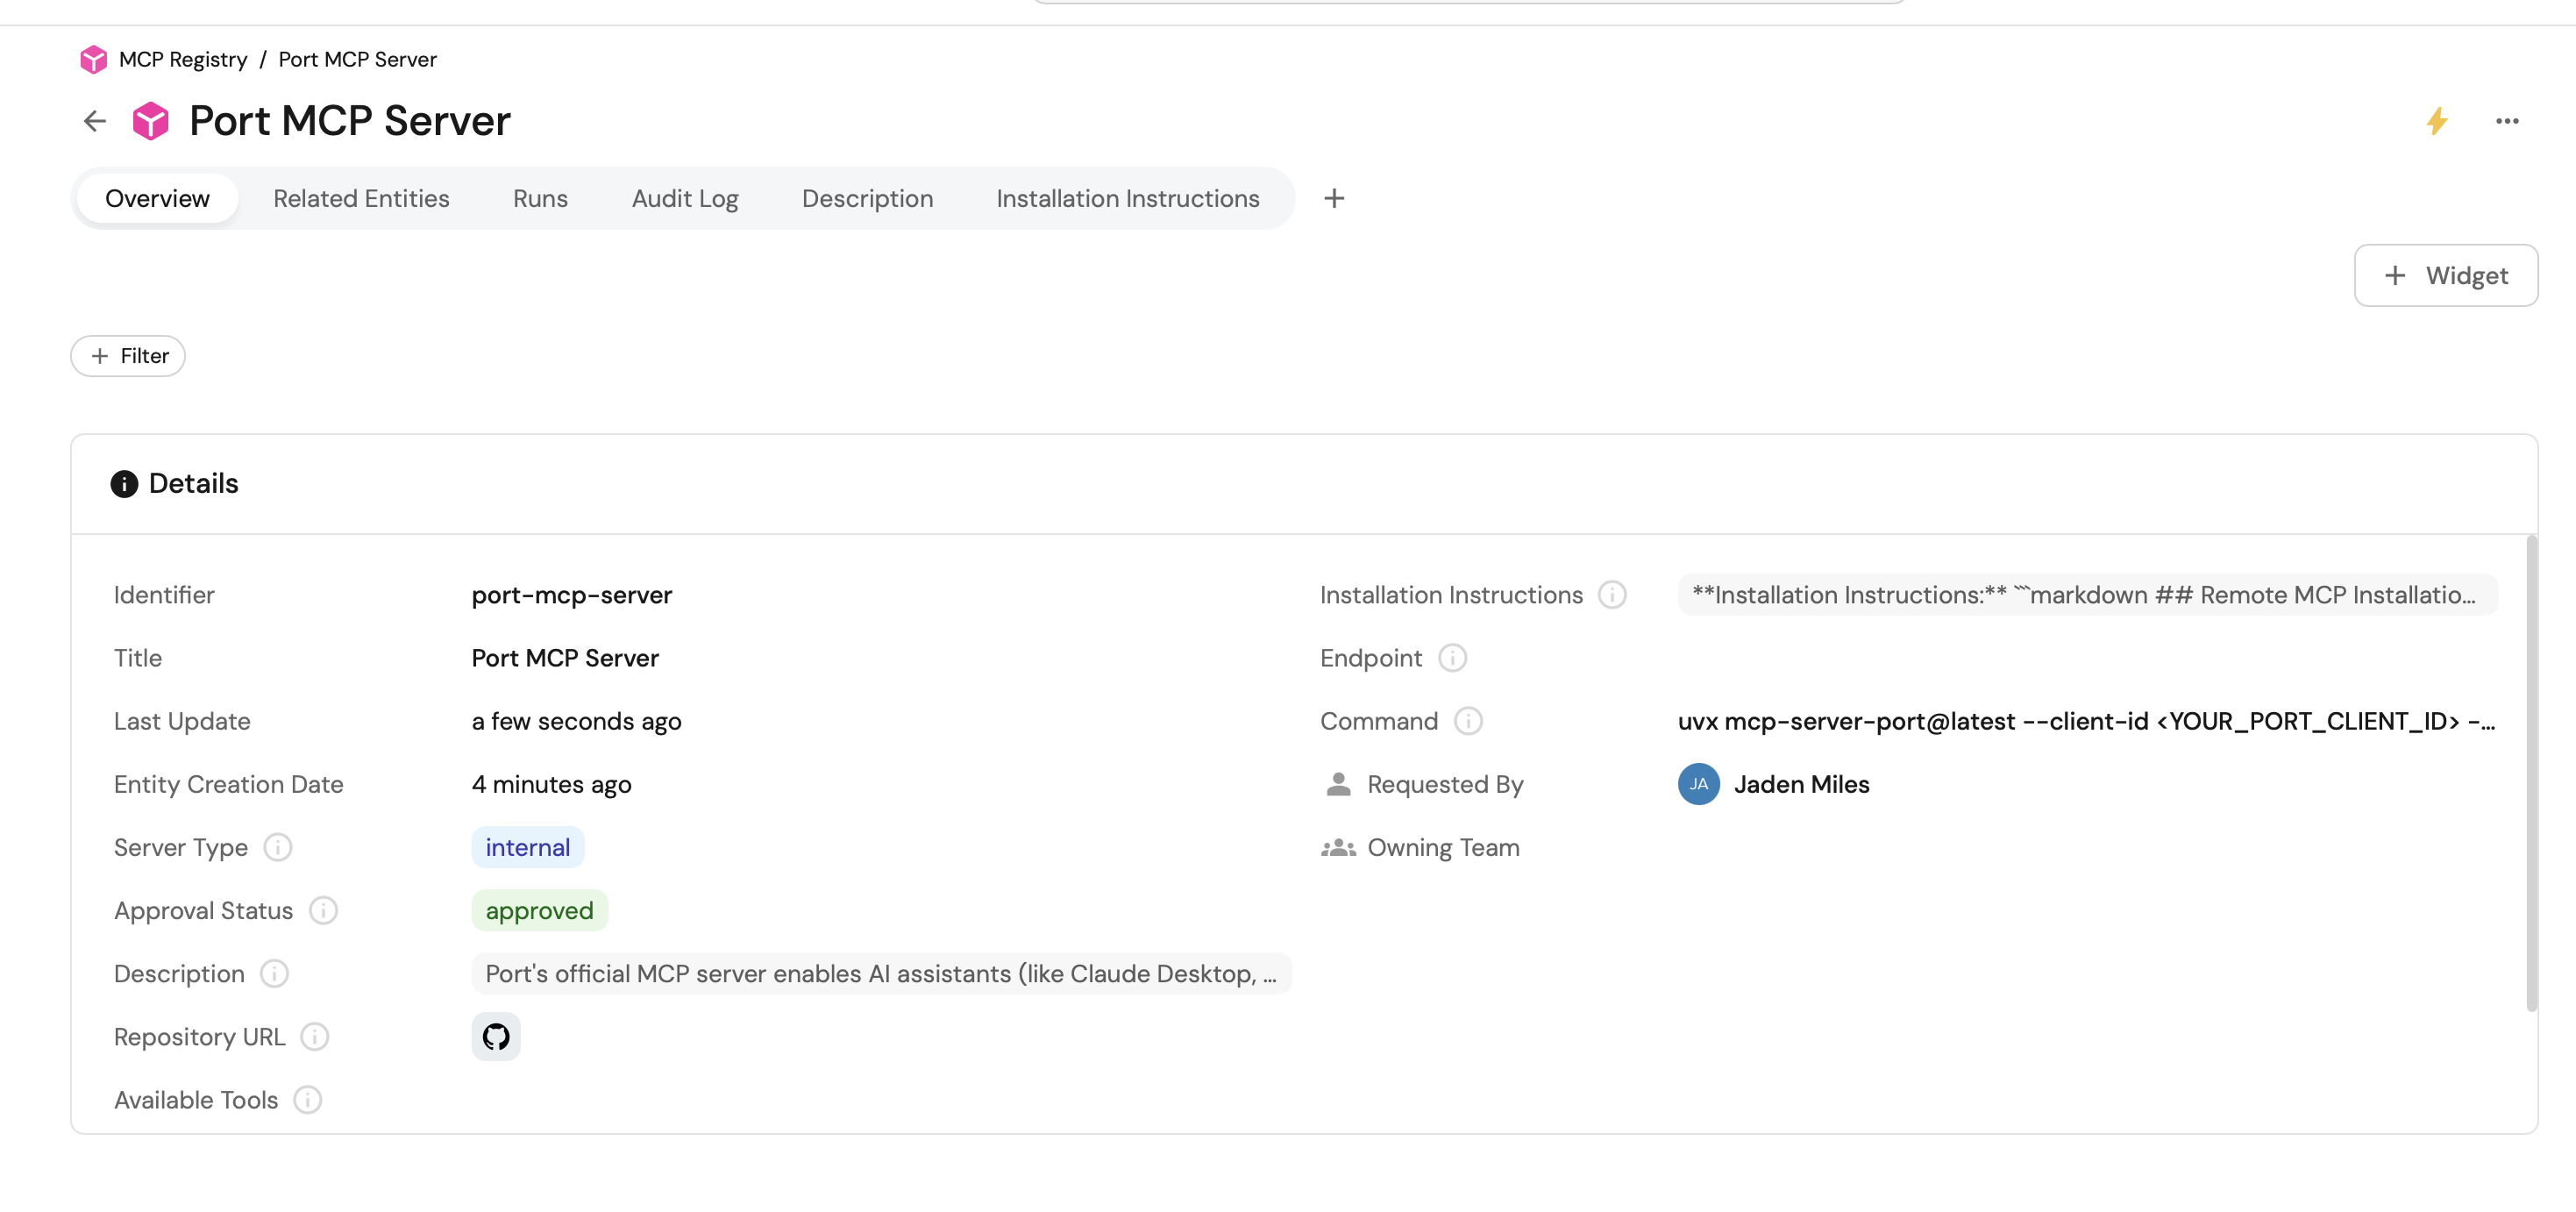
## See which MCP servers are approved in your org[](#see-which-mcp-servers-are-approved-in-your-org "Direct link to See which MCP servers are approved in your org")
### In the catalog[](#in-the-catalog "Direct link to In the catalog")
1. Open the [MCP registry](https://app.getport.io/mcpServers) page in your portal (or your custom catalog page for the registry blueprint).
2. Filter or sort by **approval status** = `approved`.
3. Open an entity to read installation instructions, labels, available tools, and ownership.
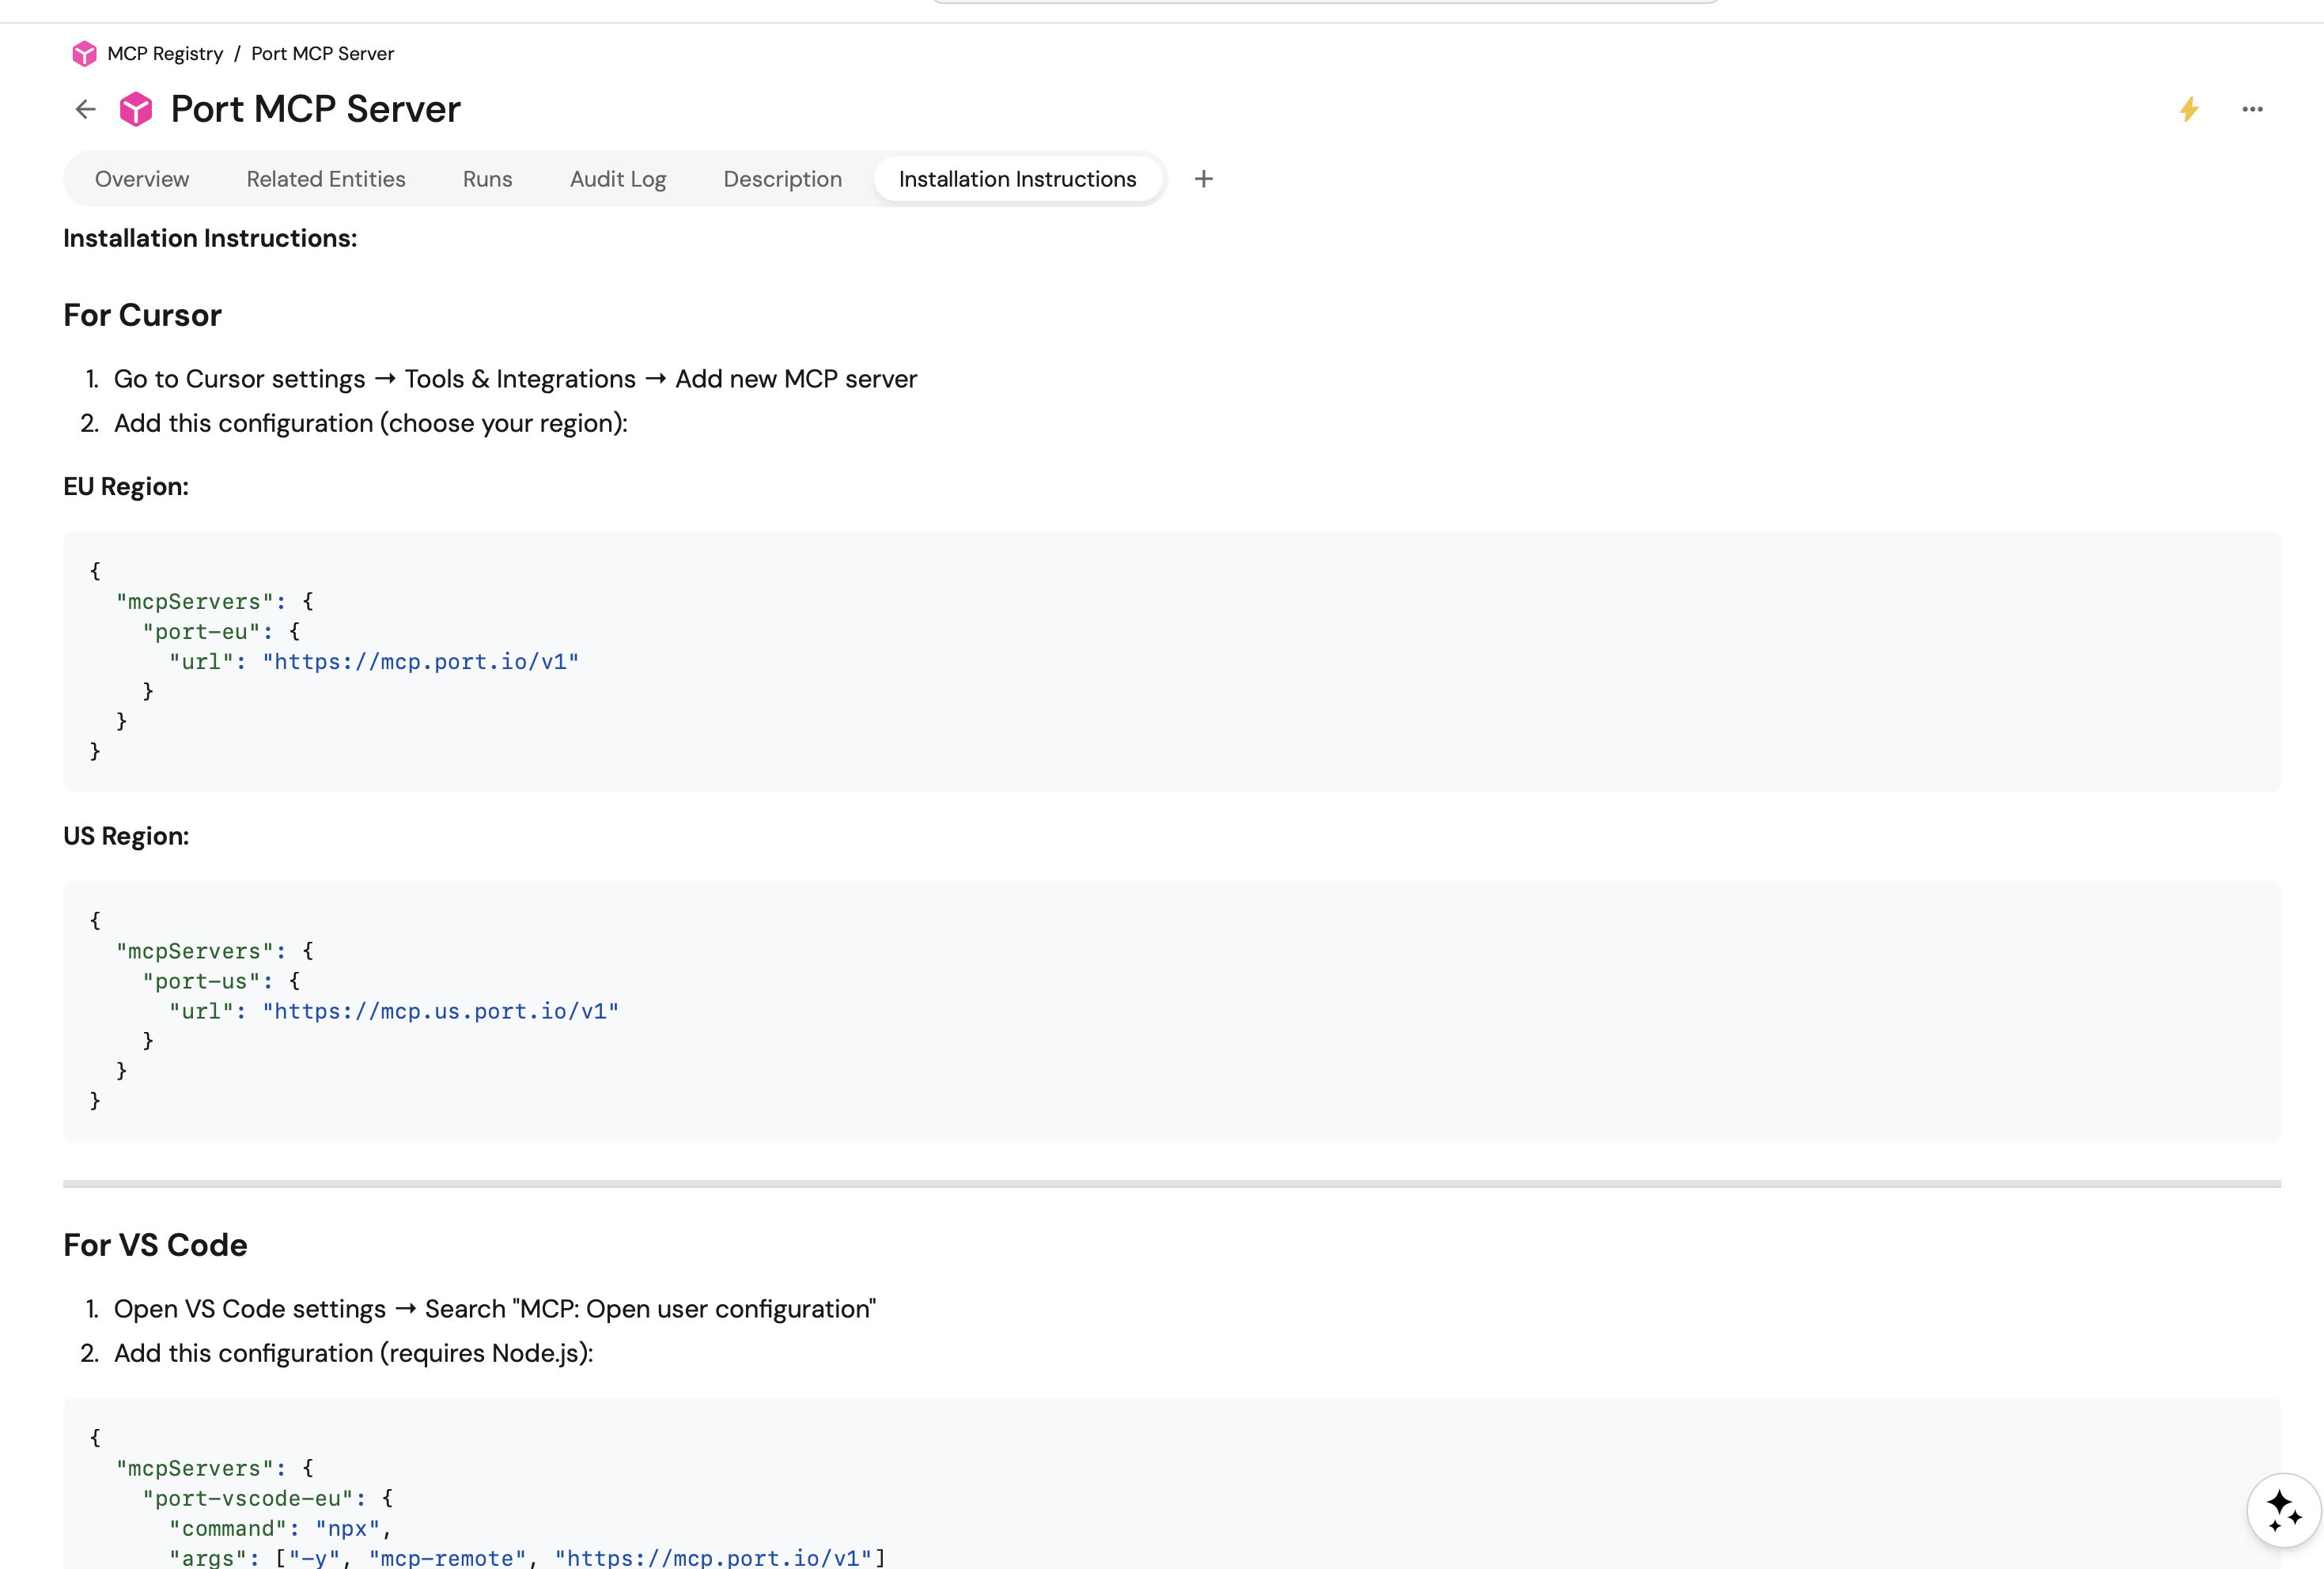
### With Port AI and IDEs[](#with-port-ai-and-ides "Direct link to With Port AI and IDEs")
When the registry lives in your [Context Lake](/context-lake/overview/.md), [Port AI](/port-ai/overview/.md) and the [Port MCP server](/agent-management/port-mcp-server/overview/.md) can answer discovery questions, for example:
* Which MCP servers are approved for our team?
* Which servers support database operations?
* What are the install steps for the approved PostgreSQL MCP?
Approved servers configured as [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md) are also available to Port AI through the unified MCP gateway.
## How this fits with Port MCP server[](#how-this-fits-with-port-mcp-server "Direct link to How this fits with Port MCP server")
| Capability | MCP registry (catalog) | Port MCP server |
| -------------------------------- | ------------------------------- | ------------------------------------------------------------------------------- |
| Govern which servers are allowed | Yes | Uses approved connectors |
| Install/config for developers | Documented on registry entities | [Overview and installation](/agent-management/port-mcp-server/installation/.md) |
| Query catalog from IDE | Via discovery + connector setup | Native MCP tools |
## Where to go next[](#where-to-go-next "Direct link to Where to go next")
* [Manage MCP server registry](/guides/all/manage-mcp-registry/.md) — full blueprint, action, and optional tool-extraction workflow.
* [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md) — connect approved external MCP servers for Port AI.
* [Port custom agents](/agent-management/custom-agents/overview/.md) — agents that use registry and connector context at runtime.
---
# Prompts
[YouTube video player](https://www.youtube.com/embed/ZfOJcl0P31s)
Port MCP Server supports two types of prompts:
1. **Static prompts**: Pre-built prompts that are always available and don't require any setup.
2. **Custom dynamic prompts**: Organization-specific prompts that you create and manage in your Port portal.
Both types become available in supported MCP clients (for example, Cursor or Claude) where developers and AI agents can discover and run them with the required inputs.
Client Support Required
Prompt support in MCP clients depends on whether the client implements the prompts feature according to the [MCP specification](https://modelcontextprotocol.info/docs/clients/). Only some MCP clients currently support prompts. Check the [MCP client documentation](https://modelcontextprotocol.info/docs/clients/) to see if your client supports prompts.
## Static prompts[](#static-prompts "Direct link to Static prompts")
The Port MCP Server comes with pre-built static prompts that are always available in your MCP clients. These prompts provide helpful guidance and assistance for common Port workflows and don't require any setup or configuration.
The following static prompt is included:
* **troubleshoot\_integration**: Troubleshoot integration issues. This prompt guides you through a systematic approach to identify and fix integration problems by analyzing sync metrics, event logs, and providing fixed configurations. Requires an `integration` argument specifying the name or identifier of the integration to troubleshoot.
Static prompts are automatically available in all MCP clients connected to your Port organization and don't appear in your Port portal's Prompts page.
## Custom dynamic prompts[](#custom-dynamic-prompts "Direct link to Custom dynamic prompts")
You can create custom prompts specific to your organization and expose them via the MCP Server. Once defined, these prompts become available in supported MCP clients where developers and AI agents can discover and run them.
#### Common use cases[](#common-use-cases "Direct link to Common use cases")
* Automate on-call runbooks and incident-triage guidance
* Standardize code review or deployment checklists
* Generate structured updates and communications (e.g., incident status, release notes)
#### Set up the data model[](#set-up-the-data-model "Direct link to Set up the data model")
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Click on `+ Blueprint`.
3. Click on the `{...} Edit JSON` button.
4. Copy and paste the following JSON configuration:
**Prompt blueprint JSON (click to expand)**
Create in Port
```
{
"identifier": "prompt",
"title": "Prompt",
"icon": "Microservice",
"ownership": {
"type": "Direct",
"title": "Owning Teams"
},
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description"
},
"arguments": {
"items": {
"type": "object",
"properties": {
"name": {
"type": "string",
"description": "The name of the argument parameter"
},
"description": {
"type": "string",
"description": "A description of what this argument is for"
},
"required": {
"type": "boolean",
"description": "Whether this argument is required or optional",
"default": false
}
},
"required": [
"name",
"description"
]
},
"type": "array",
"title": "Arguments"
},
"template": {
"icon": "DefaultProperty",
"type": "string",
"title": "Prompt Template",
"format": "markdown"
}
},
"required": [
"description",
"template"
]
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Where prompts appear
After this blueprint exists and you create entities for it, prompts will show up in supported MCP clients connected to your Port organization. In clients that surface MCP prompts, you’ll see them listed and ready to run with arguments.
#### Create prompts[](#create-prompts "Direct link to Create prompts")
Create entities of the `prompt` blueprint for each prompt you want to expose. At minimum, provide `description` and `template`. Optionally add `arguments` to parameterize the prompt.
* Using Prompts page
* Using Self-Service Action
* Using GitOps
1. Go to the [Prompts page](https://app.port.io/prompts) in your portal.
2. Click **Create prompt**.
3. Fill out the form:
* Provide a title and description.
* Write the prompt template (supports markdown).
* Define any `arguments` (optional) with `name`, `description`, and whether they are `required`.
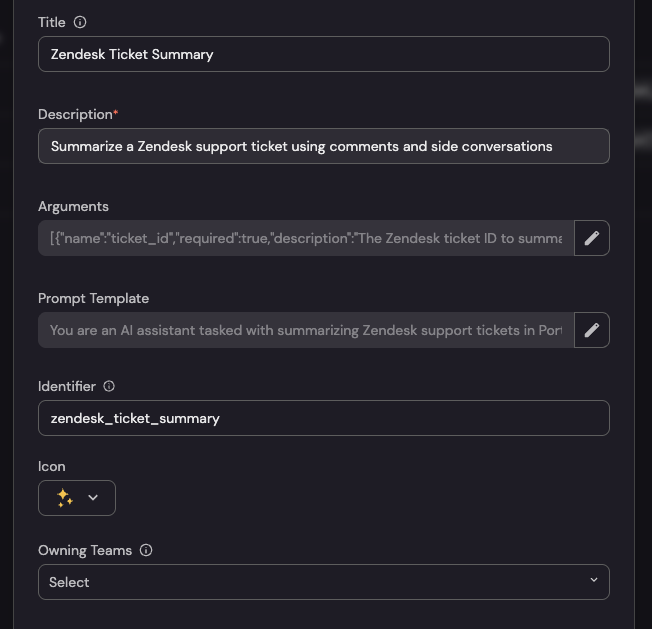
Template and placeholders
The `template` supports markdown and variable placeholders. Each argument defined in `arguments` is exposed by its `name` and can be referenced as `{{name}}` inside the template. When you run the prompt, the MCP Server collects values for required arguments and substitutes them into the matching placeholders before execution.
You can create a Self-Service Action in Port to allow your users to create prompts themselves.
1. Go to the [self-service](https://app.port.io/self-serve) page in Port.
2. Click on `+ New Action`.
3. Click on the `{...} Edit JSON` button.
4. Copy and paste the following JSON configuration:
**Create New Prompt action JSON (click to expand)**
Create in Port
```
{
"identifier": "create_new_prompt",
"title": "Create New Prompt",
"icon": "Microservice",
"description": "Create prompt templates that appear in MCP clients (Claude, Cursor, VS Code, etc.) connected to your Port organization. Users can select prompts, provide required arguments, and get contextual AI assistance with dynamic data from Port.",
"trigger": {
"type": "self-service",
"operation": "CREATE",
"userInputs": {
"properties": {
"arguments": {
"type": "array",
"title": "Template Arguments",
"description": "Define arguments that users will provide when running this prompt. Each argument becomes available as {{argument_name}} placeholder in the template. Required arguments must be provided before prompt execution.",
"items": {
"type": "object",
"properties": {
"name": {
"type": "string",
"title": "Argument Name",
"pattern": "^[a-zA-Z_][a-zA-Z0-9_]*$",
"description": "The parameter name that will be substituted in the template using {{name}} syntax (e.g., 'service_name', 'environment', 'incident_id')"
},
"description": {
"type": "string",
"title": "Argument Description",
"description": "Clear description explaining what this argument represents and how it's used in the prompt context"
},
"is_required": {
"type": "boolean",
"title": "Is Required",
"default": false,
"description": "When true, the MCP client (Claude, Cursor, VS Code) will require this argument before executing the prompt"
}
}
}
},
"owning_team": {
"type": "string",
"title": "Owning Team (Optional)",
"description": "The team that will own and maintain this prompt template",
"format": "entity",
"blueprint": "_team"
},
"prompt_title": {
"type": "string",
"title": "Prompt Title",
"description": "Human-readable name for this prompt (displayed in MCP clients like Claude, Cursor, and VS Code)",
"minLength": 3,
"maxLength": 50
},
"prompt_template": {
"type": "string",
"title": "Prompt Template",
"description": "The prompt content with placeholders for dynamic values. Use {{argument_name}} to reference arguments (e.g., 'Analyze service {{service_name}} in {{environment}}'). Supports markdown formatting. The MCP Server substitutes values into {{}} placeholders when the prompt runs.",
"minLength": 20,
"format": "multi-line"
},
"prompt_description": {
"type": "string",
"title": "Description",
"description": "Explain what this prompt does and when to use it. This description helps users select the right prompt from the MCP client interface.",
"minLength": 10,
"maxLength": 500,
"format": "multi-line"
}
},
"required": [
"prompt_title",
"prompt_description",
"prompt_template"
],
"order": [
"prompt_title",
"prompt_description",
"prompt_template",
"arguments",
"owning_team"
],
"titles": {}
},
"blueprintIdentifier": "prompt"
},
"invocationMethod": {
"type": "UPSERT_ENTITY",
"blueprintIdentifier": "prompt",
"mapping": {
"identifier": "{{ .inputs.prompt_title | ascii_downcase | gsub(\" \"; \"_\") | gsub(\"[^a-z0-9_]\"; \"\") }}",
"title": "{{ .inputs.prompt_title }}",
"team": "{{ if (.inputs.owning_team | type) == \"object\" then [.inputs.owning_team.identifier] else [] end }}",
"properties": {
"template": "{{ .inputs.prompt_template }}",
"arguments": "{{ (.inputs.arguments // []) | map({name: .name, description: .description, required: .is_required}) }}",
"description": "{{ .inputs.prompt_description }}"
}
}
},
"requiredApproval": false
}
```
Developer self-service
This Self-Service Action allows developers to create their own prompts without needing direct access to Port's data model. The action validates input and automatically creates properly formatted prompt entities.
You can ingest prompts from GitHub repositories using the GitHub integration. This enables a GitOps workflow where GitHub is the source of truth and Port stays in sync automatically.
**Prerequisites:**
[Port's GitHub integration](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/) is installed in your account.
**File structure:**
Store prompts as YAML files under `.github/prompts` using the `.prompt.yaml` suffix. This is consistent with [GitHub's prompt storage standard](https://docs.github.com/en/github-models/use-github-models/storing-prompts-in-github-repositories).
Example file: `.github/prompts/code-review.prompt.yaml`
**Example GitHub prompt (click to expand)**
```
name: code-review
description: Review code changes for correctness, security, performance, and test coverage following repo conventions.
arguments:
- name: change_scope
description: Summary of the changes or files to review.
required: false
- name: focus_areas
description: Specific concerns to prioritize (e.g., security, performance).
required: false
message: |-
# Code review
Review code changes for this repository.
Inputs:
- change_scope: {{change_scope}}
- focus_areas: {{focus_areas}}
## Instructions
Focus on:
- correctness and edge cases.
- security risks and input validation.
- performance regressions.
- missing tests or insufficient coverage.
```
**Configure the GitHub integration:**
1. Go to the [connectors](https://app.port.io/settings/data-sources) page in Port.
2. Find your GitHub integration and click on it.
3. Go to the **Mapping** tab.
4. Add the following configuration to your mapping YAML:
**GitHub integration configuration (click to expand)**
```
- kind: file
selector:
query: 'true'
files:
- path: .github/prompts/*.prompt.yaml
skipParsing: false
port:
entity:
mappings:
identifier: .repo.name + "/" + .file.name
title: .file.name | split(".") | .[0]
blueprint: '"prompt"'
properties:
description: .file.content.description
arguments: .file.content.arguments
template: .file.content.message
```
5. Click **Save** to update the integration configuration.
After configuration, prompts from your GitHub repositories will automatically sync to Port. Changes in GitHub will appear in your Port catalog after the integration syncs.
Learn more
For a complete guide on ingesting prompts and skills from GitHub using GitOps, including file structure examples, see the [Ingest prompts and skills from GitHub using GitOps](https://docs.port.io/guides/all/ingest-prompts-skills-from-github-using-gitops/) guide.
#### Examples[](#examples "Direct link to Examples")
* Incident triage
* Scorecard remediation
* On-call handoff summary
A prompt to assists on-call engineers by summarizing recent alerts and deploys related to an incident, then suggesting next steps and linking relevant runbooks.
**Example prompt execution:**
```
You are assisting with an incident in the payment-service service (production).
Incident ID: INC-2024-001
For the last 24 hours:
- Summarize critical alerts and recent deploys
- Suggest next steps and owners
- Link relevant dashboards/runbooks
```
**Incident triage prompt entity JSON (click to expand)**
```
{
"identifier": "incident_response_assistant",
"title": "Incident Response Assistant",
"team": [],
"properties": {
"description": "Assists with incident response by summarizing critical alerts, recent deploys, and suggesting next steps with relevant dashboards and runbooks",
"arguments": [
{
"name": "service_name",
"required": true,
"description": "The name of the service experiencing the incident"
},
{
"name": "environment",
"required": false,
"description": "The environment where the incident is occurring (e.g., production, staging)"
},
{
"name": "incident_id",
"required": true,
"description": "The unique identifier for the incident"
},
{
"name": "timeframe",
"required": false,
"description": "The time period to analyze (e.g., '24 hours', '1 week')"
}
],
"template": "You are assisting with an incident in the {{service_name}} service ({{environment}}).\nIncident ID: {{incident_id}}\n\nFor the last {{timeframe}}:\n- Summarize critical alerts and recent deploys\n- Suggest next steps and owners\n- Link relevant dashboards/runbooks"
},
"relations": {},
"icon": "Microservice"
}
```
A prompt that guides engineers to remediate failing scorecard rules by explaining each failure, its impact, and providing step-by-step fixes along with ownership suggestions.
**Example prompt execution:**
```
For user-management-service, generate remediation steps for failing rules in the "Production Readiness" scorecard.
For each failing rule:
- What is failing
- Why it matters
- Step-by-step remediation
- Owners and suggested timeline
```
**Scorecard remediation prompt entity JSON (click to expand)**
```
{
"identifier": "scorecard_remediation_guide",
"title": "Scorecard Remediation Guide",
"team": [],
"properties": {
"description": "Generate detailed remediation steps for failing scorecard rules, including what's failing, why it matters, step-by-step fixes, and ownership assignments",
"arguments": [
{
"name": "service_name",
"required": true,
"description": "The name of the service that needs scorecard remediation"
},
{
"name": "scorecard_name",
"required": true,
"description": "The name of the scorecard with failing rules"
}
],
"template": "For {{service_name}}, generate remediation steps for failing rules in the \"{{scorecard_name}}\" scorecard.\n\nFor each failing rule:\n- What is failing\n- Why it matters\n- Step-by-step remediation\n- Owners and suggested timeline"
},
"relations": {},
"icon": "Microservice"
}
```
A prompt to generates a thorough on-call handoff report, highlighting active incidents, key risks, pending actions, and upcoming maintenance for the specified team.
**Example prompt execution:**
```
Create an on-call handoff for Platform Engineering for the last past week.
Include:
- Active incidents and current status
- Top risks and mitigations
- Pending actions and owners
- Upcoming maintenance windows
```
**On-Call handoff report prompt entity JSON (click to expand)**
```
{
"identifier": "oncall_handoff_report",
"title": "On-Call Handoff Report",
"team": [],
"properties": {
"description": "Generate comprehensive on-call handoff documentation including active incidents, risks, pending actions, and upcoming maintenance windows",
"arguments": [
{
"name": "team",
"required": true,
"description": "The team name for which to create the on-call handoff"
},
{
"name": "timeframe",
"required": true,
"description": "The time period to cover in the handoff (e.g., 'last 24 hours', 'past week')"
}
],
"template": "Create an on-call handoff for {{team}} for the last {{timeframe}}.\n\nInclude:\n- Active incidents and current status\n- Top risks and mitigations\n- Pending actions and owners\n- Upcoming maintenance windows"
},
"relations": {},
"icon": "Microservice"
}
```
After creating entities, reconnect or refresh your MCP client; your prompts will be available and will prompt for any defined arguments.
#### See prompts in your client[](#see-prompts-in-your-client "Direct link to See prompts in your client")
* Cursor
* Claude
In Cursor, type **/** to open the prompts list. Selecting a prompt opens an input form for its arguments.
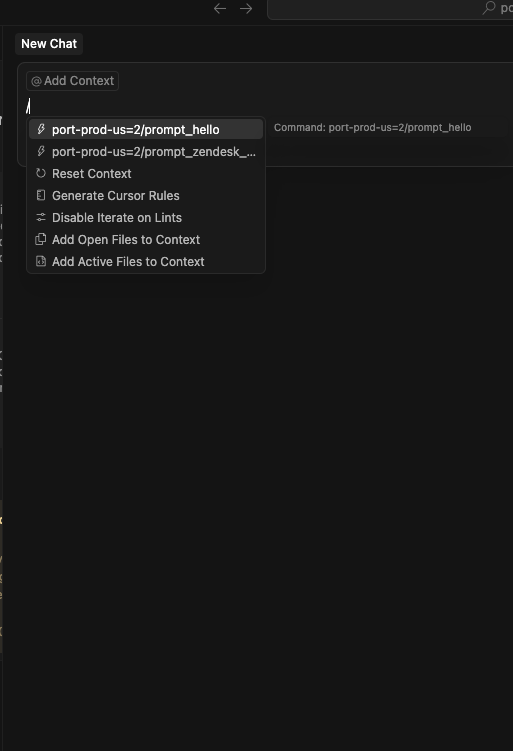
When you select a prompt, Cursor renders fields for the defined `arguments`. Required ones are marked and must be provided.
In Claude, click the **+** button and choose the prompts option to view the list from your Port organization. Selecting a prompt opens a parameter collection flow.
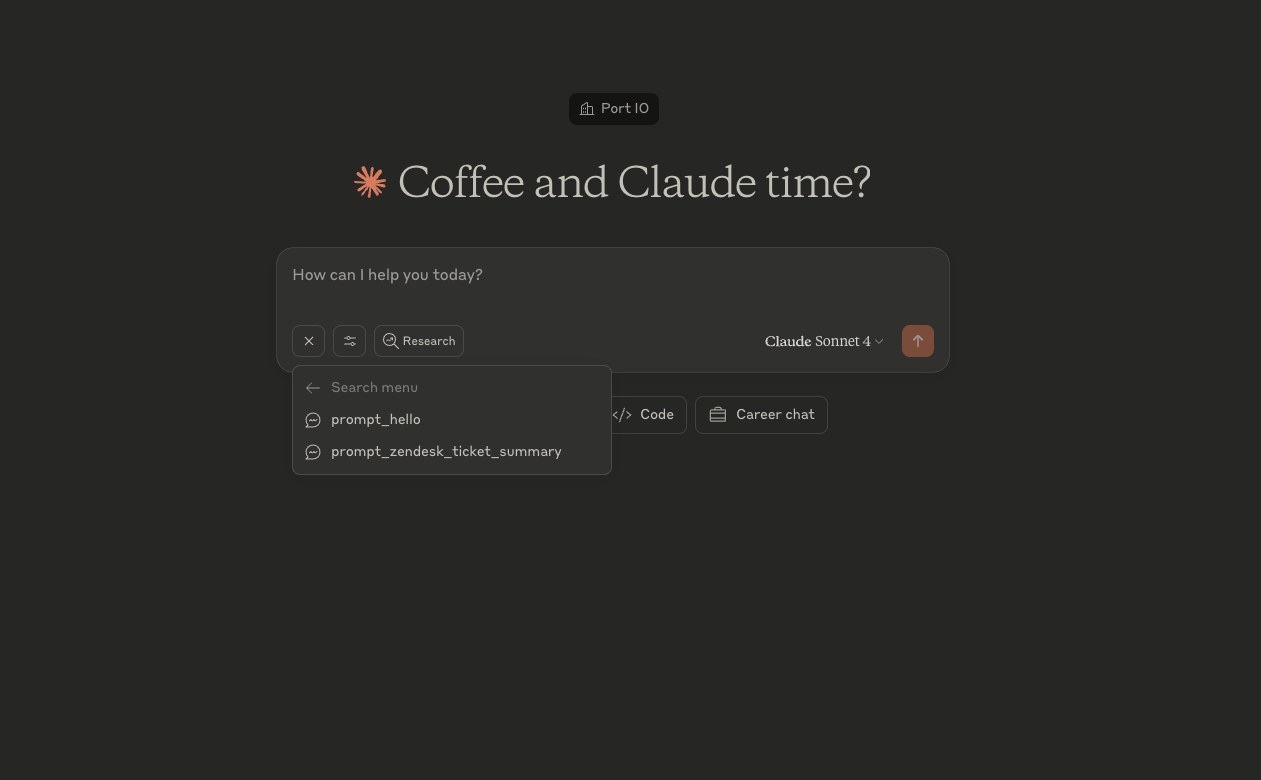
Claude will ask for any required arguments before running the prompt and will substitute them into the template.
## Using prompts in Port's AI Agent UI[](#using-prompts-in-ports-ai-agent-ui "Direct link to Using prompts in Port's AI Agent UI")
Port's AI Agent web interface now supports MCP prompts, including both static prompts and custom dynamic prompts. You can browse and use prompts directly from the chat input without needing external MCP clients like Cursor or Claude Desktop.
### How it works[](#how-it-works "Direct link to How it works")
1. **Access prompts**: Click the **+** button in the chat input to open the menu, then select **Prompts**.

2. **Browse and search**: View all available prompts from your Port organization with search and filter support.
3. **Fill arguments**: When selecting a prompt with arguments (required or optional), a dialog appears to fill in the values.
4. **Use the prompt**: After submitting arguments, the prompt content is attached to your message and sent to the AI agent.
Argument handling
When you select a prompt with arguments (required or optional), an arguments dialog appears. When you select a prompt with no arguments, Port uses it immediately without any additional steps.
---
# Enrich Port AI with skills
Skills give [Port AI](/port-ai/overview/.md) domain-specific instructions at runtime. Instead of repeating the same prompts or hoping the model infers your process, you package expert workflows as skills that Port AI loads when a task matches.
This page covers how skills enrich Port AI during a conversation or agent run. For skill concepts, blueprints, and creation steps, see the [Skills overview](/agent-management/ai-registry/skills/overview/.md).
## When to use skills[](#when-to-use-skills "Direct link to When to use skills")
Use skills when you want Port AI to follow a repeatable process, for example:
* Troubleshooting integration sync issues with a fixed diagnostic sequence.
* Guiding deployment decisions against your organization's approval rules.
* Running incident root-cause analysis with consistent data-gathering steps.
Skills work across [Port AI Assistant](/port-ai/port-ai-assistant/.md), [AI agents](/agent-management/custom-agents/overview/.md), the [Port MCP Server](/agent-management/port-mcp-server/overview/.md), and the [AI Agent widget](/interface-builder/port-interface/dashboards/custom-widgets/.md#ai-agent).
## How Port AI loads skills[](#how-port-ai-loads-skills "Direct link to How Port AI loads skills")
Port AI exposes a `load_skill` tool through the Port MCP Server. When your prompt or agent task matches a skill's description, Port AI loads that skill before continuing.
```
load_skill({ name: "troubleshoot-integration" })
```
You can also load a specific reference file from a skill:
```
load_skill({ name: "troubleshoot-integration", resource: "references/common-errors.md" })
```
Each skill includes a name, description (when to use it), step-by-step instructions, and optional references and assets. Skills follow the open [Agent Skills specification](https://agentskills.io/specification).
## Built-in skills[](#built-in-skills "Direct link to Built-in skills")
Port ships built-in skills for common platform workflows. These require no setup and are available to all users.
The `troubleshoot-integration` skill helps diagnose integration sync issues, mapping errors, and missing entities. It walks Port AI through identifying the integration, reviewing sync metrics and event logs, and recommending fixes in the correct format.
Built-in skill reference
See the full list and behavior details in the [Skills overview](/agent-management/ai-registry/skills/overview/.md#built-in-skills).
## Custom skills in Port AI[](#custom-skills-in-port-ai "Direct link to Custom skills in Port AI")
You can create custom skills as entities in your software catalog. Custom skills override built-in skills when they share the same name, so your organization's process takes precedence.
To create a custom skill:
1. Define the `skill` blueprint in your [data model](https://app.getport.io/settings/data-model).
2. Create skill entities with instructions, references, and assets.
3. Ask Port AI or an agent to perform a task that matches the skill description.
For blueprint JSON, entity examples, and GitOps ingestion options, see [Creating custom skills](/agent-management/ai-registry/skills/overview/.md#creating-custom-skills) in the Skills overview.
## Attach skills to agents[](#attach-skills-to-agents "Direct link to Attach skills to agents")
When you [build an AI agent](/agent-management/custom-agents/build-an-ai-agent/.md), you can configure which skills and tools the agent can access. Domain-specific agents combine catalog context with the right skills so automated runs follow your standards without manual prompting.
## Next steps[](#next-steps "Direct link to Next steps")
* [Skills overview](/agent-management/ai-registry/skills/overview/.md): full reference for skill structure, creation, and best practices.
* [Skills registry](/agent-management/ai-registry/skills/skills-registry/.md): organize approved skills across your organization.
* [Skills usage analytics](/agent-management/ai-registry/skills/skills-usage-analytics/.md): measure skill adoption from Cursor and Claude.
* [Port MCP Server](/agent-management/port-mcp-server/overview/.md): use skills from your IDE or external MCP clients.
---
# Skills
Open Beta
This feature is currently in open beta and available to all organizations. Should you encounter any bugs or functionality issues, please let us know so we can rectify them as soon as possible. Your feedback is greatly appreciated! ⭐
We are actively iterating to improve the experience. Breaking changes in the data model and functionality may occur. We will communicate changes on an ongoing basis. General availability is expected by Q4 2026.
Skills are domain-specific guidance packages that help Port AI handle specialized tasks more effectively. When the AI encounters a task that matches a skill's description, it loads the skill's step-by-step instructions to ensure consistent, thorough handling.
## What are skills[](#what-are-skills "Direct link to What are skills")
Skills provide structured workflows for common but complex tasks. Instead of relying on general AI capabilities, skills encode expert knowledge into reusable instruction sets that guide the AI through specific processes.
Each skill contains:
* **Name**: A unique identifier for the skill.
* **Description**: When the AI should use this skill.
* **Instructions**: Step-by-step guidance in markdown format.
* **References** (optional): Additional documentation or context.
* **Assets** (optional): Templates, configuration files, or other resources.
Skills follow the open [Agent Skills specification](https://agentskills.io/specification).
## Example skills you can create[](#example-skills-you-can-create "Direct link to Example skills you can create")
* Deployment guidelines
* Engineering metrics
* Analyze incident root cause
## Deployment guidelines
A skill that helps decide on a deployment strategy, which workflows to run, how to check deployment status, and get approval. This skill can guide developers through your organization's deployment process by providing step-by-step instructions on choosing the right deployment strategy for different environments, running the appropriate CI/CD workflows, monitoring deployment progress, and obtaining necessary approvals from stakeholders before deploying to production.
## Engineering metrics
A skill that structures how you want to get engineering metrics and what to look for. This skill helps analyze key performance indicators like lead time for changes, deployment frequency, change failure rate, and AI usage and cost metrics. It can provide guidance on how to collect, aggregate, and interpret these metrics to gain insights into your team's performance and identify areas for improvement.
## Analyze incident root cause
A skill that provides a walkthrough on steps to run when analyzing an incident root cause. This skill guides you through a systematic process for investigating incidents, including gathering relevant logs and metrics, identifying the timeline of events, examining related services and dependencies, analyzing error patterns, and documenting findings to prevent similar incidents in the future.
## How skills work[](#how-skills-work "Direct link to How skills work")
Skills are loaded via the `load_skill` tool available in the [Port MCP Server](/agent-management/port-mcp-server/overview/.md). When Port AI detects a task that matches a skill's description, it automatically loads the relevant skill before proceeding.
**Loading a skill:**
```
load_skill({ name: "troubleshoot-integration" })
```
**Loading a specific resource from a skill:**
```
load_skill({ name: "troubleshoot-integration", resource: "references/common-errors.md" })
```
## Built-in skills[](#built-in-skills "Direct link to Built-in skills")
Port includes built-in skills for common workflows. These skills are available to all users without any configuration.
**`action-permissions-helper` (click to expand)**
Helps you configure permissions for self-service actions, with a focus on dynamic permission policies.
Use it to write or debug JQ expressions for execute and approve policies, or to understand why an existing permission policy isn't behaving as expected.
**`dashboard-page-helper` (click to expand)**
Guides the creation of dashboard pages with widgets, including a fallback approach for large pages with five or more widgets. It also checks your existing sidebar structure before placing a new page, keeping your navigation organized.
**`ei-ai-copilot-adoption` (click to expand)**
Sets up GitHub Copilot adoption metrics and the GitHub Copilot AI Adoption dashboard as part of Engineering Intelligence.
Use it to measure or visualize license utilization, acceptance rate, lines-of-code efficiency, low-engagement users, or per-team Copilot rollups.
**`ei-delivery-performance` (click to expand)**
Sets up pull request and merge request delivery performance metrics and dashboards for GitHub, GitLab, or Azure DevOps as part of Engineering Intelligence.
Use it to measure cycle time, throughput, stale pull requests, or reviewer coverage.
**`ei-foundation` (click to expand)**
Validates whether your organization has the data model required for Engineering Intelligence use cases, before you run the Delivery Performance or AI Copilot Adoption skills.
Use it whenever Engineering Intelligence widgets, scorecards, or dashboards appear empty, to check readiness and identify what's missing.
**`mapping-assistant` (click to expand)**
Helps you create, modify, or troubleshoot integration mapping configurations.
Use it to write JQ expressions for data transformation, understand test results and errors, or debug mapping issues.
**`skill-creator` (click to expand)**
Guides you through creating and registering custom AI skills in Port, from clarifying the skill's purpose to writing effective instructions and registering it as a Port entity.
**`troubleshoot-integration` (click to expand)**
Diagnoses and resolves integration sync issues, mapping errors, and data problems.
Use it when data isn't syncing or appearing in Port, entities are missing or incorrect, or you're seeing sync errors and mapping configuration problems.
**`troubleshoot-scim` (click to expand)**
Diagnoses and resolves SCIM provisioning issues, including group provisioning errors, missing users, compatibility issues, and login problems. Works with Azure Entra ID, Okta, JumpCloud, Google Workspace, or any SCIM 2.0-compatible identity provider.
**`workflows` (click to expand)**
Creates or updates Port workflows, including triggers, action nodes, conditions, and data flow.
Use it to add, update, or remove individual nodes, connections, or user inputs in a workflow.
## Creating custom skills[](#creating-custom-skills "Direct link to Creating custom skills")
[YouTube video player](https://www.youtube.com/embed/h42j9WnzTBI)
You can create custom skills tailored to your organization's specific workflows. Custom skills are stored as entities in Port and can override built-in skills with the same name.
### Step 1: Create the skill blueprint[](#step-1-create-the-skill-blueprint "Direct link to Step 1: Create the skill blueprint")
First, create the `skill` blueprint in your Port organization. Go to your [data model](https://app.port.io/settings/data-model) and create a new blueprint with the following configuration:
**Skill blueprint (click to expand)**
Create in Port
```
{
"identifier": "skill",
"title": "Skill",
"icon": "Learn",
"schema": {
"properties": {
"description": {
"title": "Description",
"type": "string",
"description": "What the skill does and when the model should use it"
},
"instructions": {
"title": "Instructions",
"type": "string",
"format": "markdown",
"description": "Step-by-step instructions for the AI to follow"
},
"references": {
"title": "References",
"type": "array",
"description": "Reference documents for the skill",
"items": {
"type": "object",
"properties": {
"path": {
"type": "string",
"description": "Resource path (e.g., references/common-errors.md)"
},
"content": {
"type": "string",
"description": "The file content"
},
"description": {
"type": "string",
"description": "Optional description of the resource"
}
},
"required": ["path", "content"],
"additionalProperties": false
}
},
"assets": {
"title": "Assets",
"type": "array",
"description": "Asset files (templates, configs) for the skill",
"items": {
"type": "object",
"properties": {
"path": {
"type": "string",
"description": "Asset path (e.g., assets/mapping-template.yaml)"
},
"content": {
"type": "string",
"description": "The file content"
},
"description": {
"type": "string",
"description": "Optional description of the asset"
}
},
"required": ["path", "content"],
"additionalProperties": false
}
},
"location": {
"type": "string",
"title": "Location",
"description": "The target directory where the skill will be created on the machine.",
"default": "global",
"enum": [
"global",
"project"
],
"enumColors": {
"global": "lightGray",
"project": "lightGray"
}
}
},
"required": ["description", "instructions", "location"]
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
### Step 2: Create skill entities[](#step-2-create-skill-entities "Direct link to Step 2: Create skill entities")
Once the blueprint exists, create entities for each custom skill. Each entity represents one skill.
* Manual creation
* Using GitOps
**Required properties:**
| Property | Description |
| -------------- | --------------------------------------------------------------------------------------------------------------------------- |
| `identifier` | Unique skill name using lowercase letters and hyphens (e.g., `deploy-service`). |
| `description` | A clear description of what the skill does and when Port AI should use it. This helps the AI decide when to load the skill. |
| `instructions` | Step-by-step instructions in markdown format. |
**Optional properties:**
| Property | Description |
| ------------ | ------------------------------------------------------------------------------------------------------------------------- |
| `references` | Array of reference documents. Each item needs a `path` (e.g., `references/runbook.md`) and `content` (the document text). |
| `assets` | Array of asset files like templates or configs. Same structure as references: `path` and `content`. |
### Example: Custom deployment skill
Here's an example of a custom skill for deploying services in your organization:
```
{
"identifier": "deploy-to-production",
"title": "Deploy to Production",
"properties": {
"description": "Guide for deploying services to production. Use when users ask to deploy, release, or promote a service to production.",
"instructions": "# Deploy to Production\n\nFollow these steps to deploy a service to production:\n\n## Step 1: Verify prerequisites\n\n- Check that all tests pass.\n- Verify the service has a production-readiness scorecard score above 80%.\n- Confirm the service owner has approved the deployment.\n\n## Step 2: Run the deployment\n\nExecute the deployment action for the target service and environment.\n\n**Example input:**\n- Service: `payment-service`\n- Environment: `production`\n\n**Expected output:**\n- Deployment initiated successfully.\n- Action run ID returned for tracking.\n\n## Step 3: Verify deployment\n\n- Check the action run status.\n- Verify the service is healthy in production.\n- Monitor for any alerts in the first 15 minutes.\n\n## Common edge cases\n\n- If tests are failing, do not proceed with deployment.\n- If scorecard score is below threshold, recommend remediation steps first.\n- If deployment fails, check logs and suggest rollback if needed.",
"references": [
{
"path": "references/deployment-runbook.md",
"content": "# Deployment Runbook\n\n## Pre-deployment checklist\n\n- [ ] All CI checks pass\n- [ ] Code review approved\n- [ ] QA sign-off received\n\n## Rollback procedure\n\nIf deployment fails:\n1. Revert to previous version\n2. Notify on-call team\n3. Create incident ticket"
},
{
"path": "references/common-errors.md",
"content": "# Common Deployment Errors\n\n## ImagePullBackOff\nCause: Container registry authentication failed.\nFix: Verify registry credentials.\n\n## CrashLoopBackOff\nCause: Application fails to start.\nFix: Check application logs and configuration."
}
],
"assets": [
{
"path": "assets/deployment-config.yaml",
"content": "apiVersion: apps/v1\nkind: Deployment\nmetadata:\n name: {{ service_name }}\nspec:\n replicas: 3\n strategy:\n type: RollingUpdate"
}
]
}
}
```
You can ingest skills from GitHub repositories using the GitHub integration. This enables a GitOps workflow where GitHub is the source of truth and Port stays in sync automatically.
**Prerequisites:**
[GitHub Ocean integration](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean) is installed in your account.
Choose one mapping kind. Do not combine them:
* Use the **`skill`** kind when you only need `SKILL.md` instructions in Port. It does not ingest files under `references/` or `assets/`.
* Use the **`file`** kind when those extra files must land on the skill entity as `properties.references` and `properties.assets`.
Do not model extra files as related entities, and do not reconstruct `references` with mirror or calculation properties. `port skills add` and `port skills sync` only read stored `properties.references` and `properties.assets` on the skill entity.
**Recommended file structure:**
Store each skill in its own folder under `skills/`. Put instructions in `SKILL.md`. Put any other files the skill needs under `references/` or `assets/`:
```
skills/
├── deploy-to-production/
│ ├── SKILL.md
│ ├── references/
│ │ └── deployment-runbook.md
│ └── assets/
│ └── deployment-config.yaml
└── troubleshoot-integration/
└── SKILL.md
```
**Configure the GitHub integration:**
1. Go to the [connectors](https://app.port.io/settings/data-sources) page in Port.
2. Find your GitHub integration and click **Manage**.
3. Go to the **Mapping** tab.
4. Add the mapping for the kind you chose:
* Skill kind
* File kind
The `skill` kind discovers `SKILL.md` files, parses frontmatter, and maps instructions. Extra files in the skill folder are not ingested.
**GitHub Ocean skill kind mapping (click to expand)**
```
deleteDependentEntities: false
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: skill
selector:
query: 'true'
paths:
- path: 'skills/**/SKILL.md'
organization: my-org # Optional if githubOrganization is set (required if not set)
repos:
- name: my-skills-repo
branch: main
port:
entity:
mappings:
identifier: .__repository.full_name + "/" + .skill.skillMdPath
title: .skill.name // .skill.skillMdPath
blueprint: '"skill"'
properties:
instructions: .skill.instructions
description: .skill.description
location: '"global"'
```
The `file` kind maps `SKILL.md` plus files under `references/` and `assets/` onto one skill entity. Use the same identifier for every file in a skill folder, and set `enableMergeEntity: true` so extra files merge onto the entity instead of replacing the instructions.
**GitHub Ocean file kind mapping (click to expand)**
```
deleteDependentEntities: false
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: file
selector:
query: 'true'
files:
- path: skills/**/SKILL.md
organization: my-org # Optional if githubOrganization is set (required if not set)
repos:
- name: my-skills-repo
branch: main
port:
entity:
mappings:
identifier: .repository.name + "/" + (.path | split("/")[1])
title: .path | split("/")[1]
blueprint: '"skill"'
properties:
instructions: .content
description: .content | capture("description:\\s*(?.+)").d
location: '"global"'
relations: {}
- kind: file
selector:
query: 'true'
files:
- path: skills/**/references/**
skipParsing: true
organization: my-org # Optional if githubOrganization is set (required if not set)
repos:
- name: my-skills-repo
branch: main
port:
entity:
mappings:
identifier: .repository.name + "/" + (.path | split("/")[1])
blueprint: '"skill"'
properties:
references:
- path: .path | split("/") | .[2:] | join("/")
content: .content
- kind: file
selector:
query: 'true'
files:
- path: skills/**/assets/**
skipParsing: true
organization: my-org # Optional if githubOrganization is set (required if not set)
repos:
- name: my-skills-repo
branch: main
port:
entity:
mappings:
identifier: .repository.name + "/" + (.path | split("/")[1])
blueprint: '"skill"'
properties:
assets:
- path: .path | split("/") | .[2:] | join("/")
content: .content
```
5. Click **Save & Resync** to update the integration configuration.
After configuration, skills from your GitHub repositories will automatically sync to Port. Changes in GitHub will appear in your Port catalog after the integration syncs.
#### Common practices
* Namespace the `identifier` so skills with the same folder name in different repos don't collide. The skill kind example uses `.__repository.full_name`. The file kind example uses `.repository.name + "/" + ...`.
* Keep `deleteDependentEntities: false` on this connector. Setting it to `true` means a temporary sync issue, like a rate limit, a revoked permission, or a renamed repo, deletes skill entities on the next resync instead of leaving them stale.
* Extract `description` from the SKILL.md frontmatter instead of mapping the raw file content, so the catalog shows a short summary rather than the entire file.
* With the file kind, each extra-file event replaces the whole `references` or `assets` array. If a skill has more than one file in the same directory, use the [upload skills from a folder](/agent-management/ai-registry/skills/overview/.md#upload-skills-from-a-folder) script so the full array is written in one request.
Using GitHub (Sunset) or also syncing prompts
If your account still uses Port's older GitHub app integration, or you also want to sync prompt files alongside skills, see the [Ingest prompts and skills from GitHub using GitOps](/guides/all/ingest-prompts-skills-from-github-using-gitops/.md) guide, which covers both integration versions and the combined prompts and skills setup.
## Upload skills from a folder[](#upload-skills-from-a-folder "Direct link to Upload skills from a folder")
You can manage skills as folders in your repository and upload them to Port using a script. This is useful for version-controlling your skills and integrating with CI/CD pipelines.
### Skill folder structure[](#skill-folder-structure "Direct link to Skill folder structure")
Organize each skill as a folder with the following structure:
```
my-skill/
├── SKILL.md # Skill definition (required)
├── references/ # Reference documents (optional)
│ ├── runbook.md
│ └── common-errors.md
└── assets/ # Asset files (optional)
└── config-template.yaml
```
The `SKILL.md` file contains YAML frontmatter with the skill metadata, followed by the instructions in markdown:
```
---
name: deploy-to-production
description: Guide for deploying services to production. Use when users ask to deploy, release, or promote a service to production.
metadata:
title: Deploy to Production
---
# Deploy to Production
Follow these steps to deploy a service to production:
## Step 1: Verify prerequisites
- Check that all tests pass.
- Verify the service has a production-readiness scorecard score above 80%.
## Step 2: Run the deployment
Execute the deployment action for the target service.
## Common edge cases
- If tests are failing, do not proceed with deployment.
- If deployment fails, check logs and suggest rollback.
```
### Upload script[](#upload-script "Direct link to Upload script")
Use the following script to read a skill folder and upload it to Port as an entity.
**Upload script (click to expand)**
**Prerequisites:**
```
# Python: install dependencies
pip install requests pyyaml
# JavaScript: install dependencies
npm install js-yaml
# Bash: install jq and yq, make script executable
# macOS: brew install jq yq
# Ubuntu: sudo apt-get install jq && pip install yq
chmod +x ./upload-skill.sh
```
**Usage:**
```
# Set your Port credentials
export PORT_CLIENT_ID="your-client-id"
export PORT_CLIENT_SECRET="your-client-secret"
# For US region, also set:
# export PORT_BASE_URL="https://api.us.port.io"
# Test with dry-run first (no changes made)
python upload_skill.py ./my-skill --dry-run # Python
node upload-skill.js ./my-skill --dry-run # JavaScript
./upload-skill.sh ./my-skill --dry-run # Bash
# Upload the skill to Port
python upload_skill.py ./my-skill # Python
node upload-skill.js ./my-skill # JavaScript
./upload-skill.sh ./my-skill # Bash
```
* Python
* JavaScript
* Bash
```
#!/usr/bin/env python3
"""
Upload a skill folder to Port as an entity.
Usage:
python upload_skill.py [--dry-run]
Environment variables:
PORT_CLIENT_ID - Port client ID
PORT_CLIENT_SECRET - Port client secret
PORT_BASE_URL - Port API base URL (default: https://api.port.io)
"""
import os
import sys
import json
import requests
import yaml
import re
from pathlib import Path
PORT_BASE_URL = os.environ.get('PORT_BASE_URL', 'https://api.port.io')
def get_port_token():
client_id = os.environ.get('PORT_CLIENT_ID')
client_secret = os.environ.get('PORT_CLIENT_SECRET')
if not client_id or not client_secret:
raise Exception('PORT_CLIENT_ID and PORT_CLIENT_SECRET environment variables are required')
response = requests.post(
f'{PORT_BASE_URL}/v1/auth/access_token',
json={'clientId': client_id, 'clientSecret': client_secret}
)
response.raise_for_status()
return response.json()['accessToken']
def parse_skill_file(skill_dir):
skill_path = Path(skill_dir) / 'SKILL.md'
if not skill_path.exists():
raise Exception(f'SKILL.md not found in {skill_dir}')
content = skill_path.read_text()
# Parse YAML frontmatter
match = re.match(r'^---\n(.*?)\n---\n(.*)$', content, re.DOTALL)
if not match:
raise Exception('Invalid SKILL.md format: missing YAML frontmatter')
frontmatter = yaml.safe_load(match.group(1))
instructions = match.group(2).strip()
if not frontmatter.get('name'):
raise Exception('SKILL.md frontmatter must have a "name" field')
if not frontmatter.get('description'):
raise Exception('SKILL.md frontmatter must have a "description" field')
return {
'name': frontmatter['name'],
'description': frontmatter['description'],
'metadata': frontmatter.get('metadata', {}),
'instructions': instructions
}
def read_resources_from_dir(skill_dir, sub_dir):
dir_path = Path(skill_dir) / sub_dir
if not dir_path.exists():
return []
resources = []
for file_path in dir_path.rglob('*'):
if file_path.is_file():
relative_path = f'{sub_dir}/{file_path.relative_to(dir_path)}'
resources.append({
'path': relative_path,
'content': file_path.read_text()
})
return resources
def upload_skill(token, entity):
response = requests.post(
f'{PORT_BASE_URL}/v1/blueprints/skill/entities?upsert=true&merge=true',
headers={
'Authorization': f'Bearer {token}',
'Content-Type': 'application/json'
},
json=entity
)
response.raise_for_status()
return response.json()
def main():
args = sys.argv[1:]
dry_run = '--dry-run' in args
skill_dir = next((arg for arg in args if not arg.startswith('--')), None)
if not skill_dir:
print('Usage: python upload_skill.py [--dry-run]')
sys.exit(1)
skill_dir = Path(skill_dir).resolve()
if not skill_dir.exists():
print(f'Error: Directory not found: {skill_dir}')
sys.exit(1)
print(f'Reading skill from: {skill_dir}')
# Parse SKILL.md
skill = parse_skill_file(skill_dir)
print(f' Name: {skill["name"]}')
print(f' Description: {skill["description"][:50]}...')
# Read references and assets
references = read_resources_from_dir(skill_dir, 'references')
assets = read_resources_from_dir(skill_dir, 'assets')
print(f' References: {len(references)} file(s)')
print(f' Assets: {len(assets)} file(s)')
# Build entity
entity = {
'identifier': skill['name'],
'title': skill['metadata'].get('title', skill['name']),
'properties': {
'description': skill['description'],
'instructions': skill['instructions'],
'references': references if references else None,
'assets': assets if assets else None
}
}
print('\nEntity to create/update:')
print(json.dumps(entity, indent=2))
if dry_run:
print('\n[DRY RUN] Would create/update entity in Port')
else:
print('\nAuthenticating with Port...')
token = get_port_token()
result = upload_skill(token, entity)
print(f'\n✅ Entity created/updated successfully!')
print(f' Identifier: {result["entity"]["identifier"]}')
print(f' Title: {result["entity"]["title"]}')
if __name__ == '__main__':
main()
```
```
#!/usr/bin/env node
/**
* Upload a skill folder to Port as an entity.
*
* Usage:
* node upload-skill.js [--dry-run]
*
* Environment variables:
* PORT_CLIENT_ID - Port client ID
* PORT_CLIENT_SECRET - Port client secret
* PORT_BASE_URL - Port API base URL (default: https://api.port.io)
*/
const fs = require('fs');
const path = require('path');
const yaml = require('js-yaml');
const PORT_BASE_URL = process.env.PORT_BASE_URL || 'https://api.port.io';
async function getPortToken() {
const clientId = process.env.PORT_CLIENT_ID;
const clientSecret = process.env.PORT_CLIENT_SECRET;
if (!clientId || !clientSecret) {
throw new Error('PORT_CLIENT_ID and PORT_CLIENT_SECRET environment variables are required');
}
const response = await fetch(`${PORT_BASE_URL}/v1/auth/access_token`, {
method: 'POST',
headers: { 'Content-Type': 'application/json' },
body: JSON.stringify({ clientId, clientSecret })
});
if (!response.ok) {
throw new Error(`Failed to get Port token: ${response.status} ${response.statusText}`);
}
const data = await response.json();
return data.accessToken;
}
function parseSkillFile(skillDir) {
const skillPath = path.join(skillDir, 'SKILL.md');
if (!fs.existsSync(skillPath)) {
throw new Error(`SKILL.md not found in ${skillDir}`);
}
const content = fs.readFileSync(skillPath, 'utf-8');
// Parse YAML frontmatter
const frontmatterMatch = content.match(/^---\n([\s\S]*?)\n---\n([\s\S]*)$/);
if (!frontmatterMatch) {
throw new Error('Invalid SKILL.md format: missing YAML frontmatter');
}
const frontmatter = yaml.load(frontmatterMatch[1]);
const instructions = frontmatterMatch[2].trim();
if (!frontmatter.name) {
throw new Error('SKILL.md frontmatter must have a "name" field');
}
if (!frontmatter.description) {
throw new Error('SKILL.md frontmatter must have a "description" field');
}
return {
name: frontmatter.name,
description: frontmatter.description,
metadata: frontmatter.metadata || {},
instructions
};
}
function readResourcesFromDir(skillDir, subDir) {
const dirPath = path.join(skillDir, subDir);
if (!fs.existsSync(dirPath)) {
return [];
}
const resources = [];
const files = fs.readdirSync(dirPath, { recursive: true });
for (const file of files) {
const filePath = path.join(dirPath, file);
const stat = fs.statSync(filePath);
if (stat.isFile()) {
const relativePath = `${subDir}/${file}`;
const content = fs.readFileSync(filePath, 'utf-8');
resources.push({
path: relativePath,
content
});
}
}
return resources;
}
async function uploadSkill(token, entity) {
const response = await fetch(`${PORT_BASE_URL}/v1/blueprints/skill/entities?upsert=true&merge=true`, {
method: 'POST',
headers: {
'Content-Type': 'application/json',
Authorization: `Bearer ${token}`
},
body: JSON.stringify(entity)
});
if (!response.ok) {
const errorBody = await response.text();
throw new Error(`Failed to create entity: ${response.status} ${response.statusText}\n${errorBody}`);
}
return response.json();
}
async function main() {
const args = process.argv.slice(2);
const dryRun = args.includes('--dry-run');
const skillDir = args.find(arg => !arg.startsWith('--'));
if (!skillDir) {
console.error('Usage: node upload-skill.js [--dry-run]');
process.exit(1);
}
const resolvedDir = path.resolve(skillDir);
if (!fs.existsSync(resolvedDir)) {
console.error(`Error: Directory not found: ${resolvedDir}`);
process.exit(1);
}
console.log(`Reading skill from: ${resolvedDir}`);
// Parse SKILL.md
const skill = parseSkillFile(resolvedDir);
console.log(` Name: ${skill.name}`);
console.log(` Description: ${skill.description.substring(0, 50)}...`);
// Read references and assets
const references = readResourcesFromDir(resolvedDir, 'references');
const assets = readResourcesFromDir(resolvedDir, 'assets');
console.log(` References: ${references.length} file(s)`);
console.log(` Assets: ${assets.length} file(s)`);
// Build entity
const entity = {
identifier: skill.name,
title: skill.metadata.title || skill.name,
properties: {
description: skill.description,
instructions: skill.instructions,
references: references.length > 0 ? references : undefined,
assets: assets.length > 0 ? assets : undefined
}
};
console.log('\nEntity to create/update:');
console.log(JSON.stringify(entity, null, 2));
if (dryRun) {
console.log('\n[DRY RUN] Would create/update entity in Port');
} else {
console.log('\nAuthenticating with Port...');
const token = await getPortToken();
const result = await uploadSkill(token, entity);
console.log('\n✅ Entity created/updated successfully!');
console.log(` Identifier: ${result.entity.identifier}`);
console.log(` Title: ${result.entity.title}`);
}
}
main().catch(err => {
console.error('Error:', err.message);
process.exit(1);
});
```
```
#!/bin/bash
#
# Upload a skill folder to Port as an entity.
#
# Usage:
# ./upload-skill.sh [--dry-run]
#
# Environment variables:
# PORT_CLIENT_ID - Port client ID
# PORT_CLIENT_SECRET - Port client secret
# PORT_BASE_URL - Port API base URL (default: https://api.port.io)
#
# Dependencies: jq, yq
set -e
PORT_BASE_URL="${PORT_BASE_URL:-https://api.port.io}"
# Parse arguments
DRY_RUN=false
SKILL_DIR=""
for arg in "$@"; do
if [[ "$arg" == "--dry-run" ]]; then
DRY_RUN=true
elif [[ ! "$arg" == --* ]]; then
SKILL_DIR="$arg"
fi
done
if [[ -z "$SKILL_DIR" ]]; then
echo "Usage: ./upload-skill.sh [--dry-run]"
exit 1
fi
SKILL_DIR=$(cd "$SKILL_DIR" && pwd)
if [[ ! -d "$SKILL_DIR" ]]; then
echo "Error: Directory not found: $SKILL_DIR"
exit 1
fi
echo "Reading skill from: $SKILL_DIR"
# Check for SKILL.md
SKILL_FILE="$SKILL_DIR/SKILL.md"
if [[ ! -f "$SKILL_FILE" ]]; then
echo "Error: SKILL.md not found in $SKILL_DIR"
exit 1
fi
# Parse SKILL.md frontmatter using yq
FRONTMATTER=$(sed -n '/^---$/,/^---$/p' "$SKILL_FILE" | sed '1d;$d')
SKILL_NAME=$(echo "$FRONTMATTER" | yq -r '.name')
SKILL_DESCRIPTION=$(echo "$FRONTMATTER" | yq -r '.description')
SKILL_TITLE=$(echo "$FRONTMATTER" | yq -r '.metadata.title // .name')
# Get instructions (everything after the closing --- of frontmatter, trimmed)
INSTRUCTIONS=$(awk '/^---$/{n++; next} n>=2' "$SKILL_FILE" | sed '/./,$!d')
echo " Name: $SKILL_NAME"
echo " Description: ${SKILL_DESCRIPTION:0:50}..."
# Read references
REFERENCES="[]"
if [[ -d "$SKILL_DIR/references" ]]; then
REFERENCES=$(find "$SKILL_DIR/references" -type f | while read -r file; do
REL_PATH="references/$(basename "$file")"
CONTENT=$(cat "$file" | jq -Rs .)
echo "{\"path\": \"$REL_PATH\", \"content\": $CONTENT}"
done | jq -s '.')
echo " References: $(echo "$REFERENCES" | jq 'length') file(s)"
else
echo " References: 0 file(s)"
fi
# Read assets
ASSETS="[]"
if [[ -d "$SKILL_DIR/assets" ]]; then
ASSETS=$(find "$SKILL_DIR/assets" -type f | while read -r file; do
REL_PATH="assets/$(basename "$file")"
CONTENT=$(cat "$file" | jq -Rs .)
echo "{\"path\": \"$REL_PATH\", \"content\": $CONTENT}"
done | jq -s '.')
echo " Assets: $(echo "$ASSETS" | jq 'length') file(s)"
else
echo " Assets: 0 file(s)"
fi
# Build entity JSON
ENTITY=$(jq -n \
--arg identifier "$SKILL_NAME" \
--arg title "$SKILL_TITLE" \
--arg description "$SKILL_DESCRIPTION" \
--arg instructions "$INSTRUCTIONS" \
--argjson references "$REFERENCES" \
--argjson assets "$ASSETS" \
'{
identifier: $identifier,
title: $title,
properties: {
description: $description,
instructions: $instructions,
references: (if ($references | length) > 0 then $references else null end),
assets: (if ($assets | length) > 0 then $assets else null end)
}
}')
echo ""
echo "Entity to create/update:"
echo "$ENTITY" | jq .
if [[ "$DRY_RUN" == "true" ]]; then
echo ""
echo "[DRY RUN] Would create/update entity in Port"
exit 0
fi
# Get Port token
if [[ -z "$PORT_CLIENT_ID" || -z "$PORT_CLIENT_SECRET" ]]; then
echo "Error: PORT_CLIENT_ID and PORT_CLIENT_SECRET environment variables are required"
exit 1
fi
echo ""
echo "Authenticating with Port..."
ACCESS_TOKEN=$(curl --silent --location --request POST "${PORT_BASE_URL}/v1/auth/access_token" \
--header 'Content-Type: application/json' \
--data-raw "{
\"clientId\": \"${PORT_CLIENT_ID}\",
\"clientSecret\": \"${PORT_CLIENT_SECRET}\"
}" | jq -r '.accessToken')
# Upload entity
RESULT=$(curl --silent --location --request POST "${PORT_BASE_URL}/v1/blueprints/skill/entities?upsert=true&merge=true" \
--header "Authorization: Bearer ${ACCESS_TOKEN}" \
--header 'Content-Type: application/json' \
--data-raw "$ENTITY")
echo ""
echo "✅ Entity created/updated successfully!"
echo " Identifier: $(echo "$RESULT" | jq -r '.entity.identifier')"
echo " Title: $(echo "$RESULT" | jq -r '.entity.title')"
```
Find your Port credentials
Your Port credentials are available in the [Port UI](https://app.port.io) under **Settings > Credentials**.
## Priority and overriding[](#priority-and-overriding "Direct link to Priority and overriding")
Custom skills take priority over built-in skills. If you create a custom skill with the same identifier as a built-in skill (e.g., `troubleshoot-integration`), your custom skill will be used instead.
This allows you to:
* Customize built-in workflows for your organization's specific needs.
* Add organization-specific context to existing skills.
* Replace generic instructions with your team's best practices.
## Best practices[](#best-practices "Direct link to Best practices")
When creating custom skills, follow these guidelines for best results:
### Keep instructions concise
Skills are loaded into the AI's context, so keep instructions under 5000 tokens (approximately 500 lines). Move detailed reference content to the `references` array instead of putting everything in the main instructions.
### Write clear trigger descriptions
The `description` field determines when Port AI loads the skill. Write descriptions that clearly indicate:
* What task the skill handles.
* Keywords or phrases users might use.
* When NOT to use the skill (if relevant).
**Good example:**
> "Diagnose and resolve integration sync issues, mapping errors, and data problems. Use when users report missing data, sync failures, or integration errors."
**Poor example:**
> "Helps with integrations."
### Structure instructions effectively
Organize instructions with clear structure. Include:
* Step-by-step instructions for completing the task.
* Examples of inputs and outputs.
* Common edge cases and how to handle them.
### Use resources for detailed content
Put detailed documentation, error catalogs, or templates in the `references` and `assets` arrays. The AI can load these on demand when needed, keeping the main instructions focused.
## Related pages[](#related-pages "Direct link to Related pages")
* [Skills registry](/agent-management/ai-registry/skills/skills-registry/.md): publish and sync approved skills from Git.
* [Enrich Port AI with skills](/agent-management/ai-registry/skills/enrich-port-ai-with-skills/.md): load skills at runtime in Port AI.
* [Skills usage analytics](/agent-management/ai-registry/skills/skills-usage-analytics/.md): measure skill adoption from Cursor and Claude.
---
# Skills registry
A skills registry is a central library of reusable skills that everyone across the organization can publish and consume. Instead of each squad maintaining its own prompts and instructions, approved skills live in one catalog in Port, discovered and installed through the UI, Port MCP, or a CLI command.
## What the registry solves[](#what-the-registry-solves "Direct link to What the registry solves")
Engineering teams adopt AI agents at different layers of the stack. Without a registry, skills get duplicated, quality varies, and platform teams lose visibility into what instructions agents follow.
The skills registry gives you:
* **A catalog of every skill in your org** - discoverable through the UI, Port MCP, or a CLI install.
* **A golden path for sharing skills** - one standard way to propose, review, and publish a new skill across the org, instead of ad hoc pull requests.
* **Composable skills** - group related skills into installable plugins as your registry grows.
* **Quality and governance bars** - certification review, duplicate detection, and an ROI scorecard catch skills that shouldn't be in the registry, whether they're low-quality, redundant, or not worth their cost.
* **Visibility into usage and cost** - real usage and spend data connected to the registry, so you can see which skills are actually adopted, and which are worth what they cost to run.
## Ingest skills from Git[](#ingest-skills-from-git "Direct link to Ingest skills from Git")
You can manage skills as `SKILL.md` files in Git and ingest them into Port through the GitHub Ocean or GitLab v2 integrations.
### Choose the skill or file kind[](#choose-the-skill-or-file-kind "Direct link to Choose the skill or file kind")
Choose one mapping kind. Do not combine them:
* Use the **`skill`** kind when you only need `SKILL.md` instructions in Port. It does not ingest files under `references/` or `assets/`.
* Use the **`file`** kind when those extra files must land on the skill entity as `properties.references` and `properties.assets`.
Do not model extra files as related entities, and do not reconstruct `references` with mirror or calculation properties.
* Skill kind
* File kind
The `skill` kind discovers common Agent Skill layouts (for example `.cursor/skills/**/SKILL.md` and `skills/**/SKILL.md`), parses frontmatter and instructions, and emits one entity per skill.
**GitHub Ocean mapping configuration (click to expand)**
```
deleteDependentEntities: false
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: skill
selector:
query: 'true'
paths:
- path: 'skills/**/SKILL.md'
organization: my-org
repos:
- name: my-repo
branch: main
- path: '.cursor/skills/**/SKILL.md'
organization: my-org
port:
entity:
mappings:
identifier: .__repository.full_name + "/" + .skill.skillMdPath
title: .skill.name // .skill.skillMdPath
blueprint: '"skill"'
properties:
instructions: .skill.instructions
description: .skill.description
location: '"global"'
```
**GitLab v2 mapping configuration (click to expand)**
```
deleteDependentEntities: false
createMissingRelatedEntities: true
resources:
- kind: skill
selector:
query: 'true'
paths:
- path: 'skills/**/SKILL.md'
repos:
- group/my-repo
- path: '.cursor/skills/**/SKILL.md'
port:
entity:
mappings:
identifier: .repo.path_with_namespace + "/" + .skill.skillMdPath
title: .skill.name // .skill.skillMdPath
blueprint: '"skill"'
properties:
instructions: .skill.instructions
description: .skill.description
location: '"global"'
```
On GitLab, skill discovery always uses the repository tree API (glob-friendly, not Advanced Search). On GitHub, discovery uses recursive git-tree matching with the same path-selector shape as the file kind - large orgs pay a tree walk per scanned repository.
See also:
* [GitHub Ocean - ingest agent skills](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/capabilities/.md#ingest-agent-skills)
* [GitLab v2 - ingest agent skills](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/capabilities/.md#ingest-agent-skills)
The `file` kind is the original GitOps pattern for skills. Map `SKILL.md` into `instructions`, and map files under `references/` and `assets/` into the matching array properties on the **same skill identifier**. Set `enableMergeEntity: true` so extra files merge onto the skill instead of replacing the instructions.
**GitHub Ocean file kind mapping (click to expand)**
```
deleteDependentEntities: false
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: file
selector:
query: 'true'
files:
- path: skills/**/SKILL.md
organization: my-org
repos:
- name: my-repo
branch: main
port:
entity:
mappings:
identifier: .repository.name + "/" + (.path | split("/")[1])
title: .path | split("/")[1]
blueprint: '"skill"'
properties:
instructions: .content
description: .content | capture("description:\\s*(?.+)").d
location: '"global"'
relations: {}
- kind: file
selector:
query: 'true'
files:
- path: skills/**/references/**
skipParsing: true
organization: my-org
repos:
- name: my-repo
branch: main
port:
entity:
mappings:
identifier: .repository.name + "/" + (.path | split("/")[1])
blueprint: '"skill"'
properties:
references:
- path: .path | split("/") | .[2:] | join("/")
content: .content
- kind: file
selector:
query: 'true'
files:
- path: skills/**/assets/**
skipParsing: true
organization: my-org
repos:
- name: my-repo
branch: main
port:
entity:
mappings:
identifier: .repository.name + "/" + (.path | split("/")[1])
blueprint: '"skill"'
properties:
assets:
- path: .path | split("/") | .[2:] | join("/")
content: .content
```
Each extra-file event replaces the whole `references` or `assets` array. If a skill has more than one file in the same directory, use the [upload skills from a folder](/agent-management/ai-registry/skills/overview/.md#upload-skills-from-a-folder) script so the full array is written in one request.
### Alternative: folder kind + included files[](#alternative-folder-kind--included-files "Direct link to Alternative: folder kind + included files")
You can still manage skills as folders in Git and ingest them with `kind: folder` when you need a custom folder layout. Folder kind with `includedFiles: [SKILL.md]` maps instructions only. If you also need `references/` or `assets/`, use the file kind instead of adding extra mappings on top of folder kind.
**GitHub Ocean folder-based mapping (click to expand)**
```
deleteDependentEntities: false
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: folder
selector:
query: 'true'
folders:
- path: '**/skills/*'
organization: my-org # Optional if githubOrganization is set (required if not set)
repos:
- name: my-repo
branch: main
includedFiles:
- SKILL.md
port:
entity:
mappings:
identifier: .__repository.name + "-" + (.folder.path | split("/") | last)
title: .__repository.name + "-" + (.folder.path | split("/") | last)
blueprint: '"skill"'
properties:
instructions: .__includedFiles["SKILL.md"]
description: .folder.path | split("/") | last
location: '"global"'
```
Using GitHub (Sunset) or also syncing prompts
If your account still uses Port's older GitHub app integration, or you also want to sync prompt files alongside skills, see the [Ingest prompts and skills from GitHub using GitOps](https://docs.port.io/guides/all/ingest-prompts-skills-from-github-using-gitops/) guide, which covers both integration versions and the combined prompts and skills setup.
After configuration, skills from your repositories will automatically sync to Port. Changes in Git will appear in your Port catalog after the integration syncs.
Common practices
* Keep `deleteDependentEntities: false` on this connector. Setting it to `true` means a temporary sync issue, like a rate limit, a revoked permission, or a renamed repo, deletes skill entities on the next resync instead of leaving them stale.
* Use a consistent folder naming convention in `skills/` so skill identifiers are predictable across repositories.
You can also [upload skills from a folder](/agent-management/ai-registry/skills/overview/.md#upload-skills-from-a-folder) with a script for CI/CD pipelines.
## Build a skills registry with our guides[](#build-a-skills-registry-with-our-guides "Direct link to Build a skills registry with our guides")
Follow these guides in order to go from a bare Git repository to a fully governed skills registry:
1. [Set up a skills registry](/guides/all/setup-skills-registry/.md) - model every skill in your org as a Port entity, assign it to groups, and let developers discover them.
2. [Ship new skills through one golden path](/guides/all/ship-skills-through-one-golden-path/.md) - give developers one standard way to propose a skill and track the review from a single dashboard.
3. [Certify skills to meet industry and org standards](/guides/all/certify-skills-to-meet-industry-and-org-standards/.md) - add an AI-driven review on top of the deterministic scorecards.
4. [Avoid duplicate skills in your org registry](/guides/all/avoid-duplicate-skills-in-your-org-registry/.md) - catch a duplicate skill pre-publish or during certification.
5. [Bundle skills into plugins](/guides/all/bundle-skills-into-plugins-in-your-org-registry/.md) - group related skills into installable plugins, with an AI-driven suggestion and a self-service workflow to apply it.
6. [Measure the ROI of skills in your org registry](/guides/all/measure-the-roi-of-skills-in-your-org-registry/.md) - connect real Claude usage and spend data to the registry.
7. [Visualize Claude Skills adoption and usage](/guides/all/visualize-claude-skills-adoption/.md) - build a dashboard tracking adoption, sharing, and spend.
## Next steps[](#next-steps "Direct link to Next steps")
* [Skills overview](/agent-management/ai-registry/skills/overview/.md): blueprint setup, entity creation, and best practices.
* [Enrich Port AI with skills](/agent-management/ai-registry/skills/enrich-port-ai-with-skills/.md): how Port AI loads skills at runtime.
* [Skills usage analytics](/agent-management/ai-registry/skills/skills-usage-analytics/.md): measure skill adoption from Cursor and Claude.
* [Build an AI agent](/agent-management/custom-agents/build-an-ai-agent/.md): attach sanctioned skills to domain-specific agents.
* [External agents](/agent-management/external-agents/overview/.md): inventory of agents hosted on external platforms.
---
# Skills usage analytics
Publishing skills in a [skills registry](/agent-management/ai-registry/skills/skills-registry/.md) is only half of the story. Platform teams also need to see which skills engineers actually use, how often they are invoked, and where adoption is growing or stalling.
Port ingests skill usage metrics from AI coding tools into your [software catalog](/context-lake/data-model/configure-data-model/.md), so you can build dashboards, scorecards, and reports on skill adoption alongside the rest of your engineering context.
## What you can analyze[](#what-you-can-analyze "Direct link to What you can analyze")
Depending on the integration, skill usage data can help you answer questions such as:
* Which skills are used most often across the organization.
* How skill adoption changes day over day.
* Which users and teams invoke each skill.
* Which surfaces drive usage (for example chat, Claude Code, or Office agents).
* How estimated spend or attributed usage value relates to specific skills.
Use this data to prioritize which skills to govern in the registry, retire unused skills, and prove the impact of platform-owned skill packs.
## Ingest skill usage metrics[](#ingest-skill-usage-metrics "Direct link to Ingest skill usage metrics")
Choose the integration that matches the AI tools your teams use. Each integration creates skill usage blueprints and mapping out of the box when you enable the relevant resource kinds.
| Method | Best for | Skill usage resource | Setup |
| -------------------------- | -------------------------------------------------------------------------- | ------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------- |
| **Cursor** | Teams using Cursor Analytics (Enterprise) for skill adoption | `cursor-team-skill-usage` | [Cursor metrics](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/cursor/.md) |
| **Claude AI (Enterprise)** | Teams using Claude Enterprise analytics for org, user, or team skill usage | `claude-ai-skill-usage` | [Claude AI metrics](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/claude/.md) |
Enterprise analytics access
Both skill usage kinds rely on vendor analytics APIs that require an Enterprise plan and an API key with analytics read permissions. Confirm access on the Cursor or Claude integration page before enabling these kinds.
### Cursor[](#cursor "Direct link to Cursor")
The Cursor integration syncs daily team-level skill adoption from the Cursor Analytics API. Each entity represents a skill on a given day, including skill name and usage count.
See the [`cursor-team-skill-usage`](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/cursor/.md) kind for blueprint schema, default mapping, sample payload, and optional user filters.
### Claude AI (Enterprise)[](#claude-ai-enterprise "Direct link to Claude AI (Enterprise)")
The Claude integration syncs skill usage for a single day at a time from Anthropic's skill analytics API. Each entity includes invocation counts, distinct users, share status, product-surface breakdowns, and optional spend fields.
Leave `groupBy` empty for org-level totals, or set it to one of `user_id`, `rbac_group_id`, or `product` to break the same metrics out by user, team, or product surface. Use one dimension at a time.
See the [`claude-ai-skill-usage`](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/claude/.md) kind under Claude AI (Enterprise) mode for blueprint schema and default mapping. For user- and team-level rows, follow [Breaking down analytics on user and team level](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/claude/.md#breaking-down-analytics-on-user-and-team-level).
## Related pages[](#related-pages "Direct link to Related pages")
* [Skills overview](/agent-management/ai-registry/skills/overview/.md): skill concepts, blueprints, and creation.
* [Skills registry](/agent-management/ai-registry/skills/skills-registry/.md): publish and sync approved skills from Git.
* [Enrich Port AI with skills](/agent-management/ai-registry/skills/enrich-port-ai-with-skills/.md): load skills at runtime in Port AI.
* [Visualize Cursor metrics](/guides/all/visualize-cursor-metrics/.md): dashboards for Cursor adoption and impact.
* [Visualize Claude metrics](/guides/all/visualize-claude-metrics/.md): dashboards for Claude usage and cost.
---
# Build agents
Built on Port AI
AI Agents are built on top of [Port AI](/port-ai/overview/.md) and leverage its underlying capabilities for data access, security, and execution. This guide focuses on agent-specific building techniques.
## Getting started[](#getting-started "Direct link to Getting started")
Building an AI agent in Port involves several key steps.
Let's walk through the process of creating an agent that can assist your developers with finding information and completing tasks.
## Create a new AI agent[](#create-a-new-ai-agent "Direct link to Create a new AI agent")
To create a new agent, head to the AI Agents catalog page (this page will be created for you when you [activate the feature](/agent-management/custom-agents/overview/.md#access-to-the-feature)).
Click on the "New AI Agent" button and fill the form with the agent details.
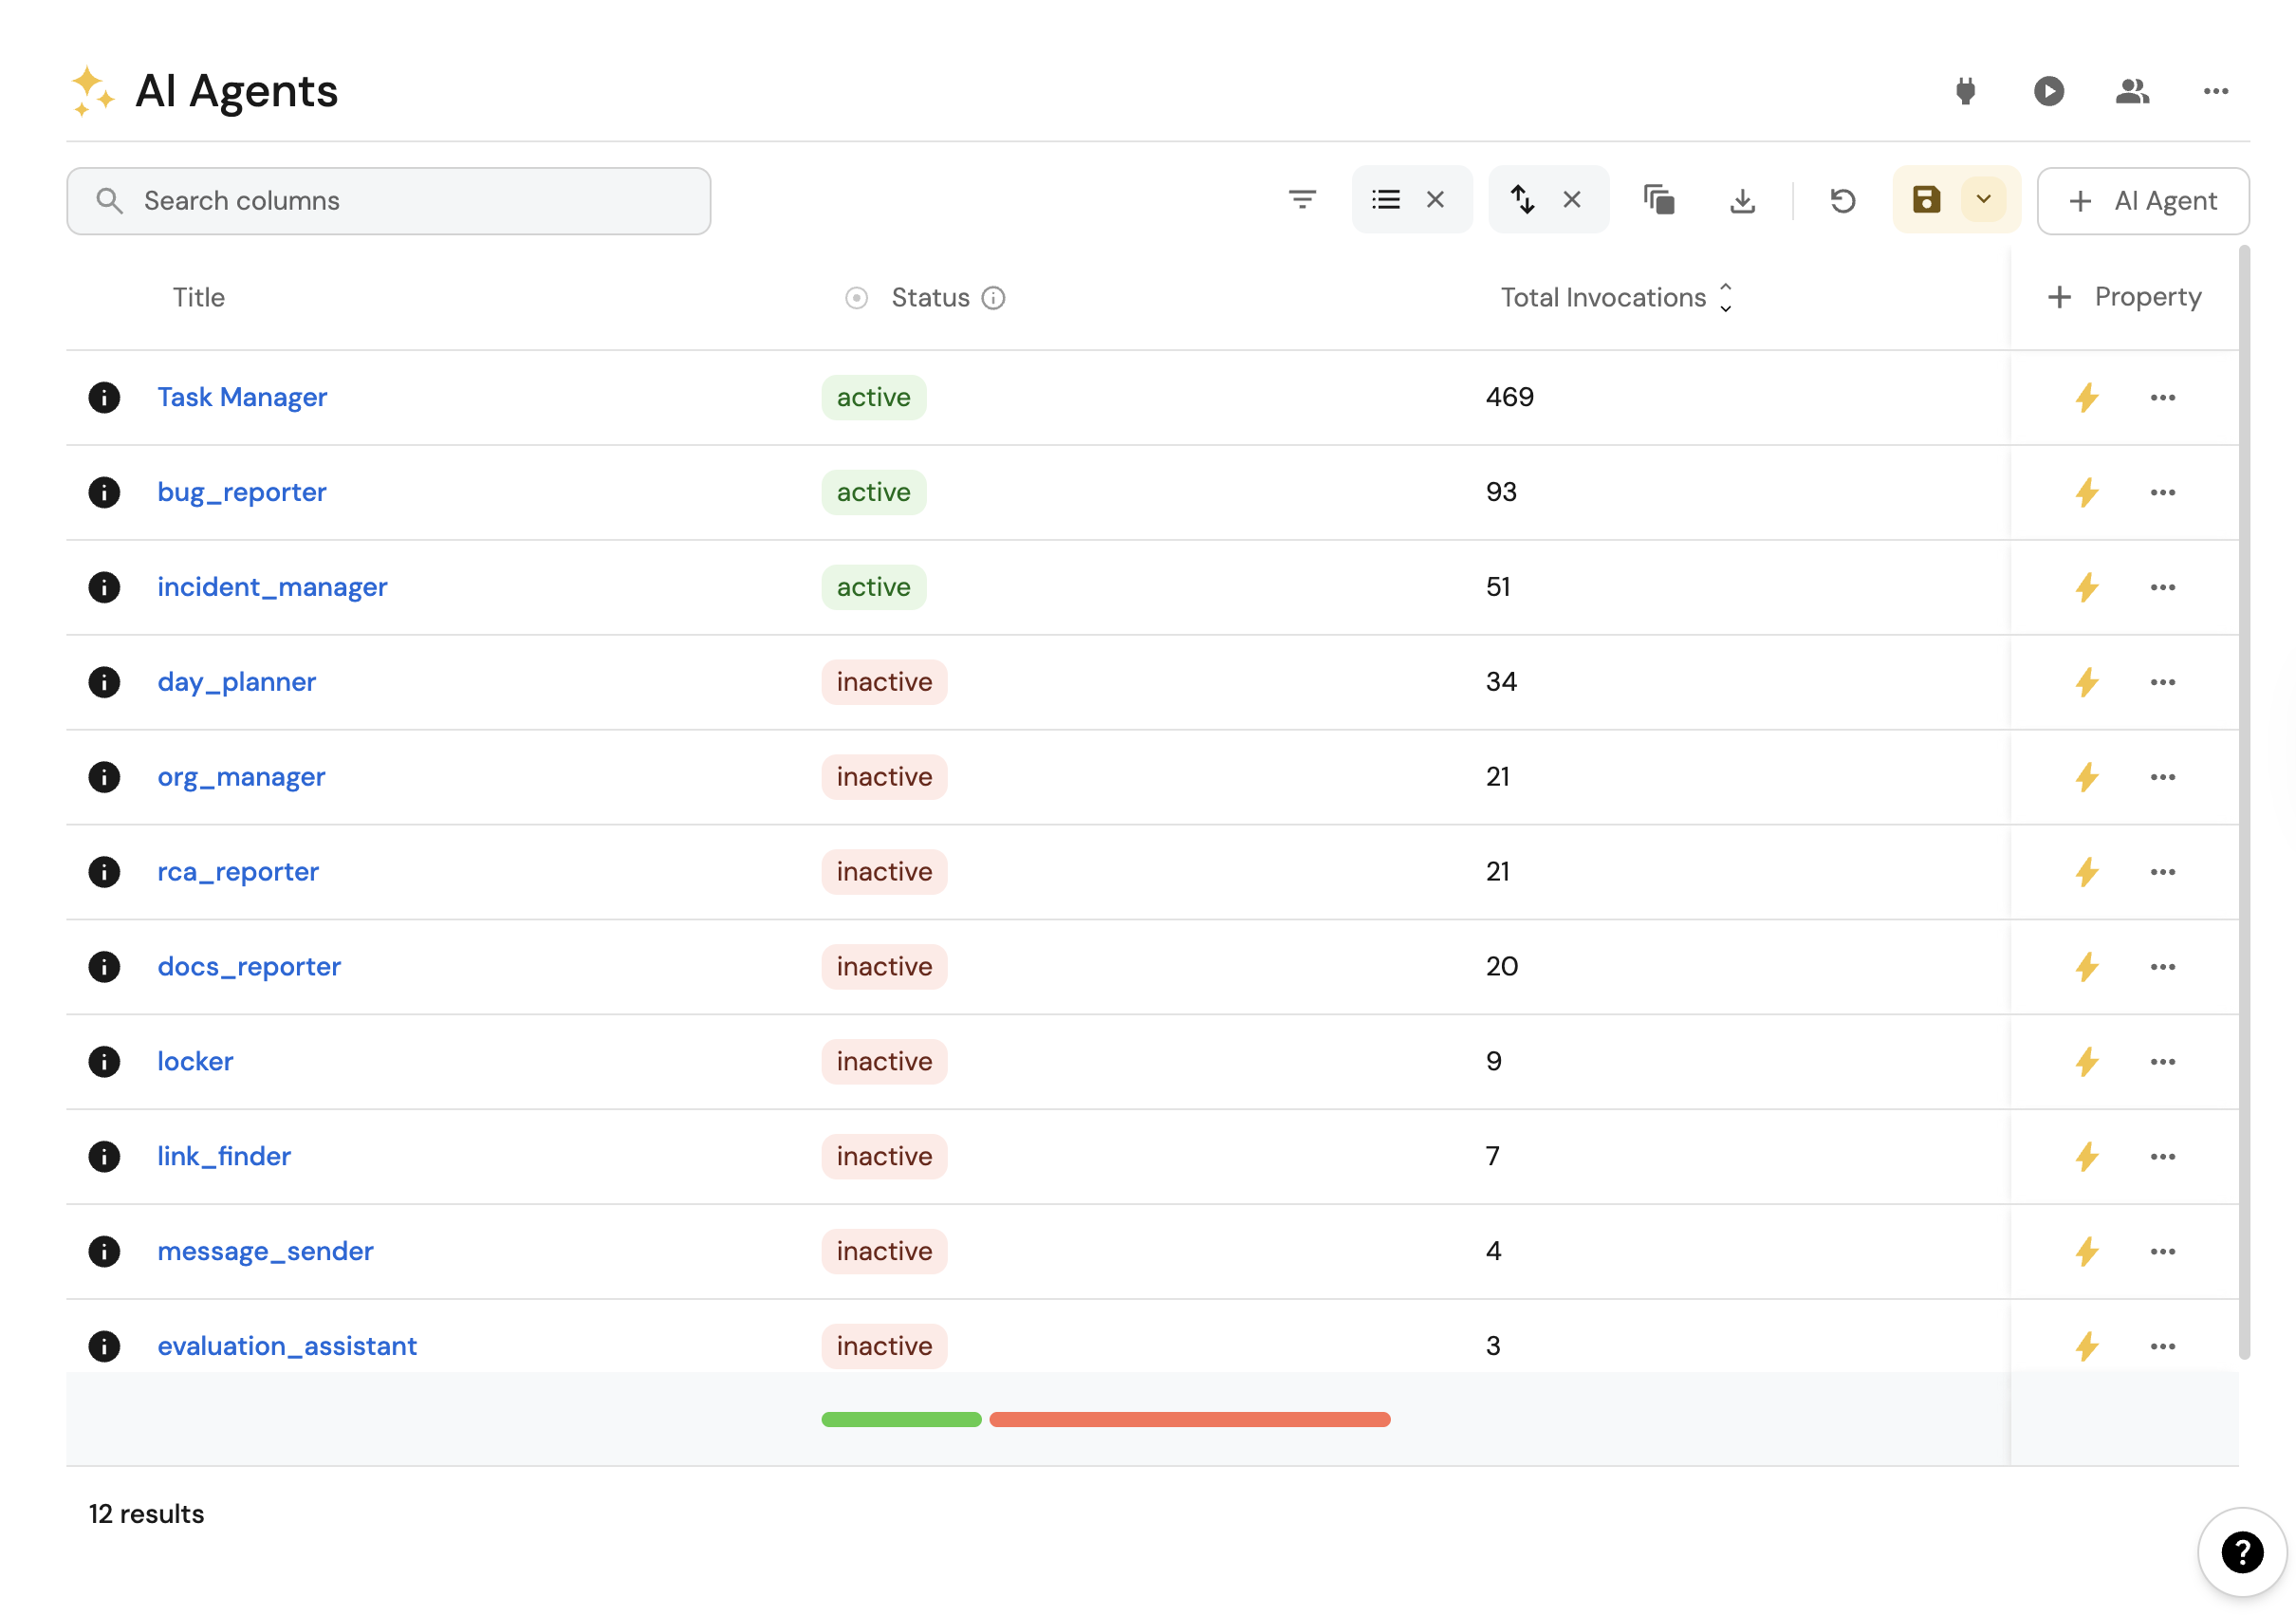 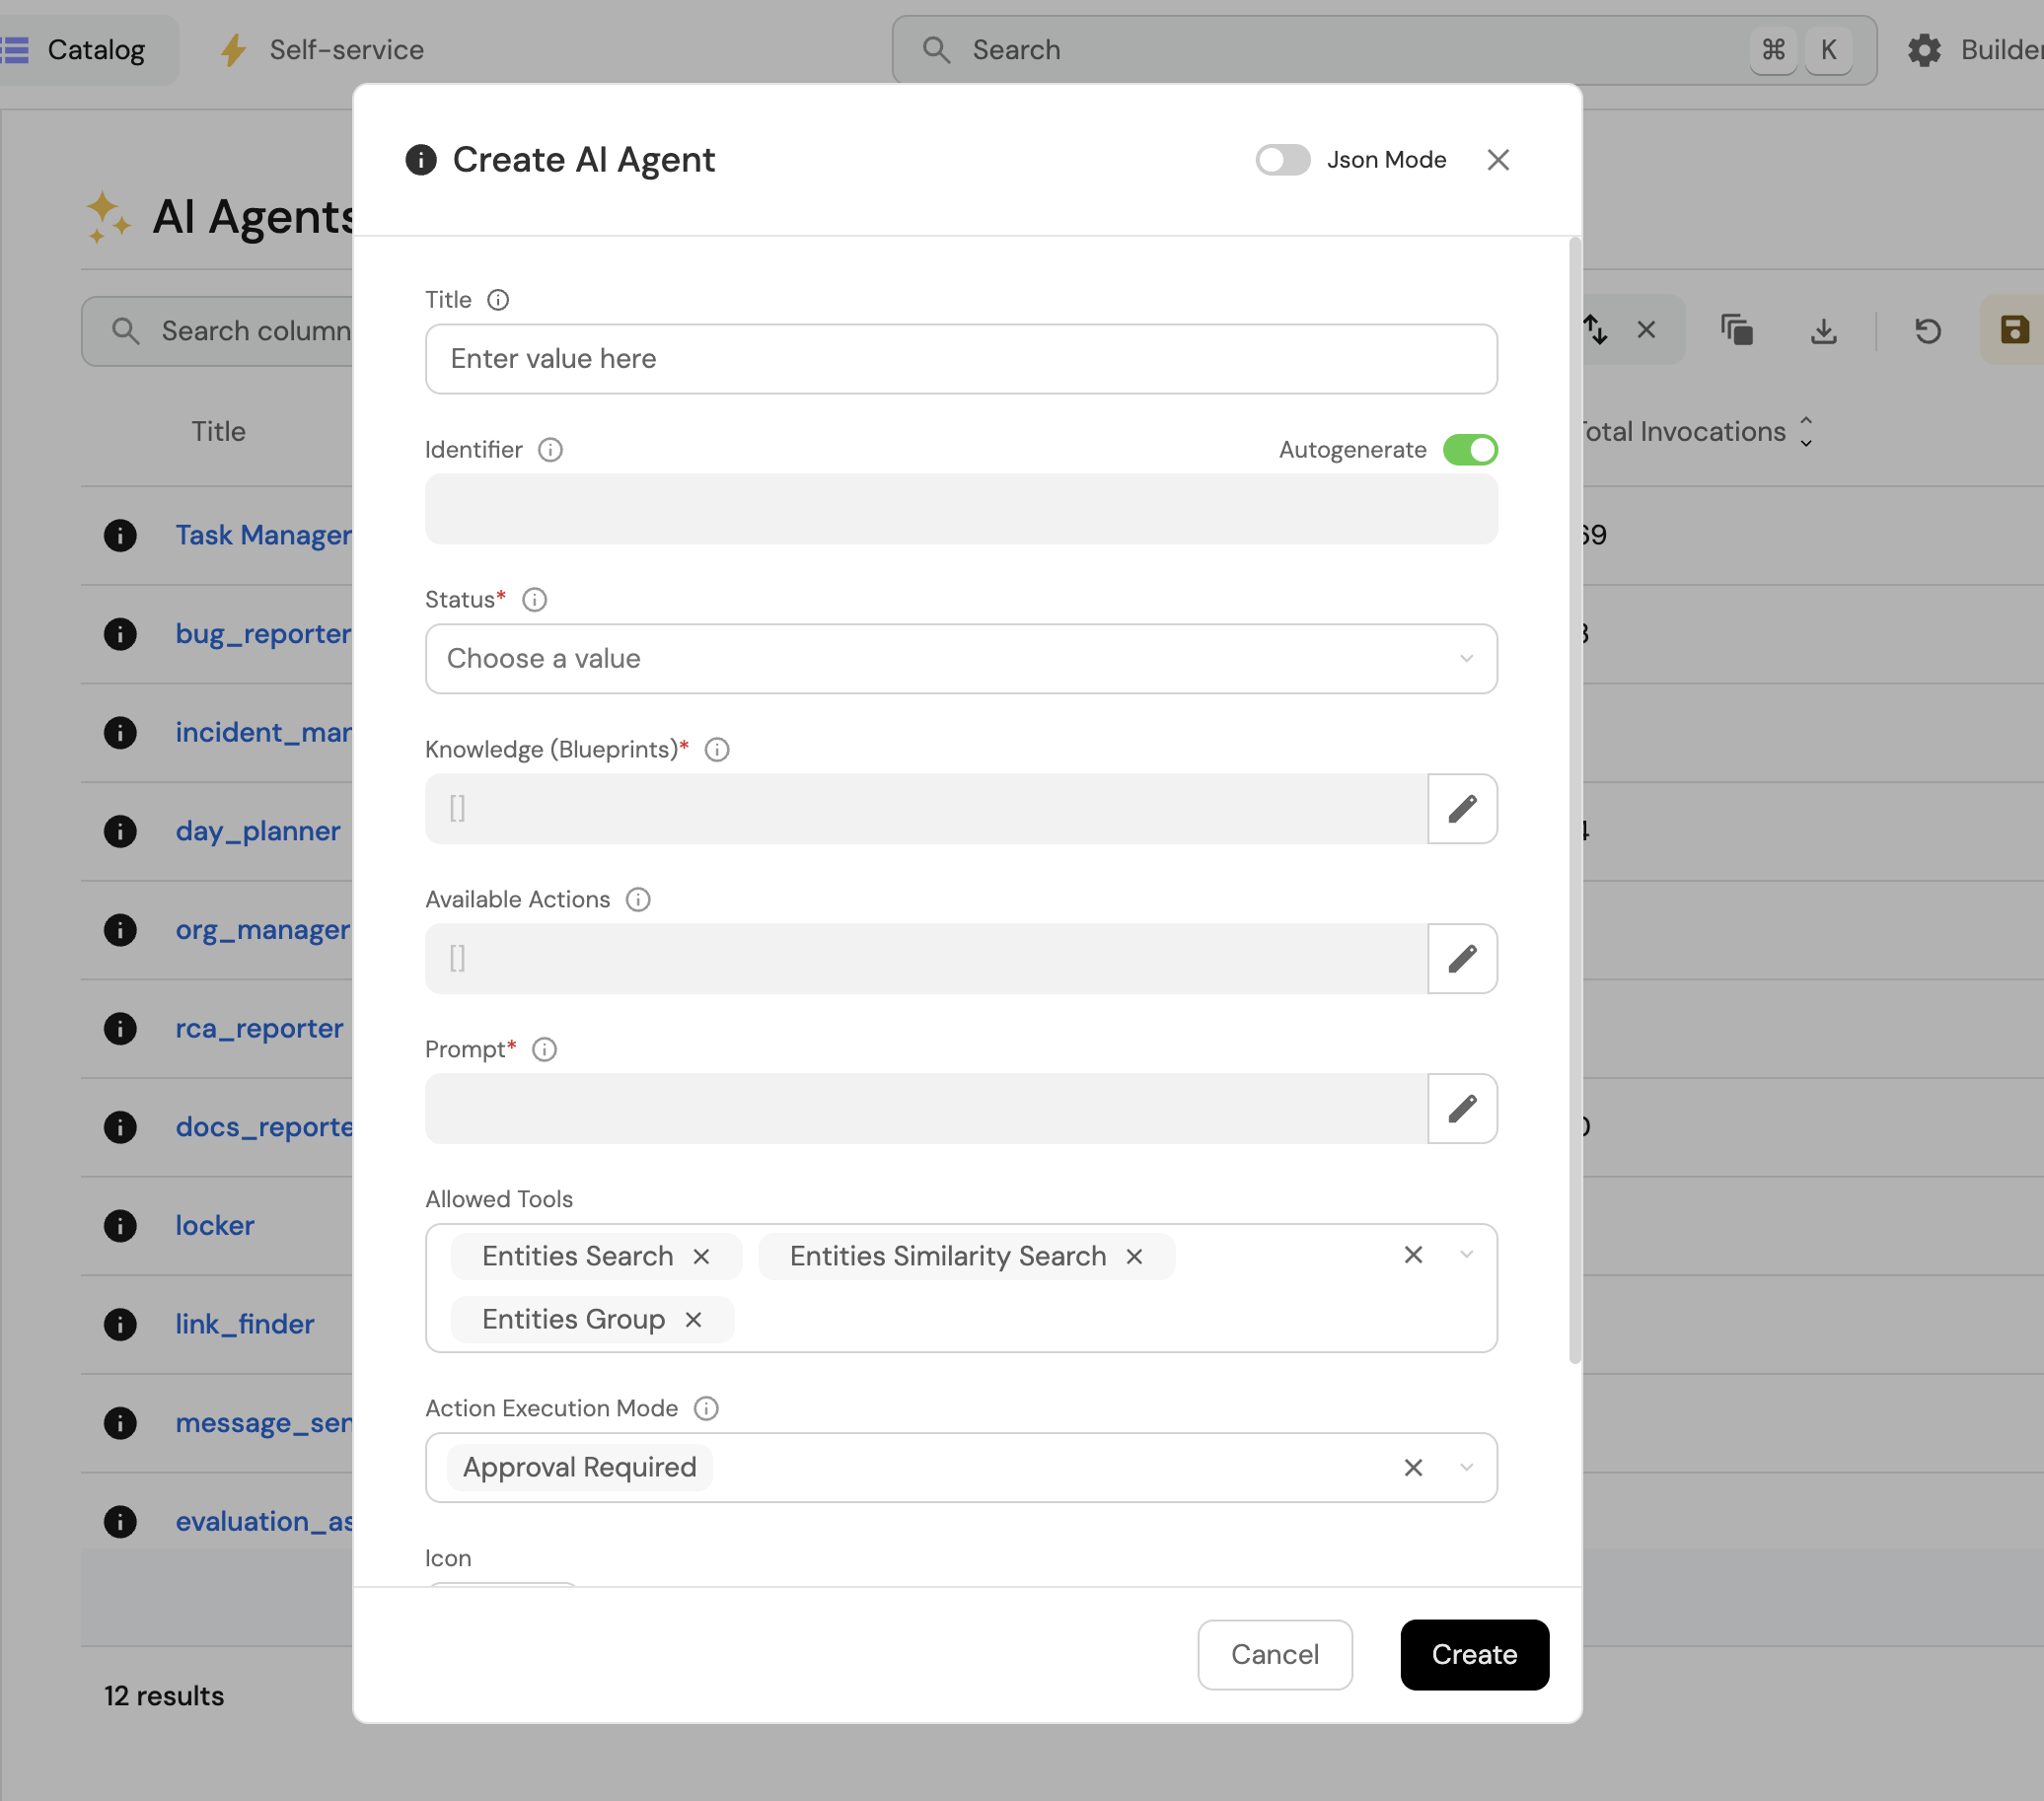
We recommend following the steps below.
### Step 1: Define your agent's purpose[](#step-1-define-your-agents-purpose "Direct link to Step 1: Define your agent's purpose")
The first step in building an AI agent is deciding on its purpose.
Here we will determine whether the agent will:
* Answer questions about your development environment.
* Help run actions and complete tasks.
We recommend starting with a simple use case that a junior assistant with access to your data could assist with.
For inspiration, check our [AI agents guides](/guides/.md?tags=Agent%20management).
### Step 2: Configure data access tools[](#step-2-configure-data-access-tools "Direct link to Step 2: Configure data access tools")
Configure which data tools your agent can access. Configure access to Port data through [Port AI tools](/port-ai/overview/.md#tools). Available tools include data query tools for retrieving information from your catalog, as well as running self-service actions.
### Step 3: Configure actions access[](#step-3-configure-actions-access "Direct link to Step 3: Configure actions access")
Actions are executed through the `run_action` tool, which dynamically handles all available actions in your Port instance. When you configure an action for the agent, it becomes available as a tool the agent can use.
Provide action access in one of these ways:
1. **Allowed Actions input (recommended)** - Add the specific actions this agent can execute in the **Allowed Actions** input in the AI agent form.
2. **Advanced mode (regex)** - Switch to **Advanced mode (regex)** if you need full control over the `tools` list (for example, mixed custom patterns). In this mode, you can add action tools using patterns such as `run_{action_identifier}`.
3. Choose the execution mode (automatic or approval-required) for the selected actions.
To find an action identifier, open the [self-service](https://app.port.io/self-serve) page and copy the action identifier.
While the underlying implementation uses the unified `run_action` tool, you can still reference specific actions with `run_{action_identifier}` for clarity and backward compatibility.
For details on manual approval vs automatic execution patterns, see [Port AI tool execution modes](/port-ai/tools-and-approvals/.md#tool-execution-modes).
### Step 4: Configure MCP server access[](#step-4-configure-mcp-server-access "Direct link to Step 4: Configure MCP server access")
You can give your agent access to tools from external systems through [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md). This lets the agent query or act on data that does not live in your Port catalog (for example, Notion, Linear, or Slack).
MCP connectors configured on the agent entity work in interactive chat when the user connects to each server. They do not run in automations or `AI_AGENT` workflow nodes. For workflow external MCP, see [use MCP connectors in workflows](/agent-management/ai-registry/mcp-connectors/use-in-workflows/.md).
1. In the **MCP servers** relation field, select which MCP servers this agent can use.
2. In the **Allowed MCP tools** section, choose which tools the agent may use for each selected server. You can toggle individual tools, or use **All** / **None** for a server.
3. **Save** is available only when every selected server is connected and has at least one tool enabled.
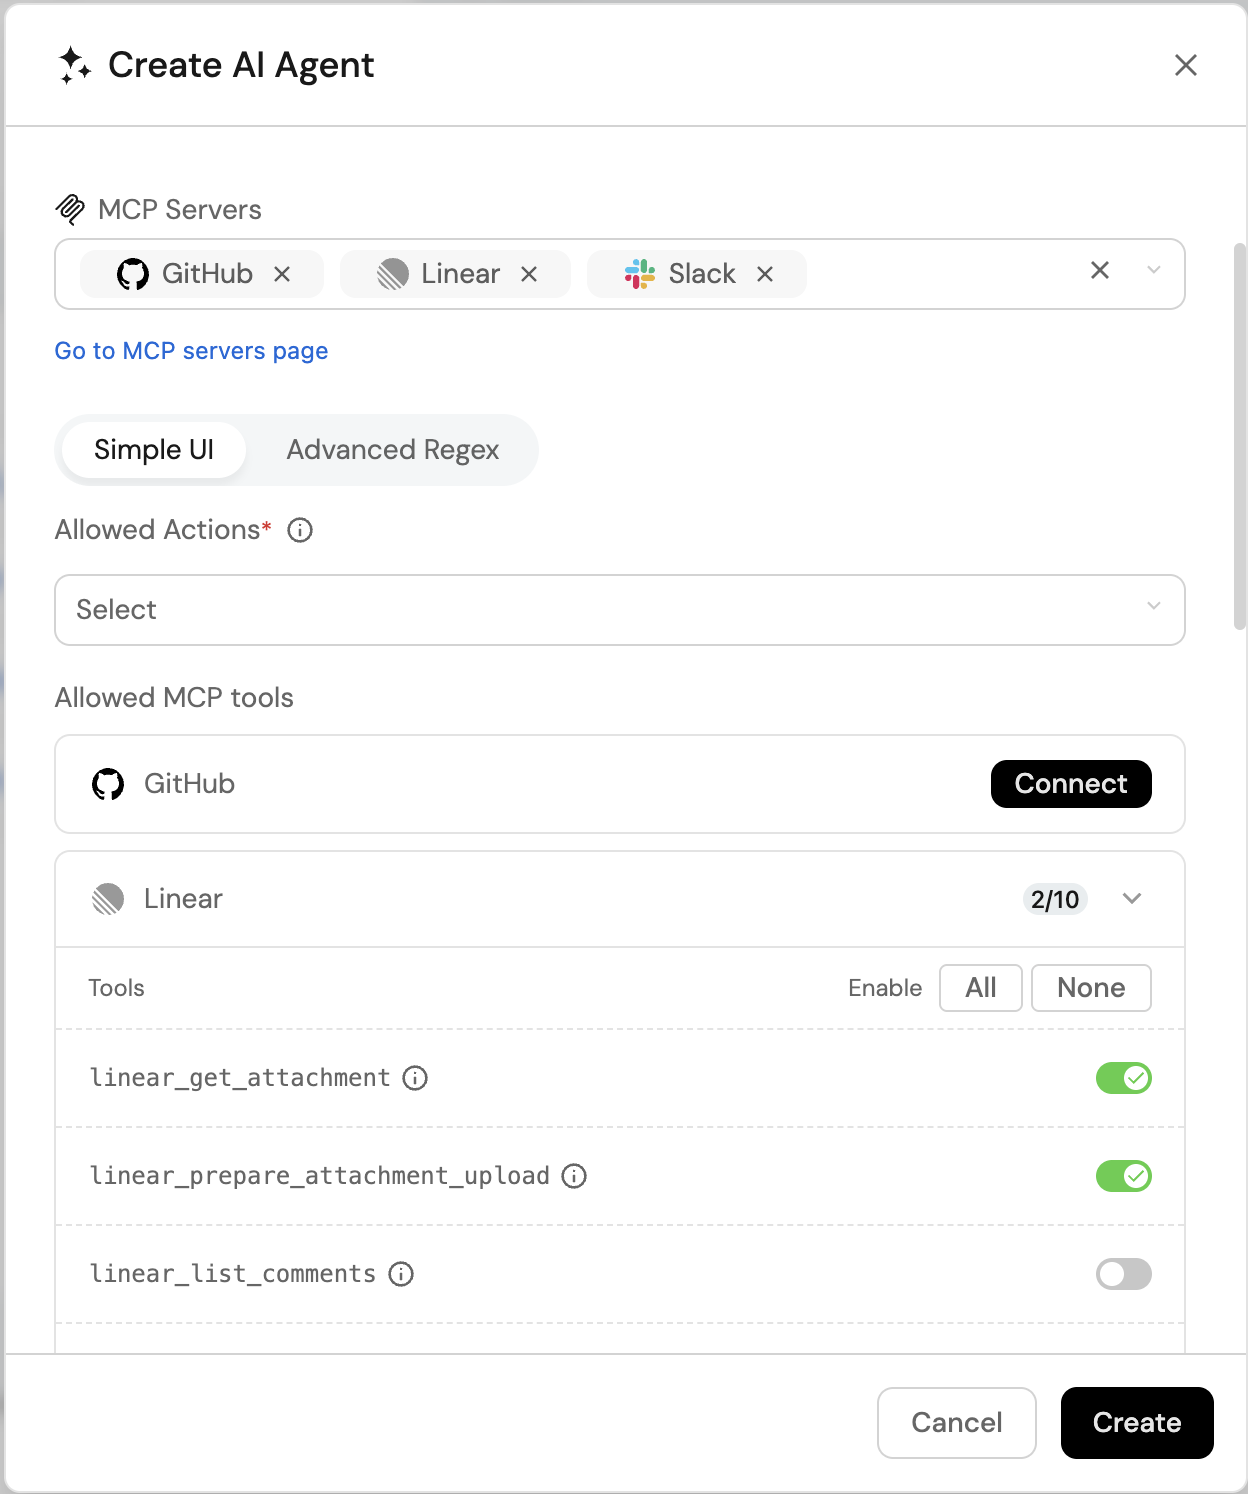
For connector setup and authentication, see [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md).
### Step 5: Define the prompt[](#step-5-define-the-prompt "Direct link to Step 5: Define the prompt")
The prompt is your main tool for influencing your agent's success. You will likely iterate on it as you observe how the agent responds to different queries.
For comprehensive guidance on crafting effective prompts, see [Context Engineering](/port-ai/context-engineering/.md). This covers prompt design principles, examples, and best practices for creating prompts that leverage your organization's specific data and terminology.
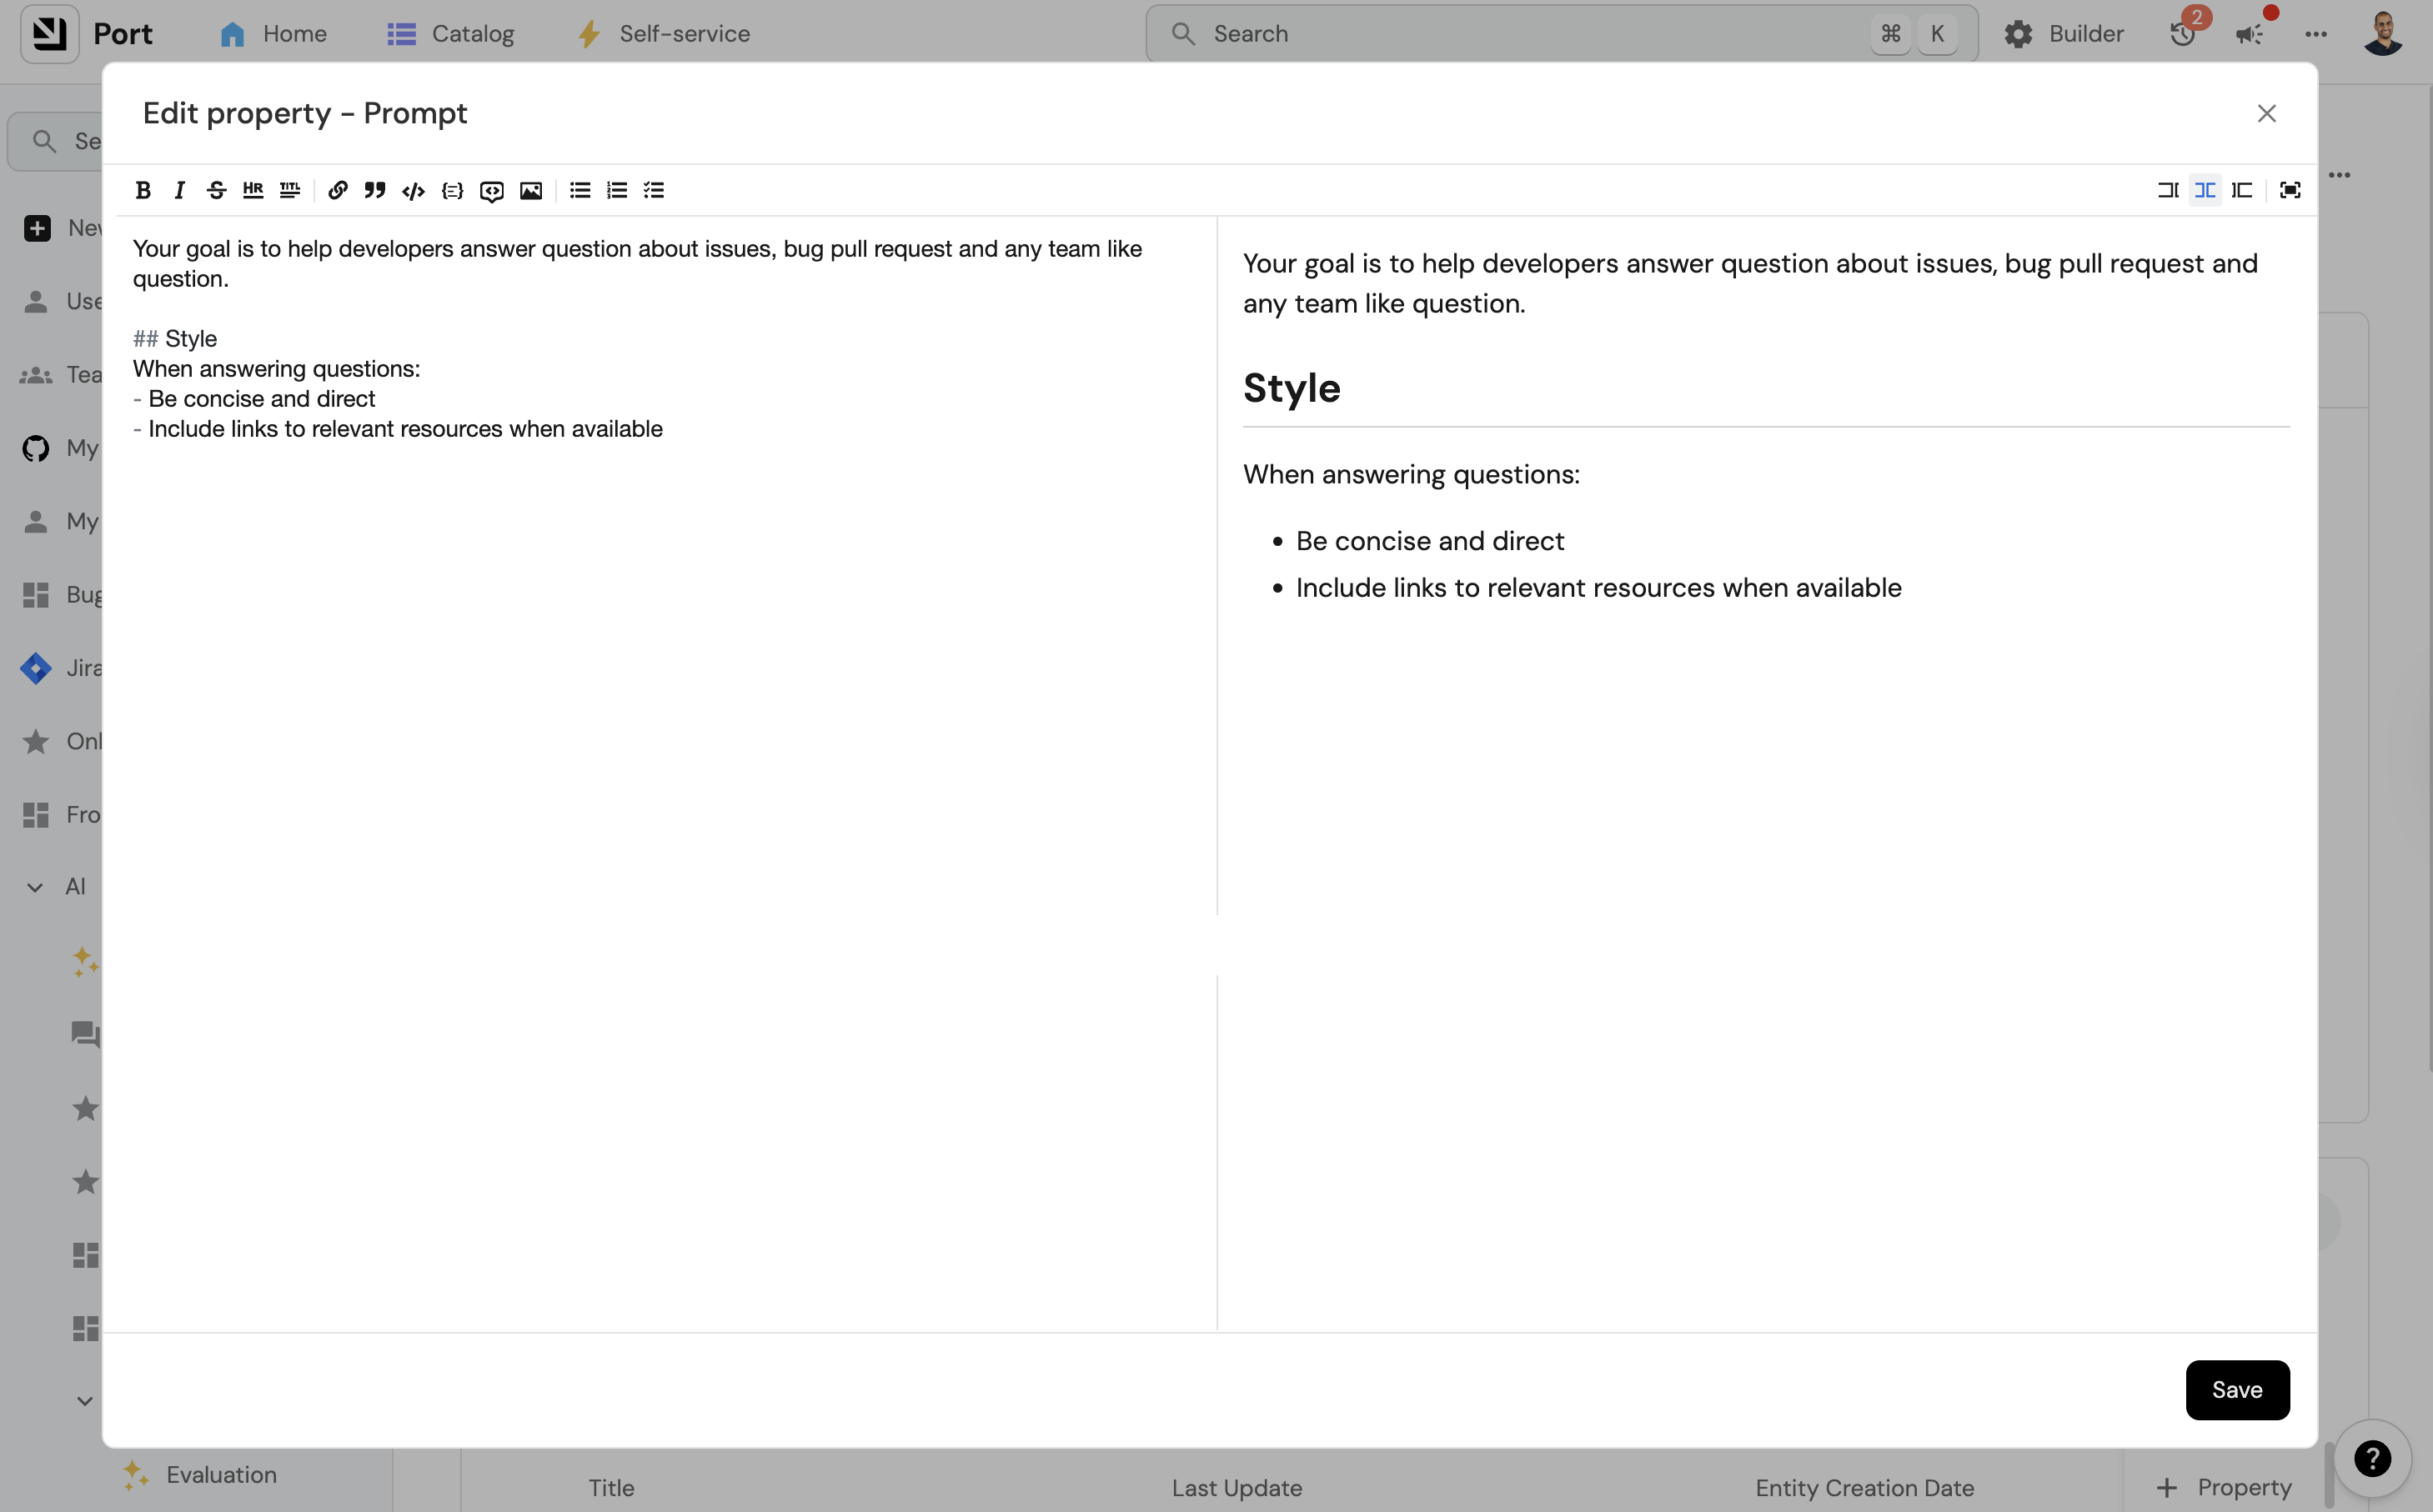
### Step 6: Activate your agent[](#step-6-activate-your-agent "Direct link to Step 6: Activate your agent")
When you feel your agent is ready:
1. Set its status to "Active".
2. Start interacting with it through the [available interfaces](/agent-management/custom-agents/interact-with-ai-agents/.md).
### Step 7: Configure user permissions[](#step-7-configure-user-permissions "Direct link to Step 7: Configure user permissions")
Creating and activating an agent is not enough for your users to interact with it. Access to Port AI features is controlled separately through the `_ai_invocation` blueprint's permissions.
Permissions required
Users need the **Read**, **Register**, and **Update** permissions on the `_ai_invocation` blueprint to invoke and interact with any Port AI feature, including your newly created agent.
[Learn how to configure access to Port AI →](/port-ai/security-and-data-controls/.md#controlling-access-to-port-ai)
## Evaluating your agent performance[](#evaluating-your-agent-performance "Direct link to Evaluating your agent performance")
Continuous evaluation and improvement are essential for maintaining effective AI agents. We recommend implementing a regular review process:
1. **Weekly reviews**: Set aside time each week to review agent interactions
2. **Identify patterns**: Look for recurring issues or misunderstandings in how the agent interprets queries
3. **Refine the prompt**: Update your agent's prompt based on your findings to address common issues
For details on how to analyze agent behavior and view execution plans, see [AI invocations](/port-ai/ai-invocations/.md).
## Examples[](#examples "Direct link to Examples")
For comprehensive examples of AI agents in action, see our practical implementation guides:
**Infrastructure & Operations:**
* [Heal unhealthy Kubernetes pods](/guides/all/heal-unhealthy-k8s-pods/.md) - Automated pod healing and recovery
* [AI-powered incident management](/guides/all/ai-powered-incident-management/.md) - AI-powered incident communication and updates
**Development Workflow:**
* [Automatically resolve tickets with Port](/guides/all/automatically-resolve-tickets/.md?approach=coding-agents) - AI-powered code generation and ticket resolution.
* [PR Enricher AI Agent](/guides/all/setup-pr-enricher-ai-agent/.md) - Enhanced pull request analysis and context
**Platform Operations:**
* [Platform Request Triage AI Agent](/guides/all/setup-platform-request-triage-ai-agent/.md) - Intelligent request routing and prioritization
* [Service Explorer AI Agent](/guides/all/setup-service-explorer-ai-agent/.md) - Service discovery and exploration
These guides provide step-by-step implementation details, including tool configuration, prompt engineering, and real-world integration patterns.
## Formatting the agent response[](#formatting-the-agent-response "Direct link to Formatting the agent response")
To format the agent's response, you can specify the desired format in its prompt. For optimal results when using the UI, it's recommended to request a markdown format response. This allows for better presentation and readability of the information provided by the agent. When sending messages through Slack, our [Slack app](/interface-builder/notifications/slack-app/.md) convert the markdown format into a Slack compatible formatting.
### Example of a Markdown Response[](#example-of-a-markdown-response "Direct link to Example of a Markdown Response")
```
:rocket: *New version deployed!*
[Added logs](https://www.example.com)
From [john-123](https://github.com/john-123)
```
## Troubleshooting and FAQ[](#troubleshooting-and-faq "Direct link to Troubleshooting and FAQ")
1I don't see an option to add an AI agent
2My agent can't access the data I need - what's wrong?
3How can I make sure the agent doesn't run actions without approval?
4My agent isn't performing well - how do I improve it?
5Users can see the agent but get an error when invoking it
6My agent is active but doesn't appear in the AI chat for my users
7I configured actions for my agent but it won't execute them
---
# Interact with agents
Built on Port AI
AI Agents are specialized implementations built on top of [Port AI](/port-ai/overview/.md), designed for machine-to-machine communication and autonomous operations within defined domains.
## Getting started[](#getting-started "Direct link to Getting started")
Once you've built your AI agents, you can integrate them into your workflows and systems. AI agents are designed for machine-to-machine communication and can be triggered programmatically through Port's API or automatically through workflow automations.
MCP servers require a connected user
If an agent uses [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md), each user must connect to all of the agent's MCP servers before chatting with it. Agent MCP does not run in automations or `AI_AGENT` workflow nodes. For workflow external MCP, see [use MCP connectors in workflows](/agent-management/ai-registry/mcp-connectors/use-in-workflows/.md). See [authenticate to connectors](/agent-management/ai-registry/mcp-connectors/.md#authenticate-to-connectors).
## How AI Agents Work[](#how-ai-agents-work "Direct link to How AI Agents Work")
AI Agents are domain-specific entities built on [Port AI](/port-ai/overview/.md) with configured tools and prompts. For details on agent architecture and configuration, see [AI agents overview](/agent-management/custom-agents/overview/.md) and [Build agents](/agent-management/custom-agents/build-an-ai-agent/.md).
## Interaction approaches[](#interaction-approaches "Direct link to Interaction approaches")
AI agents are designed for specific domains and use cases. When interacting with agents, you target the specific agent that has the expertise and tools needed for your task. This approach works best for structured scenarios like automation triggers and API integrations where you know which domain-specific capabilities you need.
## Interaction methods[](#interaction-methods "Direct link to Interaction methods")
* AI Chat Widget
* API integration
* Actions and automations
You can add AI agents directly to your dashboards as interactive widgets, providing easy access to their capabilities right where you need them.
Follow these steps to add an AI agent widget:
1. Go to a dashboard.
2. Click on `+ Widget`.
3. Select the `AI Chat` widget.
4. Configure your widget settings:
* **Agent**: Select the specific AI agent to use
* **Title**: Set a descriptive name for the widget
* **Description**: Add a description for the widget
5. Save your dashboard configuration.
6. Start asking questions through the chat interface.
The widget provides a chat interface where you can ask questions and receive responses from the **selected agent** without leaving your dashboard.
The widget will inherit all the agent's configuration including the prompts, conversation starters, tool access, etc.
**Context Awareness**: The widget recognizes the page it's placed on and suggests relevant context for your question, such as the full page, or specific elements on it like a widget, graph, text block, or table. Click a suggestion to add it to your question, then ask about what you're looking at without needing to spell out the details yourself. Click it again to remove it if it's not relevant to your question.
Conversation starters appear in the initial state, helping users understand what they can ask the agent. Users can either click a starter to begin a new chat or type their own question.
AI agents can be integrated into your applications and workflows through Port's API. Agents use the same streaming API patterns as Port AI.
**Agent-specific endpoint:**
```
curl 'https://api.port.io/v1/agent//invoke?stream=true' \
-H 'Authorization: Bearer ' \
-H 'Content-Type: application/json' \
--data-raw '{"prompt":"Analyze the health of our production services"}'
```
For comprehensive details on API interaction, streaming responses, and event types, see [API interaction](/port-ai/api-interaction/.md). For quota management, see [Limits and quotas](/port-ai/limits-and-quotas/.md).
You can trigger AI agents through Port's actions and automations, enabling integration of AI capabilities into your existing workflows. This is the primary method for creating autonomous, machine-to-machine AI systems.
### Automation Workflows
Automations allow you to automatically trigger AI agents based on events in your Port catalog. This enables reactive AI systems that respond to changes in your infrastructure or applications.
**Example: Automatic Incident Response (click to expand)**
When a new incident is created, automatically trigger an agent that:
* Analyzes the incident context
* Gathers relevant information from related services
* Creates initial response documentation
* Notifies appropriate teams
Create in Port
```
{
"identifier": "incident_response_automation",
"title": "Automatic Incident Response",
"trigger": {
"type": "automation",
"event": {
"type": "ENTITY_CREATED",
"blueprintIdentifier": "incident"
}
},
"invocationMethod": {
"type": "WEBHOOK",
"url": "https://api.port.io/v1/agent/incident_response_agent/invoke",
"method": "POST",
"headers": {
"Content-Type": "application/json"
},
"body": {
"prompt": "New incident created: {{ .entity.title }}. Severity: {{ .entity.properties.severity }}. Please analyze and provide initial response recommendations.",
"labels": {
"source": "automation",
"incident_id": "{{ .entity.identifier }}",
"trigger_type": "incident_created"
}
}
}
}
```
**Example: Infrastructure Healing (click to expand)**
Monitor infrastructure health and automatically trigger healing agents when issues are detected:
Create in Port
```
{
"identifier": "k8s_healing_automation",
"title": "Kubernetes Workload Healing",
"trigger": {
"type": "automation",
"event": {
"type": "ENTITY_UPDATED",
"blueprintIdentifier": "k8s_workload"
},
"condition": {
"type": "JQ",
"expressions": [
".diff.before.properties.isHealthy == \"Healthy\"",
".diff.after.properties.isHealthy == \"Unhealthy\""
],
"combinator": "and"
}
},
"invocationMethod": {
"type": "WEBHOOK",
"url": "https://api.port.io/v1/agent/k8s_healing_agent/invoke",
"method": "POST",
"headers": {
"Content-Type": "application/json"
},
"body": {
"prompt": "Workload {{ .event.diff.after.title }} is unhealthy. Current state: {{ .event.diff.after.properties.replicas }} replicas, {{ .event.diff.after.properties.readyReplicas }} ready. Please analyze and fix.",
"labels": {
"source": "automation",
"workload_name": "{{ .event.diff.after.identifier }}",
"namespace": "{{ .event.diff.after.properties.namespace }}"
}
}
}
}
```
### Self-Service Actions
You can create self-service actions that invoke AI agents, allowing users to trigger intelligent workflows on-demand.
**Example: Service Analysis Action (click to expand)**
Create in Port
```
{
"identifier": "analyze_service_health",
"title": "Analyze Service Health",
"description": "Get AI-powered analysis of service health and recommendations",
"trigger": {
"type": "self-service",
"operation": "DAY-2",
"blueprintIdentifier": "service"
},
"invocationMethod": {
"type": "WEBHOOK",
"url": "https://api.port.io/v1/agent/service_health_agent/invoke",
"method": "POST",
"headers": {
"Content-Type": "application/json"
},
"body": {
"prompt": "Analyze the health of service {{ .entity.title }}. Check metrics, recent deployments, and incidents.",
"labels": {
"source": "self_service",
"service_name": "{{ .entity.identifier }}",
"requested_by": "{{ .trigger.by.user.email }}"
}
}
}
}
```
For comprehensive examples, see our [AI guides](/guides/.md?tags=Agent%20management).
## Discovering Available Agents[](#discovering-available-agents "Direct link to Discovering Available Agents")
You can discover available AI agents through the AI Agents catalog page or programmatically via the API using the `_ai_agent` blueprint.
**cURL Example (click to expand)**
```
curl -L 'https://api.port.io/v1/blueprints/_ai_agent/entities' \
-H 'Accept: application/json' \
-H 'Authorization: Bearer '
```
## AI interaction details[](#ai-interaction-details "Direct link to AI interaction details")
Every AI agent interaction creates an entity in Port, providing tracking and analysis capabilities. For comprehensive details on AI invocations, execution plans, and tools used, see [AI invocations](/port-ai/ai-invocations/.md).
### Data & security considerations[](#data--security-considerations "Direct link to Data & security considerations")
For information on data handling and security, see [AI Security and Data Controls](/port-ai/security-and-data-controls/.md).
## Limits[](#limits "Direct link to Limits")
AI agents use the same rate limits and quotas as Port AI.
*Note: These limits apply when using Port's managed AI infrastructure. [Bring your own LLM provider](/port-ai/llm-providers-management/overview/.md) to use your provider's limits instead.*
For detailed information on limits, monitoring, and quota management, see [Limits and quotas](/port-ai/limits-and-quotas/.md).
## Troubleshooting and FAQ[](#troubleshooting-and-faq "Direct link to Troubleshooting and FAQ")
1Why can't I send messages to an agent in chat?
2What determines whether an agent can answer a question?
3How do I improve agent performance?
---
# Port custom agents
Built on Port AI
AI Agents are specialized implementations built on top of [Port AI](/port-ai/overview/.md), designed for specific domains and machine-to-machine communication. For general AI capabilities and human interaction, see [Port AI](/port-ai/overview/.md).
[YouTube video player](https://www.youtube.com/embed/wtnT7F8xsWQ)
## What are Port AI Agents?[](#what-are-port-ai-agents "Direct link to What are Port AI Agents?")
Port AI Agents are pre-configured, domain-specific entities built on [Port AI](/port-ai/overview/.md) that enable intelligent machine-to-machine communication. Unlike general AI assistants designed for human interaction, AI Agents are purpose-built for specific domains (like incident management, deployment orchestration, or security monitoring) and excel at autonomous operations within defined boundaries.

## Agent Characteristics[](#agent-characteristics "Direct link to Agent Characteristics")
AI Agents are distinguished by three key characteristics that make them ideal for machine-to-machine workflows:
1. **Domain Ownership** - Each agent is specifically designed for a particular domain or function (incident management, security monitoring, deployment orchestration).
2. **Autonomous Operation** - Agents operate independently within defined boundaries , making them perfect for automated workflows, background monitoring and alerting, and system-to-system communication where human intervention isn't required.
3. **Reusability Across Systems** - Agents can be integrated into multiple systems and workflows, like API-driven integration, third-party system integrations, etc.
## When to Use AI Agents vs Port AI[](#when-to-use-ai-agents-vs-port-ai "Direct link to When to Use AI Agents vs Port AI")
Choose **AI Agents** when you need:
* **Machine-to-machine communication** for automated workflows.
* **Domain-specific expertise** (e.g., incident response, security analysis).
* **Autonomous operations** that run without human intervention.
* **Reusable logic** that can be embedded in multiple systems.
Choose **[Port AI](/port-ai/overview/.md)** when you need:
* **Human interaction** and conversational interfaces.
* **General-purpose queries** across your entire catalog.
* **Ad-hoc exploration** and discovery.
## Agent-Specific Use Cases[](#agent-specific-use-cases "Direct link to Agent-Specific Use Cases")
AI Agents excel at machine-to-machine scenarios that require domain expertise and autonomous operation:
* Kubernetes Healing Agent
* Incident Response Agent
* Security Compliance Agent
This agent automatically monitors and heals Kubernetes infrastructure by detecting failures, analyzing resource constraints, and triggering remediation workflows through monitoring system integrations.
**Tools this agent would have:**
* Kubernetes cluster monitoring and diagnostics.
* Resource utilization analysis tools.
* Pod restart and scaling automation.
* Alert correlation and notification systems.
**Example scenarios:**
* Automatically detects pod failures and restart issues.
* Analyzes resource constraints and suggests scaling actions.
* Integrates with monitoring systems to trigger remediation workflows.
This agent streamlines incident management by monitoring service health, creating automated incident reports, and reducing alert noise through intelligent correlation while keeping stakeholders informed throughout outages.
**Tools this agent would have:**
* Service health monitoring and alerting.
* Incident creation and management tools.
* Multi-system alert correlation engines.
* Stakeholder notification and communication systems.
**Example scenarios:**
* Monitors service health and automatically creates incident reports.
* Correlates alerts across multiple systems to reduce noise.
* Provides automated status updates to stakeholders during outages.
This agent continuously maintains security posture by scanning for vulnerabilities and misconfigurations, creating prioritized remediation tickets, and preventing vulnerable code from reaching production through CI/CD integration.
**Tools this agent would have:**
* Vulnerability scanning and assessment tools.
* Security misconfiguration detection systems.
* Automated ticket creation and prioritization.
* CI/CD pipeline integration and gates.
**Example scenarios:**
* Continuously scans for security vulnerabilities and misconfigurations.
* Automatically creates remediation tickets with context and priority.
* Integrates with CI/CD pipelines to prevent deployment of vulnerable code.
## Getting Started with AI Agents[](#getting-started-with-ai-agents "Direct link to Getting Started with AI Agents")
AI Agents are designed for organizations that need autonomous, domain-specific AI capabilities. Before applying, ensure you have:
* Experience with [Port AI](/port-ai/overview/.md) and its capabilities.
* Understanding of your specific automation and machine-to-machine communication needs.
* Familiarity with [AI Security and Data Controls](/port-ai/security-and-data-controls/.md).
Configure agents in Port for your domains, then connect them to workflows and external systems. See [Build agents](/agent-management/custom-agents/build-an-ai-agent/.md) and [Interact with agents](/agent-management/custom-agents/interact-with-ai-agents/.md).
## Access to the feature[](#access-to-the-feature "Direct link to Access to the feature")
Access to Port AI features (including AI Agents) is controlled through the `_ai_invocation` blueprint's permissions. Users need the **Read**, **Register**, and **Update** permissions on AI invocation entities to access and interact with AI features, including your AI Agents.
After building an agent, make sure to configure the appropriate permissions so your users can actually interact with it.
Permissions required for AI features to work
Creating an AI agent is not enough on its own - users also need the **Read**, **Register**, and **Update** permissions on the `_ai_invocation` blueprint to be able to invoke and interact with it.
[Learn how to configure access to Port AI →](/port-ai/security-and-data-controls/.md#controlling-access-to-port-ai)
[Build and customize](/agent-management/custom-agents/build-an-ai-agent/.md) your AI agents for specific domains:
* Define agent instructions, goals, and expertise areas.
* Set allowed tools and configure autonomy levels for actions.
* Grant access to external [MCP connector](/agent-management/ai-registry/mcp-connectors/.md) tools when the agent needs data or actions outside your Port catalog.
* Test agent behavior and validate responses.
* Integrate agents into workflow automations and external systems.
## Security and Governance[](#security-and-governance "Direct link to Security and Governance")
AI Agents inherit all security and governance controls from [Port AI](/port-ai/overview/.md). They operate within the same secure framework with additional controls for autonomous operation:
* **RBAC compliance**: Agents respect all data access permissions and policies.
* **Audit trail**: All agent interactions are logged as AI invocations for monitoring.
* **Data governance**: Same data handling policies as [Port AI Security and Data Controls](/port-ai/security-and-data-controls/.md).
For comprehensive security information, see [AI Security and Data Controls](/port-ai/security-and-data-controls/.md).
## Implementation Strategy[](#implementation-strategy "Direct link to Implementation Strategy")
Start with focused, high-value use cases that demonstrate clear ROI:
1. **Begin with monitoring and alerting** - Implement agents that enhance existing observability.
2. **Add workflow automation** - Build agents that streamline repetitive processes.
3. **Expand to complex orchestration** - Develop agents that manage multi-system workflows.
4. **Scale across domains** - Deploy specialized agents for different organizational areas.
## Data Model[](#data-model "Direct link to Data Model")
AI Agents use the same data model as [Port AI](/port-ai/overview/.md) with additional agent-specific blueprints:
1. **AI agents** (`_ai_agent`) - The agent configurations and domain specifications that define each agent's capabilities and boundaries. See [Build agents](/agent-management/custom-agents/build-an-ai-agent/.md).
2. **[AI invocations](/port-ai/ai-invocations/.md)** (`_ai_invocations`) - Each agent interaction is recorded as an invocation, providing comprehensive audit trails for autonomous operations. These records include execution context, decisions made, and outcomes for monitoring and debugging agent behavior.
## Relevant guides[](#relevant-guides "Direct link to Relevant guides")
Explore these guides to see AI agents in action and learn how to implement them in your organization:
* [AI-powered incident management](/guides/all/ai-powered-incident-management/.md)
* [Prepare work items with AI](/guides/all/prepare-work-items-with-ai/.md)
* [Setup PR enricher AI agent](/guides/all/setup-pr-enricher-ai-agent/.md)
* [Setup service explorer AI agent](/guides/all/setup-service-explorer-ai-agent/.md)
* [Setup platform request triage AI agent](/guides/all/setup-platform-request-triage-ai-agent/.md)
* [Setup task manager AI agent](/guides/all/setup-task-manager-ai-agent/.md)
* [Setup incident manager AI agent](/guides/all/setup-incident-manager-ai-agent/.md)
* [Remediate vulnerabilities with AI](/guides/all/remediate-vulnerability-with-ai/.md)
## FAQ[](#faq "Direct link to FAQ")
1What's the difference between AI Agents and Port AI Assistant?
2Can AI Agents operate autonomously without human approval?
3How are AI Agents different from general automation tools?
4What security controls apply to autonomous AI Agents?
---
# Claude managed agents

Loading version...
Port's Claude Managed Agents integration surfaces your Anthropic agents, environments, sessions, vaults, and memory stores in your Context Lake. From there, you can trigger agent sessions directly from Port workflows or let platform engineers create new agents through self-service forms.
Supported resources [agent](https://platform.claude.com/docs/en/api/beta/agents)[environment](https://platform.claude.com/docs/en/api/beta/environments)[session](https://platform.claude.com/docs/en/api/beta/sessions)[vault](https://platform.claude.com/docs/en/api/beta/vaults)[memory-store](https://platform.claude.com/docs/en/api/beta/memory_stores)[skill](https://platform.claude.com/docs/en/api/beta/skills)
## Core support
[Live eventsSee supported resources](#webhook-configuration)
For a full end-to-end example that combines both a create-agent and a trigger-agent workflow, see the guide [Assign PR reviewers with a Claude managed agent](/guides/all/assign-pr-reviewers-with-claude/.md).
## Trigger a Claude agent[](#trigger-a-claude-agent "Direct link to Trigger a Claude agent")
Use this workflow to start a new session or continue an existing one, and send a user message to the agent. See the [Claude managed agents integration action](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/claude-managed-agents/.md#complete-workflow-examples) page for the full workflow JSON and node field reference. For a worked example, see the guide [Assign PR reviewers with a Claude managed agent](/guides/all/assign-pr-reviewers-with-claude/.md).
GitHub repository resources
When a session includes a `github_repository` resource and `githubAuthorizationToken` is configured on the integration, the token is automatically injected so the session can clone and push to the repository. This works without the GitHub MCP server. To also open pull requests, the agent needs a vault with GitHub MCP credentials (see the [MCP server setup](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/claude-managed-agents/.md#github-mcp-optional-for-pull-requests) section on the integration action page).
## Create a Claude agent[](#create-a-claude-agent "Direct link to Create a Claude agent")
Use this workflow to let platform engineers or developers create a new Claude managed agent through a self-service form. See the [Claude managed agents integration action](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/claude-managed-agents/.md#complete-workflow-examples) page for the full workflow JSON and node field reference. For a worked example, see the guide [Assign PR reviewers with a Claude managed agent](/guides/all/assign-pr-reviewers-with-claude/.md).
## MCP server setup[](#mcp-server-setup "Direct link to MCP server setup")
Agents can use Port MCP or GitHub MCP during sessions. Both require a Claude credential vault with the appropriate token. For the full credential setup steps, see [MCP server setup](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/claude-managed-agents/.md#mcp-server-setup) on the integration action page.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
* An [Anthropic API key](https://platform.claude.com/docs/en/api/overview#prerequisites).
* Your Port user role is set to `Admin`.
## Setup[](#setup "Direct link to Setup")
Choose one of the installation methods below. If you are not sure which option to use, review the [installation methods overview](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Real-time updates + customizable resync interval
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party API into Port.
The mapping uses the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to transform fields and shape incoming Claude data into Port entities.
### Webhook configuration[](#webhook-configuration "Direct link to Webhook configuration")
To enable real-time updates from Claude to Port, configure a webhook in the [Claude Console](https://platform.claude.com). The webhook endpoint URL follows the format:
```
/integration/webhook
```
Where `` is:
* **Hosted by Port**: the live events base URL shown in the install step above.
* **Self-hosted**: the `liveEvents.baseUrl` you configured during installation.
To set up the webhook:
1. In the [Claude Console](https://platform.claude.com), go to **Manage > Webhooks** and click **Add webhook endpoint**.
2. Paste the endpoint URL.
3. Under **Events to subscribe**, enable:
* `session.status_idled`
* `session.status_terminated`
* `vault.created`
* `vault.archived`
* `vault.deleted`
4. Copy the **signing secret** shown at the end and set it as `webhookSigningSecret` in your integration settings.
Signature verification is optional
Configuring `webhookSigningSecret` is optional. When set, the integration validates the signature on every incoming webhook and rejects requests with an invalid or missing signature. When not set, incoming webhook requests are accepted without signature verification.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
**Default mapping configuration (click to expand)**
```
resources:
- kind: environment
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"claude_environment"'
properties:
description: .description
scope: .scope
environmentType: .config.type
metadata: .metadata
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
- kind: vault
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .display_name
blueprint: '"claude_vault"'
properties:
metadata: .metadata
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
- kind: memory-store
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"claude_memory_store"'
properties:
description: .description
metadata: .metadata
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
- kind: skill
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: '.display_title // .id'
blueprint: '"claude_skill"'
properties:
displayTitle: .display_title
source: .source
latestVersion: .latest_version
createdAt: .created_at
updatedAt: .updated_at
- kind: agent
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"claude_agent"'
properties:
description: .description
model: .model.id
system: .system
version: .version
metadata: .metadata
mcpServers: '[.mcp_servers[]?.name] // []'
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
relations:
skills: '[.skills[]? | select(.type == "custom") | .skill_id]'
delegateAgents: '[.multiagent.agents[]?.id] // []'
- kind: session
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: '.title // .id'
blueprint: '"claude_session"'
properties:
status: .status
inputTokens: .usage.input_tokens
outputTokens: .usage.output_tokens
cacheReadInputTokens: .usage.cache_read_input_tokens
activeSeconds: .stats.active_seconds
durationSeconds: .stats.duration_seconds
agentVersion: .agent.version
githubRepositories: '[.resources[]? | select(.type == "github_repository") | .url]'
metadata: .metadata
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
relations:
agent: .agent.id
environment: .environment_id
memoryStores: '[.resources[]? | select(.type == "memory_store") | .memory_store_id]'
vaults: .vault_ids
```
## Mapping & examples per resource[](#mapping--examples-per-resource "Direct link to Mapping & examples per resource")
To view and test the integration mapping against sample API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources).
agentenvironmentsessionvaultmemory-storeskill
BlueprintJSON
Create in Port
```
{
"identifier": "claude_agent",
"title": "Claude Agent",
"icon": "Claude",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description"
},
"model": {
"type": "string",
"title": "Model"
},
"system": {
"type": "string",
"title": "System prompt"
},
"version": {
"type": "number",
"title": "Version"
},
"metadata": {
"type": "object",
"title": "Metadata"
},
"mcpServers": {
"type": "array",
"title": "MCP servers",
"items": {
"type": "string"
}
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At"
},
"updatedAt": {
"type": "string",
"format": "date-time",
"title": "Updated At"
},
"archivedAt": {
"type": "string",
"format": "date-time",
"title": "Archived At"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"skills": {
"title": "Skills",
"target": "claude_skill",
"required": false,
"many": true
},
"delegateAgents": {
"title": "Delegate agents",
"target": "claude_agent",
"required": false,
"many": true
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: agent
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"claude_agent"'
properties:
description: .description
model: .model.id
system: .system
version: .version
metadata: .metadata
mcpServers: '[.mcp_servers[]?.name] // []'
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
relations:
skills: '[.skills[]? | select(.type == "custom") | .skill_id]'
delegateAgents: '[.multiagent.agents[]?.id] // []'
```
Sample payloadJSON
```
{
"id": "agt_01abc123def456",
"name": "Code Review Agent",
"description": "Reviews pull requests and suggests improvements.",
"model": {
"id": "claude-sonnet-4-5"
},
"system": "You are a senior software engineer. Review code changes for correctness, style, and security.",
"version": 2,
"metadata": {
"team": "platform",
"owner": "alice"
},
"mcp_servers": [
{ "name": "github", "url": "https://mcp.github.com" }
],
"skills": [
{ "type": "custom", "skill_id": "skl_01review111" }
],
"multiagent": {
"type": "coordinator",
"agents": [
{ "id": "agt_01delegate222", "type": "agent", "version": 1 }
]
},
"created_at": "2026-01-10T08:00:00Z",
"updated_at": "2026-06-01T12:00:00Z",
"archived_at": null
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_environment",
"title": "Claude Environment",
"icon": "Claude",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description"
},
"scope": {
"type": "string",
"title": "Scope",
"enum": ["organization", "account"]
},
"environmentType": {
"type": "string",
"title": "Environment type",
"enum": ["cloud", "self_hosted"]
},
"metadata": {
"type": "object",
"title": "Metadata"
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At"
},
"updatedAt": {
"type": "string",
"format": "date-time",
"title": "Updated At"
},
"archivedAt": {
"type": "string",
"format": "date-time",
"title": "Archived At"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
resources:
- kind: environment
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"claude_environment"'
properties:
description: .description
scope: .scope
environmentType: .config.type
metadata: .metadata
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
```
Sample payloadJSON
```
{
"id": "env_01xyz789abc",
"name": "Default Environment",
"description": "Organization-wide default execution environment.",
"scope": "organization",
"config": {
"type": "cloud"
},
"metadata": {
"region": "us-east-1"
},
"created_at": "2026-01-05T10:00:00Z",
"updated_at": "2026-05-20T09:30:00Z",
"archived_at": null
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_session",
"title": "Claude Session",
"icon": "Claude",
"schema": {
"properties": {
"status": {
"type": "string",
"title": "Status",
"enum": ["rescheduling", "running", "idle", "terminated"],
"enumColors": {
"rescheduling": "yellow",
"running": "blue",
"idle": "green",
"terminated": "red"
}
},
"inputTokens": {
"type": "number",
"title": "Input tokens"
},
"outputTokens": {
"type": "number",
"title": "Output tokens"
},
"cacheReadInputTokens": {
"type": "number",
"title": "Cache read input tokens"
},
"activeSeconds": {
"type": "number",
"title": "Active seconds"
},
"durationSeconds": {
"type": "number",
"title": "Duration seconds"
},
"agentVersion": {
"type": "number",
"title": "Agent version"
},
"githubRepositories": {
"type": "array",
"title": "GitHub repositories",
"items": {
"type": "string"
}
},
"metadata": {
"type": "object",
"title": "Metadata"
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At"
},
"updatedAt": {
"type": "string",
"format": "date-time",
"title": "Updated At"
},
"archivedAt": {
"type": "string",
"format": "date-time",
"title": "Archived At"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"agent": {
"title": "Agent",
"target": "claude_agent",
"required": false,
"many": false
},
"environment": {
"title": "Environment",
"target": "claude_environment",
"required": false,
"many": false
},
"memoryStores": {
"title": "Memory stores",
"target": "claude_memory_store",
"required": false,
"many": true
},
"vaults": {
"title": "Vaults",
"target": "claude_vault",
"required": false,
"many": true
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: session
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: '.title // .id'
blueprint: '"claude_session"'
properties:
status: .status
inputTokens: .usage.input_tokens
outputTokens: .usage.output_tokens
cacheReadInputTokens: .usage.cache_read_input_tokens
activeSeconds: .stats.active_seconds
durationSeconds: .stats.duration_seconds
agentVersion: .agent.version
githubRepositories: '[.resources[]? | select(.type == "github_repository") | .url]'
metadata: .metadata
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
relations:
agent: .agent.id
environment: .environment_id
memoryStores: '[.resources[]? | select(.type == "memory_store") | .memory_store_id]'
vaults: .vault_ids
```
Sample payloadJSON
```
{
"id": "ses_01pqr456stu",
"title": "Review PR #142",
"status": "idle",
"agent": {
"id": "agt_01abc123def456",
"version": 2
},
"environment_id": "env_01xyz789abc",
"vault_ids": ["vlt_01aaa111bbb"],
"resources": [
{
"type": "github_repository",
"url": "https://github.com/my-org/my-repo"
},
{
"type": "memory_store",
"memory_store_id": "mem_01ccc222ddd"
}
],
"usage": {
"input_tokens": 4200,
"output_tokens": 1800,
"cache_read_input_tokens": 500
},
"stats": {
"active_seconds": 47.3,
"duration_seconds": 120.0
},
"metadata": {
"pr_number": "142",
"repo": "my-org/my-repo"
},
"created_at": "2026-06-15T14:00:00Z",
"updated_at": "2026-06-15T14:05:30Z",
"archived_at": null
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_vault",
"title": "Claude Vault",
"icon": "Claude",
"schema": {
"properties": {
"metadata": {
"type": "object",
"title": "Metadata"
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At"
},
"updatedAt": {
"type": "string",
"format": "date-time",
"title": "Updated At"
},
"archivedAt": {
"type": "string",
"format": "date-time",
"title": "Archived At"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
resources:
- kind: vault
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .display_name
blueprint: '"claude_vault"'
properties:
metadata: .metadata
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
```
Sample payloadJSON
```
{
"id": "vlt_01aaa111bbb",
"display_name": "Port MCP",
"metadata": {
"purpose": "port-mcp-credentials"
},
"created_at": "2026-02-01T09:00:00Z",
"updated_at": "2026-02-01T09:00:00Z",
"archived_at": null
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_memory_store",
"title": "Claude Memory Store",
"icon": "Claude",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description"
},
"metadata": {
"type": "object",
"title": "Metadata"
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At"
},
"updatedAt": {
"type": "string",
"format": "date-time",
"title": "Updated At"
},
"archivedAt": {
"type": "string",
"format": "date-time",
"title": "Archived At"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
resources:
- kind: memory-store
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"claude_memory_store"'
properties:
description: .description
metadata: .metadata
createdAt: .created_at
updatedAt: .updated_at
archivedAt: .archived_at
```
Sample payloadJSON
```
{
"id": "mem_01ccc222ddd",
"name": "Engineering Context",
"description": "Long-term memory for engineering best practices and team conventions.",
"metadata": {
"team": "platform"
},
"created_at": "2026-03-10T11:00:00Z",
"updated_at": "2026-06-20T08:45:00Z",
"archived_at": null
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_skill",
"title": "Claude Skill",
"icon": "Claude",
"schema": {
"properties": {
"displayTitle": {
"type": "string",
"title": "Display title"
},
"source": {
"type": "string",
"title": "Source",
"enum": ["custom", "anthropic"]
},
"latestVersion": {
"type": "string",
"title": "Latest version"
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At"
},
"updatedAt": {
"type": "string",
"format": "date-time",
"title": "Updated At"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
resources:
- kind: skill
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: '.display_title // .id'
blueprint: '"claude_skill"'
properties:
displayTitle: .display_title
source: .source
latestVersion: .latest_version
createdAt: .created_at
updatedAt: .updated_at
```
Sample payloadJSON
```
{
"id": "skl_01eee333fff",
"display_title": "Port Catalog Reader",
"source": "custom",
"latest_version": "1.2.0",
"created_at": "2026-04-01T10:00:00Z",
"updated_at": "2026-06-10T14:00:00Z"
}
```
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
---
# Cursor cloud agents

Loading version...
Port's Cursor Cloud Agents integration surfaces your Cursor cloud agents and their runs in your Context Lake. From there, you can launch new agents or send follow-up prompts to existing ones directly from Port workflows.
Supported resources [agent](https://cursor.com/docs/cloud-agent/api/endpoints#list-agents)[run](https://cursor.com/docs/cloud-agent/api/endpoints#list-runs)
## Core support
[Live eventsSee supported resources](#webhook-configuration)
## Trigger a Cursor cloud agent[](#trigger-a-cursor-cloud-agent "Direct link to Trigger a Cursor cloud agent")
Use this workflow to send a follow-up prompt to an existing Cursor cloud agent. See the [Cursor Cloud Agents integration action](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/cursor-cloud-agents/.md#trigger-agent) page for the full node field reference.
## Create a Cursor cloud agent[](#create-a-cursor-cloud-agent "Direct link to Create a Cursor cloud agent")
Use this workflow to let platform engineers or developers launch a new Cursor cloud agent through a self-service form. See the [Cursor Cloud Agents integration action](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/cursor-cloud-agents/.md#create-agent) page for the full node field reference.
Create also launches a run
Launching a new Cursor cloud agent always starts a run and billable work immediately. See [Action semantics](/workflows/build-workflows/nodes/action-nodes/integration-actions/ai/cursor-cloud-agents/.md#action-semantics) on the integration action page for details.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
* A [Cursor API key](https://cursor.com/dashboard?tab=integrations) with access to the Cloud Agents API.
* Optionally configure a **webhook signing secret** (`webhookSigningSecret`) to verify incoming Cursor webhooks. The value must be at least 32 characters. Generate a random string with `openssl rand -hex 32` and provide it during installation. When unset, webhook signature verification is skipped.
* Your Port user role is set to `Admin`.
Use a service account key
On the Cursor Enterprise plan, you can use a [service account](https://cursor.com/docs/account/enterprise/service-accounts) API key as the integration's `cursor_api_key` instead of a personal key. Runs are then attributed to the service account rather than an individual, so the integration keeps working as people and roles change. This requires the Cursor GitHub app to be connected at the team level with the target repositories authorized, and usage bills to your team's usage pool. Note that a service account key cannot reuse a user's saved MCP OAuth logins.
## Setup[](#setup "Direct link to Setup")
Choose one of the installation methods below. If you are not sure which option to use, review the [installation methods overview](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Real-time updates + customizable resync interval
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party API into Port.
The mapping uses the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to transform fields and shape incoming Cursor data into Port entities.
### Resource selectors[](#resource-selectors "Direct link to Resource selectors")
In addition to `query`, each resource supports optional **selector** fields in your Port App config:
| Resource | Field | Default | Description |
| -------- | --------------------- | ------- | --------------------------------------------------------------------------------------------------------------------------------- |
| `agent` | `includeArchived` | `false` | Include archived agents from Cursor's List Agents API. |
| `run` | `includeArchived` | `false` | Include archived agents when fanning out to List Runs (Cursor has no separate archived filter on List Runs). |
| `run` | `enrichRunsWithUsage` | `true` | Fetch token usage per agent and merge it into each run during sync. Set to `false` to skip usage API calls. |
| `run` | `oldestRunDate` | unset | ISO 8601 UTC timestamp. Stop paginating runs for each agent once a run older than this cutoff is reached (runs are newest-first). |
Example with a run sync window and usage enrichment disabled:
```
resources:
- kind: agent
selector:
query: 'true'
includeArchived: false
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"cursor_agent"'
- kind: run
selector:
query: 'true'
includeArchived: false
enrichRunsWithUsage: false
oldestRunDate: "2026-01-01T00:00:00Z"
port:
entity:
mappings:
identifier: .id
title: .id
blueprint: '"cursor_run"'
```
### Webhook configuration[](#webhook-configuration "Direct link to Webhook configuration")
Cursor's v0 API attaches a webhook per agent at launch time - there is no account-wide webhook subscription to configure in a Cursor console. On **create\_agent**, set `apiVersion` to `v0` and `reportCompletion` to `true`; the integration then attaches a static callback URL as the agent's webhook when it launches it. **trigger\_agent** follow-ups always use the v1 API but still receive completion callbacks on agents that were v0-created with a webhook.
```
/integration/webhook
```
Where `` is:
* **Hosted by Port**: the live events base URL shown in the install step above.
* **Self-hosted**: the `liveEvents.baseUrl` you configured during installation.
Optionally configure **`webhookSigningSecret`** on the integration (a sensitive installation setting). When set, it must be at least 32 characters. That value is sent to Cursor as the webhook secret and used to validate the `X-Webhook-Signature` header on incoming webhooks. When unset, signature verification is skipped.
Recommended for production
Configure `webhookSigningSecret` so incoming webhooks are authenticated. Without it, any caller that knows your callback URL can post status updates. Use at least 32 characters. `openssl rand -hex 32` produces a 64-character value that meets Cursor's requirement.
Generate a value with for example:
```
openssl rand -hex 32
```
Store it as an organization secret during SaaS installation, or set `OCEAN__INTEGRATION__CONFIG__WEBHOOK_SIGNING_SECRET` for self-hosted deployments.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
**Default mapping configuration (click to expand)**
```
resources:
- kind: agent
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"cursor_agent"'
properties:
status: .status
url: .url
repoUrls: |
[.repos[]?.url // empty]
| map(select(. != null and . != ""))
| map(if startswith("http") then . else "https://" + . end)
| map(select(test("^https?://.+")))
createdAt: .createdAt
updatedAt: .updatedAt
- kind: run
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .id
blueprint: '"cursor_run"'
properties:
status: .status
durationMs: .durationMs
branches: '[.git.branches[]?.branch | select(. != null and . != "")] // []'
prUrls: '[.git.branches[]?.prUrl? | select(. != null)] // []'
inputTokens: .usage.inputTokens
outputTokens: .usage.outputTokens
cacheReadTokens: .usage.cacheReadTokens
cacheWriteTokens: .usage.cacheWriteTokens
totalTokens: .usage.totalTokens
createdAt: .createdAt
updatedAt: .updatedAt
relations:
agent: .agentId
```
## Mapping & examples per resource[](#mapping--examples-per-resource "Direct link to Mapping & examples per resource")
To view and test the integration mapping against sample API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources).
Run token usage
Cursor's List Runs and Get Run endpoints don't return token usage inline. When `enrichRunsWithUsage` is `true` (the default), the integration makes one extra request per agent to Cursor's usage endpoint and merges each run's usage into its payload before mapping, so the `usage` field shown in the sample payload below isn't present in Cursor's own List Runs response. Set `enrichRunsWithUsage` to `false` on the `run` resource to skip those calls.
agentrun
BlueprintJSON
Create in Port
```
{
"identifier": "cursor_agent",
"title": "Cursor Agent",
"icon": "Cursor",
"schema": {
"properties": {
"status": {
"type": "string",
"title": "Status",
"enum": ["ACTIVE", "IDLE", "ARCHIVED"],
"enumColors": {
"ACTIVE": "blue",
"IDLE": "yellow",
"ARCHIVED": "lightGray"
}
},
"url": {
"type": "string",
"title": "Cursor URL",
"format": "url"
},
"repoUrls": {
"type": "array",
"title": "Repository URLs",
"items": {
"type": "string",
"format": "url"
}
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At"
},
"updatedAt": {
"type": "string",
"format": "date-time",
"title": "Updated At"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
resources:
- kind: agent
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"cursor_agent"'
properties:
status: .status
url: .url
repoUrls: |
[.repos[]?.url // empty]
| map(select(. != null and . != ""))
| map(if startswith("http") then . else "https://" + . end)
| map(select(test("^https?://.+")))
createdAt: .createdAt
updatedAt: .updatedAt
```
Sample payloadJSON
```
{
"id": "bc-35b4cb3f-5817-4859-bd44-115a68019c27",
"name": "Mcp server user access",
"status": "ARCHIVED",
"env": {
"type": "cloud"
},
"repos": [
{
"url": "github.com/talsabagport/kubectl-opslevel",
"startingRef": "main"
}
],
"workOnCurrentBranch": false,
"autoCreatePR": false,
"skipReviewerRequest": false,
"url": "https://cursor.com/agents/bc-35b4cb3f-5817-4859-bd44-115a68019c27",
"createdAt": "2026-06-04T10:59:39.801Z",
"updatedAt": "2026-06-09T14:29:11.846Z",
"latestRunId": "run-a097bb31-bde3-45d2-8492-34e5e5ebd01a"
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "cursor_run",
"title": "Cursor Run",
"icon": "Cursor",
"schema": {
"properties": {
"status": {
"type": "string",
"title": "Status",
"enum": ["CREATING", "RUNNING", "FINISHED", "ERROR", "CANCELLED", "EXPIRED"],
"enumColors": {
"CREATING": "lightGray",
"RUNNING": "blue",
"FINISHED": "green",
"ERROR": "red",
"CANCELLED": "yellow",
"EXPIRED": "yellow"
}
},
"durationMs": {
"type": "number",
"title": "Duration (ms)"
},
"branches": {
"type": "array",
"title": "Pushed branches",
"items": {
"type": "string"
}
},
"prUrls": {
"type": "array",
"title": "Pull request URLs",
"items": {
"type": "string",
"format": "url"
}
},
"inputTokens": {
"type": "number",
"title": "Input tokens"
},
"outputTokens": {
"type": "number",
"title": "Output tokens"
},
"cacheReadTokens": {
"type": "number",
"title": "Cache read tokens"
},
"cacheWriteTokens": {
"type": "number",
"title": "Cache write tokens"
},
"totalTokens": {
"type": "number",
"title": "Total tokens"
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At"
},
"updatedAt": {
"type": "string",
"format": "date-time",
"title": "Updated At"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"agent": {
"title": "Agent",
"target": "cursor_agent",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: run
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .id
blueprint: '"cursor_run"'
properties:
status: .status
durationMs: .durationMs
branches: '[.git.branches[]?.branch | select(. != null and . != "")] // []'
prUrls: '[.git.branches[]?.prUrl? | select(. != null)] // []'
inputTokens: .usage.inputTokens
outputTokens: .usage.outputTokens
cacheReadTokens: .usage.cacheReadTokens
cacheWriteTokens: .usage.cacheWriteTokens
totalTokens: .usage.totalTokens
createdAt: .createdAt
updatedAt: .updatedAt
relations:
agent: .agentId
```
Sample payloadJSON
```
{
"id": "run-abc12345-6789-4def-a012-3456789abcde",
"agentId": "bc-abc12345-6789-4def-a012-3456789abcde",
"status": "FINISHED",
"durationMs": 184320,
"git": {
"branches": [
{ "branch": "cursor/fix-flaky-checkout-test", "prUrl": "https://github.com/your-org/your-repo/pull/482" }
]
},
"usage": {
"inputTokens": 6160,
"outputTokens": 1660,
"cacheWriteTokens": 11100,
"cacheReadTokens": 21300,
"totalTokens": 40220
},
"createdAt": "2026-07-10T08:00:00Z",
"updatedAt": "2026-07-10T08:03:04Z"
}
```
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
---
# External agents
External agents are AI agents you build and run outside Port. They fall into two common patterns:
* **Code-first agents** — built with SDKs in your own code, repos, or CI (for example OpenAI Agents SDK, Anthropic Claude Agent SDK, Claude Code, or agents running in GitHub Actions).
* **Cloud-managed agents** — hosted and operated on a vendor control plane (for example AWS Bedrock / AgentCore, Azure AI Foundry, or Cursor Cloud Agents).
Port connects to these agents so you can see which ones exist in your organization, what they can access, and trigger them from your workflows.
## When teams lack a single view of external agents[](#when-teams-lack-a-single-view-of-external-agents "Direct link to When teams lack a single view of external agents")
As adoption grows, agents on external platforms often spread faster than your governance model:
* Teams deploy code-first agents in repos and cloud-managed agents on Bedrock, Foundry, Claude, and other platforms independently.
* Platform and security leads cannot answer basic questions: which agents are running, what data they can reach, or whether two teams built the same agent twice.
* Without inventory, you cannot assign ownership, enforce approval flows, or audit what an agent did after the fact.
## What Port gives you[](#what-port-gives-you "Direct link to What Port gives you")
| Capability | What it means for you |
| --------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Context Lake discovery** | Agents, environments, sessions, skills, and vaults from connected platforms appear as entities in your [Context Lake](/context-lake/overview/.md). |
| **Workflow operations** | Start sessions, send messages, or create agents through [Port workflows](/workflows/overview/.md) instead of switching to each vendor console. |
| **Data access control** | Agents respect [Context Lake permissions](/context-lake/consuming-the-lake/govern-data-access/overview/.md) — access to data is scoped to what their role allows. |
| **Cross-platform registry** | Use an [agent registry](/agent-management/ai-registry/agent-registry/.md) to track code-first and cloud-managed deployments in one view. |
## Get started by platform[](#get-started-by-platform "Direct link to Get started by platform")
| Platform | Get started |
| ------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Claude managed agents** | Surface your Anthropic agents, environments, sessions, vaults, and memory stores in your Context Lake, then trigger sessions or create agents from Port workflows. [Claude managed agents](/agent-management/external-agents/claude-managed-agents/.md). |
| **Cursor cloud agents** | Surface your Cursor cloud agents and their runs in your Context Lake, then launch new agents or send follow-up prompts from Port workflows. [Cursor cloud agents](/agent-management/external-agents/cursor-cloud-agents/.md). |
| **Cloud managed agents** | Maintain a governed registry for agents on AWS Bedrock, Azure AI Foundry, and other cloud platforms without a native Port connector. [Build an AI Agent Registry](/guides/all/build-ai-agent-registry/.md). |
## Related capabilities[](#related-capabilities "Direct link to Related capabilities")
* [AI registry](/agent-management/ai-registry/mcp-registry/.md) — govern skills, prompts, and MCP servers that agents use when they connect to Port.
* [Port MCP server](/agent-management/port-mcp-server/overview/.md) — connect IDEs and external tools to your Context Lake.
---
# Agent management
Agent management is about governing every AI agent operating in your organization - what data they can access, what actions they can take, and who can use them. That includes **code-first agents** you build with SDKs in your own repos or CI (for example OpenAI Agents SDK, Anthropic Claude Agent SDK, or Claude Code), **cloud-managed agents** hosted on vendor control planes (for example AWS Bedrock / AgentCore, Azure AI Foundry, or Cursor Cloud Agents), and **Port-native agents** configured inside Port.
## What roles do AI agents play in Port?[](#what-roles-do-ai-agents-play-in-port "Direct link to What roles do AI agents play in Port?")
Agents interact with your software factory in three complementary ways. Understanding these patterns helps you decide when to let an existing agent consume Port, when the platform should trigger agents on its own, and when to provision a new agent.
### AI agents as platform consumers[](#ai-agents-as-platform-consumers "Direct link to AI agents as platform consumers")
The most intuitive role is the agent as a user of the platform. For example, an engineer asks a coding agent to add an endpoint to a payments service. Before writing code, the agent pulls the service's owner, dependencies, and standards from Port, then spins up a preview environment and runs tests through self-service workflows.
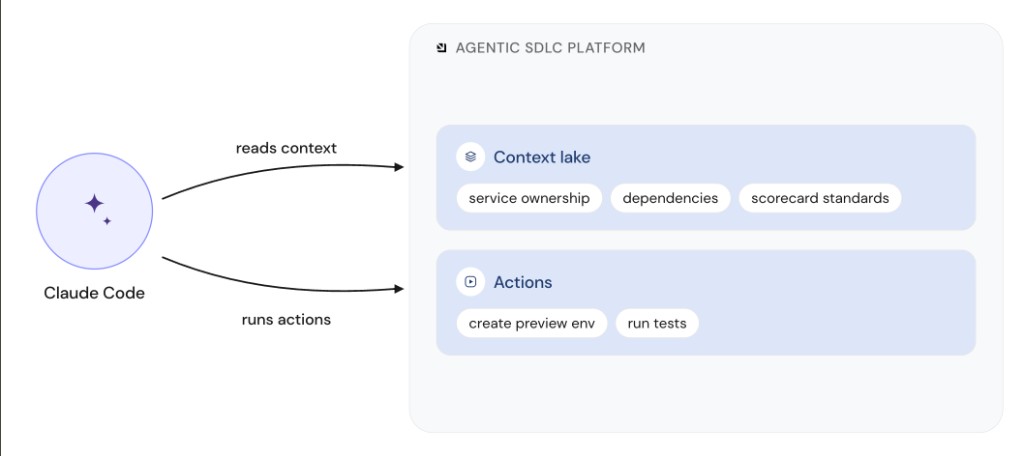
Here the agent works side by side with the developer. It reads from Context Lake and runs governed actions, the same way a human would use the platform. Use this pattern when developers already work in tools like Claude Code, Cursor, or GitHub Copilot. The [Port MCP server](/agent-management/port-mcp-server/overview/.md) exposes catalog context and workflows so those agents operate with the same source of truth and guardrails as humans.
### AI agents as internal platform components[](#ai-agents-as-internal-platform-components "Direct link to AI agents as internal platform components")
The next level treats the agent as part of the platform engine, not only as a user of it. For example, when a vulnerability is opened, Port can take a remediation agent from the [agent registry](/agent-management/ai-registry/agent-registry/.md) (or invoke an agent for that case without using a registered one) and run it inside a workflow to remediate across affected services.
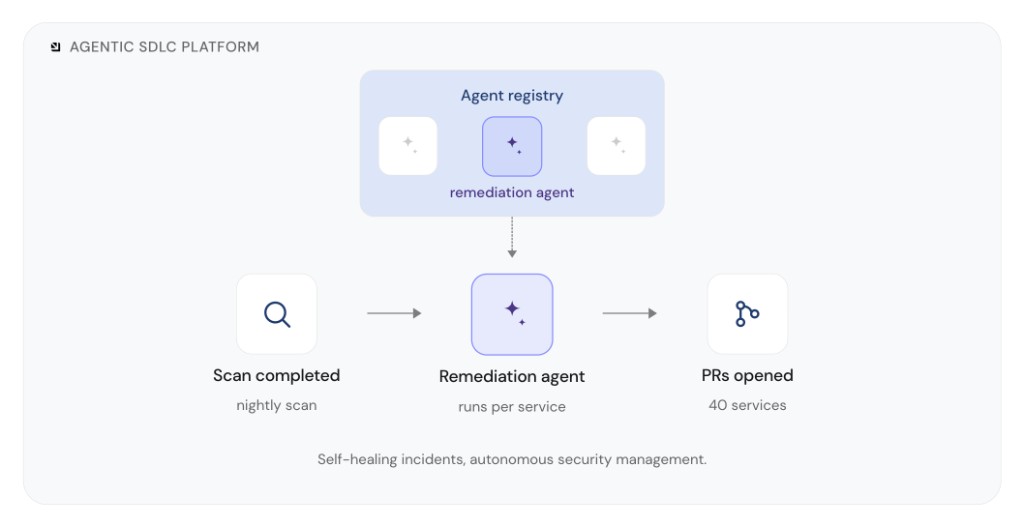
Nobody has to request an agent for each case. The platform triggers the agent from an event, and owning teams wake up to outcomes such as open PRs. Use this pattern for autonomous work such as security remediation, self-healing incidents, or other event-driven loops where the agent is a pillar of the platform itself.
### AI as reusable building blocks[](#ai-as-reusable-building-blocks "Direct link to AI as reusable building blocks")
The third role is AI as a reusable building block. For example, an engineer needs an agent. They pick the model, tools, network landscape, and use case, and the platform hands back an agent that already sits on the golden path, with identity, approved tool access, and the right scope.
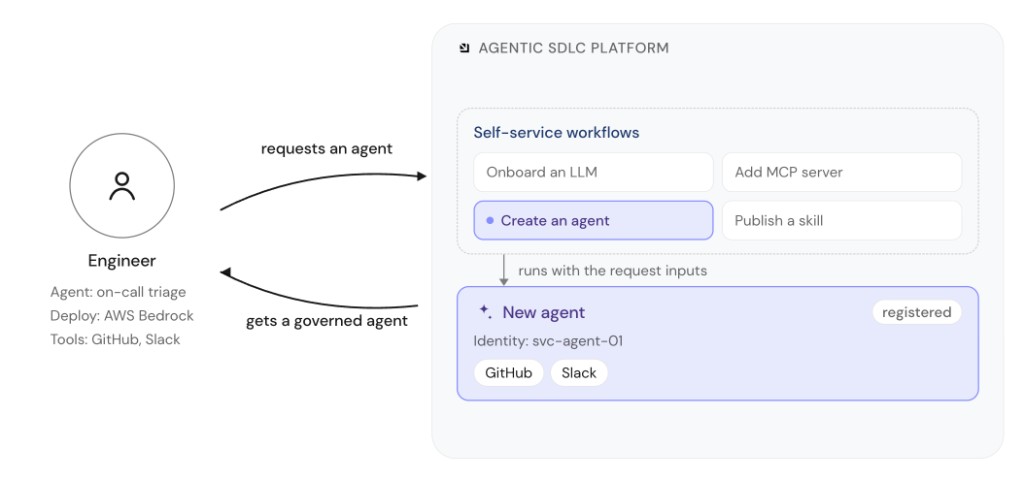
"Agent" here also covers related AI artifacts such as LLMs, MCP servers, and skills. Teams often struggle to enforce the right tools and access, apply guardrails the way they would for any other service or resource, and hand over an agent once it is built. Self-service workflows such as **Create an agent**, **Onboard an LLM**, **Add MCP server**, and **Publish a skill** turn that lifecycle into a governed process for creating, registering, and sharing AI artifacts across the organization.
## Govern agents, skills, and MCP at scale[](#govern-agents-skills-and-mcp-at-scale "Direct link to Govern agents, skills, and MCP at scale")
As engineering teams adopt AI agents, the number of agents, skills, prompts, and MCP servers grows quickly. Without a shared layer to discover and govern them, each team operates in isolation, and platform teams lose the ability to enforce standards or answer basic operational questions.
Without shared governance, agents, skills, prompts, and MCP servers end up scattered across teams, making it hard to see what exists, control access, or avoid duplication. Each team maintains separate configurations and there is no single place to track ownership, security, or approved tools.
### How Port helps[](#how-port-helps "Direct link to How Port helps")
Port gives you one place to discover and govern agents, skills, prompts, and MCP across your organization:
| You need to… | Port capability |
| -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Route and govern model traffic at scale, then connect gateway data to teams and services | [AI Gateway](/agent-management/ai-gateway/.md) |
| Discover agents on external platforms, code-first (OpenAI Agents SDK, Claude Code, GitHub Actions) or cloud-managed (Bedrock / AgentCore, Azure AI Foundry, Cursor Cloud Agents) | [External agents](/agent-management/external-agents/overview/.md) |
| Maintain a registry of external agents with ownership and status in Context Lake | [Agent registry](/agent-management/ai-registry/agent-registry/.md) |
| Govern which skills, prompts, and MCP servers teams may use | [AI registry](/agent-management/ai-registry/skills/overview/.md) (skills, [prompts](/agent-management/ai-registry/prompts/.md), [MCP registry](/agent-management/ai-registry/mcp-registry/.md)) |
| Build and run agents natively in Port | [Port custom agents](/agent-management/custom-agents/overview/.md) |
| Scope what agents can read from Context Lake | [Context Lake data access](/context-lake/consuming-the-lake/govern-data-access/overview/.md) |
| Connect IDEs and external tools to your Context Lake | [Port MCP server](/agent-management/port-mcp-server/overview/.md) |
Port brings agents, skills, prompts, and MCP under one governance layer so teams can move fast without losing control.
## What's in this section[](#whats-in-this-section "Direct link to What's in this section")
### AI Gateway[](#ai-gateway "Direct link to AI Gateway")
AI gateways route every model call through a single control point for routing, budgets, guardrails, and observability. Port sits on top of that layer, connecting gateway data to your software catalog, self-service workflows, and scorecards so you can govern agents, keys, and tools at organizational scale.
**[Learn about AI gateways →](/agent-management/ai-gateway/.md)**
### External agents[](#external-agents "Direct link to External agents")
Connect and govern agents hosted outside Port, whether you build them with SDKs in code or run them on cloud-managed platforms. Discover agents in Context Lake, trigger sessions from workflows, and track deployments through an agent registry.
**[Explore external agents →](/agent-management/external-agents/overview/.md)**
### Port MCP server[](#port-mcp-server "Direct link to Port MCP server")
Connect IDEs, AI tools, and agents to Port using natural language. The MCP server exposes your Context Lake and workflows as callable tools, so agents like Claude, Cursor, and GitHub Copilot can query the catalog and take governed actions from wherever developers already work.
**[Learn more about the Port MCP server →](/agent-management/port-mcp-server/overview/.md)**
### Port custom agents[](#port-custom-agents "Direct link to Port custom agents")
Customize and orchestrate complicated workflows inside Port. Build intelligent agents that can be used as part of automations and engineering workflows.
**Use Port custom agents to:**
* Automate incident response workflows
* Create intelligent PR review processes
* Build custom task management assistants
* Generate automated deployment reports
* Orchestrate multi-step engineering processes
**[Explore Port custom agents →](/agent-management/custom-agents/overview/.md)**
### AI registry[](#ai-registry "Direct link to AI registry")
Connect IDEs and agents to Port, publish skills and prompts, and govern which MCP servers teams may use. This part of Agent management groups the [Port MCP server](/agent-management/port-mcp-server/overview/.md), [MCP registry](/agent-management/ai-registry/mcp-registry/.md), [Skills](/agent-management/ai-registry/skills/overview/.md), [Skills usage analytics](/agent-management/ai-registry/skills/skills-usage-analytics/.md), and [Prompts](/agent-management/ai-registry/prompts/.md) documentation.
**Use the AI registry to:**
* Install and secure the Port MCP server for builders and developers.
* Track approved MCP servers and installation guidance in Context Lake.
* Define skills and prompt blueprints that Port AI and MCP clients can load at runtime.
* Measure skill adoption from Cursor and Claude integrations.
**[Set up the Port MCP server →](/agent-management/port-mcp-server/installation/.md)**
## FAQ[](#faq "Direct link to FAQ")
1What does agent management cover in Port?
2What roles can AI agents play in Port?
3How do external AI agents connect to Port?
4Can an AI agent take actions without human approval?
5What is the AI registry?
---
# Available tools
The Port MCP Server exposes different sets of tools based on your role and use case. The tools you see will depend on your permissions in Port.
* Developer
* Builder
**Developers** are typically users who consume and interact with the developer portal - querying services, running actions, and analyzing data. These tools help you get information and execute approved workflows.
Actions & workflows9 tools
`get_action_permissions`
Get permissions/approval config for actions.
[API Reference](/api-reference/get-an-actions-permissions)
`get_workflow_run`
Get the status and details of a workflow run by its identifier. Use after trigger\_run to poll for completion, or to inspect any previously-triggered run. Returns status, result, per-node execution details, and timestamps.
[API Reference](/api-reference/get-a-workflow-run-by-identifier)
`list_actions`
List actions and automations in your organization. Without identifiers, returns a summary list. With identifiers, returns full action details including complete input schemas. Self-service workflow triggers are a separate concept - use `list_self_service_triggers` to discover those.
[API Reference](/api-reference/get-actions-automations)
`list_self_service_triggers`
List self-service workflow triggers the caller can execute. Returns workflow metadata, the trigger nodeIdentifier, and the input schema for each trigger. Use before `trigger_run` to discover available operations and required inputs.
[API Reference](/api-reference/list-self-service-workflow-triggers)
`list_workflows`
List workflows in your organization. Without identifiers, returns a summary list. With identifiers, returns full workflow details including trigger configuration and node definitions.
[API Reference](/api-reference/get-workflows)
`run_action`Dynamic
Execute a self-service action or automation by identifier. Prefer `trigger_run` when you want one tool that covers both workflow runs and action runs.
[API Reference](/api-reference/execute-a-self-service-action)
`submit_input_node_response`
Submit a response to a workflow input node that is waiting for input, on behalf of the current user. Get the workflow run and node run identifiers from the user, call `get_run` and read the input node run's `output.evaluatedConfig` for the description, form, and buttons, then submit the chosen button and inputs. Only responders on the node can submit.
[API Reference](/api-reference/submit-a-response-to-an-input-node-run)
`track_action_run`
Track action execution status.
[API Reference](/api-reference/get-an-action-runs-details)
`trigger_run`
Trigger a self-service workflow or action run. For workflows, pass `type: "WORKFLOW"`, the workflow identifier, the `nodeIdentifier` from `list_self_service_triggers`, and inputs matching the trigger schema. For actions, pass `type: "ACTION"` and the action identifier. Returns the run identifier and status so you can track progress.
[API Reference](/api-reference/trigger-a-workflow-run)
Audit logs1 tool
`search_audit_logs`
Search entity audit logs using structured filters for status, operation, trigger origin, date, errors, and related resources. Supports limit and offset pagination, optional response fields, and filtering entities or blueprints by identifier.
[API Reference](/api-reference/search-entity-audit-logs)
Data model3 tools
`list_blueprints`
List blueprints in your organization. Without identifiers, returns a summary list. With identifiers, returns full blueprint details including property definitions, schemas, and enum values.
[API Reference](/api-reference/get-all-blueprints)
`list_entities`
Query entities from a blueprint with filtering, sorting, pagination, and `include`. Supports identifiers, `groupBy` for value distribution, and `countOnly` for a total count.
[API Reference](/api-reference/search-a-blueprints-entities)
▶Behavior tips (
7
)
`simulate_blueprint_permissions`
Simulate blueprint entity permissions for a user. Use list mode to return entities the user can access for a blueprint; use detail mode with entityIdentifier to check permissions for a specific entity.
[API Reference](/api-reference/simulate-permissions-for-a-user)
General3 tools
`describe_user_details`
Describe the user, which organization he is connected to and what teams he is a member of and more information regarding the user. Can be useful for questions that relate to the user or when looking up for related entities to the user
[API Reference](/api-reference/get-organization-details)
`load_skill`
Load specialized guidance for a domain-specific task. Skills provide step-by-step instructions for common workflows like troubleshooting integrations. Load a skill before starting a specialized task to ensure consistent, thorough handling.
[Documentation](/agent-management/ai-registry/skills/overview/.md)
`search_port_knowledge_sources`
Search the official Port documentation and return the most relevant sections from it for a user query. Each returned section includes the url and its actual content in markdown. Use this tool for all queries that require Port knowledge.
Pages & dashboards3 tools
`get_page`Beta
Get a specific page by identifier. Returns full page details including widgets configuration. For entity pages (type "entity"), returns a tabs array with each tab's title, widgets, layout, and reserved flag.
[API Reference](/api-reference/get-a-page)
`get_sidebar`Beta
Get the software catalog sidebar structure including all pages and folders.
[API Reference](/api-reference/pages)
`load_widget_schema`Beta
Get the JSON schema for a specific dashboard widget type. Call this before upsert\_dashboard\_page, upsert\_widget, or update\_entity\_page to understand the required structure for the widget you want to create.
Scorecards1 tool
`list_scorecards`
List scorecards in your organization. Without identifiers, returns a summary list. With identifiers, returns full scorecard details including complete rule configurations.
[API Reference](/api-reference/get-all-scorecards)
**Builders** are platform engineers or admins who design and configure the developer portal - creating blueprints, setting up scorecards, and managing the overall structure. These tools help you build and maintain the portal.
Builders have access to all the tools available to Developers, plus additional management tools for creating and configuring the portal.
Actions & workflows14 tools
`delete_action`
Delete action by identifier.
[API Reference](/api-reference/delete-an-action-automation)
`delete_workflow`
Delete workflow by identifier.
[API Reference](/api-reference/delete-a-workflow)
`get_action_permissions`
Get permissions/approval config for actions.
[API Reference](/api-reference/get-an-actions-permissions)
`get_workflow_run`
Get the status and details of a workflow run by its identifier. Use after trigger\_run to poll for completion, or to inspect any previously-triggered run. Returns status, result, per-node execution details, and timestamps.
[API Reference](/api-reference/get-a-workflow-run-by-identifier)
`list_actions`
List actions and automations in your organization. Without identifiers, returns a summary list. With identifiers, returns full action details including complete input schemas. Self-service workflow triggers are a separate concept - use `list_self_service_triggers` to discover those.
[API Reference](/api-reference/get-actions-automations)
`list_self_service_triggers`
List self-service workflow triggers the caller can execute. Returns workflow metadata, the trigger nodeIdentifier, and the input schema for each trigger. Use before `trigger_run` to discover available operations and required inputs.
[API Reference](/api-reference/list-self-service-workflow-triggers)
`list_workflows`
List workflows in your organization. Without identifiers, returns a summary list. With identifiers, returns full workflow details including trigger configuration and node definitions.
[API Reference](/api-reference/get-workflows)
`run_action`Dynamic
Execute a self-service action or automation by identifier. Prefer `trigger_run` when you want one tool that covers both workflow runs and action runs.
[API Reference](/api-reference/execute-a-self-service-action)
`submit_input_node_response`
Submit a response to a workflow input node that is waiting for input, on behalf of the current user. Get the workflow run and node run identifiers from the user, call `get_run` and read the input node run's `output.evaluatedConfig` for the description, form, and buttons, then submit the chosen button and inputs. Only responders on the node can submit.
[API Reference](/api-reference/submit-a-response-to-an-input-node-run)
`track_action_run`
Track action execution status.
[API Reference](/api-reference/get-an-action-runs-details)
`trigger_run`
Trigger a self-service workflow or action run. For workflows, pass `type: "WORKFLOW"`, the workflow identifier, the `nodeIdentifier` from `list_self_service_triggers`, and inputs matching the trigger schema. For actions, pass `type: "ACTION"` and the action identifier. Returns the run identifier and status so you can track progress.
[API Reference](/api-reference/trigger-a-workflow-run)
`update_action_permissions`
Update action permissions configuration.
[API Reference](/api-reference/update-an-actions-permissions)
`upsert_action`
Create or update an action. Updates if the action exists, creates if it does not. API Reference links to create; updates use `change-an-action-automation`.
[API Reference](/api-reference/create-an-action-automation)
`upsert_workflow`
Create or update a workflow. Updates if the workflow exists, creates if it does not.
[API Reference](/api-reference/create-a-workflow)
Audit logs1 tool
`search_audit_logs`
Search entity audit logs using structured filters for status, operation, trigger origin, date, errors, and related resources. Supports limit and offset pagination, optional response fields, and filtering entities or blueprints by identifier.
[API Reference](/api-reference/search-entity-audit-logs)
Data model8 tools
`delete_blueprint`
Delete blueprint and all its entities.
[API Reference](/api-reference/delete-a-blueprint)
`delete_entity`
Delete entity with optional dependents.
[API Reference](/api-reference/delete-an-entity)
`list_blueprints`
List blueprints in your organization. Without identifiers, returns a summary list. With identifiers, returns full blueprint details including property definitions, schemas, and enum values.
[API Reference](/api-reference/get-all-blueprints)
`list_entities`
Query entities from a blueprint with filtering, sorting, pagination, and `include`. Supports identifiers, `groupBy` for value distribution, and `countOnly` for a total count.
[API Reference](/api-reference/search-a-blueprints-entities)
▶Behavior tips (
7
)
`simulate_blueprint_permissions`
Simulate blueprint entity permissions for a user. Use list mode to return entities the user can access for a blueprint; use detail mode with entityIdentifier to check permissions for a specific entity.
[API Reference](/api-reference/simulate-permissions-for-a-user)
`trigger_auto_discovery`
Start auto-discovery to suggest or find entities for a blueprint. Call list\_blueprints first to obtain the exact blueprint identifier before invoking this tool. Supports optional user context and excluded blueprints as supported by the tool.
[API Reference](/api-reference/create-an-auto-discovery-invocation)
`upsert_blueprint`
Create or update a blueprint. Updates if the blueprint exists, creates if it does not.
[API Reference](/api-reference/create-a-blueprint)
`upsert_entity`
Create or update an entity. Updates if the entity exists, creates if it does not. Uses merge by default to preserve existing fields.
[API Reference](/api-reference/create-an-entity)
External interfaces3 tools
`list_external_interface_apps`
List external interface apps registered for your organization (public clients using PKCE). Requires organization admin.
[Documentation](/platform-administration/sso-authentication/manage-your-oauth-apps/.md)
`revoke_external_interface_app`
Revoke (permanently delete) an external interface app registration. Any UI built against it will immediately lose the ability to authenticate. Requires organization admin permissions.
[Documentation](/platform-administration/sso-authentication/manage-your-oauth-apps/.md)
`upsert_external_interface_app`
Create or update an external interface app (public/PKCE OAuth client, no client secret) for your organization, so you can build a custom UI against Port's API. Omit appId to create; pass appId to update. Requires organization admin permissions.
[Documentation](/platform-administration/sso-authentication/manage-your-oauth-apps/.md)
▶Behavior tips (
2
)
General3 tools
`describe_user_details`
Describe the user, which organization he is connected to and what teams he is a member of and more information regarding the user. Can be useful for questions that relate to the user or when looking up for related entities to the user
[API Reference](/api-reference/get-organization-details)
`load_skill`
Load specialized guidance for a domain-specific task. Skills provide step-by-step instructions for common workflows like troubleshooting integrations. Load a skill before starting a specialized task to ensure consistent, thorough handling.
[Documentation](/agent-management/ai-registry/skills/overview/.md)
`search_port_knowledge_sources`
Search the official Port documentation and return the most relevant sections from it for a user query. Each returned section includes the url and its actual content in markdown. Use this tool for all queries that require Port knowledge.
Integrations5 tools
`get_integration_event_logs`
Fetch event logs for an integration. Defaults to ERROR-level logs. Supports filters for levels, event\_id, etl\_phases, and kinds. Paginate with timestamp and log\_id from the previous response.
[API Reference](/api-reference/get-an-integrations-event-logs)
`get_integration_kinds_with_examples`
Fetch all kinds (data types) that an integration ingests, along with raw data examples for each kind. For example, a GitHub integration might have kinds like "pull\_request", "issue", and "repo".
`get_integration_sync_metrics`
Fetch sync metrics for an integration. Returns detailed metrics including status, number of items handled in each phase of the integration pipeline (extract, transform, load, delete), and per-kind statistics.
[API Reference](/api-reference/get-an-integrations-metrics-and-sync-status)
`list_integrations`
List integrations in your organization. Without identifiers, returns a summary list. With identifiers, returns full integration details including complete config with mapping configuration. Empty result is authoritative: no integrations are installed. Do not infer prior installation from existing blueprints.
[API Reference](/api-reference/get-all-integrations)
`test_integration_mapping`
Test an integration mapping against raw data examples. Validates the mapping, checks for errors, and returns the mapped results or error messages.
Pages & dashboards15 tools
`delete_sidebar_folder`Beta
Delete a folder from the sidebar. Pages and nested folders inside it are also deleted.
[API Reference](/api-reference/pages)
`delete_widget`Beta
Delete a widget from a dashboard, home, or entity page by its ID.
[API Reference](/api-reference/delete-a-widget)
`duplicate_page`Beta
Duplicate a dashboard page. Creates an identical copy with the same widgets, layout, page filters, icon, and description. Only dashboard pages are supported; entity pages cannot be duplicated.
[API Reference](/api-reference/duplicate-a-page)
`get_page`Beta
Get a specific page by identifier. Returns full page details including widgets configuration. For entity pages (type "entity"), returns a tabs array with each tab's title, widgets, layout, and reserved flag.
[API Reference](/api-reference/get-a-page)
`get_sidebar`Beta
Get the software catalog sidebar structure including all pages and folders.
[API Reference](/api-reference/pages)
`load_widget_schema`Beta
Get the JSON schema for a specific dashboard widget type. Call this before upsert\_dashboard\_page, upsert\_widget, or update\_entity\_page to understand the required structure for the widget you want to create.
`move_page`Beta
Move a page to a different location in the sidebar. Use "parent" to place the page inside a folder (or null for sidebar root) and "after" to control its position within that level.
[API Reference](/api-reference/patch-a-page)
`update_entity_page`Beta
Update an existing entity page's tabs, tab order, tab names, page metadata, or page filters. Entity pages are auto-generated per blueprint and cannot be created manually. Use upsert\_widget to update a single widget on a tab.
[API Reference](/api-reference/pages)
▶Behavior tips (
4
)
`upsert_dashboard_page`Beta
Create or update a dashboard or home page with widgets, layout, and optional page filters. Do not use on entity pages; use update\_entity\_page or upsert\_widget instead. The dashboard-widget container is auto-generated. Use load\_widget\_schema to get the schema for a specific widget type before building widgets.
[API Reference](/api-reference/pages)
▶Behavior tips (
1
)
`upsert_sidebar_folder`Beta
Create or update a folder in the sidebar. Folders can be nested by specifying a parent folder identifier. Use "after" to control position.
[API Reference](/api-reference/pages)
`upsert_widget`Beta
Create or update a single widget on a dashboard, home, or entity page. Preferred for updating one widget instead of update\_entity\_page. For entity pages, tabTitle is required — call get\_page first to see available tabs. Call load\_widget\_schema first to get the full schema for the target widget type.
[API Reference](/api-reference/create-a-widget)
`list_plugins`
List plugins uploaded to your organization (Port admin permissions required). Without identifiers, returns a summary list. With identifiers, returns full plugin details including metadata and custom parameters used by custom widgets.
[API Reference](/api-reference/list-all-plugins-for-the-organization)
`list_available_library_plugins`
List plugins in the Port Plugins library - the curated catalog from the public port-plugins repository. Each entry includes readmeContent with catalog prerequisites. Call load\_skill("list-available-library-plugins") to browse, or load\_skill("install-plugin-library") before install flows. Not the same as list\_plugins (already installed in your org).
[Documentation](/interface-builder/port-interface/plugins/.md#install-from-the-plugins-library)
`install_library_plugin`
Install a plugin from the Port Plugins library into your organization. Load install-plugin-library via load\_skill first, read readmeContent from list\_available\_library\_plugins, verify catalog prerequisites with list\_blueprints, confirm missing properties with the user, then upsert\_blueprint if needed before calling this tool. Returns alreadyInstalled: true if the plugin is already in your org. Do not use install\_integrations for library plugins.
[API Reference](/api-reference/install-a-plugin-from-the-port-public-registry) [Documentation](/interface-builder/port-interface/plugins/.md#install-from-the-plugins-library)
▶Behavior tips (
1
)
`upsert_plugin`
Create or update a plugin for custom widgets (Port admin permissions required). Updates if the plugin identifier exists, creates if it does not. Use after you have a built plugin artifact and metadata (for example identifier, title, optional params). Not for Plugins library widgets - use install\_library\_plugin for those.
[Documentation](/interface-builder/port-interface/plugins/.md#upload-custom-plugins)
Scorecards3 tools
`delete_scorecard`
Delete scorecard by identifiers.
[API Reference](/api-reference/delete-a-scorecard)
`list_scorecards`
List scorecards in your organization. Without identifiers, returns a summary list. With identifiers, returns full scorecard details including complete rule configurations.
[API Reference](/api-reference/get-all-scorecards)
`upsert_scorecard`
Create or update a scorecard. Updates if the scorecard exists, creates if it does not.
[API Reference](/api-reference/create-a-scorecard)
Client Support
Tool support in external MCP clients depends on whether the client implements the tools feature according to the [MCP specification](https://modelcontextprotocol.info/docs/clients/). Most MCP clients support tools. Check the [MCP client documentation](https://modelcontextprotocol.info/docs/clients/) to see which features your client supports.
## Select which tools to use[](#select-which-tools-to-use "Direct link to Select which tools to use")
By default, when you open a chat with Port MCP, all available tools (based on your permissions) are loaded and ready to use. However, you can customize which tools are available if you want to focus on specific workflows.
For example, if you only want to query data from Port without building or modifying anything, you can limit the tools to just the read-only ones. This helps reduce complexity and ensures you don't accidentally make changes.
### Using headers to control tool availability[](#using-headers-to-control-tool-availability "Direct link to Using headers to control tool availability")
You can use headers when configuring your MCP server connection to control which tools are available:
**Read-only mode** - The `x-read-only-mode` header controls whether write tools are available. Set it to `1` to restrict the MCP server to only expose read-only tools, completely hiding write tools from the available tools list. Set it to `0` (default) to allow all tools based on your permissions.
**Control actions** - The `x-allowed-actions-to-run` header controls which actions are available through the `run_action` tool. This header accepts a comma-separated list of action identifiers. Only the specified actions will be available. If the header is not specified, all actions you have permission to run will be available. If set to an empty string, no actions will be allowed to run.
Examples:
* `x-allowed-actions-to-run: "create_github_issue,create_incident"` - Allows only the specified GitHub and incident actions.
* `x-allowed-actions-to-run: "create_service,deploy_to_production"` - Allows only the specified deployment actions.
* `x-allowed-actions-to-run: ""` - No actions will be allowed to run.
See the [token-based authentication guide](/agent-management/port-mcp-server/token-based-authentication/.md) for examples of how to configure these headers.
### Using client UI to select tools[](#using-client-ui-to-select-tools "Direct link to Using client UI to select tools")
* Cursor
* VSCode
* Claude
In Cursor, you can customize which tools are available through the UI after connecting to Port MCP. Once connected, you can select specific tools as shown below.
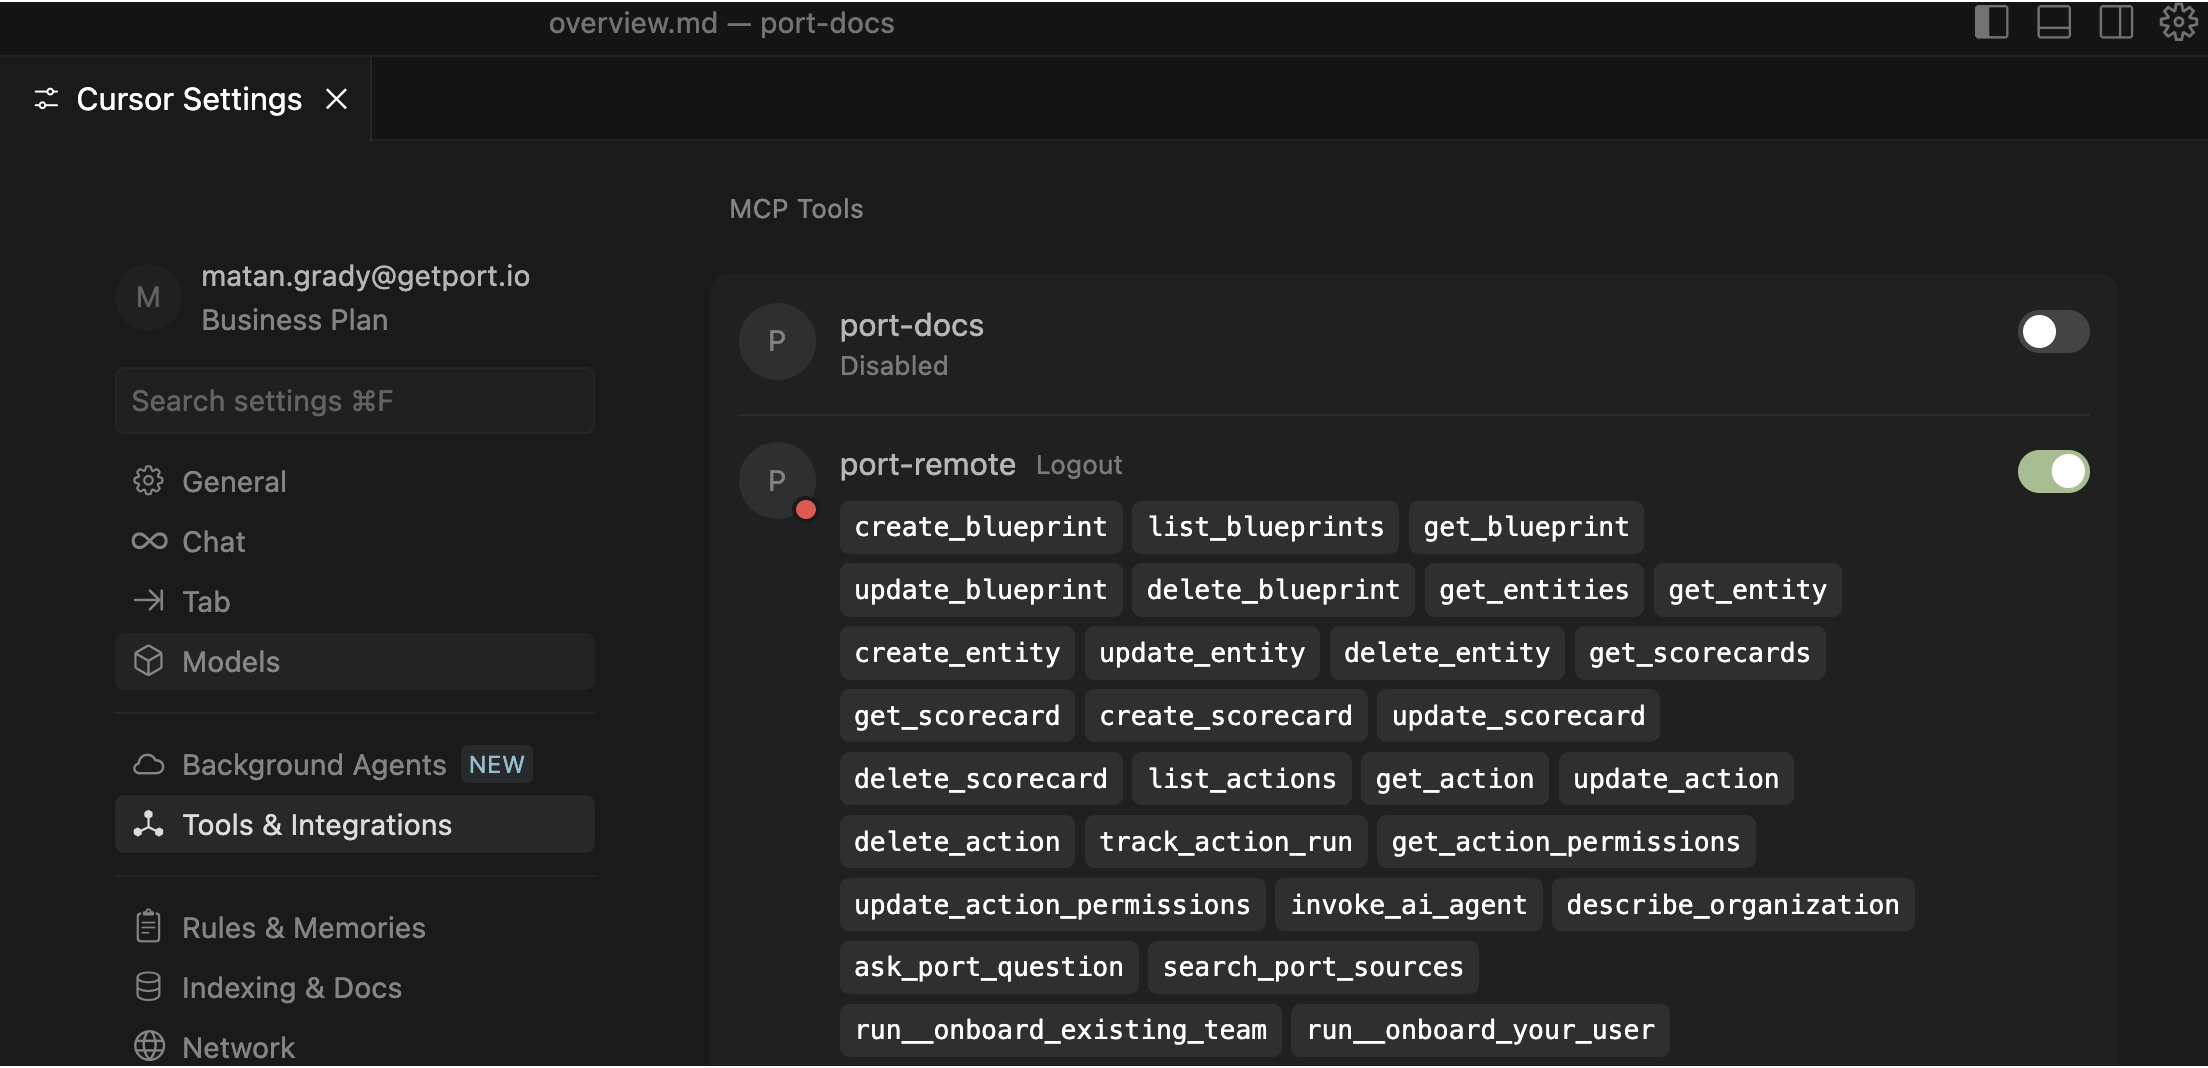
In VSCode, you can choose the tools through the UI after connecting to Port MCP.
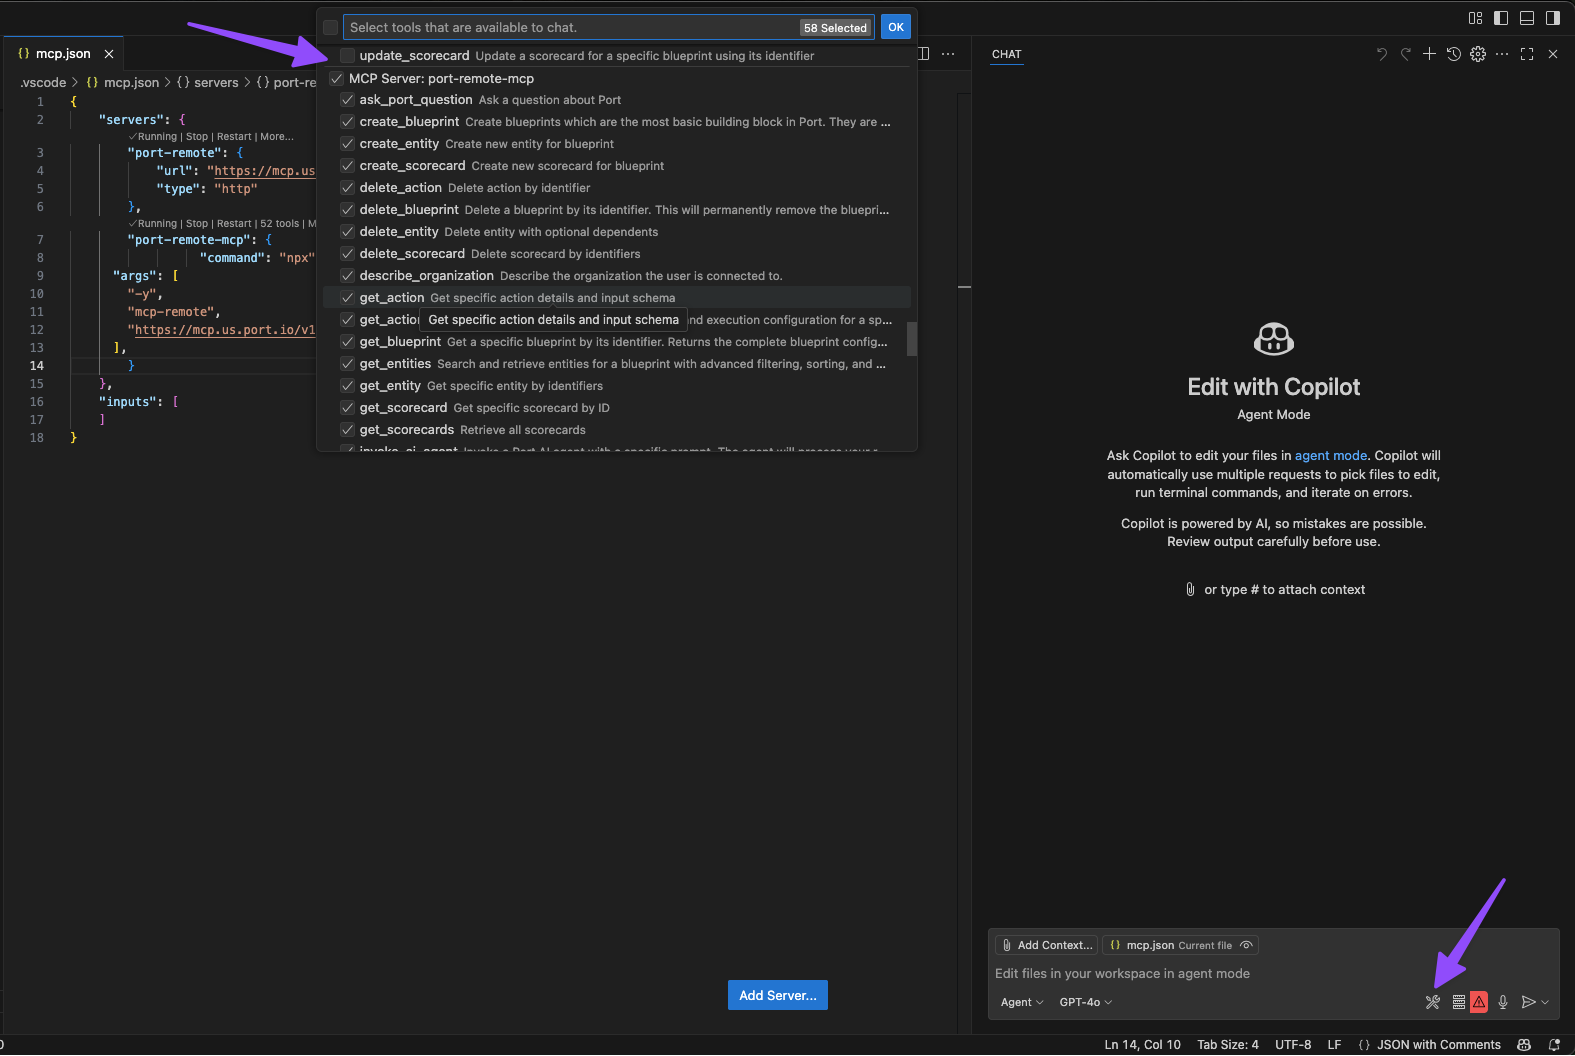
When creating a custom connector in Claude, you can specify exactly which tools to expose instead of enabling everything.
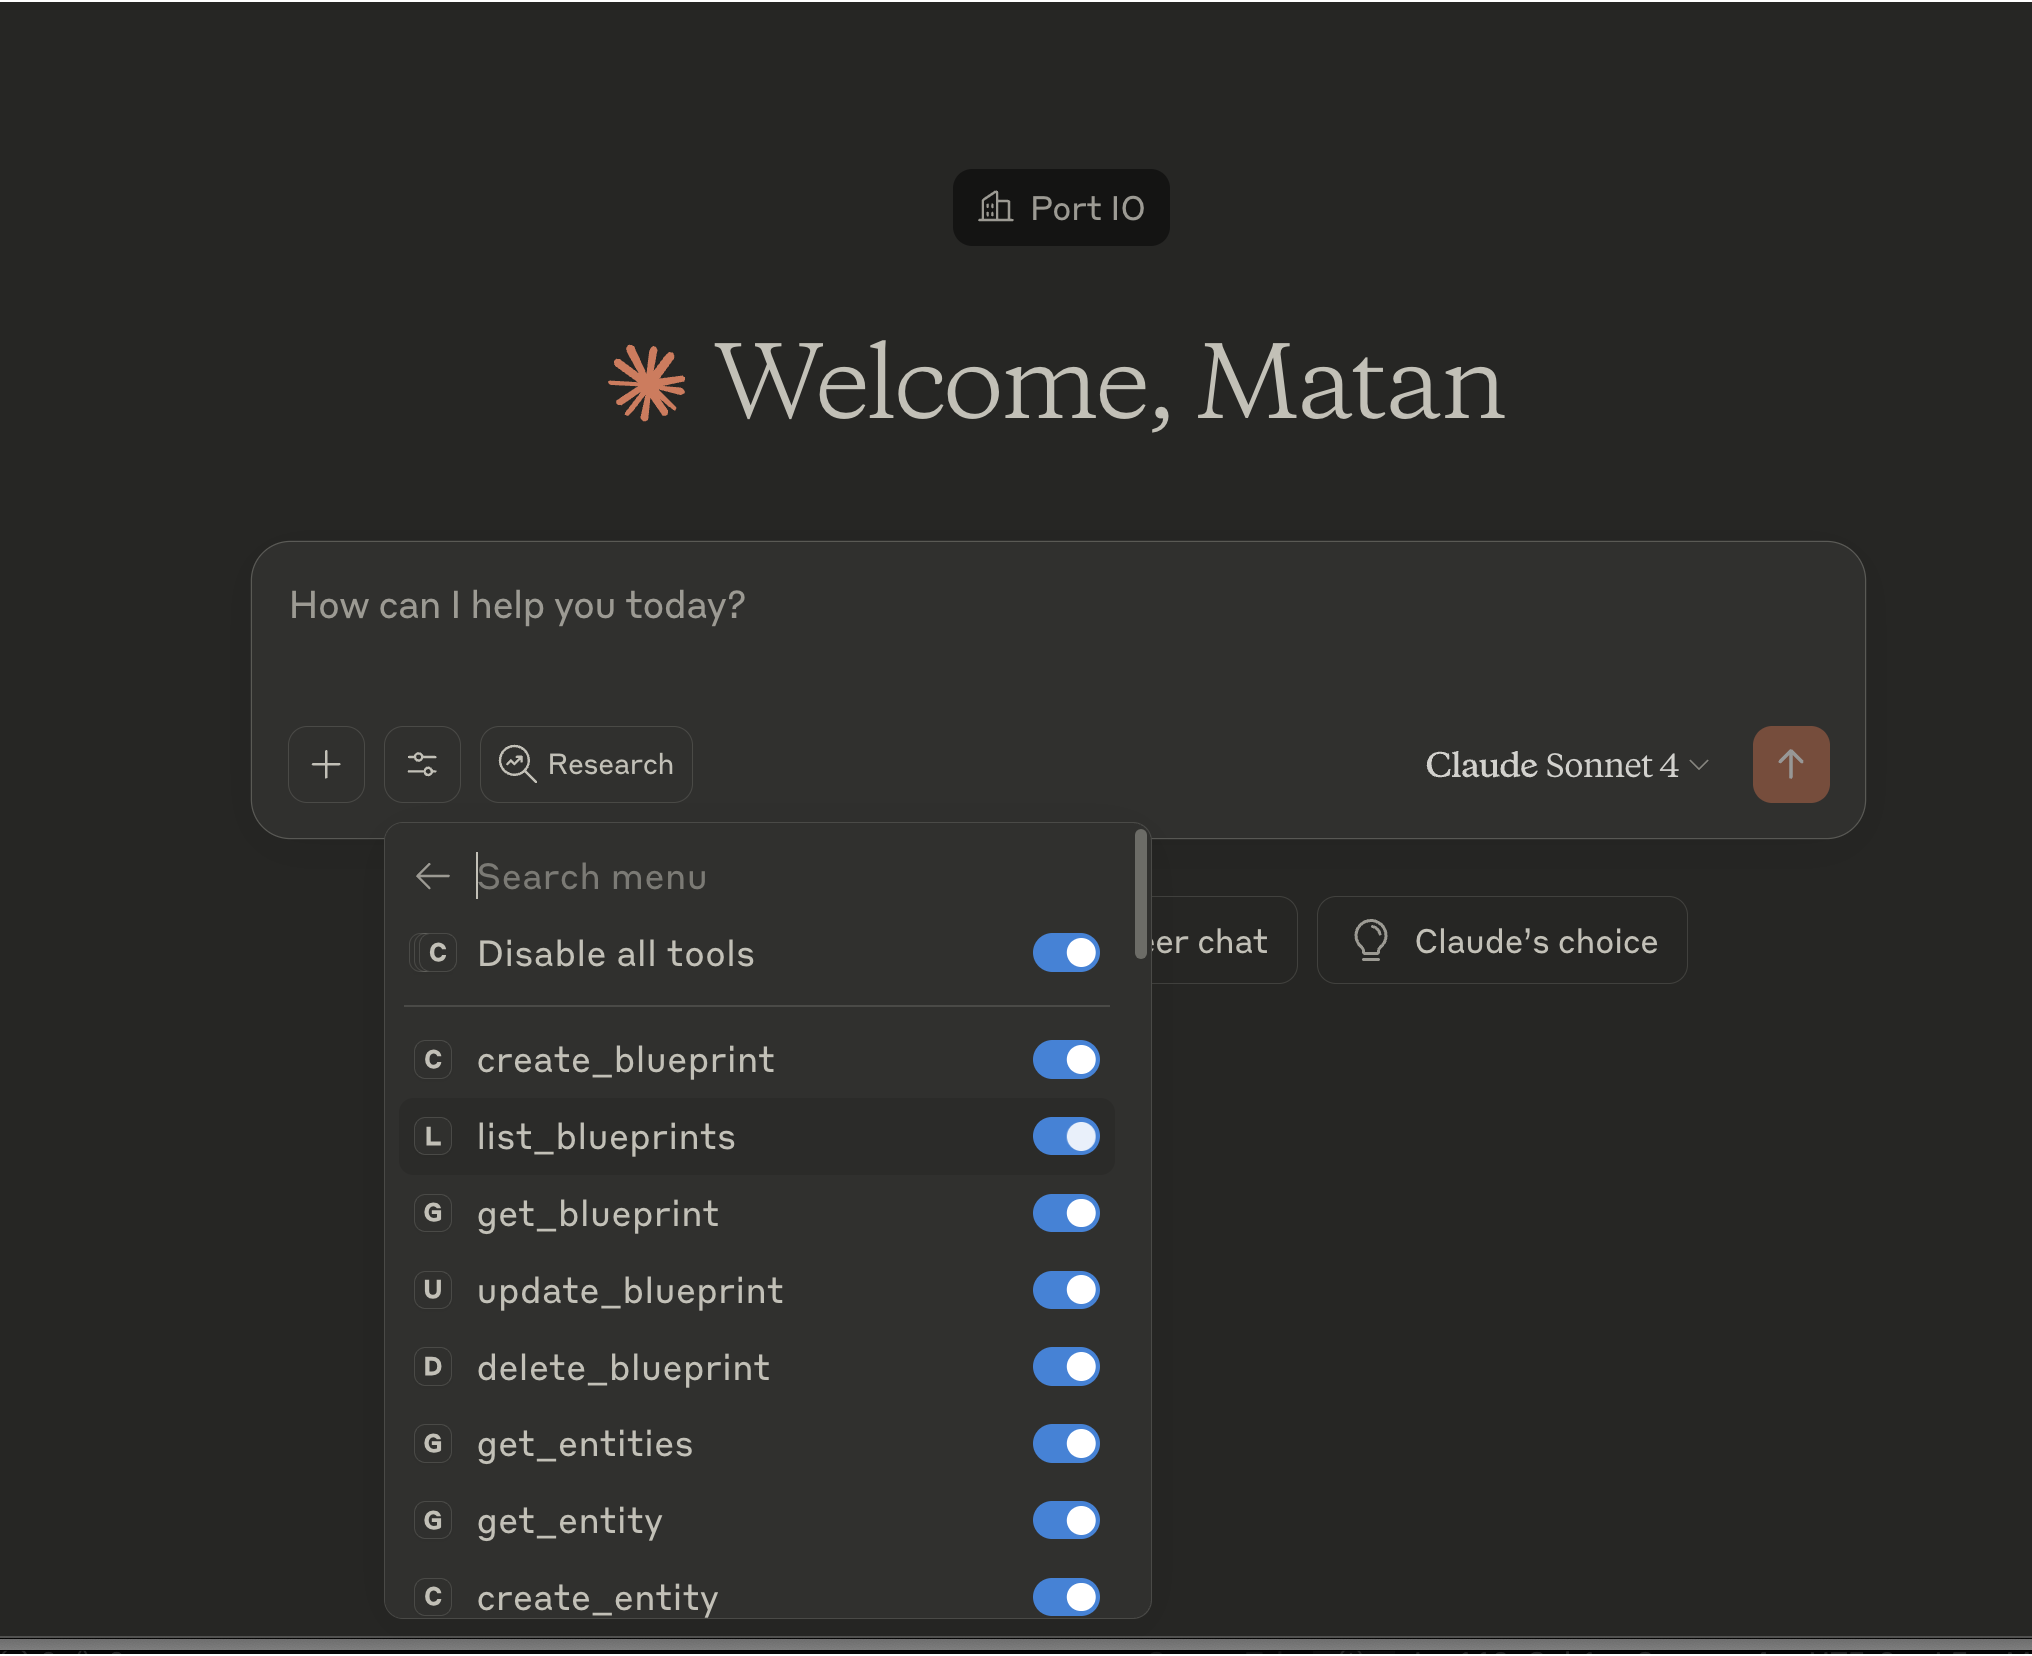
Refer to the [Claude custom connector documentation](https://support.anthropic.com/en/articles/11175166-getting-started-with-custom-connectors-using-remote-mcp) for detailed instructions.
---
# Installation
No Port AI terms required
The Port MCP server does **not** use Port AI capabilities. You can install and use it without enabling Port AI features or accepting the [Port AI Terms](https://www.port.io/legal/ai-terms).
This section details the installation process of the Port MCP server for your preferred IDE or AI assistant.
Use Port's **remote MCP server** for new connections. The Docker image and `uvx mcp-server-port` package from the [deprecated local MCP server repository](https://github.com/port-labs/port-mcp-server) are no longer maintained. If you used that server, remove its entry from your client's MCP configuration and follow the setup below.
Select your client and Port region, then follow one setup path. Use the EU endpoint (`https://mcp.port.io/v1`) for `app.port.io`, or the US endpoint (`https://mcp.us.port.io/v1`) for `app.us.port.io`.
Cursor, VS Code, GitHub Copilot CLI, and Claude Code can connect directly over HTTP. GitHub Copilot Chat in VS Code uses the VS Code connection. The `mcp-remote` package is a local compatibility proxy for clients that need it; it connects to the same remote Port server and is separate from the deprecated Docker/`uvx` server.
* Cursor
* VS Code
* GitHub Copilot UI
* GitHub Copilot CLI
* Claude AI
* Claude Code (CLI)
* Codex CLI
To connect Cursor to Port's remote MCP, follow these steps:
For the EU region, you can use the [Cursor install link](cursor://anysphere.cursor-deeplink/mcp/install?name=port\&config=eyJ1cmwiOiJodHRwczovL21jcC5wb3J0LmlvL3YxIn0=) and continue with authentication in step 3. For the US region, or to configure the connection manually, follow all steps below.
1. **Open Cursor settings**
In the settings, click **Customize**, select **MCPs**, and then click **New MCP Server**.
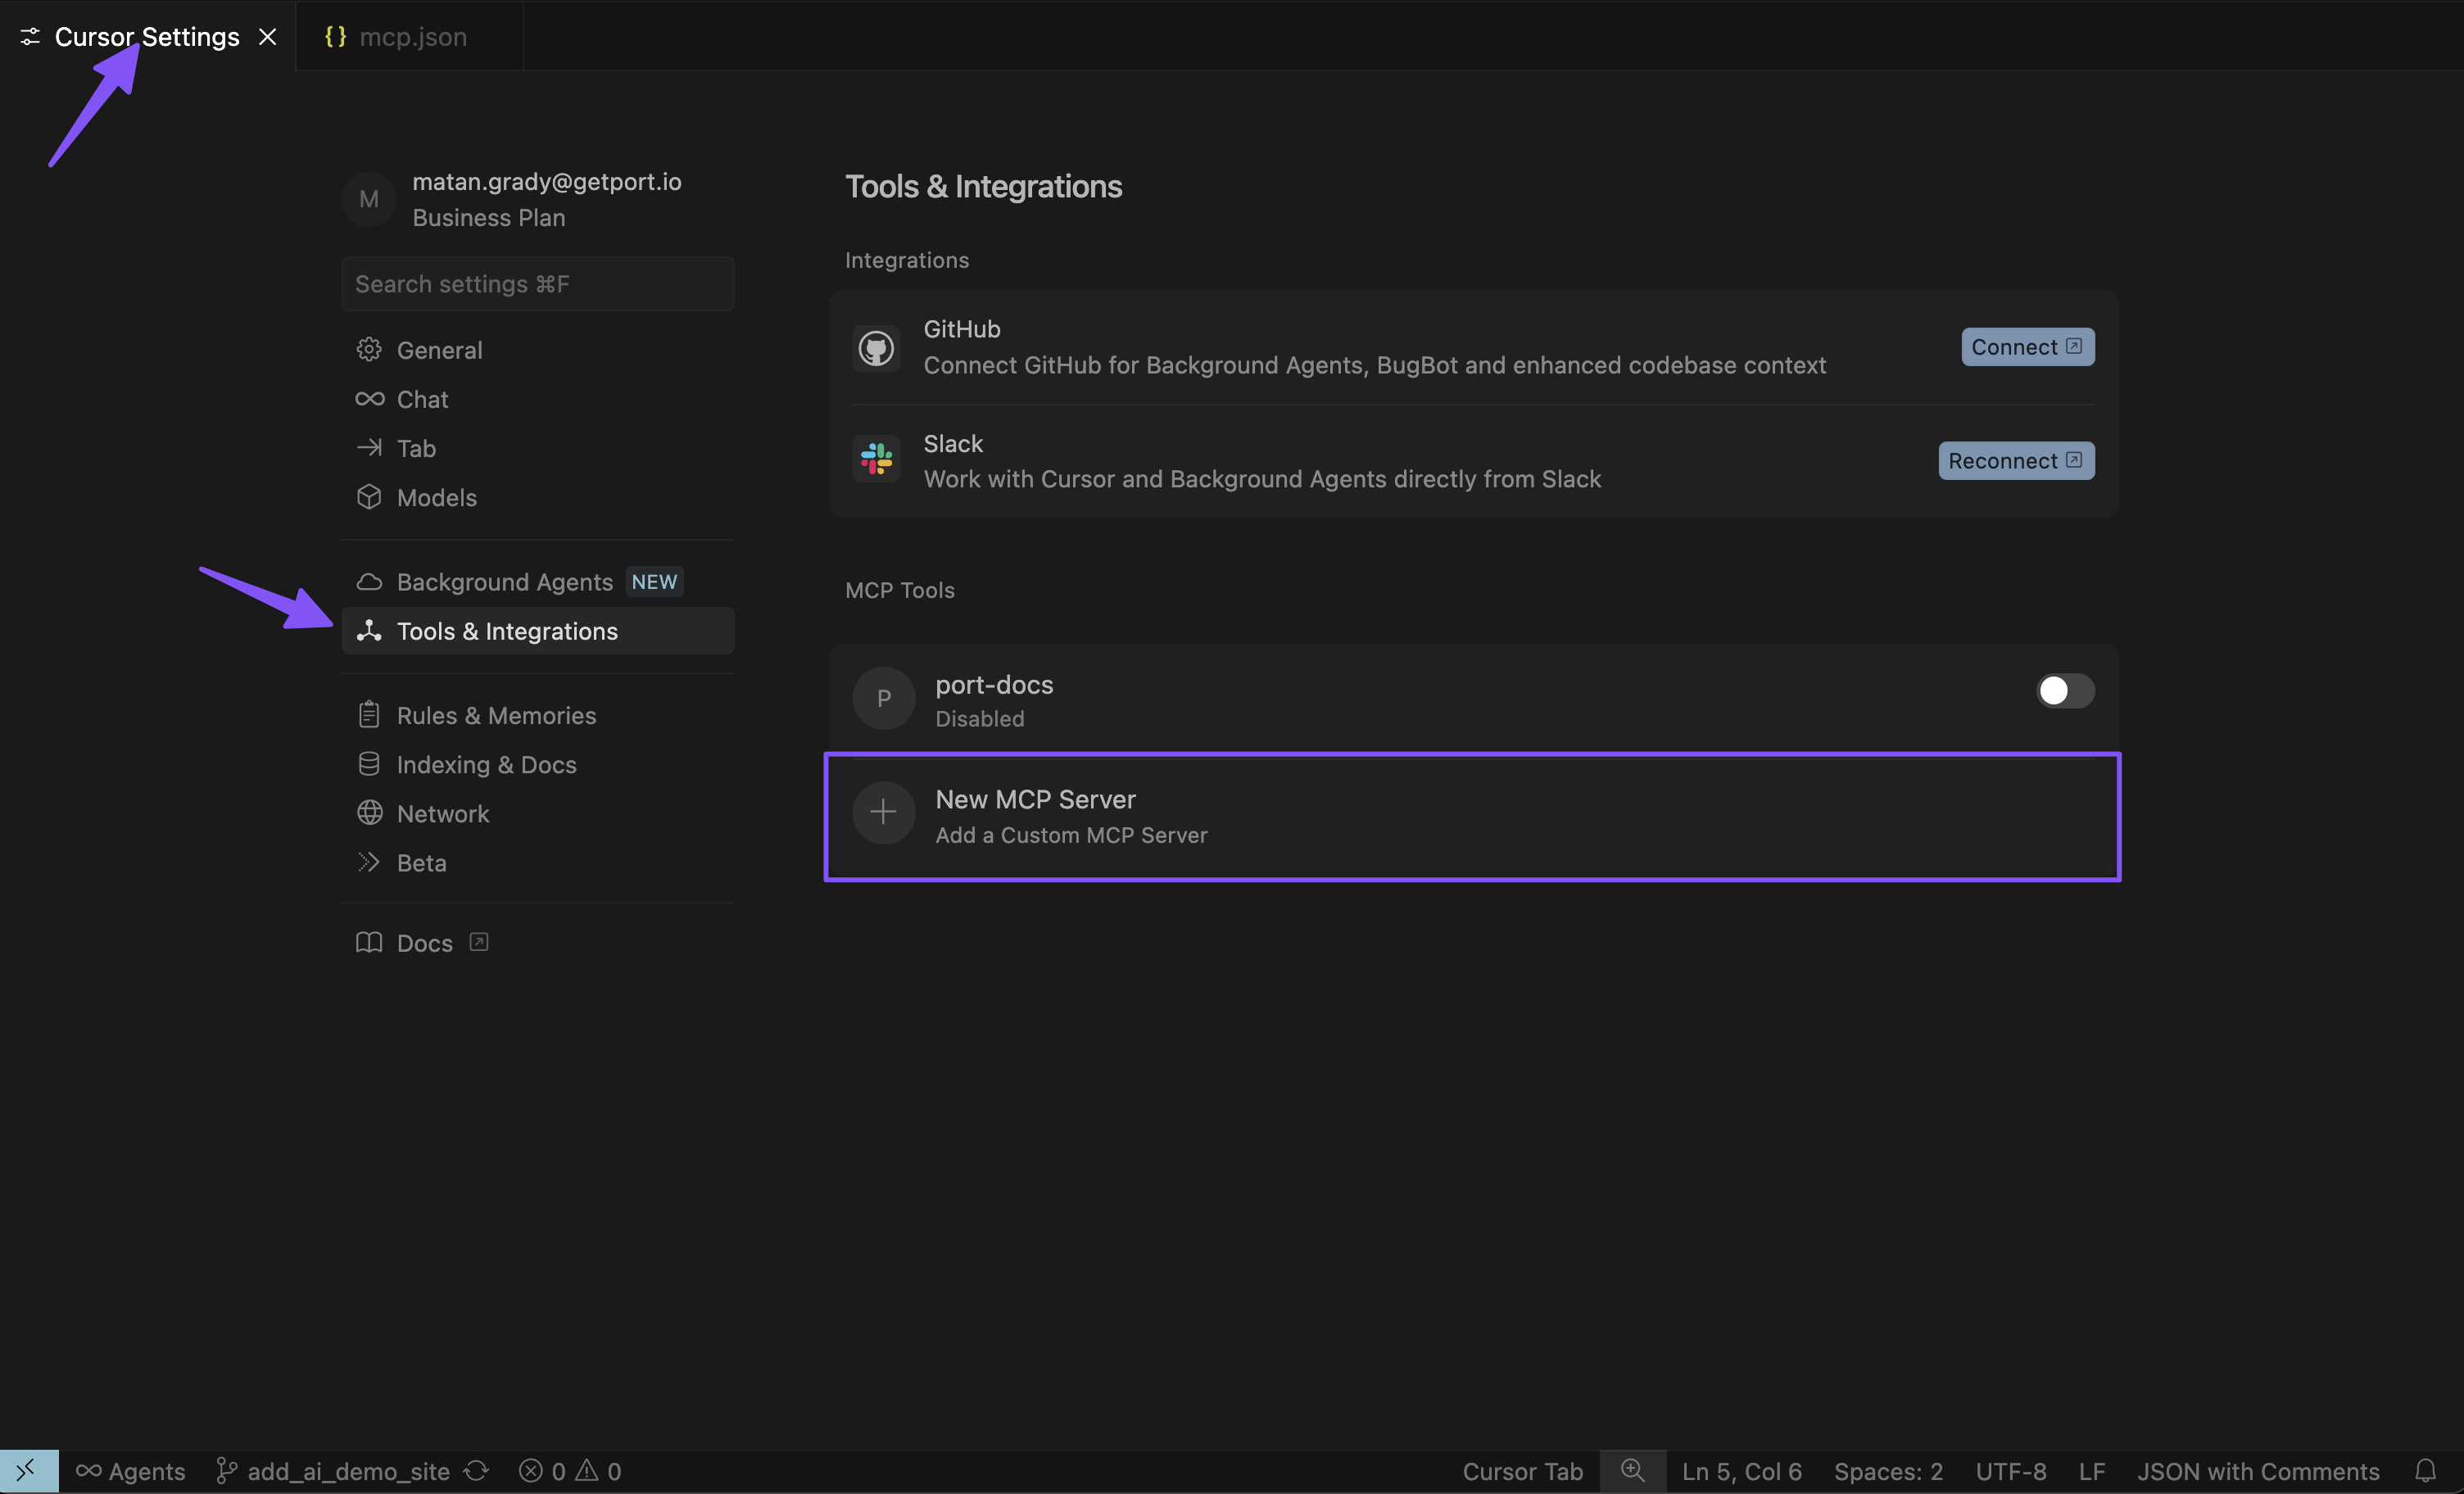
2. **Configure the MCP server**
Add the following configuration:
```
{
"mcpServers": {
"port-eu": {
"url": "https://mcp.port.io/v1",
"headers": {
"x-read-only-mode": "0"
}
}
}
}
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
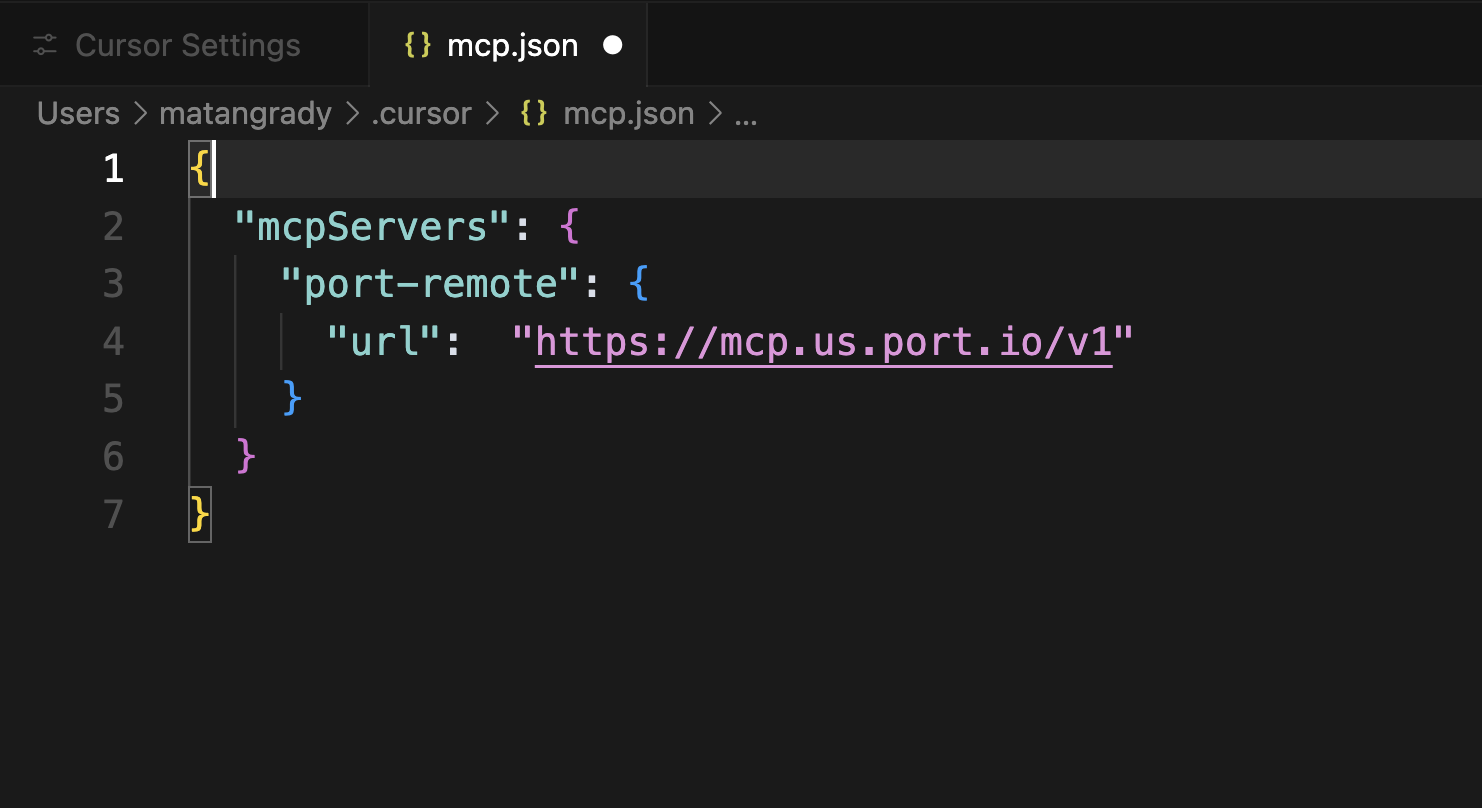
Read-only mode
The `x-read-only-mode` header defaults to `0`, which allows all tools based on your permissions. You can change it to `1` to restrict the MCP server to only expose read-only tools. When set to `1`, write tools are completely hidden from the available tools list, ensuring you can only query data without making modifications.
3. **Authenticate with Port**
Click on **"Needs login"** and complete the authentication flow in the window that opens.
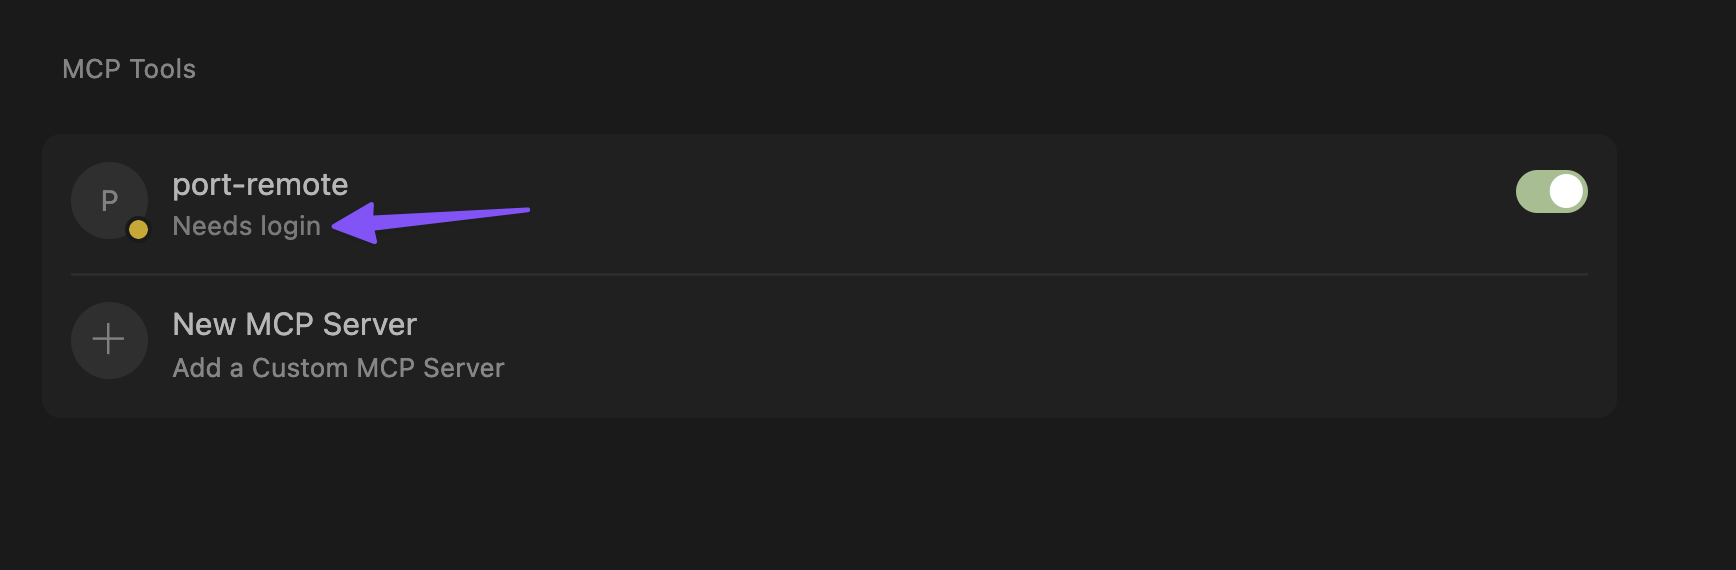
Cursor OAuth session persistence
Port MCP authentication works on the initial connection. If Cursor prompts you to re-authenticate every day or two, this is typically caused by a known Cursor OAuth issue rather than a Port-side session or configuration problem.
When Cursor refreshes your OAuth session, it may fail to persist or update tokens correctly. This is especially common when you have multiple Cursor windows open. Port's logs may show `invalid_grant` errors when Cursor attempts to refresh with a stale token.
For more details and workarounds, see these Cursor community discussions:
* [Cursor does not refresh OAuth access tokens for MCP servers](https://forum.cursor.com/t/cursor-does-not-refresh-oauth-access-tokens-for-mcp-servers/160637).
* [OAuth MCPs still require daily re-auth on 3.3.30, multi-window token store not synced](https://forum.cursor.com/t/oauth-mcps-still-require-daily-re-auth-on-3-3-30-multi-window-token-store-not-synced/160618).
* [Cursor OAuth MCPs need to connect frequently](https://forum.cursor.com/t/cursor-oauth-mcps-need-to-connect-fequently/147067).
Cursor has reported fixes for some MCP OAuth issues in stable releases after May 12, 2026. If you experience frequent re-authentication, update Cursor to the latest stable version and check whether the issue persists.
4. **Verify connection**
After successful authentication, you'll see the list of available tools from the MCP server.
Connect VS Code directly to Port's remote MCP server over HTTP. Use a current VS Code version with MCP access enabled by your organization. This setup does not require Node.js or `mcp-remote`. See the [VS Code MCP documentation](https://code.visualstudio.com/docs/agent-customization/mcp-servers) for client requirements.
## Install via the extensions tab
Install Port from the MCP gallery:
1. Open the **Extensions** view.
2. Search for `@mcp Port`.
3. Select **Port** by **port-labs**, then click **Install**.
4. If VS Code asks you to choose a server URL, pick the endpoint for your Port organization. Use `https://mcp.port.io/v1` for the EU region (`app.port.io`), or `https://mcp.us.port.io/v1` for the US region (`app.us.port.io`).
5. Complete the browser authentication flow.
6. Verify that VS Code displays the available tools. Open a chat and select Port tools from the tool picker. Try asking, "List my Port blueprints."
The gallery install allows tools based on your Port permissions. To expose only read-only tools, or to set other headers, add the server manually.
## Install manually
1. Open the **Command Palette** and run **MCP: Open User Configuration**.
2. Add the following configuration to `mcp.json`. If you already have a `servers` object, add the Port entry to it:
```
{
"servers": {
"port-vscode-eu": {
"type": "http",
"url": "https://mcp.port.io/v1",
"headers": {
"x-read-only-mode": "0"
}
}
}
}
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
Set `x-read-only-mode` to `1` if you want to expose only read-only tools. The default, `0`, allows tools based on your Port permissions.
3. Save the file, click **Start** above the Port server entry, and complete the browser authentication flow.
4. Verify that VS Code displays the available tools. Open a chat and select Port tools from the tool picker. Try asking, "List my Port blueprints."
If the connection fails, run **MCP: List Servers**, select your Port server, and choose **Show Output** to inspect the error. Check that your configuration uses the correct regional endpoint and that you completed browser authentication.
GitHub Copilot Chat in VS Code uses the same Port connection as the **VS Code** tab, including the MCP gallery install. Complete that setup, then enable the Port tools in Copilot Chat.
1. Complete the **VS Code** tab steps, including browser authentication.
2. Open Copilot Chat and switch the mode to **Agent**.
3. In the tools picker, enable the Port tools.
4. To test the installation, ask Copilot, "List my Port blueprints."
Organization policy
On Copilot Business and Copilot Enterprise, an organization owner must set **MCP servers in Copilot** to **Enabled** before Copilot Chat can call MCP tools. This policy is disabled by default. Copilot Free, Copilot Pro, Copilot Pro+, and Copilot Max are not covered by it. If the organization limits MCP access to registry servers, Port must be listed in that registry. See [managing policies for GitHub Copilot in your organization](https://docs.github.com/en/copilot/how-tos/administer-copilot/manage-for-organization/manage-policies) and [configure MCP server access](https://docs.github.com/en/copilot/how-tos/administer-copilot/manage-mcp-usage/configure-mcp-server-access).
Copilot Chat in Visual Studio and JetBrains uses each product's own MCP screen. For those editors, follow [extending GitHub Copilot Chat with MCP](https://docs.github.com/en/copilot/customizing-copilot/using-model-context-protocol/extending-copilot-chat-with-mcp) and use the Port URL from the **VS Code** tab.
Connect GitHub Copilot CLI directly to Port's remote MCP server over HTTP. See the [GitHub Copilot CLI MCP documentation](https://docs.github.com/en/copilot/how-tos/copilot-cli/customize-copilot/add-mcp-servers) for client requirements.
1. Add the following configuration to `mcp-config.json`. If you already have an `mcpServers` object, add the Port entry to it:
```
{
"mcpServers": {
"port-copilot-eu": {
"tools": ["*"],
"type": "http",
"url": "https://mcp.port.io/v1",
"headers": {
"x-read-only-mode": "0"
}
}
}
}
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
Set `x-read-only-mode` to `1` if you want to expose only read-only tools. The default, `0`, allows tools based on your Port permissions.
OAuth redirect port
GitHub Copilot CLI uses CIMD (Client ID Metadata) authorization and expects OAuth callbacks on port `33418`. If you get an error like `unauthorized_client: Callback URL mismatch`, add an `auth` block with `redirectPort` set to `33418` inside your Port server entry:
```
"auth": {
"redirectPort": 33418
}
```
2. Start Copilot CLI, run `/mcp`, select your Port server, and complete the browser authentication flow.
3. Verify that Copilot CLI displays the available Port tools. Try asking, "List my Port blueprints."
If authentication fails, check that your configuration uses the correct regional endpoint and that you completed browser authentication.
To connect Claude AI (Desktop & Web) to Port's remote MCP, install the Port official connector from the Claude connectors library. For detailed instructions, refer to the [official Anthropic documentation on custom connectors](https://support.anthropic.com/en/articles/11175166-getting-started-with-custom-connectors-using-remote-mcp).
* **Direct install link**: [Install Port connector in Claude](https://claude.ai/directory/8f5edd1c-c876-465e-a5b9-cc8e6d27dcb7).
1. **Open [Port Connector page](https://claude.ai/directory/8f5edd1c-c876-465e-a5b9-cc8e6d27dcb7)** by visiting this link or searching for "Port" connector, and click **Connect**.
2. **Enter your MCP server URL** when prompted:
```
https://mcp.port.io/v1
```
US region
If your Port organization is in the US region, use `https://mcp.us.port.io/v1` instead.
Connect Claude Code directly to Port's remote MCP server using HTTP. This is the recommended setup and does not require Node.js, `npx`, or a local MCP server.
**Prerequisites**
* Claude Code CLI installed on your machine. For installation instructions, refer to the [official Claude Code documentation](https://docs.anthropic.com/en/docs/claude-code/getting-started).
* Access to your Port account in the browser for OAuth authentication.
**Add Port MCP**
Run the following command from the directory where you use Claude Code:
```
claude mcp add --transport http port-eu https://mcp.port.io/v1 --header "x-read-only-mode: 0"
```
If your Port organization is in the US region, replace `port-eu` and `https://mcp.port.io/v1` with `port-us` and `https://mcp.us.port.io/v1`.
Read-only mode
The `x-read-only-mode` header defaults to `0`, which allows all tools based on your permissions. Change it to `1` to restrict the MCP server to only expose read-only tools. When set to `1`, write tools are completely hidden from the available tools list, ensuring you can only query data without making modifications.
**Verify the connection**
Start Claude Code:
```
claude
```
Run `/mcp`, select **port-eu** or **port-us**, and follow the browser authentication flow. After authentication, verify that the server shows its available tools. Try asking, "List my Port blueprints."
**Resolve connection timeouts**
If you previously used `claude mcp add-json` with `npx mcp-remote`, that configuration starts a local proxy. On first use, `npx` may need to download the package and its dependencies, adding startup time. The proxy also waits for browser authentication. Package registry access, proxy settings, or an incomplete login can cause this path to time out even when direct HTTP works.
Remove the old Port server entry from your MCP configuration before adding the direct HTTP connection above. If the direct connection also times out, check your region, access to the MCP endpoint from your terminal, and completion of the browser login. Use `/mcp` to inspect the connection status. See the [Claude Code MCP documentation](https://code.claude.com/docs/en/mcp) for connection diagnostics and startup timeout settings.
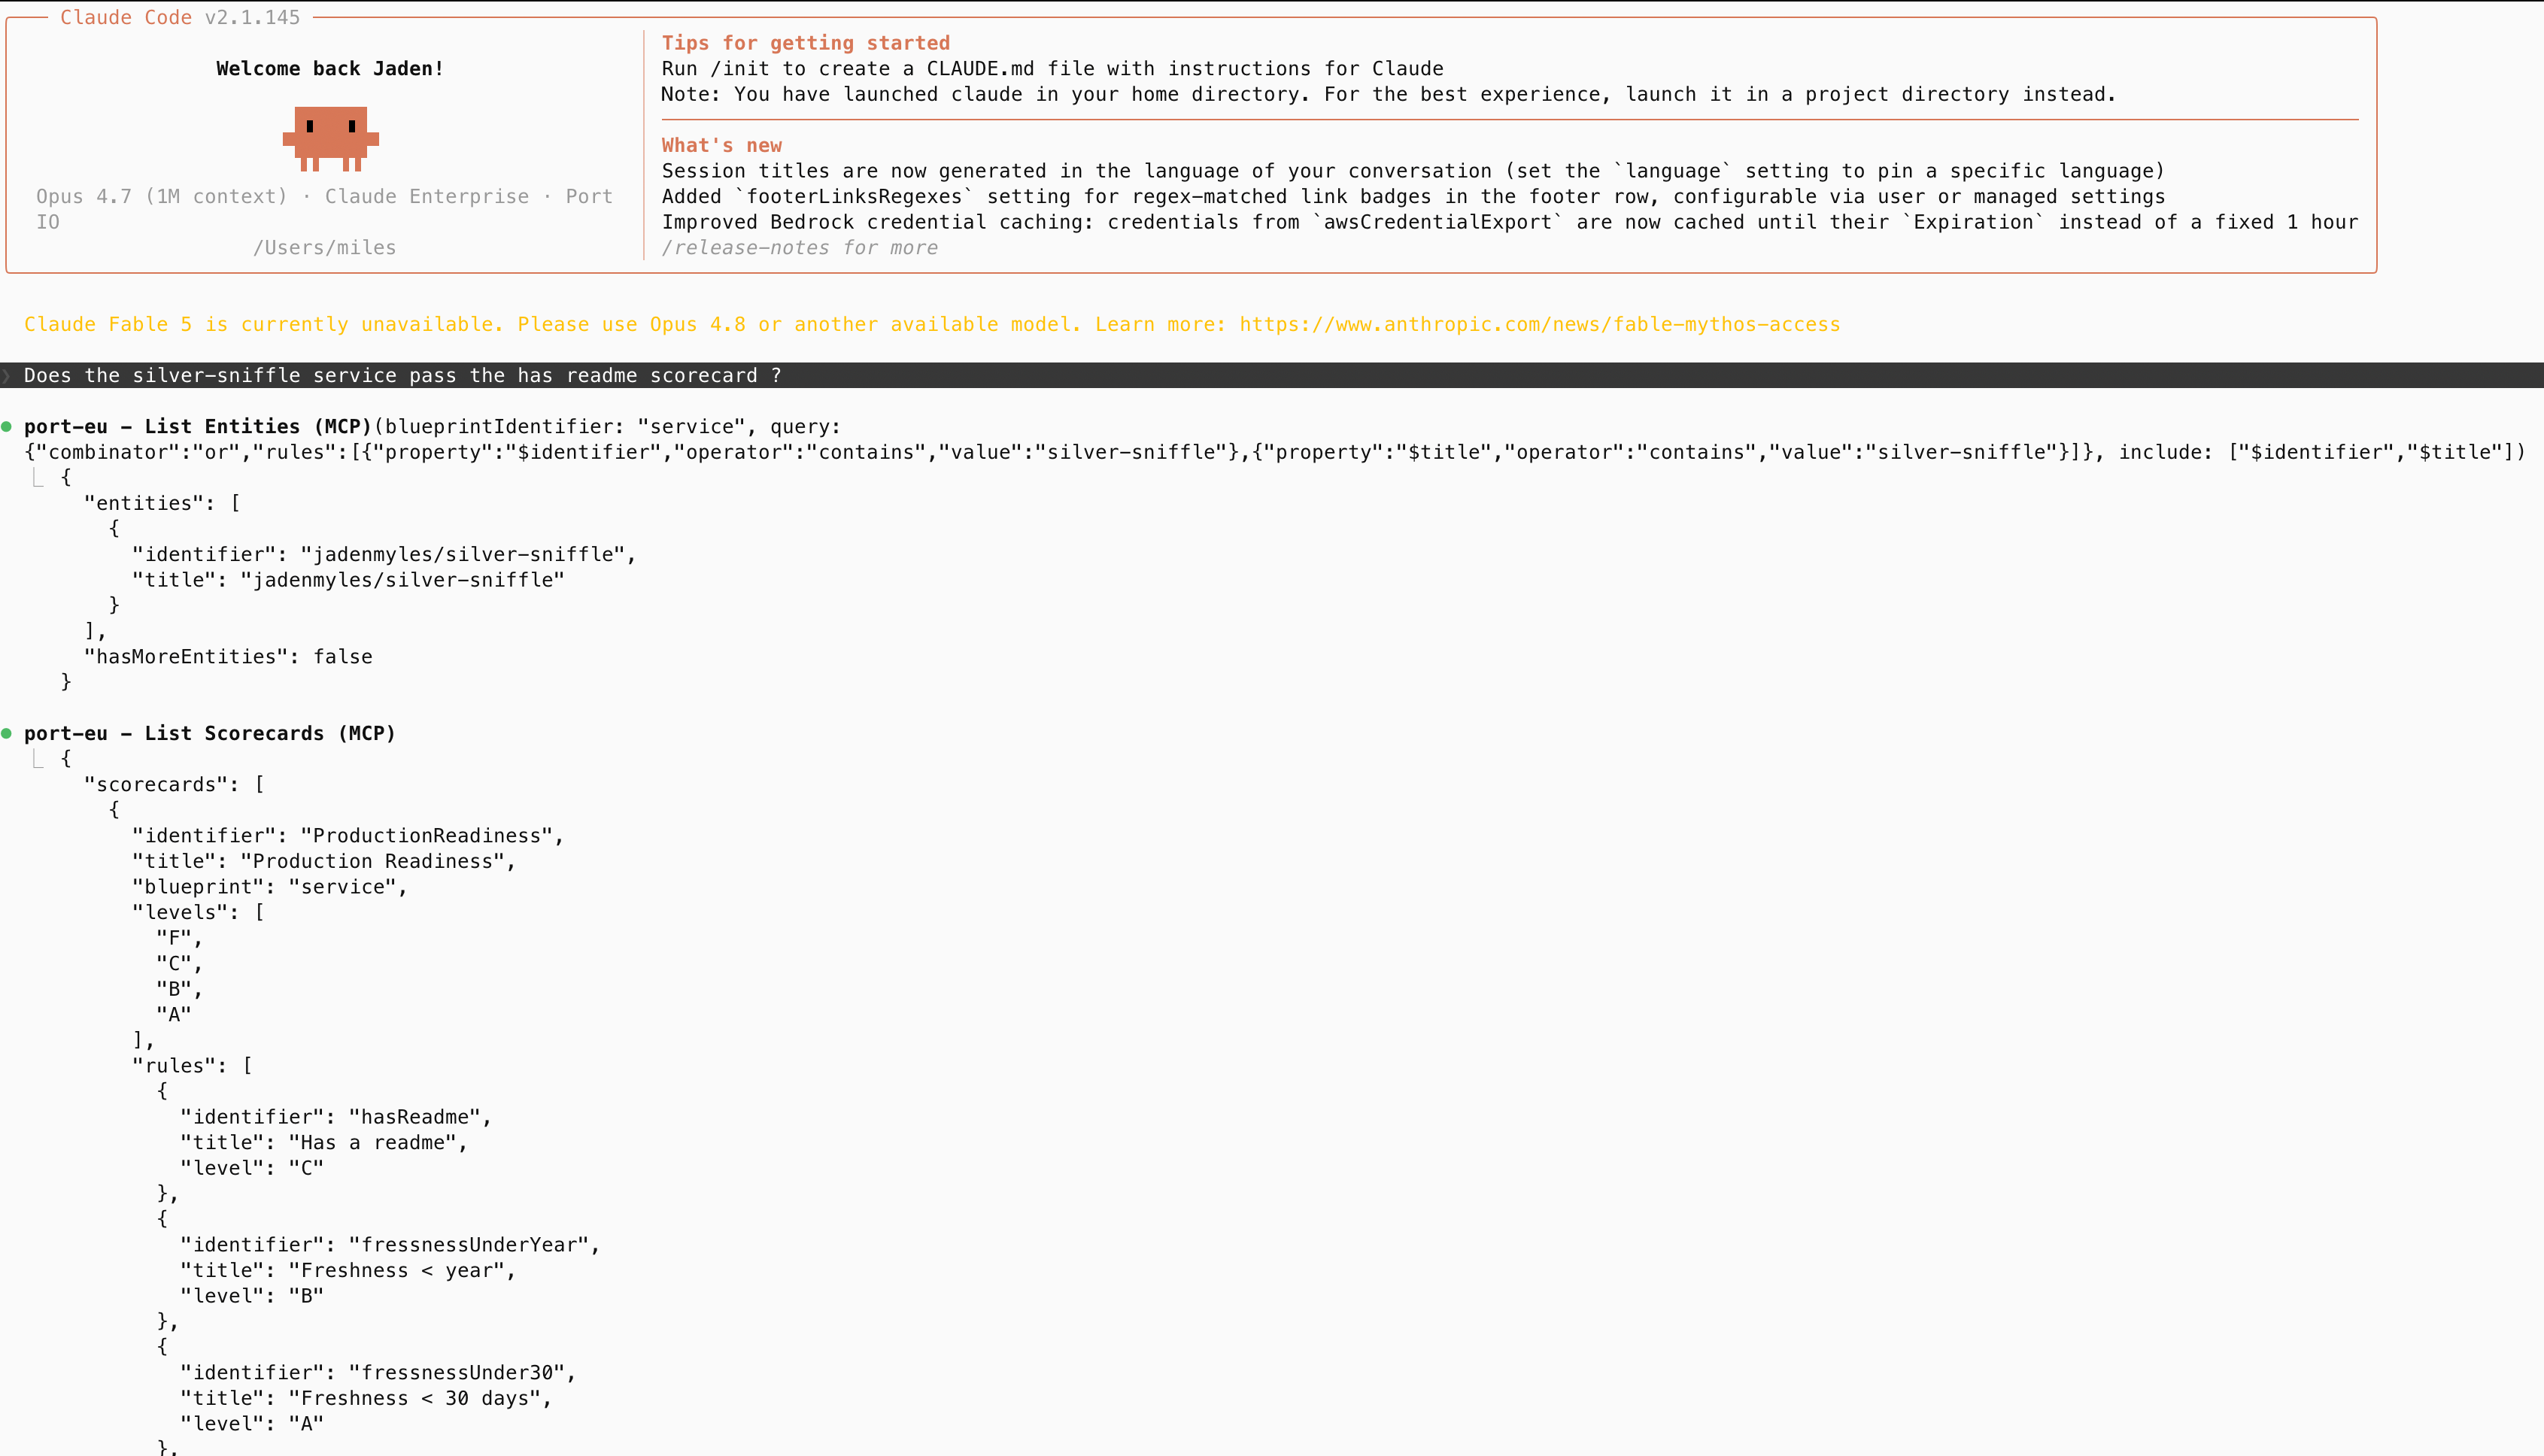
To connect OpenAI Codex CLI to Port's remote MCP server, install Codex CLI locally and add Port as a remote MCP server. For complete instructions, refer to the [official Codex CLI documentation](https://developers.openai.com/codex/cli).
**Prerequisites**
* An OpenAI account with access to Codex CLI.
* The Codex CLI installed on your machine.
* Access to your Port account in the browser for OAuth authentication.
* Your Port region. If your Port app URL contains `us`, use the US MCP URL. Otherwise, use the EU MCP URL.
* [Node.js](https://nodejs.org/) installed on your machine.
**Step 1: Install Codex CLI**
Run the following command to install Codex CLI:
```
npm install -g @openai/codex
```
After installation, verify that Codex CLI is available:
```
codex --version
```
**Step 2: Sign in to Codex**
Start Codex and complete the sign-in flow:
```
codex
```
**Step 3: Add Port MCP**
Run the following command:
```
codex mcp add port-eu --url https://mcp.port.io/v1
```
US region
If your Port organization is in the US region, replace `port-eu` and `https://mcp.port.io/v1` with `port-us` and `https://mcp.us.port.io/v1`.
**Step 4: Authenticate with Port**
After adding the server, authenticate using OAuth. Run the matching login command for the region you used in step 3:
```
codex mcp login port-eu
```
If you used `port-us` in step 3, run `codex mcp login port-us` instead.
Complete the Port authentication flow in the browser window that opens.
**Step 5: Verify the connection**
Start a Codex session and run `/mcp` and type port-eu or port-us to verify that the Port MCP server is connected and showing its tools.
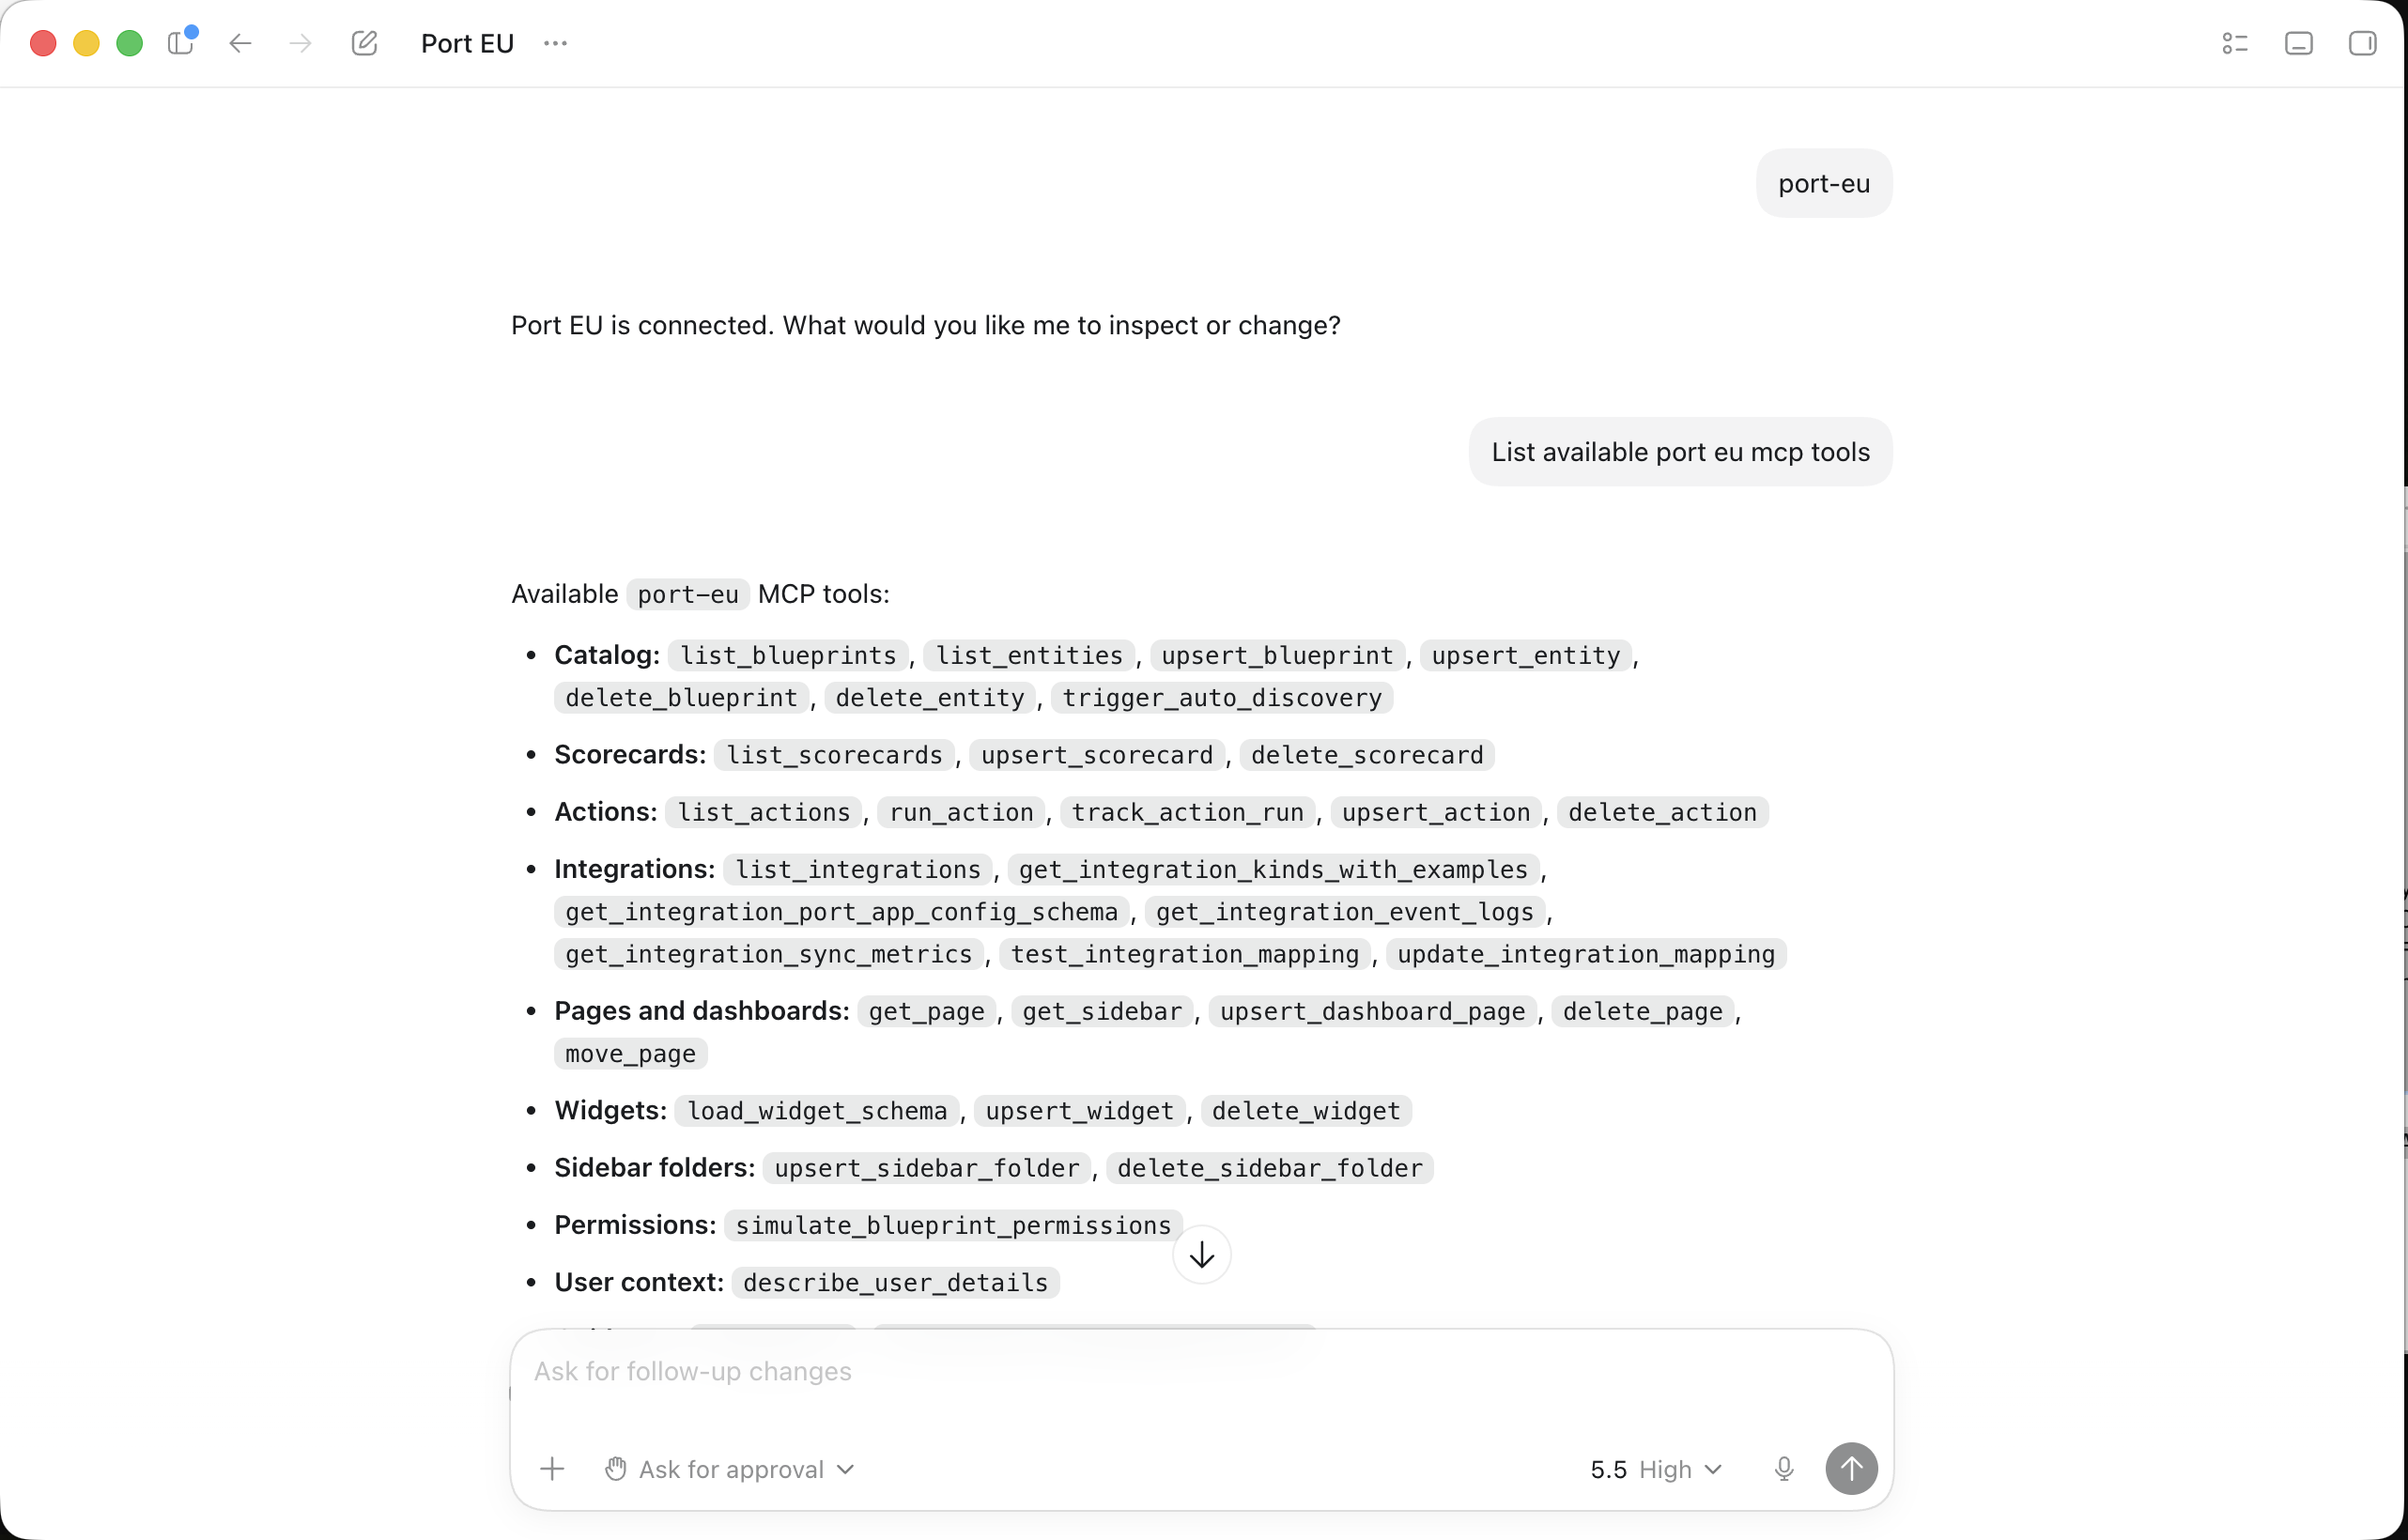
**Step 6: Query Port through Codex**
Once connected, you can interact with your Port catalog using natural language. Codex will automatically use the Port MCP tools to fulfill your requests. Try these example prompts:
* "Show me all services owned by the backend team"
* "What scorecards are failing for my production services?"
* "Who is the owner of the payments service?"
**Optional: Configure Codex manually**
You can also add the MCP server directly to your `~/.codex/config.toml` file:
```
[mcp_servers.port-eu]
url = "https://mcp.port.io/v1"
enabled = true
```
US region
If your Port organization is in the US region, replace `port-eu` and `https://mcp.port.io/v1` with `port-us` and `https://mcp.us.port.io/v1`.
After editing the file, run the matching `codex mcp login` command from step 4.
Read-only mode
You can restrict Codex to read-only Port tools by adding the `x-read-only-mode` header to your Codex MCP configuration. See the [MCP server headers](https://docs.port.io/agent-management/port-mcp-server/installation#mcp-server-headers) section for the full configuration.
Extended session duration
MCP clients can maintain authenticated sessions for up to 30 days (as long as you're not idle for 15 days). This applies to OAuth-based authentication for interactive use, providing a more seamless experience for long-running integrations.
## Connect the server to multiple organizations[](#connect-the-server-to-multiple-organizations "Direct link to Connect the server to multiple organizations")
Port uses your browser's OAuth session to approve MCP connections. When your MCP client opens the authentication prompt, you approve access in the organization where you are currently logged in. Follow these steps to connect to the correct organization:
* Make sure you are logged in to the desired organization in your browser before you start the MCP connection flow.
* Approve the OAuth prompt from your MCP client while you remain logged in to that organization.
* Continue using the MCP client; changing your browser session afterward does not change the connected organization.
To connect another organization from the same MCP client, add a second configuration and repeat the flow while logged in to the other organization. Each configuration keeps its own OAuth approval, so you can work with multiple organizations in parallel.
External tools via MCP connectors
In addition to Port's native tools, you can also access external MCP servers (like Notion, Slack, Jira, and more) through the same interface. If you have configured [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md), authenticate to them in Port and they will automatically be available in your IDE alongside Port's native capabilities.
Platform teams can also run an [MCP registry](/agent-management/ai-registry/mcp-registry/.md) in the software catalog to track which MCP servers are approved, let developers request new servers, and publish installation guidance.
## Connecting the server when SSO is enabled[](#connecting-the-server-when-sso-is-enabled "Direct link to Connecting the server when SSO is enabled")
If your organization uses SSO (Single Sign-On) and you see an error like the one below when trying to connect to the MCP Server:
This error occurs because the SSO connection needs to be configured for domain-level authentication to work with the MCP Server's OAuth flow.
*Why this happens* - When SSO is initially configured in Port, the authentication connection starts as a standard type. For the MCP Server to authenticate users through SSO, the connection needs to be upgraded to "domain level" mode, which enables Dynamic Client Registration (DCR). This configuration change can only be made by Port on the backend.
*How to resolve* - Contact our support team and let them know you're experiencing an SSO authentication error when connecting to the MCP Server. The support team will update your SSO connection configuration to enable domain-level authentication, which will allow the MCP Server OAuth flow to work correctly with your SSO provider.
Once the configuration is updated, retry the MCP Server connection and the authentication should work as expected.
## Token-based authentication[](#token-based-authentication "Direct link to Token-based authentication")
You can also connect using machine authentication for automated environments like CI/CD pipelines where interactive authentication isn't possible. Request a token from the MCP OAuth endpoint:
```
curl -X POST "https://mcp.port.io/v1/token" \
-H "Content-Type: application/x-www-form-urlencoded" \
-d "grant_type=client_credentials" \
-d "client_id=YOUR_CLIENT_ID" \
-d "client_secret=YOUR_CLIENT_SECRET"
```
For complete examples and detailed setup instructions, see our [machine authentication guide](/agent-management/port-mcp-server/token-based-authentication/.md).
## MCP server headers[](#mcp-server-headers "Direct link to MCP server headers")
The Port MCP Server supports several headers that allow you to customize its behavior:
| Header | Type | Default | Description |
| -------------------------- | ------ | ----------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `x-read-only-mode` | String | `0` | Controls whether write tools are available. Set to `1` to restrict the MCP server to only expose read-only tools, completely hiding write tools from the available tools list. Set to `0` to allow all tools based on your permissions. |
| `x-allowed-actions-to-run` | String | All actions | Comma-separated list of action identifiers that controls which actions are available through the `run_action` tool. Only the specified actions will be available. If not specified, all actions you have permission to run will be available. If set to an empty string, no actions will be allowed to run. Example: `"create_github_issue,create_incident"`. |
### Configuring headers in your MCP client[](#configuring-headers-in-your-mcp-client "Direct link to Configuring headers in your MCP client")
Headers are set in your MCP client's configuration file, not in Port itself. The exact syntax depends on your client.
* Claude Desktop
* Claude Code (CLI)
* Cursor
* VS Code
* GitHub Copilot CLI
* Codex CLI
Use the official Port connector for the standard Claude Desktop setup above. If you need to pass custom headers through a local proxy, configure `mcp-remote` in `claude_desktop_config.json` as shown below. This option requires [Node.js](https://nodejs.org/) and access to the npm registry. It connects to Port's remote MCP server.
```
{
"mcpServers": {
"port": {
"command": "npx",
"args": [
"-y",
"mcp-remote",
"https://mcp.port.io/v1",
"--header",
"x-read-only-mode: 1",
"--header",
"x-allowed-actions-to-run: create_github_issue,deploy_service"
]
}
}
}
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
Pass headers using the `--header` flag when adding the direct HTTP connection. Each header requires a separate `--header` argument. If you already added `port-eu`, update that entry's headers in your MCP configuration instead of adding it again:
```
claude mcp add --transport http port-eu https://mcp.port.io/v1 \
--header "x-read-only-mode: 1" \
--header "x-allowed-actions-to-run: create_github_issue,deploy_service"
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
Add a `headers` block to your `.cursor/mcp.json` file:
```
{
"mcpServers": {
"port": {
"url": "https://mcp.port.io/v1",
"headers": {
"x-read-only-mode": "1",
"x-allowed-actions-to-run": "create_github_issue,deploy_service"
}
}
}
}
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
Add a `headers` block to your `.vscode/mcp.json` file:
```
{
"servers": {
"port": {
"url": "https://mcp.port.io/v1",
"headers": {
"x-read-only-mode": "1",
"x-allowed-actions-to-run": "create_github_issue,deploy_service"
}
}
}
}
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
Add a `headers` block to your `mcp-config.json` file:
```
{
"mcpServers": {
"port-copilot-eu": {
"tools": ["*"],
"type": "http",
"url": "https://mcp.port.io/v1",
"headers": {
"x-read-only-mode": "1"
}
}
}
}
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
Add an `http_headers` block to your `~/.codex/config.toml` file:
```
[mcp_servers.port]
url = "https://mcp.port.io/v1"
enabled = true
[mcp_servers.port.http_headers]
x-read-only-mode = "1"
x-allowed-actions-to-run = "create_github_issue,deploy_service"
```
US region
If your Port organization is in the US region, replace `https://mcp.port.io/v1` with `https://mcp.us.port.io/v1`.
Restricting to specific actions
Use `x-allowed-actions-to-run` to scope a connection to only the actions relevant for a given context - for example, allowing a developer's IDE session to run only deployment actions, or giving a CI/CD integration access to a single scaffold action. To find an action's identifier, open the [self-service](https://app.port.io/self-serve) page and copy the identifier from the action.
## Prompts[](#prompts "Direct link to Prompts")
The MCP server exposes static and custom [prompts](/agent-management/ai-registry/prompts/.md) in supported MCP clients. For setup, the prompt blueprint, and using prompts in Port AI Assistant, see the [Prompts overview](/agent-management/ai-registry/prompts/.md).
## Connecting to AI Agents[](#connecting-to-ai-agents "Direct link to Connecting to AI Agents")
To connect the Port MCP server to AI agents in CI/CD environments or other automated contexts where interactive authentication isn't possible, see our [machine authentication](/agent-management/port-mcp-server/token-based-authentication/.md) guide.
## FAQ and troubleshooting[](#faq-and-troubleshooting "Direct link to FAQ and troubleshooting")
1What happens if I approve the OAuth prompt in the wrong organization?
2Why does Cursor prompt me to re-authenticate every day or two?
3How do I connect from Augment Code if OAuth fails?
4Why do MCP tools fail behind a corporate VPN or firewall?
5How can I disable the Port MCP installation option?
---
# Port MCP server
No Port AI terms required
The Port MCP server does **not** use Port AI capabilities. You can install and use it without enabling Port AI features or accepting the [Port AI Terms](https://www.port.io/legal/ai-terms).
[YouTube video player](https://www.youtube.com/embed/WrVgQ-whBiE)
The Port Model Context Protocol (MCP) Server acts as a bridge, enabling Large Language Models (LLMs) - like those powering Claude, Cursor, or GitHub Copilot - to interact directly with your Port.io developer portal. This allows you to leverage natural language to query your software catalog, analyze service health, manage resources, and even streamline development workflows, all from your preferred interfaces.
Port MCP server vs. Port AI
The Port MCP server is separate from [Port AI](/port-ai/overview/.md). Your IDE or chat client runs the LLM; Port only exposes catalog tools.
## Why integrate LLMs with your developer portal?[](#why-integrate-llms-with-your-developer-portal "Direct link to Why integrate LLMs with your developer portal?")
The primary advantage of the Port MCP Server is the ability to bring your developer portal's data and actions into the conversational interfaces you already use. This offers several benefits:
* **Reduced context switching:** Access Port information and initiate actions without leaving your IDE or chat tool.
* **Increased efficiency:** Get answers and perform tasks faster using natural language commands.
* **Improved developer experience:** Make your developer portal more accessible and intuitive to interact with.
* **Enhanced data-driven decisions:** Easily pull specific data points from Port to inform your work in real-time.
As one user put it:
> "It would be interesting to build a use case where a developer could ask Copilot from his IDE about stuff Port knows about, without actually having to go to Port."
The Port MCP Server directly enables these kinds of valuable, in-context interactions.
## Key capabilities and use-cases[](#key-capabilities-and-use-cases "Direct link to Key capabilities and use-cases")
[YouTube video player](https://www.youtube.com/embed/hxUTTPSApQs)
The Port MCP Server enables you to interact with your Port data and capabilities directly through natural language within your chosen LLM-powered tools. Here's what you can achieve:
### Find information quickly[](#find-information-quickly "Direct link to Find information quickly")
Effortlessly query your software catalog and get immediate answers. This eliminates the need to navigate through UIs or write complex API queries when you need information.
* Ask: "Who is the owner of service X?"
* Ask: "How many services do we have in production?"
* Ask: "Show me all the microservices owned by the Backend team."
* Ask: "What are the dependencies of the 'OrderProcessing' service?"
### Vibe-build in Port[](#vibe-build-in-port "Direct link to Vibe-build in Port")
Leverage Claude's capabilities to manage and build your entire Port software catalog. You can create and configure blueprints, set up self-service actions, design scorecards, and more.
* Follow the [Build and configure Port using the MCP server](/guides/all/build-port-with-mcp/.md) guide for complete data model, action, automation, and scorecard examples.
* Ask: "Please help me apply this guide into my Port instance - \[\[guide URL]]"
* Ask: "I want to start managing my k8s deployments, how can we build it in Port?"
* Ask: "I want a new production readiness scorecard to track the code quality and service alerts"
* Ask: "Create a new self-service action in Port to scaffold a new service"
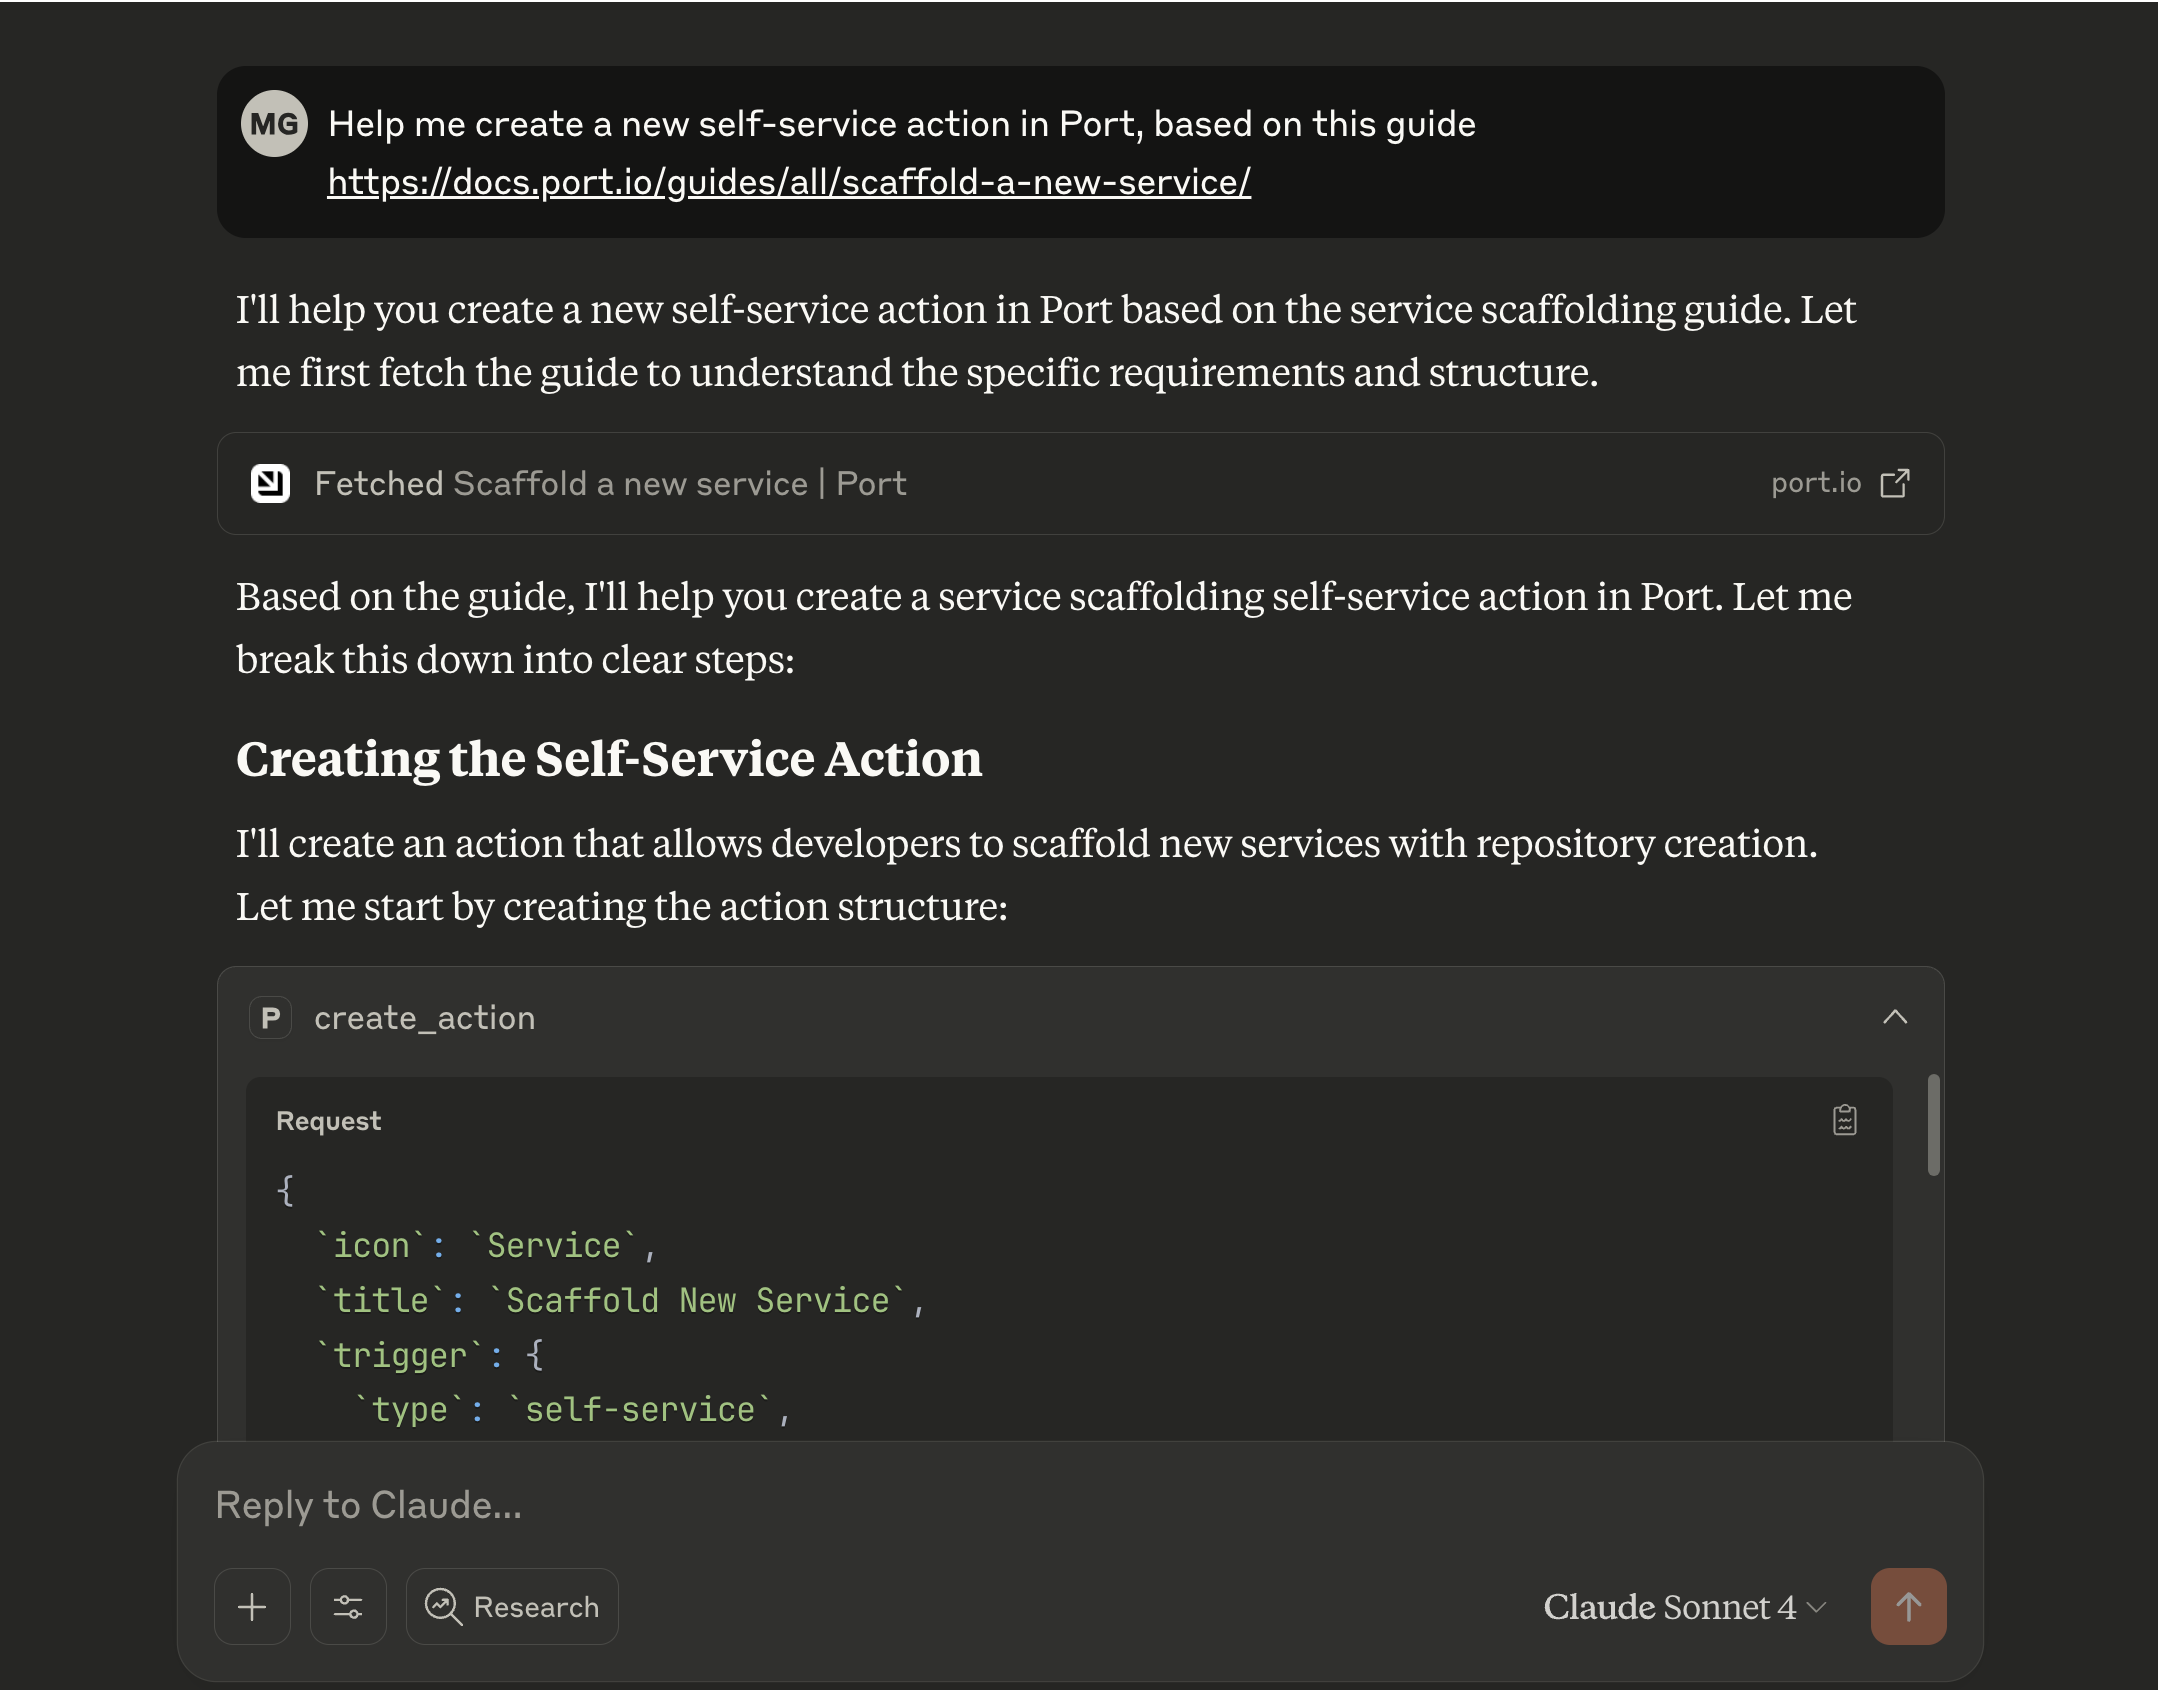
### Analyze scorecards and quality[](#analyze-scorecards-and-quality "Direct link to Analyze scorecards and quality")
Gain insights into service health, compliance, and quality by leveraging Port's scorecard data. Identify areas for improvement and track progress against your standards.
* Ask: "Which services are failing our security requirements scorecard?"
* Ask: "What's preventing the 'InventoryService' from reaching Gold level in the 'Production Readiness' scorecard?"
* Ask: "Show me the bug count vs. test coverage for all Java microservices."
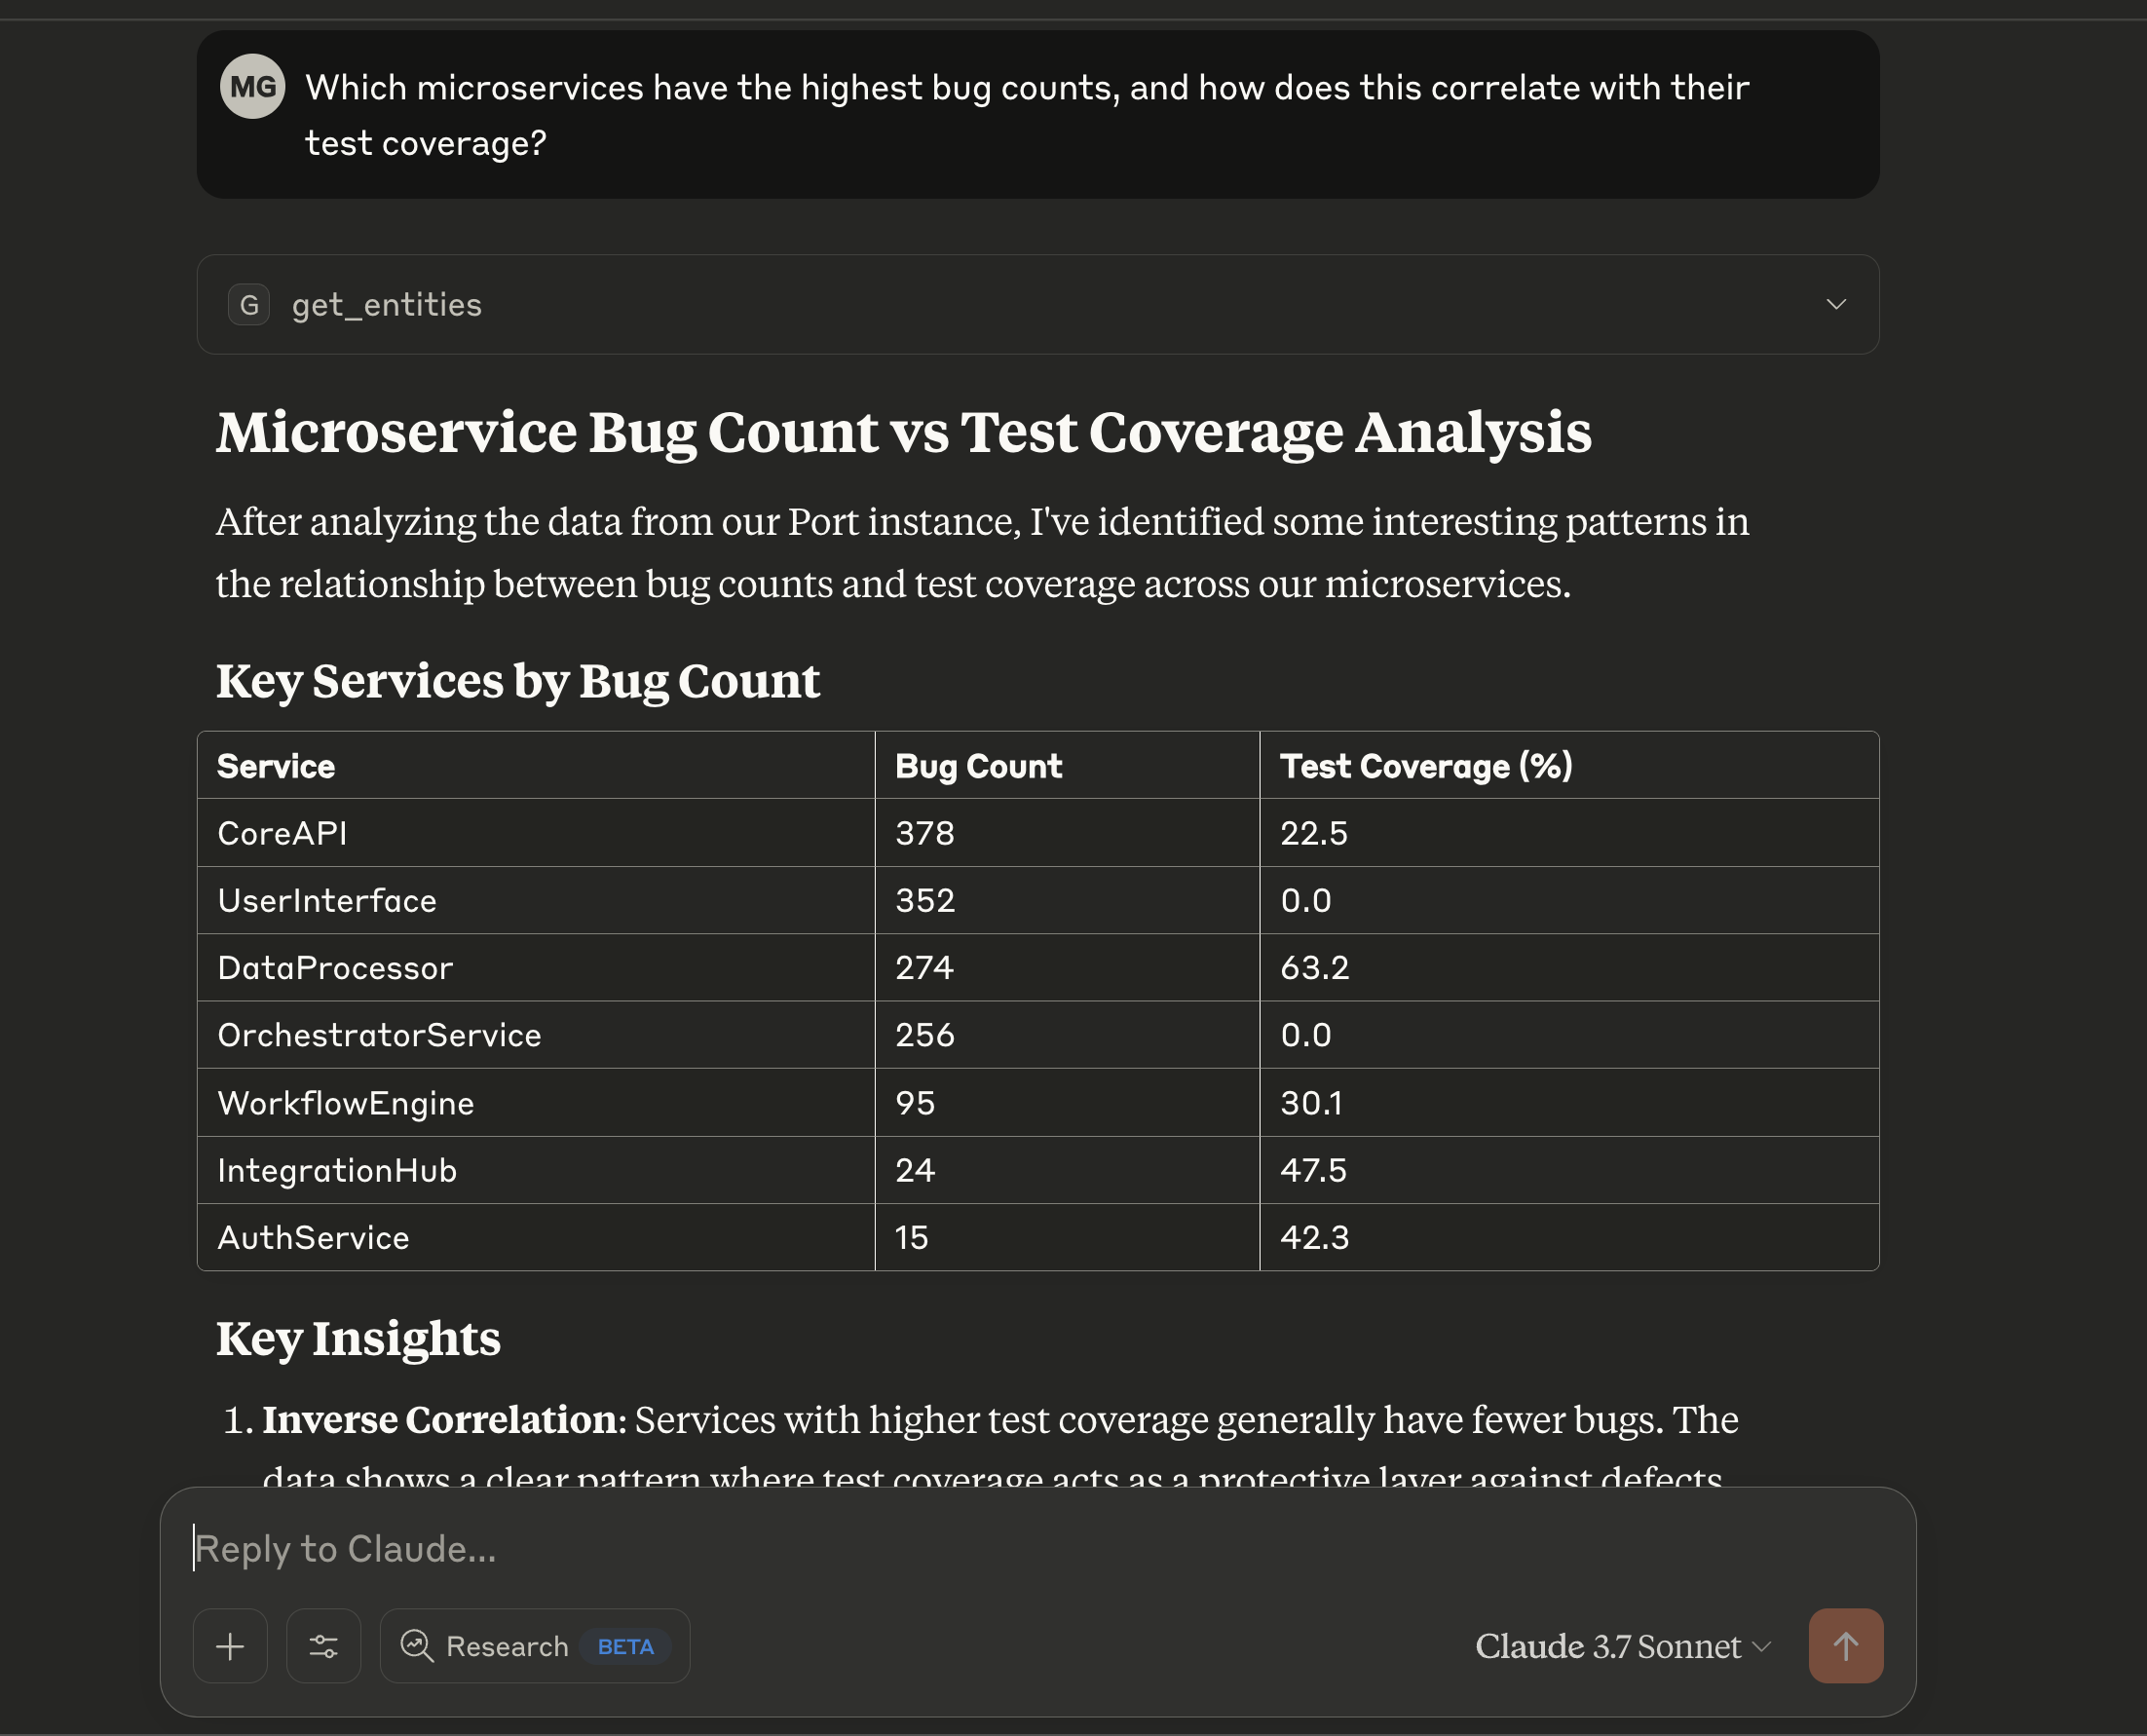
* Ask: "Which of our services are missing critical monitoring dashboards?"
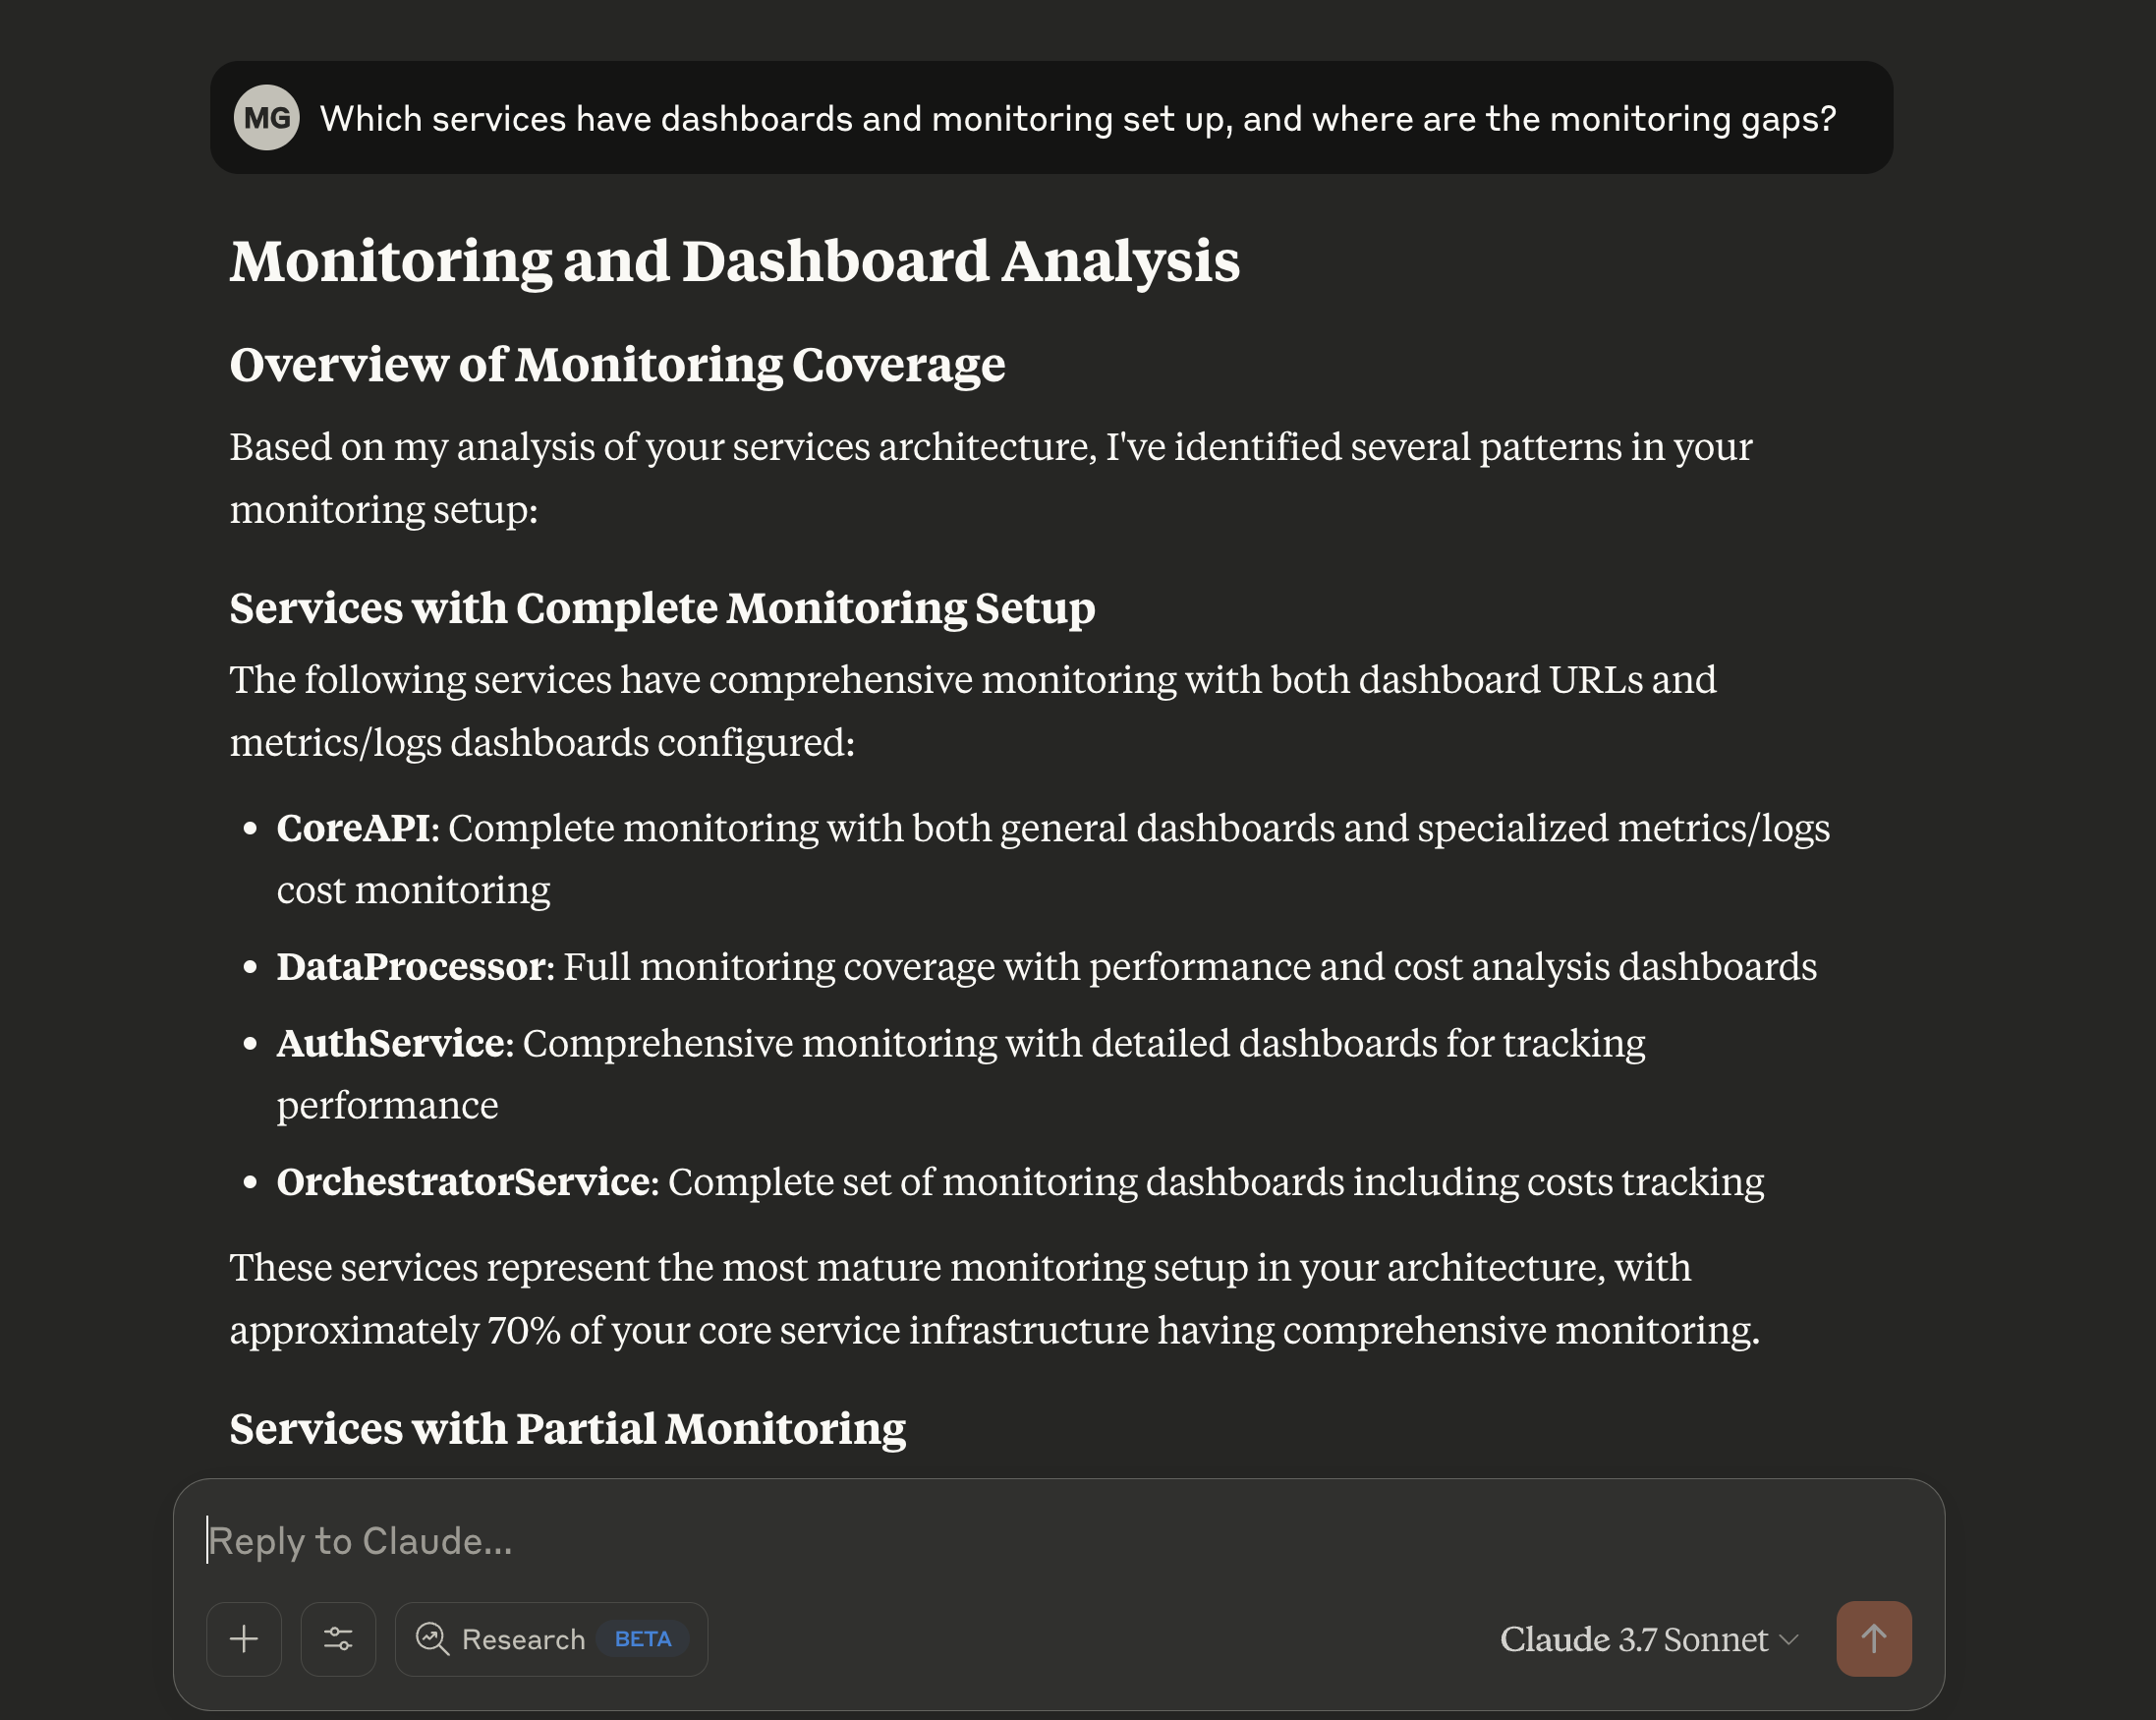
### Streamline development and operations[](#streamline-development-and-operations "Direct link to Streamline development and operations")
Receive assistance with common development and operational tasks, directly within your workflow.
* Ask: "What do I need to do to set up a new 'ReportingService'?"
* Ask: "Guide me through creating a new component blueprint with 'name', 'description', and 'owner' properties."
* Ask: "Help me add a rule to the 'Tier1Services' scorecard that requires an on-call schedule to be defined."
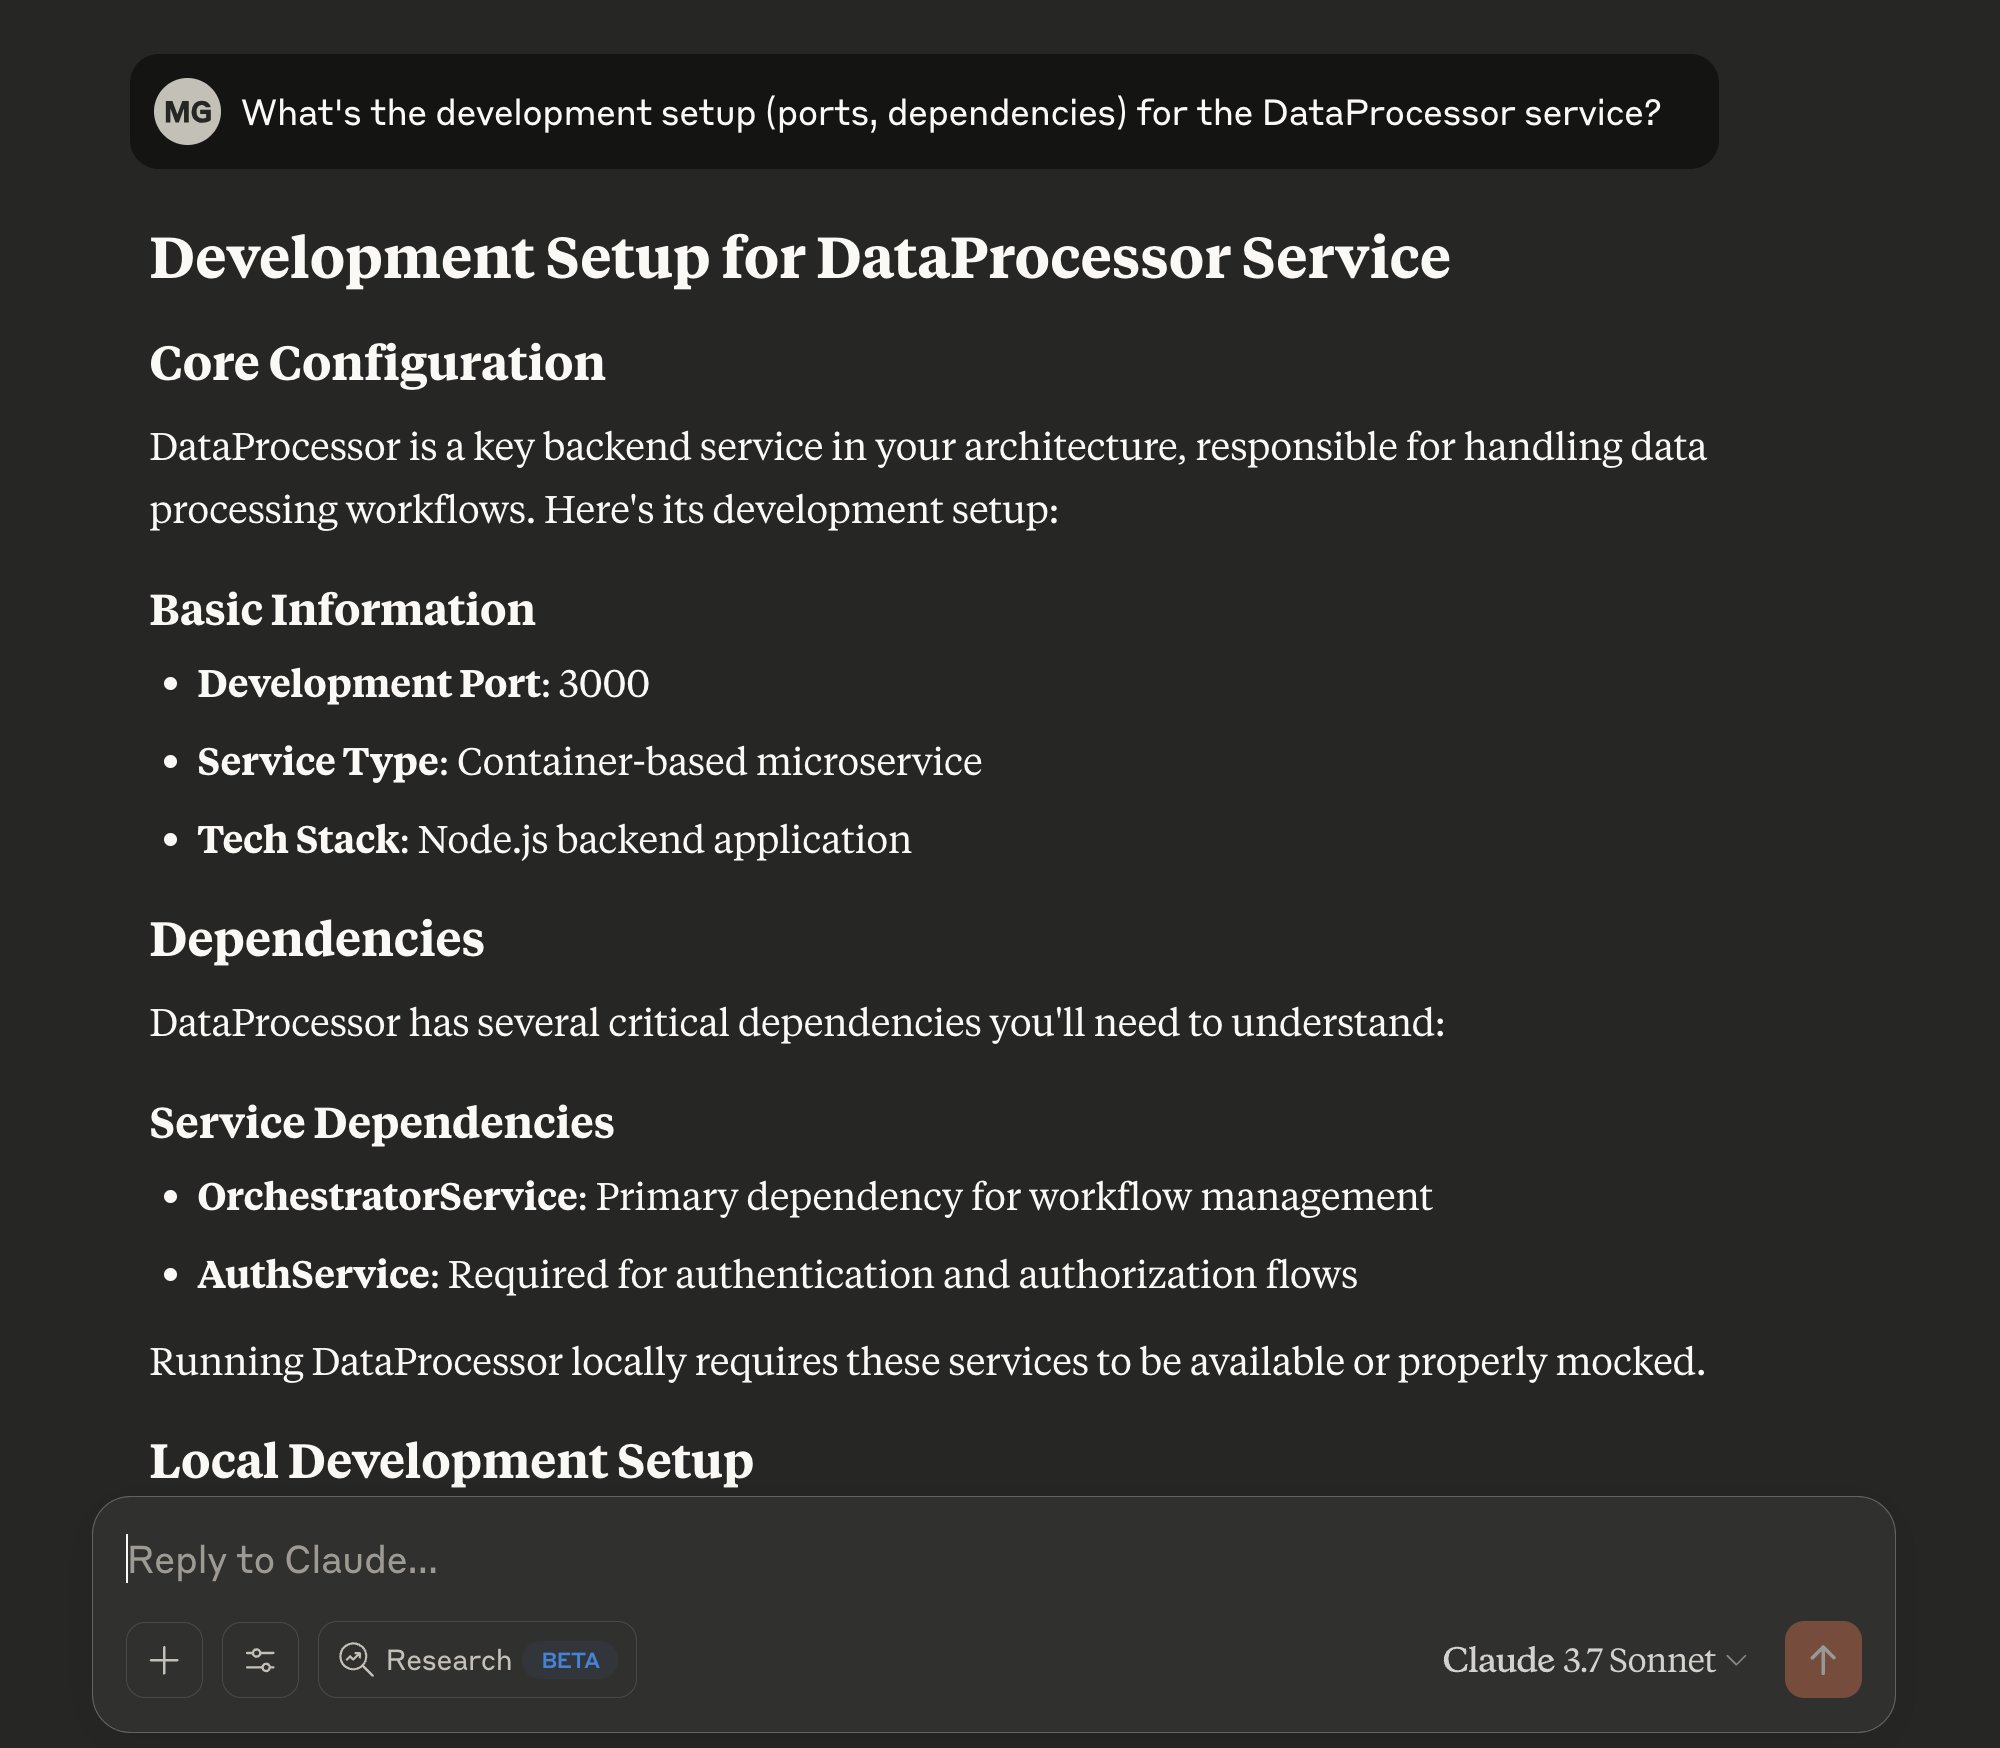
### Find your own use cases[](#find-your-own-use-cases "Direct link to Find your own use cases")
You can use Port's MCP to find the use cases that will be valuable to you. Try using this prompt: "think of creative prompts I can use to showcase the power of Port's MCP, based on the data available in Port"
## FAQ[](#faq "Direct link to FAQ")
1Who runs the LLM when I use the Port MCP server?
2Which permissions control Port MCP server access?
3What is the difference between the Port MCP server and Port AI?
## Getting started[](#getting-started "Direct link to Getting started")
Ready to connect your IDE or AI assistant to Port? See the [installation guide](/agent-management/port-mcp-server/installation/.md) for step-by-step setup instructions for Cursor, VS Code, GitHub Copilot, GitHub Copilot CLI, Claude, Codex CLI, and more.
For CI/CD pipelines and other automated environments, see [machine authentication](/agent-management/port-mcp-server/token-based-authentication/.md).
---
# Machine authentication for the Port MCP server
When you connect the Port MCP server from CI/CD pipelines, GitHub Actions, or other automated environments, interactive OAuth (browser login) is not practical. Port supports **machine-to-machine authentication** using your existing Port **client ID** and **client secret** through the MCP OAuth token endpoint.
## Authentication methods compared[](#authentication-methods-compared "Direct link to Authentication methods compared")
| Method | Best for | Long-lived secret | User consent |
| -------------------------------------------------- | ------------------------------------ | ------------------------------- | ------------ |
| Interactive OAuth (`authorization_code` + refresh) | Cursor, VS Code, Claude Desktop | Refresh token (up to \~30 days) | Yes |
| OAuth `client_credentials` (MCP token endpoint) | CI/CD, headless agents, `mcp-remote` | Port client ID + secret | No |
Long-lived vs short-lived credentials
Your **client ID** and **client secret** are long-lived. The **access token** they produce is short-lived (typically about 3 hours). Re-exchange your credentials when the token expires. There is no refresh token for the `client_credentials` grant.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
1. Create a Port **client ID** and **client secret** in your Port organization settings.
2. Use a dedicated service account credential for automation, not a personal user's credentials.
3. Store secrets in your CI secret manager. Never commit them to source control.
## Request an access token[](#request-an-access-token "Direct link to Request an access token")
Port's MCP server exposes a standards-compliant OAuth 2.0 token endpoint that accepts the `client_credentials` grant. It returns a machine JWT (`isMachine: true`) that you pass as a Bearer token when connecting to MCP.
### Discover supported grants[](#discover-supported-grants "Direct link to Discover supported grants")
```
curl -s "https://mcp.port.io/.well-known/oauth-authorization-server" | jq .
```
The response includes:
* `token_endpoint`: `https://mcp.port.io/v1/token`.
* `grant_types_supported`: `authorization_code`, `refresh_token`, `client_credentials`.
* `token_endpoint_auth_methods_supported`: `none`, `client_secret_post`, `client_secret_basic`.
US region
For US-hosted Port, replace `mcp.port.io` with `mcp.us.port.io`.
### Request a token (`client_secret_post`)[](#request-a-token-client_secret_post "Direct link to request-a-token-client_secret_post")
```
curl -s -X POST "https://mcp.port.io/v1/token" \
-H "Content-Type: application/x-www-form-urlencoded" \
-d "grant_type=client_credentials" \
-d "client_id=YOUR_CLIENT_ID" \
-d "client_secret=YOUR_CLIENT_SECRET"
```
Example response:
```
{
"access_token": "eyJ...",
"token_type": "Bearer",
"expires_in": 10800
}
```
### Request a token (`client_secret_basic`)[](#request-a-token-client_secret_basic "Direct link to request-a-token-client_secret_basic")
```
curl -s -X POST "https://mcp.port.io/v1/token" \
-H "Content-Type: application/x-www-form-urlencoded" \
-u "YOUR_CLIENT_ID:YOUR_CLIENT_SECRET" \
-d "grant_type=client_credentials"
```
### Connect with the token[](#connect-with-the-token "Direct link to Connect with the token")
Most automated setups use `mcp-remote` with a static Bearer header. Request a token from `/v1/token`, then pass it when connecting:
```
npx -y mcp-remote "https://mcp.port.io/v1" \
--header "Authorization: Bearer YOUR_ACCESS_TOKEN" \
--header "x-read-only-mode: 0"
```
If your MCP client supports OAuth machine-to-machine authentication natively, point it at the MCP server URL and let it handle token exchange against `/v1/token` using your Port client ID and secret.
Token lifecycle and rate limits
Access tokens expire (typically about 3 hours). Request a new token from `/v1/token` before expiry, or on `401` responses. Do not treat the access token itself as a long-lived secret.
The `client_credentials` grant is also rate-limited to 50 requests per 15 minutes per client. Cache tokens until they are close to expiry instead of requesting a new token on every MCP call.
## Example: Claude Code in GitHub Actions[](#example-claude-code-in-github-actions "Direct link to Example: Claude Code in GitHub Actions")
Here is a complete example showing how to connect Claude Code to the Port MCP server within a GitHub Actions workflow:
**Show example workflow (click to expand)**
.github/workflows/claude-code-mcp.yml
```
name: Port MCP Server Demo with Claude Code
on: workflow_dispatch
env:
PORT_MCP_URL: ${{ vars.PORT_MCP_URL }}
jobs:
demo:
runs-on: ubuntu-latest
permissions:
id-token: write
contents: read
steps:
- name: Checkout
uses: actions/checkout@v6
- name: Authenticate with Port
id: port-auth
run: |
response=$(curl -s -X POST "${{ env.PORT_MCP_URL }}/token" \
-H "Content-Type: application/x-www-form-urlencoded" \
-d "grant_type=client_credentials" \
-d "client_id=${{ secrets.PORT_CLIENT_ID }}" \
-d "client_secret=${{ secrets.PORT_CLIENT_SECRET }}")
token=$(echo "$response" | jq -r '.access_token')
echo "::add-mask::$token"
echo "access_token=$token" >> "$GITHUB_OUTPUT"
- name: Claude Code against Port MCP
uses: anthropics/claude-code-action@beta
with:
anthropic_api_key: ${{ secrets.ANTHROPIC_API_KEY }}
mode: agent
mcp_config: |
{
"mcpServers": {
"port-prod": {
"command": "npx",
"args": [
"mcp-remote",
"${{ env.PORT_MCP_URL }}",
"--header",
"Authorization: Bearer ${{ steps.port-auth.outputs.access_token }}",
"--header",
"x-read-only-mode: 0"
]
}
}
}
allowed_tools: "mcp__port-prod__list_blueprints,mcp__port-prod__get_entities"
direct_prompt: |
List all blueprints, then show entities of the "zendesk_ticket" blueprint.
```
### How this workflow works[](#how-this-workflow-works "Direct link to How this workflow works")
1. **Authentication** - The `port-auth` step exchanges your Port client credentials for a short-lived access token via `POST /v1/token` with `grant_type=client_credentials`.
2. **MCP connection** - Claude Code connects to the remote MCP server using the `mcp-remote` package, passing the access token in the `Authorization` header.
3. **Read-only mode** - The `x-read-only-mode` header defaults to `0`, which allows all tools based on your permissions. You can change it to `1` to restrict the MCP server to only expose read-only tools, completely hiding write tools from the available tools list.
4. **Action filtering** - The `x-allowed-actions-to-run` header (optional) allows you to control which actions are available through the `run_action` tool. It accepts a comma-separated list of action identifiers. For example, `x-allowed-actions-to-run: "create_github_issue,create_incident"` restricts access to only the specified actions.
5. **Tool access** - Claude Code can invoke only the specific Port tools listed in `allowed_tools`, ensuring controlled access to your Port instance.
6. **Execution** - The AI agent executes the provided prompt using the available Port tools to query your software catalog.
Customize your integration
For read-only workflows, you can change the `x-read-only-mode` header from `0` to `1` to restrict tools to read-only operations, or limit `allowed_tools` to just the query operations you need.
To control which actions are available, use the `x-allowed-actions-to-run` header with a comma-separated list of action identifiers. For example:
* `x-allowed-actions-to-run: "create_github_issue,merge_github_pr"` - Only the specified GitHub actions.
* `x-allowed-actions-to-run: "create_incident,send_notification"` - Only incident and notification actions.
Choose the appropriate MCP URL for your Port region (EU: `https://mcp.port.io/v1`, US: `https://mcp.us.port.io/v1`).
### Adapting for other AI agents[](#adapting-for-other-ai-agents "Direct link to Adapting for other AI agents")
While this example focuses on Claude Code, the same authentication pattern can be applied to other AI agents and platforms:
1. **Obtain Port credentials** - Create a client ID and secret in your Port dashboard.
2. **Generate access token** - Request a token from `POST /v1/token` with `grant_type=client_credentials`.
3. **Configure MCP connection** - Point your AI agent to the remote MCP server with the token.
4. **Define tool permissions** - Specify which Port tools the AI agent can access.
5. **Execute workflows** - Let the AI agent interact with your Port data and capabilities.
## When to use which method[](#when-to-use-which-method "Direct link to When to use which method")
* **Local IDE with browser login** - Use interactive OAuth from the [installation guide](/agent-management/port-mcp-server/installation/.md).
* **CI/CD or headless agents** - Request a token from `POST /v1/token` with `grant_type=client_credentials`, then pass it as a Bearer token.
* **MCP clients with native OAuth M2M support** - Configure the client to use the MCP server OAuth metadata so it handles token lifecycle automatically.
## Port API compatibility[](#port-api-compatibility "Direct link to Port API compatibility")
If you already obtain a machine token via the Port REST API (`POST /v1/auth/access_token`), you can use that same Bearer token with the MCP server. The MCP token endpoint returns the same JWT under the hood.
This is useful when a pipeline already authenticates against the Port API for other calls and you want to reuse the same token pattern. For new MCP integrations, prefer `POST /v1/token` so your auth flow stays within the MCP OAuth surface and supports discovery via `.well-known/oauth-authorization-server`.
## Security best practices[](#security-best-practices "Direct link to Security best practices")
* Use a dedicated automation credential with the minimum permissions needed.
* Rotate client secrets if they are exposed.
* Mask tokens in CI logs (for example, `::add-mask::` in GitHub Actions).
* Prefer `x-read-only-mode: 1` for read-only automation.
* Use `x-allowed-actions-to-run` to restrict which actions `run_action` can trigger.
---
# Visualize organization hierarchy
This guide demonstrates how to:
* Model the hierarchy tiers in your company.
* Create dedicated views for each tier, displaying relevant information.
## Data model overview[](#data-model-overview "Direct link to Data model overview")
Port allows you to model your team structure by connecting teams in a hierarchy using a single **Team** blueprint:
* **Team** represents any level in the hierarchy, from high-level groups to leaf-level teams that directly own resources.
* **Service** is used as an example throughout this guide for an entity owned by a team. Any blueprint that connects to teams (repositories, cloud resources, projects, etc.) can serve this role.
### Example hierarchies[](#example-hierarchies "Direct link to Example hierarchies")
The simplest hierarchy has two levels:
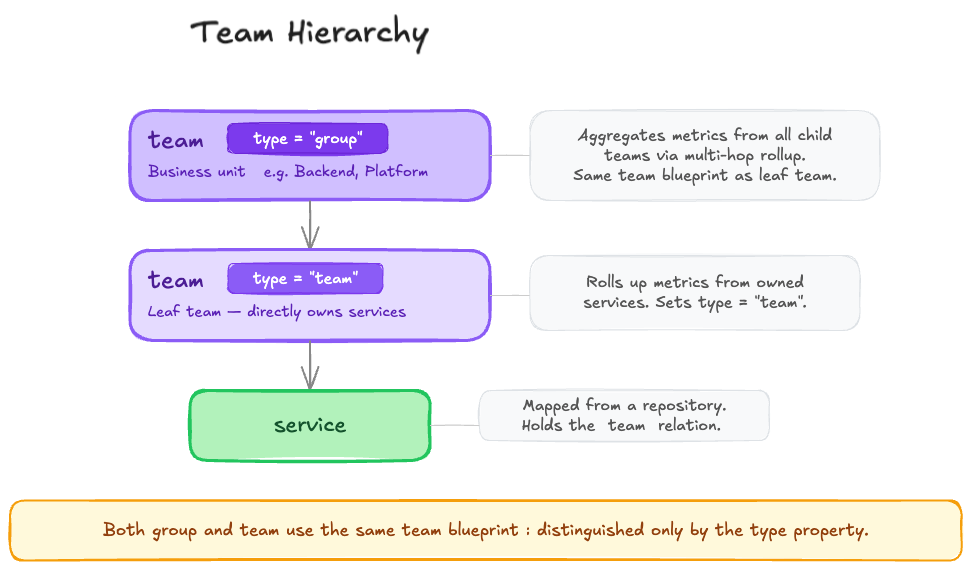
You can add more levels to match your needs by adding more enum values to the `type` property of the **Team** blueprint (which we will set up in the [section below](#extend-the-team-blueprint)).
Throughout this guide, we will use `Group > Team` as our example hierarchy, with **Service** as an example of an entity owned by a team, but any blueprint that connects to teams can play this role.
Other possible hierarchies could look like the following:
* `Department > Domain > Tribe > Squad > Service`
* `Department > Group > Unit > Team > Service`
Since every level is just a team entity with a `parent_team` relation, the setup works the same regardless of how many levels you have or what you call them.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
This guide assumes you have a Port account with admin access, and have completed the [onboarding process](https://docs.port.io/getting-started/overview).
## Set up data model[](#set-up-data-model "Direct link to Set up data model")
To support hierarchy tiers, we will extend the **Team** blueprint with a self-relation and a `type` property.
Already have this set up?
If your Team blueprint already has a `parent_team` self-relation and a `type` property, you can skip ahead to [Create dashboard](#create-dashboard) to further use the hierarchy in dashboards and widgets, or to [Next steps](#next-steps) to see what else you can build on top of it.
### Extend the Team blueprint[](#extend-the-team-blueprint "Direct link to Extend the Team blueprint")
The `Team` blueprint is available by default in Port. We need to extend it with a self-relation and a `type` property.
Perform the following steps to extend the `Team` blueprint:
**Add a self-relation**
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Search for the `Team` blueprint using the search bar.
3. Click on `+ New relation` at the bottom of the blueprint card.
4. Fill out the form as seen below, then click `Create`:
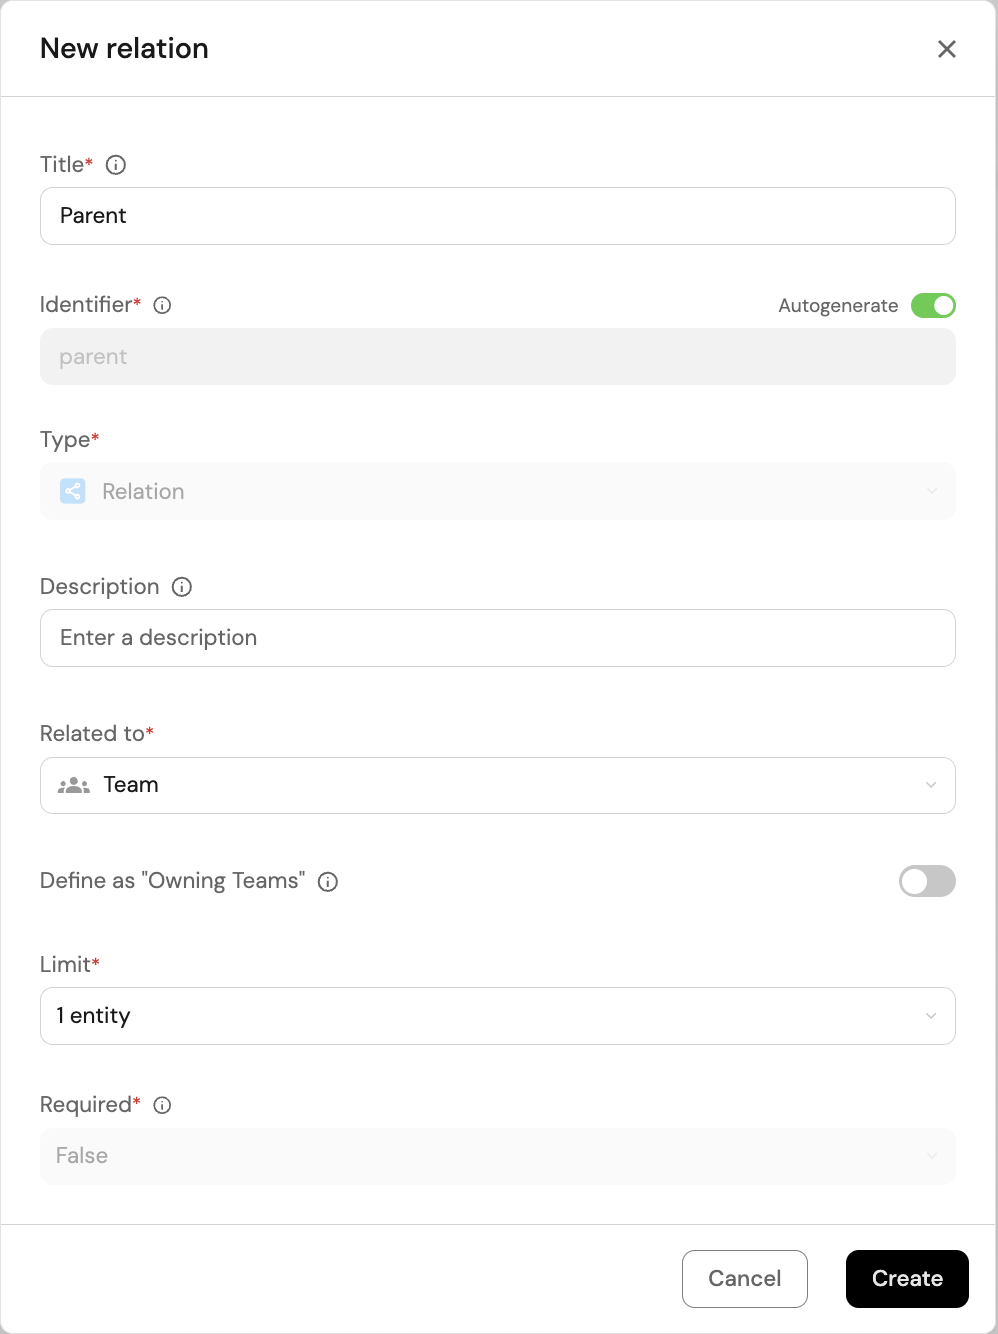
**Add a "type" property**
1. Click on `+ New property` in the `Team` blueprint card, and choose `Enum` as the property type.
2. Fill out the form with the options matching your hierarchy tiers, then click `Create`. This property is what distinguishes between hierarchy levels (e.g. "Group" vs "Team") and is also used for filtering in dashboard widgets.
You can use the following example:
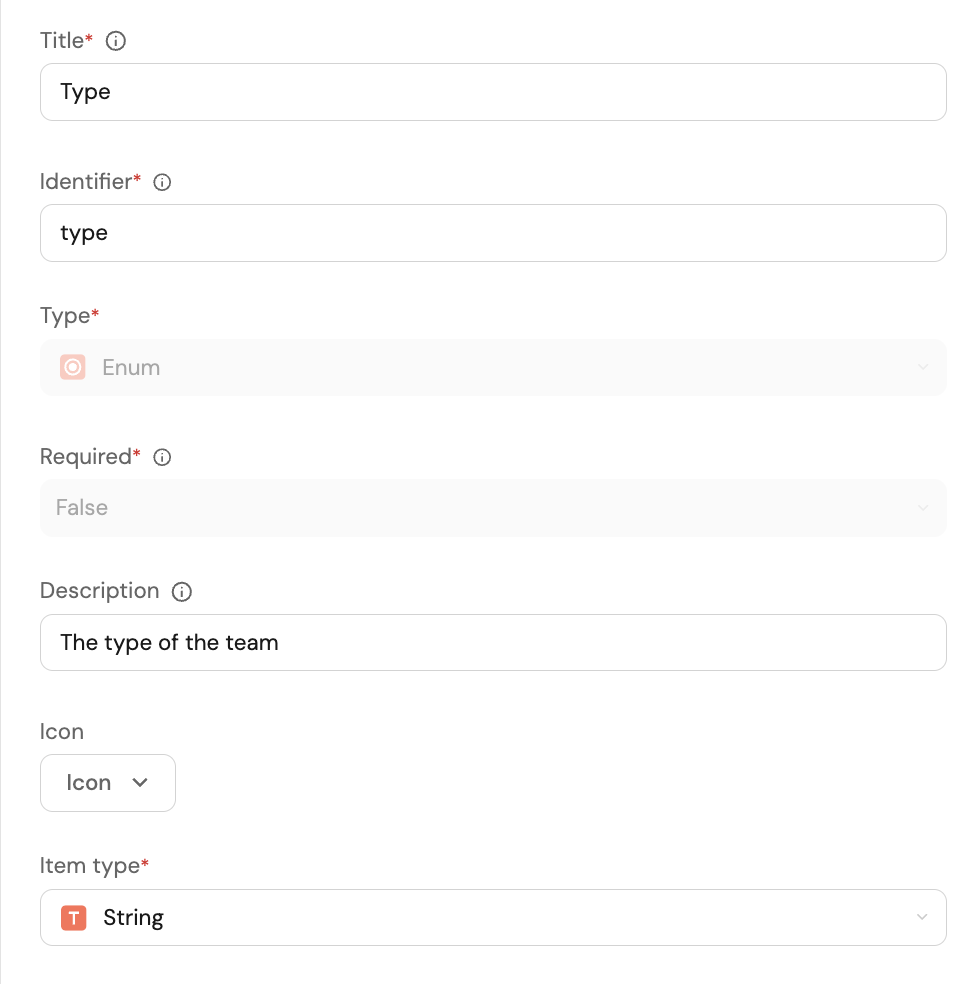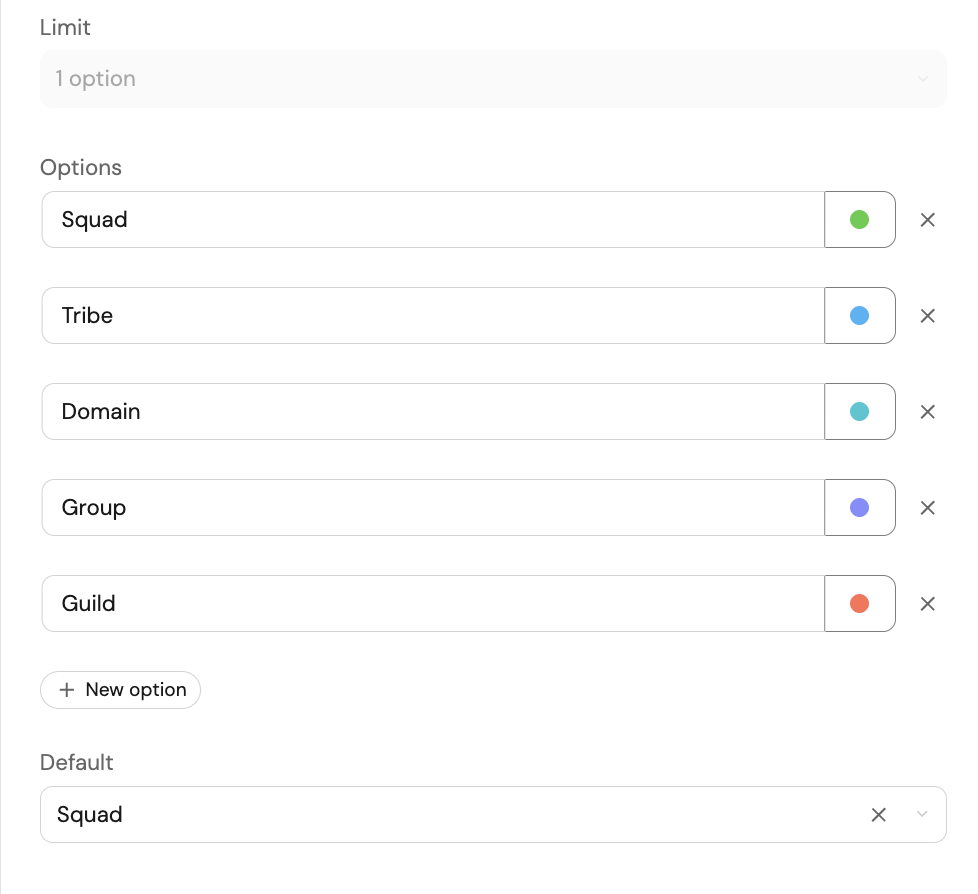
### Assign types & parent teams[](#assign-types--parent-teams "Direct link to Assign types & parent teams")
To finish setting up the data model, we need to assign each team a type and a parent team.
1. Click on the  button in the `Team` blueprint card to view all of your team entities.
2. Assign a type and a parent team to each team by hovering over the relevant property and clicking on the  button.
* Set groups to type `group` and teams to type `team`.
* Set each team's `parent_team` to its parent group.
Table properties
To make the process of assigning types and parent teams easier, you can use the  `Manage properties` button in the top-right corner of the table to hide other columns.
## Create dashboard[](#create-dashboard "Direct link to Create dashboard")
Now that our data model is set up, let's create a dedicated dashboard for group leads.
1. Go to the [catalog](https://app.port.io/catalog) page in Port.
2. In the left sidebar, click on `+`, then select `New dashboard`.
3. Name the dashboard "Group Lead". Optionally, give it a description and select an icon, then click `Create`.
Group membership requirement
The filters rely on the logged-in user's team membership, so users must be assigned to a team at the level the dashboard is scoped to. For this guide's example, that means being a member of a **Group**-level team.
Next, let's add two useful tables to the dashboard:
### Table 1: all of the group's teams[](#table-1-all-of-the-groups-teams "Direct link to Table 1: all of the group's teams")
The first table will display all of the teams under the group of the logged-in user.
1. Click on `+ Widget` in the top-right corner of the dashboard, then select `Table`.
2. Fill out the form as seen below:
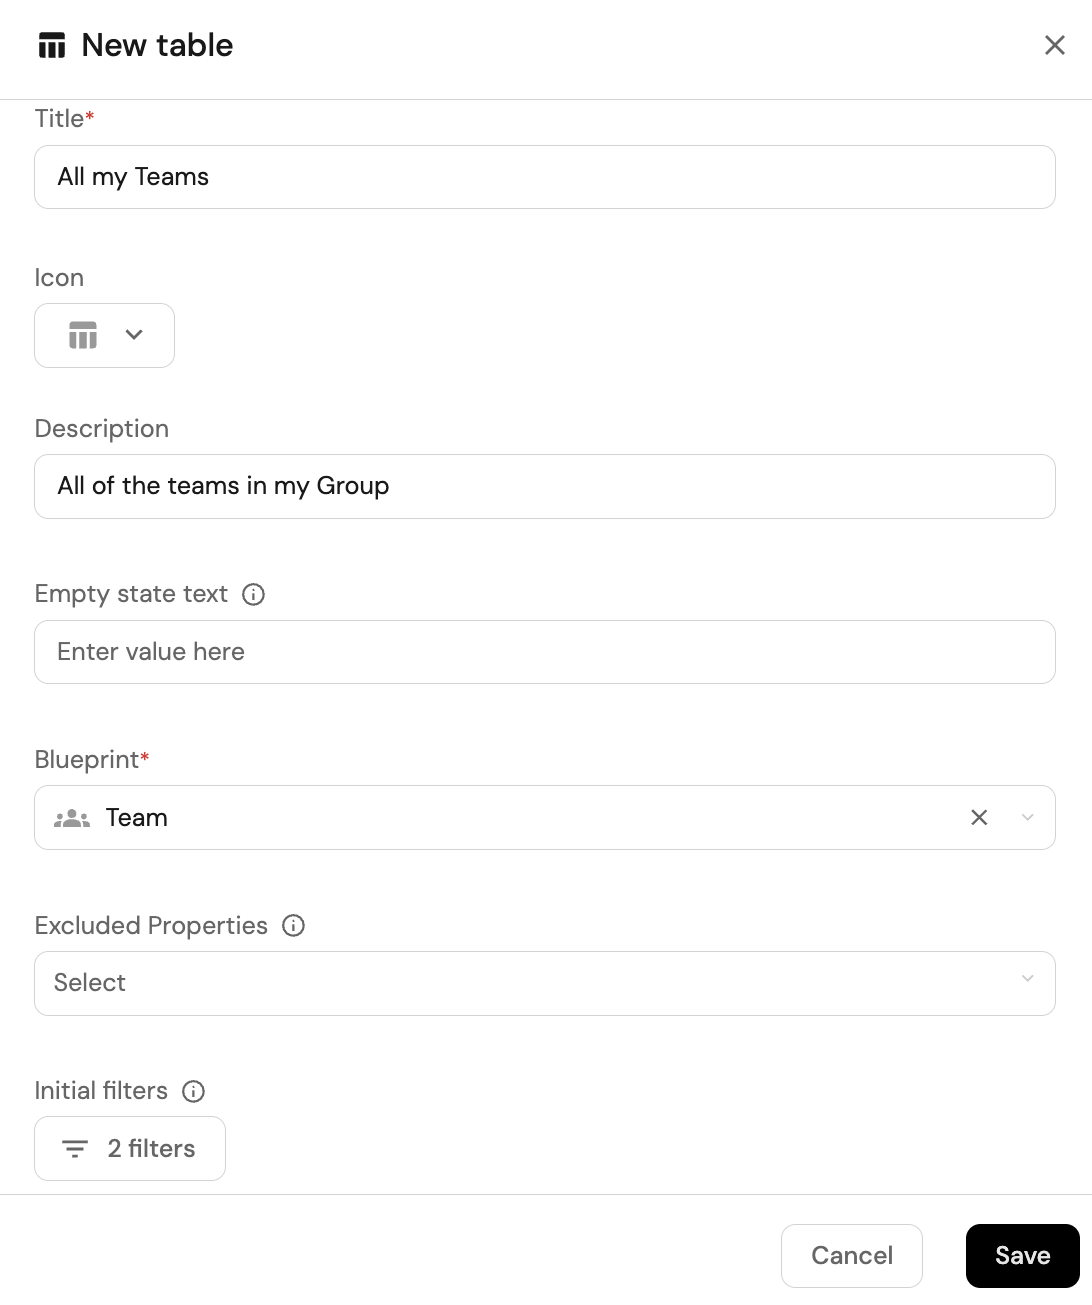
3. Define filters to ensure that only the relevant teams are displayed. Click on the `Filters` button.
4. Click on `Edit JSON`, and paste the following JSON. **Note: the filters in this table use contextual query rules, which can only be configured via JSON and not through the UI.**
```
{
"combinator": "and",
"rules": [
{
"value": "Team",
"property": "type",
"operator": "="
},
{
"operator": "matchAny",
"property": {
"path": [
{
"relation": "parent_team",
"maxHops": 1
}
]
},
"value": {
"context": "userTeams",
"property": "$identifier"
}
}
]
}
```
This JSON object defines two filters with an `AND` operator between them:
* The first filter ensures that only teams (not groups) are displayed.
* The second filter uses `matchAny` with [`maxHops`](/context-lake/consuming-the-lake/search-and-query/operators/relation-operators/.md#maxhops-limitation) to find teams that are one level below in the hierarchy via the `parent_team` self-relation. The value is resolved dynamically based on the logged-in user's team membership using a [contextual query rule](/context-lake/consuming-the-lake/search-and-query/operators/relation-operators/.md#self-relation). The value of `1` reflects the single level between groups and teams in this example - increase it to match the depth of your own hierarchy.
5. Click `Save` to save the filters, then click `Save` again to save the table.
### Table 2: all services owned by the group[](#table-2-all-services-owned-by-the-group "Direct link to Table 2: all services owned by the group")
1. Click on `+ Widget` in the top-right corner of the dashboard, then select `Table`.
2. Fill out the form as seen below:
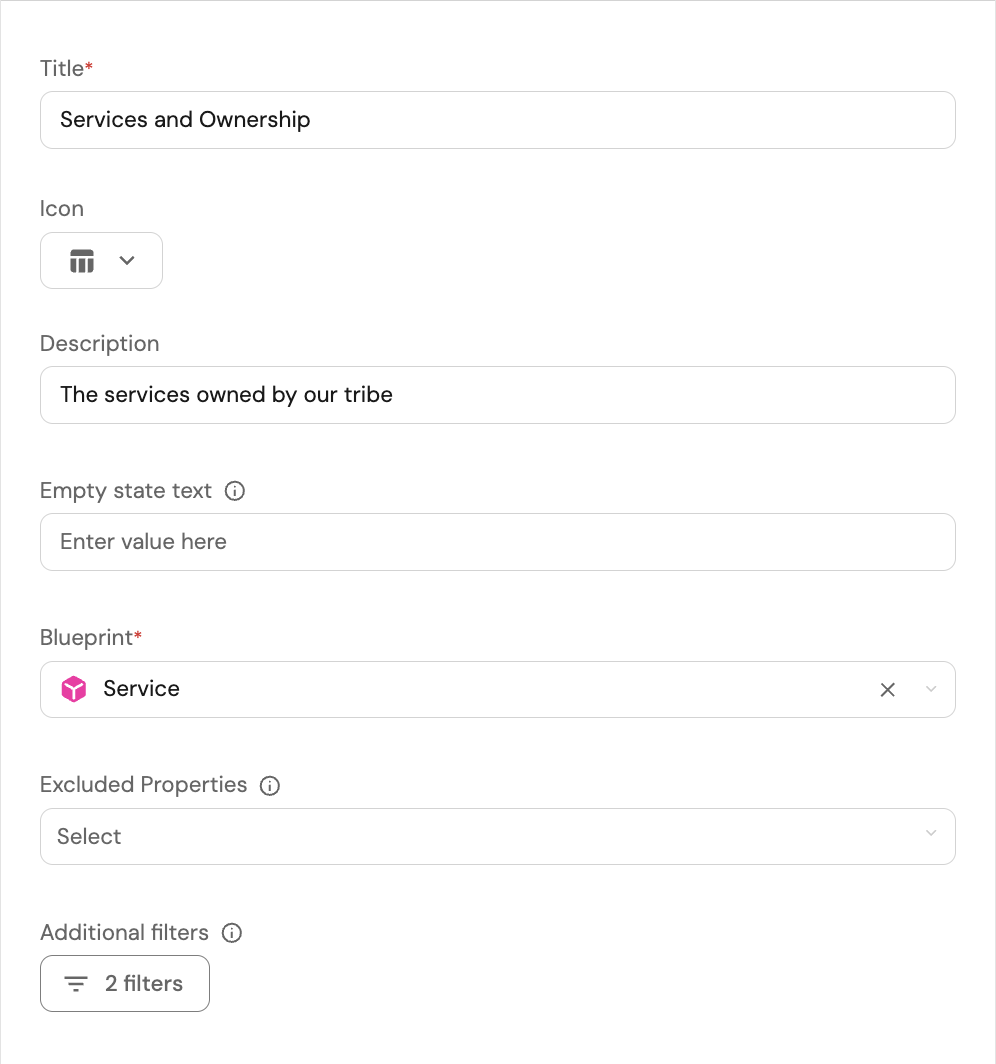
3. Define filters to ensure that only the relevant services are displayed. Click on the `Filters` button.
4. Click on `Edit JSON`, and paste the following JSON. **Note: the filters in this table use contextual query rules, which can only be configured via JSON and not through the UI.**
```
{
"combinator": "or",
"rules": [
{
"value": {
"context": "userTeams",
"property": "$identifier"
},
"property": "$team",
"operator": "containsAny"
},
{
"operator": "matchAny",
"property": {
"path": [
"$team",
{
"relation": "parent_team",
"maxHops": 1
}
]
},
"value": {
"context": "userTeams",
"property": "$identifier"
}
}
]
}
```
This JSON object defines two filters with an `OR` operator between them:
* The first filter matches services directly owned by one of the logged-in user's teams.
* The second filter uses `matchAny` with [`maxHops`](/context-lake/consuming-the-lake/search-and-query/operators/relation-operators/.md#maxhops-limitation) to find services whose owning team is one level below in the hierarchy via the `parent_team` self-relation. The value is resolved dynamically based on the logged-in user's team membership using a [contextual query rule](/context-lake/consuming-the-lake/search-and-query/operators/relation-operators/.md#self-relation).
* The value of `1` reflects the single level between groups and teams in this example - increase it to match the depth of your own hierarchy.
* Avoid using the `relatedTo` operator for this - it matches all paths between blueprints, not just the hierarchy path, which leads to unintended results and poor performance.
5. Click `Save` to save the filters, then click `Save` again to save the table.
Dashboard-level filters
If you want to apply a filter across all widgets displaying the same blueprint, you can define it once at the [dashboard level](/interface-builder/port-interface/page/dashboard-page/.md#dashboard-filters) instead of per widget.
## Advanced filter patterns[](#advanced-filter-patterns "Direct link to Advanced filter patterns")
The examples above use a simple hierarchy with services as the primary entity. This section covers how to adapt the same approach for more complex scenarios, different entity types, and visibility in both directions across the hierarchy.
### Executive visibility[](#executive-visibility "Direct link to Executive visibility")
A CTO wants one dashboard with all services, incidents, and metrics across the entire org, without being manually added to every team downstream and re-added whenever teams change.
To achieve that, assign the executive as a member of the **top-level team** in your hierarchy, then use the same filter as above with `maxHops` set to the full depth of your hierarchy:
**Filter: all services across the org (click to expand)**
```
{
"combinator": "or",
"rules": [
{
"value": {
"context": "userTeams",
"property": "$identifier"
},
"property": "$team",
"operator": "containsAny"
},
{
"operator": "matchAny",
"property": {
"path": [
"$team",
{
"relation": "parent_team",
"maxHops": 10
}
]
},
"value": {
"context": "userTeams",
"property": "$identifier"
}
}
]
}
```
* The first rule matches services directly owned by the executive's team.
* The second rule traverses up to 10 levels of `parent_team` relations, capturing services owned by any team in the hierarchy below. As long as your hierarchy does not exceed 10 levels, the dashboard will update automatically whenever teams are added or reorganized.
### Choosing the right filter property[](#choosing-the-right-filter-property "Direct link to Choosing the right filter property")
The `path` in your filter defines how Port traverses relations to reach the entity's owning team. The right path depends on how each entity type connects to teams.
**Filter by built-in `$team` relation**
Some entities, such as services, relate to a team through the built-in `$team` property. In that case, use `$team` as the starting point in the path, as shown in the examples above. This is the most common case.
**Filter by custom direct team relation**
Some entities have a custom relation to a team. For example, an incident blueprint may have a `supporting_team` relation. Since `$team` does not exist on incidents, use the relation's identifier directly in the path:
**Filter: incidents by custom team relation (click to expand)**
```
{
"combinator": "and",
"rules": [
{
"operator": "matchAny",
"property": {
"path": [
"supporting_team",
{
"relation": "parent_team",
"maxHops": 10
}
]
},
"value": {
"context": "userTeams",
"property": "$identifier"
}
}
]
}
```
**Filter by user-to-team traversal**
Some entities relate to a team indirectly through a user. For example, a pull request has an `author` relation to a User, and that user belongs to teams. To show a manager all pull requests by developers in their group, traverse from the entity through the user to the team:
**Filter: pull requests by user-to-team traversal (click to expand)**
```
{
"combinator": "and",
"rules": [
{
"operator": "matchAny",
"property": {
"path": [
"author",
"$team",
{
"relation": "parent_team",
"maxHops": 10
}
]
},
"value": {
"context": "userTeams",
"property": "$identifier"
}
}
]
}
```
**Filter by mirror property (indirect relation)**
If an entity relates to a team only through an intermediate entity, you cannot use `matchAny` to traverse that path. For example, a ServiceNow incident has no direct relation to a team - it relates to a ServiceNow service, which then relates to a team. In that case, `matchAny` path traversal will not work.
The solution is to add a [mirror property](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md) on the incident blueprint that reflects the owning team from the service (e.g. `service_owner` mirroring `service_now_service.$team`). Once the mirror property exists, you can filter directly against it using `containsAny`:
**Filter: incidents by mirror property (click to expand)**
```
{
"combinator": "and",
"rules": [
{
"value": {
"context": "userTeams",
"property": "$identifier"
},
"property": "service_owner",
"operator": "containsAny"
}
]
}
```
This works because the mirror property surfaces the owning team's identifier directly on the incident, making it filterable without needing to traverse relations.
**Filter by team lead relation**
Some organizations track leadership via a dedicated relation on the Team blueprint (e.g. `team_lead`) rather than through team membership. If yours does, you can scope dashboards to whoever is set as the lead of a team.
The filter traverses from the service up through its owning team, up the hierarchy, and then to the `team_lead` relation, matching against the current user:
**Filter: services by team lead (click to expand)**
```
{
"combinator": "and",
"rules": [
{
"operator": "matchAny",
"property": {
"path": [
"$team",
{
"relation": "parent_team",
"maxHops": 10
},
"team_lead"
]
},
"value": {
"context": "user",
"property": "$identifier"
}
}
]
}
```
## Next steps[](#next-steps "Direct link to Next steps")
Once your hierarchy is set up, you can:
* Create similar dashboards for managers of each tier in your hierarchy, where they can track and visualize useful information about the teams they are responsible for.
* Use the [View as](/platform-administration/users-and-teams/view-as-different-user/.md) feature to verify the filters work correctly from each user's perspective.
* Add additional widgets to the dashboard, such as:
* A pie chart showing the distribution of incidents across teams in your group.
* Number charts displaying the number of resolved issues per team in a given time period.
* A chart/table displaying the members of each team in your group, by role/name.
---
# Business context
Business context enriches your software catalog with the organizational, financial, and operational signals that help prioritize work, assess risk, and align engineering decisions with business objectives. It complements technical metadata by answering: *"What matters most to the business?"*
When AI agents and workflows understand this context, they can prioritize vulnerabilities by revenue impact, route incidents to the right owner, and enforce policies automatically — all without human triage.
## What business context includes[](#what-business-context-includes "Direct link to What business context includes")
### Cost and financial context[](#cost-and-financial-context "Direct link to Cost and financial context")
* **Cost center attribution** - track which department or budget owns each resource via [AWS Cost integration](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/.md) or [Kubecost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost/.md).
* **Revenue impact** - tag services that directly generate revenue or support revenue-generating features.
* **Cloud spending patterns** - understand resource costs to inform optimization and prioritization decisions.
### Criticality and risk context[](#criticality-and-risk-context "Direct link to Criticality and risk context")
* **Business criticality levels** - classify services (e.g. mission-critical, customer-facing, internal tooling) to drive different [SLA requirements](/guides/all/track-slos-and-slis-for-services/.md), triage workflows, and automation policies.
* **Disaster recovery tier** - define RTO/RPO requirements based on business impact to inform backup strategies and incident response priorities.
* **Data sensitivity** - mark resources handling PII, financial data, or regulated information to enforce compliance controls.
* **Compliance scope** - tag services subject to SOC 2, GDPR, HIPAA, or PCI-DSS to ensure audit readiness.
### Operational context[](#operational-context "Direct link to Operational context")
* **SLAs and SLOs** - define service-level agreements and objectives to measure reliability, track [MTTR](/guides/all/track-and-show-mtbf-for-services/.md), and ensure SLA compliance.
* **On-call ownership** - integrate [PagerDuty schedules](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/pagerduty/.md) to understand who is responsible right now for incident response.
* **Escalation policies** - define who to notify and when for different severity levels based on business impact.
### Organizational context[](#organizational-context "Direct link to Organizational context")
* **Team affiliation** - connect services to teams via [GitHub CODEOWNERS](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/) or [Jira project mappings](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira/examples/.md) for clear ownership.
* **Reporting hierarchy** - map organizational structure (team → department → division) for escalation paths.
* **Business unit alignment** - associate services with product lines or business units to understand impact radius.
### Customer and product context[](#customer-and-product-context "Direct link to Customer and product context")
* **Customer tier** - identify which customer segments are affected (e.g. enterprise, gold-tier, freemium) to prioritize incidents and features affecting high-value customers.
* **Product lifecycle stage** - tag services by maturity (closed beta, open beta, GA, deprecated) to set appropriate expectations and SLAs.
## Why business context matters[](#why-business-context-matters "Direct link to Why business context matters")
When AI agents and workflows have access to business context, they can:
* **Prioritize vulnerabilities** affecting revenue-generating production services over internal dev tools.
* **Route incidents** to the right on-call engineer based on service ownership and escalation policies.
* **Estimate blast radius** of a deployment by understanding dependent services and their business criticality.
* **Automatically enforce policies** like "critical services must have SLOs defined" or "PII-handling services require SOC 2 compliance checks".
* **Calculate risk scores** that combine technical severity (CVSS) with business impact (criticality, revenue, SLA, customer tier).
* **Adjust incident response** based on affected customer tier - a P1 incident affecting enterprise customers triggers immediate executive notification, while the same issue in closed beta may follow standard on-call procedures.
## Examples[](#examples "Direct link to Examples")
* Risk-based vulnerability triage
* Context-aware incident routing
* Disaster recovery policy enforcement
**Scenario:** A critical CVE is discovered in a library used by multiple services.
**Without business context:** The security team gets hundreds of alerts with no clear way to prioritize which services to patch first.
**With business context in Port:**
1. Port enriches each vulnerability with:
* Service **business criticality** (mission-critical vs. internal).
* **Revenue impact** (directly revenue-generating or not).
* **SLA requirements** (99.99% uptime vs. best-effort).
* **Data sensitivity** (handles customer PII or not).
* **Compliance scope** (subject to SOC 2 audit).
* **Customer tier** (enterprise vs. freemium).
2. An AI agent or automation calculates a **risk score**:
```
Risk = CVE Severity × (Business Criticality + Revenue Impact + SLA Weight + Compliance Factor + Customer Tier)
```
3. Results in a prioritized triage queue:
* **Fix immediately**: Payment service (mission-critical, revenue-generating, 99.99% SLA, PCI-DSS scope, enterprise customers).
* **Fix this sprint**: Customer portal (customer-facing, revenue-supporting, 99.5% SLA, gold-tier customers).
* **Backlog**: Internal dev tools (low criticality, no SLA, internal users only).
**Scenario:** A production API starts returning 500 errors during business hours.
**Without business context:** A generic "production down" alert leads to manual escalation and wasted time finding the right owner.
**With business context in Port:**
1. Port's incident automation queries the context lake for:
* Service **on-call schedule** from PagerDuty.
* Service **business criticality** and **SLA** (99.99% uptime).
* **Revenue impact** (payment processing = revenue-blocking).
* **Customer tier affected** (enterprise customers experiencing errors).
* **Product lifecycle stage** (GA with 10,000+ active users).
* **Recent deployments** (was there a recent change?).
2. Automation takes action based on context:
* **Closed beta, freemium users**: page on-call engineer via standard PagerDuty workflow.
* **GA, enterprise customers**: immediate P1 escalation → page incident captain, notify VP Engineering, create executive war room.
3. Result: faster MTTR and an appropriate response because both responders and escalation paths match business impact.
*Learn more:* [Deploy incident updates with n8n](/guides/all/ai-powered-incident-management/.md#generate-incident-updates-with-ai).
**Scenario:** A platform team needs to ensure all mission-critical services have disaster recovery plans.
**Without business context:** Manual spreadsheet tracking leads to inconsistent enforcement and audit findings.
**With business context in Port:**
1. Services are tagged with:
* **Business criticality** (mission-critical, high, medium, low).
* **Disaster recovery tier** (Tier 1: RTO < 1hr, Tier 2: RTO < 4hr, Tier 3: RTO < 24hr).
* **Customer tier impact** (affects enterprise vs. freemium).
* **Product lifecycle** (GA services have stricter DR requirements than beta).
2. A Port automation enforcement policy:
```
IF service.businessCriticality == "mission-critical"
AND service.productLifecycle == "GA"
AND service.disasterRecoveryTier != "Tier 1"
THEN fail_scorecard("Missing DR Plan")
AND create_jira_ticket(owner, "Define DR plan with RTO < 1hr for GA mission-critical service")
```
3. A scorecard dashboard shows:
* 12/15 mission-critical GA services have Tier 1 DR plans.
* 3 services out of compliance → auto-created tickets assigned to owners.
* Beta services excluded from strict DR requirements until GA launch.
## How to ingest business context[](#how-to-ingest-business-context "Direct link to How to ingest business context")
Business context comes from many sources:
* **Cloud providers** - cost data via [AWS Cost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/.md) and [Kubecost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost/.md).
* **Incident management** - on-call schedules via [PagerDuty](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/pagerduty/.md) and [ServiceNow](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/servicenow/.md).
* **Source control** - team ownership via [GitHub CODEOWNERS](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/) and [GitLab](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab/.md).
* **Project management** - business unit and stakeholders via [Jira](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira/examples/.md).
* **Manual enrichment** - business criticality, revenue impact, SLAs, customer tier, and product lifecycle added as blueprint properties and updated via [self-service actions](/workflows/actions-and-automations/setup-backend/github-workflow/.md) or [API](/api-reference/port-api/).
## How to model business context in Port[](#how-to-model-business-context-in-port "Direct link to How to model business context in Port")
Some of the most valuable catalog context is knowledge that already exists in your organization but is scattered across teams and tools. The following patterns show how to capture that context in Port so humans, workflows, and agents can use it consistently.
### Set up ownership[](#set-up-ownership "Direct link to Set up ownership")
Ownership answers "who is responsible for this service right now." It enables routing, escalation, approvals, and accountability across the SDLC.
If you use Port's default components, start with the default ownership model and extend it to match your org.
To go deeper, see [Ownership in Port](/context-lake/business-context/ownership/.md) and [Default blueprints](/context-lake/data-model/setup-blueprint/default-blueprints/.md).
### Set up service criticality and tiers[](#set-up-service-criticality-and-tiers "Direct link to Set up service criticality and tiers")
Criticality and tiering help you prioritize engineering work and apply different policies by service importance - for example, incident response expectations, approval requirements, or compliance checks.
Model criticality as a property on the entities you care about (for example, services) and use scorecards and workflows to enforce stricter standards for high-criticality services.
### Set up team assignments[](#set-up-team-assignments "Direct link to Set up team assignments")
Team assignments capture how services, repositories, and infrastructure map to teams. This supports routing, dashboards, and agent workflows that need to know which team owns an asset.
To go deeper, see [Manage users and teams](/platform-administration/users-and-teams/manage-users-teams/.md) and [Ownership in Port](/context-lake/business-context/ownership/.md).
### Set up tags and labels[](#set-up-tags-and-labels "Direct link to Set up tags and labels")
Tags and labels let you slice your catalog consistently - for example, by domain, environment, customer impact, or compliance scope.
Use blueprint properties to model the tags you care about, then use [search and query](/context-lake/consuming-the-lake/search-and-query/overview/.md) to filter entities by those tags.
### Add custom metadata[](#add-custom-metadata "Direct link to Add custom metadata")
Custom metadata is where you capture organization-specific signals that are not available from integrations - for example, support tier, internal readiness gates, or ownership exceptions.
To go deeper, see [Set up blueprints](/context-lake/data-model/setup-blueprint/overview/.md).
---
# Manage ownership in Port
Ownership in Port defines who is responsible for specific entities in your internal developer portal — such as services, repositories, or incidents.
Managing ownership correctly ensures clear accountability, smoother collaboration, and accurate reporting.
Ownership in Port is represented through relationships between **users**, **teams**, and **catalog entities**.
This page outlines how to manage ownership in Port, from syncing users and teams to assigning them to catalog entities, and visualizing the data.
## How does it work?[](#how-does-it-work "Direct link to How does it work?")
When creating a Port account, some default blueprints are created for you. Two of them are the `User` and `Team` blueprints, which are used to represent your users and teams.
Using these blueprints, we can define ownership of resources in the software catalog to specific users or teams.
Defining ownership in Port is composed of several steps:
1. [Sync Users](#sync-users) - the first step in managing ownership is syncing your users from 3rd party tools into Port, and connecting to the relevant Port user. This allows you to have a single component in your portal that represents your user across your entire ecosystem.
2. [Sync Teams](#sync-teams) - just like users, teams from 3rd party tools can be synced into Port, and connected to the relevant Port teams.
3. [Assign Users to Teams](#assign-users-to-teams) - once Port users and teams are synced and connected to each other, users can get visibility into the resources owned by their team/s.
4. [Assign Teams to Catalog Entities](#assign-teams-to-catalog-entities) - define ownership of resources in your catalog to Port teams.
For example, a GitHub repository can be owned by the `frontend` team.
5. [Assign Users to Catalog Entities](#assign-users-to-catalog-entities) - define ownership of resources in your catalog to Port users.
For example, a PagerDuty incident can be owned by the current `on-call` user.
## How ownership is defined in your catalog[](#how-ownership-is-defined-in-your-catalog "Direct link to How ownership is defined in your catalog")
Under the hood, Port represents ownership using two mechanisms on a blueprint: the `ownership` property, and the `$team` meta-property that is available on every entity.
### The `team` meta-property[](#the-team-meta-property "Direct link to the-team-meta-property")
The value returned by the `$team` meta-property depends on the [ownership type](#the-ownership-property) defined for the blueprint - it will be empty for blueprints with no ownership, directly set for blueprints with Direct ownership, or inherited for blueprints with Inherited ownership.
Each entity has a [meta-property](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md) named `team`, that stores which teams own the entity.
As an `admin`, you can also set blueprint permissions according to this field.
The `team` meta-property is an array of the owning teams' `identifiers`.
Here is an example entity:
```
{
"identifier": "pod-1",
"title": "Awesome pod",
"team": ["some-team-identifier", "another-team-identifier"],
"blueprint": "Pod",
"properties": {
...
},
"relations": {}
}
```
#### Reference an entity's team[](#reference-an-entitys-team "Direct link to Reference an entity's team")
In places where you need to reference an entity's team, use `$team` to reference the meta-property.
For example, in a search query:
```
{
"operator": "containsAny",
"property": "$team",
"value": ["team-identifier"]
}
```
### The `ownership` property[](#the-ownership-property "Direct link to the-ownership-property")
All blueprints have an `ownership` property that tells Port how to set team ownership for its entities.
This field is not mandatory.
Terraform support
The `ownership` property is also supported in Terraform starting from version **2.1.4**.
These are the available options for the `ownership` property:
1. **No ownership**
The blueprint has no defined ownership.
The `$team` property will have no meaningful value.
```
{
"identifier": "packageVersion",
"title": "Package Version",
...
}
```
2. **Direct**
Ownership of the blueprint's entities will be defined by a hidden [relation]() to the `Team` blueprint.
The `Owning teams` column will be visible in tables containing entities of the blueprint.
Direct ownership supports [multi source ingestion](#multi-source-ingestion-for-owning-teams), so multiple sources can each own a slice of the owning teams.
```
{
"identifier": "packageVersion",
"title": "Package Version",
"ownership": {
"type": "Direct"
}
...
}
```
3. **Inherited**
Ownership of the blueprint's entities will be inherited from a different related blueprint with `Direct` ownership.
The `Owning teams` column will be visible in tables containing entities of the blueprint, but will not be editable.
The `path` key is a dot-separated path of **relation identifiers** that lead to the desired blueprint.
```
{
"identifier": "packageVersion",
"title": "Package Version",
"ownership": {
"type": "Inherited",
"path": "relationIdentifier1.relationIdentifier2.relationIdentifier3"
}
...
}
```
You can also change the `title` of the ownership property. The default value is `Owning teams`.
```
{
"identifier": "packageVersion",
"title": "Package Version",
"ownership": {
"type": "Direct",
"title": "My Custom Ownership Title"
}
...
}
```
### Multi source ingestion for owning teams[](#multi-source-ingestion-for-owning-teams "Direct link to Multi source ingestion for owning teams")
By default, setting an entity's `team` replaces the full list of owning teams. Enable **Multi source ingestion** on a blueprint with `Direct` ownership to let multiple [connectors](/context-lake/ingestion/overview/.md) or API callers each own a slice of the owning teams without overwriting each other.
In the [Data model](https://app.port.io/settings/data-model) page, turn on **Multi source ingestion** when setting the blueprint's ownership to `Direct`. In the API, set `"union": true` on the ownership property.
Cannot be changed later
This setting cannot be changed after ownership is set to `Direct`.
```
{
"identifier": "packageVersion",
"title": "Package Version",
"ownership": {
"type": "Direct",
"union": true
}
...
}
```
#### Example[](#example "Direct link to Example")
The `service` blueprint has multi source ingestion enabled on its ownership. For an entity of that blueprint:
1. **Monday** - the GitHub integration writes `{ "github": ["frontend-team"] }`.
2. **Tuesday** - the PagerDuty integration writes `{ "pagerduty": ["oncall-team"] }` without removing GitHub's team.
3. **Wednesday** - Alice edits the entity in the UI and adds `platform-team`. Port saves her changes under `user:alice`.
A **GET** returns the merged, deduplicated `$team` meta-property:
```
{
"identifier": "checkout-service",
"team": ["frontend-team", "oncall-team", "platform-team"]
}
```
Each writer only updates its own source key.
#### Write and read values[](#write-and-read-values "Direct link to Write and read values")
**Write** (`POST`, `PATCH`, `PUT`) - send one source key per update, mapped to an array of team identifiers:
```
{
"team": {
"github": ["frontend-team"]
}
}
```
Use `null` instead of an array to clear a source's slice.
Source keys must match `^[A-Za-z0-9._:@/-]{1,128}$`.
**Read** (`GET`, search) - Port returns the merged, deduplicated `$team` meta-property, same as regular ownership.
In the UI, you edit the assembled list of owning teams directly. Port stores UI edits under `user:{userId}` automatically.
Consistent with relations and array properties
Multi source ingestion works the same way for [relations](/context-lake/data-model/setup-blueprint/relate-blueprints/.md#multi-source-ingestion) and [array properties](/context-lake/data-model/setup-blueprint/properties/array/.md#multi-source-ingestion): each writer owns a source key, and reads return the deduplicated combination of all sources.
#### Constraints[](#constraints "Direct link to Constraints")
* Only available on blueprints with `Direct` ownership.
* Cannot be changed after ownership is set to `Direct`. Create a new ownership configuration and migrate the values instead.
* Sending a plain array, multiple source keys, or an invalid source key returns `422`.
## Sync users[](#sync-users "Direct link to Sync users")
Users can be synced into Port either manually or automatically, depending on your integrations.
**Note** that when using an SSO provider, users and teams are synced automatically.
**Automatically**:
* **Built-in integrations**: Update the integration mapping to connect the Port user to the integration user:
* GitHub
* GitLab
* Azure DevOps
* Jira
```
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .login
title: .login
blueprint: '"_user"'
relations:
git_hub_user: .login
```
```
- kind: group-with-members
selector:
query: 'true'
includeBotMembers: 'true'
includeInheritedMembers: 'true'
port:
itemsToParse: .__members
entity:
mappings:
identifier: .item.username
title: .item.name
blueprint: '"_user"'
relations:
gitlab_user: .item.username
```
```
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: '.id'
title: '.user.displayName'
blueprint: '"_user"'
relations:
azure_devops_user: '.id'
```
```
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .accountId
title: .displayName
blueprint: '"_user"'
relations:
jira_user: .accountId
```
* **Custom integrations**: We can create a simple automation to link new Port users to the matching integration user upon creation:
* [Slack](https://docs.port.io/guides/all/map-external-users-and-teams-to-port-accounts?integration=slack#slack-sync-slack-users-when-a-new-port-user-is-added)
* [ServiceNow](https://docs.port.io/guides/all/map-external-users-and-teams-to-port-accounts?integration=servicenow#servicenow-sync-servicenow-users-when-a-new-port-user-is-added)
* [HiBob](https://docs.port.io/guides/all/map-external-users-and-teams-to-port-accounts?integration=hibob#hibob-sync-hibob-users-when-a-new-port-user-is-added)
**Manually**:
* [**Self-service Action (SSA)**]() – [Register your user](https://app.port.io/self-serve?action=_onboard_your_user) An out-of-the-box self service action used to register the logged-in user in Port, connecting it to the relevant 3rd party user/s.
* **Register a new user**
This can be done from the [Users catalog page](https://app.port.io/_users):
Click on the `+ User` button, then click on `Register existing user`.
This is useful for inviting a new user and defining their relations to 3rd party users in a single step.
* **Edit an existing user entity**
This can also be done from the [Users catalog page](https://app.port.io/_users):
Click on the `...` button, then click on `Edit`.
Ideal when updating a user with new data — for example, connecting it to a Slack user.
**Custom integrations**:
3rd party tools for which Port does not have a built-in integration can be synced manually using the following guides:
* [Slack](https://docs.port.io/guides/all/map-external-users-and-teams-to-port-accounts?integration=slack)
* [ServiceNow](https://docs.port.io/guides/all/map-external-users-and-teams-to-port-accounts?integration=servicenow)
* [HiBob](https://docs.port.io/guides/all/map-external-users-and-teams-to-port-accounts?integration=hibob)
## Sync teams[](#sync-teams "Direct link to Sync teams")
Teams can also be synced into Port either manually or automatically, depending on your integrations and conventions.
**Note** that when using an SSO provider, teams are synced automatically.
**Automatically**:
* **Built-in integrations**:
Using the integration mapping, we can define how to create/update teams in Port.
For example, the following mapping can be used to create/update teams using GitHub:
```
- kind: team
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id | tostring
title: .name
blueprint: '"_team"'
relations:
git_hub_team: .id | tostring
```
In this example, if the team already exists in Port, it will be connected to the GitHub team with the same identifier.
If it does not exist, it will be created and connected to the GitHub team with the same identifier.
**Manually**:
* **Register a new team**
This can be done from the [Teams catalog page](https://app.port.io/_teams):
Click on the `+ Team` button.
This is useful for creating a new team and defining its relations to 3rd party teams in a single step.
* **Edit an existing team entity**
This can also be done from the [Teams catalog page](https://app.port.io/_teams):
Click on the `...` button, then click on `Edit`.
Ideal when updating a team with new data — for example, connecting it to a Sentry team.
## Assign users to teams[](#assign-users-to-teams "Direct link to Assign users to teams")
In many cases, ownership is assigned to a team and not a specific user. By default, Port allows you to assign one or more owning teams to each entity in your catalog.
As a user, it's important to see all of the resources owned by you or your team/s. Therefore, the next step is to ensure that all Port users are assigned to the relevant team/s.
**Automatically**:
* When using SSO, users and teams are created and connected automatically.
* When using Entra ID, you can use this [integration tool](https://github.com/port-experimental/entra-id-provisioner) to sync users and teams into Port.
* When using Gitlab or ADO integrations, you can connect Port team to Port user when fetching the integration's teams.
For example, the following mapping connects a team in Port to a user in Port based on the GitLab association (assuming the GitLab group is already mapped to the Port team):
```
- kind: group-with-members
selector:
query: 'true'
includeBotMembers: 'true'
includeInheritedMembers: 'true'
port:
itemsToParse: .__members
entity:
mappings:
identifier: .item.email
title: .item.name
team: .full_path
blueprint: '"_user"'
```
**Manually**:
* [**Self-service action (SSA)**]() – [Add team members](https://app.port.io/self-serve?action=_onboard_existing_team)
An out-of-the-box self service action used to add users to an existing team.
* **Edit a user entity**
This can be done from the [Users catalog page](https://app.port.io/_users):
Click on the `...` button, then click on `Edit`.
* When creating/inviting a new user from the UI, you can assign them to teams as part of the creation process.
## Assign teams to catalog entities[](#assign-teams-to-catalog-entities "Direct link to Assign teams to catalog entities")
**Automatically**:
* If using GitHub, you can use the [team-mapper](https://github.com/port-experimental/repo-team-mapper) script to map repositories to teams based on commit history.
* If an entity has an property or relation that contains the integration team identifier (e.g., GitHub repository → `github-teams`), update the mapping so that the `github-teams` value will automatically be set in `owning teams`.
```
- kind: repository
selector:
query: 'true'
teams: true
port:
entity:
mappings:
identifier: .full_name
title: .name
blueprint: '"githubRepository"'
properties:
readme: file://README.md
url: .html_url
defaultBranch: .default_branch
$team: '[.teams[].id | tostring]'
relations:
githubTeams: '[.teams[].id | tostring]'
```
Note that this assumes Port team identifiers match GitHub team identifiers.
**Manually**:
* [**Self-service action (SSA)**]() – [Own services](https://app.port.io/self-serve?action=set_ownership)
An out-of-the-box self service action used to assign ownership of one or more services to a specific team.
* **Edit an entity**
This can be done from the entity's relevant catalog page:
Click on the `...` button, then click on `Edit`, and change the `Owning teams` field.
* When creating a new entity, assign its owning team(s) as part of the creation process.
## Assign users to catalog entities[](#assign-users-to-catalog-entities "Direct link to Assign users to catalog entities")
In some cases, ownership needs to be assigned to a specific user and not a team. For example, a PagerDuty incident may be owned by the current on-call user, or a GitHub Pull Request may be owned by the creator.
**Automatically**:
In many Port integrations, blueprints can have out-of-the-box relations to the **3rd party user blueprint**, with a default mapping configuration that automatically sets the value of this relation.
Additionally, some blueprints have out-of-the-box relations to the **Port user blueprint**, with a default mapping configuration that automatically sets the value of this relation as well.
Here are some common examples:
* The `GitHub Pull Request` blueprint has a default relation ("git\_hub\_creator") to the **GitHub user** that created the PR.
Additionally, it has a default relation ("creator") to the **Port user** associated with the GitHub user that created the PR.
* The `Jira Issue` blueprint has a default relation ("reporter") to the **Port user** that reported the issue.
* The `PagerDuty Incident` blueprint has a default relation ("assignee") to the **Port user** that is assigned to the incident.
**Manually**:
* **Edit an entity**
If a blueprint has a relation to the Port user blueprint, you can edit the entity from its catalog page and change the value of this relation:
Click on the `...` button, then click on `Edit`, and change the relation value.
## Visualize user & team data[](#visualize-user--team-data "Direct link to Visualize user & team data")
Now that we have set up ownership in our catalog, let's see how we can visualize it in useful ways.
### Default pages & filters[](#default-pages--filters "Direct link to Default pages & filters")
* By default, the following pages are available in your catalog:
* **User entity page**: View all Port users and their related 3rd-party users and the Port teams they belong to.
* **Team entity page**: View all Port teams and their related 3rd-party teams.
* In any table or chart, you can use the `My Teams` or `My` filters to show only entities that belong to your teams or are owned by you.
### User management dashboard[](#user-management-dashboard "Direct link to User management dashboard")
Now let's create a dedicated dashboard to manage users and ownership of entities in your catalog.
This dashboard will allow you to:
* View which users are assigned to which team/s.
* View which users from 3rd-party tools are connected to which Port user/s.
* View which teams from 3rd-party tools are connected to which Port team/s.
* View which services are owned by which team/s.
* Execute several [**self-service actions**]() to onboard users to teams, register new users, and assign ownership of services to teams.
### Create a dashboard[](#create-a-dashboard "Direct link to Create a dashboard")
1. Navigate to your [software catalog](https://app.port.io/organization/catalog).
2. Click on the `+` button in the left sidebar.
3. Select **New dashboard**.
4. Name the dashboard **Ownership Management**.
5. Input `Manage and onboard your users and teams` under **Description**.
6. Select the `Users` icon.
7. Click `Create`.
We now have a blank dashboard where we can start adding widgets to visualize ownership insights.
#### Add widgets[](#add-widgets "Direct link to Add widgets")
In the new dashboard, create the following widgets:
**Users assignment (click to expand)**
1. Click `+ Widget` and select **Table**.
2. Title: `Users assignment`.
3. Choose **User** as the **Blueprint**.
4. Click `Save`.
5. Click on the **`...`** button in the top right corner of the table and select **Customize table**.
6. Define the visible columns to include the user title, team, and third parties associated user.
7. Click on the **save icon** in the top right corner of the widget to save the customized table.
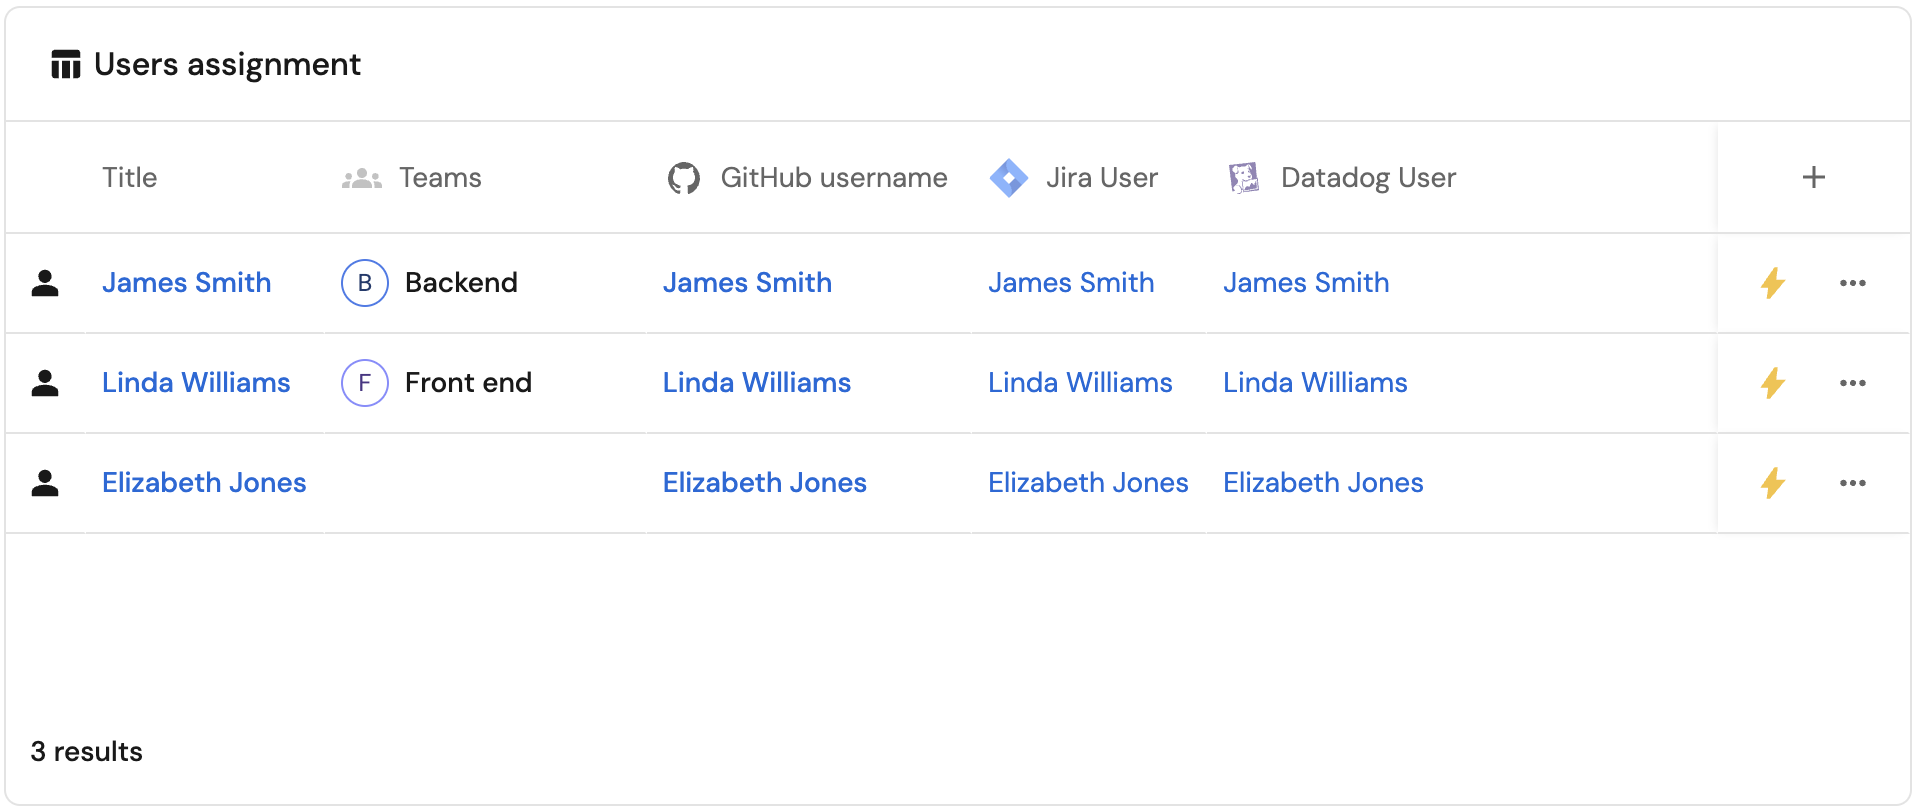
***
**Users with no teams (click to expand)**
1. Click **`+ Widget`** and select **Pie chart**.
2. Title: `Users with no teams`.
3. Choose the **User** blueprint.
4. Under `Breakdown by property`, select the **Ownership - Has Team** property
5. Click **Save**.

***
**Teams assignment (click to expand)**
1. Click **`+ Widget`** and select **Table**.
2. Title: `Teams assignment`.
3. Choose the **Team** blueprint.
4. Click **Save**.
5. Click on the **`...`** button in the top right corner of the table and select **Customize table**.
6. Define the visible columns to include the team's title, and third parties associated teams.
7. Click on the **save icon** in the top right corner of the widget to save the customized table.

***
**Services ownership (click to expand)**
1. Click **`+ Widget`** and select **Table**.
2. Title the widget **Services ownership**.
3. Choose the **Service** blueprint
4. Click **Save** to add the widget to the dashboard.
5. Click on the **`...`** button in the top right corner of the table and select **Customize table**.
6. Define the visible columns to include the service title and the owning teams.
7. Click on the **save icon** in the top right corner of the widget to save the customized table.
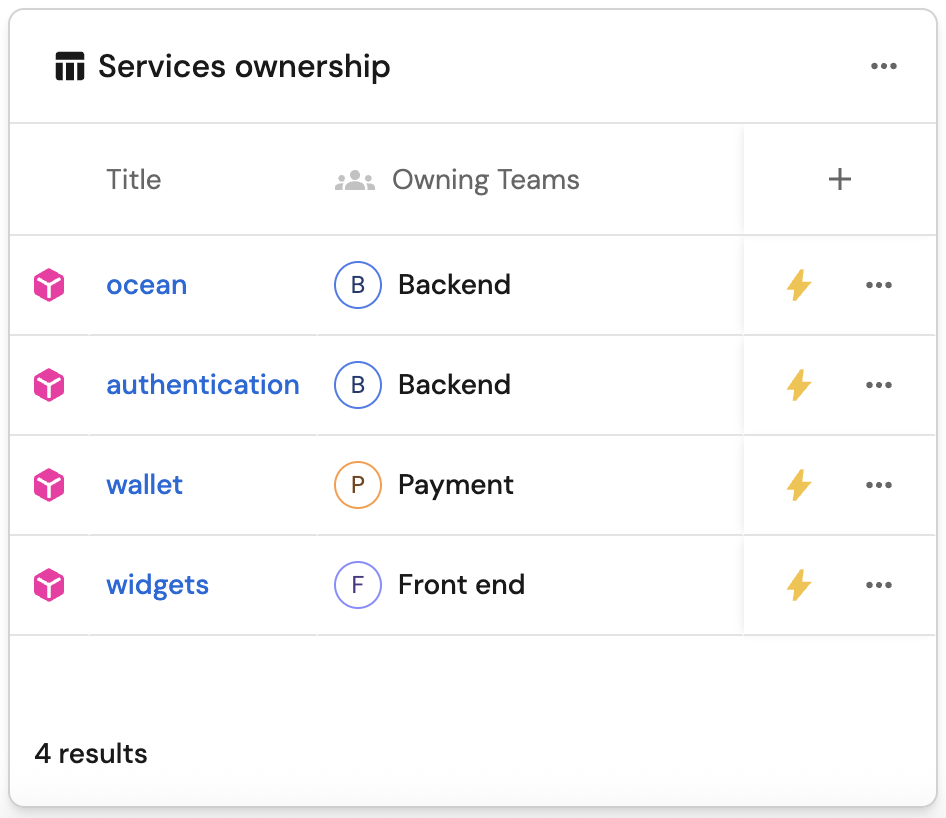
***
**Ownership management actions (click to expand)**
1. Click **`+ Widget`** and select **Action Card**.
2. Under `Actions`, select all the Ownership management actions we created:
* **Add team members**
* **Register your user**
* **Own services**
3. Title: `Ownership management`.
4. Click **Save**.
---
# Examples
In this section we'll show you a few examples of ways to use catalog permissions in your organization, and how to apply them.
## Use cases[](#use-cases "Direct link to Use cases")
The following configurations, among others, are available when using catalog permissions management:
1. Entities can be made immutable/partially immutable (can only read/create/delete/modify) for specific users/roles. For example:
1. `Deployment` entities are immutable for all roles, and `Cluster` entities are editable only by the blueprint **Moderators**.
2. **Members** can create a new `Microservice` entity, but are not permitted to delete a `Microservice` entity.
2. Each entity property/relation can be **readable** or **immutable** separately for specific users/roles. For example, the `repository_link` property can be immutable for all roles (except **Admin**).
3. Allow specific users/roles to **read** or **modify** only entities [owned by their team](#setting-permissions-by-team-ownership). For example, **Members** can edit only `Microservices` that belong to their team.
4. Action execution permissions can be given to specific users or roles. For example, you can allow every **Member** to create a new `Deployment` entity, however only `Deployment` **Moderators** can perform a day-2 action of "adding resources".
## Setting blueprint permissions[](#setting-blueprint-permissions "Direct link to Setting blueprint permissions")
To set permissions for a blueprint, click on the permissions button of the desired blueprint on the Data model page. This will open a modal that contains the permissions JSON and allows you to control every operation that can be performed on the blueprint or its entities.
### Role examples[](#role-examples "Direct link to Role examples")
* Let member register entity
* Only let admin update property
If you want to enable **Members** to register entities of a blueprint, you can change the JSON as follows:
```
{
"entities": {
"register": {
"roles": ["Admin", "Env-moderator", "Member"], // changed from ["Admin", "Env-moderator"]
"users": [],
"teams": [],
"ownedByTeam": false
}
}
}
```
To allow only **Admins** to change the property `slackChannelUrl`, remove the Moderator role:
```
{
"entities": {
"updateProperties": {
"slackChannelUrl": {
"roles": ["Admin"], // changed from ["Admin", "Env-moderator"]
"users": [],
"teams": [],
"ownedByTeam": false
}
}
}
}
```
### User examples[](#user-examples "Direct link to User examples")
* Let user edit relation
To grant permissions for a specific user to edit the `deployedAt` relation, add them to the users array:
```
{
"entities": {
"updateRelations": {
"deployedAt": {
"roles": ["Admin", "Env-moderator"],
"users": ["some-user@myorg.com"], // changed from []
"teams": [],
"ownedByTeam": false
}
}
}
}
```
### Team examples[](#team-examples "Direct link to Team examples")
* Let team edit relation
To grant permissions for a specific team to edit the `deployedAt` relation, add them to the teams array:
```
{
"entities": {
"updateRelations": {
"deployedAt": {
"roles": ["Admin", "Env-moderator"],
"users": [],
"teams": ["serviceMaintainers"],
"ownedByTeam": false
}
}
}
}
```
### Team ownership examples[](#team-ownership-examples "Direct link to Team ownership examples")
Some operations have the `ownedByTeam` flag. This allows you to set permissions by team ownership, rather than by roles or direct assignment to users.
For example, the following JSON will allow **every user**, regardless of their role, to perform the action `delete_env` on `Env` entities that belong to a team they are a part of (entities that have the `team` property set):
```
{
"actions": {
"delete_env": {
"execute": {
"roles": ["Admin", "Env-moderator"],
"users": [],
"teams": [],
"ownedByTeam": true // changed from false
}
}
}
}
```
### Inherited ownership[](#inherited-ownership "Direct link to Inherited ownership")
Inherited ownership allows you to utilize relations to automatically assign and manage entity ownership.
By using inherited ownership, you can configure entities to automatically inherit their ownership from entities they are related to.
Inherited ownership can be configured by setting the `ownership` property in the [blueprint structure](/context-lake/data-model/setup-blueprint/relate-blueprints/.md#structure-table) with `"type": "Inherited"`.
The `path` key represents the relation path to the blueprint whose entity's teams we want to inherit.
* The `path` key is a dot-separated path of **relation identifiers** that lead to the desired blueprint.
* The target blueprint must have `Direct` ownership configured.
* Inherited ownership can only be configured using a path of [`single`](/context-lake/data-model/setup-blueprint/relate-blueprints/.md#single-relation-structure) type relations.
For example, the following JSON (added to the **blueprint definition**) will configure the `myBlueprint` blueprint's entities to inherit their ownership from the `myExtraRelatedBlueprint` blueprint's entities:
```
{
"identifier": "myBlueprint",
// ...blueprint properties
"ownership": {
"type": "Inherited",
"path": "myRelatedBlueprint.myExtraRelatedBlueprint"
}
}
```
In the example above, the relation chain is: `myBlueprint` -> `myRelatedBlueprint` -> `myExtraRelatedBlueprint`.
The `Owning teams` column will be visible in tables containing entities of the blueprint, but will not be editable.
Conflict with direct team relations
Defining both `ownership.type: "Inherited"` and a direct relation to the Team blueprint (e.g., `teams`) in the same blueprint will cause the relation to be removed and ownership to fall back to `"Direct"`.
If you need inherited ownership, do not add a direct relation to the Team blueprint.
For more detailed information about ownership configuration, see the [ownership property section](/context-lake/business-context/ownership/.md#the-ownership-property) in the ownership documentation.
### Global VS granular permissions[](#global-vs-granular-permissions "Direct link to Global VS granular permissions")
When granting write permissions for entities of a blueprint, you have 2 levels of control:
1. Global permissions - create/update an entity as a whole. For example, allow **Member** users to update `Env` entities (all properties and relations).
2. Granular permissions - control which properties and relations a user/role can update when creating or updating an entity. For example, allow **Member** users to only update the property `slackChannelUrl` of `Env` entities.
To apply granular permissions for a blueprint, use the `updateProperties` and `updateRelations` fields in the JSON, see the examples below:
* Let user edit property
* Let user edit entity
The following change will allow **Member** users to update *only* the `slackChannelUrl` property of `Env` entities:
```
{
"entities": {
"updateProperties": {
"slackChannelUrl": {
"roles": ["Admin", "Env-moderator", "Member"], // changed from ["Admin", "Env-moderator"]
"users": [],
"teams": [],
"ownedByTeam": false
}
}
}
}
```
If you want to apply global permissions, use the `update` field in the JSON.
The following change will allow **Member** users to update *every* property/relation of `Env` entities that are owned by their team:
```
{
"entities": {
"update": {
"roles": ["Admin", "Env-moderator"],
"users": [],
"teams": [],
"ownedByTeam": true // changed from false
}
}
}
```
Global permissions override granular permissions
Using global permissions **overrides** any granular permissions that have been set. If both permission types are set, the global setting is used when evaluating permissions.
`update`, `updateProperties` and `updateRelations` settings apply when registering new entities as well. This means that a user can't register a new entity with a property (or relation) that he doesn't have permissions to edit.
---
# Govern data access
Port provides granular control to ensure that every user only sees the parts of the catalog that are relevant to them.
Port's catalog RBAC capabilities are enabled by utilizing [permissions controls](/platform-administration/users-and-teams/manage-users-teams/.md).
Page permissions
In order to manage who can view certain **pages** in Port, check out [page permissions](/interface-builder/port-interface/page/page-permissions/.md).
## Common usage[](#common-usage "Direct link to Common usage")
The catalog RBAC mechanism allows admins to finely control which users have access to specific information in the software catalog, for example:
* Allow a user to edit a single specific property on an entity.
* Create a fully read-only view for a developer.
* Allow users to create, edit, and delete only entities owned by their team.
* Restrict entity visibility to users whose team matches the entity's owner team.
* Allow only users with the on-call property set to true to edit entities owned by their team.
## Set access controls for catalog data[](#set-access-controls-for-catalog-data "Direct link to Set access controls for catalog data")
The default permissions assigned to every blueprint upon creation specify that users with the `admin` role and users with the specific blueprint `moderator` role can edit the blueprint itself and manage its permissions.
See [RBAC permissions](/platform-administration/users-and-teams/manage-users-teams/.md) for more information about the different roles.
The permissions described below control access to **blueprint entities and their properties**, not to the blueprint structure or permissions configuration itself. You can control who reads, creates, updates, or deletes entities, and who can view or edit specific properties within those entities.
It is possible to assign global permissions controls for a blueprint's **entities** and **properties**, using the following steps:
1. Go to the [Context lake page](https://app.port.io/settings/data-model) of your portal.
2. Select your desired blueprint, click on the `...` button in the top-right corner, and select `Permissions`:
3. A dialog will open with two tabs:
* **Entities tab** - set entity-level permissions (who can read, create, update, or delete entities)
* **Properties tab** - set property-level permissions (who can update or view specific properties)
You can also manage these permissions via the [Port API](/api-reference/update-a-blueprints-permissions/), [Terraform](https://registry.terraform.io/providers/port-labs/port-labs/latest/docs/resources/blueprint_permissions), or [Pulumi](https://www.pulumi.com/registry/packages/port/api-docs/blueprintpermissions/). Terraform and Pulumi support roles, users, teams, team ownership (`owned_by_team`), and update property/relation scopes. Advanced dynamic policies (`policy`) are not supported in those providers yet - configure them in the UI or via the API.
* Entities
* Properties
The **Entities** tab controls who can read, create, update, or delete entities. Configure entity-level access below by role, user/team, entity ownership, or dynamic policy.
* General
* Basic
* Advanced (entity owners)
* Advanced (dynamic policy)
This section allows you to assign permissions for a **role** (Member, Admin or Moderator).
Click on the dropdown in the desired role row and select the permissions that will be assigned to it.
**Edit via JSON (click to expand)**
To edit permissions via JSON, click on the `Edit JSON` button in the top-right corner of the dialog.
To give permissions to a role, add it to the `roles` array in the permission scope you desire (`read`, `register`, `unregister`, or `update`):
```
{
"entities": {
"read": {
"roles": ["myBlueprint-moderator", "Admin", "Member"],
// ...other permissions
},
"register": {
"roles": ["myBlueprint-moderator", "Admin", "Member"],
// ...other permissions
},
"unregister": {
"roles": ["myBlueprint-moderator", "Admin", "Member"],
// ...other permissions
},
"update": {
"roles": ["myBlueprint-moderator", "Admin", "Member"],
// ...other permissions
},
"updateProperties": {
"$identifier": {
"roles": ["myBlueprint-moderator", "Admin", "Member"],
// ...other permissions
}
// ...other properties
},
"updateRelations": {
"service": {
"roles": ["myBlueprint-moderator", "Admin", "Member"],
// ...other permissions
}
// ...other relations
}
}
}
```
This section allows you to assign permissions for a **user** or **team**.
find a user or team
If there isn't currently a row for the user or team, search for them in search box and select them. This will also automatically give them Read access.
Click on the dropdown in the desired user or team row and select the permissions that will be assigned to it.
"None"
If you see `None` as the permission, it means that the user or team only has permissions for `updateProperties` or `updateRelations`.
**Edit via JSON (click to expand)**
To edit permissions via JSON, click on the `Edit JSON` button in the top-right corner of the dialog.
To give permissions to a user or team, add the user or team identifier to the `users` or `teams` array in the permission scope you desire (`read`, `register`, `unregister`, or `update`):
```
{
"entities": {
"read": {
"users": ["my-user@example.port.io"],
"teams": ["my-team"],
// ...other permissions
},
"register": {
"users": ["my-user@example.port.io"],
"teams": ["my-team"],
// ...other permissions
},
"unregister": {
"users": ["my-user@example.port.io"],
"teams": ["my-team"],
// ...other permissions
},
"update": {
"users": ["my-user@example.port.io"],
"teams": ["my-team"],
// ...other permissions
},
"updateProperties": {
"$identifier": {
"users": ["my-user@example.port.io"],
"teams": ["my-team"],
// ...other permissions
}
// ...other properties
},
"updateRelations": {
"service": {
"users": ["my-user@example.port.io"],
"teams": ["my-team"],
// ...other permissions
}
// ...other relations
}
}
}
```
This section allows you to assign permissions based on **entity owners**.
Click on the dropdown in the desired row and select the permissions that will be assigned to it.
**Edit via JSON (click to expand)**
To edit permissions via JSON, click on the `Edit JSON` button in the top-right corner of the dialog.
To give permissions to entity owners, set `ownedByTeam` to `true` in the permission scope you desire (`read`, `register`, `unregister`, or `update`):
```
{
"entities": {
"read": {
"ownedByTeam": true,
// ...other permissions
},
"register": {
"ownedByTeam": true,
// ...other permissions
},
"unregister": {
"ownedByTeam": true,
// ...other permissions
},
"update": {
"ownedByTeam": true,
// ...other permissions
},
"updateProperties": {
"$identifier": {
"ownedByTeam": true,
// ...other permissions
}
// ...other properties
},
"updateRelations": {
"service": {
"ownedByTeam": true,
// ...other permissions
}
// ...other relations
}
}
}
```
#### Important notes
* In the context of the `register` permission, setting a user or team as an entity owner means that they can only create a new entity if they assign it to a team that they are a member of.
* When entity owners permissions are configured the policy is ignored.
This section allows you to assign permissions based on a **dynamic policy**.
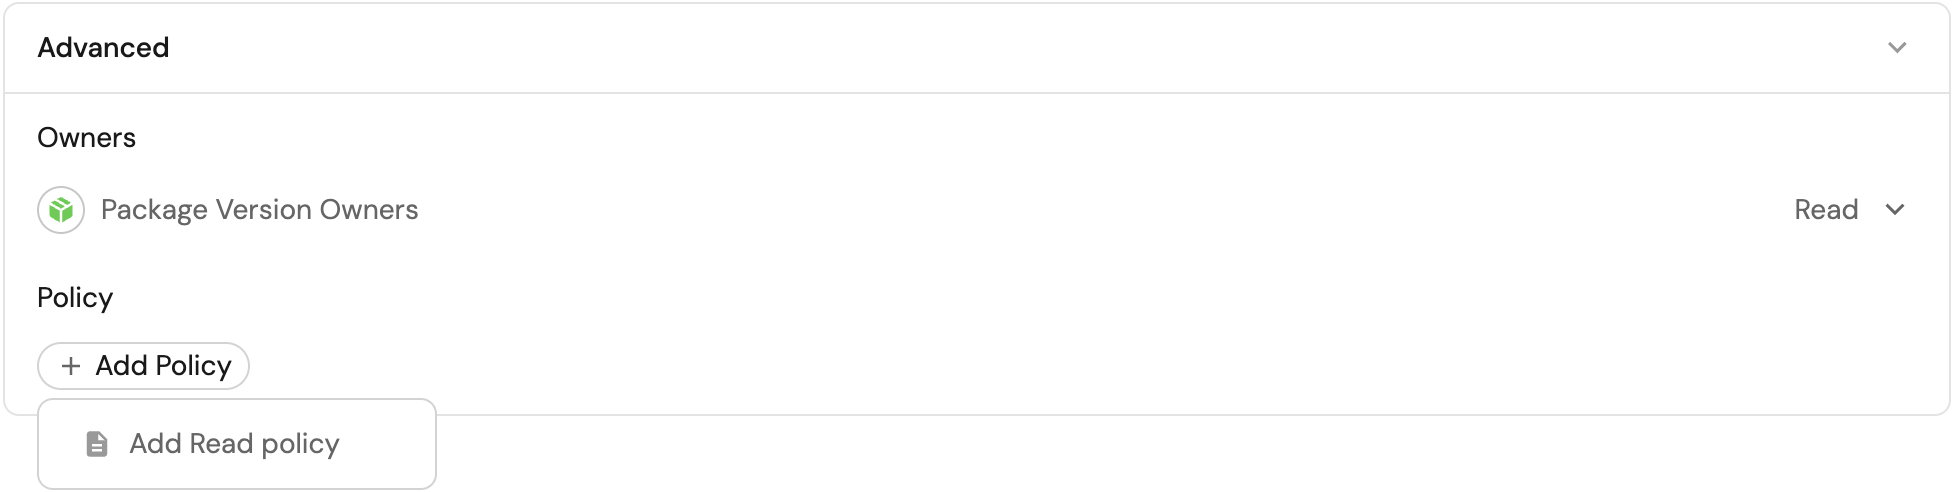
**Edit via JSON (click to expand)**
To edit permissions via JSON, click on the `Edit JSON` button in the top-right corner of the dialog.
To configure a policy, add a `policy` query to the relevant scope. The `policy` key allows you to give **dynamic** permissions to users, by using [search queries](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules).
* For **`read`**, **`update`**, and **`unregister`**: the policy filters the specific entities you are allowed to view or mutate.
* For **`register`**: Port simulates the new entity and evaluates the query against it. For this reason, the `relatedTo` operator and queries against calculation/aggregation properties are not supported.
You can also use [contextual query rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#contextual-query-rules) to get the context of the user executing the query.
In the following example, `on-call` users are granted `read` access only to entities that share the same `region` as one of their owning teams:
```
{
"entities": {
// ...other scopes
"read": {
"policy": {
"combinator": "and",
"rules": [
{
"property": {
"context" : "user",
"property": "isOnCall"
},
"operator": "=",
"value": "true"
},
{
"property": "region",
"operator": "containsAny",
"value": {
"context" : "userTeams",
"property": "region"
}
},
]
}
// ...other permissions
}
}
}
```
conflicting permissions
When **entity owners** permissions are configured, the **dynamic policy** is ignored.
The **Properties** tab restricts access to specific properties. You can control which properties are editable and which properties are visible to different users.
* Update properties
* Read properties
Limit which properties specific users can modify. A user with update permission on a property can change its value regardless of entity-level update restrictions.
Configure access by role, user, team, or entity ownership. Note: entity ownership (ownedByTeam) is supported for update properties, but dynamic policies are not.
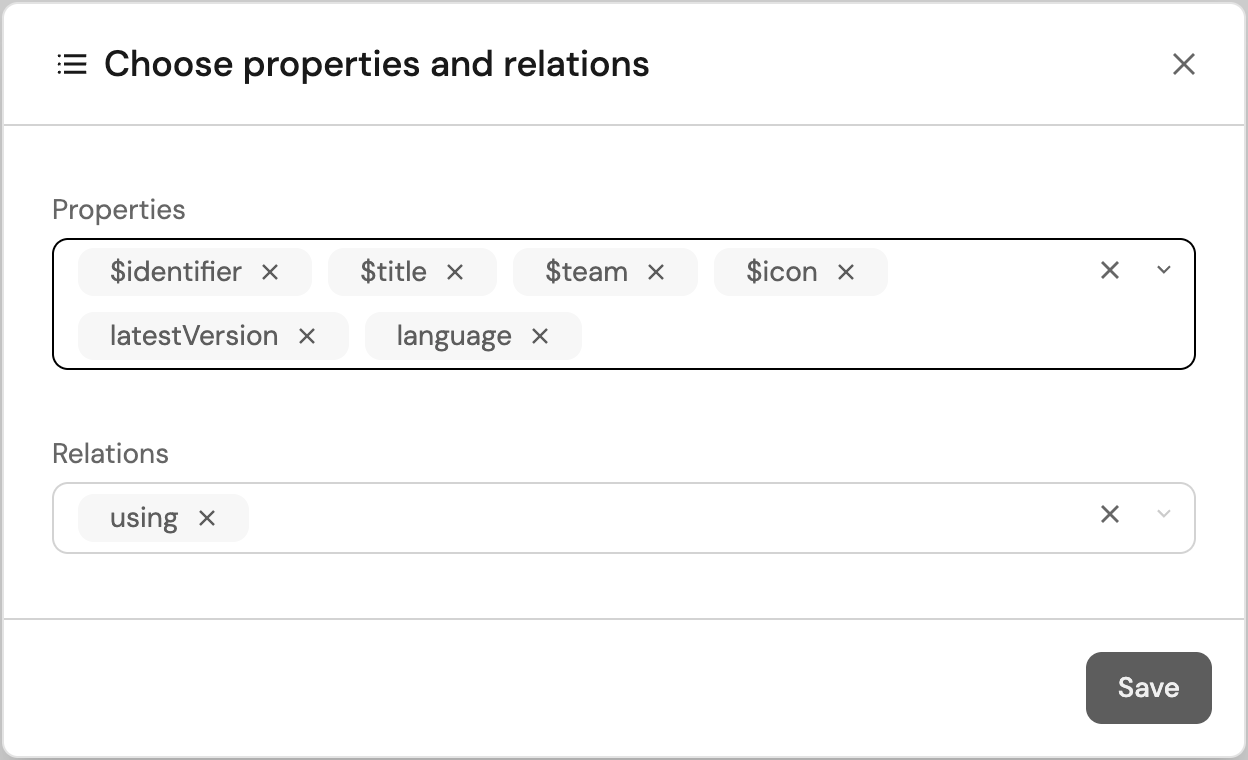
```
{
"entities": {
"updateProperties": {
"api_key": {
"roles": ["platform-team", "Admin"],
"users": ["my-user@example.port.io"],
"teams": ["my-team"],
"ownedByTeam": true
}
// ...other properties
}
}
}
```
Hide specific properties from users who shouldn't see them. Users must have entity-level read access first, properties with no explicit read restrictions are visible by default.
Configure access by role, user, or team. Note: only roles, users, and teams are supported for read properties. Entity ownership (ownedByTeam) and dynamic policies are not supported.
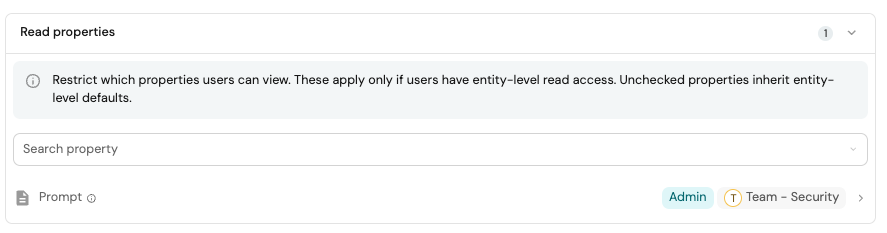
```
{
"entities": {
"readProperties": {
"api_key": {
"roles": ["platform-team", "Admin"],
"users": ["my-user@example.port.io"],
"teams": ["my-team"]
}
// ...other properties
}
}
}
```
Affected components
Setting `read` permissions on entities takes effect at the API level, meaning that any component in Port that fetches entities will be affected by these permissions.
For example, a table widget that displays entities will only show entities that the user has read permissions for.
## Permission simulator[](#permission-simulator "Direct link to Permission simulator")
The permission simulator allows you to test and validate blueprint permissions before saving them.
You can simulate `read`, `register` (create), `update`, and `unregister` (delete) access for any user in your organization and quickly understand why access is granted or denied. It's available from Port AI, the UI, or the API, not only from the browser.
### Use the simulator[](#use-the-simulator "Direct link to Use the simulator")
* Port AI
* UI
* API
Ask [Port AI](/port-ai/port-ai-assistant/.md), or your coding agent over the [Port MCP server](/agent-management/port-mcp-server/overview/.md), to run the check in plain language. For example:
*"Why can Alex Chen update the checkout-service entity on the Service blueprint?"*
Port AI runs the simulator and reports the exact rule that grants access, for example that Alex is on the team that owns checkout-service.
*"Which services can anyone on the security-team currently update?"*
Port AI returns every entity accessible under that rule, useful for checking a policy's blast radius before you widen it to more teams.
1. Go to the [Context lake page](https://app.port.io/settings/data-model), open a blueprint, and click `Permissions`.
2. In the **Permission Simulator** section at the bottom of the page, select:
* A user from your organization.
* An operation: `read`, `register` (create), `update`, or `unregister` (delete).
3. Review the results table to see all entities the selected user can access for the selected operation.
4. (Optional) Select a specific entity to open the detailed access breakdown.
5. In the detail view, review:
* The visual flow (user → granted/denied → entity).
* Which checks passed or failed.
* The exact check that granted access (if access is granted).
Test changes before saving
The simulator evaluates pending permission changes from the form, not only the saved configuration.
This lets you verify impact in real time before applying your changes.
This checks whether `alex-chen` can `update` the `checkout-service` entity on the `Service` blueprint, and why. Call `POST` on `/v1/blueprints/{blueprint_identifier}/permissions/simulate` with:
```
{
"userIdentifier": "alex-chen",
"operation": "update",
"entityIdentifier": "checkout-service"
}
```
Drop `entityIdentifier` to list every entity the user can reach for that operation, instead of checking one:
```
{
"userIdentifier": "alex-chen",
"operation": "update"
}
```
See [Simulate permissions for a user](/api-reference/simulate-permissions-for-a-user/) for the full request and response schema.
### How permissions are evaluated[](#how-permissions-are-evaluated "Direct link to How permissions are evaluated")
The simulator evaluates five checks. Access is granted if **any one** of the following checks passes:
1. **Role check** - verifies whether the user's role is included in the operation's allowed `roles`.
2. **Owned by team** - when `ownedByTeam` is enabled, verifies whether the user belongs to at least one team in the entity's `$team`.
3. **Team list** - verifies whether the user belongs to any team listed in the operation's `teams`.
4. **User list** - verifies whether the user is explicitly listed in the operation's `users`.
5. **Policy** - verifies whether the entity matches the configured `policy` query.
When access is granted, the simulator indicates the granting path, for example: "Has role `Admin` which allows this operation".
For policy-based access, the evaluated query is also displayed.
## Software catalog RBAC examples[](#software-catalog-rbac-examples "Direct link to Software catalog RBAC examples")
Refer to the [examples](/context-lake/consuming-the-lake/govern-data-access/examples/.md) page for practical examples of Port's RBAC.
## FAQ[](#faq "Direct link to FAQ")
1What happens if a user lacks the permissions to edit a required property of the blueprint?
2What happens if the ownedByTeam setting is enabled for entity registration, but the user can't edit the team property?
3How are multiple permission checks combined?
4Do entity read permissions affect dashboards and other Port components?
---
# Other consumption methods
External AI agents and automation workflows can leverage Port's Context Lake to make intelligent, context-aware decisions without needing direct access to your entire toolchain. Instead of building custom integrations for each tool, external systems can query Port's unified knowledge layer to understand your organization's structure, relationships, and standards.
## n8n integration[](#n8n-integration "Direct link to n8n integration")
Port provides a custom n8n node that simplifies integration with Port's AI agents and Context Lake. To get started:
1. **[Set up Port's n8n custom node](/context-lake/consuming-the-lake/other-consumption-methods/port-n8n-node/.md)** — Install and configure the Port node in your n8n instance
2. **[Build automation workflows](/guides/all/remediate-vulnerability-with-n8n-and-port/.md)** — See an example of using Port as a context lake for vulnerability management workflows
---
# Port n8n node
Port provides a custom n8n node ([n8n-nodes-portio-experimental](https://www.npmjs.com/package/@port-labs/n8n-nodes-portio-experimental)) that simplifies integration with Port's AI agents and API. Instead of making manual HTTP requests for authentication, invocation, and response retrieval, the Port node handles all of this automatically, making it easy to build powerful automation workflows that leverage Port's Context Lake.
This guide walks you through installing and configuring Port's custom n8n node in your n8n instance.

## Prerequisites[](#prerequisites "Direct link to Prerequisites")
Before you begin, ensure you have:
* **npm installed** — Required for installing the Port n8n node package. npm comes with Node.js, [install Node.js](https://nodejs.org/) if you don't have it.
* **A working n8n instance** — Either n8n Cloud or a self-hosted instance. If you don't have one, follow n8n's [guide on using Docker](https://docs.n8n.io/hosting/installation/docker/).
* **Port API credentials** — Your Port `Client ID` and `Client Secret`. [Learn how to get them](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md#find-your-port-credentials).
* **A Port account with AI features enabled** — Required for using Port AI agents in your workflows.
* We recommend [creating a dedicated service account](https://docs.port.io/platform-administration/users-and-teams/manage-users-teams/#service-accounts) in Port for each workflow or agent integration. This improves security and makes it easier to manage credentials.
## Set up n8n instance[](#set-up-n8n-instance "Direct link to Set up n8n instance")
If you don't have an n8n instance running, you can set one up using one of the options below.
The location where you mount the n8n data directory is important - this is where the Port n8n node package will be installed.
* npm
* Docker
* Docker compose
If you prefer running n8n directly with npm, install it globally and start it from your terminal.
1. **Install n8n**:
```
npm install n8n -g
```
2. **Start n8n**:
```
n8n start
```
3. **Open n8n** — Visit `http://localhost:5678`.
Using a bind mount allows the container to read/write directly to your local filesystem, making it easier to install and manage the Port n8n node package.
1. **Create a directory for n8n data** (we will call this `$n8n_HOME`):
```
mkdir -p ~/n8n-data
```
2. **Run n8n with a bind mount**:
```
docker volume create n8n_data
docker run -it --rm \
--name n8n \
-p 5678:5678 \
-e GENERIC_TIMEZONE="Africa/Accra" \
-e TZ="Africa/Accra" \
-e N8N_ENFORCE_SETTINGS_FILE_PERMISSIONS=true \
-e N8N_RUNNERS_ENABLED=true \
-e N8N_COMMUNITY_PACKAGES_ENABLED=true \
-v ~/n8n-data:/home/node/.n8n \
docker.n8n.io/n8nio/n8n
```
Configuration notes
* The `N8N_COMMUNITY_PACKAGES_ENABLED=true` environment variable is required for n8n to load community-installed nodes like the Port n8n node.
* Replace `"Africa/Accra"` with your preferred timezone. The `GENERIC_TIMEZONE` and `TZ` environment variables should match.
* Replace `~/n8n-data` with the actual local path you want to use such as `/Users/janedoe/n8n-data`. Anything n8n writes to `/home/node/.n8n` (inside the container) will persist directly to your local directory.
3. **Access n8n** — Open your browser and navigate to `http://localhost:5678`.
If you prefer using Docker Compose, create a `docker-compose.yml` file:
```
version: '3'
services:
n8n:
image: docker.n8n.io/n8nio/n8n
ports:
- "5678:5678"
environment:
- GENERIC_TIMEZONE=Europe/Madrid
- TZ=Europe/Madrid
- N8N_COMMUNITY_PACKAGES_ENABLED=true
volumes:
- ./n8n-data:/home/node/.n8n
```
The `N8N_COMMUNITY_PACKAGES_ENABLED=true` environment variable is required for n8n to load community-installed nodes like the Port n8n node.
Then run:
```
# Navigate to the directory containing your docker compose file
cd /path/to/your/compose/file/directory
# Pull latest version
docker compose pull
# Start the container
docker compose up -d
```
## Install Port's n8n node[](#install-ports-n8n-node "Direct link to Install Port's n8n node")
Now that you have n8n running, let's install Port's custom node using one of the options below.
If you use n8n Cloud, the Port node is verified and available directly from the canvas. If you do not see it, [restart your workspace](#restart-n8n-cloud-workspace) and confirm that **Verified Community Nodes** is enabled in your [Admin Panel](https://app.n8n.cloud/dashboard).
* Install from n8n browser UI
* Install from terminal
1. In your n8n instance, go to **Settings**.
2. Select **Community Nodes**.
3. Click **Install**.
4. Enter `@port-labs/n8n-nodes-portio-experimental` as the npm package name.
5. Click **Install** to finish the setup.
1) **Navigate to your n8n data directory** (the `$n8n_HOME` directory you created earlier):
```
cd ~/n8n-data
```
2) **Install the Port n8n node package**:
```
mkdir -p custom
cd custom
npm i @port-labs/n8n-nodes-portio-experimental
```
The package is installed in the `custom` folder in your n8n data directory (`$n8n_HOME`).
3) **Restart your n8n instance**:
* **If using Docker**: Stop the container (`Ctrl+C` or `docker stop n8n`) and start it again with the same command.
* **If using Docker Compose**: Run `docker compose restart`.
Restart required
n8n needs to be restarted after installing community packages so it can discover and load them. Make sure `N8N_COMMUNITY_PACKAGES_ENABLED=true` is set in your Docker configuration.
The Port n8n node package is available on npm at [@port-labs/n8n-nodes-portio-experimental](https://www.npmjs.com/package/@port-labs/n8n-nodes-portio-experimental). The package has been fully approved and is ready for production use.
## Quick start[](#quick-start "Direct link to Quick start")
Now that the Port node is installed, let us verify it works by creating a simple workflow.
### Add a Port node to your workflow[](#add-a-port-node-to-your-workflow "Direct link to Add a Port node to your workflow")
1. **Create a new workflow** in your n8n instance.
2. **Add a trigger** — For testing, add a **Manual Trigger** node so you can trigger the workflow manually by clicking the **Execute Workflow** button.
3. **Add the Port node**:
* Click the **+** button on the left side of the screen to add a new node
* Search for `port` in the node search
4. **Select a Port node** — Click the "Port API AI" search result and select "Invoke AI interaction" (this is the easiest one to test with).
5. **Connect the nodes** — Drag from the **+** icon on the trigger node to the left side of the Port AI node to connect them.

Success!
You have successfully deployed your first Port n8n node! The node is now available in your n8n instance.
### Configure Port credentials[](#configure-port-credentials "Direct link to Configure Port credentials")
Before you can use the Port node, you need to add your Port API credentials.
1. **Open the Port node** — Double-click the Port AI node you just added.
2. **Create a new credential**:
* At the top of the node configuration, you will see a dropdown named `Credential to connect with`
* Click this dropdown and select `Create new credential`
3. **Enter your Port credentials**:
* **Client ID** — Your Port Client ID
* **Client Secret** — Your Port Client Secret
If you're not sure how to get your Port credentials, see the [Port API documentation](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md#find-your-port-credentials).
4. **Save the credential** — Click "Save" to store the credential.
You can store multiple Port account credentials in n8n and select which one to use for each node. This is useful if you work with multiple Port organizations.
## Verify the installation[](#verify-the-installation "Direct link to Verify the installation")
To verify everything is working:
1. **Configure the Port node** — In the **General Purpose AI Interaction** node:
* Select your Port credential from the dropdown
* Enter a simple prompt like "List all ec2 instances in the eu-west region"
* Save the node
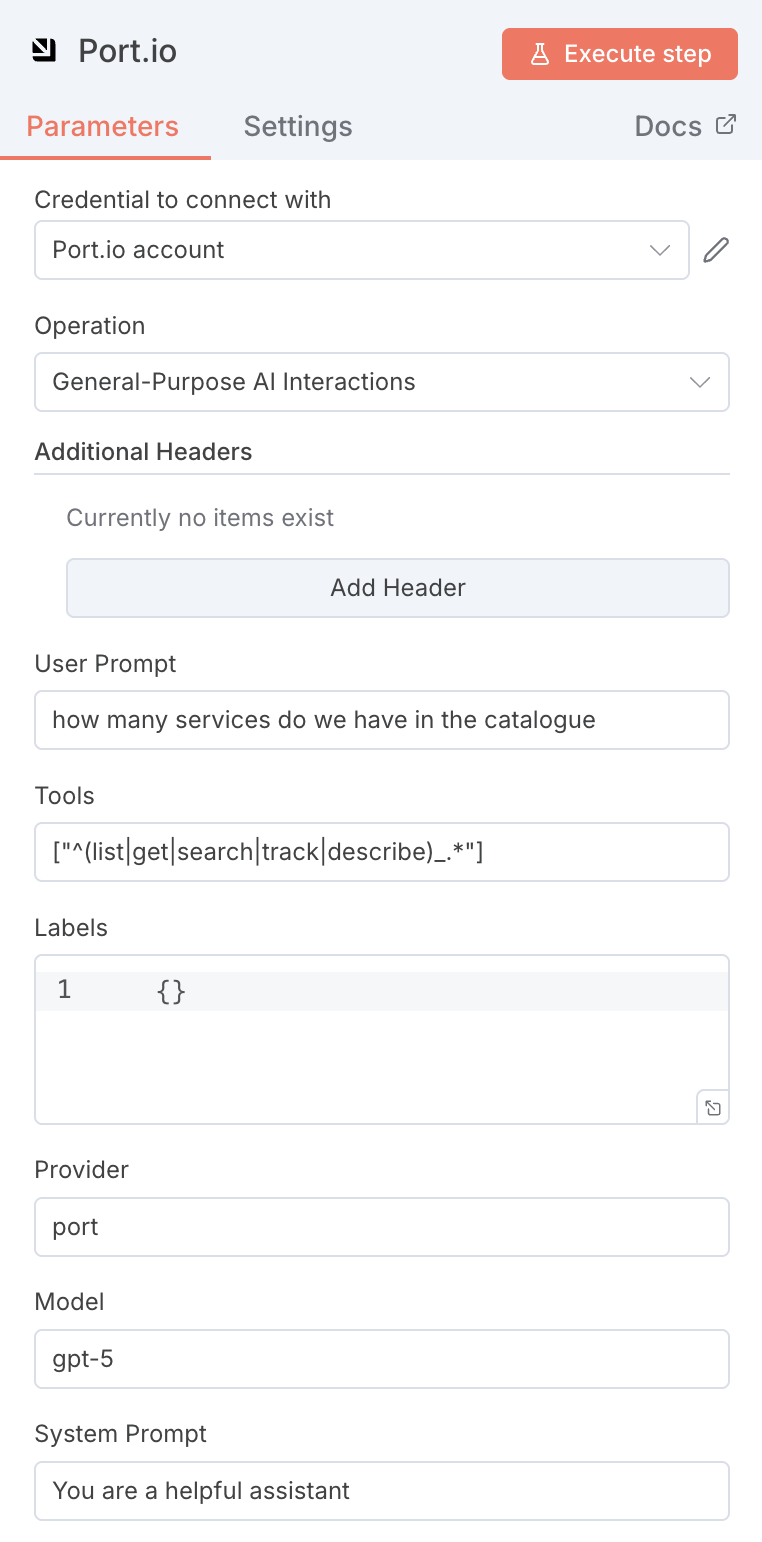
2. **Execute the workflow** — Click **Execute Workflow** to test the connection.
3. **Check the output** — If successful, you should see the AI response in the node output.
## Available operations[](#available-operations "Direct link to Available operations")
The Port n8n node provides operations for interacting with Port's AI capabilities. Each operation corresponds to a different use case for querying and automating with Port's Context Lake.
`generalInvoke`
Direct Port AI query. Use this operation to interact with Port's Context Lake through natural language. You can query your software catalog, get insights about your services, or leverage Port's AI to analyze your data.
[API Reference](/api-reference/general-purpose-ai-interactions)
`invokeAgent`
Call a specific AI agent. Use this operation when you want to run predefined agent workflows configured in Port. Agents are reusable AI configurations that can be invoked with a simple prompt.
[API Reference](/api-reference/invoke-a-specific-agent)
`getInvocation`
Retrieve results by invocation ID. Use this operation to fetch the results of a previous AI invocation. This is useful for asynchronous workflows where you need to poll for results.
[API Reference](/api-reference/get-an-invocations-result)
## What's next?[](#whats-next "Direct link to What's next?")
Now that you have Port's n8n node installed and configured, you can:
* **Build automation workflows** — Use Port's Context Lake to enrich your n8n workflows with organizational context
* **Integrate with AI agents** — Invoke Port AI agents from n8n workflows
* **Query the catalog** — Access service metadata, ownership, dependencies, and more
## Related guides[](#related-guides "Direct link to Related guides")
* [Remediate security vulnerability with n8n and Port AI](/guides/all/remediate-vulnerability-with-n8n-and-port/.md) — Example workflow using Port as a context lake for vulnerability management
* [Port n8n nodes repository](https://github.com/port-labs/port-n8n-nodes) — Source code and detailed documentation for the Port n8n nodes
## Troubleshooting[](#troubleshooting "Direct link to Troubleshooting")
### Node not appearing in n8n[](#node-not-appearing-in-n8n "Direct link to Node not appearing in n8n")
* **Check package installation** — Verify that `npm i @port-labs/n8n-nodes-portio-experimental` completed successfully. Check for a `node_modules` directory in your `$n8n_HOME` directory.
* **Verify environment variable** — Ensure `N8N_COMMUNITY_PACKAGES_ENABLED=true` is set in your Docker configuration.
* **Check installation location** — Make sure the package is installed in the same directory that's mounted to `/home/node/.n8n` in the Docker container.
* **Restart n8n** — Community packages are only loaded when n8n starts, so a restart is required after installation.
### Restart n8n Cloud workspace[](#restart-n8n-cloud-workspace "Direct link to Restart n8n Cloud workspace")
If you need to restart your hosted instance:
1. Open the [n8n Cloud admin panel](https://app.n8n.cloud/dashboard).
2. Select the **Settings** (gear) icon.
3. Scroll to **Workspace status** and select **Restart workspace**.
### Credential errors[](#credential-errors "Direct link to Credential errors")
* **Verify credentials** — Double-check that your Client ID and Client Secret are correct.
* **Check AI features** — Ensure your Port account has AI features enabled.
* **Test API access** — Try making a direct API call to verify your credentials work.
---
# Consumption methods
Consuming the lake is how developers, agents, and workflows read and use data from your context lake after it is ingested.
Use this section to query the catalog, connect AI tools through the Port MCP server, govern who can see what, and trigger automations from external tools.
## Query the catalog[](#query-the-catalog "Direct link to Query the catalog")
[API access & search](/context-lake/consuming-the-lake/search-and-query/overview/.md) is Port's search and query syntax for filtering and retrieving catalog entities. Use it to power catalog pages, dashboards, scorecard rules, workflow conditions, and direct API calls.
## Consume via the Port MCP server[](#consume-via-the-port-mcp-server "Direct link to Consume via the Port MCP server")
The [Port MCP server](/context-lake/consuming-the-lake/port-mcp-server/.md) exposes the catalog to any MCP client - your IDE, an AI agent, or a custom tool - using the same tools that power [Port AI agents](/agent-management/custom-agents/overview/.md) to answer questions and take action on live catalog data.
## Consume via the Port CLI[](#consume-via-the-port-cli "Direct link to Consume via the Port CLI")
The [Port CLI](/port-ai/interfaces/port-cli/.md) is a command-line client for the Port API. Coding agents run it from the shell, print raw JSON, and pipe results through jq or a script. Platform engineers use it to export, compare, and migrate organizations.
## Govern data access[](#govern-data-access "Direct link to Govern data access")
[Governable data access](/context-lake/consuming-the-lake/govern-data-access/overview/.md) is what sets Port's RBAC apart from a static permissions list: rules are evaluated at runtime against live catalog data.
You can define a policy like ***"only the payments team can see mission-critical services in the finance domain"***, and Port enforces it dynamically as ownership, criticality, and domain properties change - no manual permission updates required.
## Trigger from external tools[](#trigger-from-external-tools "Direct link to Trigger from external tools")
The [Port n8n node](/context-lake/consuming-the-lake/other-consumption-methods/port-n8n-node/.md) lets automation platforms outside Port, such as n8n, query the context lake and drive workflows without needing direct access to your toolchain.
---
# Port MCP server
No Port AI terms required
The Port MCP server does **not** use Port AI capabilities. You can install and use it without enabling Port AI features or accepting the [Port AI Terms](https://www.port.io/legal/ai-terms).
The [Port MCP server](/agent-management/port-mcp-server/overview/.md) is how LLMs, IDEs, and automated workflows **consume** your Context Lake without going through the Port UI or writing API calls by hand.
Connect Cursor, Claude, GitHub Copilot, or any MCP-compatible client to Port and use natural language to query blueprints and entities, run actions, load skills, and work with the same catalog data that powers your portal.
## What you can do[](#what-you-can-do "Direct link to What you can do")
* **Query the catalog** in your IDE: ownership, dependencies, scorecard status, and entity details.
* **Run Port actions** from a chat or agent session when your role allows it.
* **Build and update catalog resources** with developer MCP tools (entities, actions, scorecards, and more depending on your permissions).
For installation, supported clients, authentication, and the full tool list, see [Port MCP server overview and installation](/agent-management/port-mcp-server/overview/.md).
## How this relates to AI agents[](#how-this-relates-to-ai-agents "Direct link to How this relates to AI agents")
[Port AI agents](/agent-management/custom-agents/overview/.md) and the Port MCP server use the same underlying [Port MCP tools](/agent-management/port-mcp-server/available-tools/.md). The difference is mostly **who invokes them** and **where**:
| | **Port MCP server** | **Port AI agents** |
| --------------------- | ----------------------------------------------------------- | ------------------------------------------------------------------------ |
| **Typical caller** | Developers in IDEs, external MCP clients, CI jobs | Systems, webhooks, APIs, orchestration |
| **Interaction style** | Conversational, ad hoc | Domain-specific, autonomous, machine-to-machine |
| **Best for** | Exploring the catalog, building in Port from your toolchain | Automated workflows (incident response, remediation, scheduled analysis) |
You can use the MCP server on its own. When [Port AI agents](/agent-management/custom-agents/overview/.md) are configured, the MCP server can also invoke them, but core catalog query and action tools do not require agents.
[Port AI](/port-ai/overview/.md) (assistant, API, Slack) uses the same tool surface for human-facing and programmatic AI access.
## Ingestion vs. consumption[](#ingestion-vs-consumption "Direct link to Ingestion vs. consumption")
| Direction | Interface | Purpose |
| ----------- | ----------------------------------------------------------------------------------------- | ------------------------------------------------------- |
| **Ingest** | [Port MCP in ingestion](/context-lake/ingestion/ingest-data-into-port/other/port-mcp/.md) | Create or update entities from an agent or IDE workflow |
| **Consume** | Port MCP server (this page) | Read and act on catalog data from external AI tools |
For live data that is not modeled in the catalog, pair MCP consumption with [MCP connectors](/agent-management/ai-registry/mcp-connectors/.md). See [Integrations vs. MCP connectors](/context-lake/ingestion/integrations-vs-mcp/.md).
## Where to go next[](#where-to-go-next "Direct link to Where to go next")
* [Port MCP server overview and installation](/agent-management/port-mcp-server/overview/.md).
* [Available MCP tools](/agent-management/port-mcp-server/available-tools/.md).
* [Port AI agents](/agent-management/custom-agents/overview/.md).
* [Token-based authentication for CI/CD](/agent-management/port-mcp-server/token-based-authentication/.md).
---
# Advanced
### Search route query parameters[](#search-route-query-parameters "Direct link to Search route query parameters")
The search route also supports several query parameters that affect the returned output:
| Parameter | Description | Available values | Default value |
| ------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ---------------- | ------------- |
| `attach_title_to_relation` | `true`: Both the identifier and the title of the related Entity will appear under the Relation key
`false`: Only the identifier of the related Entity will appear under the Relation key | `true`/`false` | `false` |
| `exclude_calculated_properties` | Should [mirror properties](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md) and [calculation properties](/context-lake/data-model/setup-blueprint/properties/calculation-property/.md) be returned with the result | `true`/`false` | `false` |
#### `attach_title_to_relation` example[](#attach_title_to_relation-example "Direct link to attach_title_to_relation-example")
Here are examples outputs based on the value of the `attach_title_to_relation` parameter:
* True
* False
Here is a search response with `attach_title_to_relation=true`:
```
{
"ok": true,
"matchingBlueprints": [
"region",
"deployment",
"vm",
"microservice",
"k8sCluster",
"permission",
"runningService"
],
"entities": [
{
"identifier": "e_vb9EPyW1zOamcbT1",
"title": "cart-deployment",
"blueprint": "deployment",
"team": ["Team BE"],
"properties": {
"version": "1.4",
"user": "yonatan",
"status": "failed",
"github-action-url": "https://a.com",
"Region": "AWS"
},
"relations": {
"microservice": {
"identifier": "e_47MwTvQj03MpVyBx",
"title": "admin-test"
}
},
"createdAt": "2022-07-27T17:11:04.344Z",
"createdBy": "auth0|6278b02000955c006f9132d3",
"updatedAt": "2022-07-27T17:11:04.344Z",
"updatedBy": "auth0|6278b02000955c006f9132d3"
}
]
}
```
Here is the same search response with `attach_title_to_relation=false`:
```
{
"ok": true,
"matchingBlueprints": [
"region",
"deployment",
"vm",
"microservice",
"k8sCluster",
"permission",
"runningService"
],
"entities": [
{
"identifier": "e_vb9EPyW1zOamcbT1",
"title": "cart-deployment",
"blueprint": "deployment",
"team": ["Team BE"],
"properties": {
"version": "1.4",
"user": "yonatan",
"status": "failed",
"github-action-url": "https://a.com",
"Region": "AWS"
},
"relations": {
"microservice": "e_47MwTvQj03MpVyBx"
},
"createdAt": "2022-07-27T17:11:04.344Z",
"createdBy": "auth0|6278b02000955c006f9132d3",
"updatedAt": "2022-07-27T17:11:04.344Z",
"updatedBy": "auth0|6278b02000955c006f9132d3"
}
]
}
```
---
# Examples
This page provides practical examples of using Port's search and query syntax across different features.
## Catalog pages[](#catalog-pages "Direct link to Catalog pages")
Initial filters for [catalog pages](/interface-builder/port-interface/page/catalog-page/.md) are configured when creating or editing a catalog page in your [software catalog](https://app.getport.io/organization/catalog). These filters pre-filter which entities appear when the page loads, improving performance and showing only relevant data.
Filters are particularly useful for blueprints with large entity counts (such as Snyk vulnerabilities), where requests may take a long time to ld or even time out without filtering.
* Basic example
* Advanced example
This example demonstrates how to filter a Snyk vulnerability catalog page, showing only `high` and `critical` severity vulnerabilities:
```
{
"combinator": "and",
"rules": [
{
"value": [
"high",
"critical"
],
"property": "severity",
"operator": "in"
}
]
}
```
This example demonstrates how to filter a service catalog page with multiple conditions, showing only production services owned by specific teams that were updated within a specific date range:
```
{
"combinator": "and",
"rules": [
{
"value": "production",
"property": "environment",
"operator": "="
},
{
"value": [
"platform_team",
"developers_team"
],
"property": "$team",
"operator": "containsAny"
},
{
"property": "last_push",
"operator": "between",
"value": {
"from": "",
"to": ""
}
}
]
}
```
## Entity pages[](#entity-pages "Direct link to Entity pages")
Filters for related entity tabs are configured when creating custom tabs on any [entity page](/interface-builder/port-interface/page/entity-page/.md).
To add filters, navigate to the **Related Entities** tab, click the `+` button to create a new tab or edit an existing one. Then under **Initial filters**, click the filters button to add your query.
These filters are particularly useful when a tab displays a large number of related entities. Filters improve performance and make the data more manageable.
* Basic example
* Advanced example
This example demonstrates how to filter related pull requests for a repository entity, showing only PRs with an `open` status:
```
{
"combinator": "and",
"rules": [
{
"value": "open",
"property": "status",
"operator": "="
}
]
}
```
This example demonstrates how to filter related PagerDuty incidents for a service entity with multiple conditions, showing only high-urgency incidents that are still unresolved and were created in the last week:
```
{
"combinator": "and",
"rules": [
{
"value": "high",
"property": "urgency",
"operator": "="
},
{
"value": [
"triggered",
"acknowledged"
],
"property": "status",
"operator": "in"
},
{
"property": "created_at",
"operator": "between",
"value": {
"preset": "lastWeek"
}
}
]
}
```
## Dashboard widgets[](#dashboard-widgets "Direct link to Dashboard widgets")
Widget-specific filters are configured in the widget creatio or edit form for [dashboard widgets](/interface-builder/port-interface/dashboards/overview/.md). These filters determine which entities are included in calculations and visualizations.
* Basic property filter
* Filter by contextual data
* Filter by relation-path
This example demonstrates how to filter overdue pull requests, showing only PRs with an `open` status that were created in the **past 90 days**:
```
{
"combinator": "and",
"rules": [
{
"value": "open",
"property": "status",
"operator": "="
},
{
"property": "createdAt",
"operator": "between",
"value": {
"preset": "last3Months"
}
}
]
}
```
JSON mode required
Contextual queries using the `context` field require JSON mode. You cannot configure these through the UI form.
**Filter by logged-in user**
This example demonstrates how to filter entities owned by the logged-in user:
```
{
"combinator": "and",
"rules": [
{
"operator": "matchAny",
"property": {
"path": ["relationID_1"]
},
"value": {
"context": "user",
"property": "$identifier"
}
}
]
}
```
**Filter by user's teams**
This example demonstrates how to filter entities by the logged-in user's owning teams:
```
{
"combinator": "and",
"rules": [
{
"value": {
"context": "user",
"property": "$team"
},
"property": "$team",
"operator": "containsAny"
}
]
}
```
This example demonstrates how to filter pull requests based on their relationship to a specific repository. It shows only PRs belonging to the `backend-api` service:
```
{
"combinator": "and",
"rules": [
{
"operator": "matchAny",
"property": {
"path": [
"service"
]
},
"value": "backend_api"
}
]
}
```
## Blueprint read permissions[](#blueprint-read-permissions "Direct link to Blueprint read permissions")
Blueprint read permissions can be configured with dynamic `policy` rules using search and query syntax. Configure these in the [data model](https://app.port.io/settings/data-model) page by clicking on a blueprint and going to the **Permissions** tab.
The `policy` key allows you to create dynamic read access rules that grant users access to entities based on their properties, team membership, and contextual user data. This determines which entities users can see in catalog pages.
For detailed examples and information, see the [read permissions policy section](/context-lake/consuming-the-lake/govern-data-access/overview/.md#set-global-access-controls-to-catalog-data) in the catalog RBAC documentation.
## Aggregation properties[](#aggregation-properties "Direct link to Aggregation properties")
Configure filters when creating or editing an [aggregation property](/context-lake/data-model/setup-blueprint/properties/aggregation-property/.md) in the [data model](https://app.getport.io/settings/data-model) page. The search and query filter is defined under the `query` section of the aggregation property.
This example demonstrates how to add an aggregation property to a `service` blueprint that calculates the number of open high-severity vulnerabilities for each service, filtering only vulnerabilities with `severity` set to `high` and `status` set to `open`:
```
{
"aggregationProperties": {
"numberOfOpenHighVulnerabilities": {
"title": "Number of open high severity vulnerabilities",
"target": "vulnerability",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "severity",
"operator": "=",
"value": "high"
},
{
"property": "status",
"operator": "=",
"value": "open"
}
]
}
}
}
}
```
## Scorecards[](#scorecards "Direct link to Scorecards")
Configure filters when creating or editing a scorecard. [Filters](/governance/standards-and-compliance/concepts-and-structure/.md#filter-elements) determine which entities the rule evaluates, filtering out irrelevant entities and performing checks only on entities that pass the filtering.
Scorecards use conditions
Scorecard filters use `conditions` instead of `rules`, but follow the same structure with `combinator`, `property`, `operator`, and `value`.
This example demonstrates how to filter a scorecard to apply only to production services owned by specific teams. This ensures the quality check only runs on critical services:
```
"filter": {
"combinator": "and",
"conditions": [
{
"value": [
"builder_team",
"developers_team"
],
"operator": "containsAny",
"property": "$team"
},
{
"value": "production",
"operator": "=",
"property": "environment"
}
]
}
```
Supported operators
For a complete list of the available operators in scorecard filters, see the available operators section under the [rule elements](/governance/standards-and-compliance/concepts-and-structure/.md#rule-elements) documentation.
## Self-service actions[](#self-service-actions "Direct link to Self-service actions")
Configure these options when creating or editing an action in the [self-service actions](https://app.port.io/self-serve) page.
* Action conditions
* Entity input datasets
* Dynamic permissions
Action conditions determine which entities an action appears on, ensuring actions are only available for relevant entities. Configure this in the **Basic Details** tab of the action form.
DAY-2 and DELETE only
Action conditions are only available for DAY-2 and DELETE operations.
This example demonstrates how to conditionally display an action based on entity properties. It shows the action only on entities where the `environment` property equals `production`:
```
{
"type": "SEARCH",
"rules": [
{
"operator": "=",
"property": "environment",
"value": "production"
}
],
"combinator": "and"
}
```
Filter dropdown options in action forms to show only relevant entities based on properties, relations, or user context.
To configure this, go to the **User Form** tab when setting up entity-type inputs, then expand the [advanced configuration](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/advanced-form-configurations/.md) section where you can define a dataset filter. This is particularly useful for filtering entity options based on the logged-in user or their teams.
This example demonstrates how to filter an entity input dropdown to show only environments owned by the logged-in user's teams. This ensures users can only select environments they have access to:
```
{
"properties": {
"environment": {
"type": "string",
"format": "entity",
"blueprint": "environment",
"dataset": {
"combinator": "and",
"rules": [
{
"property": "team_mirror", // Need to add a mirror property of the Owning team
"operator": "in", // to the environment blueprint
"value": {
"jqQuery": ".user.team"
}
}
]
}
}
}
}
```
[Dynamic permissions](/workflows/actions-and-automations/create-self-service-experiences/set-self-service-actions-rbac/dynamic-permissions/.md) control who can execute or approve actions based on entity properties and user context. When creating or editing an action, go to the **Permissions** tab to configure query-based permissions.
For examples of dynamic action permissions using search and query syntax, see the [examples](/workflows/actions-and-automations/create-self-service-experiences/set-self-service-actions-rbac/dynamic-permissions/examples/.md) page.
## API[](#api "Direct link to API")
You can use search and query syntax with the following API routes: [search entities](/api-reference/search-entities/) and [search a blueprint's entities](/api-reference/search-a-blueprints-entities/).
United States region
The examples below use the EU region API.
If you wish to use the US region API, replace `https://api.port.io` with `https://api.us.port.io`.
The following examples provide a foundation for using the search route. You can modify the `rules` array to match your specific search requirements.
* Python
* Javascript
* cURL
```
# Dependencies to install:
# $ python -m pip install requests
import json
import requests
CLIENT_ID = "YOUR_CLIENT_ID"
CLIENT_SECRET = "YOUR_CLIENT_SECRET"
API_URL = "https://api.port.io/v1"
credentials = {"clientId": CLIENT_ID, "clientSecret": CLIENT_SECRET}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
access_token = f"Bearer {token_response.json()['accessToken']}"
# You can now use the value in access_token when making further requests
headers = {
'Authorization': access_token
}
query = {
"combinator": "or",
"rules": [
{
"property": "$title",
"operator": "=",
"value": "admin-prod"
},
{
"property": "$title",
"operator": "=",
"value": "admin-test"
}
]
}
search_req = requests.post(f"{API_URL}/entities/search", headers=headers, json=query)
search_entities = search_req.json()['entities']
for entity in search_entities:
print(json.dumps(entity))
```
```
// Dependencies to install:
// $ npm install axios --save
const axios = require("axios").default;
const CLIENT_ID = "YOUR_CLIENT_ID";
const CLIENT_SECRET = "YOUR_CLIENT_SECRET";
const API_URL = "https://api.port.io/v1";
(async () => {
const tokenResp = await axios.post(`${API_URL}/auth/access_token`, {
clientId: CLIENT_ID,
clientSecret: CLIENT_SECRET,
});
const accessToken = tokenResp.data.accessToken;
// You can now use the value in accessToken when making further requests
const config = {
headers: {
Authorization: `Bearer ${accessToken}`,
},
};
const query = {
combinator: "or",
rules: [
{
property: "$title",
operator: "=",
value: "admin-prod",
},
{
property: "$title",
operator: "=",
value: "admin-test",
},
],
};
const response = await axios.post(
`${API_URL}/entities/search`,
query,
config
);
console.log(response.data["entities"]);
})();
```
```
#!/bin/bash
# Dependencies to install:
# For apt:
# $ sudo apt-get install jq
# For yum:
# $ sudo yum install jq
access_token=$(curl --location --request POST 'https://api.port.io/v1/auth/access_token' \
--header 'Content-Type: application/json' \
--data-raw '{
"clientId": "CLIENT_ID",
"clientSecret": "CLIENT_SECRET"
}' | jq '.accessToken' | sed 's/"//g')
# The token will be available in the access_token variable
curl --location --request POST 'https://api.port.io/v1/entities/search?attach_title_to_relation=true&exclude_calculated_properties=false' \
--header "Authorization: Bearer $access_token" \
--header 'Content-Type: application/json' \
--data-raw '{
"combinator": "or",
"rules": [
{
"property": "$title",
"operator": "=",
"value": "admin-prod"
},
{
"property": "$title",
"operator": "=",
"value": "admin-test"
}
]
}'
```
---
# Comparison operators
This page details the available comparison operators when writing [rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules) as part of the search route.
### = (Equal)[](#-equal "Direct link to = (Equal)")
The `=` operator checks exact matches of the specified value:
```
{
"operator": "=",
"property": "myProperty",
"value": "myExactValue"
}
```
This operator can also be used to check the value of `boolean` properties:
```
{
"operator": "=",
"property": "myBooleanProperty",
"value": true
}
```
For datetime properties, the `=` operator only supports ISO8601 format strings:
```
{
"operator": "=",
"property": "$createdAt",
"value": "2022-07-26T16:38:06.839Z"
}
```
DateTime format support
The `=` operator only supports ISO8601 format strings for datetime values.
To use preset date ranges (like "lastWeek", "today", etc.), use the [between](#between) or [notBetween](#notbetween) operators instead.
### != (Not Equal)[](#-not-equal "Direct link to != (Not Equal)")
The `!=` operator checks exact matches of the specified value and returns all results that fail to satisfy the check:
```
{
"operator": "!=",
"property": "myProperty",
"value": "myExactValue"
}
```
This operator can also be used to check the value of `boolean` properties:
```
{
"operator": "!=",
"property": "myBooleanProperty",
"value": false
}
```
Not supported on array properties
The `=` and `!=` operators are **not supported** on array-type properties and may produce unexpected or incorrect results. For array properties, use [`containsAny`](#containsany), [`isEmpty`](#isempty), or [`isNotEmpty`](#isnotempty) instead.
However, the `!=` and [`notIn`](#notin) operators work correctly on `string` and enum-valued properties to exclude specific values from results.
### > (Greater Than)[](#-greater-than "Direct link to > (Greater Than)")
The `>` operator checks values larger than the specified value:
```
{
"operator": ">",
"property": "myNumericProperty",
"value": 7
}
```
### >= (Greater Than or Equal)[](#-greater-than-or-equal "Direct link to >= (Greater Than or Equal)")
The `>=` operator checks values larger than or equal to the specified value:
```
{
"operator": ">=",
"property": "myNumericProperty",
"value": 7
}
```
### < (Less Than)[](#-less-than "Direct link to < (Less Than)")
The `<` operator checks values less than the specified value:
```
{
"operator": "<",
"property": "myNumericProperty",
"value": 7
}
```
### <= (Less Than or Equal)[](#-less-than-or-equal "Direct link to <= (Less Than or Equal)")
The `<=` operator checks values less than or equal to the specified value:
```
{
"operator": "<=",
"property": "myNumericProperty",
"value": 7
}
```
### isEmpty[](#isempty "Direct link to isEmpty")
The `isEmpty` operator checks if the value of the specified property is `null`:
```
{
"operator": "isEmpty",
"property": "myProperty"
}
```
### isNotEmpty[](#isnotempty "Direct link to isNotEmpty")
The `isNotEmpty` operator checks if the value of the specified property is not `null`:
```
{
"operator": "isNotEmpty",
"property": "myProperty"
}
```
### propertySchema[](#propertyschema "Direct link to propertySchema")
The `propertySchema` filter can be used with any standard operator. It allows you to filter entities based on a properties matching a specific type (for example, find all string properties with a given value):
* String
* URL
```
{
"propertySchema": {
"type": "string"
},
"operator": "=",
"value": "My value"
}
```
```
{
"propertySchema": {
"type": "string",
"format": "url"
},
"operator": "=",
"value": "https://example.com"
}
```
Using propertySchema in search rules
* The `propertySchema` can be used with any Port [property](/context-lake/data-model/setup-blueprint/properties/overview/.md#supported-properties).
* The `propertySchema` replaces the `property` filter when performing property schema search.
### between[](#between "Direct link to between")
The `between` operator checks datetime values and returns entities whose relevant datetime property matches the given range:
```
{
"operator": "between",
"property": "$createdAt",
"value": {
"preset": "lastWeek"
}
}
```
**Available Presets:**
* `last3Years` - In the past 3 years
* `last2Years` - In the past 2 years
* `last12Months` - In the past 365 days
* `last6Months` - In the past 180 days
* `last3Months` - In the past 90 days
* `lastMonth` - In the past 30 days
* `last2Weeks` - In the past 2 weeks
* `lastWeek` - In the past week
* `lastDay` - In the past day
* `today` - Today
* `tomorrow` - Tomorrow
* `yesterday` - Yesterday
* `nextDay` - In the next day
* `nextWeek` - In the next week
* `next2Weeks` - In the next 2 weeks
* `nextMonth` - In the next 30 days
* `next3Months` - In the next 90 days
* `next6Months` - In the next 180 days
* `next12Months` - In the next 365 days
When using the catalog page UI, these presets are available via the `is` operator when filtering datetime properties.
Future date presets availability
The future date presets (`nextDay`, `nextWeek`, `next2Weeks`, `nextMonth`, `next3Months`, `next6Months`, `next12Months`) are only available in the [catalog page](/interface-builder/port-interface/page/catalog-page/.md) filters and initial filters. They are not supported in table widgets or other locations.
The `between` operator also supports standard date ranges:
```
{
"combinator": "and",
"rules": [
{
"operator": "between",
"property": "$createdAt",
"value": {
"from": "2022-07-26T16:38:06.839Z",
"to": "2022-07-29T17:00:28.006Z"
}
}
]
}
```
### notBetween[](#notbetween "Direct link to notBetween")
The `notBetween` operator checks datetime values and returns entities whose relevant datetime property does not match the given range:
```
{
"operator": "notBetween",
"property": "$createdAt",
"value": {
"preset": "lastWeek"
}
}
```
### contains[](#contains "Direct link to contains")
The `contains` operator checks if the specified value exists within a **string** property:
```
{
"property": "myStringProperty",
"operator": "contains",
"value": "mySubString"
}
```
### doesNotContains[](#doesnotcontains "Direct link to doesNotContains")
The `doesNotContains` operator checks if the specified value **does not** exists in the specified property:
```
{
"operator": "doesNotContains",
"property": "myStringProperty",
"value": "otherValue"
}
```
### containsAny[](#containsany "Direct link to containsAny")
The `containsAny` operator checks if **any** of the specified strings exist in the target **array**:
```
{
"operator": "containsAny",
"property": "myArrayProperty",
"value": ["Value1", "Value2", ...]
}
```
### beginsWith[](#beginswith "Direct link to beginsWith")
The `beginsWith` operator checks if the specified property starts with the specified value:
```
{
"operator": "beginsWith",
"property": "myStringProperty",
"value": "myString"
}
```
### doesNotBeginsWith[](#doesnotbeginswith "Direct link to doesNotBeginsWith")
The `doesNotBeginsWith` operator checks if the specified property **does not** start with the specified value:
```
{
"operator": "doesNotBeginsWith",
"property": "myStringProperty",
"value": "otherValue"
}
```
### endsWith[](#endswith "Direct link to endsWith")
The `endsWith` operator checks if the specified property ends with the specified value:
```
{
"operator": "endsWith",
"property": "myStringProperty",
"value": "myString"
}
```
### doesNotEndsWith[](#doesnotendswith "Direct link to doesNotEndsWith")
The `doesNotEndsWith` operator checks if the specified property **does not** end with the specified value:
```
{
"operator": "doesNotEndsWith",
"property": "myStringProperty",
"value": "otherValue"
}
```
### in[](#in "Direct link to in")
The `in` operator checks if a `string` property is equal to one or more specified `string` values:
* Standard
* Dynamic Filter
```
{
"property": "myStringProperty",
"operator": "in",
"value": ["Value1", "Value2"]
}
```
In order to filter entities that **belong to one or more of your teams** you can use the special `My Teams` filter:
```
{
"property": "$team",
"operator": "in",
"value": ["My Teams"]
}
```
You can also use the `My Teams` filter in the UI:
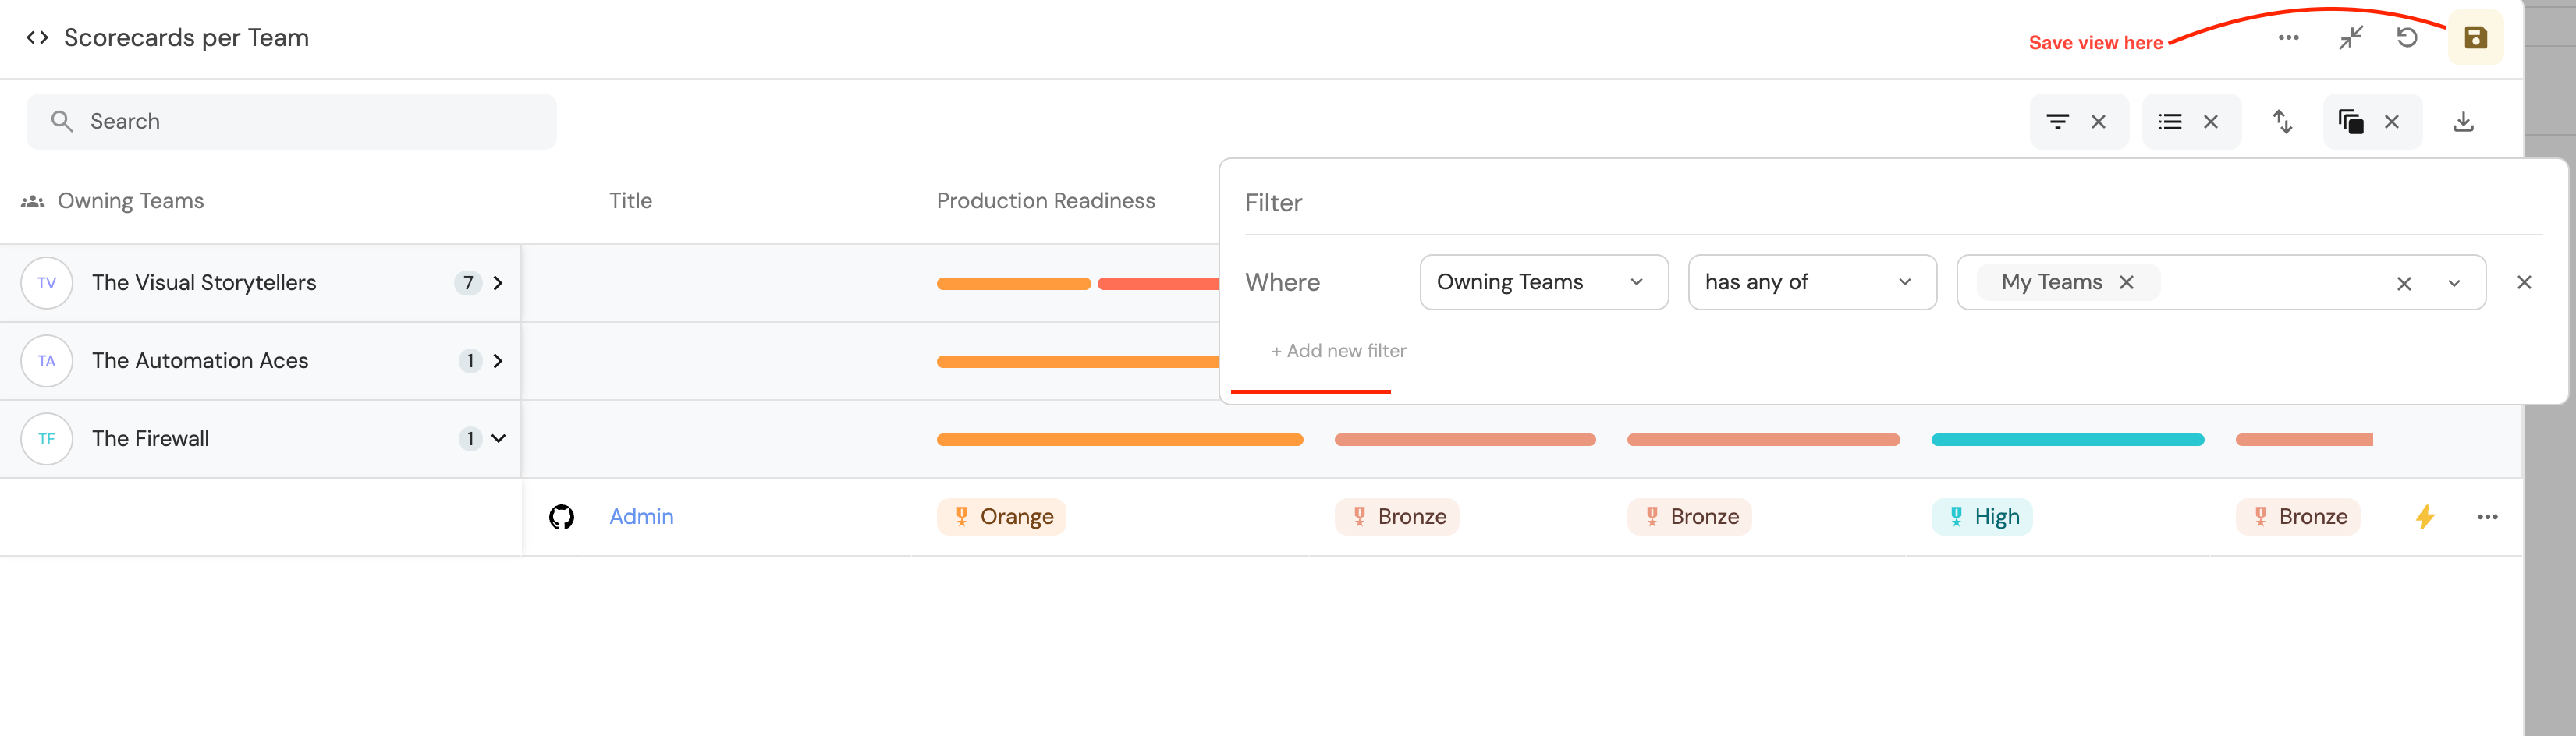
### notIn[](#notin "Direct link to notIn")
The `notIn` operator checks if a `string` property is **not equal** to all of the specified `string` values:
```
{
"property": "myStringProperty",
"operator": "notIn",
"value": ["Value1", "Value2"]
}
```
---
# Relation operators
This page details the available relation operators when writing [rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules) as part of the search route.
## RelatedTo[](#relatedto "Direct link to RelatedTo")
The `relatedTo` operator will return all entities that have a relationship with the specified entity:
### Structure[](#structure "Direct link to Structure")
| Field | Description |
| ----------- | ------------------------------------------------------------------------------------------ |
| `operator` | Search operator to use when evaluating this rule, see a list of available operators below. |
| `blueprint` | Blueprint of the entity identifier specified in the `value` field. |
| `value` | Value to filter by. |
```
{
"operator": "relatedTo",
"blueprint": "myBlueprint",
"value": "myEntity"
}
```
The operator also supports multiple related entities as the searched value:
```
{
"operator": "relatedTo",
"blueprint": "myBlueprint",
"value": ["myFirstEntity", "mySecondEntity"]
}
```
This query will return all of the entities that are related to one or more of the identifiers in the value array.
### Required[](#required "Direct link to Required")
The `relatedTo` operator also supports the `required` property - which allows you to search for:
* Related entities from all relations (relations with either required `true` or `false`).
* Related entities only from required relations (relations with required `true`).
* Related entities only from non-required relations (relations with required `false`).
For example, to search only for related entities that *require* the `myEntity` entity from the `myBlueprint` blueprint, use the following search rule:
```
{
"operator": "relatedTo",
"required": true,
"value": "myEntity",
"blueprint": "myBlueprint"
}
```
### Direction[](#direction "Direct link to Direction")
The `relatedTo` operator also supports the `direction` property - which allows you to search for dependent entities in a specific direction on the dependency graph. To better understand the functionality of this property, let's take a look at the example below:
Let's assume that we have the blueprints `deploymentConfig` and `microservice` with the following relation definition (declared on the `deploymentConfig` blueprint):
```
"relations": {
"microservice": {
"description": "The service this Deployment Config belongs to",
"many": false,
"required": false,
"target": "microservice",
"title": "Microservice"
}
}
```
In addition, we have the following entities:
```
Deployment Configs:
- Order-Service-Production
- Cart-Service-Production
Microservices:
- Order Service
- Cart Service
Environments:
- Production
```
And the following relations:
```
Order-Service-Production -> Order-Service
Order-Service-Production -> Production
Cart-Service-Production -> Cart-Service
Cart-Service-Production -> Production
```
By looking at the resulting graph layout, we can also map the directions:
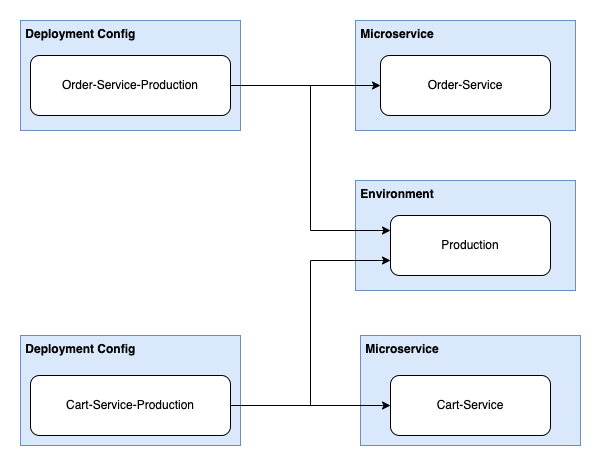
* To search for entities which the source depends on - use `"direction": "upstream"`.
* To search for entities which depend on the source - use `"direction": "downstream"`.
In the example shown above, if we want to get the `Microservice` and `Environment` that *Order-Service-Production* depends on, the search rule would be:
```
{
"operator": "relatedTo",
"blueprint": "deploymentConfig",
"value": "Order-Service-Production",
"direction": "upstream"
}
```
And the result shall be:
**Order-Service-Production upstream related entities (click to expand)**
```
{
"ok": true,
"matchingBlueprints": ["microservice", "environment"],
"entities": [
{
"identifier": "Order-Service",
"title": "Order-Service",
"blueprint": "microservice",
"properties": {
"on-call": "mor@getport.io",
"language": "Python",
"slack-notifications": "https://slack.com/Order-Service",
"launch-darkly": "https://launchdarkly.com/Order-Service"
},
"relations": {},
"createdAt": "2022-11-17T15:54:20.432Z",
"createdBy": "auth0|62ab380295b34240aa511cdb",
"updatedAt": "2022-11-17T15:54:20.432Z",
"updatedBy": "auth0|62ab380295b34240aa511cdb"
},
{
"identifier": "Production",
"title": "Production",
"blueprint": "environment",
"properties": {
"awsRegion": "eu-west-1",
"configUrl": "https://github.com/config-labs/kube/config.yml",
"slackChannel": "https://yourslack.slack.com/archives/CHANNEL-ID",
"onCall": "Mor P",
"namespace": "Production"
},
"relations": {},
"createdAt": "2022-09-19T08:54:23.025Z",
"createdBy": "Cnc3SiO7T0Ld1y1u0BsBZFJn0SCiPeLS",
"updatedAt": "2022-10-16T09:28:32.960Z",
"updatedBy": "auth0|62ab380295b34240aa511cdb"
}
]
}
```
If we want to get all of the `deploymentConfigs` that are deployed in the *Production* `Environment`, the search rule would be:
```
{
"operator": "relatedTo",
"blueprint": "environment",
"value": "Production",
"direction": "downstream"
}
```
And the result shall be:
**Production downstream related entities (click to expand)**
```
{
"ok": true,
"matchingBlueprints": ["deploymentConfig"],
"entities": [
{
"identifier": "Order-Service-Production",
"title": "Order-Service-Production",
"blueprint": "deploymentConfig",
"properties": {
"url": "https://github.com/port-labs/order-service",
"config": {
"encryption": "SHA256"
},
"monitor-links": [
"https://grafana.com",
"https://prometheus.com",
"https://datadog.com"
]
},
"relations": {
"microservice": "Order-Service",
"environment": "Production"
},
"createdAt": "2022-11-17T15:55:55.591Z",
"createdBy": "auth0|62ab380295b34240aa511cdb",
"updatedAt": "2022-11-17T15:55:55.591Z",
"updatedBy": "auth0|62ab380295b34240aa511cdb"
},
{
"identifier": "Cart-Service-Production",
"title": "Cart-Service-Production",
"blueprint": "deploymentConfig",
"properties": {
"url": "https://github.com/port-labs/cart-service",
"config": {
"foo": "bar"
},
"monitor-links": [
"https://grafana.com",
"https://prometheus.com",
"https://datadog.com"
]
},
"relations": {
"microservice": "Cart-Service",
"environment": "Production"
},
"createdAt": "2022-11-17T15:55:10.714Z",
"createdBy": "auth0|62ab380295b34240aa511cdb",
"updatedAt": "2022-11-17T15:55:20.253Z",
"updatedBy": "auth0|62ab380295b34240aa511cdb"
}
]
}
```
## MatchAny[](#matchany "Direct link to MatchAny")
The `matchAny` operator will match entities based on your input:
* If you specify a single value, it will find all entities with the same identifier.
* If you provide a list of values, it will match any entity whose identifier is in the list.
### Related to by specific path[](#related-to-by-specific-path "Direct link to Related to by specific path")
You can search for entities that are related through a specific path of relations. This is useful when you want to find entities that are connected through a specific chain of relationships.
### Structure[](#structure-1 "Direct link to Structure")
| Field | Description |
| ------------------------ | -------------------------------------------------------------------------------------------------------------------- |
| `property.path` | An array containing the full path of relation identifiers to traverse. |
| `property.fromBlueprint` | *(Optional)* The blueprint to start the path traversal from. If omitted, traversal starts from the target blueprint. |
| `operator` | The search operator to use. For this feature, use `"matchAny"`. |
| `value` | The value or list of values to match against the target entity identifiers at the end of the path. |
#### For upstream paths[](#for-upstream-paths "Direct link to For upstream paths")
```
{
"property": {
"path": ["relation1", "relation2", "relation3"]
},
"operator": "matchAny",
"value": "targetEntity"
}
```
#### For downstream paths[](#for-downstream-paths "Direct link to For downstream paths")
```
{
"property": {
"path": ["relation1", "relation2", "relation3"],
"fromBlueprint": "sourceBlueprint"
},
"operator": "matchAny",
"value": "targetEntity"
}
```
When using downstream paths, the `fromBlueprint` parameter specifies the source blueprint from which to start the path traversal.
Instead of thinking about the path as downstream from the target, we treat it as upstream from the specified blueprint to the target blueprint. This means that the path will be traversed starting from entities of the specified `fromBlueprint`.
### Examples[](#examples "Direct link to Examples")
Suppose you have the following data model:
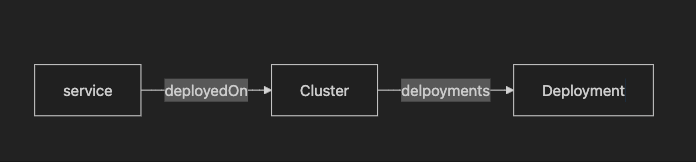
#### Find all services related to a cluster (upstream)
To find all services that are related to a specific cluster (e.g., "production-cluster"):
```
{
"combinator": "and",
"rules": [
{
"property": "$blueprint",
"operator": "=",
"value": "service"
},
{
"property": {
"path": ["deployedOn"]
},
"operator": "matchAny",
"value": "production-cluster"
}
]
}
```
This will return all **services** that have a deployment in the "production-cluster".
***
#### Example 2: Find all deployments related to a specific service (downstream)
To find all deployments related to a specific service (e.g., "production-service"):
```
{
"combinator": "and",
"rules": [
{
"property": "$blueprint",
"operator": "=",
"value": "deployment"
},
{
"property": {
"path": ["deployedOn", "deployments"],
"fromBlueprint": "service"
},
"operator": "matchAny",
"value": "production-service"
}
]
}
```
This will return all **deployments** that are related to the "production-service".
***
#### Contextual values[](#contextual-values "Direct link to Contextual values")
You can combine relation-path filters with [contextual query rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#contextual-query-rules) to dynamically filter entities based on the current user. This is useful when you need to filter entities based on ownership derived from related entities.
The following rule filters entities where the owner is derived from a **directly related entity**:
```
{
"combinator": "and",
"rules": [
{
"operator": "matchAny",
"property": {
"path": ["relationID_1"]
},
"value": {
"context": "user",
"property": "$identifier"
}
}
]
}
```
This will return all entities where the related entity (via `relationID_1`) matches the current user's identifier.
You can also traverse **multiple relations** to find ownership. The following rule filters entities where the owner is derived by traversing through two related entities:
```
{
"combinator": "and",
"rules": [
{
"operator": "matchAny",
"property": {
"path": ["relationID_1", "relationID_2"]
},
"value": {
"context": "user",
"property": "$identifier"
}
}
]
}
```
This will return all entities where the entity at the end of the relation chain (traversing `relationID_1` → `relationID_2`) matches the current user's identifier.
In the above examples:
* `property.path` specifies the chain of relations to traverse (replace the relation names with your actual relation identifiers).
* The contextual `value` dynamically resolves to the current user's identifier.
* The `matchAny` operator matches entities where the value at the end of the relation path equals the contextual value.
## Self-relation[](#self-relation "Direct link to Self-relation")
Self-relations allow a blueprint to reference itself, so entities of the same type can be connected.
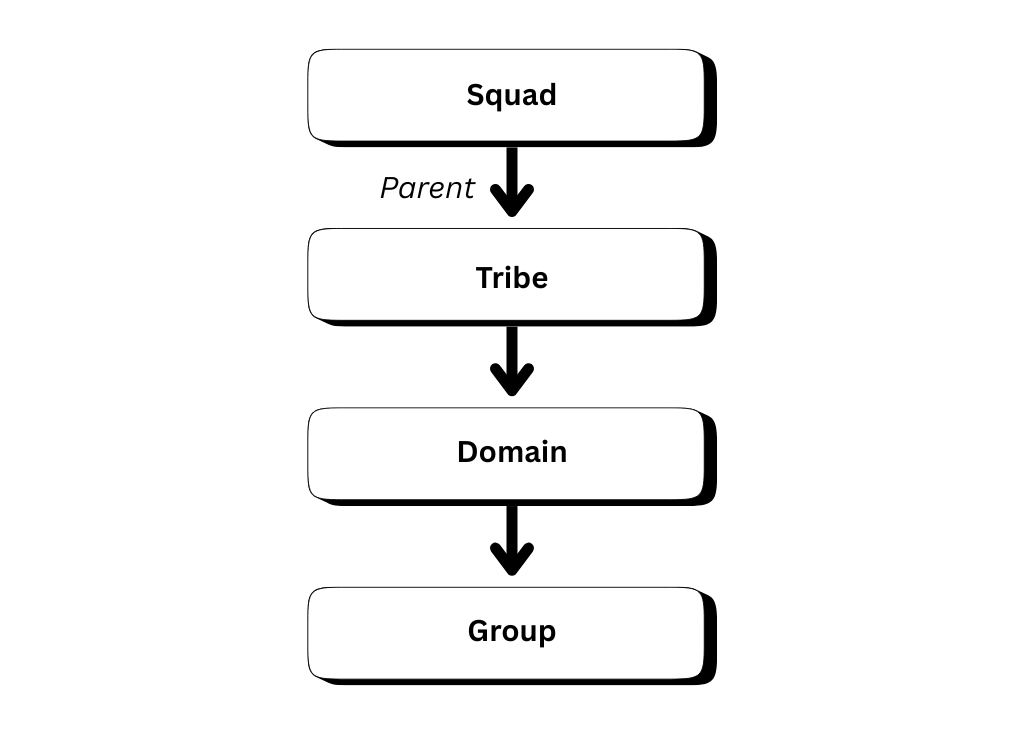
In this example, a **group** is comprised of one or more **domains**, which are comprised of one or more **tribes**, and so on.
The diagram illustrates the hierarchy, where different entities are linked by the same self-relation (parent) within the `Team` blueprint.
You can use the `matchAny` operator to search through self-relations, allowing you to find entities at various levels of the hierarchy.
### Examples[](#examples-1 "Direct link to Examples")
**Example 1: basic self-relation with fixed hops count**
If you want **exactly 2 hops**, specify the self-relation twice:
```
{
"combinator": "and",
"rules": [
{
"property": {
"path": [
"parent",
"parent"
],
"fromBlueprint" : "Team"
},
"operator": "matchAny",
"value": "targetEntity"
}
]
}
```
For example, if the `value` is `Squad`:
* First hop: `Squad` → `Tribe`.
* Second hop: `Tribe` → `Domain`.
Result: `Domain` (only the final destination after exactly 2 hops).
***
**Example 2: self-relation with maxHops for variable hops**
If you want a variable number of hops (between 1 and 15), use `maxHops`.
`maxHops` specifies the maximum number of hops to traverse through the self-relation.
```
{
"combinator": "and",
"rules": [
{
"property": {
"path": [
{
"relation": "parent",
"maxHops": 3
}
],
"fromBlueprint": "Team"
},
"operator": "matchAny",
"value": "targetEntity"
}
]
}
```
For example, if the `value` is `Squad`:
* First hop: `Squad` → `Tribe`.
* Second hop: `Tribe` → `Domain`.
* Third hop: `Domain` → `Group`.
Result: `Tribe`, `Domain` and `Group` (all entities found along the path up to 3 hops).
maxHops limitation
The `maxHops` parameter can only be applied **once** per path, and it accepts values from **1 to 15**.
***
**Example 3: mixed approach**
You can also mix fixed hops with variable hops. For example, if you specify the self-relation twice followed by a `maxHops` object, the system will start traversing from the 2 hops already made and continue with the additional hops specified in `maxHops`.
```
{
"combinator": "and",
"rules": [
{
"property": {
"path": [
"parent",
"parent",
{
"relation": "parent",
"maxHops": 3
}
],
"fromBlueprint": "Team"
},
"operator": "matchAny",
"value": "targetEntity"
}
]
}
```
For example, if the `value` is `Squad`:
* First hop: `Squad` → `Tribe`.
* Second hop: `Tribe` → `Domain`.
* Third hop: `Domain` → `Group`.
Result: `Domain` (from fixed hops) and `Group` (from variable hops, up to 3 additional hops).
---
# API access & search
Port's search and query syntax provides a powerful way to filter and retrieve data from your software catalog. You can use this syntax across the Port product to dynamically filter entities, control permissions, configure automations, and more.
## Where to use search & query?[](#where-to-use-search--query "Direct link to Where to use search & query?")
You can use the search and query syntax in the following areas:
* **Catalog pages** - Initial filters for pages and tables.
* **Entity pages** - Filters for custom related entity tabs.
* **Dashboard widgets** - Dashboard-level filters and widget-specific filters for [data widgets](/interface-builder/port-interface/dashboards/data-widgets/.md).
* **Blueprint read permissions** - Dynamic `policy` rules to control which entities users can see.
* **Aggregation properties** - Filters to determine which entities are included in [aggregation calculations](/context-lake/data-model/setup-blueprint/properties/aggregation-property/.md).
* **Scorecards** - Filters to determine which entities a rule evaluates.
* **Self-service actions** - Action conditions, entity input datasets, and dynamic permissions.
* **API** - Search endpoints ([search entities](/api-reference/search-entities/) and [search a blueprint's entities](/api-reference/search-a-blueprints-entities/)).
For practical examples of using search & query in each of these areas, see the [examples](/context-lake/consuming-the-lake/search-and-query/examples/.md) page.
## Common queries usage[](#common-queries-usage "Direct link to Common queries usage")
High quality search is essential to effectively track assets in your software catalog.
Using Port's search you can:
* Find all running services that are not healthy.
* List all libraries that have known vulnerabilities.
* Filter all services running in a specific cluster (in a query or self service form).
* Catalog initial filters based on the logged in user's properties.
## Examples[](#examples "Direct link to Examples")
Refer to the [examples](/context-lake/consuming-the-lake/search-and-query/examples/.md) page for practical code snippets for search.
## Advanced[](#advanced "Direct link to Advanced")
Refer to the [advanced](/context-lake/consuming-the-lake/search-and-query/advanced/.md) page for advanced search use cases and outputs.
---
# Structure & syntax
This page details the structure and syntax used to build search queries in Port, including how to construct search requests, define rules, use combinators, and apply operators to filter entities.
## Search request[](#search-request "Direct link to Search request")
A search request contains filters and rules to find matching [entities]() in your software catalog.
To search for entities using the API, see the [search](/api-reference/search-a-blueprints-entities/) route.
A search request is comprised of the following elements:
| Field | Description |
| ------------ | ---------------------------------------------------------- |
| `combinator` | Defines the logical operation to apply to the query rules. |
| `rules` | An array of search rules to filter results with. |
For example:
```
{
"combinator": "and",
"rules": [
{
"property": "$blueprint",
"operator": "=",
"value": "myBlueprint"
},
{
"property": "$identifier",
"operator": "contains",
"value": "myIdentifierPart"
}
]
}
```
The query above searches for all entities based on the `myBlueprint` blueprint whose `identifier` contains the string `myIdentifierPart`.
## Combinator[](#combinator "Direct link to Combinator")
There are two available combinators:
* `and` - will apply a logical AND operation between all rules, requiring all of them to satisfy for a given asset in order to return it.
* `or` - will apply a logical OR operation between all rules, requiring at least one of them to satisfy for a given asset in order to return it.
single rule queries
If you only have a single rule in your query, the combinator has no effect. But keep in mind that it still needs to be included to adhere to the query structure.
**Single rule query example (click to expand)**
In the following example, only a single rule appears in the `rules` array, so the `combinator` field has no effect:
```
{
"combinator": "and",
"rules": [
{
"property": "$blueprint",
"operator": "=",
"value": "myBlueprint"
}
]
}
```
* And
* Or
```
{
"combinator": "and",
"rules": [
{
"property": "$blueprint",
"operator": "=",
"value": "myBlueprint"
},
{
"property": "$identifier",
"operator": "contains",
"value": "myIdentifierPart"
}
]
}
```
```
{
"combinator": "or",
"rules": [
{
"property": "$blueprint",
"operator": "=",
"value": "myBlueprint"
},
{
"property": "$identifier",
"operator": "contains",
"value": "myIdentifierPart"
}
]
}
```
### Nested queries[](#nested-queries "Direct link to Nested queries")
Rules can be nested, An item in the `rules` array can itself be a `{combinator, rules}` object, allowing you to build complex boolean logic:
```
{
"combinator": "or",
"rules": [
{
"combinator": "and",
"rules": [
{ "property": "language", "operator": "=", "value": "Python" },
{ "property": "tier", "operator": "=", "value": "production" }
]
},
{
"combinator": "and",
"rules": [
{ "property": "language", "operator": "=", "value": "Go" },
{ "property": "tier", "operator": "=", "value": "critical" }
]
}
]
}
```
The query above matches entities that are **either** (Python AND production) **or** (Go AND critical).
No short-circuit evaluation
All rules in a query are evaluated simultaneously and there is no short-circuit logic. For example, if the top-level combinator is `"or"` with five nested rule groups, all five groups are evaluated for every entity even if the first group already matches. The `"or"` combinator means an entity is included in the results if **at least one** group matches, but it does not skip evaluating the remaining groups.
## Rules[](#rules "Direct link to Rules")
A search rule is a small filtering unit, used to control the search output.
Here is an example search rule:
```
{
"property": "$blueprint",
"operator": "=",
"value": "microservice"
}
```
Port has 2 types of search rule operators:
1. Comparison (e.g. `=`, `>`).
2. Relation (e.g. `relatedTo`).
### Comparison operators[](#comparison-operators "Direct link to Comparison operators")
#### Structure[](#structure "Direct link to Structure")
| Field | Description |
| ---------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `operator` | Search operator to use when evaluating this rule, see a list of available operators below |
| `property` | Property to filter by according to its value. It can be a [meta-property](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md) such as `$identifier`, or one of the [standard properties](/context-lake/data-model/setup-blueprint/properties/overview/.md#available-properties) |
| `value` | The value to filter by |
#### Operators[](#operators "Direct link to Operators")
A wide variety of operators are available, see them [here](/context-lake/consuming-the-lake/search-and-query/operators/comparison-operators/.md).
***
### Relation operators[](#relation-operators "Direct link to Relation operators")
Several relation-based operators are available, see them [here](/context-lake/consuming-the-lake/search-and-query/operators/relation-operators/.md).
### Contextual query rules[](#contextual-query-rules "Direct link to Contextual query rules")
Contextual query rules inject the logged-in user's identity into a query at evaluation time, allowing you to access that user's properties and/or owning teams. You can mix contextual query rules freely with other rules as part of your queries.
#### Where contextual query rules are supported[](#where-contextual-query-rules-are-supported "Direct link to Where contextual query rules are supported")
| Location | Supported | Notes |
| ----------------------------------- | --------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Catalog page initial filters | ✅ | Filter entities shown on a catalog page based on the viewer |
| Dashboard widget filters | ✅ | Scope chart/table widgets to the logged-in user |
| Self-service action `dataset` rules | ✅ | Filter entities in an [entity input](/workflows/actions-and-automations/create-self-service-experiences/setup-ui-for-action/user-inputs/entity/.md) dropdown |
| API search requests | ✅ | Context is derived from the API token's associated user |
Use contextual rules instead of dynamic properties
The older [dynamic properties](#dynamic-properties) syntax (`{{getUserTeams()}}`) is deprecated. Contextual query rules are the replacement, they work in all the same places **including** self-service action inputs and API requests.
#### How to use contextual query rules[](#how-to-use-contextual-query-rules "Direct link to How to use contextual query rules")
This can be used in either the `property` or `value` key in a query rule:
* Property
* Value
```
{
...other rule keys
"property": {
"context": "user" | "userTeams",
"property": "prop"
}
}
```
```
{
...other rule keys
"value": {
"context": "user" | "userTeams",
"property": "prop"
}
}
```
#### Available contexts[](#available-contexts "Direct link to Available contexts")
| Context | Description |
| ----------- | ----------------------------------------------------------------- |
| `user` | The entity of the user triggering the query |
| `userTeams` | The entities of the owning teams of the user triggering the query |
#### Usage examples[](#usage-examples "Direct link to Usage examples")
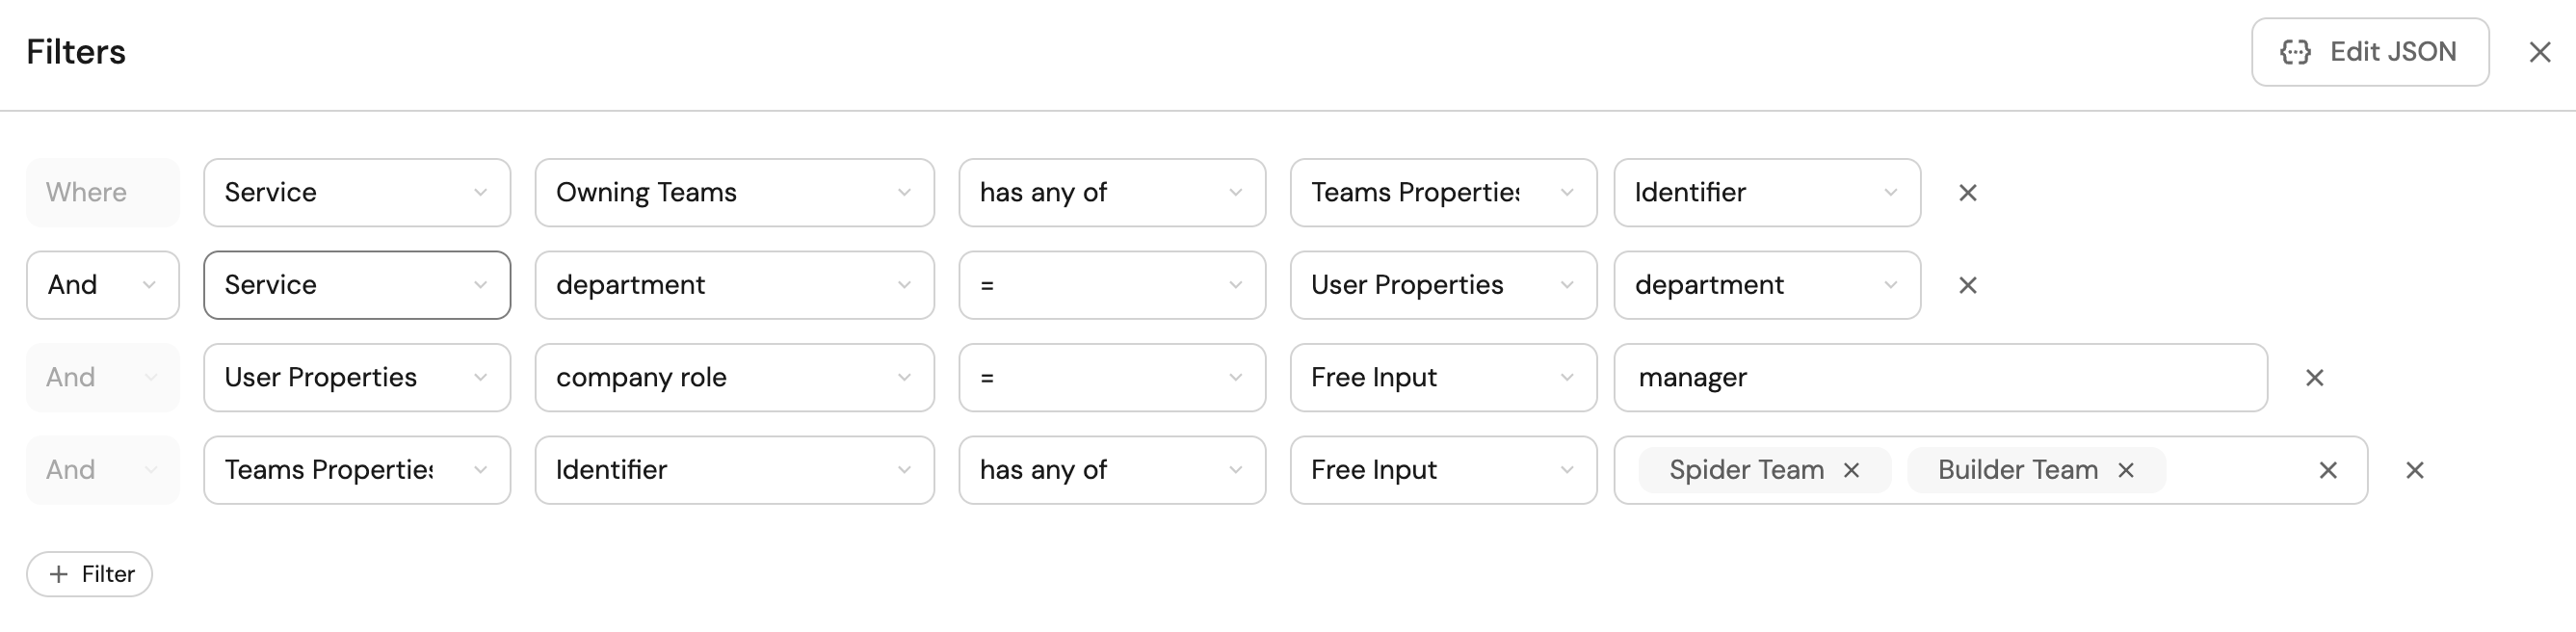
The following rule will result in the entities owned by any one of the user's teams:
```
[
...other rules
{
"property": "$team",
"operator": "containsAny",
"value": {
"context": "userTeams",
"property": "$identifier"
}
}
]
```
The following rule will result in entities with the same department as the user's:
```
[
...other rules
{
"property": "department",
"operator": "=",
"value": {
"context": "user",
"property": "department"
}
}
]
```
The following rule asserts that only users with `manager` role will get the resulting entities:
```
[
...other rules
{
"property": {
"context": "user",
"property": "company_role"
},
"operator": "=",
"value": "manager"
}
]
```
The following rule asserts that only users in the user's team/s will get the resulting entities:
```
[
...other rules
{
"property": {
"context": "userTeams",
"property": "$identifier"
},
"operator": "containsAny",
"value": ["Spider Team", "Builder Team"]
}
]
```
For examples of using contextual values with relation path filters, see [filter with contextual values](/context-lake/consuming-the-lake/search-and-query/operators/relation-operators/.md#filter-with-contextual-values).
### Filter by relations/scorecards[](#filter-by-relationsscorecards "Direct link to Filter by relations/scorecards")
When using the [search a blueprint's entities](/api-reference/search-a-blueprints-entities/) API route, you can also filter results by [relations]() or [scorecards]().
See the following examples for each filter type:
* Relation
* Scorecard
* Scorecard rule
```
{
"relation": "relationId",
"operator": "=",
"value": "value"
}
```
```
{
"scorecard": "scorecardId",
"operator": "=",
"value": "Bronze"
}
```
```
{
"scorecard": "scorecardId",
"scorecardRule": "scorecardRuleId",
"operator": "=",
"value": "Bronze"
}
```
### Dynamic properties[](#dynamic-properties "Direct link to Dynamic properties")
Deprecated, use contextual query rules instead
Dynamic properties are deprecated and will be discontinued soon. Use [contextual query rules](#contextual-query-rules) instead, which work in more places and provide access to the full user/team entity.
When using Port's UI, you can use properties of the logged-in user when writing rules by using the following functions:
* `getUserTeams` - a list of the teams the user belongs to.
* `getUserEmail` - the user's email.
* `getUserFullName` - the user's full name.
* `blueprint` - the blueprint identifier of the current page.
UI only & not supported in self-service actions
These functions are evaluated **only** in Port's UI context: [catalog page](/interface-builder/port-interface/page/catalog-page/.md#page-creation) initial filters and [dashboard widget](/interface-builder/port-interface/dashboards/custom-widgets/.md#chart-filters) filters. They are **not** evaluated in self-service action schemas (e.g., `dataset` rules on entity inputs) or API requests. Using them there will yield empty values. For action inputs, use [contextual query rules](#contextual-query-rules) instead.
#### Usage examples[](#usage-examples-1 "Direct link to Usage examples")
```
[
{
"property": "$team",
"operator": "containsAny",
"value": ["{{getUserTeams()}}"]
}
]
```
```
[
{
"property": "emails",
"operator": "contains",
"value": "{{getUserEmail()}}"
}
]
```
```
[
{
"property": "name",
"operator": "=",
"value": "{{getUserFullName()}}"
}
]
```
```
[
{
"property": "$blueprint",
"operator": "=",
"value": "{{blueprint}}"
}
]
```
---
# Data model
[YouTube video player](https://www.youtube.com/embed/5-JE7EUKcf4)
Your data model is the schema layer of your [context lake](/context-lake/overview/.md) - it defines what the things your organization cares about are called, what properties describe them, and how they relate to one another.
Combined with [data ingestion](/context-lake/ingestion/overview/.md), which populates that schema with real, live entities, the data model turns your software catalog into an **organizational semantic layer**: something AI agents, workflows, and dashboards can query and act on with full context.
## Blueprints, properties, and relations[](#blueprints-properties-and-relations "Direct link to Blueprints, properties, and relations")
[Blueprints](/context-lake/data-model/setup-blueprint/overview/.md) are the basic building block of your data model - each one represents an asset in your organization, such as a microservice, a Kubernetes cluster, or a cloud account. A blueprint is made up of [properties](/context-lake/data-model/setup-blueprint/properties/overview/.md), the customizable fields that hold the data ingested for that asset, and connected to other blueprints through [relations](/context-lake/data-model/setup-blueprint/relate-blueprints/.md), the logical connections between them (for example, a service *depends on* a package, or a deployment *runs in* an environment).
Port's [plug & play integrations](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#available-plug--play-integrations) come with predefined blueprints, properties, and relations out of the box, but you can freely edit them or create your own to match your organization's structure.
Editing the data model can be done from the UI, Port's API, or simply by describing the change in natural language through [Port's AI assistant](/port-ai/port-ai-assistant/.md) or an agent connected via the [Port MCP server](/agent-management/port-mcp-server/overview/.md).
## Define your ontology[](#define-your-ontology "Direct link to Define your ontology")
A schema alone tells Port what fields exist. An [ontology](/context-lake/data-model/define-your-ontology/.md) tells it what those fields *mean* - through descriptions on blueprints and properties, semantic relation titles, and well-chosen property types. This is what lets AI agents reason about your catalog correctly instead of just reading raw values.
## Manage your data model as code[](#manage-your-data-model-as-code "Direct link to Manage your data model as code")
If you prefer to version-control your data model alongside your infrastructure, Port's data model can be defined and managed using [Terraform](/context-lake/data-model/iac/terraform-managed-blueprint/.md) or [Pulumi](/context-lake/data-model/iac/pulumi-managed-blueprint/.md), in addition to the UI, API, and Port AI.
---
# Define your ontology
In Port, your data model is more than a schema - it is an ontology. A schema tells a system what fields exist. An ontology tells a system what those fields *mean*.
This distinction matters enormously for AI agents. When an agent queries your context lake, it reads descriptions, relation titles, and property types to understand your organization's structure and make decisions. A schema without semantic meaning is a structure humans can browse. An ontology with semantic meaning is a knowledge graph agents can traverse and act on.
This page covers various elements that give your context lake ontological meaning:
## Blueprint and property descriptions[](#blueprint-and-property-descriptions "Direct link to Blueprint and property descriptions")
The `description` field on a blueprint and on each of its properties is how you communicate intent to agents and to future humans reading the model.
Create in Port
```
{
"identifier": "service",
"title": "Service",
"description": "A deployable unit of software owned by a team. Represents a microservice, backend API, or frontend application tracked in the catalog.",
"schema": {
"properties": {
"on_call": {
"type": "string",
"format": "user",
"title": "On-call engineer",
"description": "The engineer currently on-call for this service. Updated automatically from PagerDuty."
},
"tier": {
"type": "string",
"title": "Service tier",
"description": "Business criticality of this service. Tier 1 = customer-facing revenue path. Tier 2 = internal platform dependency. Tier 3 = non-critical tooling.",
"enum": ["tier-1", "tier-2", "tier-3"]
}
}
}
}
```
**Write descriptions as if explaining to a new team member who has no context.** The agent has exactly the same level of familiarity.
* The blueprint description should explain *what this entity represents* in your organization, not just what the word means generically.
* Property descriptions should explain *what the value means*, where it comes from, and any implicit conventions (for example, which team owns it, or what the expected format is).
These descriptions are read by Port AI when it queries the catalog, by custom agents when they plan their next action, and by external agents connecting via the MCP server. They are also rendered in the UI when a user hovers over the info icon on a property.
## Relation titles and descriptions[](#relation-titles-and-descriptions "Direct link to Relation titles and descriptions")
Relations are the edges of your knowledge graph. The `title` you give a relation is the semantic label of that edge — it is how agents understand the connection between two blueprints. The `description` explains why the edge exists and what it means to traverse it.
```
{
"relations": {
"owned_by": {
"title": "Owned by",
"description": "The team responsible for this service's development and on-call. Used to route incidents, enforce ownership-based permissions, and calculate team workload.",
"target": "team",
"required": false,
"many": false
},
"runs_in": {
"title": "Runs in",
"description": "The cloud environment (production, staging, dev) where this service is currently deployed. Many-to-many: a service can run in multiple environments simultaneously.",
"target": "environment",
"required": false,
"many": true
},
"depends_on": {
"title": "Depends on",
"description": "Upstream services this service calls at runtime. Used to calculate blast radius during incidents and map the impact of a degraded dependency.",
"target": "service",
"required": false,
"many": true
}
}
}
```
**Titles** provide the semantic label. Compare these two for the same structural edge:
| Vague title | Semantic title |
| ----------- | -------------- |
| `team` | `Owned by` |
| `env` | `Runs in` |
| `svc` | `Depends on` |
The vague titles are technically correct but semantically silent. When an agent asks *"which team is responsible for the payment service?"*, it needs to traverse the `Owned by` edge — not figure out that `team` might mean ownership.
**Descriptions** resolve ambiguity that a title alone cannot. A service can *own*, *use*, *deploy to*, or *report to* a team in different contexts — all of which would share the same target blueprint. The description is what tells an agent which kind of connection this is, when to traverse it, and what it means in your organization's domain.
## Property types as semantic signals[](#property-types-as-semantic-signals "Direct link to Property types as semantic signals")
Choosing a property type is not just a validation decision — it is a semantic declaration. Port offers [several property types](/context-lake/data-model/setup-blueprint/properties/overview/.md#supported-properties), and each one signals something different about the value.
| When you use this type | The agent understands |
| ---------------------- | --------------------------------------------------------------------------------------------------------------- |
| `team` | This value is a Port team — it has members, a manager, and can be used for ownership and permission resolution. |
| `user` | This value is a Port user — it has an email, role, and team memberships. |
| `url` | This value is a navigable link to an external resource (dashboard, repository, runbook). |
| `boolean` | This is a binary flag. The agent can use it as a condition without parsing string values. |
| `number` | This is a numeric measure. The agent can compare, rank, and threshold on it. |
| `string` | This is free-form text. The agent cannot make structural assumptions about it. |
Using `string` for a value that is structurally a team name, a URL, or a numeric count deprives the agent of the semantic signal it needs to reason correctly. An agent that sees a `team`-typed `owned_by` property can immediately resolve ownership, query that team's properties, and apply team-based permissions. An agent that sees a `string` field named `owner` has to guess.
The same principle applies to format specifiers like `date-time`, `email`, and `ipv4`: they narrow the value's meaning and give agents precise handling rules.
## Enum values with descriptions[](#enum-values-with-descriptions "Direct link to Enum values with descriptions")
Enums define the vocabulary of a field. Without a description, an agent can only infer meaning from the value string itself.
```
{
"severity": {
"type": "string",
"title": "Severity",
"description": "Impact level of this incident on users and revenue. critical = complete service outage or data loss. high = major feature unavailable, no workaround. medium = degraded performance, workaround exists. low = cosmetic or minor issue, no user impact.",
"enum": ["critical", "high", "medium", "low"]
}
}
```
Put the per-value meaning directly in the property `description`. Explain:
* What each value represents in your organization's conventions.
* What conditions or thresholds map to each value.
* How the value is set (manually, automatically, by an SLA policy, etc.).
An agent asked to *"escalate all critical incidents in the payment service"* can only act correctly if it knows that `critical` means complete outage, not just "bad". An agent asked to *"create an incident with appropriate severity"* needs the vocabulary to make that judgment.
***
Taken together, these elements transform your context lake from a record store into a knowledge graph. Every description you write, every relation title you choose, every property type you select, and every enum definition you annotate is a piece of ontological signal that makes the graph richer for both agents and humans.
For the technical fields and configuration options, see [set up blueprints](/context-lake/data-model/setup-blueprint/overview/.md), [properties](/context-lake/data-model/setup-blueprint/properties/overview/.md), and [relate blueprints](/context-lake/data-model/setup-blueprint/relate-blueprints/.md).
---
# Pulumi-Managed Blueprint Example
This example includes a complete [blueprint](/context-lake/data-model/setup-blueprint/overview/.md) resource definition in Pulumi, which includes:
* [Blueprint](/context-lake/data-model/setup-blueprint/overview/.md?definition=pulumi#configure-blueprints-in-port) definition examples.
* All [property](/context-lake/data-model/setup-blueprint/properties/overview/.md) type definitions.
* [Relation](/context-lake/data-model/setup-blueprint/relate-blueprints/.md?definition=pulumi#configure-relations-in-port) definition example.
* [Mirror property](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md) definition example.
* [Calculation property](/context-lake/data-model/setup-blueprint/properties/calculation-property/.md) definition example.
Here is the example definition in all the supported languages:
* Python
* TypeScript
* JavaScript
* GO
```
from pulumi import ResourceOptions
import port_pulumi as port
other = port.Blueprint(
"other",
identifier="test-docs-relation",
icon="Microservice",
title="Test Docs Relation",
properties=port.BlueprintPropertiesArgs(
string_props={
"myStringProp": port.BlueprintPropertiesStringPropsArgs(
title="My string", required=False
)
}
),
)
blueprint = port.Blueprint(
"myBlueprint",
identifier="test-docs",
icon="Microservice",
title="Test Docs",
properties=port.BlueprintPropertiesArgs(
string_props={
"myStringProp": port.BlueprintPropertiesStringPropsArgs(
title="My string", required=False
),
"myUrlProp": port.BlueprintPropertiesStringPropsArgs(
title="My url", required=False, format="url"
),
"myEmailProp": port.BlueprintPropertiesStringPropsArgs(
title="My email", required=False, format="email"
),
"myUserProp": port.BlueprintPropertiesStringPropsArgs(
title="My user", required=False, format="user"
),
"myTeamProp": port.BlueprintPropertiesStringPropsArgs(
title="My team", required=False, format="team"
),
"myDatetimeProp": port.BlueprintPropertiesStringPropsArgs(
title="My datetime", required=False, format="date-time"
),
"myTimerProp": port.BlueprintPropertiesStringPropsArgs(
title="My timer", required=False, format="timer"
),
"myYAMLProp": port.BlueprintPropertiesStringPropsArgs(
title="My yaml", required=False, format="yaml"
),
},
number_props={
"myNumberProp": port.BlueprintPropertiesNumberPropsArgs(
title="My number", required=False,
)
},
boolean_props={
"myBooleanProp": port.BlueprintPropertiesBooleanPropsArgs(
title="My boolean", required=False
)
},
object_props={
"myObjectProp": port.BlueprintPropertiesObjectPropsArgs(
title="My object", required=False
)
},
array_props={
"myArrayProp": port.BlueprintPropertiesArrayPropsArgs(
title="My array", required=False
)
}
),
mirror_properties={
"myMirrorProp": port.BlueprintMirrorPropertiesArgs(
title="My mirror property", path="myRelation.myStringProp"
),
"myMirrorPropWithMeta": port.BlueprintMirrorPropertiesArgs(
title="My mirror property of meta property", path="myRelation.$identifier"
),
},
calculation_properties={
"myCalculation": port.BlueprintCalculationPropertiesArgs(
title="My calculation property", calculation=".properties.myStringProp + .properties.myStringProp", type="string",
),
"myCalculationWithMeta": port.BlueprintCalculationPropertiesArgs(
title="My calculation property with meta properties", calculation='.identifier + "-" + .title + "-" + .properties.myStringProp', type="string",
),
},
relations={
"myRelation": port.BlueprintRelationsArgs(
title="My relation", target="test-docs-relation", many=False, required=False,
),
},
opts=ResourceOptions(depends_on=[other]),
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
const other = new port.Blueprint("other", {
identifier: "test-docs-relation",
icon: "Microservice",
title: "Test Docs Relation",
properties: {
stringProps: {
myStringProp: {
title: "My string",
required: false,
},
},
},
});
const myBlueprint = new port.Blueprint(
"myBlueprint",
{
identifier: "test-docs",
icon: "Microservice",
title: "Test Docs",
properties: {
stringProps: {
myStringProp: {
title: "My string",
required: false,
},
myUrlProp: {
title: "My url",
required: false,
format: "url",
},
myEmailProp: {
title: "My email",
required: false,
format: "email",
},
myUserProp: {
title: "My user",
required: false,
format: "user",
},
myTeamProp: {
title: "My team",
required: false,
format: "team",
},
myDatetimeProp: {
title: "My datetime",
required: false,
format: "date-time",
},
myTimerProp: {
title: "My timer",
required: false,
format: "timer",
},
myYAMLProp: {
title: "My yaml",
required: false,
format: "yaml",
},
},
numberProps: {
myNumberProp: {
title: "My number",
required: false,
},
},
booleanProps: {
myBooleanProp: {
title: "My boolean",
required: false,
},
},
objectProps: {
myObjectProp: {
title: "My object",
required: false,
},
},
arrayProps: {
myArrayProp: {
title: "My array",
required: false,
},
},
},
mirrorProperties: {
myMirrorProp: {
title: "My mirror property",
path: "myRelation.myStringProp",
},
myMirrorPropWithMeta: {
title: "My mirror property of meta property",
path: "myRelation.$identifier",
},
},
calculationProperties: {
myCalculation: {
title: "My calculation property",
calculation: ".properties.myStringProp + .properties.myStringProp",
type: "string",
},
myCalculationWithMeta: {
title: "My calculation property with meta properties",
calculation:
'.identifier + "-" + .title + "-" + .properties.myStringProp',
type: "string",
},
},
relations: {
myRelation: {
title: "My relation",
target: "test-docs-relation",
many: false,
required: false,
},
},
},
{ dependsOn: [other] }
);
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const other = new port.Blueprint("other", {
identifier: "test-docs-relation",
icon: "Microservice",
title: "Test Docs Relation",
properties: {
stringProps: {
myStringProp: {
title: "My string",
required: false,
},
},
},
});
const myBlueprint = new port.Blueprint(
"myBlueprint",
{
identifier: "test-docs",
icon: "Microservice",
title: "Test Docs",
properties: {
stringProps: {
myStringProp: {
title: "My string",
required: false,
},
myUrlProp: {
title: "My url",
required: false,
format: "url",
},
myEmailProp: {
title: "My email",
required: false,
format: "email",
},
myUserProp: {
title: "My user",
required: false,
format: "user",
},
myTeamProp: {
title: "My team",
required: false,
format: "team",
},
myDatetimeProp: {
title: "My datetime",
required: false,
format: "date-time",
},
myTimerProp: {
title: "My timer",
required: false,
format: "timer",
},
myYAMLProp: {
title: "My yaml",
required: false,
format: "yaml",
},
},
numberProps: {
myNumberProp: {
title: "My number",
required: false,
},
},
booleanProps: {
myBooleanProp: {
title: "My boolean",
required: false,
},
},
objectProps: {
myObjectProp: {
title: "My object",
required: false,
},
},
arrayProps: {
myArrayProp: {
title: "My array",
required: false,
},
},
},
mirrorProperties: {
myMirrorProp: {
title: "My mirror property",
path: "myRelation.myStringProp",
},
myMirrorPropWithMeta: {
title: "My mirror property of meta property",
path: "myRelation.$identifier",
},
},
calculationProperties: {
myCalculation: {
title: "My calculation property",
calculation: ".properties.myStringProp + .properties.myStringProp",
type: "string",
},
myCalculationWithMeta: {
title: "My calculation property with meta properties",
calculation:
'.identifier + "-" + .title + "-" + .properties.myStringProp',
type: "string",
},
},
relations: {
myRelation: {
title: "My relation",
target: "test-docs-relation",
many: false,
required: false,
},
},
},
{ dependsOn: [other] }
);
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
other, err := port.NewBlueprint(ctx, "other", &port.BlueprintArgs{
Identifier: pulumi.String("test-docs-relation"),
Icon: pulumi.String("Microservice"),
Title: pulumi.String("Test Docs Relation"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myStringProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My string"),
Required: pulumi.Bool(false),
},
},
},
})
if err != nil {
return err
}
myBlueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("test-docs"),
Icon: pulumi.String("Microservice"),
Title: pulumi.String("Test Docs"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myStringProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My string"),
Required: pulumi.Bool(false),
},
"myUrlProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My url"),
Required: pulumi.Bool(false),
Format: pulumi.String("url"),
},
"myEmailProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My email"),
Required: pulumi.Bool(false),
Format: pulumi.String("email"),
},
"myUserProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My user"),
Required: pulumi.Bool(false),
Format: pulumi.String("user"),
},
"myTeamProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My team"),
Required: pulumi.Bool(false),
Format: pulumi.String("team"),
},
"myDatetimeProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My datetime"),
Required: pulumi.Bool(false),
Format: pulumi.String("date-time"),
},
"myTimerProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My timer"),
Required: pulumi.Bool(false),
Format: pulumi.String("timer"),
},
"myYAMLProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My yaml"),
Required: pulumi.Bool(false),
Format: pulumi.String("yaml"),
},
},
NumberProps: port.BlueprintPropertiesNumberPropsMap{
"myNumberProp": port.BlueprintPropertiesNumberPropsArgs{
Title: pulumi.String("My number"),
Required: pulumi.Bool(false),
},
},
BooleanProps: port.BlueprintPropertiesBooleanPropsMap{
"myBooleanProp": port.BlueprintPropertiesBooleanPropsArgs{
Title: pulumi.String("My boolean"),
Required: pulumi.Bool(false),
},
},
ObjectProps: port.BlueprintPropertiesObjectPropsMap{
"myObjectProp": port.BlueprintPropertiesObjectPropsArgs{
Title: pulumi.String("My object"),
Required: pulumi.Bool(false),
},
},
ArrayProps: port.BlueprintPropertiesArrayPropsMap{
"myArrayProp": port.BlueprintPropertiesArrayPropsArgs{
Title: pulumi.String("My array"),
Required: pulumi.Bool(false),
},
},
},
MirrorProperties: port.BlueprintMirrorPropertiesMap{
"myMirrorProp": port.BlueprintMirrorPropertiesArgs{
Title: pulumi.String("My mirror property"),
Path: pulumi.String("myRelation.myStringProp"),
},
"myMirrorPropWithMeta": port.BlueprintMirrorPropertiesArgs{
Title: pulumi.String("My mirror property of meta property"),
Path: pulumi.String("myRelation.$identifier"),
},
},
CalculationProperties: port.BlueprintCalculationPropertiesMap{
"myCalculation": port.BlueprintCalculationPropertiesArgs{
Title: pulumi.String("My calculation property"),
Calculation: pulumi.String(".properties.myStringProp + .properties.myStringProp"),
Type: pulumi.String("string"),
},
"myCalculationWithMeta": port.BlueprintCalculationPropertiesArgs{
Title: pulumi.String("My calculation property with meta properties"),
Calculation: pulumi.String(".identifier + \"-\" + .title + \"-\" + .properties.myStringProp"),
Type: pulumi.String("string"),
},
},
Relations: port.BlueprintRelationsMap{
"myRelation": &port.BlueprintRelationsArgs{
Title: pulumi.String("My relation"),
Target: pulumi.String("test-docs-relation"),
Many: pulumi.Bool(false),
Required: pulumi.Bool(false),
},
},
}, pulumi.DependsOn([]pulumi.Resource{other}))
if err != nil {
return err
}
return nil
})
}
```
---
# Terraform-Managed Blueprint Example
This example includes a complete [blueprint](/context-lake/data-model/setup-blueprint/overview/.md) resource definition in Terraform, which includes:
* [Blueprint](/context-lake/data-model/setup-blueprint/overview/.md?definition=tf#configure-blueprints-in-port) definition examples.
* All [property](/context-lake/data-model/setup-blueprint/properties/overview/.md) type definitions.
* [Relation](/context-lake/data-model/setup-blueprint/relate-blueprints/.md?definition=tf#configure-relations-in-port) definition example.
* [Mirror property](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md) definition example.
* [Calculation property](/context-lake/data-model/setup-blueprint/properties/calculation-property/.md) definition example.
Here is the example definition. Set your Port [credentials](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md#find-your-port-credentials) as environment variables and add the configuration to a `.tf` file.
```
export PORT_CLIENT_ID=""
export PORT_CLIENT_SECRET=""
```
In your `.tf` file, configure the `port-labs/port-labs` provider and define the blueprint resource:
**Terraform blueprint example (click to expand)**
```
terraform {
required_providers {
port = {
source = "port-labs/port-labs"
version = "~> 2.0.3"
}
}
}
provider "port" {
base_url = "https://api.port.io"
}
resource "port_blueprint" "myBlueprint" {
depends_on = [
port_blueprint.other
]
# ...blueprint properties
identifier = "test-docs"
icon = "Microservice"
title = "Test Docs"
properties = {
string_props = {
"myStringProp" = {
title = "My string"
required = false
}
"myUrlProp" = {
title = "My url"
required = false
format = "url"
}
"myEmailProp" = {
title = "My email"
required = false
format = "email"
}
"myUserProp" = {
title = "My user"
required = false
format = "user"
}
"myTeamProp" = {
title = "My team"
required = false
format = "team"
}
"myDatetimeProp" = {
title = "My datetime"
required = false
format = "date-time"
}
"myYAMLProp" = {
title = "My YAML"
required = false
format = "yaml"
}
"myTimerProp" = {
title = "My timer"
required = false
format = "timer"
}
}
number_props = {
"myNumberProp" = {
title = "My number"
required = false
}
}
boolean_props = {
"myBooleanProp" = {
title = "My boolean"
required = false
}
}
object_props = {
"myObjectProp" = {
title = "My object"
required = false
}
}
array_props = {
"myArrayProp" = {
title = "My array"
required = false
}
}
}
mirror_properties = {
"myMirrorProp" = {
title = "My mirror property"
path = "myRelation.myStringProp"
}
"myMirrorPropWithMeta" = {
title = "My mirror property of meta property"
path = "myRelation.$identifier"
}
}
calculation_properties = {
"myCalculation" = {
title = "My calculation property"
calculation = ".properties.myStringProp + .properties.myStringProp"
type = "string"
}
# Calculation property making use of meta-properties
"myCalculationWithMeta" = {
title = "My calculation property with meta properties"
calculation = ".identifier + \"-\" + .title + \"-\" + .properties.myStringProp"
type = "string"
}
}
relations = {
"myRelation" = {
target = port_blueprint.other.identifier
title = "myRelation"
many = false
required = false
}
}
}
resource "port_blueprint" "other" {
# ...blueprint properties
identifier = "test-docs-relation"
icon = "Microservice"
title = "Test Docs Relation"
properties = {
string_props = {
"myStringProp" = {
title = "My string"
required = false
}
}
}
}
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
---
# Default blueprints
Every Port account comes with a set of default [blueprints](), used to represent common concepts in your organization.
See the list below for a description of each blueprint.
You can view and edit blueprints in the [data model page](https://app.port.io/settings/data-model) of your portal.
###  Service[](#-service "Direct link to -service")
`service` - a flexible [blueprint]() representing a piece of software that is owned by a team/group in your organization.
This blueprint serves as a single component with rich context about all the resources related to the software, such as:
* **The code itself** - a repository or a specific folder in a monorepo.
* **Incident management** components, such as a PagerDuty service.
* **Code scanning** components, such as Snyk Targets or Sonar Cloud projects.
* **Project management** components, such as Jira projects and issues.
* **Runtime** components, such as workloads.
Services are the core component of R\&D operations within a developer portal, providing each team with a unified view of its services and their status across different domains, such as **security**, **stability**, **access management**, and more.
###  Environment[](#-environment "Direct link to -environment")
`environment` - represents a deployment environment in your organization.
In addition to this [blueprint](), 3 default [entities]() will be created: `Production`, `Staging`, and `Test`.
You can modify the default environments and/or create additional ones.
###  Workload[](#-workload "Direct link to -workload")
`workload` - represents a `service` running in a specific `environment`, with context of the relevant related components.
For example, a `frontend` service in your organization can have `frontend-prod` and `frontend-test` workloads, each with its own Kubernetes namespace, Sentry project, and owning team.
### Deployment[](#deployment "Direct link to Deployment")
`deployment` - represents a production deployment, created each time a PR is merged to the default branch.
Deployment entities provide traceability from code change to production, helping you track delivery frequency and link deployments back to the services and teams responsible for them.
###  User[](#-user "Direct link to -user")
`_user` - represents a user in your organization.
This blueprint can be related to other "user" blueprints coming from your connectors, such as `github_user`, allowing you to manage a user across multiple tools from a single component.
###  Team[](#-team "Direct link to -team")
`_team` - represents a team in your organization.
This blueprint can be related to other "team" blueprints coming from your connectors, such as `github_team`, allowing you to manage a team across multiple tools from a single component.
Users in Port can be assigned to teams, allowing you to implement ownership of components in your portal.
###  Organization[](#-organization "Direct link to -organization")
`organization` - a logical grouping of teams and services in your catalog.
Organizations represent higher-level business units in your company hierarchy, making it easier to manage ownership and visibility across multiple teams and their services.
###  Scorecard[](#-scorecard "Direct link to -scorecard")
`_scorecard` - represents a scorecard in Port.
Scorecards enable you to define and track metrics and standards for entities in your catalog. Each scorecard evaluates entities based on a set of rules and assigns them a level, such as `Basic`, `Bronze`, `Silver`, or `Gold`.
###  Scorecard rule[](#-scorecard-rule "Direct link to -scorecard-rule")
`_rule` - represents an individual rule within a scorecard.
Each rule defines one or more conditions that an entity must meet to reach a specific level in its scorecard.
###  Scorecard rule result[](#-scorecard-rule-result "Direct link to -scorecard-rule-result")
`_rule_result` - represents the evaluation result of a scorecard rule for a specific entity.
Rule results track whether each entity passes or fails each scorecard rule, giving you a clear view of where entities stand and what needs to be improved.
###  AI agent[](#-ai-agent "Direct link to -ai-agent")
`_ai_agent` - represents an AI agent registered in your portal.
AI agents are the primary interface for interacting with Port using natural language. This blueprint tracks the agents available in your organization.
### AI invocation[](#ai-invocation "Direct link to AI invocation")
`_ai_invocations` - represents a single interaction with an AI agent.
Each time an agent is invoked, a corresponding AI invocation entity is created, providing a record of agent usage. Permissions on this blueprint control which users in your organization can access Port AI features.
### MCP server[](#mcp-server "Direct link to MCP server")
`_mcp_server` - represents an external MCP (Model Context Protocol) server connected to Port.
MCP servers extend Port's AI capabilities by providing additional tools and context that AI agents can use. Registering MCP servers in Port allows AI agents to discover and use their tools dynamically.
###  Workflow[](#-workflow "Direct link to -workflow")
`_workflow` - represents a workflow defined in your portal.
Every workflow is automatically synced to this blueprint as an entity, giving you a catalog view of all workflows across your organization. The `_workflow` blueprint supports team ownership, so you can assign owning teams to workflows and control access using Port's standard blueprint permissions model. See [workflow catalog and ownership](/workflows/permissions-and-rbac/workflow-catalog/.md) for details.
## System blueprints reference[](#system-blueprints-reference "Direct link to System blueprints reference")
Port includes protected system blueprints (identifiers starting with `_`) that power core platform features. These blueprints have specific constraints that differ from user-created blueprints.
| Identifier | Display name | Purpose | Can delete | Can extend |
| ------------------ | --------------------- | ------------------------------------------------ | ---------- | -------------------- |
| `_user` | User | Represents users in your organization | No | Yes (relations only) |
| `_team` | Team | Represents teams in your organization | No | Yes (relations only) |
| `_scorecard` | Scorecard | Tracks scorecards defined in Port | No | No |
| `_rule` | Scorecard Rule | Individual rules within scorecards | No | No |
| `_rule_result` | Scorecard Rule Result | Evaluation results of scorecard rules | No | No |
| `_ai_agent` | AI Agent | AI agents registered in your portal | No | No |
| `_ai_invocations` | AI Invocation | Records of AI agent interactions | No | No |
| `_ai_conversation` | AI Conversation | Groups related AI invocations into conversations | No | No |
| `_mcp_server` | MCP Server | External MCP servers connected to Port | No | No |
| `_workflow` | Workflow | Workflows defined in your portal | No | No |
System blueprint constraints
System blueprints are managed by Port and cannot be deleted or have their core schema modified. They are automatically created and maintained to support platform functionality.
The `_user` and `_team` blueprints can be extended with additional relations to link Port users and teams to entities from your integrations (for example, linking `_user` to a `githubUser` or `pagerdutyUser`). You can also configure permissions on system blueprints to control user access to features (for example, restricting AI access via `_ai_invocations` permissions).
In addition to system blueprints, Port uses special identifiers for navigation:
* `$home`: References the portal home page in URLs and navigation contexts.
---
# Set up blueprints
Blueprints are the most basic building block in Port. They are used to represent assets in your organization, and the relationships between them.
Blueprints are comprised of [properties](/context-lake/data-model/setup-blueprint/properties/overview/.md), which are used to define the structure of the data they represent. Port supports a wide variety of property types, allowing you to model your data in the most accurate way possible.
Blueprints are completely customizable, and support any number of properties. They are created and managed in the [Data model](https://app.port.io/settings/data-model) of the portal.
## Common blueprints[](#common-blueprints "Direct link to Common blueprints")
Blueprints can be used to represent any asset in your software catalog, some common examples are:
* Microservices
* Packages
* Package versions
* CI jobs
* K8s Clusters
* Cloud accounts
* Cloud environments
* Developer environments
* Service deployment
* Pods
* VMs
Check out our [**live demo**](https://demo.port.io/settings) to see an example of a fleshed-out builder with a variety of blueprints.
## Configure blueprints in Port[](#configure-blueprints-in-port "Direct link to Configure blueprints in Port")
Port offers a variety of ways to create and edit blueprints:
* Port AI
* UI
* API
* Terraform
* Pulumi
You can use [Port AI](/port-ai/port-ai-assistant/.md) to create and configure blueprints through natural language - no manual JSON editing required.
Open the AI assistant in your Port portal and describe what you need. For example:
*"Create a microservice blueprint with properties for programming language (string), repository URL (URL), and deployment status (string enum with values: active, inactive, deprecated)"*
Port AI will generate and apply the blueprint schema for you. You can then refine it with follow-up prompts like *"Add an owner team property"* or *"Make the repository URL required"*.
MCP server
If you have the [Port MCP server](/agent-management/port-mcp-server/overview/.md) configured in your IDE, you can manage blueprints directly from your coding environment using the same natural language approach.
Create in Port
```
{
"identifier": "myIdentifier",
"title": "My title",
"description": "My description",
"icon": "My icon",
"calculationProperties": {},
"schema": {
"properties": {},
"required": []
},
"relations": {}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
#### To edit an existing blueprint:
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Expand your desired blueprint by double-clicking on it.
3. Here you can add, remove, or edit this blueprint's [properties](/context-lake/data-model/setup-blueprint/properties/overview/.md) and [relations](/context-lake/data-model/setup-blueprint/relate-blueprints/.md).
4. To edit the blueprint's metadata (title, icon, etc.), click on the `...` icon in the top right corner of the blueprint card, and choose `Edit blueprint`.
#### To create a new blueprint:
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Click on `+ Blueprint`:
3. Choose a title, icon, and description for your blueprint, then click `Create`.
4. Your blueprint has been created, the next step is to [ingest data into it](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md).
```
resource "port_blueprint" "myBlueprint" {
title = "My blueprint"
icon = "My icon"
identifier = "myIdentifier"
description = "My description"
properties {
string_props = {
"myProperty" = {
type = "string"
title = "My Property"
}
"myUrlProperty" = {
title = "URL Property"
format = "url"
}
}
}
}
```
Full example
For a full example, check the [Terraform-Managed Blueprint Example](/context-lake/data-model/iac/terraform-managed-blueprint/.md) page.
* Python
* TypeScript
* JavaScript
* GO
```
"""A Python Pulumi program"""
impor t pulumi
from port_pulumi import Blueprint
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
icon="My icon",
description="My description",
properties=port.BlueprintPropertiesArgs(
string_props={
"myStringProp": port.BlueprintPropertiesStringPropsArgs(
title="My string", required=False
),
"myUrlProp": port.BlueprintPropertiesStringPropsArgs(
title="My url", required=False, format="url"
),
"myEmailProp": port.BlueprintPropertiesStringPropsArgs(
title="My email", required=False, format="email"
),
"myUserProp": port.BlueprintPropertiesStringPropsArgs(
title="My user", required=False, format="user"
),
"myTeamProp": port.BlueprintPropertiesStringPropsArgs(
title="My team", required=False, format="team"
),
"myDatetimeProp": port.BlueprintPropertiesStringPropsArgs(
title="My datetime", required=False, format="date-time"
),
"myTimerProp": port.BlueprintPropertiesStringPropsArgs(
title="My timer", required=False, format="timer"
),
"myYAMLProp": port.BlueprintPropertiesStringPropsArgs(
title="My yaml", required=False, format="yaml"
),
}
)
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
icon: "My icon",
description: "My description",
properties: [
{
identifier: "language",
title: "Language",
type: "string",
required: true,
},
],
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
icon: "My icon",
description: "My description",
properties: [
{
name: "language",
value: "Node",
},
],
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Icon: pulumi.String("My icon"),
Description: pulumi.String("My description"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myStringProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My string"),
Required: pulumi.Bool(false),
},
},
},
})
ctx.Export("blueprint", blueprint.Title)
if err != nil {
return err
}
return nil
})
}
```
Full example
For a full example, check the [Pulumi-Managed Blueprint Example](/context-lake/data-model/iac/pulumi-managed-blueprint/.md) page.
## Blueprint structure[](#blueprint-structure "Direct link to Blueprint structure")
Each blueprint is represented by a [Json schema](https://json-schema.org/), as shown in the following section:
Create in Port
```
{
"identifier": "myIdentifier",
"title": "My title",
"description": "My description",
"icon": "My icon",
"calculationProperties": {},
"schema": {
"properties": {
"myProp1": {
"type": "my_type",
"title": "My title"
},
"myProp2": {
"type": "my_special_type",
"title": "My special title"
}
},
"required": []
},
"relations": {}
}
```
### Structure table[](#structure-table "Direct link to Structure table")
| Field | Description | Notes |
| ----------------------- | --------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------- |
| `identifier` | The identifier is used for API calls, programmatic access and distinguishing between different blueprints. | **Required**. (Maximum 100 characters) |
| `title` | Human-readable name for the blueprint. | **Required**. (Maximum 100 characters) |
| `description` | The value is visible as a tooltip to users when hovering over the info icon in the UI. | |
| `icon` | Icon for the blueprint and entities of the blueprint. | See the full icon list [below](#full-icon-list). |
| `calculationProperties` | Contains the properties defined using [calculation properties](/context-lake/data-model/setup-blueprint/properties/calculation-property/.md). | **Required** |
| `mirrorProperties` | Contains the properties defined using [mirror properties](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md). | |
| `schema` | An object containing two nested fields: `properties` and `required`. | **Required**. See the schema structure [here](#schema-object). |
| `ownership` | Defines how ownership of entities is determined. | See the [ownership](/context-lake/business-context/ownership/.md#the-ownership-property) section for details. |
Available properties
All available properties are listed in the [properties](/context-lake/data-model/setup-blueprint/properties/overview/.md) page
### Schema object[](#schema-object "Direct link to Schema object")
```
"schema": {
"properties": {},
"required": []
}
```
| Schema field | Description |
| ------------ | ----------------------------------------------------------------------------------------------------------------------------------- |
| `properties` | See the [`properties`](/context-lake/data-model/setup-blueprint/properties/overview/.md) section for more details. |
| `required` | A list of the **required** properties, out of the `properties` object list.
These are mandatory fields to fill in the UI form. |
### Full icon list[](#full-icon-list "Direct link to Full icon list")
Port provides a wide selection of built-in icons for use in blueprints, properties, actions, action inputs, etc. Enterprise customers can also [upload custom icons](/interface-builder/port-interface/customization/.md#custom-icons) to align with their organization's branding.
**Full icon list (click to expand)**
`Actions, Add, AddUser, AI, Airflow, Alert, AmazonEC2, AmazonEKS, AmazonRDS, AmazonS3, Amplication, Ansible, API, APIalt, ApiDocs, APIEndpoint, AppRunner, Apps, Aqua, Argo, ArgoRollouts, Armis, AuditLog, Aws, Azure, AzureAD, AzureDevops, AzurePipline, AzureProvider, Backstage, BadgeAlert, Bar, BitBucket, BitBucketGitops, BlankPage, Blueprint, Bolt, Book, Box, Branch, Bucket, Buddy, Bug, Bulb, Calendar, Catalog, Chat, Checklist, Checkmarx, CICD, CircleCI, Clickup, Clock, ClockLoader, ClosedFolder, Cloud, Cloudflare, CloudFormation, Cluster, Codacy, Code, CodeBlocks, Codecov, Codefresh, Columns, Commit, ConcourseCI, Confluence, Consul, Cookiecutter, Coralogix, Cost, CPlusPlus, CPU, Crossplane, CSharp, Css3, CSV, Customer, Database, Databricks, Datadog, Day2Operation, DBT, DefaultBlueprint, DefaultProperty, Delete, Dependabot, DeployedAt, Deployment, Deployments, Details, DevopsTool, DevTV, Docker, Docs, DownArrow, Download, DrawIO, Drive, DynamicFeed, Dynatrace, Ecs, Edit, ElasticSearch, Emergency, EmptyBox, Environment, Environments, ErrorLogs, EU, Euro, Event, Exporter, Falcosidekick, Figma, Finance, FireHydrant, FitView, Flag, Flagsmith, Fluentd, Fluxcd, Flyway, GCE, General, Git, GitHub, GithubActions, GithubCopilot, GithubGitops, GitIssue, GitLab, GitLabGitops, GitPullRequest, GitSubIcon, GitVersion, GKE, Go, Google, GoogleCloud, GoogleCloudPlatform, GoogleMaps, GPU, Grafana, Graphql, groundcover, GroupBy, HAProxy, HashiCorp, Health, Helm, Help, Home, HourGlass, HourGlassExpired, Html5, Hubspot, Humio, IaC, Infinity, Instance, Istio, Java, Javascript, Jenkins, JFrog, JfrogXray, Jira, Job, Js, JsonEditor, JumpCloudProvider, Jupyter, Kafka, KafkaUI, Key, Kiali, Kibana, KNative, Komodor, Kotlin, Kubecost, Kyverno, Lambda, Lastpass, Launchdarkly, Layers, Learn, LeftArrow, Linear, LineChart, Link, LinkOut, Linux, List, Lock, LogOut, Logz, LucidCharts, Mail, Manager, ManageSearch, Markdown, Matlab, Merge, Metric, Microservice, Microservices, Microsoft, MicrosoftEntraID, Migrate, Miro, Misconfiguration, Mixpanel, MongoDb, Moon, Move, Neo4j, NewPage, NewRelic, Node, NodeJS, Notion, NSQ, Ocean, OctopusDeploy, Okta, OneLogin, Opencost, OpenFolder, OpsGenie, Organization, OutSystems, Package, Pagerduty, Perl, Permissions, Php, Pie, Pipeline, Plug, PlugOff, Port, PostgreSQL, Prometheus, Properties, Pulsar, Pulumi, Python, R, Rancher, React, RedhatOpenshift, Redis, Register, Relation, Reminder, Repeat, Reset, RightArrow, Rocket, Role, Rope, Ruby, SalesForce, Scala, Score, SDK, Search, SendGrid, Sensu, Sentry, Server, Service, Servicenow, Settings, SettingsEthernet, Share, Shield, Sinch, SingleStore, Siren, Slack, Snowflake, SNS, Snyk, SonarCloud, Sonarqube, SonartypeNexusIQ, Sort, Speed, Spinnaker, Spring, SQL, Stack, Stackhawk, StackOverflow, Star, StatusPage, Stonebranch, Stoplight, Store, Stripe, Sun, Supervisor, Support, Swagger, Swift, Sync, Table, Tableau, Team, TeamCity, Template, Terraform, Thanos, Travel, Tribe, Trivy, Twilio, TwoUsers, Typescript, Unavailable, Unleash, Unlock, UpArrow, Updates, Url, USA, User, Users, Version, Vulnerability, Webhook, Widget, Windows, Wiz, Youtrack, Zendesk, Zipkin`
---
# Aggregation property
Aggregation properties allow you to calculate metrics based on the [relations](/context-lake/data-model/setup-blueprint/relate-blueprints/.md) in your catalog.
Using the aggregation property enables you to see relevant metrics on related entities, without having to manually calculate them.
Aggregations can be performed on any blueprint that is related in any way to the current blueprint (directly, indirectly, upstream or downstream).
Relation traversal
By default, aggregations consider all possible paths between the source and target entities. To control which path is used, see [path filter](#path-filter).
## Common usage[](#common-usage "Direct link to Common usage")
Use aggregation properties to calculate metrics over related entities, such as:
* The number of open Jira issues for a service.
* The number of unresolved high and critical vulnerabilities.
* The average number of deployments per week.
* The total monthly cost of related cloud resources.
You can use these metrics in scorecards and initiative rules.
## When to use aggregation properties[](#when-to-use-aggregation-properties "Direct link to When to use aggregation properties")
Aggregation property ideally will be defined on blueprints which are in the **higher abstraction level** in your catalog.
Those blueprints are usually the ones that are **related to many other blueprints** in your catalog, and therefore, they are the ones that can benefit the most from aggregation properties.
## Specification[](#specification "Direct link to Specification")
The `aggregationProperties` key is a top-level key in a blueprint definition, alongside `identifier`, `title`, and `schema`.
The aggregation property supports calculations by entities or by property.
* Calculations by **entities** are performed on the entities that match the query (e.g. count the number of entities that match the query).
* Calculations by **property** are performed on the property of the entities that match the query (e.g. sum the value of the property of the entities that match the query).
## Definitions[](#definitions "Direct link to Definitions")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* API
* Terraform
* Pulumi
### Calculate by entities
Calculate by entities is used to calculate metrics based on the entities that match the query.
Supported methods:
* `count` - Count the number of entities that match the query. For example, count the number of open Jira issues related to a microservice.
* `average` - Calculate the average of entities per a defined time period. For example, calculate the average deployment frequency per week.
- Entities Count
- Entities Average
In this example, we have a microservice blueprint and we want to calculate the number of open Jira issues related to each microservice.
```
{
"aggregationProperties": {
"numberOfOpenJiraIssues": {
"title": "Number of open Jira issues",
"target": "jiraIssue",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "OPEN"
}
]
}
}
}
}
```
The `aggregationProperties` contains a key called `numberOfOpenJiraIssues` which is the identifier of the aggregation property we want to define.
* `title` - The title of the aggregation property.
* `target` - The blueprint we want to aggregate data from.
* `query` - **Optional** - The query that will be performed on the target blueprint. The query is based on the Filters to include or exclude specific data based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules)
* `calculationSpec` - The calculation specification.
* `"calculationBy": "entities"` - The calculation will be performed on the **entities** that match the query.
* `"func": "count"` - is the function we want to use for the calculation.
In this example, we have a microservice blueprint, and we want to calculate the average deployment frequency for each of the microservices.
```
{
"aggregationProperties": {
"averageDeploymentFrequency": {
"title": "Average deployment frequency",
"target": "deployment",
"calculationSpec": {
"calculationBy": "entities",
"func": "average",
"averageOf": "week",
"measureTimeBy": "$createdAt"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "SUCCESS"
}
]
}
}
}
}
```
The `aggregationProperties` contains a key called `averageDeploymentFrequency` which is the identifier of the aggregation property we want to define.
* `title` - The title of the aggregation property.
* `target` - The blueprint we want to aggregate data from.
* `query` - **Optional** - The query that will be performed on the target blueprint. The query is based on the Filters to include or exclude specific data based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules)
* `calculationSpec` - The calculation specification.
* `"calculationBy": "entities"` - The calculation will be performed on the entities that match the query (e.g. count the number of entities that match the query).
* `"func": "average"` - is the function we want to use for the calculation.
* `"averageOf": "week"` - The time period we want to calculate the average for. In this example, we want to calculate the average deployment frequency for each week. Supported Options are: `hour, day ,week and month`
* `"measureTimeBy": "$createdAt"` - The time property we want to measure the average by. You can use any date property in the target blueprint by default, we add $createdAt and $updatedAt as [meta-properties](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md) to each entity.
### Calculate by property
Calculate by property is used to calculate metrics based on the property of the entities that match the query.
The property type must be a number.
Supported methods:
* `sum` - Sum the value of the property of the entities that match the query. For example, sum the story points of open Jira issues related to a microservice.
* `average` - Calculate the average of the property of the entities that match the query. For example, average cpu usage of a microservice.
* `min` - Calculate the minimum value of the property of the entities that match the query. For example, lowest alert severity of a microservice in the last week.
* `max` - Calculate the maximum value of the property of the entities that match the query. For example, highest alert severity of a microservice in the last week.
* `median` - Calculate the median value of the property of the entities that match the query. For example, median cpu usage of a microservice in the last week.
- Sum
- Average
- Min
- Max
- Median
In this example, we have a microservice blueprint, and we want to calculate the sum of the story points of open Jira issues related to each microservice.
```
{
"aggregationProperties": {
"sumOfStoryPoints": {
"title": "Sum of story points",
"target": "jiraIssue",
"calculationSpec": {
"calculationBy": "property",
"func": "sum",
"property": "storyPoints"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "OPEN"
}
]
}
}
}
}
```
The `aggregationProperties` contains a key called `sumOfStoryPoints` which is the identifier of the aggregation property we want to define.
* `title` - The title of the aggregation property.
* `target` - The blueprint we want to aggregate data from.
* `query` - **Optional** - The query that will be performed on the target blueprint. The query is based on the Filters to include or exclude specific data based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules)
* `calculationSpec` - The calculation specification.
* `"calculationBy": "property"` - The calculation will be performed on the property of the entities that match the query (e.g. sum the value of the property of the entities that match the query).
* `"func": "sum"` is the function we want to use for the calculation.
* `"property": "storyPoints"` - The property we want to calculate the sum of. The property type must be a number.
In this example, we have a microservice blueprint, and we want to calculate the average cpu usage of each microservice.
```
{
"aggregationProperties": {
"averageCpuUsage": {
"title": "Average CPU usage",
"target": "deployment",
"calculationSpec": {
"calculationBy": "property",
"func": "average",
"property": "cpuUsage",
"averageOf": "week",
"measureTimeBy": "$createdAt"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "SUCCESS"
}
]
}
}
}
}
```
The `aggregationProperties` contains a key called `averageCpuUsage` which is the identifier of the aggregation property we want to define.
* `title` - The title of the aggregation property.
* `target` - The blueprint we want to aggregate data from.
* `query` - **Optional** - The query that will be performed on the target blueprint. The query is based on the Filters to include or exclude specific data based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules)
* `calculationSpec` - The calculation specification.
* `calculationBy` - `property` The calculation will be performed on the property of the entities that match the query (e.g. average the value of the property of the entities that match the query).
* `"func": "average"` - is the function we want to use for the calculation.
* `"property": "cpuUsage"` - The property we want to calculate the average of. The property type must be a number.
* `"averageOf": "week"` - The time period we want to calculate the average for. In this example, we want to calculate the average deployment frequency for each week. Supported Options are: \`hour, day ,week, month and total
* `"measureTimeBy": "$createdAt"` - The time property we want to measure the average by. You can use any date property in the target blueprint by default, we add $createdAt and $updatedAt as [meta-properties](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md) to each entity.
In this example, we have a microservice blueprint, and we want to calculate the minimum value of the alert severity of each microservice in the last week.
```
{
"aggregationProperties": {
"minAlertSeverity": {
"title": "Minimum alert severity",
"target": "alert",
"calculationSpec": {
"calculationBy": "property",
"func": "min",
"property": "severity"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "OPEN"
},
{
"property": "$createdAt",
"operator": "between",
"value": {
"preset": "lastWeek"
}
}
]
}
}
}
}
```
The `aggregationProperties` contains a key called `minAlertSeverity` which is the identifier of the aggregation property we want to define.
* `title` - The title of the aggregation property.
* `target` - The blueprint we want to aggregate data from.
* `query` - **Optional** - The query that will be performed on the target blueprint. The query is based on the Filters to include or exclude specific data based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules)
* `calculationSpec` - The calculation specification.
* `"calculationBy": "property"` The calculation will be performed on the property of the entities that match the query (e.g. minimum value of the property of the entities that match the query).
* `"func": "min"` - is the function we want to use for the calculation.
* `"property": "severity"` - The property we want to calculate the minimum of. The property type must be a number.
In this example, we have a microservice blueprint, and we want to calculate the maximum value of the alert severity of each microservice in the last week.
```
{
"aggregationProperties": {
"maxAlertSeverity": {
"title": "Maximum alert severity",
"target": "alert",
"calculationSpec": {
"calculationBy": "property",
"func": "max",
"property": "severity"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "OPEN"
},
{
"property": "$createdAt",
"operator": "between",
"value": {
"preset": "lastWeek"
}
}
]
}
}
}
}
```
The `aggregationProperties` contains a key called `maxAlertSeverity` which is the identifier of the aggregation property we want to define.
* `title` - The title of the aggregation property.
* `target` - The blueprint we want to aggregate data from.
* `query` - **Optional** - The query that will be performed on the target blueprint. The query is based on the Filters to include or exclude specific data based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules)
* `calculationSpec` - The calculation specification.
* `"calculationBy": "property"` The calculation will be performed on the property of the entities that match the query (e.g. maximum value of the property of the entities that match the query).
* `"func": "max"` - is the function we want to use for the calculation.
* `"property": "severity"` - The property we want to calculate the maximum of. The property type must be a number.
In this example, we have a microservice blueprint, and we want to calculate the median value of the cpu usage across all related pods of each microservice.
```
{
"aggregationProperties": {
"medianCpuUsage": {
"title": "Median CPU usage",
"target": "pod",
"calculationSpec": {
"calculationBy": "property",
"func": "median",
"property": "cpuUsage"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "OPEN"
},
{
"property": "$createdAt",
"operator": "between",
"value": {
"preset": "lastWeek"
}
}
]
}
}
}
}
```
The `aggregationProperties` contains a key called `medianCpuUsage` which is the identifier of the aggregation property we want to define.
* `title` - The title of the aggregation property.
* `target` - The blueprint we want to aggregate data from.
* `query` - **Optional** - The query that will be performed on the target blueprint. The query is based on the Filters to include or exclude specific data based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules)
* `calculationSpec` - The calculation specification.
* `"calculationBy": "property"` The calculation will be performed on the property of the entities that match the query (e.g. median value of the property of the entities that match the query).
* `"func": "median"` is the function we want to use for the calculation.
* `"property": "cpuUsage"` - The property we want to calculate the median of. The property type must be a number.
### Calculate by entities
Calculate by entities is used to calculate metrics based on the entities that match the query.
Supported methods:
* `count_entities` - Count the number of entities that match the query. For example, count the number of open Jira issues related to a microservice.
* `average_entities` - Calculate the average of entities per a defined time period. For example, calculate the average deployment frequency per week.
- Entities Count
- Entities Average
In this example, we create a parent blueprint with a child blueprint and an aggregation property to count the parent kids:
```
resource "port_blueprint" "parent_blueprint" {
title = "Parent Blueprint"
icon = "Terraform"
identifier = "parent"
description = ""
properties = {
number_props = {
"age" = {
title = "Age"
}
}
}
}
resource "port_blueprint" "child_blueprint" {
title = "Child Blueprint"
icon = "Terraform"
identifier = "child"
description = ""
properties = {
number_props = {
"age" = {
title = "Age"
}
}
}
relations = {
"parent" = {
title = "Parent"
target = port_blueprint.parent_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "parent_aggregation_properties" {
blueprint_identifier = port_blueprint.parent_blueprint.identifier
properties = {
count_kids = {
target_blueprint_identifier = port_blueprint.child_blueprint.identifier
title = "Count Kids"
icon = "Terraform"
description = "Count Kids"
method = {
count_entities = true
}
}
}
}
```
In this example, we have a microservice blueprint, and we want to calculate the average deployment frequency for each of the microservices.
```
resource "port_blueprint" "microservice_blueprint" {
title = "Microservice Blueprint"
icon = "Terraform"
identifier = "microservice"
description = ""
}
resource "port_blueprint" "deployment_blueprint" {
title = "Deployment Blueprint"
icon = "Terraform"
identifier = "deployment"
description = ""
relations = {
"microservice" = {
title = "Microservice"
target = port_blueprint.microservice_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "microservice_aggregation_properties" {
blueprint_identifier = port_blueprint.microservice_blueprint.identifier
properties = {
average_deployment_frequency = {
target_blueprint_identifier = port_blueprint.deployment_blueprint.identifier
title = "Average deployment frequency"
icon = "Terraform"
description = "Average deployment frequency"
method = {
average_entities = {
average_of = "week"
measure_time_by = "$createdAt"
}
}
}
}
}
```
### Calculate by property
Calculate by property is used to calculate metrics based on the property of the entities that match the query.
The property type must be a number.
Supported methods:
* `average_by_property` - Calculate the average of the property of the entities that match the query. For example, average cpu usage of a microservice.
* `aggregate_by_property` - Aggregate the value of the property of the entities that match the query, supported aggregation functions are: `sum, min, max, median`. For example, sum the story points of open Jira issues related to a microservice.
- Sum
- Average
- Min
- Max
- Median
In this example, we have a microservice blueprint, and we want to calculate the sum of the story points of open Jira issues related to each microservice.
```
resource "port_blueprint" "microservice_blueprint" {
title = "Microservice Blueprint"
icon = "Terraform"
identifier = "microservice"
description = ""
}
resource "port_blueprint" "jira_issue_blueprint" {
title = "Jira Issue Blueprint"
icon = "Terraform"
identifier = "jira_issue"
description = ""
properties = {
number_props = {
"storyPoints" = {
title = "Story Points"
}
}
}
relations = {
"microservice" = {
title = "Microservice"
target = port_blueprint.microservice_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "microservice_aggregation_properties" {
blueprint_identifier = port_blueprint.microservice_blueprint.identifier
properties = {
sum_of_story_points = {
target_blueprint_identifier = port_blueprint.jira_issue_blueprint.identifier
title = "Sum of story points"
icon = "Terraform"
description = "Sum of story points"
method = {
aggregate_by_property = {
func = "sum"
property = "storyPoints"
}
}
}
}
}
```
In this example, we have a microservice blueprint, and we want to calculate the average cpu usage of each microservice.
```
resource "port_blueprint" "microservice_blueprint" {
title = "Microservice Blueprint"
icon = "Terraform"
identifier = "microservice"
description = ""
}
resource "port_blueprint" "deployment_blueprint" {
title = "Deployment Blueprint"
icon = "Terraform"
identifier = "deployment"
description = ""
properties = {
number_props = {
"cpuUsage" = {
title = "CPU Usage"
}
}
}
relations = {
"microservice" = {
title = "Microservice"
target = port_blueprint.microservice_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "microservice_aggregation_properties" {
blueprint_identifier = port_blueprint.microservice_blueprint.identifier
properties = {
average_cpu_usage = {
target_blueprint_identifier = port_blueprint.deployment_blueprint.identifier
title = "Average CPU usage"
icon = "Terraform"
description = "Average CPU usage"
method = {
average_by_property = {
average_of = "week"
measure_time_by = "$createdAt"
property = "cpuUsage"
}
}
}
}
}
```
In this example, we have a microservice blueprint, and we want to calculate the minimum value of the alert severity of each microservice in the last week.
```
resource "port_blueprint" "microservice_blueprint" {
title = "Microservice Blueprint"
icon = "Terraform"
identifier = "microservice"
description = ""
}
resource "port_blueprint" "alert_blueprint" {
title = "Alert Blueprint"
icon = "Terraform"
identifier = "alert"
description = ""
properties = {
number_props = {
"severity" = {
title = "Severity"
}
}
}
relations = {
"microservice" = {
title = "Microservice"
target = port_blueprint.microservice_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "microservice_aggregation_properties" {
blueprint_identifier = port_blueprint.microservice_blueprint.identifier
properties = {
min_alert_severity = {
target_blueprint_identifier = port_blueprint.alert_blueprint.identifier
title = "Minimum alert severity"
icon = "Terraform"
description = "Minimum alert severity"
method = {
aggregate_by_property = {
func = "min"
property = "severity"
}
}
}
}
}
```
In this example, we have a microservice blueprint, and we want to calculate the maximum value of the alert severity of each microservice in the last week.
```
resource "port_blueprint" "microservice_blueprint" {
title = "Microservice Blueprint"
icon = "Terraform"
identifier = "microservice"
description = ""
}
resource "port_blueprint" "alert_blueprint" {
title = "Alert Blueprint"
icon = "Terraform"
identifier = "alert"
description = ""
properties = {
number_props = {
"severity" = {
title = "Severity"
}
}
}
relations = {
"microservice" = {
title = "Microservice"
target = port_blueprint.microservice_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "microservice_aggregation_properties" {
blueprint_identifier = port_blueprint.microservice_blueprint.identifier
properties = {
max_alert_severity = {
target_blueprint_identifier = port_blueprint.alert_blueprint.identifier
title = "Maximum alert severity"
icon = "Terraform"
description = "Maximum alert severity"
method = {
aggregate_by_property = {
func = "max"
property = "severity"
}
}
}
}
}
```
In this example, we have a microservice blueprint, and we want to calculate the median value of the cpu usage across all related pods of each microservice.
```
resource "port_blueprint" "microservice_blueprint" {
title = "Microservice Blueprint"
icon = "Terraform"
identifier = "microservice"
description = ""
}
resource "port_blueprint" "pod_blueprint" {
title = "Pod Blueprint"
icon = "Terraform"
identifier = "pod"
description = ""
properties = {
number_props = {
"cpuUsage" = {
title = "CPU Usage"
}
}
}
relations = {
"microservice" = {
title = "Microservice"
target = port_blueprint.microservice_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "microservice_aggregation_properties" {
blueprint_identifier = port_blueprint.microservice_blueprint.identifier
properties = {
median_cpu_usage = {
target_blueprint_identifier = port_blueprint.pod_blueprint.identifier
title = "Median CPU usage"
icon = "Terraform"
description = "Median CPU usage"
method = {
aggregate_by_property = {
func = "median"
property = "cpuUsage"
}
}
}
}
}
```
### Using a `query` in aggregation properties
You can use the query to filter the entities you want to perform the calculation on.
The query is based on the Filters to include or exclude specific data based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules)
#### Query Example
Create a repository blueprint and a pull request blueprint and an aggregation property to calculate the average of fix pull request per month:
To do that we will add a query to the aggregation property to filter only pull requests with fixed title:
```
resource "port_blueprint" "repository_blueprint" {
title = "Repository Blueprint"
icon = "Terraform"
identifier = "repository"
description = ""
}
resource "port_blueprint" "pull_request_blueprint" {
title = "Pull Request Blueprint"
icon = "Terraform"
identifier = "pull_request"
description = ""
properties = {
string_props = {
"status" = {
title = "Status"
}
}
}
relations = {
"repository" = {
title = "Repository"
target = port_blueprint.repository_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "repository_aggregation_properties" {
blueprint_identifier = port_blueprint.repository_blueprint.identifier
properties = {
fix_pull_requests_count = {
target_blueprint_identifier = port_blueprint.pull_request_blueprint.identifier
title = "Pull requests per month"
icon = "Terraform"
description = "Pull requests per month"
method = {
average_entities = {
average_of = "month"
measure_time_by = "$createdAt"
}
}
query = jsonencode(
{
"combinator" : "and",
"rules" : [
{
"property" : "$title",
"operator" : "ContainsAny",
"value" : ["fix", "fixed", "fixing", "Fix"]
}
]
}
)
}
}
}
```
### Calculate by entities
Calculate by entities is used to calculate metrics based on the entities that match the query.
Supported methods:
* `countEntities` - Count the number of entities that match the query. For example, count the number of open Jira issues related to a microservice.
* `averageEntities` - Calculate the average of entities per a defined time period. For example, calculate the average deployment frequency per week.
In Pulumi, aggregation properties are defined using the `port.AggregationProperties` resource (separate from the blueprint). Below are examples in different languages.
* TypeScript
* Python
* JavaScript
* Go
**Entities count** - Count the number of child entities related to each parent:
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
const parentBlueprint = new port.Blueprint("parentBlueprint", {
identifier: "parent",
title: "Parent Blueprint",
properties: {
numberProps: {
age: { title: "Age" },
},
},
});
const childBlueprint = new port.Blueprint("childBlueprint", {
identifier: "child",
title: "Child Blueprint",
properties: {
numberProps: {
age: { title: "Age" },
},
},
relations: {
parent: {
title: "Parent",
target: parentBlueprint.identifier,
},
},
});
const parentAggregationProperties = new port.AggregationProperties("parentAggregationProperties", {
blueprintIdentifier: parentBlueprint.identifier,
properties: {
count_kids: {
targetBlueprintIdentifier: childBlueprint.identifier,
title: "Count Kids",
icon: "Terraform",
description: "Count Kids",
method: {
countEntities: true,
},
},
},
});
```
**Entities average** - Average deployment frequency per week for each microservice:
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
const microserviceBlueprint = new port.Blueprint("microserviceBlueprint", {
identifier: "microservice",
title: "Microservice Blueprint",
});
const deploymentBlueprint = new port.Blueprint("deploymentBlueprint", {
identifier: "deployment",
title: "Deployment Blueprint",
relations: {
microservice: {
title: "Microservice",
target: microserviceBlueprint.identifier,
},
},
});
const microserviceAggregationProperties = new port.AggregationProperties("microserviceAggregationProperties", {
blueprintIdentifier: microserviceBlueprint.identifier,
properties: {
average_deployment_frequency: {
targetBlueprintIdentifier: deploymentBlueprint.identifier,
title: "Average deployment frequency",
icon: "Terraform",
description: "Average deployment frequency",
method: {
averageEntities: {
averageOf: "week",
measureTimeBy: "$createdAt",
},
},
},
},
});
```
**Entities count** - Count the number of child entities related to each parent:
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint, AggregationProperties
parent_blueprint = Blueprint(
"parentBlueprint",
identifier="parent",
title="Parent Blueprint",
properties={
"number_props": {
"age": {"title": "Age"},
},
},
)
child_blueprint = Blueprint(
"childBlueprint",
identifier="child",
title="Child Blueprint",
properties={
"number_props": {
"age": {"title": "Age"},
},
},
relations={
"parent": {
"title": "Parent",
"target": parent_blueprint.identifier,
},
},
)
parent_aggregation_properties = AggregationProperties(
"parentAggregationProperties",
blueprint_identifier=parent_blueprint.identifier,
properties={
"count_kids": {
"target_blueprint_identifier": child_blueprint.identifier,
"title": "Count Kids",
"icon": "Terraform",
"description": "Count Kids",
"method": {
"count_entities": True,
},
},
},
)
```
**Entities average** - Average deployment frequency per week for each microservice:
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint, AggregationProperties
microservice_blueprint = Blueprint(
"microserviceBlueprint",
identifier="microservice",
title="Microservice Blueprint",
)
deployment_blueprint = Blueprint(
"deploymentBlueprint",
identifier="deployment",
title="Deployment Blueprint",
relations={
"microservice": {
"title": "Microservice",
"target": microservice_blueprint.identifier,
},
},
)
microservice_aggregation_properties = AggregationProperties(
"microserviceAggregationProperties",
blueprint_identifier=microservice_blueprint.identifier,
properties={
"average_deployment_frequency": {
"target_blueprint_identifier": deployment_blueprint.identifier,
"title": "Average deployment frequency",
"icon": "Terraform",
"description": "Average deployment frequency",
"method": {
"average_entities": {
"average_of": "week",
"measure_time_by": "$createdAt",
},
},
},
},
)
```
**Entities count** - Count the number of child entities related to each parent:
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const parentBlueprint = new port.Blueprint("parentBlueprint", {
identifier: "parent",
title: "Parent Blueprint",
properties: {
numberProps: {
age: { title: "Age" },
},
},
});
const childBlueprint = new port.Blueprint("childBlueprint", {
identifier: "child",
title: "Child Blueprint",
properties: {
numberProps: {
age: { title: "Age" },
},
},
relations: {
parent: {
title: "Parent",
target: parentBlueprint.identifier,
},
},
});
const parentAggregationProperties = new port.AggregationProperties("parentAggregationProperties", {
blueprintIdentifier: parentBlueprint.identifier,
properties: {
count_kids: {
targetBlueprintIdentifier: childBlueprint.identifier,
title: "Count Kids",
icon: "Terraform",
description: "Count Kids",
method: {
countEntities: true,
},
},
},
});
```
**Entities average** - Average deployment frequency per week for each microservice:
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const microserviceBlueprint = new port.Blueprint("microserviceBlueprint", {
identifier: "microservice",
title: "Microservice Blueprint",
});
const deploymentBlueprint = new port.Blueprint("deploymentBlueprint", {
identifier: "deployment",
title: "Deployment Blueprint",
relations: {
microservice: {
title: "Microservice",
target: microserviceBlueprint.identifier,
},
},
});
const microserviceAggregationProperties = new port.AggregationProperties("microserviceAggregationProperties", {
blueprintIdentifier: microserviceBlueprint.identifier,
properties: {
average_deployment_frequency: {
targetBlueprintIdentifier: deploymentBlueprint.identifier,
title: "Average deployment frequency",
icon: "Terraform",
description: "Average deployment frequency",
method: {
averageEntities: {
averageOf: "week",
measureTimeBy: "$createdAt",
},
},
},
},
});
```
**Entities count** - Count the number of child entities related to each parent:
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
parentBlueprint, err := port.NewBlueprint(ctx, "parentBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("parent"),
Title: pulumi.String("Parent Blueprint"),
Properties: port.BlueprintPropertiesArgs{
NumberProps: port.BlueprintPropertiesNumberPropsMap{
"age": port.BlueprintPropertiesNumberPropsArgs{
Title: pulumi.String("Age"),
},
},
},
})
if err != nil {
return err
}
childBlueprint, err := port.NewBlueprint(ctx, "childBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("child"),
Title: pulumi.String("Child Blueprint"),
Properties: port.BlueprintPropertiesArgs{
NumberProps: port.BlueprintPropertiesNumberPropsMap{
"age": port.BlueprintPropertiesNumberPropsArgs{
Title: pulumi.String("Age"),
},
},
},
Relations: port.BlueprintRelationsMap{
"parent": port.BlueprintRelationsArgs{
Title: pulumi.String("Parent"),
Target: parentBlueprint.Identifier,
},
},
})
if err != nil {
return err
}
_, err = port.NewAggregationProperties(ctx, "parentAggregationProperties", &port.AggregationPropertiesArgs{
BlueprintIdentifier: parentBlueprint.Identifier,
Properties: port.AggregationPropertiesPropertiesMap{
"count_kids": port.AggregationPropertiesPropertiesArgs{
TargetBlueprintIdentifier: childBlueprint.Identifier,
Title: pulumi.String("Count Kids"),
Icon: pulumi.String("Terraform"),
Description: pulumi.String("Count Kids"),
Method: port.AggregationPropertiesPropertiesMethodArgs{
CountEntities: pulumi.Bool(true),
},
},
},
})
return err
})
}
```
**Entities average** - Average deployment frequency per week for each microservice:
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
microserviceBlueprint, err := port.NewBlueprint(ctx, "microserviceBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("microservice"),
Title: pulumi.String("Microservice Blueprint"),
})
if err != nil {
return err
}
deploymentBlueprint, err := port.NewBlueprint(ctx, "deploymentBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("deployment"),
Title: pulumi.String("Deployment Blueprint"),
Relations: port.BlueprintRelationsMap{
"microservice": port.BlueprintRelationsArgs{
Title: pulumi.String("Microservice"),
Target: microserviceBlueprint.Identifier,
},
},
})
if err != nil {
return err
}
_, err = port.NewAggregationProperties(ctx, "microserviceAggregationProperties", &port.AggregationPropertiesArgs{
BlueprintIdentifier: microserviceBlueprint.Identifier,
Properties: port.AggregationPropertiesPropertiesMap{
"average_deployment_frequency": port.AggregationPropertiesPropertiesArgs{
TargetBlueprintIdentifier: deploymentBlueprint.Identifier,
Title: pulumi.String("Average deployment frequency"),
Icon: pulumi.String("Terraform"),
Description: pulumi.String("Average deployment frequency"),
Method: port.AggregationPropertiesPropertiesMethodArgs{
AverageEntities: &port.AggregationPropertiesPropertiesMethodAverageEntitiesArgs{
AverageOf: pulumi.String("week"),
MeasureTimeBy: pulumi.String("$createdAt"),
},
},
},
},
})
return err
})
}
```
### Calculate by property
Calculate by property is used to calculate metrics based on the property of the entities that match the query. The property type must be a number. Use `aggregateByProperty` with `func` set to `"sum"`, `"min"`, `"max"`, or `"median"`, or use `averageByProperty` for time-based averages.
**Sum example (TypeScript)** - Sum of story points of open Jira issues per microservice:
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
const microserviceBlueprint = new port.Blueprint("microserviceBlueprint", {
identifier: "microservice",
title: "Microservice Blueprint",
});
const jiraIssueBlueprint = new port.Blueprint("jiraIssueBlueprint", {
identifier: "jira_issue",
title: "Jira Issue Blueprint",
properties: {
numberProps: {
storyPoints: { title: "Story Points" },
},
},
relations: {
microservice: {
title: "Microservice",
target: microserviceBlueprint.identifier,
},
},
});
const microserviceAggregationProperties = new port.AggregationProperties("microserviceAggregationProperties", {
blueprintIdentifier: microserviceBlueprint.identifier,
properties: {
sum_of_story_points: {
targetBlueprintIdentifier: jiraIssueBlueprint.identifier,
title: "Sum of story points",
icon: "Terraform",
description: "Sum of story points",
method: {
aggregateByProperty: {
func: "sum",
property: "storyPoints",
},
},
},
},
});
```
### Using a `query` in aggregation properties
You can use the `query` property to filter the entities you want to perform the calculation on. The query is based on Port's [Search Rules](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules).
**Query example (TypeScript)** - Average of fix pull requests per month per repository:
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
const repositoryBlueprint = new port.Blueprint("repositoryBlueprint", {
identifier: "repository",
title: "Repository Blueprint",
});
const pullRequestBlueprint = new port.Blueprint("pullRequestBlueprint", {
identifier: "pull_request",
title: "Pull Request Blueprint",
properties: {
stringProps: {
status: { title: "Status" },
},
},
relations: {
repository: {
title: "Repository",
target: repositoryBlueprint.identifier,
},
},
});
const repositoryAggregationProperties = new port.AggregationProperties("repositoryAggregationProperties", {
blueprintIdentifier: repositoryBlueprint.identifier,
properties: {
fix_pull_requests_count: {
targetBlueprintIdentifier: pullRequestBlueprint.identifier,
title: "Pull requests per month",
icon: "Terraform",
description: "Pull requests per month",
method: {
averageEntities: {
averageOf: "month",
measureTimeBy: "$createdAt",
},
},
query: JSON.stringify({
combinator: "and",
rules: [
{
property: "$title",
operator: "ContainsAny",
value: ["fix", "fixed", "fixing", "Fix"],
},
],
}),
},
},
});
```
### Path filter[](#path-filter "Direct link to Path filter")
The `pathFilter` option lets you control which entities are included in your aggregation calculation based on their relationship path from the source entity. This is useful for complex relationship chains, where you may want to aggregate data only from entities connected through specific paths.
When a `pathFilter` is defined, Port will include only entities that can be reached through the exact relationship path you specify.
* **Forwards path →**
Following relations forwards, from the source of a relation to its target (e.g., from a repository to its services).
* **Backwards path ←**
Following relations backwards, from the target of a relation to its source (e.g., from a service back to its repository).
**Structure**
| Field | Description |
| -------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `pathFilter.path` | An array containing the full path of relation identifiers to traverse. |
| `pathFilter.fromBlueprint` | *(Optional)* The blueprint to start the path traversal from. Can be the target blueprint or omitted. If omitted, traversal starts from the source blueprint. |
**For forwards paths**
```
{
"pathFilter": [
{
"path": ["relation1", "relation2", "relation3"]
}
]
}
```
**For backwards paths**
```
{
"pathFilter": [
{
"path": ["relation1", "relation2", "relation3"],
"fromBlueprint": "{{targetBlueprint}}"
}
]
}
```
#### Examples[](#examples "Direct link to Examples")
Suppose you have the following data model:
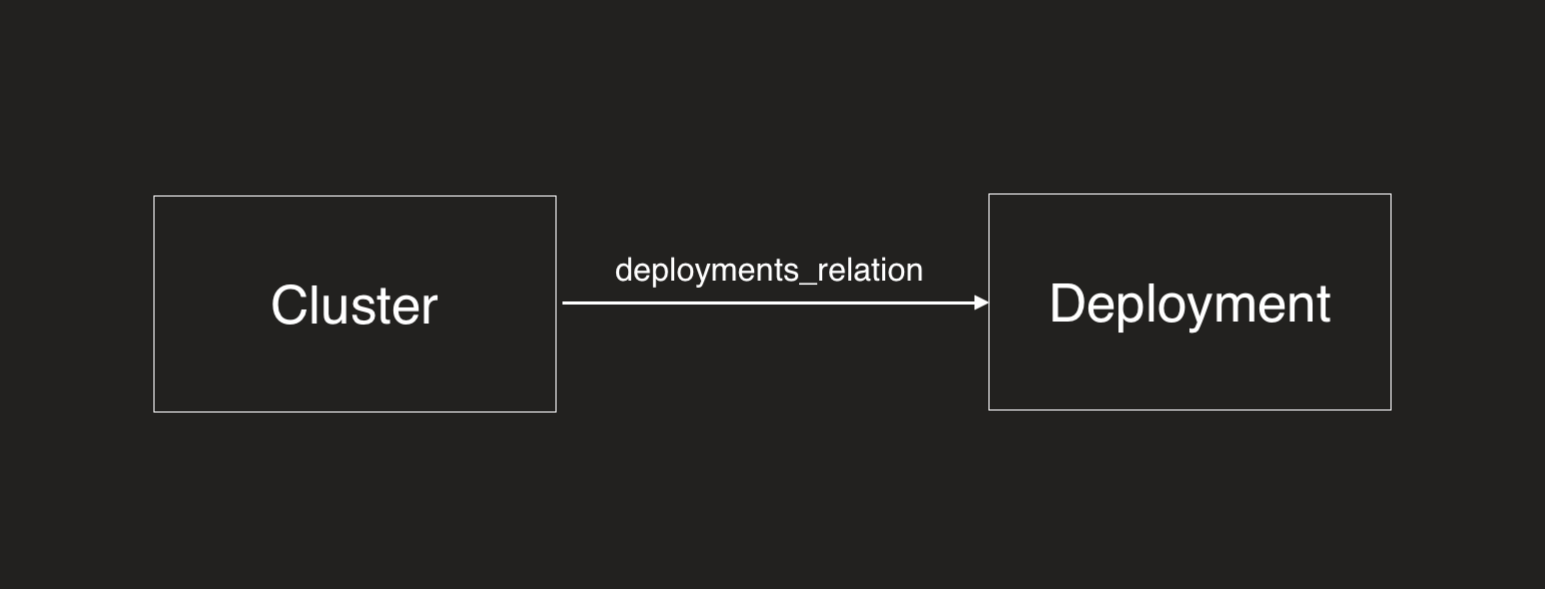
* API
* Terraform
* Pulumi
**Example 1: Standard Path Filter - forwards path**
Count how many deployments are directly related to a cluster:
```
{
"identifier": "cluster",
"title": "Cluster",
"aggregationProperties": {
"deploymentCount": {
"title": "Deployment Count",
"target": "deployment",
"pathFilter": [
{
"path": ["deployments_relation"]
}
],
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
}
}
}
}
```
The `pathFilter` with `"path": ["deployments_relation"]` counts deployments that are directly related to the cluster through the `deployments_relation` relation.
**Example 2: Using fromBlueprint - backwards path**
Count how many clusters are related to a deployment:
```
{
"identifier": "deployment",
"title": "Deployment",
"aggregationProperties": {
"clusterCount": {
"title": "Cluster Count",
"target": "cluster",
"pathFilter": [
{
"path": ["deployments_relation"],
"fromBlueprint": "cluster"
}
],
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
}
}
}
}
```
The `fromBlueprint: "cluster"` specifies that the path traversal should start from the cluster blueprint (the target), then follow the path backwards through `deployments_relation` to deployment.
**Example 1: Standard Path Filter - forwards path**
Count how many deployments are directly related to a cluster:
```
resource "port_blueprint" "cluster_blueprint" {
identifier = "cluster"
title = "Cluster"
relations = {
"deployments_relation" = {
title = "Deployments"
target = port_blueprint.deployment_blueprint.identifier
}
}
}
resource "port_blueprint" "deployment_blueprint" {
identifier = "deployment"
title = "Deployment"
}
resource "port_aggregation_properties" "cluster_aggregation_properties" {
blueprint_identifier = port_blueprint.cluster_blueprint.identifier
properties = {
deployment_count = {
target_blueprint_identifier = port_blueprint.deployment_blueprint.identifier
title = "Deployment Count"
icon = "Terraform"
description = "Deployment Count"
path_filter = [
{
path = ["deployments_relation"]
}
]
method = {
count_entities = true
}
}
}
}
```
The `path = ["deployments_relation"]` counts deployments that are directly related to the cluster through the `deployments_relation` relation.
**Example 2: Using fromBlueprint - backwards path**
Count how many clusters are related to a deployment:
```
resource "port_blueprint" "deployment_blueprint" {
identifier = "deployment"
title = "Deployment"
}
resource "port_blueprint" "cluster_blueprint" {
identifier = "cluster"
title = "Cluster"
relations = {
"deployments_relation" = {
title = "Deployments"
target = port_blueprint.deployment_blueprint.identifier
}
}
}
resource "port_aggregation_properties" "deployment_aggregation_properties" {
blueprint_identifier = port_blueprint.deployment_blueprint.identifier
properties = {
cluster_count = {
target_blueprint_identifier = port_blueprint.cluster_blueprint.identifier
title = "Cluster Count"
icon = "Terraform"
description = "Cluster Count"
path_filter = [
{
path = ["deployments_relation"]
from_blueprint = "cluster"
}
]
method = {
count_entities = true
}
}
}
}
```
The `from_blueprint = "cluster"` specifies that the path traversal should start from the cluster blueprint (the target), then follow the path backwards through `deployments_relation` to deployment.
**Example 1: Standard path filter - forwards path**
Count how many deployments are directly related to a cluster:
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
const deploymentBlueprint = new port.Blueprint("deploymentBlueprint", {
identifier: "deployment",
title: "Deployment",
});
const clusterBlueprint = new port.Blueprint("clusterBlueprint", {
identifier: "cluster",
title: "Cluster",
relations: {
deployments_relation: {
title: "Deployments",
target: deploymentBlueprint.identifier,
},
},
});
const clusterAggregationProperties = new port.AggregationProperties("clusterAggregationProperties", {
blueprintIdentifier: clusterBlueprint.identifier,
properties: {
deployment_count: {
targetBlueprintIdentifier: deploymentBlueprint.identifier,
title: "Deployment Count",
icon: "Terraform",
description: "Deployment Count",
pathFilters: [
{
paths: ["deployments_relation"],
},
],
method: {
countEntities: true,
},
},
},
});
```
The `pathFilters` with `paths: ["deployments_relation"]` counts deployments that are directly related to the cluster through the `deployments_relation` relation.
**Example 2: Using fromBlueprint - backwards path**
Count how many clusters are related to a deployment:
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
const deploymentBlueprint = new port.Blueprint("deploymentBlueprint", {
identifier: "deployment",
title: "Deployment",
});
const clusterBlueprint = new port.Blueprint("clusterBlueprint", {
identifier: "cluster",
title: "Cluster",
relations: {
deployments_relation: {
title: "Deployments",
target: deploymentBlueprint.identifier,
},
},
});
const deploymentAggregationProperties = new port.AggregationProperties("deploymentAggregationProperties", {
blueprintIdentifier: deploymentBlueprint.identifier,
properties: {
cluster_count: {
targetBlueprintIdentifier: clusterBlueprint.identifier,
title: "Cluster Count",
icon: "Terraform",
description: "Cluster Count",
pathFilters: [
{
paths: ["deployments_relation"],
fromBlueprint: "cluster",
},
],
method: {
countEntities: true,
},
},
},
});
```
The `fromBlueprint: "cluster"` specifies that the path traversal should start from the cluster blueprint (the target), then follow the path backwards through `deployments_relation` to deployment.
Path Filter Performance
Path filters can affect the performance of aggregation calculations. In general, shorter and more direct paths perform better than long or complex multi-hop paths.
## Examples[](#examples-1 "Direct link to Examples")
Below is a collection of real-world aggregation property use cases organized by category. Each includes a description of the use case and the JSON definition you can copy directly into your blueprint.
### DevOps & deployments[](#devops--deployments "Direct link to DevOps & deployments")
**Deployment frequency (weekly average) (click to expand)**
Track how often deployments occur per week for each service.
```
{
"deploymentFrequency": {
"title": "Deployment frequency",
"target": "deployment",
"calculationSpec": {
"calculationBy": "entities",
"func": "average",
"averageOf": "week",
"measureTimeBy": "$createdAt"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "SUCCESS"
}
]
}
}
}
```
**Total deployments count (click to expand)**
Count the total number of deployments for a service.
```
{
"totalDeployments": {
"title": "Total deployments",
"target": "deployment",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
}
}
}
```
**Failed deployments in the last week (click to expand)**
Count deployments that failed in the past 7 days.
```
{
"failedDeploymentsLastWeek": {
"title": "Failed deployments (last week)",
"target": "deployment",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "FAILED"
},
{
"property": "$createdAt",
"operator": "between",
"value": {
"preset": "lastWeek"
}
}
]
}
}
}
```
**Total CI/CD pipelines (click to expand)**
Count the number of workflows/pipelines associated with a repository.
```
{
"totalPipelines": {
"title": "Total pipelines",
"target": "githubWorkflow",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
}
}
}
```
### Pull requests & code review[](#pull-requests--code-review "Direct link to Pull requests & code review")
**Open pull requests count (click to expand)**
Count all open PRs for a service or repository.
```
{
"openPullRequests": {
"title": "Open pull requests",
"target": "githubPullRequest",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "open"
}
]
}
}
}
```
**Merged PRs per week (click to expand)**
Track the average number of PRs merged per week.
```
{
"mergedPRsPerWeek": {
"title": "Merged PRs per week",
"target": "githubPullRequest",
"calculationSpec": {
"calculationBy": "entities",
"func": "average",
"averageOf": "week",
"measureTimeBy": "mergedAt"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "merged"
}
]
}
}
}
```
**Average PR lead time (hours) (click to expand)**
Calculate the average time from PR creation to merge.
```
{
"averagePRLeadTime": {
"title": "Average PR lead time (hours)",
"target": "githubPullRequest",
"calculationSpec": {
"calculationBy": "property",
"func": "average",
"property": "leadTimeHours",
"averageOf": "total",
"measureTimeBy": "$createdAt"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "merged"
}
]
}
}
}
```
**Total lines changed (click to expand)**
Sum the total lines added and deleted across all PRs.
```
{
"totalLinesChanged": {
"title": "Total lines changed",
"target": "githubPullRequest",
"calculationSpec": {
"calculationBy": "property",
"func": "sum",
"property": "linesChanged"
}
}
}
```
### Issues & project management[](#issues--project-management "Direct link to Issues & project management")
**Open Jira issues count (click to expand)**
Count open issues assigned to a service or team.
```
{
"openJiraIssues": {
"title": "Open Jira issues",
"target": "jiraIssue",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "in",
"value": ["To Do", "In Progress", "In Review"]
}
]
}
}
}
```
**Total story points (open work) (click to expand)**
Sum story points for all open issues.
```
{
"totalStoryPoints": {
"title": "Total story points (open)",
"target": "jiraIssue",
"calculationSpec": {
"calculationBy": "property",
"func": "sum",
"property": "storyPoints"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "!=",
"value": "Done"
}
]
}
}
}
```
**High-priority bugs count (click to expand)**
Count critical and high-priority bugs.
```
{
"highPriorityBugs": {
"title": "High priority bugs",
"target": "jiraIssue",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "issueType",
"operator": "=",
"value": "Bug"
},
{
"property": "priority",
"operator": "in",
"value": ["Critical", "High"]
},
{
"property": "status",
"operator": "!=",
"value": "Done"
}
]
}
}
}
```
### Security & vulnerabilities[](#security--vulnerabilities "Direct link to Security & vulnerabilities")
**Critical vulnerabilities count (click to expand)**
Count unresolved critical and high severity vulnerabilities.
```
{
"criticalVulnerabilities": {
"title": "Critical vulnerabilities",
"target": "vulnerability",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "severity",
"operator": "in",
"value": ["CRITICAL", "HIGH"]
},
{
"property": "status",
"operator": "!=",
"value": "RESOLVED"
}
]
}
}
}
```
**Total open vulnerabilities (click to expand)**
Count all unresolved vulnerabilities regardless of severity.
```
{
"openVulnerabilities": {
"title": "Open vulnerabilities",
"target": "vulnerability",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "!=",
"value": "RESOLVED"
}
]
}
}
}
```
### Incidents & alerts[](#incidents--alerts "Direct link to Incidents & alerts")
**Open incidents count (click to expand)**
Count active incidents for a service.
```
{
"openIncidents": {
"title": "Open incidents",
"target": "incident",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "in",
"value": ["triggered", "acknowledged"]
}
]
}
}
}
```
**Mean time to resolve (MTTR) (click to expand)**
Calculate the average time to resolve incidents.
```
{
"mttr": {
"title": "MTTR (hours)",
"target": "incident",
"calculationSpec": {
"calculationBy": "property",
"func": "average",
"property": "timeToResolveHours",
"averageOf": "month",
"measureTimeBy": "resolvedAt"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "resolved"
}
]
}
}
}
```
**P1 incidents in the last month (click to expand)**
Count high-severity incidents from the past month.
```
{
"p1IncidentsLastMonth": {
"title": "P1 incidents (last month)",
"target": "incident",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "severity",
"operator": "=",
"value": "P1"
},
{
"property": "$createdAt",
"operator": "between",
"value": {
"preset": "lastMonth"
}
}
]
}
}
}
```
### Infrastructure & resources[](#infrastructure--resources "Direct link to Infrastructure & resources")
**Running pods count (click to expand)**
Count pods in running state for a workload.
```
{
"runningPods": {
"title": "Running pods",
"target": "pod",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "Running"
}
]
}
}
}
```
**Average CPU usage (click to expand)**
Calculate average CPU usage across related resources.
```
{
"averageCpuUsage": {
"title": "Average CPU usage (%)",
"target": "pod",
"calculationSpec": {
"calculationBy": "property",
"func": "average",
"property": "cpuUsage",
"averageOf": "total",
"measureTimeBy": "$updatedAt"
}
}
}
```
**Total memory allocated (click to expand)**
Sum memory allocation across all pods.
```
{
"totalMemoryAllocated": {
"title": "Total memory allocated (MB)",
"target": "pod",
"calculationSpec": {
"calculationBy": "property",
"func": "sum",
"property": "memoryAllocatedMB"
}
}
}
```
### SLOs & compliance[](#slos--compliance "Direct link to SLOs & compliance")
**Number of SLOs defined (click to expand)**
Count how many SLOs are defined for a service.
```
{
"numberOfSLOs": {
"title": "Number of SLOs",
"target": "serviceLevelObjective",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
}
}
}
```
**Failing SLOs count (click to expand)**
Count SLOs that are currently not meeting their targets.
```
{
"failingSLOs": {
"title": "Failing SLOs",
"target": "serviceLevelObjective",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
},
"query": {
"combinator": "and",
"rules": [
{
"property": "status",
"operator": "=",
"value": "Failed"
}
]
}
}
}
```
**Has PR template (boolean check) (click to expand)**
Count PR templates to determine if one exists (use with calculation property to convert to boolean).
```
{
"hasPRTemplate": {
"title": "Has PR template",
"target": "pullRequestTemplate",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
}
}
}
```
### Costs & cloud resources[](#costs--cloud-resources "Direct link to Costs & cloud resources")
**Total monthly cost (click to expand)**
Sum the cost of all related cloud resources.
```
{
"totalMonthlyCost": {
"title": "Total monthly cost ($)",
"target": "cloudResource",
"calculationSpec": {
"calculationBy": "property",
"func": "sum",
"property": "monthlyCost"
}
}
}
```
**Number of cloud resources (click to expand)**
Count cloud resources associated with a service or environment.
```
{
"cloudResourceCount": {
"title": "Cloud resources",
"target": "cloudResource",
"calculationSpec": {
"calculationBy": "entities",
"func": "count"
}
}
}
```
## Limitations[](#limitations "Direct link to Limitations")
* The aggregation property value for all entities of a blueprint will be recalculated **every 15 minutes**.
* The maximum number of entities based on the blueprint where the aggregation property is defined is **20,000**.
* If the total number of connected target entities across all relations exceeds **2,000,000** after filtering, the aggregation property will not be calculated.
* When calculating by property (`sum`, `average`, `min`, `max`, `median`), only **number** type properties are supported.
---
# Array
Array is a data type used to save lists of data.
## Common usage[](#common-usage "Direct link to Common usage")
Use array properties to store multiple values for an entity, such as:
* Programming languages used in a repository.
* Container image tags available for a service.
* Monitoring tools configured for a service.
* Links to runbooks and dashboards.
Use [relations](/context-lake/data-model/setup-blueprint/relate-blueprints/.md) when these values represent other entities in your catalog.
## Multi source ingestion[](#multi-source-ingestion "Direct link to Multi source ingestion")
By default, array properties use last-writer-wins behavior: each update replaces the full array.
Enable **Multi source ingestion** to let multiple [connectors](/context-lake/ingestion/overview/.md) or API callers contribute to the same list without overwriting each other. This works for **string** and **number** item types only.
In the [Data model](https://app.port.io/settings/data-model) or software catalog, turn on **Multi source ingestion** when creating the property.
In the API, set `"union": true`. This setting cannot be changed after creation.
### Example[](#example "Direct link to Example")
The `service` blueprint has multi source ingestion enabled on its `vulnerabilities` property. For a `payments-api` entity:
1. **Monday** - the Snyk integration writes `{ "snyk": ["CVE-101", "CVE-102"] }`.
2. **Tuesday** - Dependabot writes `{ "dependabot": ["CVE-102", "CVE-203"] }` without removing Snyk's findings.
3. **Wednesday** - Alice edits the entity in the UI and adds `CVE-300`. Port saves her changes under `user:alice`.
A **GET** returns the merged, deduplicated array:
```
{ "vulnerabilities": ["CVE-101", "CVE-102", "CVE-203", "CVE-300"] }
```
Each writer only updates its own source key. `CVE-102` appears once even though both scanners reported it.
### Write and read values[](#write-and-read-values "Direct link to Write and read values")
**Write** (`POST`, `PATCH`, `PUT`) - send one source key per update:
```
{
"properties": {
"vulnerabilities": {
"scanner-a": ["CVE-2024-1", "CVE-2024-2"]
}
}
}
```
Use `null` instead of an array to clear a source's slice.
Source keys must match `^[A-Za-z0-9._:@/-]{1,128}$`.
**Read** (`GET`, search) - Port returns the merged, deduplicated array:
```
{ "vulnerabilities": ["CVE-2024-1", "CVE-2024-2", "CVE-2024-3"] }
```
In the UI, you edit the assembled array directly. Port stores UI edits under `user:{userId}` automatically.
Related property types
[Calculation](/context-lake/data-model/setup-blueprint/properties/calculation-property/.md) and [aggregation](/context-lake/data-model/setup-blueprint/properties/aggregation-property/.md) properties read the assembled value.
Multi source ingestion works the same way for [relations](/context-lake/data-model/setup-blueprint/relate-blueprints/.md#multi-source-ingestion) and [owning teams](/context-lake/business-context/ownership/.md#multi-source-ingestion-for-owning-teams): each writer owns a source key, and reads return the deduplicated combination of all sources.
### Constraints[](#constraints "Direct link to Constraints")
* `items.type` must be `string` or `number`.
* `minItems` and `maxItems` are not supported with `union`.
* You cannot toggle `union` after creation. Create a new property and [migrate the data](/context-lake/ingestion/ingest-data-into-port/other/migrate-data/.md) instead.
* Sending a plain array, multiple source keys, or an invalid source key returns `422`.
## API definition[](#api-definition "Direct link to API definition")
```
{
"myArrayProp": {
"title": "My array",
"icon": "My icon",
"description": "My array property",
"type": "array",
"default": [1, 2, 3]
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myArrayProp" = {
title = "My array"
required = true
string_items = {}
}
}
}
}
```
Array types in Terraform
To set the type of an array property, you need to use the `_items` property type. For example, to set an array of strings, you need to use the `string_items` property type.
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myArrayProp" = {
title = "My array"
required = true
string_items = {} # You can also set here default values
}
}
}
}
```
We currently support the following types of array items: `string_items`, `number_items`, `boolean_items`, `object_items`.
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesArrayPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
array_props={
"myArrayProp": BlueprintPropertiesArrayPropsArgs(
title="My array", required=True, string_items={},
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
arrayProps: {
myArrayProp: {
title: "My array",
required: true,
stringItems: {},
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
arrayProps: {
myArrayProp: {
title: "My array",
required: true,
stringItems: {},
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
ArrayProps: port.BlueprintPropertiesArrayPropsMap{
"myArrayProp": port.BlueprintPropertiesArrayPropsArgs{
Title: pulumi.String("My array"),
Required: pulumi.Bool(true),
StringItems: port.BlueprintPropertiesArrayPropsStringItemsArgs{},
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## Validate array[](#validate-array "Direct link to Validate array")
Array validations support the following operators:
* `minItems`
* `maxItems`
* `uniqueItems`
`minItems` and `maxItems` are not supported on [array properties with multi source ingestion enabled](#multi-source-ingestion).
JSON schema validations
Array validations follow the JSON schema model, refer to the [JSON schema docs](https://json-schema.org/understanding-json-schema/reference/array.html) to learn about all of the available validations
* Basic
* Terraform
```
{
"myArrayProp": {
"title": "My array",
"icon": "My icon",
"description": "My array property",
"type": "array",
"minItems": 0,
"maxItems": 5,
"uniqueItems": false
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myArrayProp" = {
title = "My array"
required = true
string_items = {}
min_items = 0
max_items = 5
}
}
}
}
```
---
# Boolean
Boolean is a primitive data type that has one of two possible values - `true` and `false`.
## Common usage[](#common-usage "Direct link to Common usage")
Use boolean properties to record yes/no states, such as:
* Whether an environment allows deployments.
* Whether a service handles personally identifiable information (PII).
* Whether a repository enables branch protection.
* Whether a resource has public network access.
## API definition[](#api-definition "Direct link to API definition")
```
{
"myBooleanProp": {
"title": "My boolean",
"icon": "My icon",
"description": "My boolean property",
"type": "boolean",
"default": true
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
boolean_props = {
"myBooleanProp" = {
title = "My boolean"
required = true
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesBooleanPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
boolean_props={
"myBooleanProp": BlueprintPropertiesBooleanPropsArgs(
title="My boolean",
required=True,
)
}
),
relations={},
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
booleanProps: {
myBooleanProp: {
title: "My boolean",
required: true,
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
booleanProps: {
myBooleanProp: {
title: "My boolean",
required: true,
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
BooleanProps: port.BlueprintPropertiesBooleanPropsMap{
"myBooleanProp": port.BlueprintPropertiesBooleanPropsArgs{
Title: pulumi.String("My boolean"),
Required: pulumi.Bool(false),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
---
# Calculation property
Calculation properties allow you to use existing properties defined on blueprints, either directly or by using relations and mirror properties, in order to create new properties by using the [`jq`](https://github.com/stedolan/jq) processor for `JSON`.
Starting March 30, 2026, [**persistent** calculation properties](#persistent-calculation-properties) were introduced, which have various benefits compared to the legacy calculation properties.
Port accounts created after March 30, 2026 have persistent calculation properties **by default**.
If your account was created before this date, you can [enable persistent calculation properties](#how-to-enable-the-feature) for your organization.
## Common usage[](#common-usage "Direct link to Common usage")
Use calculation properties to derive values from an entity's existing data, such as:
* Build a dashboard URL from a service identifier.
* Count items in a list of code owners.
* Combine configuration objects from properties and mirrors.
* Convert a numeric measurement into a display label.
Use an [aggregation property](/context-lake/data-model/setup-blueprint/properties/aggregation-property/.md) when you need to summarize multiple related entities.
## Definition[](#definition "Direct link to Definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* API
* Terraform
* Pulumi
The `calculationProperties` key is a top-level key in a blueprint definition, alongside `identifier`, `title`, and `schema`.
You can access properties as part of the calculation by using `.properties`
```
{
"calculationProperties": {
"myCalculationProp": {
"title": "My calculation property",
"type": "string",
"calculation": ".properties.myStringProp + .properties.myStringProp"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
myStringProp = { title = "Source string" }
}
}
calculation_properties = {
myCalculationProp = {
title = "My calculation property"
type = "string"
calculation = ".properties.myStringProp + .properties.myStringProp"
}
}
}
```
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintCalculationPropertiesArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={"myStringProp": {"title": "Source string"}}
),
calculation_properties={
"myCalculation": BlueprintCalculationPropertiesArgs(
title="My calculation property", calculation=".properties.myStringProp + .properties.myStringProp", type="string",
)
},
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: { myStringProp: { title: "Source string" } },
},
calculationProperties: {
myCalculation: {
title: "My calculation property",
calculation: ".properties.myStringProp + .properties.myStringProp",
type: "string",
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: { myStringProp: { title: "Source string" } },
},
calculationProperties: {
myCalculation: {
title: "My calculation property",
calculation: ".properties.myStringProp + .properties.myStringProp",
type: "string",
},
},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myStringProp": port.BlueprintPropertiesStringPropsArgs{Title: pulumi.String("Source string")},
},
},
CalculationProperties: port.BlueprintCalculationPropertiesMap{
"myCalculation": port.BlueprintCalculationPropertiesArgs{
Title: pulumi.String("My calculation property"),
Calculation: pulumi.String(".properties.myStringProp + .properties.myStringProp"),
Type: pulumi.String("string"),
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## Supported types[](#supported-types "Direct link to Supported types")
* Basic
* Format
* Spec
Calculation properties support the following output types: `string`, `number`, `object`, `array`, and `boolean`. For example:
```
{
"calculationProperties": {
"myCalculationProp": {
"title": "My calculation property",
"type": "my_output_type",
"calculation": ".properties.myStringProp + .properties.myStringProp"
}
}
}
```
Calculation properties support the following output formats: `yaml`, `team`, `user`, `ipv6`, and `url`. For example:
```
{
"calculationProperties": {
"myCalculationProp": {
"title": "My calculation property",
"type": "string",
"format": "user",
"calculation": ".properties.user"
}
}
}
```
Calculation properties support the following output specs: `markdown`, `open-api` and `async-api`. For example:
```
{
"calculationProperties": {
"myCalculationProp": {
"title": "My calculation property",
"type": "string",
"format": "url",
"spec": "embedded-url"
"calculation": ".properties.text"
}
}
}
```
## Using `meta properties` in calculation properties[](#using-meta-properties-in-calculation-properties "Direct link to using-meta-properties-in-calculation-properties")
It is possible to use [meta properties](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md) as template values for calculation properties.
For example, if you want to concatenate a template URL (for example `https://datadog.com`) with the `identifier` meta property:
Given the following `notification-service` entity:
```
{
"identifier": "notification-service",
"title": "Notification Service",
"properties": {
...
},
}
```
And the following calculation property definition for the blueprint:
```
{
"calculationProperties": {
"monitorUrl": {
"title": "Monitor url",
"type": "string",
"format": "url",
"calculation": "'https://datadog.com/' + .identifier"
}
}
}
```
The value of the property `monitorUrl` will be `https://datadog.com/notification-service`
## Using `mirror properties` in calculation properties[](#using-mirror-properties-in-calculation-properties "Direct link to using-mirror-properties-in-calculation-properties")
It is possible to use [mirror properties](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md) as template values for calculation properties.
For example, if an entity has a mirror property called `owningSquad`:
```
"mirrorProperties": {
"owningSquad": {
"path": "microservice-to-squad.$title"
}
}
```
A calculation property that links to the slack channel of the squad can be:
```
"owning_squad_slack": {
"title": "Owning Squad Channel",
"calculation": "'https://slack.com/' + .properties.owningSquad",
}
```
Calculation on calculation is not supported
Calculation properties **cannot** be used as template values for other calculation properties.
## Colorized calculation properties[](#colorized-calculation-properties "Direct link to Colorized calculation properties")
You can colorize calculation properties according to their value, by adding a `colorized` key with the value `true` to the calculation property object. You can also add a `colors` key to specify the colors of the different values, otherwise, the colors will be chosen automatically for you.
For example, if you want to colorize a calculation property called `status-calculation` with the values `OK`, `WARNING`, and `CRITICAL`:
```
"properties":{
"status":{
"type": "string"
},
},
"calculationProperties": {
"status-calculation": {
"title": "Status",
"type": "string",
"calculation": ".properties.status",
"colorized": true,
"colors": {
"OK": "green",
"WARNING": "yellow",
"CRITICAL": "red"
}
}
}
```
***
Parameters with special characters
Parameters that contain special characters (for example: `-`) or start with a digit (for example: `@/#/$/1/2/3`) should be surrounded with single quotes.
```
"properties":{
"prop-with-special-char":{
"type": "string"
},
},
"calculationProperties": {
"myCalculatedProp": {
"title": "My Calculated Property",
"type": "string",
"calculation": ".properties.'prop-with-special-char'",
}
}
```
## Examples[](#examples "Direct link to Examples")
Refer to the calculation property [examples](/context-lake/data-model/setup-blueprint/properties/calculation-property/examples/.md) page.
## Persistent calculation properties[](#persistent-calculation-properties "Direct link to Persistent calculation properties")
With persistent calculation properties, values are computed and stored in the background, as opposed to being computed on-request.
**Benefits compared to legacy calculation properties:**
These benefits require [persistent calculation properties](#how-to-enable-the-feature) to be enabled.
* **Faster entities table**: Loading the entities table is much faster because calculations are not run on each request (for example, up to **10 times** faster for a blueprint with **100,000** entities and **3** calculation properties).
* **Filter by calculation properties**: You can filter entities by calculation properties in search and the API—something that was not possible before.
* **Richer visualizations**: You can create line charts on calculation properties and use drill-down pie charts based on calculation properties.
* **Automation triggers and conditions**: Since calculation property values are stored like regular properties, any change to a calculation property counts as an entity update. This means [entity change triggers](/workflows/actions-and-automations/define-automations/setup-trigger/.md#available-triggers) will fire when a calculation property value changes, and you can reference calculation properties in trigger [conditions](/workflows/actions-and-automations/define-automations/setup-trigger/.md#conditions).
Automation triggers and blueprint changes
Automations are triggered only when an **entity's** calculation property value changes (for example, because the entity's underlying data changed). Editing the calculation expression on the **blueprint** itself like changing the JQ formula will **not** trigger automations for every entity of that blueprint, even though their values may be recalculated.
### How to enable the feature[](#how-to-enable-the-feature "Direct link to How to enable the feature")
For existing users only
Port accounts created after **March 30, 2026** have persistent calculation properties enabled by default. The steps below apply only to existing users who have not yet enabled this feature.
Before enabling, review the [breaking changes](#breaking-changes) below, or use the [helper script](#identify-calculation-properties-to-review) to scan your organization automatically.
To obtain your bearer token
1. Open the [Credentials](https://app.port.io/organization/home?openModal=credentials) modal.
2. Click on the **Generate API token** button, and copy the generated token.
```
curl -L -X POST 'https://api.port.io/v1/blueprints/persistent-calculation-properties/register' \
-H 'Authorization: '
```
### Identify calculation properties to review[](#identify-calculation-properties-to-review "Direct link to Identify calculation properties to review")
Before you enable the feature, you can run a helper script that scans your Port organization for calculation properties that may need the updates described in [Breaking changes](#breaking-changes) below.
The script is **read-only**: it only reads data from Port and does not modify blueprints, entities, or any other catalog data.
The [persistent calculation properties script](https://github.com/port-labs/script-examples/tree/main/persistent-calculation-properties) in the `port-labs/script-examples` repository:
* Connects to your Port organization.
* Checks whether persistent calculation properties are already enabled.
* Scans blueprint calculation properties for the same breaking patterns (relative `now` in JQ, and `.relations..title` or `.relations..identifier`).
* Generates an HTML report under `output/` (for example `output/index.html`) with summary statistics and a table of properties that need review.
See the repository README for prerequisites, `config.json`, and how to run `npm start`.
### Breaking changes[](#breaking-changes "Direct link to Breaking changes")
When moving to persistent calculation, two behaviors change and may require updates to your calculation properties.
Updates may be required
If you have calculation properties that use relative date (`now`) or relation titles (e.g. `.relations.relationName.title`), review the items below and update them before enabling the feature.
#### Change 1: Relative date (`now` in JQ)[](#change-1-relative-date-now-in-jq "Direct link to change-1-relative-date-now-in-jq")
Calculations that use the `now` JQ function (relative to the current time) are no longer evaluated at request time. Their values are accurate to roughly an hour, not to the second or minute.
**What you can do:**
* If roughly hour-level accuracy is enough for your use case, no change is needed.
* If you need second- or minute-level accuracy, do not compute the relative date inside the calculation property. Store only the **target date** in the property (e.g. from entity data), and compute the relative value (e.g. "minutes ago") where you use the property—for example in the UI or in a workflow.
#### Change 2: Relation titles (`.relations..title`)[](#change-2-relation-titles-relationsnametitle "Direct link to change-2-relation-titles-relationsnametitle")
With persistent calculation, the evaluation context does not use the [Search entities](/api-reference/search-entities/) `attach_title_to_relation` behavior. So JQ that expects relation values to be objects with `.title` (e.g. `.relations.microservice.title`) will break, because in this context relations are **string or array of strings** (identifiers only). For the two response shapes, see the [attach\_title\_to\_relation parameter](/context-lake/consuming-the-lake/search-and-query/advanced/.md#attach_title_to_relation-example) in the advanced search docs.
**What you can do:**
* If you need the related entity's **title** inside the JQ, create a [mirror property](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md) for the title (e.g. `path: "relationName.$title"`) and reference that property in your calculation (e.g. `.properties.myRelationTitle`) instead of `.relations.relationName.title`.
* Otherwise, write the JQ for identifier-only relations (string or array of strings).
### Limitations[](#limitations "Direct link to Limitations")
#### Calculations based on mirror properties[](#calculations-based-on-mirror-properties "Direct link to Calculations based on mirror properties")
[Mirror properties](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md) get their values from a related (parent) entity. When a parent entity's value changes, the calculation property in the child entity that depends on this mirror property is **not** updated in real time. It is only updated on the hourly sync process.
This means:
* If you update a parent entity and immediately read a child entity that has a calculation based on a mirror property from that parent, you may get stale data.
* For API workflows that chain writes and reads, consider using [automation triggers](/workflows/actions-and-automations/define-automations/setup-trigger/.md) on entity updates rather than immediate follow-up API calls.
No race condition for other calculations
Calculation properties that do **not** use the `now` function or mirror properties are calculated before the entity is written to the database. For these calculations, when you receive a success response from a write operation, the calculation value is already accurate.
### Rollback the feature[](#rollback-the-feature "Direct link to Rollback the feature")
If you need to disable persistent calculation and return to on-request evaluation, send a single POST request to the unregister endpoint. It is a straightforward switch—nothing else in your catalog or blueprints changes beyond how calculation properties are evaluated.
The request matches [How to enable the feature](#how-to-enable-the-feature), but use the `unregister` path instead.
```
curl -L -X POST 'https://api.port.io/v1/blueprints/persistent-calculation-properties/unregister' \
-H 'Authorization: '
```
Use the same bearer token as in [How to enable the feature](#how-to-enable-the-feature).
---
# Examples
Here are a few examples of calculation properties use cases:
## Basic calculation property[](#basic-calculation-property "Direct link to Basic calculation property")
In the following example, we will create a calculation property called `MBMemory` of type `number`, and then transform it into a GB unit:
```
"properties":{
"MBMemory":{
"type": "number"
},
},
"calculationProperties" : {
"GBMemory": {
"title": "GB Memory",
"type": "number",
"calculation": ".properties.MBMemory / 1024"
}
}
```
In this instance, if you have a `MBMemory` **string** property with the value:
```
{
"MBMemory": 2048
}
```
Then the `GBMemory` calculation property value will be:
```
{
"GBMemory": 2
}
```
This is an example of how calculation properties can be used to perform math equations over data ingested into Port.
## Concatenate strings[](#concatenate-strings "Direct link to Concatenate strings")
Assume you have two `string` properties: one is called `str1` with the value `hello`, the other is called `str2` with the value `world`. The following calculation will result in `hello world`:
```
{
"title": "Concatenate strings example",
"type": "string",
"calculation": ".properties.str1 + .properties.str2"
}
```
Use single quotes for templates
If you want to provide your own string template to concatenate properties , wrap your template string with single quotes (`'`), such as `'https://' + .properties.str1'`
## Calculate array length[](#calculate-array-length "Direct link to Calculate array length")
Assume you have an `array` property called `myArr` with the value `["this", "is", "port"]`.
The following calculation will result in `3`:
```
{
"title": "Calculate array length",
"type": "number",
"calculation": ".properties.myArr | length"
}
```
## Slice array[](#slice-array "Direct link to Slice array")
Assume you have an `array` property called `array1` with the value `[1,2,3,4]`. You can use the following slicing calculation to get the result `[2,3,4]`:
```
{
"title": "Slice array example",
"type": "string",
"calculation": ".properties.array1[1:4]"
}
```
## Merge objects[](#merge-objects "Direct link to Merge objects")
Assume you have two `object` properties: one called `deployed_config` with the value `{cpu: 200}`, the other called `service_config` with the value `{memory: 400}`. You can merge these two object properties and receive a unified config by using the following calculation:
```
"calculationProperties" : {
"merge_config": {
"title": "Merge config",
"type": "object",
"calculation": ".properties.deployed_config * .properties.service_config",
}
}
```
The result will be `{cpu: 200, memory: 400}`.
Object merging
* Object merging performs a deep merge, resulting in nested keys from the original objects appearing in the resulting merged object.
* If the same `key` appears in one or more of the merged properties, the last property that appears will have its `keys` take precedence over the `keys` of properties that appeared earlier in the calculation.
For example, Let's assume we have 2 properties with type `object`, and we want to perform a deep merge between them:
```
{
"obj1": {
"cpu": 200
},
"obj2": {
"cpu": 400
}
}
```
If the calculation is `".properties.obj1 * .properties.obj2"` , the result will be `{cpu: 400}`,
If the calculation is `".properties.obj2 * .properties.obj1"` , the result will be `{cpu: 200}`,
For merging YAML properties, the merging behavior will be the same, but if you specify `type: "string` and `format: "yaml"`, the result will be a YAML object.
## If-else conditions[](#if-else-conditions "Direct link to If-else conditions")
Assume that your services use multiple packages, some written in Python and some written in Node.js.
By using an if-else JQ rule, you can specify a different URL for each package, based on its language:
```
"calculationProperties" : {
"package_manager_url": {
"title": "Package Link",
"type": "string",
"format": "url",
"calculation": "if .properties.language == \"Python\" then \"https://pypi.org/project/\" + .identifier else \"https://www.npmjs.com/package/\" + .identifier end",
}
}
```
For the following entity:
```
{
"identifier": "requests",
"properties": {
"language": "Python"
}
}
```
The result will be `package_manager_url: "https://pypi.org/project/requests"`.
For the following entity:
```
{
"identifier": "axios",
"properties": {
"language": "Nodejs"
}
}
```
The result will be `package_manager_url: "https://www.npmjs.com/package/axios"`.
## Calculate K8S labels[](#calculate-k8s-labels "Direct link to Calculate K8S labels")
You can create a calculation property inside your Blueprint to display a specific tag. Looking at the Node Blueprint, you can find the following property:
```
"properties": {
...
"labels": {
"type": "object",
"title": "Labels",
"description": "Labels of the Node"
},
```
And the labels object looks like:
```
{
"kubernetes.io/metadata.name": "port-k8s-exporter",
"name": "port-k8s-exporter"
}
```
To display the value of `name`, create a new calculation property within the same Blueprint. then use the following JQ calculation:
```
.properties.labels."name"
```
The result will be a property that displays `port-k8s-exporter`.
## Calculate Cloud resource tags[](#calculate-cloud-resource-tags "Direct link to Calculate Cloud resource tags")
Assuming you have a property `tags` in your Blueprint, you can use JQ to display the value of a tag.
In Port's AWS exporter, you can find the following array:
```
"tags": [
{
"Value": "authentication-service",
"Key": "server-application"
},
{
"Value": "1a23-4bc5d-67efg-89k10",
"Key": "applyId"
},
{
"Value": "0.0.11",
"Key": "server-version"
}
]
```
To display a Value of `applyId`, create a new calculation property within the Blueprint of the entity, and use the following JQ calculation:
```
.properties.tags.[] | select(.Key=="applyId") | .Value
```
The result will be a property that will display `1a23-4bc5d-67efg-89k10`.
---
# Datetime
Datetime is a data type used to reference a date and time.
## Common usage[](#common-usage "Direct link to Common usage")
Use date & time properties to record timestamps from your tools, such as:
* The latest successful deployment.
* The start and resolution times of an incident.
* A certificate expiration date.
* The latest security scan.
Port already tracks entity creation and update times in [meta-properties](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md). Use a [timer](/context-lake/data-model/setup-blueprint/properties/timer/.md) when a deadline should emit a timer-expired event.
## Display format[](#display-format "Direct link to Display format")
By default, Port displays datetime values relative to the current time (e.g., "3 months ago"). Use the optional `date_format` field to override this - for example, to show exact timestamps for audit logs, or to match your team's locale conventions. The following formats are supported:
* `relative` - Relative to the current time, e.g., "3 months ago" (default).
* `12-hour` - 12-hour clock, US convention, e.g., "Nov 26, 2025, 8:50 PM".
* `24-hour` - 24-hour clock, international convention, e.g., "26 Nov 2025 20:50".
* `YYYY-MM-DD HH:mm` - Fixed ISO-like format, e.g., "2025-11-26 20:50".
## API definition[](#api-definition "Direct link to API definition")
Use the `date_format` field to control how the value is displayed in the UI. See [display format](#display-format) for supported values.
* Basic
* Array
```
{
"myDatetimeProp": {
"title": "My datetime",
"icon": "My icon",
"description": "My datetime property",
"type": "string",
"format": "date-time",
"date_format": "12-hour",
"default": "2022-04-18T11:44:15.345Z"
}
}
```
```
{
"myDatetimeArray": {
"title": "My datetime array",
"icon": "My icon",
"description": "My datetime array",
"type": "array",
"items": {
"type": "string",
"format": "date-time",
"date_format": "12-hour"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
Use the `date_format` field to control how the value is displayed in the UI. See [display format](#display-format) for supported values.
* Basic
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myDatetimeProp" = {
title = "My datetime"
icon = "My icon"
description = "My datetime property"
format = "date-time"
date_format = "12-hour"
default = "2022-04-18T11:44:15.345Z"
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myDatetimeArray" = {
title = "My datetime array"
icon = "My icon"
required = false
string_items = {
format = "date-time"
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
Use `dateFormat` in TypeScript and JavaScript, `date_format` in Python, and `DateFormat` in Go. Version 2.29.0 exposes this setting for scalar string properties; array items support `format: "date-time"` without a display-format setting in these providers.
Use the `date_format` field to control how the value is displayed in the UI. See [display format](#display-format) for supported values.
* Basic
* Enum
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myDatetimeProp": BlueprintPropertiesStringPropsArgs(
title="My datetime",
format="date-time",
date_format="12-hour",
required=True,
)
}
),
relations={},
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myDatetimeProp: {
title: "My datetime",
format: "date-time",
dateFormat: "12-hour",
required: true,
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myDatetimeProp: {
title: "My datetime",
format: "date-time",
dateFormat: "12-hour",
required: true,
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myDatetimeProp": &port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My datetime"),
Format: pulumi.String("date-time"),
DateFormat: pulumi.String("12-hour"),
Required: pulumi.Bool(false),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesStringPropsArgs,BlueprintPropertiesArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myDatetimeProp": BlueprintPropertiesStringPropsArgs(
title="My datetime",
required=True,
format="date-time",
date_format="12-hour",
enums=["2022-04-18T11:44:15.345Z", "2022-05-18T11:44:15.345Z"],
enum_colors={
"2022-04-18T11:44:15.345Z": "red",
"2022-05-18T11:44:15.345Z": "green"
},
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myDatetimeProp: {
title: "My datetime",
format: "date-time",
dateFormat: "12-hour",
required: true,
enums: ["2022-04-18T11:44:15.345Z", "2022-05-18T11:44:15.345Z"],
enumColors: {
"2022-04-18T11:44:15.345Z": "red",
"2022-05-18T11:44:15.345Z": "green",
},
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myDatetimeProp: {
title: "My datetime",
format: "date-time",
dateFormat: "12-hour",
required: true,
enums: ["2022-04-18T11:44:15.345Z", "2022-05-18T11:44:15.345Z"],
enumColors: {
"2022-04-18T11:44:15.345Z": "red",
"2022-05-18T11:44:15.345Z": "green",
},
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myDatetimeProp": &port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My datetime"),
Format: pulumi.String("date-time"),
DateFormat: pulumi.String("12-hour"),
Required: pulumi.Bool(false),
Enums: pulumi.StringArray{
pulumi.String("2022-04-18T11:44:15.345Z"),
pulumi.String("2022-05-18T11:44:15.345Z"),
},
EnumColors: pulumi.StringMap{
"2022-04-18T11:44:15.345Z": pulumi.String("red"),
"2022-05-18T11:44:15.345Z": pulumi.String("green"),
},
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
---
# Email
Email is a data type used to save Email addresses.
## Common usage[](#common-usage "Direct link to Common usage")
Use email properties to store contact addresses, such as:
* Team support mailboxes.
* Security contact addresses.
* External vendor contacts.
Use the [Port User property](/context-lake/data-model/setup-blueprint/properties/user/.md) when you want to display a person's name and avatar. You can store internationalized email addresses with `"format": "idn-email"`.
## API definition[](#api-definition "Direct link to API definition")
* Basic
* Enum
* Array
* Basic (international address)
```
{
"myEmailProp": {
"title": "My email",
"icon": "My icon",
"description": "My email property",
"type": "string",
"format": "email",
"default": "me@example.com"
}
}
```
```
{
"myEmailEnum": {
"title": "My email enum",
"icon": "My icon",
"description": "My email enum",
"type": "string",
"format": "email",
"enum": ["me@example.com", "example@example.com"],
"enumColors": {
"me@example.com": "red",
"example@example.com": "green"
}
}
}
```
```
{
"myEmailArray": {
"title": "My email array",
"icon": "My icon",
"description": "My email array",
"type": "array",
"items": {
"type": "string",
"format": "email"
}
}
}
```
```
{
"myInternationalEmailProp": {
"title": "My international email",
"icon": "My icon",
"description": "My international email property",
"type": "string",
"format": "idn-email",
"default": "a-mí@उदाहरण.com"
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Enum
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myEmailProp" = {
title = "My email"
icon = "My icon"
description = "My email property"
format = "email"
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
myEmailProp = {
title = "My email"
required = false
format = "email"
enum = ["me@example.com", "example@example.com"]
enum_colors = {
"me@example.com" = "red",
"example@example.com" = "green"
}
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
myEmailArray = {
title = "My email array"
string_items = {
format = "email"
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
* Enum
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myEmailProp": BlueprintPropertiesStringPropsArgs(
title="My email",
format="email",
)
}
),
relations={},
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myEmailProp: {
title: "My email",
format: "email",
required: true,
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myEmailProp: {
title: "My email",
format: "email",
required: true,
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myEmailProp": &port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My email"),
Format: pulumi.String("email"),
Required: pulumi.Bool(true),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myEmailProp": BlueprintPropertiesStringPropsArgs(
title="My email",
required=True,
format="email",
enums=["me@example.com", "other@example.com"],
enum_colors={
"me@example.com": "red",
"other@example.com": "green",
},
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myEmailProp: {
title: "My email",
required: true,
format: "email",
enums: ["me@example.com", "other@example.com"],
enumColors: {
"me@example.com": "red",
"other@example.com": "green",
},
}
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myEmailProp: {
title: "My email",
required: true,
format: "email",
enums: ["me@example.com", "other@example.com"],
enumColors: {
"me@example.com": "red",
"other@example.com": "green",
},
}
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myEmailProp": &port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My email"),
Required: pulumi.Bool(false),
Format: pulumi.String("email"),
Enums: pulumi.StringArray{
pulumi.String("me@example.com"),
pulumi.String("other@example.com"),
},
EnumColors: pulumi.StringMap{
"me@example.com": pulumi.String("red"),
"other@example.com": pulumi.String("green"),
},
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
---
# Embedded URL
The `embedded URL` property is used to embed and display a webpage within an [entity]() in Port.
Using this property will automatically create an additional tab in each [entity page](/interface-builder/port-interface/page/entity-page/.md), displaying the embedded content.
In the following example, we see the `Shipping` entity page, which is an instance on the `Domain` blueprint.
The blueprint has an `embedded URL` property named `Architecture`, which is automatically displayed in a dedicated tab:
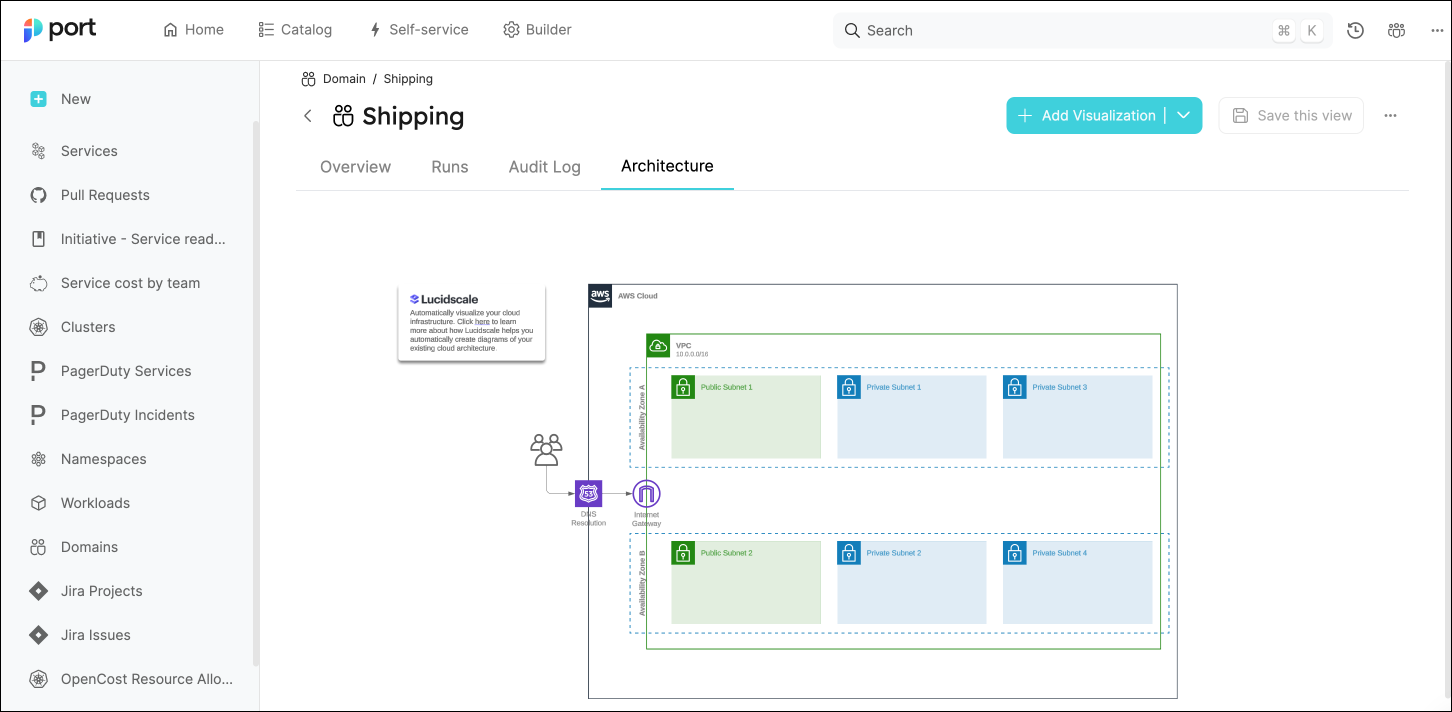
## URL type[](#url-type "Direct link to URL type")
Port supports the following URL types:
* **Public link** - A link to a public webpage, which does not require authentication.
* **Private link** - A link to a webpage that is protected by SSO authentication. To use this type, you'll need to provide the required parameters, see the [authentication](/context-lake/data-model/setup-blueprint/properties/embedded-url/authentication/.md) section for more information and examples.
## Common usage[](#common-usage "Direct link to Common usage")
Use embedded URL properties to display external content on entity pages, such as:
* Monitoring dashboards for a service.
* Architecture diagrams.
* Charts from observability tools.
The source website must allow embedding. Configure [authentication](/context-lake/data-model/setup-blueprint/properties/embedded-url/authentication/.md) for supported pages that require sign-in.
## Schema definition[](#schema-definition "Direct link to Schema definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* API
* Terraform
```
{
"myEmbeddedUrl": {
"title": "My Embedded URL",
"type": "string",
"format": "url",
"spec": "embedded-url",
"description": "embedded-url Prop",
// specAuthentication is needed only when using a protected/private URL
"specAuthentication": {
"authorizationUrl": "https://app.com",
"tokenUrl": "https://app.com",
"clientId": "1234",
"authorizationScope": [
"api://xxxx-xxxx-xxxx-xxxx-xxxx/user.read"
]
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
myEmbeddedUrl = {
title = "My Embedded URL"
required = false
format = "url"
spec = "embedded-url"
}
}
}
}
```
## Examples[](#examples "Direct link to Examples")
### Datadog dashboard[](#datadog-dashboard "Direct link to Datadog dashboard")
In this example we are embedding a [Datadog](https://docs.datadoghq.com/dashboards/sharing/) dashboard in order to get application metrics directly inside Port.
Add the `embedded-URL` property to a Blueprint:
**Blueprint property definition (click to expand)**
```
{
"datadog": {
"title": "Datadog",
"type": "string",
"format": "url",
"spec": "embedded-url"
}
}
```
Create or edit an Entity of the Blueprint you added the `Datadog` property to, and specify the URL to the Datadog dashboard:

Now go to the specific entity page of your Entity and the Datadog dashboard will be visible in a dedicated tab:
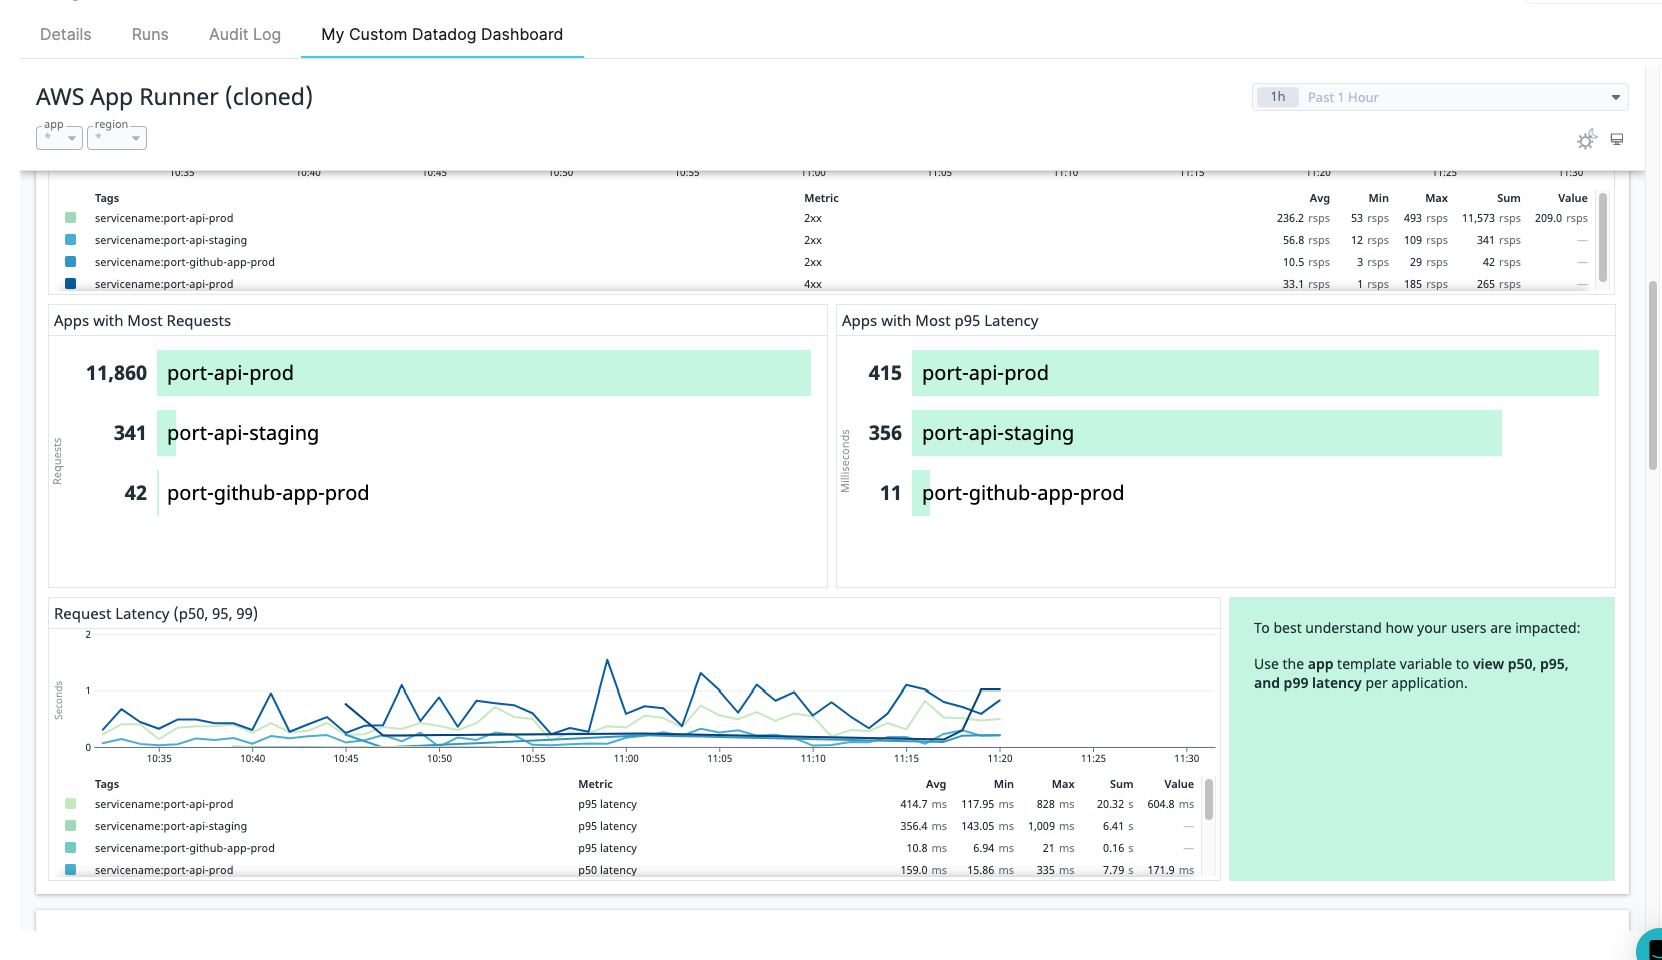
### New Relic chart[](#new-relic-chart "Direct link to New Relic chart")
In this example we are embedding a CPU usage [New Relic Chart](https://one.eu.newrelic.com/) to get infrastructure metrics directly inside Port.
Add the `embedded-URL` property to a Blueprint:
**Blueprint property definition (click to expand)**
```
{
"cpuUsage": {
"type": "string",
"title": "CPU usage",
"spec": "embedded-url",
"format": "url"
}
}
```
Go to new relic and extract the chart URL of a specific chart
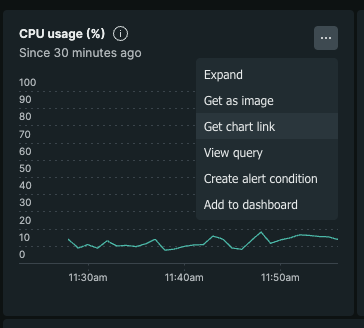
Create or edit an Entity of the Blueprint you added the `cpuUsage` property to, and specify the URL to the CPU Usage chart:
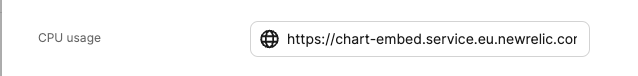
Now go to the specific entity page of your Entity and the CPU Usage chart will be visible in a dedicated tab:
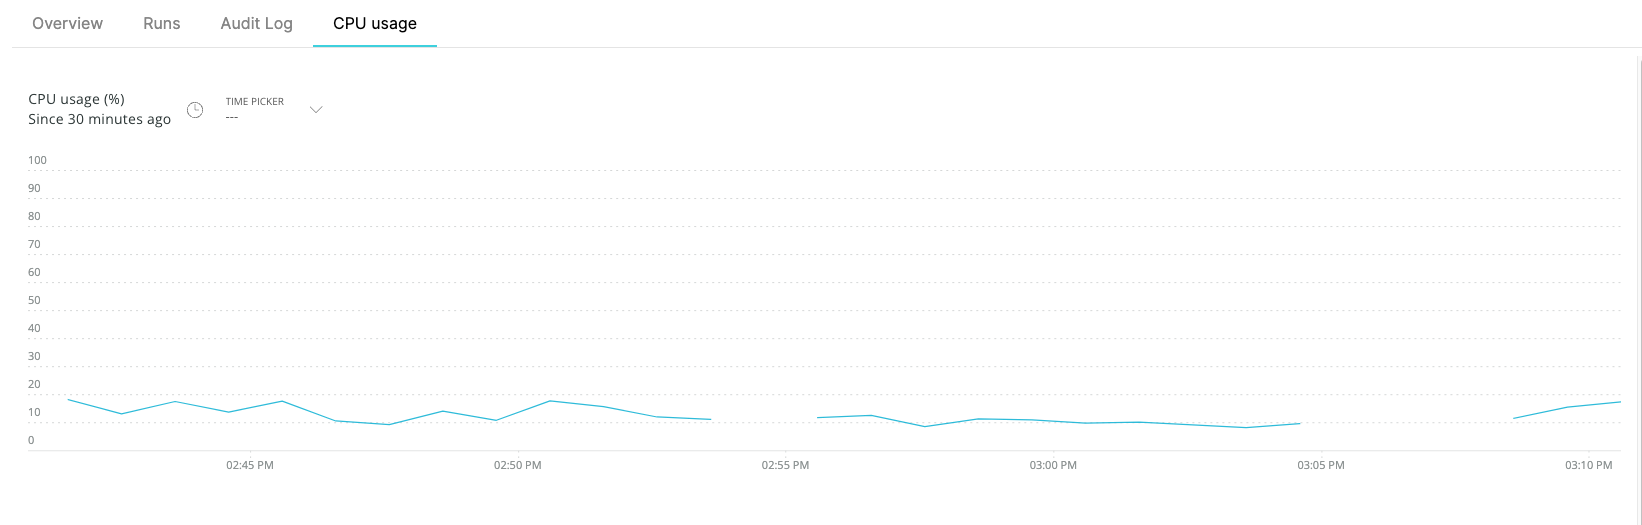
---
# Authentication
With this feature, you can embed another website that's protected by SSO authentication. To do this, you'll need the required parameters to create a JWT token.
## Authentication code flow + PKCE[](#authentication-code-flow--pkce "Direct link to Authentication code flow + PKCE")
The following diagram outlines the login scheme used to authenticate with your SSO and gain access to the private resource:
Here is an explanation of the login flow:
1. The widget will generate a PKCE `code_verifier` & `code_challenge`.
2. The widget URL is set to the `authorizationUrl` along with the `clientId` and the generated `code_challenge`.
3. The widget will then be redirected to the SSO sign-in page.
4. The user will sign in using the SSO (If the user is already signed in to the SSO, this step will happen automatically).
5. The SSO sign-in page will redirect the widget back to with the authorization `code` as a URL hash parameter.
6. The widget will send the `code`, `clientId` and the `code_verifier` to the `tokenURL`.
7. The SSO will validate the PKCE code.
8. A response will come back with an access token.
9. The widget will pass the access token as a query parameter `auth_token={accessToken}` to the URL specified in the property value.
10. Your page should be displayed now!
## Required parameters[](#required-parameters "Direct link to Required parameters")
To set up the authentication, you'll need the following parameters:
* `clientId`
* `authorizationUrl`
* `tokenUrl`
Here's an example of how to apply these parameters in your Blueprint:
```
{
"title": "Grafana",
"type": "string",
"format": "url",
"spec": "embedded-url",
"specAuthentication": {
"clientId": "your-client-id",
"authorizationUrl": "your-authorization-url",
"tokenUrl": "your-token-url"
}
}
```
## Examples[](#examples "Direct link to Examples")
### Okta[](#okta "Direct link to Okta")
**Setup (click to expand)**
**Steps:**
1. Follow the steps in [Okta's documentation](https://developer.okta.com/docs/guides/implement-grant-type/authcodepkce/main/) to create an Application in your Okta Organization.
2. Make sure the Port host is in the `Redirect Uris`:
1. Go to Applications -> The application you just created -> Login.
2. Add `https://app.port.io` as a Sign-in redirect URI.
3. Enable IFrame for Sign-In Page:
1. Go to Customizations -> Other.
2. Scroll to "IFrame Embedding" and enable it.
**Configure Grafana with OAuth & Port embedding**
Example values are for illustration only
The following example is just for illustration purposes and may not reflect the actual URLs and client IDs used in your Okta setup.
Based on Grafana docs for [JWT Configuration](https://grafana.com/docs/grafana/latest/setup-grafana/configure-security/configure-authentication/jwt/) & [OAuth Configuration](https://grafana.com/docs/grafana/latest/setup-grafana/configure-security/configure-authentication/generic-oauth/)
```
[security] ;Required for the embedding
allow_embedding = true
[auth.jwt] ;Required for the embedding
...
jwk_set_url = https://{your-okta-org}.okta.com/oauth2/default/v1/keys
expect_claims = {"iss": "https://{your-okta-org}.okta.com", "aud": "https://{your-okta-org}.okta.com"}
url_login = true
...
[auth.generic_oauth] ;Regular OAuth authentication
...
client_id = {CLIENT_ID}
client_secret = {CLIENT_SECRET}
auth_url = https://{your-okta-org}.okta.com/oauth2/v1/authorize
token_url = https://{your-okta-org}.okta.com/oauth2/v1/token
api_url = https://{your-okta-org}.okta.com/oauth2/v1/userinfo
enable_login_token = true
use_pkce = true
...
```
**Troubleshooting**
* "*Okta 400 Bad Request*"
* Check that you used the correct authorizationUrl & clientId.
* Check that your application is activated.
* "*Okta 400 Bad Request displayed. Your request resulted in an error. The 'redirect\_uri' parameter must be a Login redirect URI in the client app settings*".
* Make sure you entered as a Sign-in redirect URI for your application as mentioned in the steps above.
* "*refused to connect.*"
* Make sure you enabled "IFrame Embedding" as mentioned in the steps above.
* "*Could not fetch your auth token.*"
* Make sure your tokenUrl is the correct url.
### Onelogin[](#onelogin "Direct link to Onelogin")
**Setup (click to expand)**
**Steps:**
1. Follow steps 1 & 2 in [Onelogin's documentation](https://onelogin.service-now.com/support?id=kb_article\&sys_id=143e6c13dbfd0450ca1c400e0b9619d6#add) to add an OpenId Connect (OIDC) application in your Onelogin organization.
2. Make sure the Port host is in the `Redirect URIs`:
1. Go to Applications -> The application you just added -> Configuration.
2. Add `https://app.port.io` as a Redirect URI.
**Configure Grafana with OAuth & Port embedding**
Example values are for illustration only
The following example is just for illustration purposes and may not reflect the actual URLs and client IDs used in your Onelogin setup.
Based on Grafana docs for [JWT Configuration](https://grafana.com/docs/grafana/latest/setup-grafana/configure-security/configure-authentication/jwt/) & [OAuth Configuration](https://grafana.com/docs/grafana/latest/setup-grafana/configure-security/configure-authentication/generic-oauth/)
```
[security] ;Required for the embedding
allow_embedding = true
[auth.jwt] ;Required for the embedding
...
jwk_set_url = https://{your-onelogin-org}.onelogin.com/oidc/2/certs
expect_claims = {"iss": "https://{your-onelogin-org}/oidc/2"}
url_login = true
...
[auth.generic_oauth] ;Regular OAuth authentication
...
client_id = {CLIENT_ID}
client_secret = {CLIENT_SECRET}
auth_url = https://{your-onelogin-org}.onelogin.com/oidc/2/auth
token_url = https://{your-onelogin-org}.onelogin.com/oidc/2/token
api_url = https://{your-onelogin-org}.onelogin.com/oidc/2/me
enable_login_token = true
use_pkce = true
...
```
**Troubleshoot**
* "*unrecognized route or not allowed method*"
* Check that you used the correct authorizationUrl.
* "*client is invalid*"
* Check that you used the correct clientId.
* "*redirect\_uri did not match any client's registered redirect\_uris*".
* Make sure you entered as a Redirect URI for your application as mentioned in the steps above.
* "*Could not fetch your auth token.*"
* Make sure your tokenUrl is the correct URL.
### Azure AD[](#azure-ad "Direct link to Azure AD")
**Setup (click to expand)**
**Steps:**
1. Follow the [Register an application](https://learn.microsoft.com/en-us/azure/active-directory/develop/quickstart-register-app#register-an-application) steps in Azure Documentation to add an application in your Azure subscription.
2. Follow the [Add a redirect URI](https://learn.microsoft.com/en-us/azure/active-directory/develop/quickstart-register-app#add-a-redirect-uri) steps in Azure documentation to add `https://app.port.io` as a Redirect URI.
3. Follow the [Configure platform settings](https://learn.microsoft.com/en-us/azure/active-directory/develop/quickstart-register-app#configure-platform-settings) to configure your application as `Single-page application`.
4. Add a custom scope to your new application:
1. In your application click on the Expose an API button on the left sidebar.
2. Click on the `Add a scope` button to add a scope that will allow Admins and users to consent `Read User`. 
3. Add the scope you just created under the `Authorization Scope` field in the property in your blueprint inside Port.
```
...
"schema": {
"properties": {
"ff": {
"type": "string",
"title": "ff",
"format": "url",
"spec": "embedded-url",
"specAuthentication": {
"authorizationUrl": "https://app.com",
"tokenUrl": "https://app.com",
"clientId": "1234",
"authorizationScope": [
"api://xxxx-xxxx-xxxx-xxxx-xxxx/user.read"
]
}
}
}
}
...
```
**Configure Grafana with OAuth & Port embedding**
Example values are for illustration only
The following example is just for illustration purposes and may not reflect the actual URLs and client IDs used in your Azure AD setup.
Based on Grafana docs for [JWT Configuration](https://grafana.com/docs/grafana/latest/setup-grafana/configure-security/configure-authentication/jwt/) & [Azure AD Configuration](https://grafana.com/docs/grafana/latest/setup-grafana/configure-security/configure-authentication/azuread/)
```
[security] ;Required for the embedding
allow_embedding = true
[auth.jwt] ;Required for the embedding
...
email_claim = preferred_username
username_claim = preferred_username
jwk_set_url = "https://login.microsoftonline.com/common/discovery/v2.0/keys"
expect_claims = {"iss": "https://login.microsoftonline.com/{YOUR_APPLICATION_UUID}/v2.0"}
url_login = true
...
[auth.azuread] ;Regular Azure AD authentication
...
client_id = {CLIENT_ID}
client_secret = {CLIENT_SECRET}
auth_url = "https://login.microsoftonline.com/{YOUR_APPLICATION_UUID}/oauth2/v2.0/authorize"
token_url = "https://login.microsoftonline.com/{YOUR_APPLICATION_UUID}/oauth2/v2.0/token"
allowed_domains = "{my-domain}.com"
use_pkce = true
...
```
**Troubleshoot**
* "*Could not fetch your auth token.*"
* Make sure your tokenUrl is the correct URL.
---
# Enum
Enum is a data type used to define a named set of constant values.
## Common usage[](#common-usage "Direct link to Common usage")
Use enum properties when a value must come from a predefined set, such as:
* Service lifecycle: experimental, production, deprecated.
* Deployment status: pending, in progress, succeeded, failed.
* Environment: development, staging, production.
* Service criticality: low, medium, high, critical.
## API definition[](#api-definition "Direct link to API definition")
### Limit field[](#limit-field "Direct link to Limit field")
When creating a blueprint property of type Enum in the UI, use the **limit** field to define how many values users can select for that property.
In the property creation form, the limit field dropdown provides two options:
* **1 value**: Only one value can be selected.
* **List of values**: Multiple values can be selected.
Selecting the **list of values** option will set the property's `type` to `array` in the JSON definition.
Limit field restriction
The limit field setting, whether it's **1 value** or a **list of values**, is permanent and cannot be changed after the property is created. If you create a property with a single value limit, you won’t be able to change it later to allow multiple values.
To change the limit configuration after creation:
1. Create a new property with the **limit** field set to a **list of values**.
2. Use the [migrate blueprint data](/context-lake/ingestion/ingest-data-into-port/other/migrate-data/.md) feature to insert the data to the new property.
3. Delete the old property.
4. Rename the new property to the old property name (optional).
* Basic
* Array
```
{
"myStringEnum": {
"title": "My enum",
"icon": "My icon",
"type": "string",
"enum": ["my-option-1", "my-option-2"],
"enumColors": {
"my-option-1": "red",
"my-option-2": "green"
}
}
}
```
```
{
"myStringArray": {
"title": "My enum array",
"icon": "My icon",
"description": "My enum array",
"type": "array",
"items": {
"type": "string",
"enum": ["my-option-1", "my-option-2"],
"enumColors": {
"my-option-1": "red",
"my-option-2": "green"
}
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myEnumProp" = {
title = "My Enum"
required = false
enum = ["my-option-1", "my-option-2"]
enum_colors = {
"my-option-1" = "green"
"my-option-2" = "blue"
}
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
my_enum_array_prop = {
title = "myEnumArrayProp"
string_items = {
enum = ["my-option-1", "my-option-2", "my-option-3"]
enum_colors = {
"my-option-1" = "gold"
"my-option-2" = "bronze"
"my-option-3" = "lightGray"
}
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
* Array
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties={
"string_props": {
"myEnumProp": {
"title": "My Enum",
"required": True,
"enum_colors": {
"my-option-1": "red",
"my-option-2": "green",
},
"enums": ["my-option-1", "my-option-2"]
}
}
},
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myEnumProp: {
title: "My Enum",
required: true,
enums: ["my-option-1", "my-option-2"],
enumColors: {
"my-option-1": "red",
"my-option-2": "green",
},
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myEnumProp: {
title: "My Enum",
required: true,
enums: ["my-option-1", "my-option-2"],
enumColors: {
"my-option-1": "red",
"my-option-2": "green",
},
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myEnumProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My Enum"),
Required: pulumi.Bool(false),
Enums: pulumi.StringArray{
pulumi.String("my-option-1"),
pulumi.String("my-option-2"),
},
EnumColors: pulumi.StringMap{
"my-option-1": pulumi.String("red"),
"my-option-2": pulumi.String("green"),
},
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="myBlueprint",
properties={
"array_props": {
"myEnumProp": {
"title":"My Enum Array",
"required":True,
"string_items": {
"enums" : ["my-option-1", "my-option-2"],
"enum_colors" : {
"my-option-1": "red",
"my-option-2": "green",
}
}
}
}
},
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
arrayProps: {
myEnum: {
title: "My enum",
required: true,
stringItems: {
enumColors: {
"my-option-1": "red",
"my-option-2": "green",
},
enums: ["my-option-1", "my-option-2"],
},
}
}
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
arrayProps: {
myEnumProp: {
title: "My Enum",
required: true,
stringItems: {
enums: ["my-option-1", "my-option-2"],
enumColors: {
"my-option-1": "red",
"my-option-2": "green",
},
},
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("myBlueprint"),
Properties: &port.BlueprintPropertiesArgs{
ArrayProps: port.BlueprintPropertiesArrayPropsMap{
"myEnumProp": &port.BlueprintPropertiesArrayPropsArgs{
Title: pulumi.String("My Enum"),
Required: pulumi.Bool(false),
StringItems: &port.BlueprintPropertiesArrayPropsStringItemsArgs{
Enums: pulumi.StringArray{
pulumi.String("my-option-1"),
pulumi.String("my-option-2"),
},
EnumColors: pulumi.StringMap{
"my-option-1": pulumi.String("red"),
"my-option-2": pulumi.String("green"),
},
},
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## Available enum colors[](#available-enum-colors "Direct link to Available enum colors")
Properties defined using [enum](#api-definition) can also include specific colors for the different values available in the property definition, the available enum colors are:
```
blue
turquoise
orange
purple
pink
yellow
green
red
darkGray
lightGray
bronze
```
---
# Labeled URL
Labeled URL is an object type used to store URLs with custom display labels. This property allows you to associate a human-readable label with a URL, making it easier to display meaningful link text in the UI instead of showing icons only.
Creating via UI
When creating a [URL property](/context-lake/data-model/setup-blueprint/properties/url/.md) in the UI, enabling the **Custom display text** toggle creates a labeled URL property. Note that this toggle cannot be changed after the property is saved.
## Common usage[](#common-usage "Direct link to Common usage")
Use labeled URL properties when a link needs readable display text, such as:
* Runbook links labeled with incident types.
* Monitoring dashboards labeled with environment names.
* Pull requests labeled with their titles.
## Schema structure[](#schema-structure "Direct link to Schema structure")
A labeled URL object contains two fields:
| Field | Type | Required | Description |
| ------------- | ------ | -------- | ------------------------------------------ |
| `url` | string | Yes | The URL to link to (internal or external). |
| `displayText` | string | No | The display text to show for the link. |
### Example value[](#example-value "Direct link to Example value")
```
{
"url": "https://app.datadoghq.com/dashboard/abc123",
"displayText": "Production Metrics Dashboard"
}
```
## Display behavior[](#display-behavior "Direct link to Display behavior")
Labeled URLs are rendered intelligently based on the URL type:
* **Internal links**: Displayed as navigable links within Port.
* **External links**: Displayed as buttons that open in a new tab.
## API definition[](#api-definition "Direct link to API definition")
* Basic
* Array
```
{
"myLabeledUrlProp": {
"title": "My labeled URL",
"icon": "Link",
"description": "My labeled URL property",
"type": "object",
"format": "labeled-url"
}
}
```
```
{
"myLabeledUrlArray": {
"title": "My labeled URL array",
"icon": "Link",
"description": "My labeled URL array",
"type": "array",
"items": {
"type": "object",
"format": "labeled-url"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
object_props = {
"myLabeledUrlProp" = {
title = "My labeled URL"
description = "My labeled URL property"
format = "labeled-url"
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myLabeledUrlArray" = {
title = "My labeled URL array"
description = "My labeled URL array"
object_items = {
format = "labeled-url"
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
* Array
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesObjectPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
object_props={
"myLabeledUrlProp": BlueprintPropertiesObjectPropsArgs(
title="My labeled URL",
required=False,
format="labeled-url",
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
objectProps: {
myLabeledUrlProp: {
title: "My labeled URL",
required: false,
format: "labeled-url",
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
objectProps: {
myLabeledUrlProp: {
title: "My labeled URL",
required: false,
format: "labeled-url",
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
ObjectProps: port.BlueprintPropertiesObjectPropsMap{
"myLabeledUrlProp": port.BlueprintPropertiesObjectPropsArgs{
Title: pulumi.String("My labeled URL"),
Required: pulumi.Bool(false),
Format: pulumi.String("labeled-url"),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesArrayPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
array_props={
"myLabeledUrlArray": BlueprintPropertiesArrayPropsArgs(
title="My labeled URL array",
required=False,
object_items={
"format": "labeled-url"
}
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
arrayProps: {
myLabeledUrlArray: {
title: "My labeled URL array",
required: false,
objectItems: {
format: "labeled-url",
},
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
arrayProps: {
myLabeledUrlArray: {
title: "My labeled URL array",
required: false,
objectItems: {
format: "labeled-url",
},
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
ArrayProps: port.BlueprintPropertiesArrayPropsMap{
"myLabeledUrlArray": port.BlueprintPropertiesArrayPropsArgs{
Title: pulumi.String("My labeled URL array"),
Required: pulumi.Bool(false),
ObjectItems: port.BlueprintPropertiesArrayPropsObjectItemsArgs{
Format: pulumi.String("labeled-url"),
},
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## Using labeled URLs in self-service actions[](#using-labeled-urls-in-self-service-actions "Direct link to Using labeled URLs in self-service actions")
You can use labeled URL properties as user inputs in self-service actions and automations. The input form provides a JSON editor with schema validation to ensure proper structure.
### Example action input[](#example-action-input "Direct link to Example action input")
```
{
"documentationLink": {
"title": "Documentation Link",
"description": "Link to the service documentation",
"type": "object",
"format": "labeled-url"
}
}
```
### Example entity data[](#example-entity-data "Direct link to Example entity data")
When populating an entity with labeled URL data:
```
{
"identifier": "my-service",
"title": "My Service",
"properties": {
"documentationLink": {
"url": "https://docs.example.com/my-service",
"label": "Service Documentation"
},
"relatedLinks": [
{
"url": "https://github.com/org/my-service",
"label": "GitHub Repository"
},
{
"url": "https://app.datadoghq.com/dashboard/xyz",
"label": "Monitoring Dashboard"
}
]
}
}
```
---
# Markdown
The `Markdown` property is used to display [Markdown](https://en.wikipedia.org/wiki/Markdown) content within an [entity]() in Port.
Using this property will automatically create an additional tab in each [entity page](/interface-builder/port-interface/page/entity-page/.md), displaying the formatted content.
## Common usage[](#common-usage "Direct link to Common usage")
Use Markdown properties to display documentation alongside your entities, such as:
* Repository README files.
* Service runbooks and troubleshooting instructions.
* Architecture notes and Mermaid diagrams.
## Schema definition[](#schema-definition "Direct link to Schema definition")
```
{
"title": "Markdown Property",
"type": "string",
"format": "markdown",
"description": "A Markdown property"
}
```
## Upload images[](#upload-images "Direct link to Upload images")
You can add images directly to your content while editing a **markdown property** in Port.
Use any of the following methods to upload an image:
* **Paste from clipboard**: copy an image and paste it into the editor with `Cmd+V` (macOS) or `Ctrl+V` (Windows/Linux).
* **Drag & drop**: drag an image file from your computer into the editor.
* **Toolbar**: click the **image** button in the editor toolbar to select a file to upload.
To insert an image hosted at an external URL, use `Ctrl+K` and provide the image URL.
**Limitations:**
* Maximum file size: **10MB** per image.
* Maximum **50** uploaded images per
markdown property
.
* Supported formats are PNG, JPEG, GIF, WebP, APNG, and AVIF.
## Limitations[](#limitations "Direct link to Limitations")
### Relative links are not supported[](#relative-links-are-not-supported "Direct link to Relative links are not supported")
When displaying markdown content in Port (especially content ingested from Git repositories or other external sources), **relative links will not work**. This is because the markdown is rendered in the context of your Port portal, not the original source location.
For example, links like `[guide](./docs/guide.md)` or `[readme](../README.md)` from a GitHub README file will not function correctly when displayed in Port.
**Solutions:**
* Use **absolute URLs** instead: `[guide](https://github.com/your-org/your-repo/blob/main/docs/guide.md)`.
* Transform relative links to absolute URLs during ingestion using JQ expressions in your integration mapping.
* For links to other entities in your Port catalog, use entity page URLs: `/serviceEntity?identifier=my-service`.
### GitOps and external markdown files[](#gitops-and-external-markdown-files "Direct link to GitOps and external markdown files")
When using GitOps to display an external markdown file using the `markdown` property, changes made to the markdown file will not be reflected in Port until the `port.yml` file is also updated (this triggers a re-ingestion of the entity).
One way to handle this is to add a step in your CI workflow that bumps a "version" field in the `port.yml` file whenever specific files in the repository are updated, ensuring re-ingestion of the entity.
***
## Mermaid[](#mermaid "Direct link to Mermaid")
The markdown widget also supports [Mermaid](https://mermaid-js.github.io/mermaid/#/), a diagramming and charting tool that uses text and code to generate diagrams and charts.
To use Mermaid with the markdown widget, all you need to do is add mermaid syntax to the markdown property. You can refer to the [Mermaid Examples](https://mermaid.js.org/syntax/examples.html) for more examples and information on how to use it.
**Mermaid diagram example (click to expand)**
````
```mermaid
sequenceDiagram
participant ClientService
participant PaymentService
participant InventoryService
participant ShippingService
ClientService->>PaymentService: Request Payment
PaymentService-->>InventoryService: Update Inventory
InventoryService-->>ShippingService: Ship Order
ShippingService-->>InventoryService: Confirm Shipment
InventoryService-->>PaymentService: Update Payment Status
PaymentService-->>ClientService: Return Payment Status
```
````
---
# Meta-Properties
A meta-property is a property that exists on every entity in Port by default.
Meta-properties are always referenced using a dollar sign (`$`) before them, this makes it easier to tell if a property is user-defined or a meta-property.
The following table lists all of the available meta-properties:
| Meta-property | Description | Notes |
| ------------- | ------------------------------------------------------------------------------------------------------------------- | -------------------------------------------- |
| `$identifier` | **Unique** Entity identifier, used for API calls, programmatic access and distinguishing between different entities | |
| `$title` | A human-readable name for the entity | |
| `$team` | The team this entity belongs to | |
| `$icon` | The entity's icon | |
| `$createdAt` | The entity's creation time | Value is set upon creation and never changes |
| `$updatedAt` | The entity's last update time | Value is updated automatically |
| `$createdBy` | The user who created the entity | Value is set upon creation and never changes |
| `$updatedBy` | The user who last updated the entity | Value is updated automatically |
| `$blueprint` | The entity's blueprint | |
---
# Mirror property
Mirror property allows you to map data from related entities to your entity. Mirror property can be used for blueprints that have [relations defined](/context-lake/data-model/setup-blueprint/relate-blueprints/.md).
When two blueprints are connected via a relation, a new set of properties becomes available to entities in the `source` blueprint.
Those new properties are called `mirrorProperties`.
Mirror properties will appear on the `source` blueprint as an additional key called `mirrorProperties`. It represents additional properties queried from the `target` blueprint (or from other entities further down the connection graph).
Mirror properties allow you to map property values from related entities, to `keys` in the `source` blueprint, thus giving you more context and data when viewing an Entity, while not cluttering the output with unnecessary fields.
Mirror properties support both [user-defined](/context-lake/data-model/setup-blueprint/properties/overview/.md#supported-properties) properties, and [meta-properties](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md) by using similar syntax.
## Common usage[](#common-usage "Direct link to Common usage")
Use mirror properties to display values from related catalog entities, such as:
* A service's owning team name.
* A workload's environment type.
* A deployment's repository URL.
## API definition[](#api-definition "Direct link to API definition")
The `mirrorProperties` key is a top-level key in a blueprint definition, alongside `identifier`, `title`, and `schema`.
* Basic
```
{
"mirrorProperties": {
"myMirrorProp": {
"title": "My mirror property",
"path": "myRelation.myProperty"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
Chained relations via path key
The `path` key receives a path of chained relations, which lead up to a blueprint property or [meta-property](#meta-property-as-a-mirror-property)
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
```
resource "port_blueprint" "related" {
identifier = "relatedBlueprint"
title = "Related blueprint"
properties = {
string_props = {
myProperty = { title = "Source property" }
}
}
}
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
relations = {
myRelation = { target = port_blueprint.related.identifier }
}
mirror_properties = {
myMirrorProp = {
title = "My mirror property"
path = "myRelation.myProperty"
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintMirrorPropertiesArgs
related_blueprint = Blueprint(
"relatedBlueprint",
identifier="relatedBlueprint",
title="Related blueprint",
properties={"string_props": {"myProperty": {"title": "Source property"}}},
)
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
relations={"myRelation": {"target": related_blueprint.identifier}},
mirror_properties={
"myMirrorProp": BlueprintMirrorPropertiesArgs(
title="My mirror property", path="myRelation.myProperty"
)
},
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
const relatedBlueprint = new port.Blueprint("relatedBlueprint", {
identifier: "relatedBlueprint",
title: "Related blueprint",
properties: { stringProps: { myProperty: { title: "Source property" } } },
});
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
relations: { myRelation: { target: relatedBlueprint.identifier } },
mirrorProperties: {
myMirrorProp: {
title: "My mirror property",
path: "myRelation.myProperty",
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const relatedBlueprint = new port.Blueprint("relatedBlueprint", {
identifier: "relatedBlueprint",
title: "Related blueprint",
properties: { stringProps: { myProperty: { title: "Source property" } } },
});
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
relations: { myRelation: { target: relatedBlueprint.identifier } },
mirrorProperties: {
myMirrorProp: {
title: "My mirror property",
path: "myRelation.myProperty",
},
},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
relatedBlueprint, err := port.NewBlueprint(ctx, "relatedBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("relatedBlueprint"),
Title: pulumi.String("Related blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myProperty": port.BlueprintPropertiesStringPropsArgs{Title: pulumi.String("Source property")},
},
},
})
if err != nil {
return err
}
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Relations: port.BlueprintRelationsMap{
"myRelation": port.BlueprintRelationsArgs{Target: relatedBlueprint.Identifier},
},
MirrorProperties: port.BlueprintMirrorPropertiesMap{
"myMirrorProp": port.BlueprintMirrorPropertiesArgs{
Title: pulumi.String("My mirror property"),
Path: pulumi.String("myRelation.myProperty"),
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## `Meta-property` as a mirror property[](#meta-property-as-a-mirror-property "Direct link to meta-property-as-a-mirror-property")
This is a mirror property created from one of Port's [meta-properties](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md) on the `target` blueprint.
In the following example, we create a mirror property called `microserviceName` which is mapped to the `title` meta-property in the `target` blueprint (in this example the name of the relation is `deployment-to-microservice`). Note how the `title` field is referenced using `$title` because it is a meta-property:
```
"microserviceName": {
"title": "Microservice Name",
"path": "deployment-to-microservice.$title"
}
```
## Nested relation as a mirror property[](#nested-relation-as-a-mirror-property "Direct link to Nested relation as a mirror property")
It is possible to use mirror properties to map properties from blueprints that are not direct descendants of our `source` blueprint.
For example, let's assume we have the following Relation chain: `Microservice -> System -> Domain`.
We want to map the members of the domain that owns the microservice directly to the `Microservice` entities.
The members of the domain are listed in an [array property](/context-lake/data-model/setup-blueprint/properties/array/.md) under the user-defined property `domain_members`.
The names of the relations are:
* `Microservice -> System`: `system`
* `System -> Domain`: `domain`
Let's map the squad members using a mirror property called `owningDomainMembers`:
```
"owningDomainMembers": {
"title": "Owning Domain Members",
"path": "system.domain.domain_members"
}
```
---
# Number
Number is a primitive data type used to save numeric data.
## Common usage[](#common-usage "Direct link to Common usage")
Use number properties to store measurements and counts ingested from your tools, such as:
* Open vulnerability counts.
* CPU and memory allocations.
* Deployment replica counts.
* Monthly cloud costs.
## API definition[](#api-definition "Direct link to API definition")
* Basic
* Enum
* Array
* Enum Array
```
{
"myNumberProp": {
"title": "My number",
"icon": "My icon",
"description": "My number property",
"type": "number",
"default": 7
}
}
```
```
{
"myNumberEnum": {
"title": "My number enum",
"icon": "My icon",
"description": "My number enum",
"type": "number",
"enum": [1, 2, 3, 4]
}
}
```
```
{
"myNumberArray": {
"title": "My number array",
"icon": "My icon",
"description": "My number array",
"type": "array",
"items": {
"type": "number"
}
}
}
```
```
{
"myNumberArray": {
"title": "My number enum array",
"icon": "My icon",
"description": "My number enum array",
"type": "array",
"items": {
"type": "number",
"enum": [1, 2, 3, 4],
"enumColors": {
"1": "red",
"2": "green",
"3": "blue"
}
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Enum
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
number_props = {
"myNumberProp" = {
title = "My number"
description = "My number property"
default = 7
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
number_props = {
"myNumberProp" = {
title = "My number"
description = "My number property"
enum = [1, 2, 3, 4]
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myNumberArray" = {
title = "My number array"
description = "My number array"
number_items = {}
}
"myNumberArrayWithDefault" = {
title = "My number array with default"
description = "My number array"
number_items = {
default = [1, 2, 3, 4]
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesNumberPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
number_props={
"myNumberProp": BlueprintPropertiesNumberPropsArgs(
title="My number", required=False,
)
},
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
numberProps: {
myNumberProp: {
title: "My number",
required: false,
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
numberProps: {
myNumberProp: {
title: "My number",
required: false,
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
NumberProps: port.BlueprintPropertiesNumberPropsMap{
"myNumberProp": port.BlueprintPropertiesNumberPropsArgs{
Title: pulumi.String("My number"),
Required: pulumi.Bool(false),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## Validate number[](#validate-number "Direct link to Validate number")
Number validations support the following operators:
* `range`
Ranges of numbers are specified using a combination of the `minimum` and `maximum` keywords, (or `exclusiveMinimum` and `exclusiveMaximum` for expressing exclusive range).
If *x* is the value being validated, the following must hold true:
* *x* ≥ `minimum`
* *x* > `exclusiveMinimum`
* *x* ≤ `maximum`
* *x* < `exclusiveMaximum`
- Basic
- Array
- Terraform
```
{
"myNumberProp": {
"title": "My number",
"icon": "My icon",
"description": "My number property",
"type": "number",
"minimum": 0,
"maximum": 50
}
}
```
```
{
"myNumberArray": {
"title": "My number array",
"icon": "My icon",
"description": "My number array",
"type": "array",
"items": {
"type": "number",
"exclusiveMinimum": 0,
"exclusiveMaximum": 50
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
"number_props" = {
"myNumberProp" = {
title = "My number"
icon = "My icon"
description = "My number property"
minimum = 0
maximum = 50
}
}
}
}
```
---
# JSON
JSON is a data type used to save structured data as key-value pairs.
## Common usage[](#common-usage "Direct link to Common usage")
Use JSON properties to store structured data, such as:
* Cloud resource tags and Kubernetes labels.
* Service configuration values.
* Structured metadata from an integration.
## API definition[](#api-definition "Direct link to API definition")
JSON properties use `"type": "object"` without a `format` field. The following example defines the property in your blueprint; `icon`, `description`, and `default` are optional.
* Basic
* Array
```
{
"myObjectProp": {
"type": "object",
"title": "My object"
}
}
```
```
{
"myObjectArray": {
"title": "My object array",
"icon": "My icon",
"description": "My object array",
"type": "array",
"items": {
"type": "object"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
object_props = {
"myObjectProp" = {
title = "My object"
icon = "My icon"
description = "My object property"
default = jsonencode({ "myKey" = "myValue" })
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
myObjectArray = {
title = "My object array"
object_items = {}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesObjectPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
object_props={
"myObjectProp": BlueprintPropertiesObjectPropsArgs(
title="My object", required=False
)
}
),
relations={},
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
objectProps: {
myObjectProp: {
title: "My object",
required: true,
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
objectProps: {
myObjectProp: {
title: "My object",
required: true,
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
ObjectProps: port.BlueprintPropertiesObjectPropsMap{
"myObjectProp": port.BlueprintPropertiesObjectPropsArgs{
Title: pulumi.String("My object"),
Required: pulumi.Bool(false),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## Validate object[](#validate-object "Direct link to Validate object")
Object validations support the following operators:
* `properties` - which keys must appear and what their type should be.
* `additionalProperties` - are keys not defined in `properties` allowed and what their type should be.
* `patternProperties` - which regex pattern should properties follow
JSON schema validations
Object validations follow the JSON schema model, refer to the [JSON schema docs](https://json-schema.org/understanding-json-schema/reference/object.html) to learn about all of the available validations
* Basic
* Array
```
{
"myObjectProp": {
"title": "My object",
"icon": "My icon",
"description": "My object property",
"type": "object",
"properties": {
"myRequiredProp": { "type": "number" }
},
"patternProperties": {
"^S_": { "type": "string" },
"^I_": { "type": "number" }
},
"additionalProperties": true
}
}
```
```
{
"myObjectArray": {
"title": "My object array",
"icon": "My icon",
"description": "My object array",
"type": "array",
"items": {
"type": "object",
"properties": {
"myRequiredProp": { "type": "number" }
},
"patternProperties": {
"^S_": { "type": "string" },
"^I_": { "type": "number" }
},
"additionalProperties": true
}
}
}
```
---
# Properties
Properties are customizable data fields of [blueprints](/context-lake/data-model/setup-blueprint/overview/.md), used to save and display information from external data sources.
Default visibility in tables
New properties added to an existing blueprint are **hidden by default** in all table views across Port (catalog pages, entity pages, table and entity details widgets).
To display the property in a table, click on the  **Manage Properties** icon and toggle the property on.
## Configure properties in Port[](#configure-properties-in-port "Direct link to Configure properties in Port")
You can create, delete, or edit properties via the Data model page or directly from the software catalog.
### From the Data model page[](#from-the-data-model-page "Direct link to From the Data model page")
**To edit an existing property:**
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Expand the blueprint you want to edit by double-clicking on it.
3. Under the **Properties** tab, click on the property you want to edit.
4. Make your desired changes to the form, then click **Save**.
**To create a new property:**
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Expand the blueprint you want to edit by double-clicking on it.
3. Click on the **+ New property** button:

4. Fill in the form with the desired property details, including the [property type](/context-lake/data-model/setup-blueprint/properties/overview/.md#supported-properties), then click **Create**.
5. Newly added properties are hidden by default across all views.
### From the software catalog[](#from-the-software-catalog "Direct link to From the software catalog")
Each catalog page in your software catalog contains a table with all entities created from a certain blueprint. You can modify the properties of the blueprint directly from this table:
1. Go to the desired page of your [software catalog](https://app.port.io/organization/catalog).
2. In the top-right corner of the table are its filters, click on the **Manage properties** button:
3. A dropdown will appear showing all of the properties. To modify or delete a property, hover over it and click on the `...` icon:
**Note** that [meta-properties](/context-lake/data-model/setup-blueprint/properties/meta-properties/.md) are not editable, so you will not see a `...` icon next to them.
4. To create a new property in the blueprint, click on the **+ Property** button at the bottom of the dropdown.
Hiding properties
You can also hide properties from the table by clicking on the toggle on the right side of the property name.
## Structure[](#structure "Direct link to Structure")
Each blueprint has a `properties` section under its `schema`. Each property is defined as an object with the following structure:
```
{
"myProp": {
"title": "My property",
"icon": "My icon",
"description": "My property",
"type": "property_type"
}
}
```
The different components that make up a basic property definition are listed in the following table:
| Field | Description |
| ------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `title` | Property title. |
| `identifier` | Property identifier. (Maximum 100 characters) |
| `type` | **Mandatory field.** The data type of the property. |
| `icon` | Icon for the property.
See the [full icon list](/context-lake/data-model/setup-blueprint/overview/.md#full-icon-list). |
| `description` | Description of the property.
This value is visible to users when hovering on the info icon in the UI. It provides detailed information about the use of a specific property. |
| `default` | Default value for this property in case an entity is created without explicitly providing a value. |
Property name
The name of the property is the key of the property object. For example, in the code block above, the name of the property is `myProp`.
## Change a property's type[](#change-a-propertys-type "Direct link to Change a property's type")
The **type** field setting of a property (**number**, **string**, etc.) is permanent and cannot be changed after the property is created. If you create a **number** property, you won't be able to change it later to a **string**.
To change the type configuration after creation:
1. Create a new property with the desired **type**.
2. Use the [migrate blueprint data](/context-lake/ingestion/ingest-data-into-port/other/migrate-data/.md) feature to insert the data to the new property. Ensure you apply the correct conversions if needed (for example, converting numbers to strings).
3. Delete the old property.
4. Rename the new property to the old property name (optional).
## Configure provider examples[](#configure-provider-examples "Direct link to Configure provider examples")
The property pages include resource examples for version **2.29.0** of the [Terraform provider](https://registry.terraform.io/providers/port-labs/port-labs/2.29.0/docs/resources/port_blueprint) and [Pulumi provider](https://www.pulumi.com/registry/packages/port/api-docs/blueprint/). Run each example independently, or adapt its properties into a blueprint you already manage.
### Configure Terraform[](#configure-terraform "Direct link to Configure Terraform")
Set your [Port credentials](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md#find-your-port-credentials) through environment variables:
```
export PORT_CLIENT_ID=""
export PORT_CLIENT_SECRET=""
```
Add this provider configuration to your Terraform project alongside the resource example. Use `https://api.us.port.io` for a US-region organization.
```
terraform {
required_providers {
port = {
source = "port-labs/port-labs"
version = "2.29.0"
}
}
}
provider "port" {
base_url = "https://api.port.io"
}
```
Run `terraform init`, then `terraform validate` and `terraform plan` to review the proposed changes before applying them.
### Configure Pulumi[](#configure-pulumi "Direct link to Configure Pulumi")
Create a Pulumi project for your chosen language and install the matching Port package:
* Python
* TypeScript / JavaScript
* Go
```
pip install port-pulumi==2.29.0
```
```
npm install @port-labs/port@2.29.0
```
```
go get github.com/port-labs/pulumi-port/sdk/v2@v2.29.0
```
Configure your stack with your Port credentials and region:
```
pulumi config set port:clientId ""
pulumi config set port:secret "" --secret
pulumi config set port:baseUrl "https://api.port.io"
```
Use `https://api.us.port.io` for a US-region organization. Add the resource example to your program and run `pulumi preview` to review the proposed changes.
## Supported properties[](#supported-properties "Direct link to Supported properties")
The sections below follow the property picker's order. The **Object** form offers JSON, YAML, and Protobuf. Labeled URL has its own documentation page; in the UI, create it by enabling **Custom display text** on a **URL** property. You can configure Email through JSON or a provider.
### Essential[](#essential "Direct link to Essential")
* [Owning teams](/context-lake/data-model/setup-blueprint/properties/owning-teams/.md) - adds a relation to the `Team` blueprint and sets the blueprint's ownership. Can be added once per blueprint.
* [String](/context-lake/data-model/setup-blueprint/properties/string/.md) - a primitive data type used to save text data.
* [Email](/context-lake/data-model/setup-blueprint/properties/email/.md) - a string format used to save email addresses.
* [Number](/context-lake/data-model/setup-blueprint/properties/number/.md) - a primitive data type used to save numeric data.
* [Boolean](/context-lake/data-model/setup-blueprint/properties/boolean/.md) - a primitive data type with one of two possible values, true and false.
* [Object](/context-lake/data-model/setup-blueprint/properties/object/.md) - groups the JSON, YAML, and Protobuf options in the property form.
* [JSON](/context-lake/data-model/setup-blueprint/properties/object/.md) - stores structured data using the API type `object`.
* [YAML](/context-lake/data-model/setup-blueprint/properties/yaml/.md) - a string format used to save object definitions in YAML.
* [Protobuf](/context-lake/data-model/setup-blueprint/properties/proto/.md) - a string format used to save proto definitions.
* [Labeled URL](/context-lake/data-model/setup-blueprint/properties/labeled-url-object/.md) - an object format used to store URLs with custom display labels.
* [Array](/context-lake/data-model/setup-blueprint/properties/array/.md) - a data type used to save lists of data. Supports [multi source ingestion](/context-lake/data-model/setup-blueprint/properties/array/.md#multi-source-ingestion) to combine values from multiple writers.
* [Enum](/context-lake/data-model/setup-blueprint/properties/enum/.md) - a data type used to define a named set of constant values.
* [URL](/context-lake/data-model/setup-blueprint/properties/url/.md) - a data type used to save links to websites.
* [Date & time](/context-lake/data-model/setup-blueprint/properties/datetime/.md) - a data type used to reference a date and time.
### Relations[](#relations "Direct link to Relations")
* [Mirror](/context-lake/data-model/setup-blueprint/properties/mirror-property/.md) - maps data from related entities onto your entity.
* [Relation](/context-lake/data-model/setup-blueprint/relate-blueprints/.md) - connects entities from different blueprints.
### Advanced[](#advanced "Direct link to Advanced")
* [Calculation](/context-lake/data-model/setup-blueprint/properties/calculation-property/.md) - calculates a property's value based on other properties and relations.
* [Aggregation](/context-lake/data-model/setup-blueprint/properties/aggregation-property/.md) - calculates metrics based on relations in your catalog, such as counting entities or averaging values.
* [Timer](/context-lake/data-model/setup-blueprint/properties/timer/.md) - defines an expiration date or lifespan for an entity.
### Embed[](#embed "Direct link to Embed")
* [Embedded URL](/context-lake/data-model/setup-blueprint/properties/embedded-url/.md) - embeds external content, such as a dashboard or web page, directly on an entity page.
* [Swagger UI](/context-lake/data-model/setup-blueprint/properties/swagger/.md) - displays OpenAPI and AsyncAPI specification files within entity pages.
* [Markdown](/context-lake/data-model/setup-blueprint/properties/markdown/.md) - displays formatted Markdown content within entity pages.
### Users & teams[](#users--teams "Direct link to Users & teams")
* [Port Team](/context-lake/data-model/setup-blueprint/properties/team/.md) - references teams that exist in Port.
* [Port User](/context-lake/data-model/setup-blueprint/properties/user/.md) - references users that exist in Port.
---
# Owning teams
Owning Teams can be added once per blueprint. It creates a relation to the `Team` blueprint, and sets the ownership of the blueprint's entities accordingly.
## Common usage[](#common-usage "Direct link to Common usage")
Use owning teams to assign responsibility for services, repositories, and infrastructure resources. Port uses this ownership configuration to identify the teams responsible for each entity.
For the full ownership model, including the available ownership types and how to sync, assign, and visualize ownership across your catalog, see [manage ownership in Port](/context-lake/business-context/ownership/.md).
---
# Protobuf
Protobuf is a data type used to save Protocol Buffers definitions.
## Common usage[](#common-usage "Direct link to Common usage")
Use Protobuf properties to store Protocol Buffers definitions from `.proto` files, such as:
* Message schemas exchanged between services.
* gRPC service and method definitions.
## API definition[](#api-definition "Direct link to API definition")
* Basic
* Array
```
{
"myProtoProp": {
"title": "My Proto",
"icon": "My icon",
"description": "My proto property",
"type": "string",
"format": "proto"
}
}
```
```
{
"myProtoArray": {
"title": "My proto array",
"icon": "My icon",
"description": "My proto array",
"type": "array",
"items": {
"type": "string",
"format": "proto"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myProtoProp" = {
title = "My proto"
required = false
format = "proto"
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myProtoArray" = {
title = "My proto array"
required = false
string_items = {
format = "proto"
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myProtoProp": BlueprintPropertiesStringPropsArgs(
title="My proto",
required=False,
format="proto",
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myProtoProp: {
title: "My proto",
required: false,
format: "proto",
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myProtoProp: {
title: "My proto",
required: false,
format: "proto",
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myProtoProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My proto"),
Required: pulumi.Bool(false),
Format: pulumi.String("proto"),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
---
# String
String is a primitive data type used to save text data.
## Common usage[](#common-usage "Direct link to Common usage")
Use string properties to store free-form text from your development tools, such as:
* Container image tags and package versions.
* Git commit hashes.
* Repository file paths.
* Service descriptions.
## API definition[](#api-definition "Direct link to API definition")
* Basic
* Enum
* Array
* Enum Array
```
{
"myStringProp": {
"title": "My string",
"icon": "My icon",
"description": "My string property",
"type": "string",
"default": "My default"
}
}
```
```
{
"myStringEnum": {
"title": "My string enum",
"icon": "My icon",
"description": "My string enum",
"type": "string",
"enum": ["my-option-1", "my-option-2"],
"enumColors": {
"my-option-1": "red",
"my-option-2": "green"
}
}
}
```
```
{
"myStringArray": {
"title": "My string array",
"icon": "My icon",
"description": "My string array",
"type": "array",
"items": {
"type": "string"
}
}
}
```
```
{
"myStringArray": {
"title": "My string enum array",
"icon": "My icon",
"description": "My string enum array",
"type": "array",
"items": {
"type": "string",
"enum": ["my-option-1", "my-option-2"],
"enumColors": {
"my-option-1": "red",
"my-option-2": "green"
}
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Enum
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myStringProp" = {
title = "My string"
required = false
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myStringProp" = {
title = "My string"
required = false
enum = ["my-option-1", "my-option-2"]
enum_colors = {
"my-option-1" = "red"
"my-option-2" = "green"
}
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myStringArray" = {
title = "My string array"
string_items = {} # Pass an empty object only sets the type to string
}
"myStringArrayWithDefault" = {
title = "My string array with default"
string_items = {
default = ["my-default-1", "my-default-2"]
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
* Enum
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myStringProp": BlueprintPropertiesStringPropsArgs(
title="My string", required=False
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myStringProp: {
title: "My string",
required: true,
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myStringProp: {
title: "My string",
required: true,
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myStringProp": &port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My String"),
Required: pulumi.Bool(true),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myStringProp": {
"title": "My String",
"required": True,
"enums": ["my-option-1", "my-option-2"],
"enum_colors": {
"my-option-1": "red",
"my-option-2": "green"
}
}
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myStringProp: {
title: "My String",
required: true,
enums: ["my-option-1", "my-option-2"],
enumColors: {
"my-option-1": "red",
"my-option-2": "green",
},
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myStringProp: {
title: "My String",
required: true,
enums: ["my-option-1", "my-option-2"],
enumColors: {
"my-option-1": "red",
"my-option-2": "green",
},
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myStringProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My String"),
Required: pulumi.Bool(false),
Enums: pulumi.StringArray{
pulumi.String("my-option-1"),
pulumi.String("my-option-2"),
},
EnumColors: pulumi.StringMap{
"my-option-1": pulumi.String("red"),
"my-option-2": pulumi.String("green"),
},
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## Validate string[](#validate-string "Direct link to Validate string")
String validations support the following operators:
* `minLength` - enforce minimal string length.
* `maxLength` - enforce maximal string length.
* `pattern` - enforce Regex patterns.
- Basic
- Array
- Terraform
- Pulumi
```
{
"myStringProp": {
"title": "My string",
"icon": "My icon",
"description": "My string property",
"type": "string",
"minLength": 1,
"maxLength": 32,
"pattern": "^[a-zA-Z0-9-]*-service$"
}
}
```
```
{
"myStringArray": {
"title": "My string array",
"icon": "My icon",
"description": "My string array",
"type": "array",
"items": {
"type": "string",
"minLength": 1,
"maxLength": 32,
"pattern": "^[a-zA-Z0-9-]*-service$"
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myStringProp" = {
title = "My string"
required = false
min_length = 1
max_length = 32
pattern = "^[a-zA-Z0-9-]*-service$"
}
}
}
}
```
```
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My blueprint",
properties: {
stringProps: {
myStringProp: {
maxLength: 32,
minLength: 1,
pattern: "^[a-zA-Z0-9-]*-service$"
}
}
}
});
```
## Available enum colors[](#available-enum-colors "Direct link to Available enum colors")
Properties defined using [enum](#api-definition) can also include specific colors for the different values available in the property definition, to see the available enum colors refer to the [enum page](/context-lake/data-model/setup-blueprint/properties/enum/.md#available-enum-colors).
---
# Swagger UI
The `Swagger UI` property is used to import and display [OpenAPI](https://www.openapis.org/) and/or [AsyncAPI](https://www.asyncapi.com/) specification files within an [entity]() in Port.
Using this property will automatically create an additional tab in each [entity page](/interface-builder/port-interface/page/entity-page/.md), displaying the specification files in [Swagger UI](https://swagger.io/) format. Within this tab, you will be able to perform HTTP calls to the spec target directly from Port.
The following is an example of a `Swagger UI` tab in an entity page:
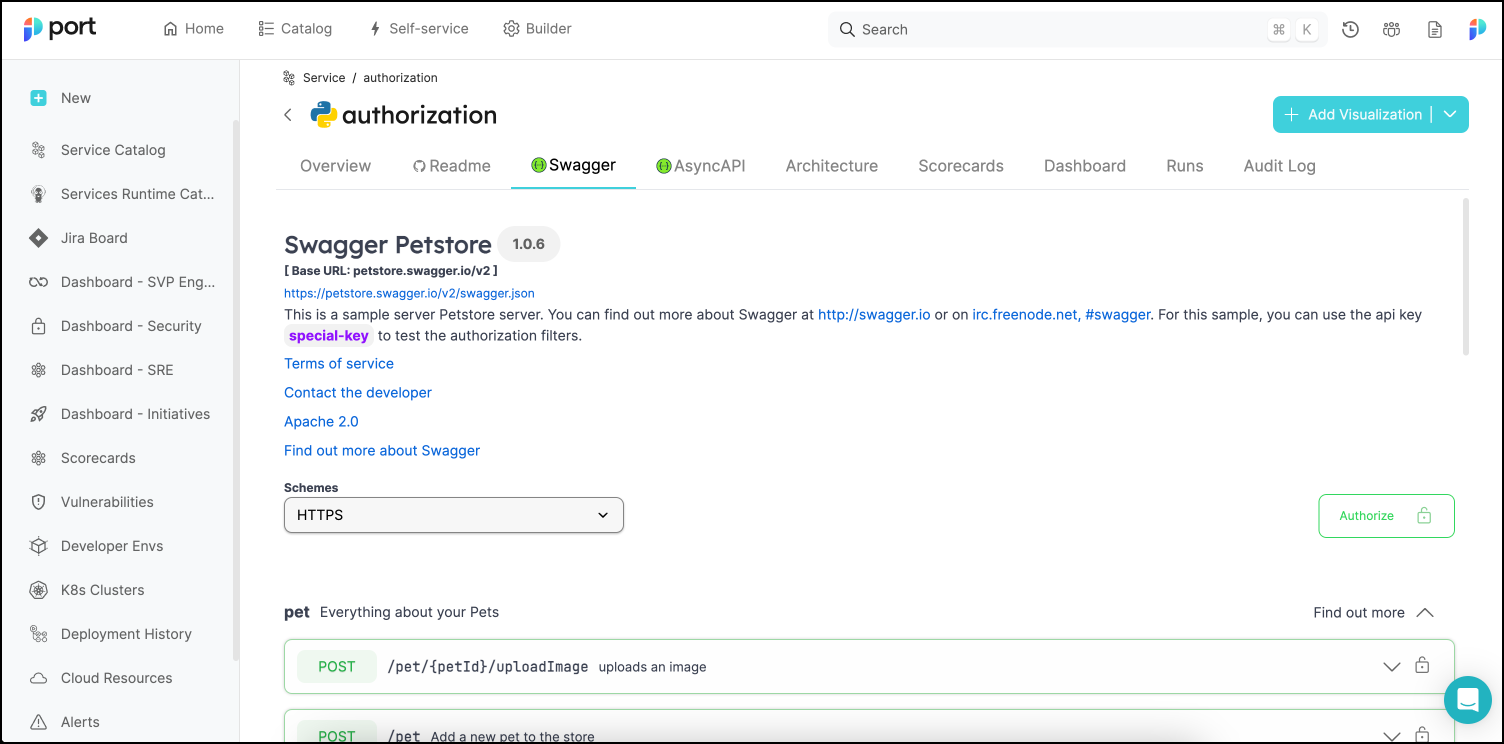
## Common usage[](#common-usage "Direct link to Common usage")
Use Swagger UI properties to display API contracts alongside your services, such as:
* OpenAPI specifications for HTTP APIs.
* AsyncAPI specifications for event-driven services.
* API documentation ingested from a repository or specification URL.
## OpenAPI[](#openapi "Direct link to OpenAPI")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
### Definition[](#definition "Direct link to Definition")
* URL
* JSON
* YAML
When using the URL format, Port will query the provided URL for the OpenAPI spec and expects a JSON OpenAPI spec
CORS configuration
When using URL for the `open-api` display, make sure that your server allows cross-origin (CORS) requests from Port:
* EU region: `app.port.io`
* US region: `app.us.port.io`
To serve the OpenAPI spec from an AWS S3 bucket, add a CORS policy to the bucket that allows requests from both `app.port.io` and `app.us.port.io`. Check out the [AWS documentation](https://docs.aws.amazon.com/AmazonS3/latest/userguide/enabling-cors-examples.html?icmpid=docs_amazons3_console) for more information.
* API
* Terraform
```
{
"myOpenApi": {
"title": "My Open API",
"type": "string",
"format": "url",
"spec": "open-api",
"description": "Open-API Prop"
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
myOpenApi = {
title = "My Open Api"
required = false
format = "url"
spec = "open-api"
}
}
}
}
```
When using the JSON type, you will need to provide the full JSON OpenAPI spec as an object to the entity:
* API
* Terraform
```
{
"myOpenApi": {
"title": "My Open API",
"type": "object",
"spec": "open-api",
"description": "Open-API Prop"
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
object_props = {
myOpenApi = {
title = "My Open Api"
required = false
spec = "open-api"
}
}
}
}
```
When using the YAML type, you will need to provide the full YAML OpenAPI spec to the entity:
* API
* Terraform
```
{
"myOpenApi": {
"title": "My Open API",
"type": "string",
"format": "yaml",
"spec": "open-api",
"description": "Open-API Prop"
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myOpenApi" = {
title = "My OpenAPI"
required = false
format = "yaml"
spec = "open-api"
}
}
}
}
```
***
### Example[](#example "Direct link to Example")
Here is how the Swagger tab in the specific entity page appears when an OpenAPI spec is provided:
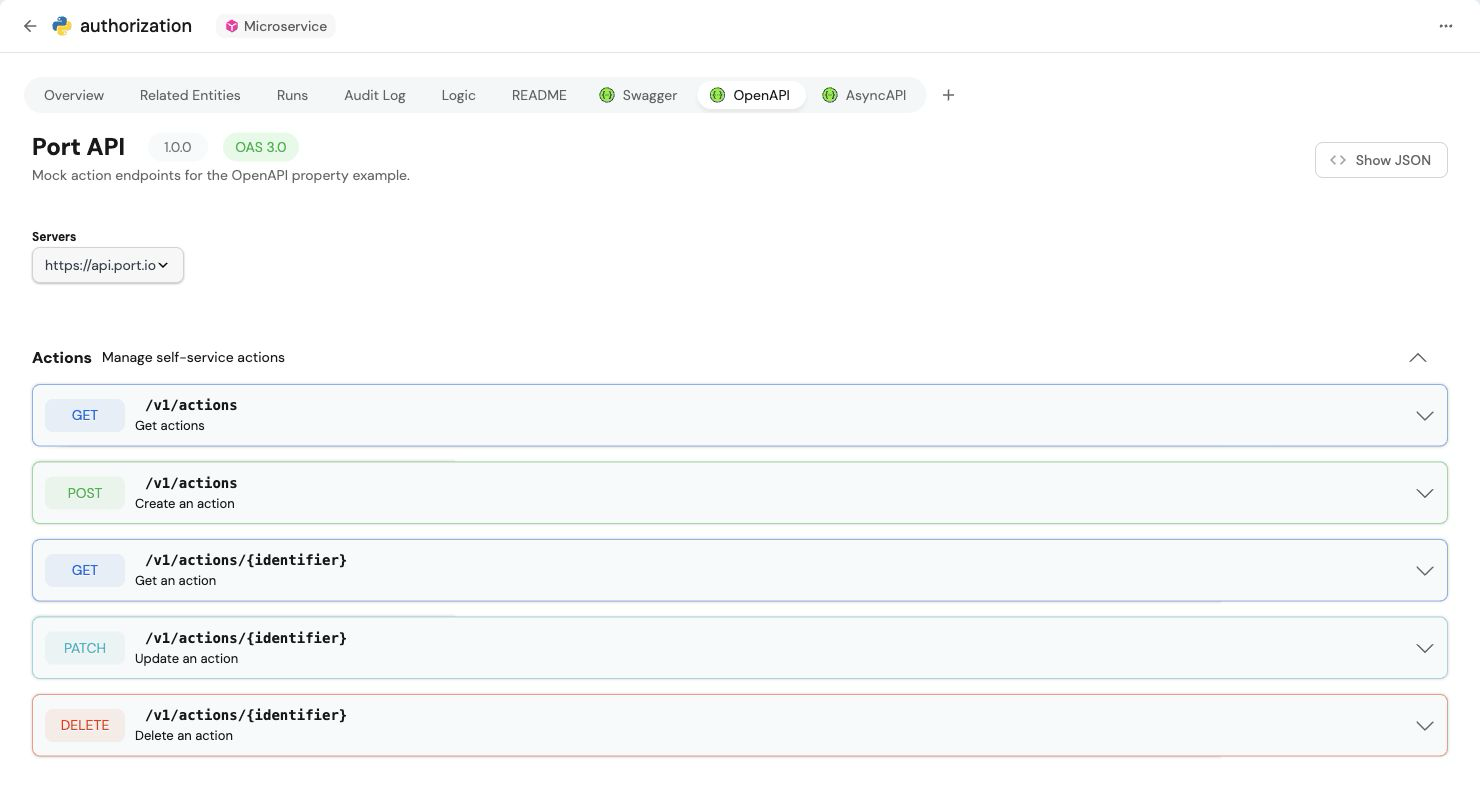
## AsyncAPI[](#asyncapi "Direct link to AsyncAPI")
### Definition[](#definition-1 "Direct link to Definition")
* URL
* JSON
* YAML
When using the URL format, Port will query the provided URL for the AsyncAPI spec and expects a JSON AsyncAPI spec
CORS configuration
When using URL for the `async-api` display, make sure that your server allows cross-origin (CORS) requests from Port:
* EU region: `app.port.io`
* US region: `app.us.port.io`
To serve the AsyncAPI spec from an AWS S3 bucket, add a CORS policy to the bucket that allows requests from both `app.port.io` and `app.us.port.io`. Check out the [AWS documentation](https://docs.aws.amazon.com/AmazonS3/latest/userguide/enabling-cors-examples.html?icmpid=docs_amazons3_console) for more information.
* API
* Terraform
```
{
"myAsyncApi": {
"title": "My Async API",
"type": "string",
"format": "url",
"spec": "async-api",
"description": "async-api Prop"
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
myAsyncApi = {
title = "My Async API"
required = false
format = "url"
spec = "async-api"
}
}
}
}
```
When using the JSON type, you will need to provide the full JSON AsyncAPI spec as an object to the Entity:
* API
* Terraform
```
{
"myAsyncApi": {
"title": "My Async API",
"type": "object",
"spec": "async-api",
"description": "async-api Prop"
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
object_props = {
myAsyncApi = {
title = "My Async Api"
required = false
spec = "async-api"
}
}
}
}
```
When using the YAML type, you will need to provide the full YAML AsyncAPI spec to the entity:
* API
* Terraform
```
{
"myOpenApi": {
"title": "My Async API",
"type": "string",
"format": "yaml",
"spec": "async-api",
"description": "Async-API Prop"
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myAsyncApi" = {
title = "My AsyncAPI"
required = false
format = "yaml"
spec = "async-api"
}
}
}
}
```
***
### Example[](#example-1 "Direct link to Example")
Here is how the Swagger tab in the specific entity page appears when an AsyncAPI spec is provided:
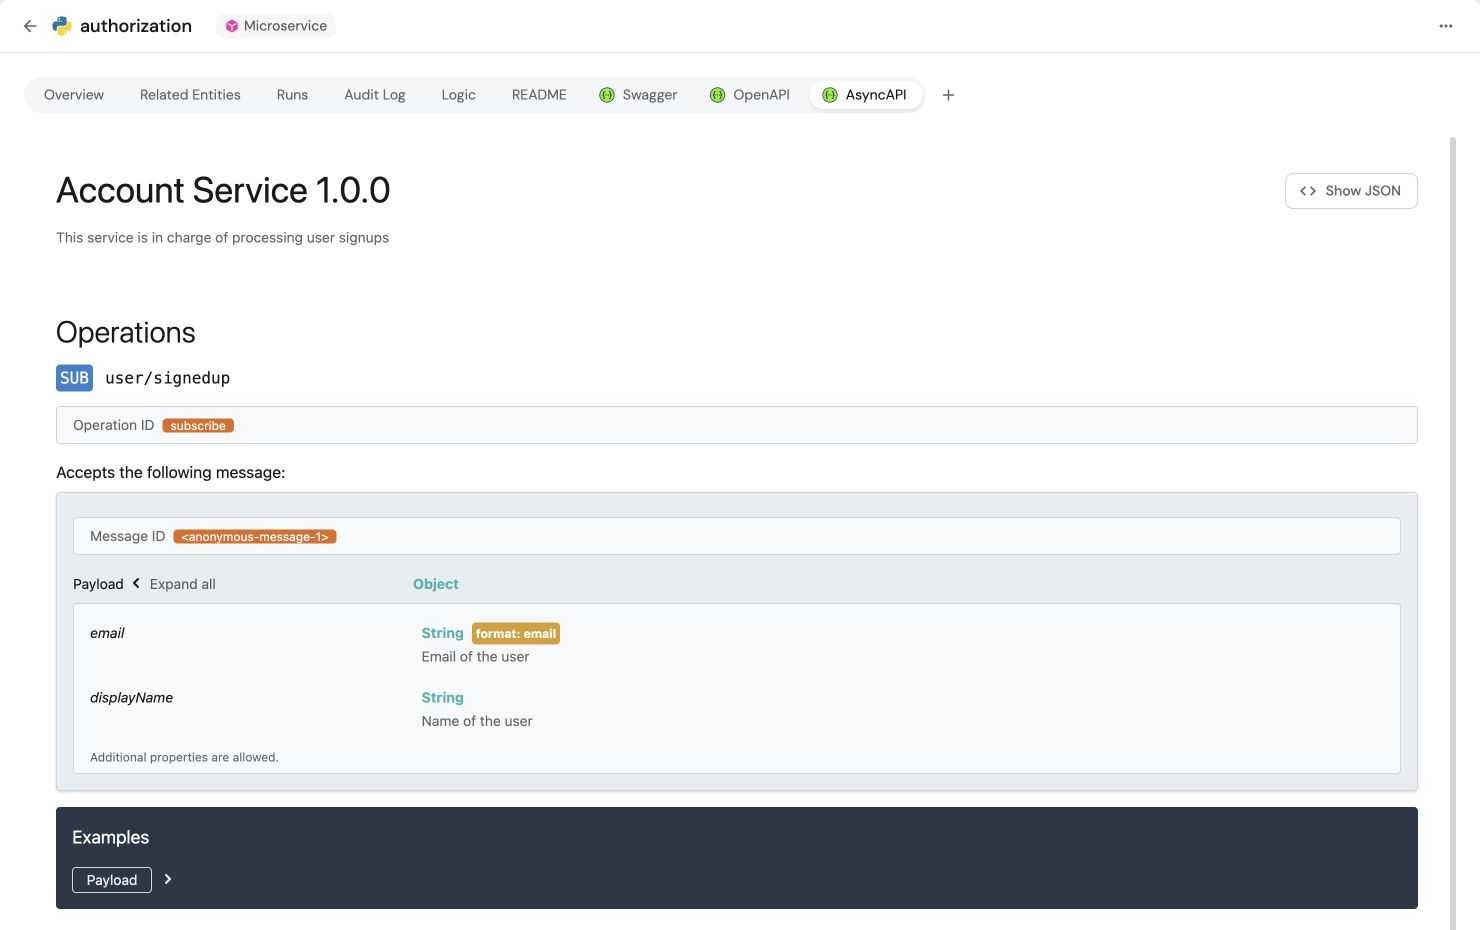
---
# Team
Team is a data type used to reference teams that exist in Port.
## Common usage[](#common-usage "Direct link to Common usage")
Use Port Team properties to reference teams in your organization, such as:
* The team responsible for operational support.
* Teams that review changes to a service.
* Teams that maintain shared infrastructure.
To define entity ownership, use [owning teams](/context-lake/data-model/setup-blueprint/properties/owning-teams/.md). A Port Team property alone does not configure ownership.
## API definition[](#api-definition "Direct link to API definition")
### Limit field[](#limit-field "Direct link to Limit field")
When creating a blueprint property of type Team in the UI, use the **limit** field to define how many values users can select for that property.
In the property creation form, the limit field dropdown provides two options:
* **1 value**: Only one value can be selected.
* **List of values**: Multiple values can be selected.
Selecting the **list of values** option will set the property's `type` to `array` in the JSON definition.
Limit field restriction
The limit field setting, whether it's **1 value** or a **list of values**, is permanent and cannot be changed after the property is created. If you create a property with a single value limit, you won’t be able to change it later to allow multiple values.
To change the limit configuration after creation:
1. Create a new property with the **limit** field set to a **list of values**.
2. Use the [migrate blueprint data](/context-lake/ingestion/ingest-data-into-port/other/migrate-data/.md) feature to insert the data to the new property.
3. Delete the old property.
4. Rename the new property to the old property name (optional).
* Basic
* Array
```
{
"myTeamProp": {
"title": "My team",
"icon": "My icon",
"description": "My team property",
"type": "string",
"format": "team",
"default": "my-team"
}
}
```
```
{
"myTeamArray": {
"title": "My team array",
"icon": "My icon",
"description": "My team array",
"type": "array",
"items": {
"type": "string",
"format": "team"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
myTeamProp = {
title = "My team"
required = false
format = "team"
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
myTeamArray = {
title = "My team array"
required = false
string_items = {
format = "team"
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myTeamProp": BlueprintPropertiesStringPropsArgs(
title="My team",
required=False,
format="team",
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myTeamProp: {
title: "My team",
required: false,
format: "team",
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myTeamProp: {
title: "My team",
required: false,
format: "team",
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myTeamProp": &port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My team"),
Required: pulumi.Bool(false),
Format: pulumi.String("team"),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
---
# Timer
Timer is a data type used to define an expiration date/lifespan of a specific entity.
## Common usage[](#common-usage "Direct link to Common usage")
Use timer properties to track deadlines that can trigger automation, such as:
* The expiration of a temporary development environment.
* The end of temporary resource access.
* A scheduled cleanup time for cloud resources.
A timer emits a timer-expired event when its deadline passes. Configure an [automation](/workflows/actions-and-automations/define-automations/setup-trigger/.md) to perform cleanup or revoke access; the timer itself does not perform those actions.
## API definition[](#api-definition "Direct link to API definition")
Set the property value on each entity to a future timestamp. Avoid a fixed blueprint default that will eventually be in the past.
* Basic
```
{
"myTimerProp": {
"title": "My timer",
"icon": "My icon",
"description": "My timer property",
"type": "string",
"format": "timer"
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myTimerProp" = {
title = "My timer"
icon = "My icon"
description = "My timer property"
format = "timer"
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myTimerProp": BlueprintPropertiesStringPropsArgs(
title="My timer",
format="timer",
required=True,
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myTimerProp: {
title: "My timer",
format: "timer",
required: true,
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myTimerProp: {
title: "My timer",
format: "timer",
required: true,
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myTimerProp": &port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My timer"),
Format: pulumi.String("timer"),
Required: pulumi.Bool(true),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
## Example[](#example "Direct link to Example")
Here is an entity for a `timerExample` blueprint which has a timer property with the identifier `timer`.
In the example entity, an expiration datetime is specified:
```
"identifier": "entityIdentifier",
"title": "Timer Example",
"icon": "Microservice",
"blueprint": "timerExample",
"properties": {
"timer": "2022-12-01T16:50:00+02:00"
},
"relations": {}
```
Looking at Port's UI, we can see that the timer we created expires in 2 hours:
After 2 hours pass, the property status will change to `Expired`, and an event of `Timer Expired` will be sent to the ChangeLog:
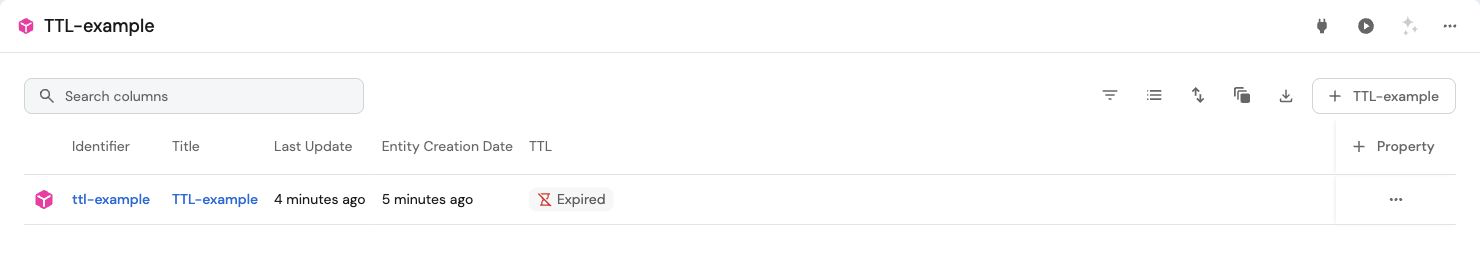
The timer expiration event will also appear in Port's audit log:
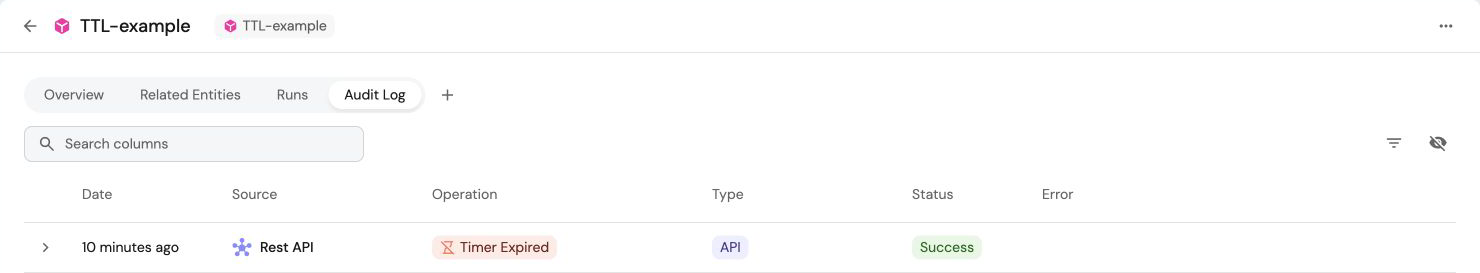
In order to notify about the timer expiration, the following notification body will be sent to the Webhook/Kafka topic configured in the blueprint's `changelogDestination`:
```
{
"context": {
"blueprint": "timerExample",
"entity": "entityIdentifier"
},
"action": "TIMER_EXPIRED",
"trigger": {
"at": "2022-12-01T16:50:00+02:00",
"by": {
"byPort": true,
"orgId": "org_example"
},
"origin": "API"
},
"resourceType": "entity",
"status": "SUCCESS"
}
```
---
# URL
URL is a data type used to save links to websites.
## Common usage[](#common-usage "Direct link to Common usage")
Use URL properties to link entities to resources in your tools, such as:
* Source code repositories and pull requests.
* Monitoring dashboards.
* Runbooks and service documentation.
* CI/CD workflow runs.
## Custom display text[](#custom-display-text "Direct link to Custom display text")
When creating a URL property in the UI, you can enable the **Custom display text** toggle to show custom text rather than the full URL. This is useful when you want to display a human-readable label (such as "Production Dashboard" or "API Documentation") instead of the raw URL.
* **Toggle off (default)**: The property stores a simple URL string.
* **Toggle on**: The property is defined as a [labeled URL object](/context-lake/data-model/setup-blueprint/properties/labeled-url-object/.md) with both a URL and display text. See the linked page for implementation details.
Toggle cannot be modified after saving
Once a URL property is saved, the custom display text toggle cannot be changed.
## API definition[](#api-definition "Direct link to API definition")
### Limit field[](#limit-field "Direct link to Limit field")
When creating a blueprint property of type URL in the UI, use the **limit** field to define how many values users can select for that property.
In the property creation form, the limit field dropdown provides two options:
* **1 value**: Only one value can be selected.
* **List of values**: Multiple values can be selected.
Selecting the **list of values** option will set the property's `type` to `array` in the JSON definition.
Limit field restriction
The limit field setting, whether it's **1 value** or a **list of values**, is permanent and cannot be changed after the property is created. If you create a property with a single value limit, you won’t be able to change it later to allow multiple values.
To change the limit configuration after creation:
1. Create a new property with the **limit** field set to a **list of values**.
2. Use the [migrate blueprint data](/context-lake/ingestion/ingest-data-into-port/other/migrate-data/.md) feature to insert the data to the new property.
3. Delete the old property.
4. Rename the new property to the old property name (optional).
* Basic
* Enum
* Array
```
{
"myUrlProp": {
"title": "My url",
"icon": "My icon",
"description": "My url property",
"type": "string",
"format": "url",
"default": "https://example.com"
}
}
```
```
{
"myUrlEnum": {
"title": "My url enum",
"icon": "My icon",
"description": "My url enum",
"type": "string",
"format": "url",
"enum": ["https://example.com", "https://port.io"],
"enumColors": {
"https://example.com": "red",
"https://port.io": "green"
}
}
}
```
```
{
"myUrlArray": {
"title": "My url array",
"icon": "My icon",
"description": "My url array",
"type": "array",
"items": {
"type": "string",
"format": "url"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Enum
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myUrlProp" = {
title = "My url"
required = false
format = "url"
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myUrlEnum" = {
title = "My url enum"
required = false
format = "url"
enum = ["https://example.com", "https://port.io"]
enum_colors = {
"https://example.com" = "red",
"https://port.io" = "green"
}
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myUrlArray" = {
title = "My url array"
required = false
string_items = {
format = "url"
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
* Enum
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myUrlProp": BlueprintPropertiesStringPropsArgs(
title="My url", required=False, format="url"
),
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myUrlProp: {
title: "My url",
required: true,
format: "url",
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myUrlProp: {
title: "My url",
required: true,
format: "url",
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myUrlProp": &port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My url"),
Required: pulumi.Bool(true),
Format: pulumi.String("url"),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
* Python
* TypeScript
* JavaScript
* Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint, BlueprintPropertiesArgs, BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myUrlProp":BlueprintPropertiesStringPropsArgs(
title="My url",
required=True,
format="url",
enums=["https://example.com", "https://port.io"],
enum_colors={
"https://example.com": "red",
"https://port.io": "green"
}
)
},
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myUrlProp: {
title: "My url",
required: true,
format: "url",
enums: ["https://example.com", "https://port.io"],
enumColors: {
"https://example.com": "red",
"https://port.io": "green",
},
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myUrlProp: {
title: "My url",
required: true,
format: "url",
enums: ["https://example.com", "https://port.io"],
enumColors: {
"https://example.com": "red",
"https://port.io": "green",
},
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myUrlProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My url"),
Required: pulumi.Bool(false),
Format: pulumi.String("url"),
Enums: pulumi.StringArray{
pulumi.String("https://example.com"),
pulumi.String("https://port.io"),
},
EnumColors: pulumi.StringMap{
"https://example.com": pulumi.String("red"),
"https://port.io": pulumi.String("green"),
},
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
---
# User
User is a data type used to reference users that exist in Port.
## Common usage[](#common-usage "Direct link to Common usage")
Use Port User properties to reference people by email address, such as:
* The engineer currently on call.
* The lead maintainer of a service.
* The reviewer assigned to a change.
## Display format[](#display-format "Direct link to Display format")
Both `email` and `user` formats accept an email address, but display it differently:
* `email` format displays the raw email string.
* `user` format displays the user's name and avatar from Port's list of known users.
The `user` format also indicates each user's status:
| User status | Example |
| ------------ | ------------------------------------------------------------------------------------------------------------------------------- |
| Active |  |
| Invited |  |
| Unregistered |  |
## API definition[](#api-definition "Direct link to API definition")
You can add user properties using the blueprint JSON editor, the API, Terraform, or Pulumi.
User selection in the UI
Selecting **User** in the blueprint UI form creates a [relation](/context-lake/data-model/setup-blueprint/relate-blueprints/.md) to the `_user` blueprint, rather than a user property.
### Single or multiple users[](#single-or-multiple-users "Direct link to Single or multiple users")
Use the **Basic** definition for a single user or the **Array** definition for multiple users.
Changing the number of users
You cannot switch an existing property between a single value and an array. Create a new property and [migrate its data](/context-lake/ingestion/ingest-data-into-port/other/migrate-data/.md) before replacing the original.
* Basic
* Array
```
{
"myUserProp": {
"title": "My user",
"icon": "My icon",
"description": "My user property",
"type": "string",
"format": "user",
"default": "me@example.com"
}
}
```
```
{
"myUserArray": {
"title": "My user array",
"icon": "My icon",
"description": "My user array",
"type": "array",
"items": {
"type": "string",
"format": "user"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
myUserProp = {
title = "My user"
required = false
format = "user"
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myUserArray" = {
title = "My user array"
required = false
string_items = {
format = "user"
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesStringPropsArgs,BlueprintPropertiesArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myUserProp": BlueprintPropertiesStringPropsArgs(
title="My user",
required=False,
format="user",
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myUserProp: {
title: "My user",
required: false,
format: "user",
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myUserProp: {
title: "My user",
required: false,
format: "user",
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myUserProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My user"),
Required: pulumi.Bool(false),
Format: pulumi.String("user"),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
---
# YAML
YAML is a data type used to save object definitions in YAML.
## Common usage[](#common-usage "Direct link to Common usage")
Use YAML properties to store the contents of configuration files, such as:
* Kubernetes manifests.
* Helm values files.
* CI/CD pipeline definitions.
## API definition[](#api-definition "Direct link to API definition")
* Basic
* Array
```
{
"myYAMLProp": {
"title": "My yaml",
"icon": "My icon",
"description": "My yaml property",
"type": "string",
"format": "yaml"
}
}
```
```
{
"myYAMLArray": {
"title": "My yaml array",
"icon": "My icon",
"description": "My yaml array",
"type": "array",
"items": {
"type": "string",
"format": "yaml"
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
## Terraform definition[](#terraform-definition "Direct link to Terraform definition")
The examples below use version **2.29.0** of the Terraform and Pulumi providers. [Configure your provider](/context-lake/data-model/setup-blueprint/properties/overview/.md#configure-provider-examples) first, then run one example at a time in its own project. Each example creates a blueprint; use distinct identifiers when you combine examples.
* Basic
* Array
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
string_props = {
"myYAMLProp" = {
title = "My yaml"
required = false
format = "yaml"
}
}
}
}
```
```
resource "port_blueprint" "myBlueprint" {
identifier = "myBlueprint"
title = "My blueprint"
properties = {
array_props = {
"myYAMLArray" = {
title = "My yaml array"
required = false
string_items = {
format = "yaml"
}
}
}
}
}
```
## Pulumi definition[](#pulumi-definition "Direct link to Pulumi definition")
* Basic
- Python
- TypeScript
- JavaScript
- Go
```
"""A Python Pulumi program"""
import pulumi
from port_pulumi import Blueprint,BlueprintPropertiesArgs,BlueprintPropertiesStringPropsArgs
blueprint = Blueprint(
"myBlueprint",
identifier="myBlueprint",
title="My Blueprint",
properties=BlueprintPropertiesArgs(
string_props={
"myYAMLProp": BlueprintPropertiesStringPropsArgs(
title="My yaml",
required=False,
format="yaml",
)
}
),
relations={}
)
```
```
import * as pulumi from "@pulumi/pulumi";
import * as port from "@port-labs/port";
export const blueprint = new port.Blueprint("myBlueprint", {
identifier: "myBlueprint",
title: "My Blueprint",
properties: {
stringProps: {
myYAMLProp: {
title: "My yaml",
required: false,
format: "yaml",
},
},
},
});
```
```
"use strict";
const pulumi = require("@pulumi/pulumi");
const port = require("@port-labs/port");
const entity = new port.Blueprint("myBlueprint", {
title: "My Blueprint",
identifier: "myBlueprint",
properties: {
stringProps: {
myYAMLProp: {
title: "My yaml",
required: false,
format: "yaml",
},
},
},
relations: {},
});
exports.title = entity.title;
```
```
package main
import (
"github.com/port-labs/pulumi-port/sdk/v2/go/port"
"github.com/pulumi/pulumi/sdk/v3/go/pulumi"
)
func main() {
pulumi.Run(func(ctx *pulumi.Context) error {
blueprint, err := port.NewBlueprint(ctx, "myBlueprint", &port.BlueprintArgs{
Identifier: pulumi.String("myBlueprint"),
Title: pulumi.String("My Blueprint"),
Properties: port.BlueprintPropertiesArgs{
StringProps: port.BlueprintPropertiesStringPropsMap{
"myYAMLProp": port.BlueprintPropertiesStringPropsArgs{
Title: pulumi.String("My yaml"),
Required: pulumi.Bool(false),
Format: pulumi.String("yaml"),
},
},
},
})
if err != nil {
return err
}
ctx.Export("blueprint", blueprint.Title)
return nil
})
}
```
---
# Relate Blueprints
Relations define connections between [blueprints](/context-lake/data-model/setup-blueprint/overview/.md), consequently connecting the [entities](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md) based on these blueprints.
This provides logical context to the software catalog.
## Common relations[](#common-relations "Direct link to Common relations")
Relations can be used to represent the logical connections between assets in your software catalog, for example:
* The **packages** that a **microservice** uses.
* The **run** history of a **CI job**.
* The **Kubernetes clusters** that exist in a **cloud account**.
In this [live demo](https://demo.port.io/settings/data-model) example, we can see the Data model page with all of the blueprints and their relations. 🎬
## Relation schema structure[](#relation-schema-structure "Direct link to Relation schema structure")
The basic structure of a relation object:
```
{
"myRelation": {
"title": "My title",
"target": "My target blueprint",
"required": true,
"many": false
}
}
```
relation declaration
A relation exists under the `relations` key in the [Blueprint JSON schema](/context-lake/data-model/setup-blueprint/overview/.md#blueprint-schema-structure).
## Structure table[](#structure-table "Direct link to Structure table")
| Field | Description | Notes |
| ------------ | ------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `identifier` | Unique identifier (Maximum 100 characters) | The identifier is used for API calls, programmatic access and distinguishing between different relations.
The identifier is the key of the relation schema object, in the [schema structure](#relation-schema-structure) above, the identifier is `myRelation` |
| `title` | Relation name that will be shown in the UI | Human-readable name for the relation |
| `target` | Target blueprint identifier | The target blueprint has to exist when defining the relation |
| `required` | Boolean flag to define whether the target must be provided when creating a new entity of the blueprint | |
| `many` | Boolean flag to define whether multiple target entities can be mapped to the Relation | For more information refer to [many relation](#many) |
## Types of relations[](#types-of-relations "Direct link to Types of relations")
### 👤 Single[](#bust_in_silhouette-single "Direct link to bust_in_silhouette-single")
A single type relation is used to map a single target entity to the source.
#### 💡 Common Single Relations[](#-common-single-relations "Direct link to 💡 Common Single Relations")
* Map a **Deployment** to the **Running Service** that it deployed.
* Map a **package version** to the **package**.
* Map a **K8s cluster** to the **cloud account** it is provisioned in.
In this [live demo](https://demo.port.io/githubWorkflowEntity?identifier=wish_list_build_185674921\&activeTab=3) example, we can see a specific Deployment Workflow and its related Service. 🎬
#### Single Relation Structure[](#single-relation-structure "Direct link to Single Relation Structure")
A single type relation is distinguished by the `many: false` configuration:
* API
* Terraform
```
{
"myRelation": {
"title": "My title",
"target": "myTargetBlueprint",
"required": false,
"many": false
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
```
resource "port_blueprint" "myBlueprint" {
# ...blueprint properties
# ...user-defined properties
relations {
identifier = "myRelation"
title = "My relation"
target = "myTargetBlueprint"
required = false
many = false
}
}
```
### 👥 Many[](#-many "Direct link to 👥 Many")
A many type relation is used to map multiple target entities to the source.
#### 💡 Common Many Relations[](#-common-many-relations "Direct link to 💡 Common Many Relations")
* Map dependencies between services.
* Map the **packages** used by a **service**.
* Map the **cloud resources** used by a **service**.
* Map the **services deployed** in a **developer environment**.
In this [live demo](https://demo.port.io/jiraIssueEntity?identifier=WISH-789\&activeTab=1) example, we can see a specific Jira issue and its related Services. 🎬
#### Many Relation Structure[](#many-relation-structure "Direct link to Many Relation Structure")
A many type relation is distinguished by the `many: true` configuration:
* API
* Terraform
```
{
"myRelation": {
"title": "My title",
"target": "myTargetBlueprint",
"required": false,
"many": true
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
```
resource "port_blueprint" "myBlueprint" {
# ...blueprint properties
# ...user-defined properties
relations {
identifier = "myRelation"
title = "My relation"
target = "myTargetBlueprint"
required = false
many = true
}
}
```
Relation Configuration Restriction
A Relation can't be configured with both `many` and `required` set to `true`.
## Multi source ingestion[](#multi-source-ingestion "Direct link to Multi source ingestion")
By default, relations use last-writer-wins behavior: each update replaces the full list of targets.
Enable **Multi source ingestion** to let multiple [connectors](/context-lake/ingestion/overview/.md) or API callers contribute targets to the same relation without overwriting each other. This is only available on `many` relations.
In the [Data model](https://app.port.io/settings/data-model) or software catalog, turn on **Multi source ingestion** when creating the relation. In the API, set `"union": true`.
Cannot be changed later
This setting cannot be changed after the relation is created.
### Example[](#example "Direct link to Example")
The `service` blueprint has multi source ingestion enabled on its `dependencies` relation. For an entity of that blueprint:
1. **Monday** - the Snyk integration writes `{ "snyk": ["lodash", "axios"] }`.
2. **Tuesday** - Dependabot writes `{ "dependabot": ["axios", "express"] }` without removing Snyk's targets.
3. **Wednesday** - Alice edits the entity in the UI and adds `winston`. Port saves her changes under `user:alice`.
A **GET** returns the merged, deduplicated list of targets:
```
{ "dependencies": ["lodash", "axios", "express", "winston"] }
```
Each writer only updates its own source key. `axios` appears once even though both scanners reported it.
### Write and read values[](#write-and-read-values "Direct link to Write and read values")
**Write** (`POST`, `PATCH`, `PUT`) - send one source key per update, mapped to an array of target identifiers:
```
{
"relations": {
"dependencies": {
"snyk": ["lodash", "axios"]
}
}
}
```
Use `null` instead of an array to clear a source's slice.
Source keys must match `^[A-Za-z0-9._:@/-]{1,128}$`.
A source's slice can also be defined using a [search query](/context-lake/ingestion/configure-mapping/configuration-methods/.md#mapping-relations-using-search-queries) instead of a static list of identifiers:
```
{
"relations": {
"dependencies": {
"snyk": {
"combinator": "and",
"rules": [{ "property": "$blueprint", "operator": "=", "value": "package" }]
}
}
}
}
```
**Read** (`GET`, search) - Port returns the merged, deduplicated list of target identifiers:
```
{ "dependencies": ["lodash", "axios", "express", "winston"] }
```
In the UI, you edit the assembled list directly. Port stores UI edits under `user:{userId}` automatically.
Consistent with array properties and ownership
Multi source ingestion works the same way for [array properties](/context-lake/data-model/setup-blueprint/properties/array/.md#multi-source-ingestion) and [owning teams](/context-lake/business-context/ownership/.md#multi-source-ingestion-for-owning-teams): each writer owns a source key, and reads return the deduplicated combination of all sources.
### Constraints[](#constraints "Direct link to Constraints")
* Only available on `many` relations.
* Cannot be changed after the relation is created. Create a new relation and migrate the values instead.
* Sending a plain array, multiple source keys, or an invalid source key returns `422`.
## Configure relations in Port[](#configure-relations-in-port "Direct link to Configure relations in Port")
Relations are part of the structure of a [blueprint](/context-lake/data-model/setup-blueprint/overview/.md#blueprint-structure).
* UI
* API
* Terraform
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Expand the blueprint from which you would like to create a relation.
3. Click on the `+ New relation` button:
4. Fill in the form with your desired values, then click `Create`.
Create in Port
```
{
"identifier": "myIdentifier",
"title": "My title",
"description": "My description",
"icon": "My icon",
"calculationProperties": {},
"schema": {
"properties": {},
"required": []
},
"relations": {
"myRelation": {
"title": "My title",
"target": "My target blueprint",
"required": true,
"many": false
}
}
}
```
Check out Port's [API reference](/api-reference/port-api/) to learn more.
```
resource "port_blueprint" "myBlueprint" {
# ...blueprint properties
# ...user-defined properties
relations = {
"myRelation" = {
title = "My title"
target = "My target blueprint"
required = true
many = false
}
}
}
```
---
# Extend the context lake
You can extend the Context Lake beyond native integrations by connecting external MCP servers and publishing skills.
## Extension options[](#extension-options "Direct link to Extension options")
* **[MCP connectors](/agent-management/ai-registry/mcp-connectors/.md)** — Connect external MCP servers so Port AI and agents can query tools like Notion, Linear, and Jira at runtime.
* **[Skills](/agent-management/ai-registry/skills/overview/.md)** — Publish reusable instruction packages that guide Port AI and agents through domain-specific workflows.
---
# Auto discovery
The **auto discovery** capability uses [Port AI](/port-ai/overview/.md) to discover entities and their relations. This helps you maintain a complete and accurate catalog, especially for entities that are not automatically created through integrations (see common use-cases below).
### Common use cases
* **Services**: Service blueprint centralizes different components of a service like its repository, incidents for example. For that reason, unlike GitHub repositories or PagerDuty services that sync automatically from integrations, services are typically created manually. Auto discovery helps you identify and create these missing services.
* **Users**: Discover users from related entities. For instance, if you have GitHub repositories synced, we can analyze pull requests and issues entities to suggest users who contributed to them but do not yet exist in your catalog.
## When to use catalog auto discovery[](#when-to-use-catalog-auto-discovery "Direct link to When to use catalog auto discovery")
This feature is most effective for blueprints that don't have a single clear source of truth. Below are some guidelines to help you decide when to use catalog discovery and when to use classic integration mapping.
**When classic data mapping is preferred**
Use [integration mapping](/context-lake/ingestion/configure-mapping/overview/.md) when an entity has a clear, single source of truth, for example:
* **Repositories**: When a repository is ingested directly from your SCM tool (e.g., GitHub, GitLab), it makes more sense to use integration mapping to create and maintain it.
**When catalog auto discovery is preferred**
Use catalog discovery when an entity can be created based on multiple relations to different blueprints, without a clear source of truth or a single mapping pattern:
* **Services**: A service can be identified through various sources such as Jira projects, Snyk projects, PagerDuty services, Sonar projects, or a combination of these. Since no single integration fully represents the service, catalog discovery can analyze these related entities to suggest services.
* **Users**: A user can be derived from multiple relations, including Jira users, Snyk users, PagerDuty users, and more. Catalog discovery helps unify these sources to identify users who should exist in your catalog.
## How to use catalog auto discovery[](#how-to-use-catalog-auto-discovery "Direct link to How to use catalog auto discovery")
**Run the discovery:**
1. Navigate to the [Catalog](https://app.port.io/organization/catalog) page in Port.
2. Open the catalog page of the blueprint for which you want to discover new entities.
3. Click on the  button in the top right corner of the page.
4. For the best results, we recommend providing the definition of the blueprint you want to discover, along with clear instructions for patterns or specific properties that should be considered.
For example:
* **Mono-repo microservices:**
```
Services are represented as code in a repository.
Check the file structure of each repository to identify services.
Services may be found in specific folders, such as "apps" or "services".
```
* **Service repository identification:**
```
Focus on repos that have keywords that can indicate they are services
(e.g., "service", "ms", "srv").
Ignore repos of libraries and packages. Having also a PagerDuty service
with a similar name as a repo is a strong indication that this is a service.
```
* **Identify users:**
```
Check "Jira issues" assignees and "pull requests" to identify developers in the organization.
```
5. Select related blueprints to analyze. The entities from these blueprints will be used to identify patterns and suggest new entities for your target blueprint. This field is mandatory and is automatically filled with all directly related blueprints.
6. Click on the `Discover` button.

**Review and edit suggestions:**
Once the process is complete, a list of suggested entities will be displayed, divided into two sections: **Create** and **Update**.
You can:
* Edit individual entity suggestions.
* Approve or decline suggestions individually or in bulk.
* View the proposed updates to existing entities by clicking the  button.
Suggested entities persist until they are approved or declined. You can close the discovery results window and return to review pending suggestions at any time by accessing the discovery results from the blueprint's catalog page using the  button.
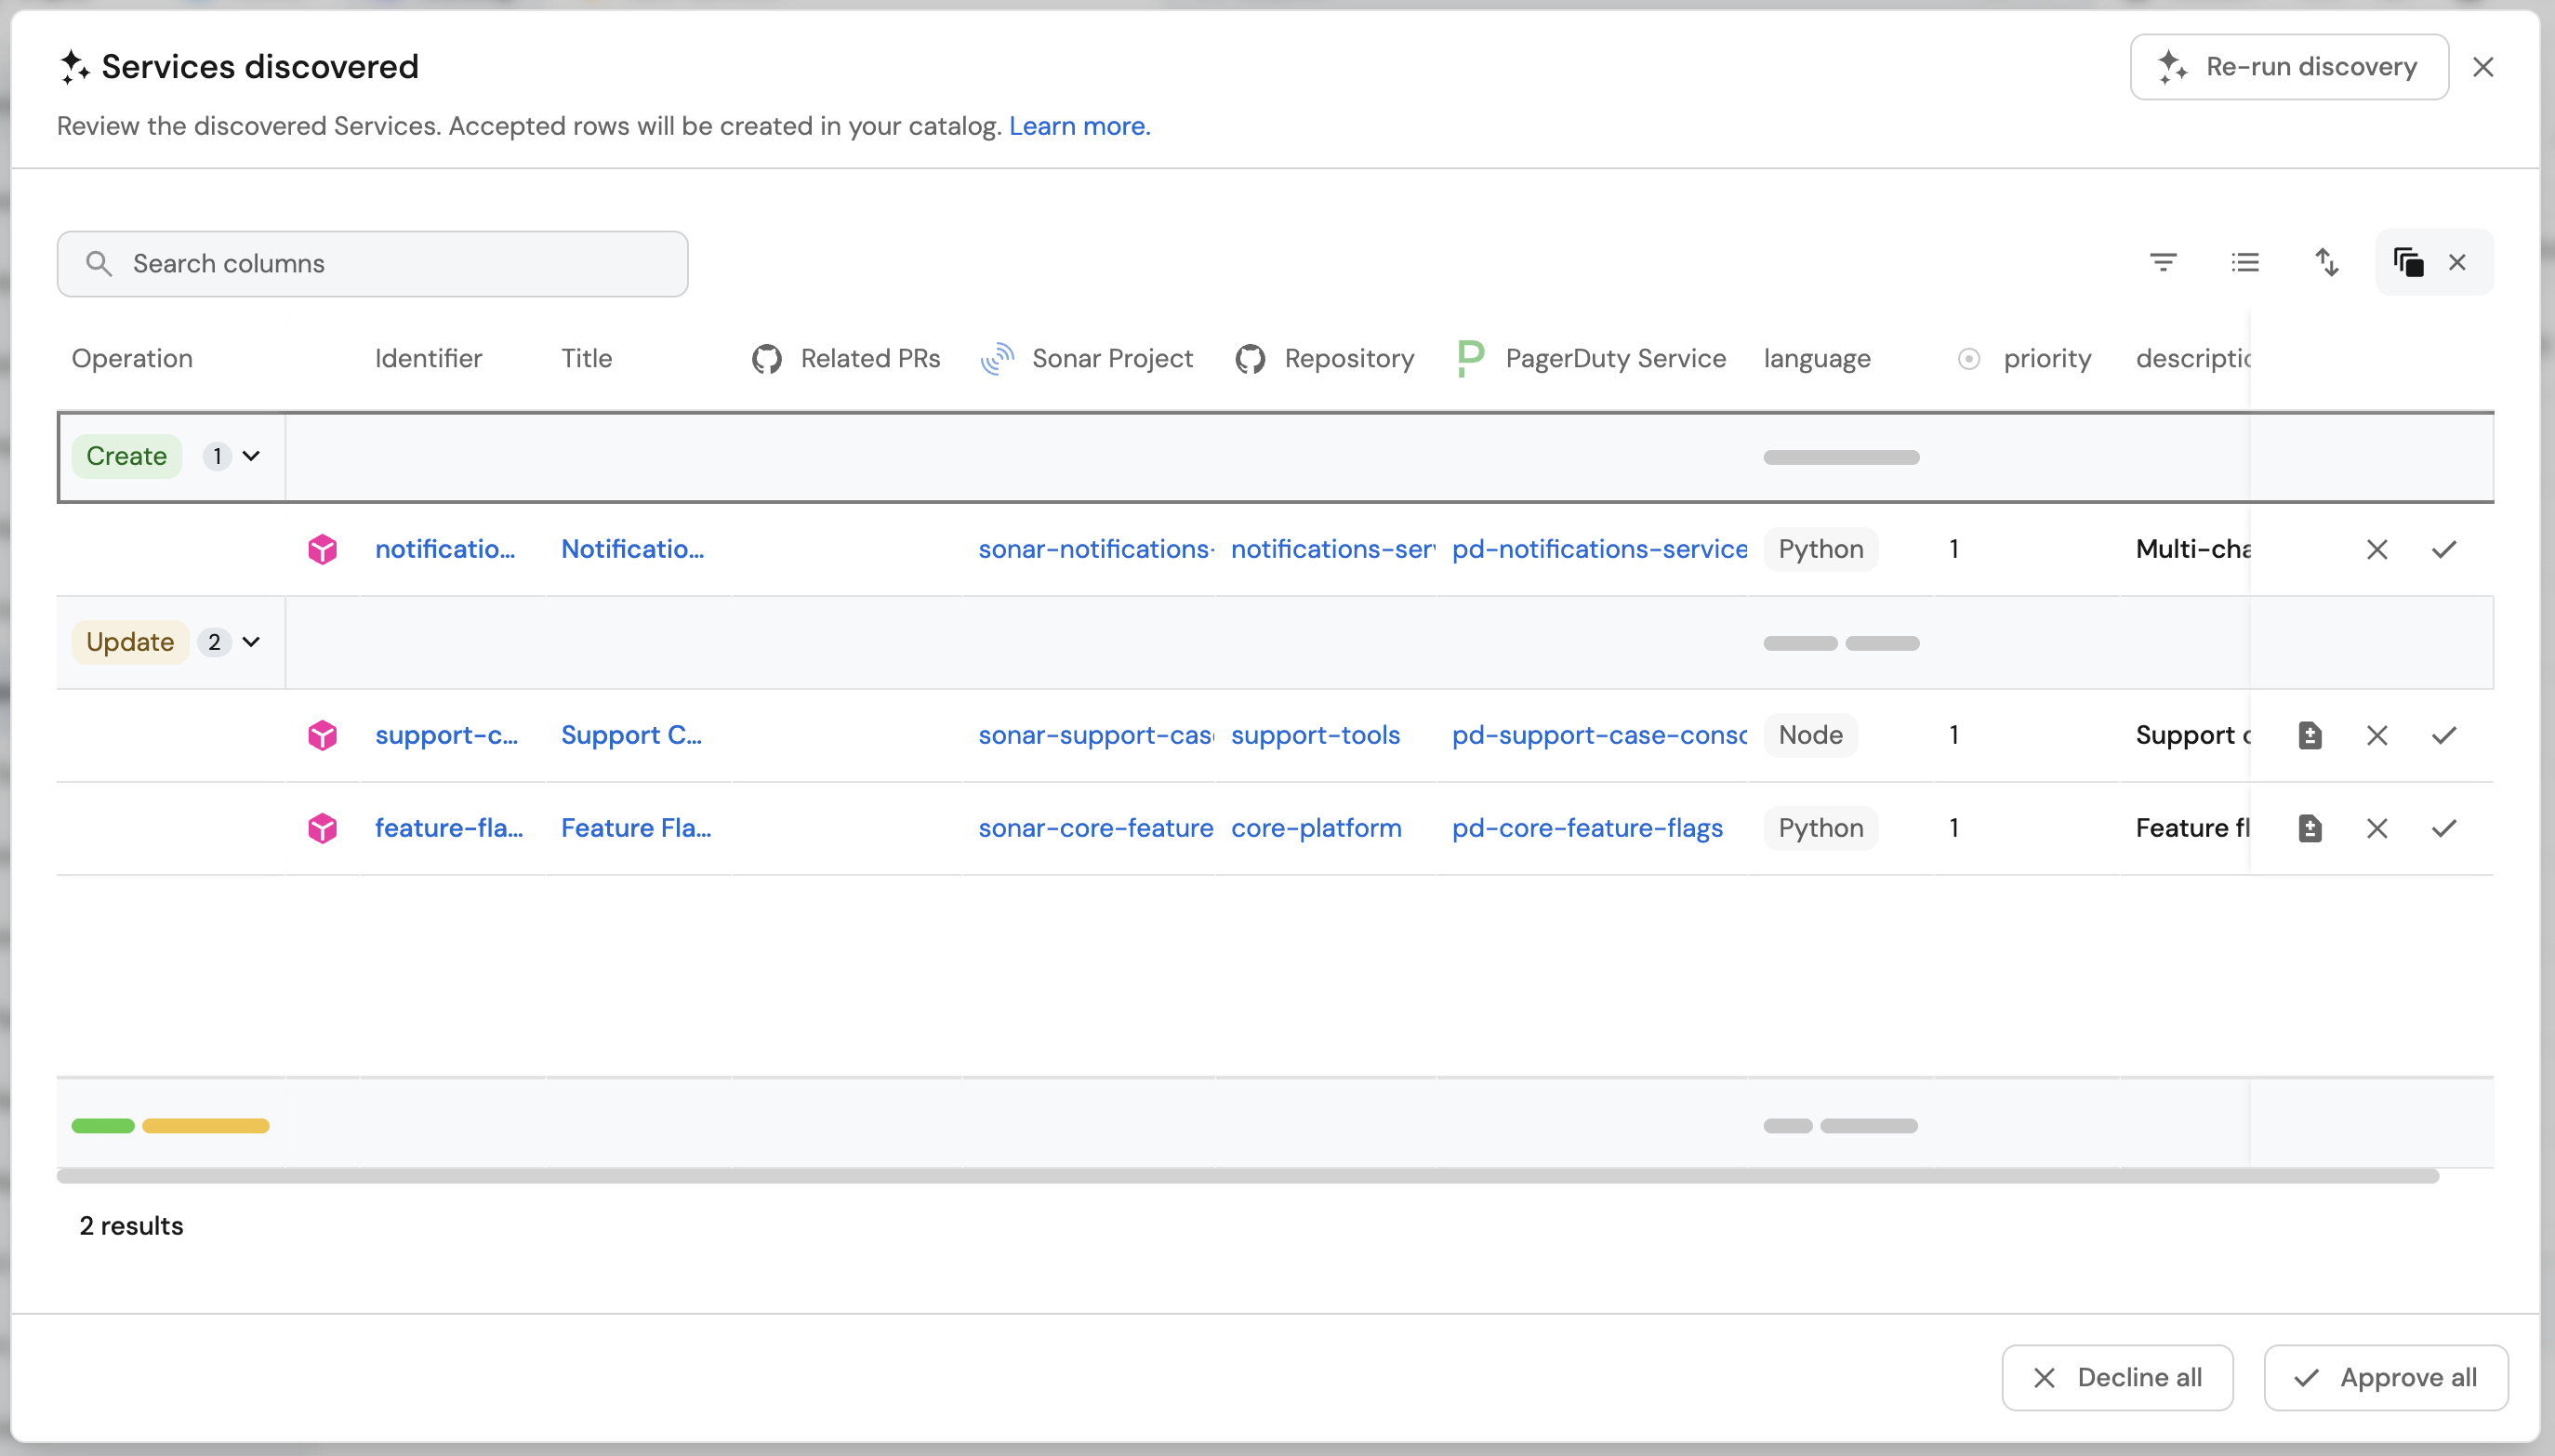
**Re-run the discovery**
You can re-run the discovery process at any time to generate additional or different suggestions. Each discovery run analyzes the current state of your catalog and may produce new suggestions based on newly added entities, updated relationships, or refined patterns. Re-running the discovery does not affect previously approved or declined suggestions.
Using auto discovery via the API
This feature is also available via API for a more programatic execution of the process. Refer to the [API reference](/api-reference/port-api/) catalog auto discovery for the full list of paths.
## Permissions[](#permissions "Direct link to Permissions")
The permissions are derived from the blueprint permissions.
You can approve suggested entities only if you have write access to the blueprint.
For more information about blueprint permissions, see the [set catalog RBAC](/context-lake/consuming-the-lake/govern-data-access/overview/.md) documentation.
To learn more about how Port AI uses your data, see the [security and data controls](/port-ai/security-and-data-controls/.md) documentation.
## Limitations[](#limitations "Direct link to Limitations")
* **Entity evaluation limit**: Discovery evaluates only the 500 most recently added entities from each related blueprint.
* **Property truncation**: Only the first 100 characters of each property value are analyzed. Longer content (such as large markdown fields) will be truncated.
* **LLM provider**: This feature currently uses Port's LLM and does not support [Bring Your Own LLM (BYOLLM)](/port-ai/overview/.md#bring-your-own-llm-byollm).
## FAQ[](#faq "Direct link to FAQ")
1Can catalog auto discovery use Bring Your Own LLM?
2Are there usage limits?
3Is the AI trained based on my data?
4How much catalog data does each discovery run evaluate?
---
# Common jq use-cases
Port uses [JQ](https://jqlang.github.io/jq/manual/) to transform and map data in integration mapping configurations, self-service action backends, and dynamic policies. This page covers the patterns that most commonly cause issues: null returns, silent failures, and type errors.
## Filtering arrays that contain empty strings[](#filtering-arrays-that-contain-empty-strings "Direct link to Filtering arrays that contain empty strings")
The built-in `isNotEmpty` operator returns `true` for `[""]`, an array with one empty string, because the array itself is not empty. To exclude these, combine `isNotEmpty` with an explicit empty-string check in JQ.
**Goal:** Filter entities where `entra_group_ids` contains at least one real value (not just `""`).
**Wrong: matches `[""]`:**
```
{
"property": "entra_group_ids",
"operator": "isNotEmpty"
}
```
**Correct: excludes `[""]`:**
```
{
"combinator": "and",
"rules": [
{ "property": "entra_group_ids", "operator": "isNotEmpty" },
{
"property": "entra_group_ids",
"operator": "!=",
"value": { "jqQuery": "[\"\"]" }
}
]
}
```
If you are writing a JQ expression directly (for example in a mapping or backend body), use:
```
.entra_group_ids | map(select(. != "")) | length > 0
```
## Parsing a JSON field value[](#parsing-a-json-field-value "Direct link to Parsing a JSON field value")
Some integration API responses include a field whose value is a **JSON-encoded string** - a string that contains serialized JSON. Use `fromjson` to parse it before accessing keys.
YAML inputs in self-service actions
In self-service actions, inputs declared with `type: "string"` and `format: "yaml"` are **not** raw strings at runtime. Port validates and parses the submitted YAML, then delivers the resulting object to your backend. You can therefore access keys directly without any parsing step:
```
.inputs.raw_config.dataset
```
If you need the object to be forwarded correctly, make sure the invocation method has `omitUserInputs: false` (see [omitUserInputs and omitPayload](#omituserinputs-and-omitpayload-with-the-port-execution-agent)).
**Use case:** An API field `metadata` contains a JSON-encoded string such as `"{\"dataset\": \"prod\"}"` and you need to read the `dataset` key.
**Input field:** `metadata` - a plain string whose value is JSON.
**Wrong: errors because JQ cannot index a string as an object:**
```
.metadata.dataset
```
**Correct: parses the JSON string first:**
```
(.metadata | fromjson).dataset
```
**Null-safe version** (returns `null` instead of erroring when the field is missing or empty):
```
(.metadata // "{}" | fromjson).dataset
```
**Mapping example (integration YAML):**
```
- kind: workspace
port:
entity:
mappings:
properties:
dataset: '(.metadata | fromjson).dataset'
```
`format: json` in blueprint properties
If the source field is always a JSON-encoded string, you can also declare the blueprint property as `type: "object"` and use `format: "json"` in the mapping so Port parses it automatically. See [Object property](https://docs.port.io/context-lake/data-model/setup-blueprint/properties/object).
## Array relations with missing entities[](#array-relations-with-missing-entities "Direct link to Array relations with missing entities")
If you map a relation to an array and one identifier in that array does not exist as an entity in Port, the upsert of the parent entity fails with a validation error.
**Problem mapping:**
```
githubTeams: "[.__teams[].id | tostring]"
```
If team `"3178082"` does not exist in Port, the entire repository entity upsert fails.
**Option A: exclude known missing IDs:**
```
githubTeams: '([.__teams[].id | tostring] - ["3178082", "8446394"])'
```
**Option B: filter out items with missing IDs (recommended):**
```
githubTeams: "[.__teams[] | select(.id != null) | .id | tostring]"
```
**Option C: filter to only IDs that match a known pattern:**
```
githubTeams: '[.__teams[].id | tostring | select(test("^[0-9]+$"))]'
```
Relations may be empty
Filtering out missing IDs means those relations will be absent from the entity. The entity will still be created, and the relation will just be empty. This is usually the correct tradeoff.
## omitUserInputs and omitPayload with the Port execution agent[](#omituserinputs-and-omitpayload-with-the-port-execution-agent "Direct link to omitUserInputs and omitPayload with the Port execution agent")
When you run a self-service action through the [Port execution agent](https://docs.port.io/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/) (GitLab pipeline, GitHub workflow, or `WEBHOOK` with `agent: true`), Port forwards an event payload that your agent maps with `invocations.json` (see [Control the payload](https://docs.port.io/workflows/actions-and-automations/setup-backend/webhook/port-execution-agent/control-the-payload/)). In the documented example payload, `payload.properties` can be an **empty object** until user inputs are included in the forwarded message.
Port's guides therefore often set **`omitUserInputs`** and **`omitPayload`** to **`false`** on the invocation method whenever the backend or agent mapping needs those fields (for example [Trigger ServiceNow incident](https://docs.port.io/guides/all/interact-with-servicenow/#trigger-a-servicenow-incident) and [Deploy S3 bucket using Crossplane](https://docs.port.io/guides/all/deploy-s3-bucket-crossplane/)).
**Symptom:** Your `invocations.json` filter references `.payload.properties.some_input`, but the condition never matches because `payload.properties` is `{}`.
**Fix - set both flags to `false` on the invocation method** (GitLab example):
```
{
"invocationMethod": {
"type": "GITLAB",
"projectName": "my-project",
"groupName": "my-group",
"defaultRef": "main",
"agent": true,
"omitUserInputs": false,
"omitPayload": false
}
}
```
**GitHub workflow example:**
```
{
"invocationMethod": {
"type": "GITHUB",
"org": "my-org",
"repo": "my-repo",
"workflow": "my-workflow.yml",
"omitUserInputs": false,
"omitPayload": false,
"reportWorkflowStatus": true
}
}
```
**Filter expression after fix:**
```
{
"enabled": ".payload.properties.target_platform == \"gcp\""
}
```
Check agent mapping errors first
If you see `Could not find suitable mapping for the event` in Port agent logs, confirm that `invocations.json` is loaded and that user inputs are present under `.payload.properties` (see the `omitUserInputs` / `omitPayload` settings above).
## Reading a CODEOWNERS file[](#reading-a-codeowners-file "Direct link to Reading a CODEOWNERS file")
For **GitHub Ocean**, Port recommends **`includedFiles`** on the `repository` resource and mapping file text from **`.__includedFiles[""]`**, instead of the legacy **`file://`** prefix (deprecated; see [Enrich entities with file contents](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/capabilities#enrich-entities-with-file-contents)).
**Recommended: repository `kind` with `includedFiles`:**
```
- kind: repository
selector:
query: "true"
includedFiles:
- README.md
- CODEOWNERS
- .github/CODEOWNERS
port:
entity:
mappings:
properties:
readme: .__includedFiles["README.md"]
codeowners: (.__includedFiles["CODEOWNERS"] // .__includedFiles[".github/CODEOWNERS"])
```
`includedFiles` resolves paths on the repository default branch, stores each file under `.__includedFiles`, and uses **`null`** when a path is missing. Extend the list for the paths you rely on (for example `.gitlab/CODEOWNERS` on GitLab - see the [GitLab integration](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/) docs).
**Alternative: `file` `kind` with a glob path** (one entity per matched file; useful for deep paths such as `**/.github/CODEOWNERS`):
```
- kind: file
selector:
query: "true"
files:
- path: "**/.github/CODEOWNERS"
organization: my-org
port:
entity:
mappings:
properties:
codeowners: .content
```
**Parse the first owner from the default rule (`*`):**
```
.codeowners
| split("\n")[]
| select(startswith("*"))
| split(" ")[1]
```
**Return all owners as an array:**
```
[
.codeowners
| split("\n")[]
| select(startswith("*"))
| split(" ")[1:][]
| select(. != "")
]
```
## Mapping GitHub topics to a team relation[](#mapping-github-topics-to-a-team-relation "Direct link to Mapping GitHub topics to a team relation")
If your teams are represented as GitHub repository topics, use `select` with a list of known team slugs to map them:
```
team: >-
[
.topics[]
| select(. == "devops" or . == "platform" or . == "security")
] | first // null
```
**Dynamic: match any topic that exists as a Port team identifier:**
```
team: >-
.topics
| map(select(. != null and . != ""))
| first // null
```
**Map to an array relation (multiple team owners):**
```
teams: >-
[
.topics[]
| select(. == "devops" or . == "platform" or . == "security")
]
```
Match team identifiers exactly
Keep the team slug in the topic lowercase and hyphen-separated (for example `platform-eng`), and make sure it matches the Port team identifier exactly. Port identifiers are case-sensitive.
## Null-safe navigation[](#null-safe-navigation "Direct link to Null-safe navigation")
**Problem:** `.properties.description` throws if `properties` is `null`.
**Use `//` to provide a fallback:**
```
.properties.description // ""
```
**Use `?` to suppress errors on a whole expression:**
```
(.properties.tags[]? | select(. == "production")) // false
```
**Check before mapping (if/else):**
```
if .description != null and .description != ""
then .description
else "No description provided"
end
```
**Safe array iteration (skip nulls):**
```
[.items[]? | select(. != null) | .id]
```
**Common pattern: safe string concat:**
```
((.firstName // "") + " " + (.lastName // "")) | ltrimstr(" ") | rtrimstr(" ")
```
## Filtering workflow runs to a specific repository[](#filtering-workflow-runs-to-a-specific-repository "Direct link to Filtering workflow runs to a specific repository")
The GitHub Ocean integration injects `.__repository` (the repo name string) into each workflow run object. Use it in your selector to scope ingestion:
```
- kind: workflow-run
selector:
query: '.__repository == "my-repo-name"'
```
**Filter to multiple repositories**
```
selector:
query: '[.__repository] | inside(["repo-a", "repo-b", "repo-c"])'
```
**Important:** For GitHub Ocean, ingestion is capped at the **latest 100 workflow runs per workflow** (see [migration from GitHub app](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/migration/key-changes#summary-of-key-changes)). Previously ingested runs can be removed on resync depending on your configuration. To retain history, add a **`ttl`** property on your workflow run blueprint and set it in your mapping so older runs are not deleted during resync.
---
# Configuration methods
Port provides two ways to configure an integration's mapping - the [form editor](#form-editor), a visual, guided experience, and the [YAML editor](#yaml-editor), a code-based configuration. Both editors apply the same [mapping concepts](/context-lake/ingestion/configure-mapping/overview/.md#mapping-concepts).
## Form editor[](#form-editor "Direct link to Form editor")
Limited availability
The form editor is currently available for select integrations, with support for all integrations coming soon.
The form editor is the default mapping experience. It provides a visual, step-by-step interface for configuring the [mapping concepts](/context-lake/ingestion/configure-mapping/overview/.md#mapping-concepts) above.
To access the form editor, click on an integration in your [connectors page](https://app.port.io/settings/data-sources) and navigate to the **Mapping** tab. If AI is enabled for your organization, an **Ask AI** button is available at the top of the editor for mapping assistance.
YAML errors may block the form editor
If your mapping YAML contains an error, the form editor may be unavailable and the YAML view will be shown first. In that case, hover over the **Edit form** button to see a description of the issue, or use **Test mapping** in the YAML view to identify it.
Each integration resource appears as a collapsible strip that you can drag and drop to reorder. Click a strip to expand and configure it. To add a new resource, click `+ Resource` at the bottom, then select a [kind](/context-lake/ingestion/configure-mapping/overview/.md#resources-and-kinds) from the list of all supported kinds for that integration.
Each resource has three configuration phases:
### Extraction[](#extraction "Direct link to Extraction")
Configure [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) to shape the API request for this resource. Selectors add parameters to the API request, changing what the API returns. They do not filter the response after it arrives.
Click `+ Selector` to see all selectors supported by the selected kind. Hover over a selector to read its description and purpose.
### Transformation[](#transformation "Direct link to Transformation")
Configure the [entity mappings](/context-lake/ingestion/configure-mapping/overview/.md#entity-mappings) for this resource. The left panel contains the mapping configuration, and the right panel shows **Raw data samples** from the integration to help write and validate JQ expressions.
**Target blueprint**
Select the blueprint to map data into from the **Target Blueprint** dropdown. Click `+ New Blueprint` to create a new blueprint directly from the mapping form - it will be created in Port and automatically selected.
**Data filter**
Filters which items from the API response are ingested. This corresponds to the [query](/context-lake/ingestion/configure-mapping/overview/.md#query) concept. Set to `true` to ingest all items, or use a JQ expression to filter specific items.
**Property mapping**
Maps API response fields to blueprint properties. Each row shows a JQ expression on the left and the target Port property on the right. Click the edit icon next to any property to open the JQ expression editor, which displays a raw data sample alongside your expression for real-time validation. If AI is enabled for your organization, the  icon appears in the top-right corner of the JQ expression editor - click it to describe in natural language what you want to calculate, and AI will generate the JQ expression for you.
Click `+ Property` to add more properties from the blueprint. To create a new property on the blueprint directly, click `+ New Property` - it will be added to the blueprint and immediately available for mapping. For more details on properties, see [setup blueprint](/context-lake/data-model/setup-blueprint/overview/.md).
**Map by property**
To find and update an entity by one of its properties instead of its identifier, click the edit icon next to the **Identifier** row. In the `Edit JQ expression` editor, toggle **Search query** in the top-right corner. This replaces the identifier with a search query rule.
For a description of this feature and its limitations, see [Map by property](/context-lake/ingestion/configure-mapping/overview/.md#map-by-property) in the mapping concepts section.
**Relation mapping**
Maps [relations](/context-lake/ingestion/configure-mapping/overview/.md#mapping-relations) between entities. Click `+ Relation` to add a relation from the blueprint. To create a new relation on the blueprint, click `+ New Relation`. For more details, see [relate blueprints](/context-lake/data-model/setup-blueprint/relate-blueprints/.md).
Each relation supports the two approaches described in [Mapping relations](/context-lake/ingestion/configure-mapping/overview/.md#mapping-relations). When editing a relation's JQ expression, toggle **Search query** in the expression editor to switch from a direct identifier reference to a search-based relation.
**Items to parse**
To create multiple entities from an array field in the API response, click the `...` menu at the bottom-right of the transformation panel and enable **Items to parse**. Three fields will appear above the property mapping section: **Items To Parse**, **Items To Parse Name**, and **Items To Parse Top Level Transform**.
For a description of each option, see [Items to parse](/context-lake/ingestion/configure-mapping/overview/.md#items-to-parse) in the mapping concepts section.
### Test[](#test "Direct link to Test")
Click **Test mapping** to run the mapping against the raw data samples and preview the resulting Port entity. The test shows results only for the current resource.
If the test fails, see [Common test errors](/context-lake/ingestion/configure-mapping/overview/.md#common-test-errors) for a description of each error and how to resolve it.
### Advanced configuration[](#advanced-configuration "Direct link to Advanced configuration")
The **Advanced Configuration** section at the bottom of the modal exposes the [advanced options](/context-lake/ingestion/configure-mapping/overview/.md#advanced-options) for the integration. Common options include:
* **Auto-create related entities**
* **Auto-delete related entities**
* **Deletion safety limit**
See the [advanced options](/context-lake/ingestion/configure-mapping/overview/.md#advanced-options) section for a description of each setting. Additional options may appear depending on the integration - refer to the integration's documentation for the full list of available options.
Once you have finished configuring the mapping, click **Save and Resync** to save your changes and trigger a full resync.
***
## YAML editor[](#yaml-editor "Direct link to YAML editor")
To access the YAML editor, click on an integration in your [connectors page](https://app.port.io/settings/data-sources), navigate to the **Mapping** tab, and click `{...} Edit YAML` in the top-right corner. The YAML editor appears in the bottom corner of the modal, with the test result panel on the right. If AI is enabled for your organization, an **Ask AI** button is available in the right corner above the YAML editor for mapping assistance.
### Extraction[](#extraction-1 "Direct link to Extraction")
This section covers the YAML keys used to control which objects are fetched from the integration's API. Some keys use [JQ queries](https://jqlang.github.io/jq/manual/) to filter the ingested data.
* The `resources` key is the root of the YAML configuration:
```
resources:
- kind: repository
...
```
* The `kind` key is a specifier for the object you wish to map from the tool's API (in this example, a Github repository).
To see which `kinds` are available for mapping, refer to the integration's documentation. In this example, the available kinds are listed in the [Github integration page](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/#port-app-configyml-structure).
```
resources:
- kind: repository
selector:
...
```
* The `selector` block can contain two types of keys:
* Integration-specific keys (e.g., `repoSearch`, `branchSearch`) that add parameters to the API request, changing what the API returns. These correspond to the [selector](/context-lake/ingestion/configure-mapping/overview/.md#selector) concept and vary by integration.
* The `query` key, a JQ expression that filters the API response after it arrives. This corresponds to the [query](/context-lake/ingestion/configure-mapping/overview/.md#query) concept and is equivalent to the **Data filter** in the form editor.
```
resources:
- kind: repository
selector:
query: "true" # JQ expression - filters objects in the API response
# Integration-specific selector parameters, for example:
includedFiles:
- README.md
- CODEOWNERS
port:
```
Using a JQ expression, you can define your desired filter conditions. For example, to ingest only repositories with a name starting with `"service"`, use the `query` key like this:
```
query: .name | startswith("service")
```
For an explanation of these concepts, see [Resources and kinds](/context-lake/ingestion/configure-mapping/overview/.md#resources-and-kinds), [Selector](/context-lake/ingestion/configure-mapping/overview/.md#selector), and [Query](/context-lake/ingestion/configure-mapping/overview/.md#query).
### Transformation[](#transformation-1 "Direct link to Transformation")
This section covers the YAML keys used to map API response fields to Port entity properties.
The `port.entity.mappings` key contains the section used to map the object fields to Port entities.
Here you can specify the `blueprint` in Port to which the data should be mapped, and which API object will be ingested to each of its properties. To map properties, specify the property identifier as the key inside the `properties` object.
```
resources:
- kind: repository
selector:
query: "true"
port:
entity:
mappings: # Mappings between one GitHub API object to a Port entity. Each value is a JQ query.
identifier: ".name"
title: ".name"
blueprint: '"service"'
properties:
description: ".description"
url: ".html_url"
defaultBranch: ".default_branch"
```
To create multiple mappings of the same kind, add another item to the `resources` array:
```
resources:
- kind: repository
selector:
query: "true"
port:
entity:
mappings: # Mappings between one GitHub API object to a Port entity. Each value is a JQ query.
identifier: ".name"
title: ".name"
blueprint: '"service"'
properties:
description: ".description"
url: ".html_url"
defaultBranch: ".default_branch"
- kind: repository # In this instance repository is mapped again with a different filter
selector:
query: '.name == "MyRepositoryName"'
port:
entity:
mappings: ...
```
For an explanation of entity mappings, see [Entity mappings](/context-lake/ingestion/configure-mapping/overview/.md#entity-mappings).
**Mapping relations**
For instance, a `Service` blueprint can be related to a `PagerDuty service` blueprint.
After ingesting all of our Services and PagerDuty services, we want to connect each `Service` to its corresponding `PagerDuty service`.
**Assigning relations automatically using the mapping configuration**
You can define the relation in the mapping file of your connector (e.g. PagerDuty) so that relations are assigned automatically during ingestion.
Here's an example:
* Go to your [connectors page](https://app.port.io/settings/data-sources) and click on the PagerDuty exporter:
* In the bottom left panel, edit the mapping YAML file, and add the following entry to it:
```
- kind: services
selector:
query: "true"
port:
entity:
mappings:
identifier: .name
blueprint: '"service"'
properties: {}
relations:
pager_duty_service: .id
```
In this mapping configuration, `pager_duty_service` is the name of the relation identifier, and `.id` is a JQ expression that extracts the identifier of the `PagerDuty service` from the ingested data.
When the data is ingested:
* If a `service` entity with the same identifier (`.name`) already exists in your catalog, Port will update it, adding the `pager_duty_service` relation and other associated data, such as the on-call property.
* If no such `service` exists, Port will create a new `service` entity with that identifier and attach the related `PagerDuty service` and the on-call property.
This configuration ensures your catalog stays up to date automatically. You can also customize the relation logic, for example, using search-based relations, depending on your naming conventions or data structure.
**Mapping relations using search queries**
In the example above we map a relation using a direct reference to the related entity's `identifier`.
Port also allows you to use a [search query rule](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules) to map relations based on a **property** of the related entity.
This is useful in cases where you don't have the identifier of the related entity, but you do have one of its properties.
For example, consider the following scenario:
Say we have a `service` blueprint that has a relation (named `service_owner`) to a `user` blueprint. The `user` blueprint has a property named `github_username`.
Now, we want to map the `service_owner` relation based on the `github_username` property of the `user` entity.
To achieve this, we can use the following mapping configuration:
```
- kind: repository
selector:
query: 'true'
port:
entity:
mappings:
identifier: .name
title: .name
blueprint: '"service"'
relations:
service_owner:
combinator: '"and"'
rules:
- property: '"github_username"'
operator: '"="'
value: .owner.login
```
Instead of directly referencing the `user` entity's `identifier`, we use a search query rule to find the `user` entity whose `github_username` property matches the `.owner.login` value returned from GitHub's API.
When using a search query rule to map a relation, Port will query all entities of the **relation's target blueprint** (in this case - `user`) and return the one/s that match the rule.
**Map by property**
In some cases, we may not know the identifier of the entity we want to map to. If that entity has a property that we do know, we can use it to map the data.
This is especially useful when patching entities whose identifiers are not known in advance. Take the following example:
* Say we installed Port's PagerDuty integration, and we want to connect each `service` (Git repository) to the relevant `PagerDuty service`.
* We can create a property in our `service` blueprint named `pagerduty_service_id`, containing the identifier of the relevant PagerDuty service.
* Then, in the `PagerDuty` integration mapping, we can use this property to map each `PagerDuty service` to the relevant `service`.
* This way, we would not need to have a separate blueprint for `PagerDuty services`, since the integration maps directly to the `service` blueprint.
Mapping by property is done using a [search query rule](/context-lake/consuming-the-lake/search-and-query/structure-and-syntax/.md#rules) in the following format:
```
resources:
- kind: services
selector:
query: 'true'
port:
entity:
mappings:
identifier:
combinator: '"and"'
rules:
- operator: '"="'
property: '"pagerduty_service_id"'
value: .id
blueprint: '"service"'
properties:
oncall: .__oncall_user | sort_by(.escalation_level) | .[0].user.email
... # Any other properties you want to map
```
In the example above, we search for a `service` entity whose `pagerduty_service_id` property is equal to the `id` of the PagerDuty service, and map data from the PagerDuty service to it.
API usage
Searching by property can also be used when using Port's API to [create an entity](/api-reference/create-an-entity/).
To avoid failures when multiple blueprints share the same property value, add a `$blueprint` rule to your search query to restrict matches to a specific blueprint:
```
combinator: "and"
rules:
- property: "$blueprint"
operator: "="
value: "service"
# your other rules...
```
**Items to parse**
**`itemsToParse`**
The following example iterates over a Jira issue's `comments` array and creates a separate `comment` entity for each comment, using `.item` to reference each element:
```
- kind: issue
selector:
query: .issueType == 'Bug'
port:
itemsToParse: .fields.comments
entity:
mappings:
identifier: .item.id
blueprint: '"comment"'
properties:
text: .item.text
author: .item.author.name
relations:
issue: .key
```
In this example, Port will iterate over each comment in the `comments` array and create a separate `comment` entity for each one. The `.item` reference allows you to access properties of the current comment being processed.
**`itemsToParseName`**
The following example uses `itemsToParseName: 'comment'` to replace the default `.item` reference, avoiding a naming conflict with a top-level `item` key in the API response:
```
- kind: issue
selector:
query: .issueType == 'Bug'
port:
itemsToParse: .fields.comments
itemsToParseName: 'comment'
entity:
mappings:
identifier: .comment.id
blueprint: '"comment"'
properties:
text: .comment.text
author: .comment.author.name
relations:
issue: .key
```
In this example, we use `comment` instead of `item` to reference each array element, avoiding conflicts with any top-level `item` property in the API response.
**`itemsToParseTopLevelTransform`**
By default, Port removes the target array specified in `itemsToParse` from the original payload to improve parsing performance. The `itemsToParseTopLevelTransform` flag controls this behavior:
* When set to `true` (default): The target array is removed from the payload, and you can only access array items via `.item` (or your custom `itemsToParseName`).
* When set to `false`: The target array remains in the payload, allowing you to access both the original array and individual items.
**Example with `itemsToParseTopLevelTransform: true` (default):**
```
- kind: issue
selector:
query: .issueType == 'Bug'
port:
itemsToParse: .fields.comments
itemsToParseTopLevelTransform: true
entity:
mappings:
identifier: .item.id
blueprint: '"comment"'
properties:
text: .item.text
issueKey: .key # Can access top-level properties
relations:
issue: .key
```
**Example with `itemsToParseTopLevelTransform: false`:**
```
- kind: issue
selector:
query: .issueType == 'Bug'
port:
itemsToParse: .fields.comments
itemsToParseTopLevelTransform: false
entity:
mappings:
identifier: .item.id
blueprint: '"comment"'
properties:
text: .item.text
totalComments: .fields.comments | length # Can access the original array
issueKey: .key
relations:
issue: .key
```
When `itemsToParseTopLevelTransform` is `false`, you can access the original array (e.g., `.fields.comments`) in addition to individual items via `.item`.
Limitations
* The `itemsToParseName` key is not supported in non-Ocean integrations: [Github app](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/), [Kubernetes](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/.md) and [Webhook integrations](/context-lake/ingestion/ingest-data-into-port/webhook/ingest-via-webhooks-overview/.md).
* When `itemsToParseName` is enabled, you cannot use the "test mapping" option in Port's UI.
The object returned from Jira for which we would apply this mapping might look like this (note the `comments` array):
**Example Jira API response (click to expand)**
```
{
"url": "https://example.com/issue/1",
"status": "Open",
"issueType": "Bug",
"comments": [
{
"id": "123",
"text": "This issue is not reproducing"
},
{
"id": "456",
"text": "Great issue!"
}
],
"assignee": "user1",
"reporter": "user2",
"creator": "user3",
"priority": "High",
"created": "2024-03-18T10:00:00Z",
"updated": "2024-03-18T12:30:00Z",
"key": "ISSUE-1"
}
```
### Test[](#test-1 "Direct link to Test")
The mapping configuration window contains a JQ playground that allows you to test your JQ queries against example responses from the API of the integrated tool. This is useful for validating your queries and ensuring they return the expected results.
For integrations based on the [Ocean framework](https://ocean.port.io/integrations-library/), examples will be automatically generated for each resource `kind` in your mapping, based on real data ingested from the tool. You can disable this behavior by setting the `sendRawDataExamples` flag to `false` in the integration's configuration.
To test your mapping against the example data, click on the `Test mapping` button in the bottom-right panel.
**Manually add test examples**
For each resource `kind` in your mapping (in the bottom-left panel), you can add an example in the `Test examples` section.
Click on the `Add kind` button to add an example:
After adding your example, click on the `Test mapping` button in the bottom-right panel to test your mapping against the example data.
If the test fails, see [Common test errors](/context-lake/ingestion/configure-mapping/overview/.md#common-test-errors) for a description of each error and how to resolve it.
Port's JQ playground
In addition to the aforementioned JQ playground, Port provides a general [JQ playground](https://jq.port.io/) where you can test any JSON snippet against JQ expressions with real-time filters and AI-powered assistance.
### Advanced configuration[](#advanced-configuration-1 "Direct link to Advanced configuration")
**Additional options**
To use the [advanced options](/context-lake/ingestion/configure-mapping/overview/.md#advanced-options), add them to the root of the mapping configuration:
```
createMissingRelatedEntities: true
deleteDependentEntities: true
entityDeletionThreshold: 0
resources:
- kind: repository
...
```
**Edit an integration's mapping**
Once you have configured an integration's mapping to your liking, click the `Resync` button in the bottom-right to save your changes.
To edit an integration's mapping using Port's API, you can use the [Patch integration](/api-reference/update-an-integration/) route.
Resync via the API
To perform a simple resync of an integration via the API without changing its mapping, use the same `Patch integration` route with the integration identifier and an empty body.
---
# Clean up stale entities
When you remove a resource type from your integration mapping or decommission an integration, the associated entities in Port are not automatically deleted. This documentation explains how to properly clean up stale entities to keep your software catalog accurate and up to date.
## When cleanup is needed[](#when-cleanup-is-needed "Direct link to When cleanup is needed")
Cleanup is typically required when you:
* Remove a `kind` from your integration mapping (for example, removing `pull-request` to stop syncing PRs).
* Delete an integration entirely.
* Rename a blueprint identifier.
* Change your mapping in a way that orphans previously synced entities.
## The 3-step cleanup process[](#the-3-step-cleanup-process "Direct link to The 3-step cleanup process")
Removing stale entities requires completing these steps in order. Skipping a step or performing them out of sequence can leave orphaned data in your catalog.
### Step 1: Remove the mapping[](#step-1-remove-the-mapping "Direct link to Step 1: Remove the mapping")
Before deleting any entities, remove the resource mapping from your integration configuration. This prevents the integration from recreating the entities on the next resync.
1. Go to your [connectors page](https://app.getport.io/settings/data-sources).
2. Click on the integration you want to modify.
3. Navigate to the **Mapping** tab.
4. Remove the entire resource block for the `kind` you no longer want to sync.
5. Click **Save & Resync**.
For example, if you no longer want to sync pull requests, remove this entire block:
```
- kind: pull-request
selector:
query: "true"
port:
entity:
mappings:
identifier: ".id | tostring"
title: ".title"
blueprint: '"pullRequest"'
properties:
# ... properties
```
Order matters
Always remove the mapping **before** deleting entities. If you delete entities first, the next integration resync will recreate them.
### Step 2: Delete the entities[](#step-2-delete-the-entities "Direct link to Step 2: Delete the entities")
Once the mapping is removed, delete the stale entities. You can do this through the UI or via the API.
* Using the UI
* Using the API
## Delete entities one by one
1. Go to the [catalog page](https://app.getport.io/services) for the relevant blueprint.
2. On the entity you want to delete click on the `...` button.
3. Click on **Unregister** button in the toolbar.
4. Confirm the deletion by clicking on **Unregister** again.
## Delete all entities of a blueprint
If you need to delete all entities of a specific blueprint:
1. Go to the catalog page for the blueprint.
2. Click the `...` menu in the top-right corner.
3. Select **Delete page**.
4. Click **Delete** to confirm the deletion.
## Delete a single entity
```
curl -X DELETE "https://api.getport.io/v1/blueprints//entities/" \
-H "Authorization: Bearer $PORT_ACCESS_TOKEN"
```
## Delete multiple entities (up to 100)
```
curl -X POST "https://api.getport.io/v1/blueprints//bulk/entities/delete" \
-H "Authorization: Bearer $PORT_ACCESS_TOKEN" \
-H "Content-Type: application/json" \
-d '{
"entities": ["entity_id_1", "entity_id_2", "entity_id_3"]
}'
```
## Delete all entities of a blueprint
To delete all entities belonging to a specific blueprint:
```
curl -X DELETE "https://api.getport.io/v1/blueprints//all-entities" \
-H "Authorization: Bearer $PORT_ACCESS_TOKEN"
```
If the entities have dependent entities (entities that reference them via required relations), add the `delete_dependents` query parameter:
```
curl -X DELETE "https://api.getport.io/v1/blueprints//all-entities?delete_dependents=true" \
-H "Authorization: Bearer $PORT_ACCESS_TOKEN"
```
Irreversible operation
Entity deletion is permanent and cannot be undone. Consider [exporting your entities](#export-before-deletion) before deleting them if you might need the data later.
### Step 3: Delete the blueprint (optional)[](#step-3-delete-the-blueprint-optional "Direct link to Step 3: Delete the blueprint (optional)")
If you no longer need the blueprint itself, delete it after all its entities have been removed.
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Find the blueprint you want to delete.
3. Click the `...` menu on the blueprint card.
4. Select **Delete blueprint**.
5. Type **DELETE** and click on `Delete` to confirm the deletion.
Blueprint deletion requirements
You can only delete a blueprint if:
* It has no remaining entities.
* No other blueprints have required relations pointing to it.
If other blueprints reference this blueprint, update or remove those relations first.
When you delete a blueprint, Port also deletes any associated catalog pages that were automatically created for that blueprint.
## Export before deletion[](#export-before-deletion "Direct link to Export before deletion")
Before deleting entities, you may want to export them for backup or audit purposes.
* Using the UI
* Using the API
1. Go to the catalog page for the blueprint.
2. Click the **Export** button in the toolbar.
3. Choose your export format (CSV or JSON) to download the file.
Use the search endpoint to retrieve all entities of a blueprint:
```
curl -X POST "https://api.getport.io/v1/entities/search" \
-H "Authorization: Bearer $PORT_ACCESS_TOKEN" \
-H "Content-Type: application/json" \
-d '{
"combinator": "and",
"rules": [
{
"property": "$blueprint",
"operator": "=",
"value": ""
}
]
}' > entities_backup.json
```
## Handle dependent entities[](#handle-dependent-entities "Direct link to Handle dependent entities")
When deleting entities that are referenced by other entities through relations, you have two options:
### Option 1: Auto-delete dependent entities[](#option-1-auto-delete-dependent-entities "Direct link to Option 1: Auto-delete dependent entities")
Use the `delete_dependents` parameter to automatically delete entities that depend on the ones you're deleting:
```
curl -X DELETE "https://api.getport.io/v1/blueprints//all-entities?delete_dependents=true" \
-H "Authorization: Bearer $PORT_ACCESS_TOKEN"
```
### Option 2: Update relations first[](#option-2-update-relations-first "Direct link to Option 2: Update relations first")
Manually update or remove the relations in dependent entities before deleting:
1. Identify which entities reference the entities you want to delete.
2. Update those entities to remove or change the relation values.
3. Then delete the original entities.
## Mapping configuration options[](#mapping-configuration-options "Direct link to Mapping configuration options")
Port provides configuration options to control automatic entity deletion during integration resyncs.
### deleteDependentEntities[](#deletedependententities "Direct link to deleteDependentEntities")
When enabled, Port automatically deletes dependent entities when their parent entity is removed during a resync. Add this to your mapping configuration:
```
deleteDependentEntities: true
resources:
- kind: repository
# ...
```
This option only controls deletion through required dependent relations. Setting it to `false` does not disable standard reconciliation cleanup and does not preserve an auto-created related entity that Port identifies as stale.
For details about entities created by `createMissingRelatedEntities`, including how to preserve them independently, see [auto-created related entities during reconciliation](/context-lake/ingestion/configure-mapping/overview/.md#auto-created-related-entities-during-reconciliation).
### entityDeletionThreshold[](#entitydeletionthreshold "Direct link to entityDeletionThreshold")
Controls whether the integration's deletion mechanism is active. Set to `0` to disable automatic deletion or `1` to enable it:
```
entityDeletionThreshold: 1
resources:
- kind: repository
# ...
```
### enableDelete[](#enabledelete "Direct link to enableDelete")
`enableDelete` is an optional boolean on each item in the mapping `resources` list (same level as `kind`, `selector`, and `port`).
When cleanup is on, a resync can delete catalog entities that no longer appear in the integration data.
Set `enableDelete` to `false` on a resource if you still want that data synced into Port, but you do **not** want those entities deleted during cleanup.
Typical use case: the source occasionally returns an empty list (outage, filter change, partial sync) and you do not want Port to remove everything that was already in the catalog.
| Value | Cleanup behavior |
| ---------------- | ------------------------------------------------------------------------------------------------------------------------------ |
| `true` / omitted | Entities of that resource’s blueprint **can be deleted** if they are missing from the resync (default). |
| `false` | Entities of that resource’s blueprint are **not deleted** during cleanup. New and updated entities are still written normally. |
Cleanup uses the Port **blueprint** from the mapping (`blueprint: '"…"'`), not the integration `kind` name. The flag protects that blueprint.
**Conflicting `enableDelete` values on the same blueprint**
If **two (or more) resources map to the same static blueprint** and set conflicting `enableDelete` values:
| Resource A | Resource B | Same blueprint? | Resync cleanup deletes for that blueprint |
| ---------------- | ---------------- | --------------- | -------------------------------------------- |
| `false` | `true` / omitted | Yes | **No** |
| `false` | `false` | Yes | **No** |
| `true` / omitted | `true` / omitted | Yes | **Yes** (if `entityDeletionThreshold` is on) |
One `enableDelete: false` is enough. Another resource that maps to the **same** blueprint with `enableDelete: true` does **not** turn deletes back on for that blueprint.
Cleanup ownership is per blueprint, not per mapping row
Cleanup ownership is per integration + blueprint: Port stores one set of entities for that blueprint from the integration. There is no separate “delete bucket” per `kind` / mapping row when several rows write to the same blueprint. To allow deletes again, set every resource that maps to that blueprint to `enableDelete: true` (or omit the flag), or split them onto different blueprints.
**Interaction with `entityDeletionThreshold`**
| `entityDeletionThreshold` | `enableDelete` | Resync cleanup deletes for that blueprint |
| ------------------------- | ---------------- | ----------------------------------------------------------------------------- |
| off (`0`) | any | No |
| on (`1`) | `true` / omitted | Yes (unless another resource protects the same blueprint, as described above) |
| on (`1`) | `false` | No |
`enableDelete: true` does **not** re-enable deletes when `entityDeletionThreshold` is `0`.
**Interaction with `deleteDependentEntities`**
When any resource has `enableDelete: false` with a static blueprint literal, Port also turns off cascade deletes (`deleteDependentEntities`) for that resync’s cleanup. That way a related parent deleted in the same cleanup run cannot remove a protected blueprint as a dependent.
**YAML example**
Different blueprints - each resource controls its own blueprint:
**Different blueprints example (click to expand)**
```
entityDeletionThreshold: 1
resources:
- kind: namespace
enableDelete: false # namespace blueprint: no cleanup deletes
selector:
query: "true"
port:
entity:
mappings:
identifier: .metadata.uid
title: .metadata.name
blueprint: '"namespace"'
- kind: application
# enableDelete omitted → true → argocdApplication may be cleaned up
selector:
query: "true"
port:
entity:
mappings:
identifier: .metadata.uid
title: .metadata.name
blueprint: '"argocdApplication"'
```
Same blueprint - protect wins (entities of `service` are **not** deleted):
**Same blueprint example (click to expand)**
```
entityDeletionThreshold: 1
resources:
- kind: service
enableDelete: false
selector:
query: '.type == "api"'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"service"'
- kind: service
# true / omitted does NOT override the false above
selector:
query: '.type == "worker"'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"service"'
```
**Limitations**
* Configure `enableDelete` in the **YAML** mapping editor. There is no dedicated form-editor toggle in the current release.
* Applies to **resync / reconciliation cleanup** only. Live or webhook-driven deletes are not controlled by this flag.
* Protection matches **static** blueprint string literals only (for example `blueprint: '"namespace"'`). Dynamic JQ blueprint expressions are not protected.
For related global options, see [Configure mapping - Advanced options](/context-lake/ingestion/configure-mapping/overview/.md#advanced-options).
## Troubleshooting[](#troubleshooting "Direct link to Troubleshooting")
### Entities reappear after deletion[](#entities-reappear-after-deletion "Direct link to Entities reappear after deletion")
If entities reappear after you delete them, the integration mapping still includes the resource type. Make sure you:
1. Removed the `kind` from the mapping configuration.
2. Saved and resynced the integration.
3. Then deleted the entities.
### Cannot delete blueprint[](#cannot-delete-blueprint "Direct link to Cannot delete blueprint")
If you cannot delete a blueprint, check for:
* **Remaining entities**: Delete all entities of the blueprint first.
* **Incoming relations**: Other blueprints may have relations pointing to this blueprint. Update or remove those relations first.
### Dependent entities blocking deletion[](#dependent-entities-blocking-deletion "Direct link to Dependent entities blocking deletion")
If you receive an error about dependent entities:
* Use the `delete_dependents=true` parameter in your API call.
* Or manually remove the relations from dependent entities first.
---
# Configure mapping
The mapping of an integration's connector defines the ingested data and its destination. It allows you to specify:
* **Which data** you wish to ingest from the integrated tool.
* **Which properties** in the integration's blueprints will be filled with the ingested data.
## How does mapping work?[](#how-does-mapping-work "Direct link to How does mapping work?")
Integration mapping is configured in the [connectors page](https://app.port.io/settings/data-sources) of your portal, under `Exporters`.
Each integration has its own mapping, which can be edited via a YAML editor or a visual form.
To understand how mapping works, let's take a look at an example. After you complete the [onboarding](/getting-started/overview/.md) and connect your Git provider to Port, you will see an exporter entry in your [connectors page](https://app.port.io/settings/data-sources):
Clicking on this entry will open a modal. Click the **Mapping** tab to view and edit the mapping configuration.
From there, you can click `{...} Edit YAML` to open the YAML editor, or use the form editor to configure the mapping through a visual interface.
Note that Port provides default mapping, providing values to the properties defined in the relevant blueprint:
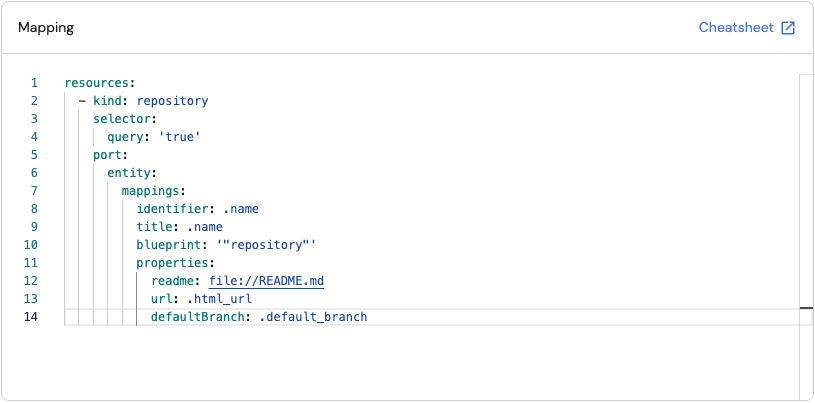
Port provides two ways to configure the mapping:
* [Form editor](/context-lake/ingestion/configure-mapping/configuration-methods/.md#form-editor) - a visual, guided experience.
* [YAML editor](/context-lake/ingestion/configure-mapping/configuration-methods/.md#yaml-editor) - a code-based configuration.
## Mapping concepts[](#mapping-concepts "Direct link to Mapping concepts")
The following concepts are the building blocks of a mapping configuration. They apply to both editors - understanding them once lets you work fluently in either.
### Resources and kinds[](#resources-and-kinds "Direct link to Resources and kinds")
A resource represents one type of data to fetch and map. Each resource specifies a **kind** - the API object type to fetch (e.g., `repository`, `pull-request`, `issue`).
Resources are processed **sequentially from top to bottom**. This means:
* The first resource is fetched and ingested before the second one starts.
* If you have relations between entities (e.g., pull requests referencing repositories), list the **target blueprint first** so those entities exist before the relation is created.
* For large datasets, the order can affect sync duration since each resource must complete before the next begins.
A mapping can contain multiple resources of the same kind with different filters, allowing you to map the same API object to different blueprints or with different property values.
### Selector[](#selector "Direct link to Selector")
Selectors belong to the **Extraction** phase. They modify the API request by adding query parameters or other parameters that change what the API returns. Unlike the `query` filter, selectors act on the request - not the response.
Available selectors vary per integration, based on the API capabilities of the integrated tool. Using selectors to narrow what the API returns can **reduce sync time** and **help avoid hitting API rate limits**.
### Query[](#query "Direct link to Query")
The `query` field belongs to the **Transformation** phase. It accepts a JQ expression evaluated against each object returned by the API:
* If the expression evaluates to `true`, the object is ingested.
* If it evaluates to `false`, the object is skipped.
Set `query` to `"true"` to ingest all objects, or use a JQ expression to filter specific objects. This field is called **Data filter** in the form editor. In YAML, it appears as `query` inside the `selector` block - but unlike other selector keys, it filters the API response rather than modifying the request.
### Entity mappings[](#entity-mappings "Direct link to Entity mappings")
Entity mappings define how fields from the API response are translated into Port entity properties. For each resource, you specify a target blueprint, how to derive the entity's identifier and title, which API fields map to which blueprint properties, and optionally which relations to populate.
The exact structure of entity mappings differs between the two editors - see [Transformation](/context-lake/ingestion/configure-mapping/configuration-methods/.md#transformation) in the form editor section and [Transformation](/context-lake/ingestion/configure-mapping/configuration-methods/.md#transformation-1) in the YAML editor section.
JQ syntax for identifiers with hyphens
When using JQ to reference identifiers or property names that contain hyphens, you must wrap them in double quotes and use bracket notation.
For example, use `.["my-property"]` instead of `.my-property`, which JQ interprets as subtraction.
This applies to secrets, properties, and any other identifiers containing hyphens:
* Secrets: `.secrets["zendesk-api-token"]`
* Properties: `.properties["my-custom-field"]`
* Relations: `.relations["parent-service"]`
### Mapping relations[](#mapping-relations "Direct link to Mapping relations")
In Port, [relations](/context-lake/data-model/setup-blueprint/relate-blueprints/.md) define how [blueprints](/context-lake/data-model/setup-blueprint/overview/.md) are connected to one another. The mapping configuration lets you populate these relations automatically during ingestion.
There are two ways to reference a related entity in a mapping:
* **Direct identifier reference** - provide the related entity's identifier as a JQ expression. Use this when the API response contains the identifier of the related entity.
* **Search query** - find the related entity by matching one of its properties. Use this when you don't have the identifier directly, but know a property value that uniquely identifies it.
**Limitations for search query relations**
* A ["single type" relation](/context-lake/data-model/setup-blueprint/relate-blueprints/.md#bust_in_silhouette-single) expects a single entity to be returned. A ["many type" relation](/context-lake/data-model/setup-blueprint/relate-blueprints/.md#-many) expects an array.
* The maximum number of entities returned is 500.
* Calculation properties are not supported.
* Mirror properties are supported only for single type relations, one level deep.
* Only the `=`, `in`, and `contains` operators are supported.
* The search is scoped to the relation's target blueprint - it will not match entities from other blueprints, even if they have a matching property value.
**Manually assigning relations in the UI**
You can also assign relations manually without touching the mapping configuration:
1. Go to the relevant catalog page (e.g., [services](https://app.port.io/services)).
2. Hover over an entity, click `...`, and select **Edit**.
3. In the relation field, select the related entity from the dropdown, then click **Update**.
**Relation values are overwritten on every sync**
Every time an integration syncs an entity, the relation value in Port is **replaced** with whatever the mapping returns. Port does not merge or append relation values across syncs or across different integrations.
This has two important implications:
1. **If your JQ returns an empty array** (e.g. because a filter excludes all items), Port will clear that relation - removing any previously set values.
2. **If two integrations both write to the same relation**, the last sync to run wins. The other integration's values are overwritten.
The mapping expression must therefore return the **complete desired set** of relation identifiers every time it runs.
**Workarounds:**
* **Merge all sources in one mapping:** Use a single integration that queries all sources and returns the merged set in the JQ expression.
* **Manage the relation manually:** Exclude the relation from the integration's mapping entirely by omitting it from the `relations` block, and assign values manually in Port's UI.
* **Use an automation to append:** Create a [Port automation](/workflows/actions-and-automations/define-automations/examples/.md#add-to-a-relation-without-overwriting-existing-values) that reacts to entity changes and uses JQ array concatenation to append new values while preserving existing ones.
### Map by property[](#map-by-property "Direct link to Map by property")
In some cases you may not know the identifier of the entity you want to map to, but you do know one of its properties. Instead of a direct identifier, you can use a search query rule in the `identifier`, `team`, or `relation` fields to find and update the entity by that property. Search query mapping is only supported for these three fields.
This is useful when you want to map data directly to an existing entity without needing a separate blueprint. For example, a PagerDuty integration can map directly to a `service` entity using a `pagerduty_service_id` property, without a separate `PagerDuty service` blueprint.
**Limitations**
* The search query must return **exactly one entity** - otherwise the entire request will fail.
To avoid failures from identical property values across multiple blueprints, include an additional rule filtering by `$blueprint`.
* If the search query returns no entities, a new entity **will not** be created.
* The query is executed on the same blueprint from the request's URL.
* Only the `=` and `in` operators are supported.
* `Calculation` and `mirror` properties are not supported.
API usage
Searching by property can also be used when using Port's API to [create an entity](/api-reference/create-an-entity/).
### Items to parse[](#items-to-parse "Direct link to Items to parse")
When the API returns an array that you want to expand into multiple separate Port entities, use items to parse. Port iterates over the array and creates one entity per item.
There are three related options:
* **`itemsToParse`** - a JQ expression pointing to the array in the API response. Each element in the array becomes a separate entity.
* **`itemsToParseName`** - a custom name for referencing each array element. Use this when your API response already has a top-level key that conflicts with the default name.
* **`itemsToParseTopLevelTransform`** - controls whether the target array is removed from the payload during iteration. When `true` (default), the array is removed. When `false`, the original array remains accessible alongside individual items.
**Limitations**
* `itemsToParseName` is not supported in non-Ocean integrations: [Github app](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/), [Kubernetes](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/.md), and [Webhook integrations](/context-lake/ingestion/ingest-data-into-port/webhook/ingest-via-webhooks-overview/.md).
* When `itemsToParseName` is enabled, you cannot use the "test mapping" option in Port's UI.
### Advanced options[](#advanced-options "Direct link to Advanced options")
These options apply globally across all resources in a mapping configuration. In the YAML editor they are set at the root level, in the form editor they appear under **Advanced Configuration**.
| UI label | YAML key | Description |
| ---------------------------- | ------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Auto-create related entities | `createMissingRelatedEntities` | Automatically creates missing related entities during ingestion. Useful when creating an entity whose related entity does not yet exist in Port. |
| Auto-delete related entities | `deleteDependentEntities` | Deletes dependent Port entities when a related entity is removed. Required when two blueprints have a required relation and the source entity must be deleted alongside the target. |
| Deletion prevention flag | `entityDeletionThreshold` | Accepts 2 values (0 or 1) that controls if the deletion mechanism of the integration would be activated or not (0 means disabled and 1 is enabled) |
#### Per-resource delete control[](#per-resource-delete-control "Direct link to Per-resource delete control")
Set on each item under `resources[]` in the YAML mapping (not at the root level):
`enableDelete` (optional, default `true`) controls whether resync cleanup can delete this resource's entities:
* `true` / omitted: entities can be deleted during resync cleanup.
* `false`: entities are synced and updated, but not deleted during resync cleanup.
`enableDelete` is scoped by blueprint, not by resource
If another resource maps to the same blueprint with `enableDelete: true` (or omits the key), deletes stay off for that blueprint, protect wins. While protect is on, the `deleteDependentEntities` cascade is also off for that cleanup. See [enableDelete](/context-lake/ingestion/configure-mapping/entity-cleanup/.md#enabledelete) for the full behavior and examples.
Additional options may be available depending on the integration. Refer to the specific integration's documentation for the full list.
Auto-create related entities in protected blueprints
The **Auto-create related entities** option cannot be used to create entities in protected blueprints such as `_user` and `_team`.
#### Auto-created related entities during reconciliation[](#auto-created-related-entities-during-reconciliation "Direct link to Auto-created related entities during reconciliation")
When `createMissingRelatedEntities` is set to `true`, Port creates a minimal related entity when a mapping references an entity that does not exist. This entity, sometimes called a skeleton entity, uses the referenced identifier for its identifier and title, along with any default blueprint properties.
Port associates the skeleton entity with an auto-managed data source derived from the integration. This association makes the entity part of the integration's reconciliation scope.
During a full resync, Port protects a skeleton entity while at least one entity successfully ingested in that resync still references it. If the referencing entity fails to ingest and reconciliation continues, the skeleton entity is no longer protected and may be deleted as stale. This risk applies to partial or entity-level failures where reconciliation still runs. Port does not perform stale entity cleanup when reconciliation is aborted.
Auto-created related entities can be deleted
Setting `deleteDependentEntities` to `false` does not protect skeleton entities from reconciliation cleanup. This option only controls whether Port can delete entities through required dependent relations. It does not disable the direct deletion of an entity that reconciliation identifies as stale.
To preserve a related entity independently of an integration:
* Ingest it from a separate integration, pipeline, API request, or manual catalog operation before the integration references it. The entity then has a different data source and is not part of this integration's stale entity cleanup unless the integration later manages it directly.
* Set `entityDeletionThreshold` to `0` if you need to disable all automatic entity deletion for the integration. This also prevents cleanup of other entities that disappear from the source.
Integrations operate as machine identities, so blueprint entity permissions do not restrict their reconciliation operations. Follow the principle of least privilege when granting additional organization-level permissions. Admin permissions broaden what an integration can access, but they are not required for reconciliation to delete entities associated with that integration's data source.
### JQ runtime[](#jq-runtime "Direct link to JQ runtime")
Port's JQ runtime runs in **UTC**. This affects any time-based JQ functions you use in your mapping, such as `now`, `todate`, `strftime`, and `strptime`.
When writing JQ expressions that reference the current time or calculate relative durations, assume the server clock is UTC:
```
# Get the current time as a UTC ISO string
now | todate
# Output: "2024-04-15T10:30:00Z"
# Calculate days since last update (assuming .updated_at is an ISO string)
(now - (.updated_at | sub("\\.[0-9]+Z$"; "Z") | strptime("%Y-%m-%dT%H:%M:%SZ") | mktime)) / 86400 | floor
```
Local timezone offsets
If your source data contains timestamps with a non-UTC offset (e.g. `2024-04-15T12:30:00+02:00`), you must normalize them to UTC before comparing against `now` or using Port's datetime property format. Port stores and displays all datetime values in UTC.
### Common test errors[](#common-test-errors "Direct link to Common test errors")
When running **Test mapping**, you may come across one of the following errors:
* **`Missing kind example for {kind}`**
Cause: No example data is available for this resource kind.
Resolution: Add example data for the missing kind.
* **`Selector query is false or evaluated to false`**
Cause: The data filter expression returned `false` for the example data.
Resolution: Update your JQ expression or use an example that matches your filter.
* **`must NOT have additional properties, additional property: "[property]"`**
Cause: The mapping YAML contains an unrecognized field, often due to a typo.
Resolution: Check for typos in your field names and ensure they match the expected mapping schema.
* **`Blueprint with identifier "[identifier]" was not found`**
Cause: The blueprint identifier referenced in the mapping does not exist in your portal.
Resolution: Verify the identifier matches an existing blueprint in your portal.
---
# Advanced
The following advanced query parameters are available:
* Delete Dependents
* Create Missing Related Entities
The `delete_dependents` query parameter is used to enable the deletion of dependent Port entities. This is useful when you have two blueprints with a required relation, and the target entity in the relation should be deleted. In this scenario, the delete operation will fail if this flag is set to `false`, if the flag is set to `true`, the source entity will be deleted as well.
* Available at `DELETE` API endpoint of a specific entity.
* Default: `false` (disabled)
* Use case: Deletion of dependent Port entities. Must be enabled if you want to delete a target entity (and its source entities) when the entity's blueprint has required relations.
The `create_missing_related_entities` parameter is used to enable the creation of missing related Port entities. This is useful when you want to create an entity and its related entity in one call, or if you want to create an entity that its related entity does not exist yet.
In both of these scenarios, the resulting *related* entity will be a barebones entity which you can later on update with relevant information as usual.
* Available at `POST`, `PUT`, `PATCH` API endpoints of a specific entity.
* Default: `false` (disabled)
* Use case: Creation of missing related Port entities. Must be enabled, if you want to create a source entity (and its target related entity) even though the target entity doesn't exist.
---
# CI/CD
By using Port's CI/CD integrations you can always keep your software catalog up to date by making updates directly from your CI/CD.
In addition, you can use Port as a source-of-truth and use values saved in Port for configurations, variables and other programmatic resources for your CI/CD pipelines as they are running.
## Available CI/CD integrations[](#available-cicd-integrations "Direct link to Available CI/CD integrations")
## [🗃GitHub Workflow](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/github-workflow/.md)
[1 item](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/github-workflow/.md)
## [🗃Codefresh Workflow](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/codefresh-workflow-template/.md)
[1 item](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/codefresh-workflow-template/.md)
## [🗃Jenkins Deployment](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/jenkins-deployment/.md)
[1 item](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/jenkins-deployment/.md)
## [🗃CircleCI Deployment](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/circleci-workflow/.md)
[1 item](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/circleci-workflow/.md)
## [🗃Azure Pipelines](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/azure-pipelines/.md)
[1 item](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/azure-pipelines/.md)
## [🗃Gitlab Pipelines](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/gitlab-pipelines/.md)
[1 item](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/gitlab-pipelines/.md)
---
# Azure Pipelines
Using Azure Pipelines, you can easily create/update and query entities in Port.
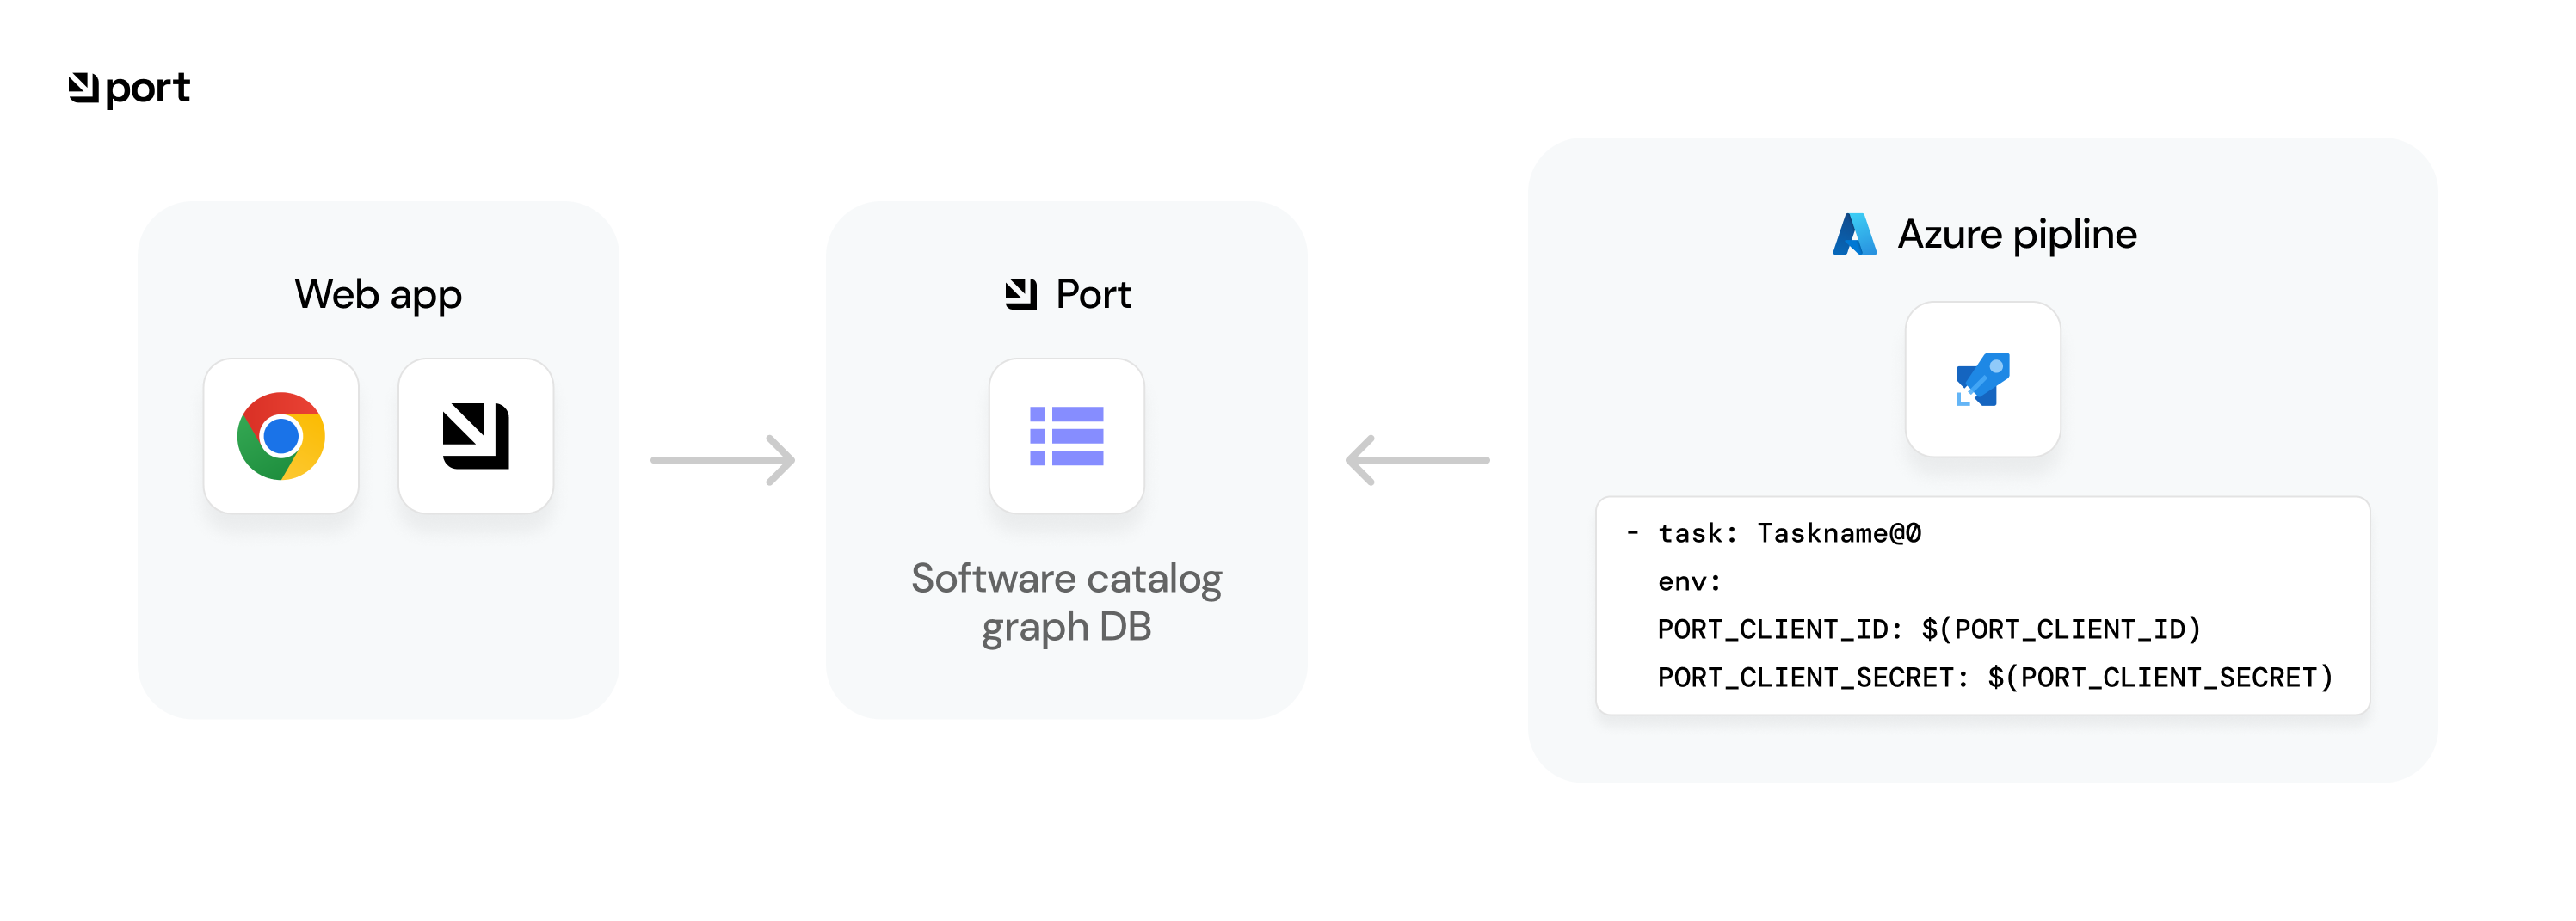
## 💡 Common Azure Pipelines usage[](#-common-azure-pipelines-usage "Direct link to 💡 Common Azure Pipelines usage")
Port's API allows for easy integration between Port and your Azure Pipeline jobs, for example:
* Report the status of a running **CI job**.
* Update the software catalog about a new **build version** for a **microservice**.
* Get existing **entities**.
## Setup[](#setup "Direct link to Setup")
To interact with Port using Azure Pipelines, you will first need to [define your Port credentials](https://learn.microsoft.com/en-us/azure/devops/pipelines/process/set-secret-variables?view=azure-devops\&tabs=yaml%2Cbash#secret-variable-in-the-ui) as variables for your pipeline. Then, pass the defined variables to your pipeline script, for example, `Python`:
```
- task: PythonScript@0
env:
PORT_CLIENT_ID: $(PORT_CLIENT_ID) # The variable name for your Port clientId
PORT_CLIENT_SECRET: $(PORT_CLIENT_SECRET) # The variable name for your Port clientSecret
inputs:
scriptSource: "filePath"
scriptPath: "main.py"
```
Make sure you have an existing [Blueprint](/context-lake/data-model/setup-blueprint/overview/.md) in your Port installation to create/update entities.
## Working with Port's API[](#working-with-ports-api "Direct link to Working with Port's API")
Here is an example snippet showing how to integrate a job that uses Port's API with your existing Azure pipelines using Python:
Add the following task to your Azure pipeline:
**Azure pipeline YAML (click to expand)**
```
- script: |
pip install -r port_requirements.txt
- task: PythonScript@0
env:
PORT_CLIENT_ID: $(PORT_CLIENT_ID)
PORT_CLIENT_SECRET: $(PORT_CLIENT_SECRET)
inputs:
scriptSource: "filePath"
scriptPath: "port.py"
```
Python dependencies required
In the following example, we use Python modules which need to be installed. You can use the following `requirements.txt`:
**port\_requirements.txt (click to expand)**
```
requests>=2.28.2
```
* Create/Update
* Get
Create the following Python script in your repository to create or update Port entities as part of your pipeline:
```
import os
import requests
import json
# These are the credentials passed by the variables of your pipeline to your tasks and in to your env
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
entity_json = {
"identifier": "example-entity",
"properties": {
"myStringProp": "My value",
"myNumberProp": 1,
"myBooleanProp": true,
"myArrayProp": ["myVal1", "myVal2"],
"myObjectProp": {"myKey": "myVal", "myExtraKey": "myExtraVal"}
}
}
# request url : {API_URL}/blueprints//entities
create_response = requests.post(f'{API_URL}/blueprints/test-blueprint/entities?upsert=true', json=entity_json, headers=headers)
print(json.dumps(create_response.json(), indent=4))
```
Create the following Python script in your repository to get Port entities as part of your pipeline:
```
import os
import requests
import json
# These are the credentials passed by the variables of your pipeline to your tasks and in to your env
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
# request url : {API_URL}/blueprints//entities/
get_response = requests.get(f"{API_URL}/blueprints/test-blueprint/entities/test-entity", headers=headers)
print(json.dumps(get_response.json(), indent=4))
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Examples[](#examples "Direct link to Examples")
Refer to the [examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/azure-pipelines/examples/.md) page for practical examples of working with Port using Azure Pipelines.
---
# Examples
## Basic create/update example[](#basic-createupdate-example "Direct link to Basic create/update example")
In this example you will create blueprints for `ciJob` and `image` entities, and a relation between them. Then you will add some Python code to create new entities in Port every time the Azure Pipeline is triggered:
**Image blueprint (click to expand)**
Create in Port
```
{
"identifier": "image",
"title": "Image",
"icon": "Docker",
"schema": {
"properties": {
"synkHighVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk High Vaulnerabilities"
},
"synkMediumVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk Medium Vaulnerabilities"
},
"imageTag": {
"type": "string",
"title": "Image Tag"
},
"gitRepoUrl": {
"type": "string",
"format": "url",
"title": "Git Url",
"description": "Git Url for the sourcecode"
},
"imageRegistry": {
"type": "string",
"format": "url",
"title": "Image Registry",
"description": "Docker registry"
},
"unitTestCoverage": {
"type": "number",
"title": "Unit Test coverage (%)",
"description": "The unit test coverage pecentage"
},
"integTestCoverage": {
"type": "number",
"title": "Integ Test coverage (%)",
"description": "The integration test coverage pecentage"
},
"size": {
"type": "number",
"title": "Image Size (GB)",
"description": "The image size in Gigabyte"
}
},
"required": []
},
"calculationProperties": {}
}
```
**CI Job blueprint (including the image relation) (click to expand)**
Create in Port
```
{
"identifier": "ciJob",
"title": "CI Job",
"icon": "CICD",
"schema": {
"properties": {
"triggeredBy": {
"type": "string",
"icon": "TwoUsers",
"title": "Triggered By",
"description": "The user who triggered the run"
},
"commitHash": {
"type": "string",
"title": "Commit Hash"
},
"jobBranch": {
"type": "string",
"icon": "Git",
"format": "url",
"title": "Job branch"
},
"runLink": {
"type": "string",
"format": "url",
"title": "Action Run Link"
}
},
"required": []
},
"relations": {
"image": {
"title": "Job Images",
"target": "image",
"required": false,
"many": true
}
},
"calculationProperties": {}
}
```
After creating the blueprints, you can add a Python script for creating/updating a Port entity:
```
import os
import requests
import json
# Env vars passed by the pipeline variables
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
API_URL = 'https://api.port.io/v1'
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
# use this access token + header for all http requests to Port
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
entity_json = {
"identifier": "new-cijob-run",
"properties": {
"triggeredBy": os.environ['QUEUED_BY'],
"commitHash": os.environ['GIT_SHA'],
"actionJob": os.environ['JOB_NAME'],
"jobLink": os.environ['JOB_URL']
},
"relations": {
"image": ["example-image"]
}
}
create_response = requests.post(f'{API_URL}/blueprints/{blueprint_id}/entities?upsert=true&create_missing_related_entities=true', json=entity_json, headers=headers)
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Relation auto-created
Please notice that you have also created the `image` relation, and added a related image entity called `example-image`. This is the artifact of the ciJob, and you will update it later. The creation was done using the `create_missing_related_entities=true` flag in the API url, allowing the relation to be created even though the `example-image` entity doesn't exist yet.
After adding your new Python script to your repository, add the following code to your Azure pipeline `yml` file to call your script and update/create a new `ciJob` entity:
```
steps:
# ... other tasks and steps
- script: |
pip install -r port_requirements.txt
- task: PythonScript@0
env:
PORT_CLIENT_ID: $(PORT_CLIENT_ID)
PORT_CLIENT_SECRET: $(PORT_CLIENT_SECRET)
QUEUED_BY: $(Build.QueuedBy)
GIT_SHA: $(Build.SourceVersion)
JOB_NAME: $(Build.DefinitionName)
JOB_URL: "$(System.TeamFoundationCollectionUri)$(System.TeamProject)/_build/results?buildId=$(Build.BuildId)"
inputs:
scriptSource: "filePath"
scriptPath: "main.py"
```
## Basic get example[](#basic-get-example "Direct link to Basic get example")
The following example gets the `new-cijob-run` entity from the previous example, this can be useful if your CI process creates a build artifact and then references some of its data (for example, the run link of the latest `ciJob`).
Add the following snippet to your Python code:
```
entity_id = "new-cijob-run"
blueprint_id = "ciJob"
get_response = requests.get(f"{API_URL}/blueprints/{blueprint_id}/entities/{entity_id}",
headers=headers)
entity = get_response.json()['entity']
print(f"Image tag is: {entity['properties']['runLink']}")
```
## Relation example[](#relation-example "Direct link to Relation example")
The following example demonstrates how to update the `example-image` entity that was automatically created when creating the `ciJob` entity shown in the previous example.
Add the following snippet to your Python code:
```
image_entity_json = {
"identifier": "example-image",
"team": [],
"properties": {
"imageTag": "v1",
"synkHighVulnerabilities": "0",
"synkMediumVulnerabilities": "0",
"gitRepoUrl": "https://github.com/my-org/my-cool-repo",
"imageRegistry": "docker.io/cool-image",
"size": "0.71",
"unitTestCoverage": "20",
"unitTestCoverage": "50"
},
"relations": {}
}
create_image_response = requests.post(f'{API_URL}/blueprints/image/entities?upsert=true', json=image_entity_json, headers=headers)
```
That's it! The entity is created or updated and is visible in the UI.
---
# CircleCI workflows
Using CircleCI workflows, you can easily create/update and query entities in Port.
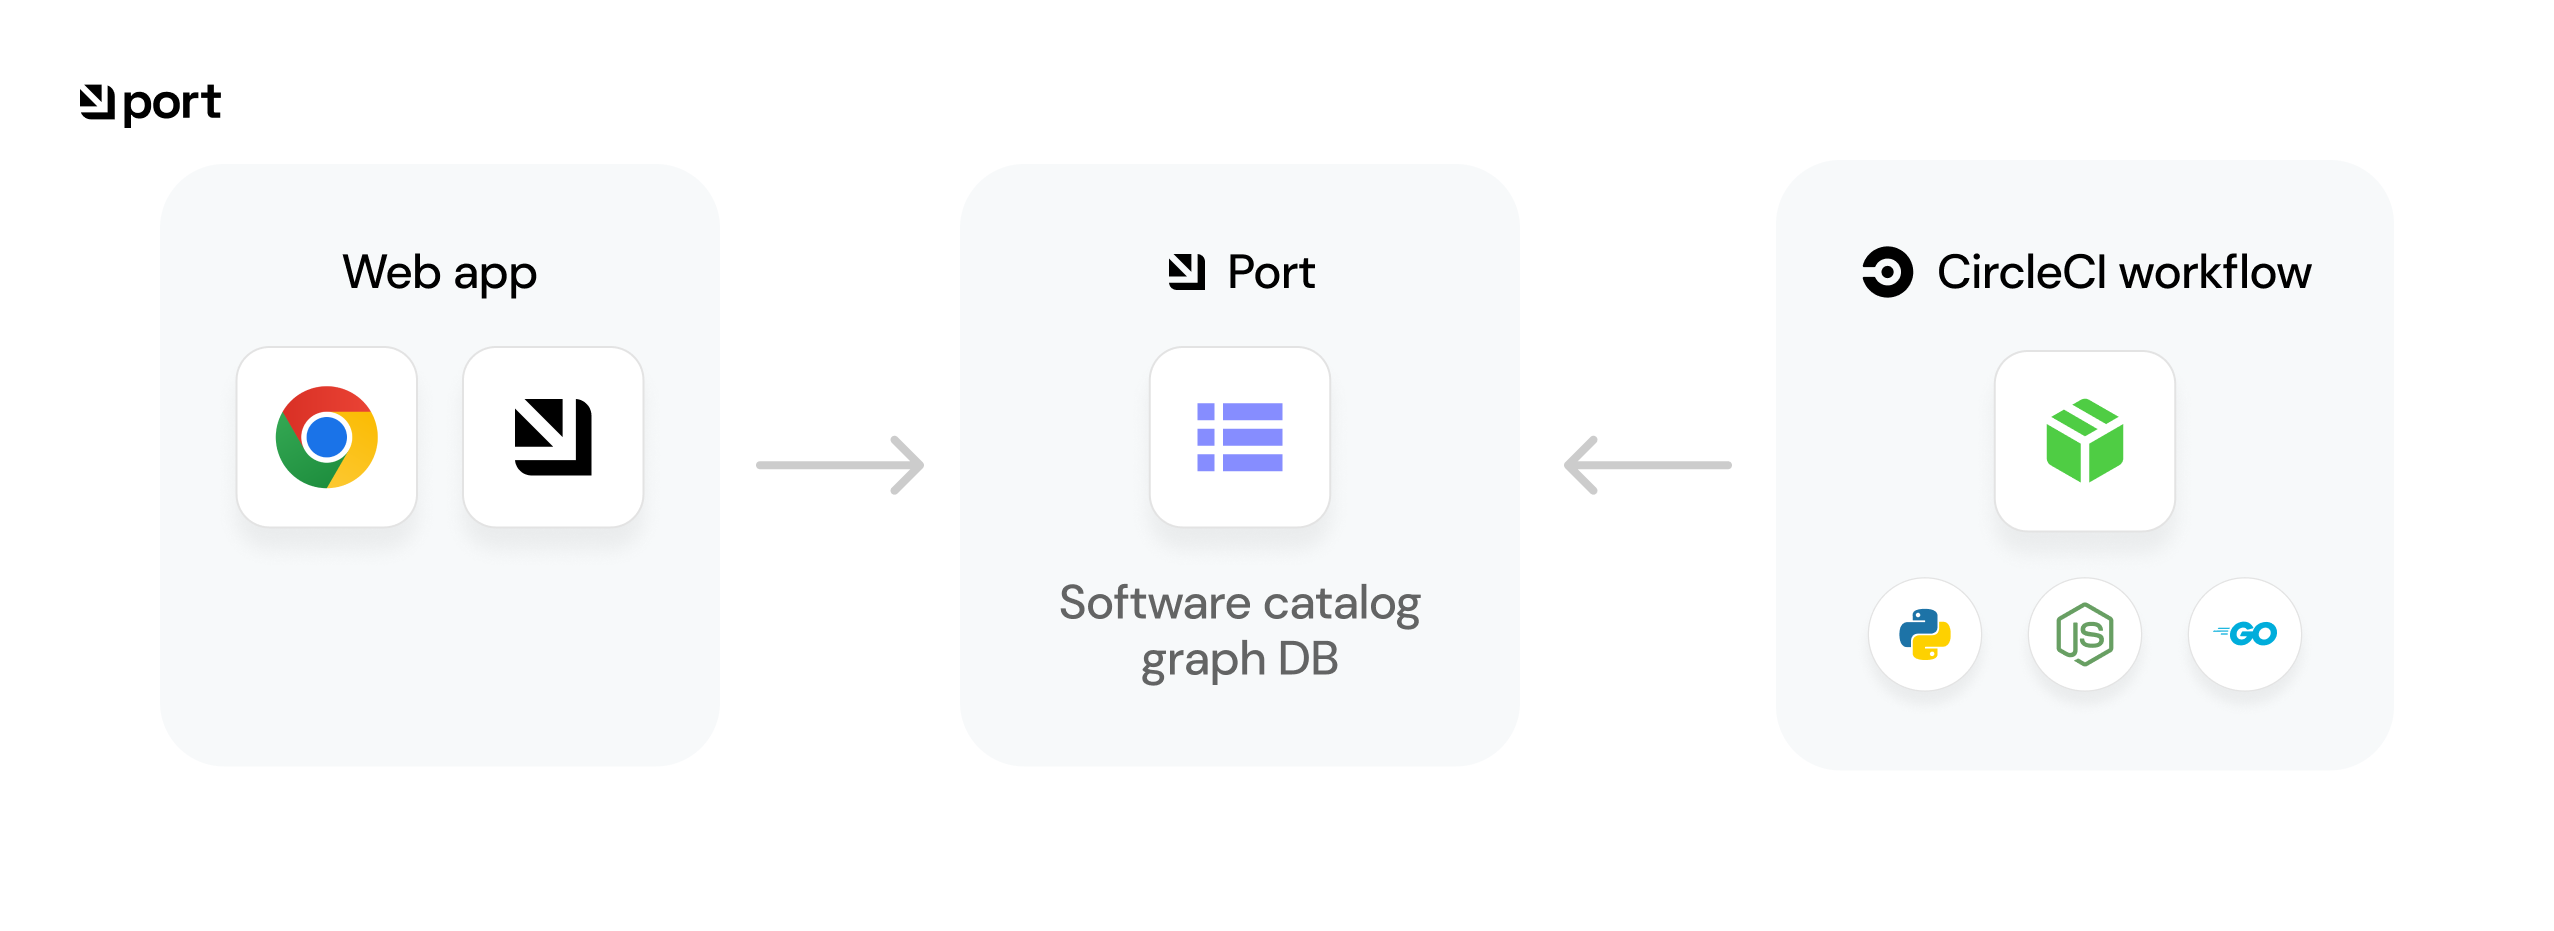
## 💡 Common CircleCI workflow usage[](#-common-circleci-workflow-usage "Direct link to 💡 Common CircleCI workflow usage")
Port's API allows for easy integration between Port and your CircleCI workflows, for example:
* Report the status of a running **CI job**.
* Update the software catalog about a new **build version** for a **microservice**.
* Get existing **entities**.
## Setup[](#setup "Direct link to Setup")
To interact with Port using Circle CI, you will first need to set up a [CircleCI context](https://circleci.com/docs/contexts/) in order to save your Port credentials, and pass the context to the relevant workflow.
```
workflows:
deploy-service:
jobs:
- report-to-port:
context:
# the CircleCI context name of the credentials
- port
```
Make sure you have an existing [Blueprint](/context-lake/data-model/setup-blueprint/overview/.md) in your Port installation to create/update entities.
## Working with Port's API[](#working-with-ports-api "Direct link to Working with Port's API")
Here is an example snippet showing how to integrate a job that uses Port's API with your existing CircleCI pipelines using Python:
Add the following job and workflow to your CircleCI pipeline:
**CircleCI Pipeline YAML (click to expand)**
```
jobs:
# ... other jobs
report-to-port:
docker:
- image: cimg/python:3.11
environment:
API_URL: https://api.port.io
steps:
- checkout
- run: pip install -r port_requirements.txt
- run: python get_port_entity.py
workflows:
# ... other workflows
deploy-production-service:
jobs:
# ... other jobs
- report-to-port:
context:
- port
```
Python dependencies required
In the following example, we use Python modules which need to be installed. You can use the following `requirements.txt`:
**port\_requirements.txt (click to expand)**
```
requests>=2.28.2
```
* Create/Update
* Get
Create the following Python script in your repository to create or update Port entities as part of your pipeline:
```
import os
import requests
import json
# These are the credentials passed by the 'port' context to your environment variables
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
entity_json = {
"identifier": "example-entity",
"properties": {
"myStringProp": "My value",
"myNumberProp": 1,
"myBooleanProp": true,
"myArrayProp": ["myVal1", "myVal2"],
"myObjectProp": {"myKey": "myVal", "myExtraKey": "myExtraVal"}
}
}
# request url : {API_URL}/blueprints//entities
create_response = requests.post(f'{API_URL}/blueprints/test-blueprint/entities?upsert=true', json=entity_json, headers=headers)
print(json.dumps(create_response.json(), indent=4))
```
Create the following Python script in your repository to get Port entities as part of your pipeline:
```
import os
import requests
import json
# These are the credentials passed by the 'port' context to your environment variables
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
# request url : {API_URL}/blueprints//entities/
get_response = requests.get(f"{API_URL}/blueprints/test-blueprint/entities/test-entity", headers=headers)
print(json.dumps(get_response.json(), indent=4))
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Examples[](#examples "Direct link to Examples")
Refer to the [examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/circleci-workflow/examples/.md) page for practical examples of working with Port using CircleCI.
---
# Examples
## Basic create/update example[](#basic-createupdate-example "Direct link to Basic create/update example")
In this example you will create blueprints for `ciJob` and `image` entities, and a relation between them. Then you will add some Python code to create new entities in Port every time the CircleCI workflow is triggered:
**Image blueprint (click to expand)**
Create in Port
```
{
"identifier": "image",
"title": "Image",
"icon": "Docker",
"schema": {
"properties": {
"synkHighVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk High Vaulnerabilities"
},
"synkMediumVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk Medium Vaulnerabilities"
},
"imageTag": {
"type": "string",
"title": "Image Tag"
},
"gitRepoUrl": {
"type": "string",
"format": "url",
"title": "Git Url",
"description": "Git Url for the sourcecode"
},
"imageRegistry": {
"type": "string",
"format": "url",
"title": "Image Registry",
"description": "Docker registry"
},
"unitTestCoverage": {
"type": "number",
"title": "Unit Test coverage (%)",
"description": "The unit test coverage pecentage"
},
"integTestCoverage": {
"type": "number",
"title": "Integ Test coverage (%)",
"description": "The integration test coverage pecentage"
},
"size": {
"type": "number",
"title": "Image Size (GB)",
"description": "The image size in Gigabyte"
}
},
"required": []
},
"calculationProperties": {}
}
```
**CI Job blueprint (including the image relation) (click to expand)**
Create in Port
```
{
"identifier": "ciJob",
"title": "CI Job",
"icon": "CICD",
"schema": {
"properties": {
"triggeredBy": {
"type": "string",
"icon": "TwoUsers",
"title": "Triggered By",
"description": "The user who triggered the run"
},
"commitHash": {
"type": "string",
"title": "Commit Hash"
},
"jobBranch": {
"type": "string",
"icon": "Git",
"format": "url",
"title": "Job branch"
},
"runLink": {
"type": "string",
"format": "url",
"title": "Action Run Link"
}
},
"required": []
},
"relations": {
"image": {
"title": "Job Images",
"target": "image",
"required": false,
"many": true
}
},
"calculationProperties": {}
}
```
After creating the blueprint, you can add a Python script for creating/updating a Port entity:
```
import os
import requests
import json
# Env vars passed by the CircleCI context
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
API_URL = 'https://api.port.io/v1'
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
# use this access token + header for all http requests to Port
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
entity_json = {
"identifier": "new-cijob-run",
"properties": {
"triggeredBy": os.environ['CIRCLE_USERNAME'],
"commitHash": os.environ['CIRCLE_SHA1'],
"actionJob": os.environ['CIRCLE_JOB'],
"runLink": os.environ['CIRCLE_BUILD_URL']
},
"relations": {
"image": ["example-image"]
}
}
create_response = requests.post(f'{API_URL}/blueprints/{blueprint_id}/entities?upsert=true&create_missing_related_entities=true', json=entity_json, headers=headers)
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Relation auto-created
Please notice that you have also created the `image` relation, and added a related image entity called `example-image`. This is the artifact of the ciJob, and you will update it later. The creation was done using the `create_missing_related_entities=true` flag in the API url, allowing the relation to be created even though the `example-image` entity doesn't exist yet.
After adding your new Python script to your repository, add the following code to your CircleCI workflow `yml` file to call your script and update/create a new `ciJob` entity:
```
jobs:
# ... other jobs
report-to-port:
docker:
- image: cimg/python:3.11
environment:
API_URL: https://api.port.io
steps:
- checkout
- run: pip install -r port_requirements.txt
- run: python update_deployment_port.py
workflows:
# ... other workflows
deploy-production-service:
jobs:
# ... other jobs
- report-to-port:
context:
- port
```
## Basic get example[](#basic-get-example "Direct link to Basic get example")
The following example gets the `new-cijob-run` entity from the previous example, this can be useful if your CI process creates a build artifact and then references some of its data (for example, the run link of the latest `ciJob`).
Add the following snippet to your Python code:
```
entity_id = "new-cijob-run"
blueprint_id = "ciJob"
get_response = requests.get(f"{API_URL}/blueprints/{blueprint_id}/entities/{entity_id}",
headers=headers)
entity = get_response.json()['entity']
print(f"Run link is: {entity['properties']['runLink']}")
```
## Relation example[](#relation-example "Direct link to Relation example")
The following example demonstrates how to update the `example-image` entity that was automatically created when creating the `ciJob` entity shown in the previous example.
Add the following snippet to your Python code:
```
image_entity_json = {
"identifier": "example-image",
"team": [],
"properties": {
"imageTag": "v1",
"synkHighVulnerabilities": "0",
"synkMediumVulnerabilities": "0",
"gitRepoUrl": "https://github.com/my-org/my-cool-repo",
"imageRegistry": "docker.io/cool-image",
"size": "0.71",
"unitTestCoverage": "20",
"unitTestCoverage": "50"
},
"relations": {}
}
create_image_response = requests.post(f'{API_URL}/blueprints/image/entities?upsert=true', json=image_entity_json, headers=headers)
print(create_image_response.json())
```
That's it! The entity is created or updated and is visible in the UI.
---
# Codefresh Workflow Template
Our [Codefresh workflow template](https://github.com/port-labs/port-codefresh-workflow-template) allows you to create/update and query entities in Port directly from your Codefresh workflow templates.
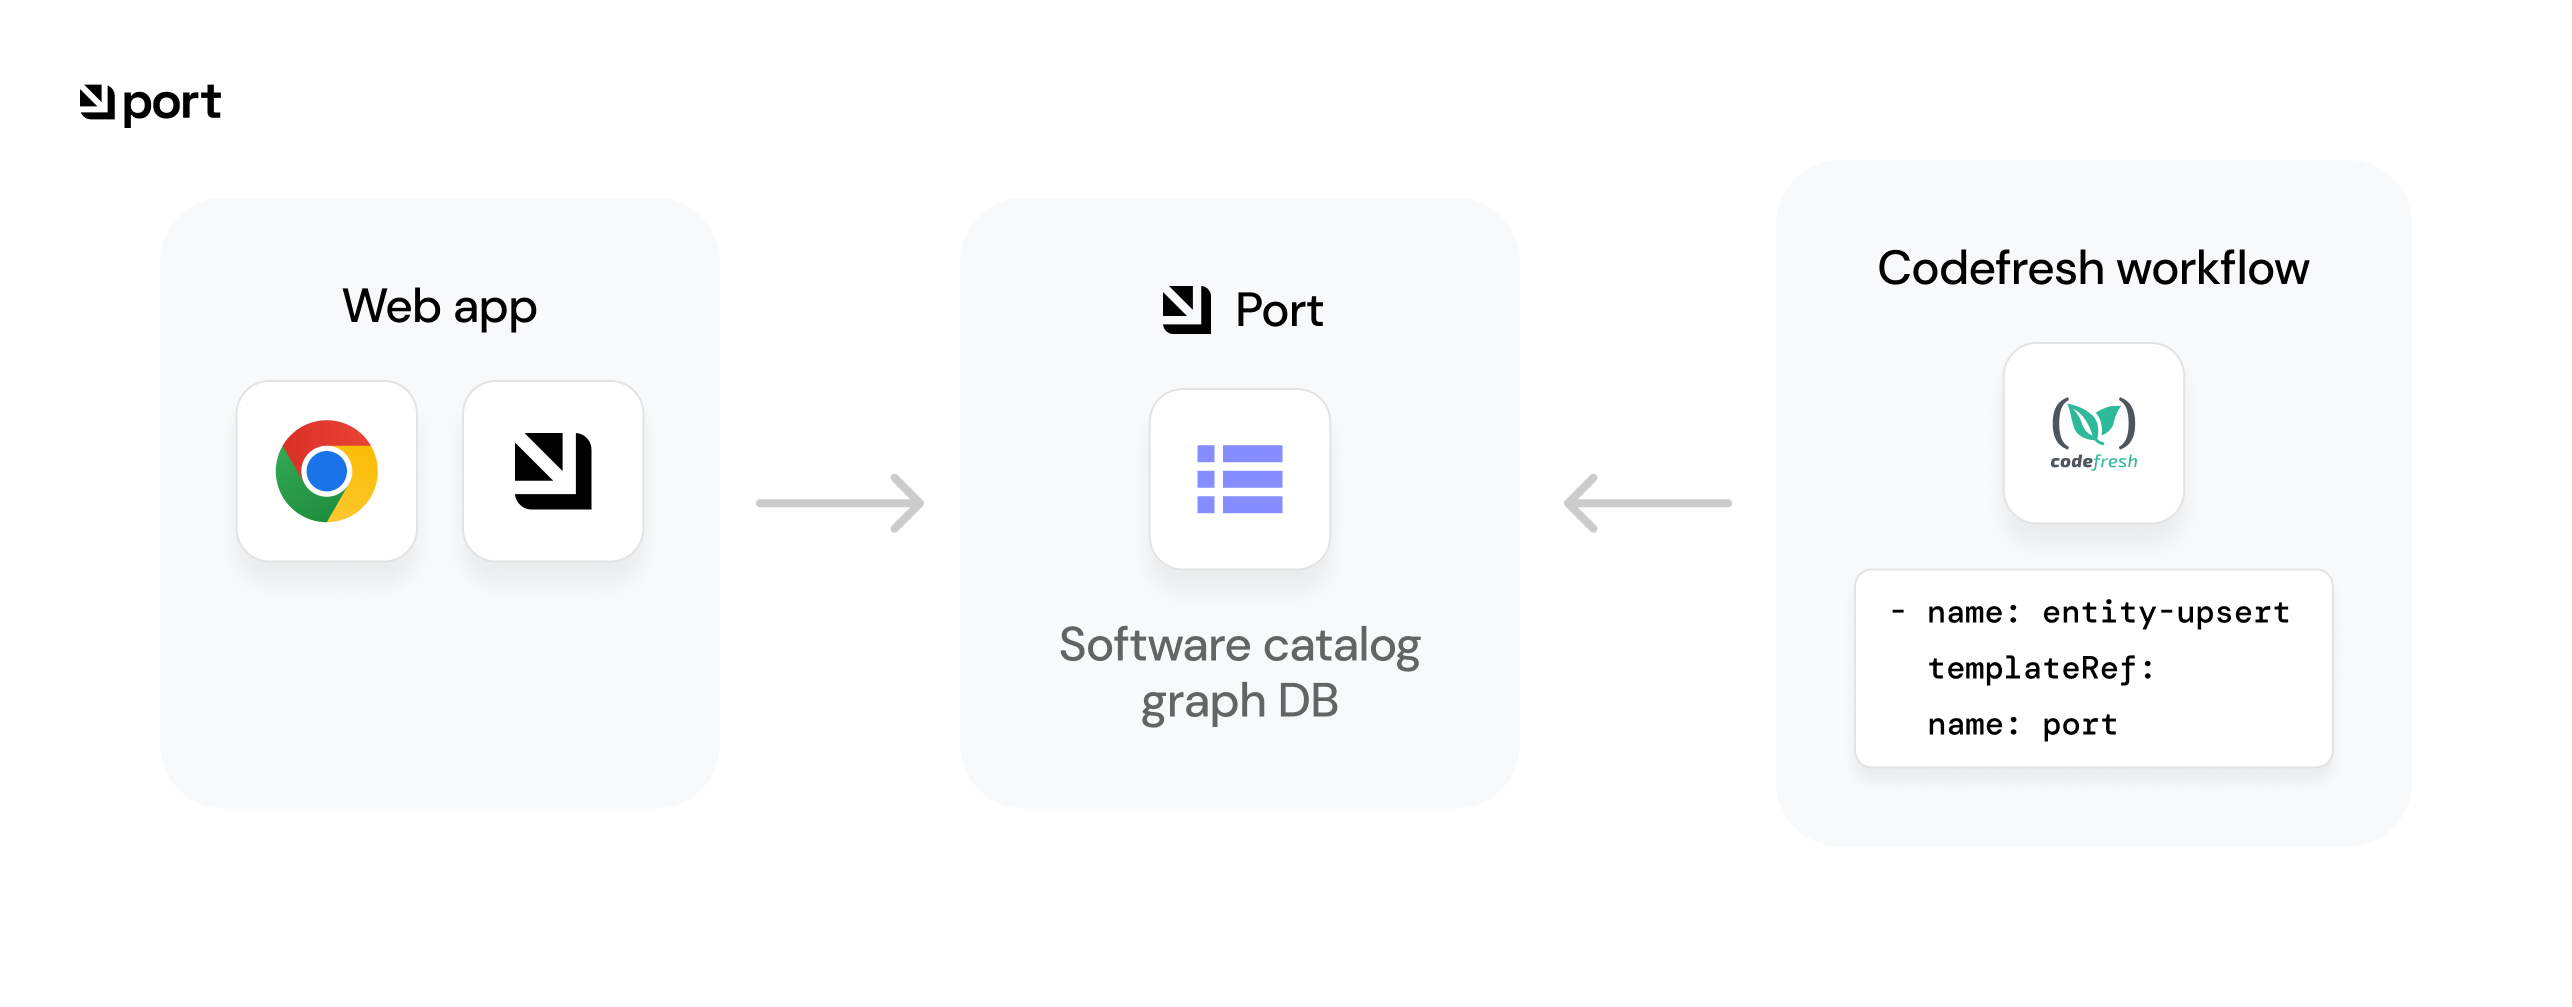
## 💡 Codefresh integration usage[](#-codefresh-integration-usage "Direct link to 💡 Codefresh integration usage")
Port's Codefresh workflow template provides a native way to integrate Port with your Codefresh CI workflows, for example:
* Report the status of a running **CI job**.
* Update the software catalog about a new **build version** for a **microservice**.
* Get existing **entities**.
## Installation[](#installation "Direct link to Installation")
To use Port's Codefresh workflow template you need to perform the following steps:
1. Go to the [workflow template repository](https://github.com/port-labs/port-codefresh-workflow-template) in GitHub.
2. Copy the file [`portWorkflowTemplate.yml`](https://github.com/port-labs/port-codefresh-workflow-template/blob/main/portWorkflowTemplate.yml) to one of your codefresh `git sources` and commit it to your git source.
3. Add the required service account, cluster role and role binding to your codefresh runtime namespace by applying the contents of the [`rbac.yml`](https://github.com/port-labs/port-codefresh-workflow-template/blob/main/rbac.yml) file by using the command: `kubectl apply -f rbac.yml -n YOUR_NAMESPACE`.
4. Add the required secret containing your `PORT_CLIENT_ID` and `PORT_CLIENT_SECRET` after encoding them using base64. You can use [`portCredentials.yml`](https://github.com/port-labs/port-codefresh-workflow-template/blob/main/portCredentials.yml) as an example.
Skip default-format credentials
If you save the CLIENT\_ID and SECRET using the exact format shown in `portCredentials.yml`, you do not need to provide the parameters `PORT_CREDENTIALS_SECRET`, `PORT_CLIENT_ID_KEY` and `PORT_CLIENT_SECRET_KEY` when calling templates from the workflow template.
### Verify[](#verify "Direct link to Verify")
To verify the installation of the workflow template, follow these steps:
1. Go to the Codefresh interface.
2. Under the CI OPS category, click on Workflow Templates.
3. In the search bar, type `port` the workflow template should appear.
## Usage[](#usage "Direct link to Usage")
Port's Codefresh workflow template supports the following methods:
* Create/Update catalog entities - invoked with the `upsert-entity` template, receives the identifier and other properties of a new entity or an entity that needs to be updated.
* Get catalog entities - invoked with the `get-entity` template, receives the identifier of an existing entity and retrieves it for use in your CI.
- Create/Update
- Get
```
- name: entity-upsert
templateRef:
name: port
template: entity-upsert
arguments:
parameters:
# Note: if you save the CLIENT_ID and CLIENT_SECRET in the same format shown
# in the portCredentials.yml file, there is no need to provide
# PORT_CREDENTIALS_SECRET, PORT_CLIENT_ID_KEY, PORT_CLIENT_SECRET_KEY
- name: PORT_CREDENTIALS_SECRET
value: "port-credentials"
- name: PORT_CLIENT_ID_KEY
value: "PORT_CLIENT_ID"
- name: PORT_CLIENT_SECRET_KEY
value: "PORT_CLIENT_SECRET"
- name: BLUEPRINT_IDENTIFIER
value: "myBlueprint"
- name: ENTITY_IDENTIFIER
value: "myEntity"
- name: ENTITY_TITLE
value: "myTitle"
- name: ENTITY_PROPERTIES
value: |
{
"myStringProp": "My value",
"myNumberProp": 1,
"myBooleanProp": true,
"myArrayProp": ["myVal1", "myVal2"],
"myObjectProp": {"myKey": "myVal", "myExtraKey": "myExtraVal"}
}
```
**Inputs**
| Input | Description | Notes |
| ------------------------- | ------------------------------------------------------------------------- | ----------------------------------------------- |
| `PORT_CREDENTIALS_SECRET` | Name of the secret to get the `CLIENT_ID` and `CLIENT_SECRET` from | Default value: `port-credentials` |
| `PORT_CLIENT_ID_KEY` | Key in the secret where the base64 encoded `PORT_CLIENT_ID` is stored | Default value: `PORT_CLIENT_ID` |
| `PORT_CLIENT_SECRET_KEY` | key in the secret where the base64 encoded `PORT_CLIENT_SECRET` is stored | Default value: `PORT_CLIENT_SECRET` |
| `BLUEPRINT_IDENTIFIER` | Identifier of the blueprint to create an entity of | **Required** |
| `ENTITY_IDENTIFIER` | Identifier of the new (or existing) entity | Leave empty to get an auto-generated identifier |
| `ENTITY_TITLE` | Title of the new (or existing) entity | |
| `ENTITY_TEAM` | Teams array of the new (or existing) entity | |
| `ENTITY_ICON` | Icon of the new (or existing) entity | |
| `ENTITY_PROPERTIES` | Properties of the new (or existing) entity | |
| `ENTITY_RELATIONS` | Relations of the new (or existing) entity. | |
**Outputs**
| Output | Description | Notes |
| ------------------- | ------------------------------------------ | ----- |
| `ENTITY_IDENTIFIER` | identifier of the new (or existing) entity | |
```
- name: entity-get
templateRef:
name: port
template: entity-get
arguments:
parameters:
# Note: if you save the CLIENT_ID and CLIENT_SECRET in the same format shown
# in the portCredentials.yml file, there is no need to provide
# PORT_CREDENTIALS_SECRET, PORT_CLIENT_ID_KEY, PORT_CLIENT_SECRET_KEY
- name: PORT_CREDENTIALS_SECRET
value: "port-credentials"
- name: PORT_CLIENT_ID_KEY
value: "PORT_CLIENT_ID"
- name: PORT_CLIENT_SECRET_KEY
value: "PORT_CLIENT_SECRET"
- name: BLUEPRINT_IDENTIFIER
value: "microservice"
- name: ENTITY_IDENTIFIER
value: "morp"
```
**Inputs**
| Input | Description | Notes |
| ------------------------- | ------------------------------------------------------------------------- | ----------------------------------- |
| `PORT_CREDENTIALS_SECRET` | Name of the secret to get the `CLIENT_ID` and `CLIENT_SECRET` from | Default value: `port-credentials` |
| `PORT_CLIENT_ID_KEY` | Key in the secret where the base64 encoded `PORT_CLIENT_ID` is stored | Default value: `PORT_CLIENT_ID` |
| `PORT_CLIENT_SECRET_KEY` | Key in the secret where the base64 encoded `PORT_CLIENT_SECRET` is stored | Default value: `PORT_CLIENT_SECRET` |
| `BLUEPRINT_IDENTIFIER` | Identifier of the blueprint the target entity is from | **Required** |
| `ENTITY_IDENTIFIER` | Identifier of the target entity | |
**Outputs**
| Output | Description | Notes |
| --------------------------- | ----------------------------------------------------- | ----- |
| `PORT_COMPLETE_ENTITY` | Complete entity JSON | |
| `PORT_BLUEPRINT_IDENTIFIER` | Identifier of the blueprint the target entity is from | |
| `PORT_ENTITY_IDENTIFIER` | Identifier of the target entity | |
| `PORT_ENTITY_TITLE` | Title of the entity | |
| `PORT_ENTITY_PROPERTIES` | All properties of the entity in JSON format | |
| `PORT_ENTITY_RELATIONS` | All relations of the entity in JSON format | |
## Examples[](#examples "Direct link to Examples")
Refer to the [examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/codefresh-workflow-template/examples/.md) page for practical examples of Port's Codefresh workflow template.
---
# Examples
## Basic create/update example[](#basic-createupdate-example "Direct link to Basic create/update example")
In this example you will create blueprints for `ciJob` and `image` entities, and a relation between them. Then you will add code that uses Port's Codefresh workflow template to create new entities every time the Codefresh CI workflow runs:
**Image blueprint (click to expand)**
Create in Port
```
{
"identifier": "image",
"title": "Image",
"icon": "Docker",
"schema": {
"properties": {
"synkHighVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk High Vaulnerabilities"
},
"synkMediumVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk Medium Vaulnerabilities"
},
"imageTag": {
"type": "string",
"title": "Image Tag"
},
"gitRepoUrl": {
"type": "string",
"format": "url",
"title": "Git Url",
"description": "Git Url for the sourcecode"
},
"imageRegistry": {
"type": "string",
"format": "url",
"title": "Image Registry",
"description": "Docker registry"
},
"unitTestCoverage": {
"type": "number",
"title": "Unit Test coverage (%)",
"description": "The unit test coverage pecentage"
},
"integTestCoverage": {
"type": "number",
"title": "Integ Test coverage (%)",
"description": "The integration test coverage pecentage"
},
"size": {
"type": "number",
"title": "Image Size (GB)",
"description": "The image size in Gigabyte"
}
},
"required": []
},
"calculationProperties": {}
}
```
**CI Job blueprint (including the image relation) (click to expand)**
Create in Port
```
{
"identifier": "ciJob",
"title": "CI Job",
"icon": "CICD",
"schema": {
"properties": {
"triggeredBy": {
"type": "string",
"icon": "TwoUsers",
"title": "Triggered By",
"description": "The user who triggered the run"
},
"commitHash": {
"type": "string",
"title": "Commit Hash"
},
"jobBranch": {
"type": "string",
"icon": "Git",
"format": "url",
"title": "Job branch"
},
"runLink": {
"type": "string",
"format": "url",
"title": "Action Run Link"
}
},
"required": []
},
"relations": {
"image": {
"title": "Job Images",
"target": "image",
"required": false,
"many": true
}
},
"calculationProperties": {}
}
```
After creating the blueprint, you can add the following snippet to your Codefresh workflow template `yml` file to create the new ciJob entity in your Codefresh CI:
```
- name: entity-upsert
templateRef:
name: port
template: entity-upsert
arguments:
parameters:
- name: PORT_CREDENTIALS_SECRET
value: "port-credentials"
- name: PORT_CLIENT_ID_KEY
value: "PORT_CLIENT_ID"
- name: PORT_CLIENT_SECRET_KEY
value: "PORT_CLIENT_SECRET"
- name: BLUEPRINT_IDENTIFIER
value: "ciJob"
- name: ENTITY_IDENTIFIER
value: "new-cijob-run"
- name: ENTITY_PROPERTIES
value: |
{
"runLink": "${{CF_BUILD_URL}}",
"triggeredBy": "${{CF_BUILD_INITIATOR}}"
}
```
## Basic get example[](#basic-get-example "Direct link to Basic get example")
The following example gets the `ciJob` entity from the previous example. This can be useful if your CI process needs to reference data from the ciJob (for example, the user who triggered the last job) when deploying the latest version of your service.
Add the following steps to your workflow `yml` file:
```
- name: entity-get
templateRef:
name: port
template: entity-get
arguments:
parameters:
- name: PORT_CREDENTIALS_SECRET
value: "port-credentials"
- name: PORT_CLIENT_ID_KEY
value: "PORT_CLIENT_ID"
- name: PORT_CLIENT_SECRET_KEY
value: "PORT_CLIENT_SECRET"
- name: BLUEPRINT_IDENTIFIER
value: "ciJob"
- name: ENTITY_IDENTIFIER
value: "new-cijob-run"
```
Using entity-get output
For an example showing how to make use of the output from the `entity-get` workflow template, go to [complete example](#complete-example).
## Complete example[](#complete-example "Direct link to Complete example")
Here is a complete workflow `yml` to create both `image` entity, and a `cijob` entity with a relation between them, and then print the complete JSON of the new `image` entity:
```
apiVersion: argoproj.io/v1alpha1
kind: WorkflowTemplate
metadata:
name: port.codefresh-complete-example.0.0.1
annotations:
port/version: "0.0.1"
port/description: "This Workflow Template is used to create an image entity, a ciJob entity and then print the JSON of the new image"
spec:
arguments:
parameters:
entrypoint: ci-tasks
templates:
- name: ci-tasks
metadata:
annotations:
dag:
tasks:
- name: entity-upsert-image
templateRef:
name: port
template: entity-upsert
arguments:
parameters:
- name: PORT_CREDENTIALS_SECRET
value: "port-credentials"
- name: PORT_CLIENT_ID_KEY
value: "PORT_CLIENT_ID"
- name: PORT_CLIENT_SECRET_KEY
value: "PORT_CLIENT_SECRET"
- name: BLUEPRINT_IDENTIFIER
value: "image"
- name: ENTITY_IDENTIFIER
value: "example-image"
- name: ENTITY_PROPERTIES
value: |
{
"imageTag": "v1",
"synkHighVulnerabilities": "0",
"synkMediumVulnerabilities": "0",
"gitRepoUrl": "https://github.com/my-org/my-cool-repo",
"imageRegistry": "docker.io/cool-image",
"size": "0.71",
"unitTestCoverage": "20",
"unitTestCoverage": "50",
}
- name: entity-upsert-cijob
dependencies:
[entity-upsert-image]
templateRef:
name: port
template: entity-upsert
arguments:
parameters:
- name: PORT_CREDENTIALS_SECRET
value: "port-credentials"
- name: PORT_CLIENT_ID_KEY
value: "PORT_CLIENT_ID"
- name: PORT_CLIENT_SECRET_KEY
value: "PORT_CLIENT_SECRET"
- name: BLUEPRINT_IDENTIFIER
value: "ciJob"
- name: ENTITY_IDENTIFIER
value: "new-cijob-run"
- name: ENTITY_PROPERTIES
value: |
{
"runLink": "${{CF_BUILD_URL}}",
"triggeredBy": "${{CF_BUILD_INITIATOR}}"
}
- name: ENTITY_RELATIONS
value: |
{
"image": ["example-image"]
}
- name: entity-get
dependencies:
[entity-upsert-image, entity-upsert-cijob]
templateRef:
name: port
template: entity-get
arguments:
parameters:
- name: PORT_CREDENTIALS_SECRET
value: port-credentials
- name: PORT_CLIENT_ID_KEY
value: PORT_CLIENT_ID
- name: PORT_CLIENT_SECRET_KEY
value: PORT_CLIENT_SECRET
- name: BLUEPRINT_IDENTIFIER
value: "image"
- name: ENTITY_IDENTIFIER
value: "example-image"
- name: log-info
dependencies: [entity-get]
template: log-info
arguments:
parameters:
- name: INFO
value: "{{workflow.outputs.parameters.PORT_COMPLETE_ENTITY}}"
- name: log-info
inputs:
parameters:
- name: INFO
script:
image: alpine:latest
command: ["/bin/sh"]
env:
- name: INFO
value: "{{ inputs.parameters.INFO }}"
source: |
set -e
echo ${INFO}
```
That's it! The Entity is created or updated and is visible in the UI.
---
# GitHub Workflow
Port's [GitHub action](https://github.com/marketplace/actions/port-github-action) allows you to create/update and query entities in Port directly from your GitHub workflows.
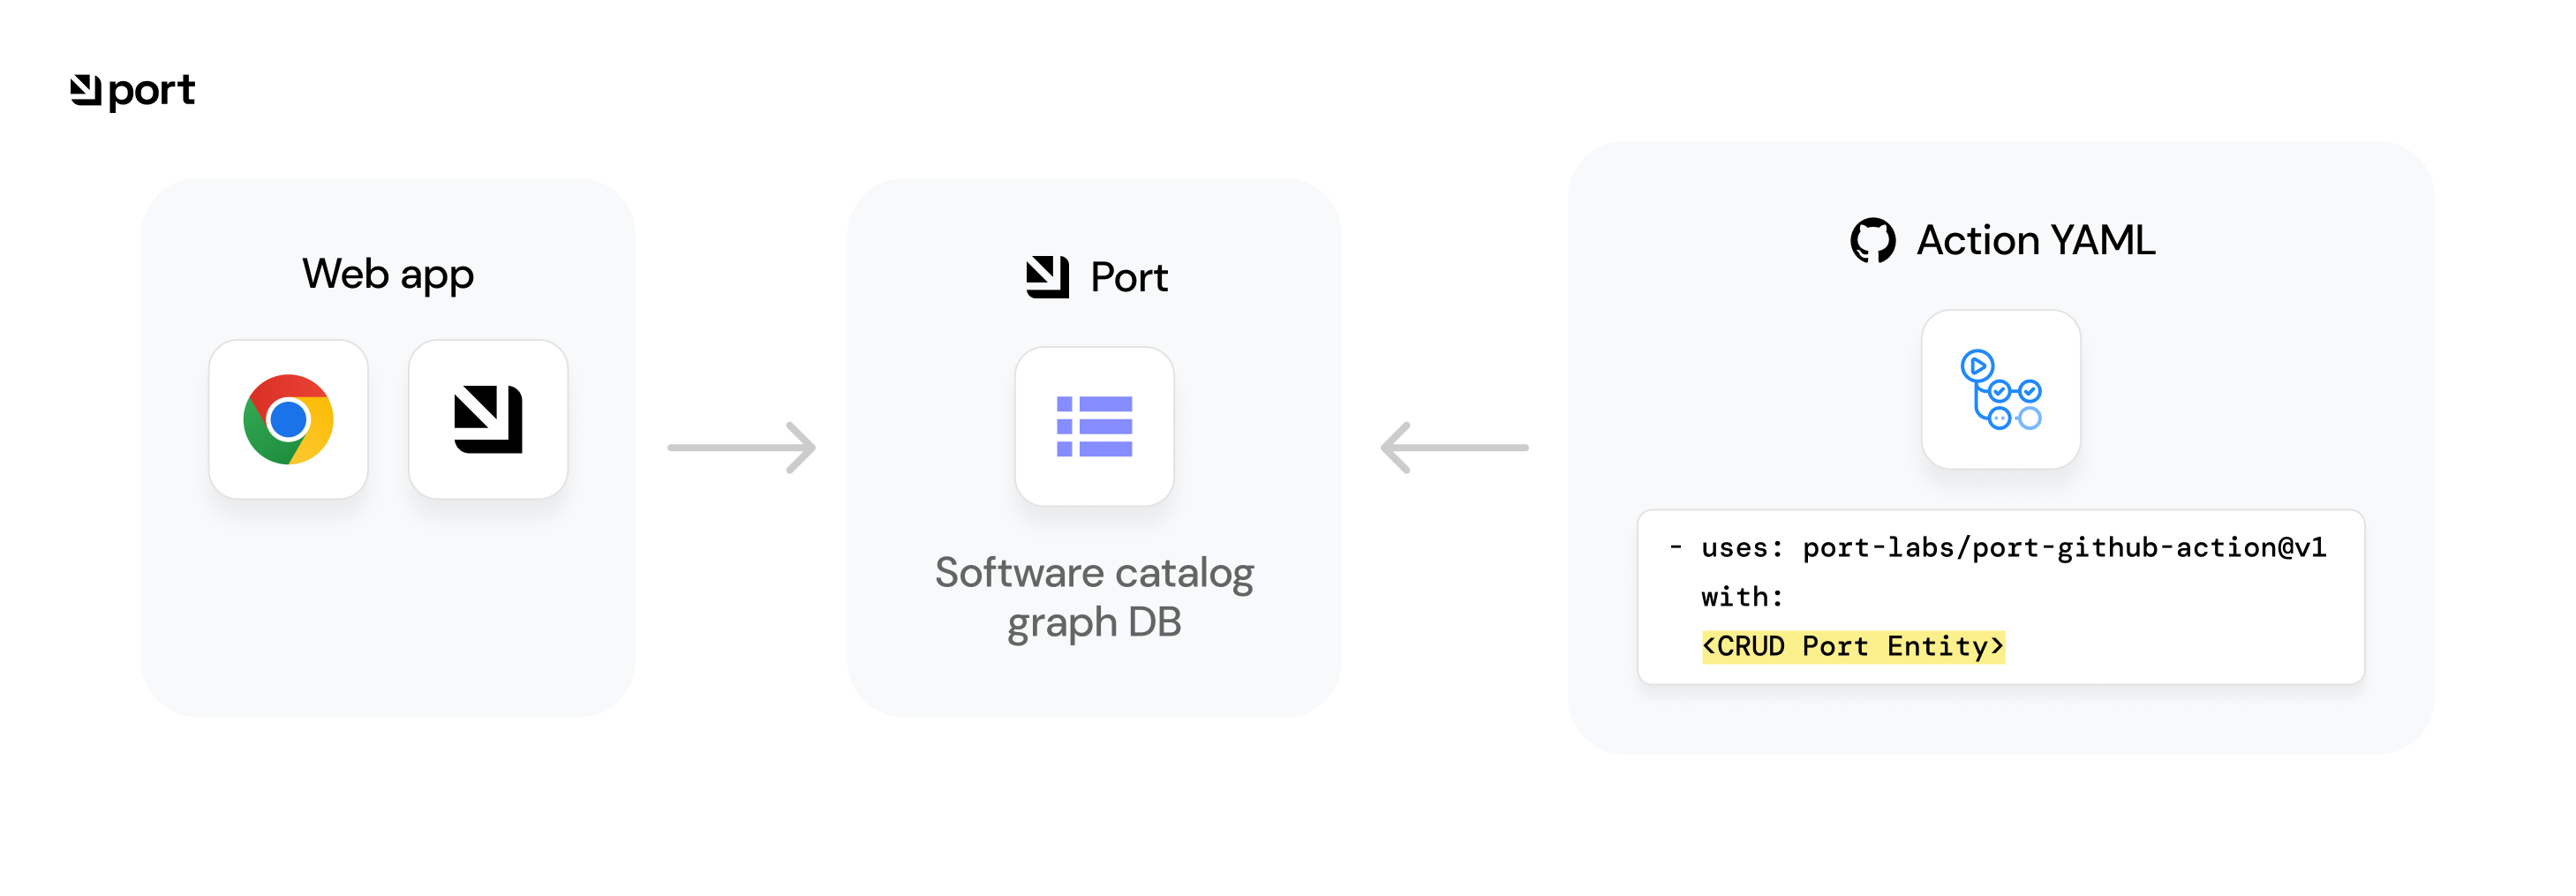
public repository
The GitHub action is open source - see the repository [**here**](https://github.com/port-labs/port-github-action).
## 💡 Common Github workflow usage[](#-common-github-workflow-usage "Direct link to 💡 Common Github workflow usage")
Port's GitHub action provides a native way to integrate Port with your GitHub workflows, for example:
* Report the status of a running **CI job**.
* Update the software catalog about a new **build version** for a **microservice**.
* Get existing **entities**.
## Usage[](#usage "Direct link to Usage")
To use Port's GitHub action, add the following line as a step in your GitHub workflow:
```
- uses: port-labs/port-github-action@v1
```
Add your Port `CLIENT_ID` and `CLIENT_SECRET` as [GitHub secrets](https://docs.github.com/en/actions/security-guides/encrypted-secrets) in the relevant repository.
## Configuration[](#configuration "Direct link to Configuration")
Port's GitHub action supports the following operations:
* Create/Update catalog entities - invoked with the `UPSERT` operation, receives the identifier and other properties of a new entity or an entity that needs to be updated.
* Bulk Create/Update catalog entities - invoked with the `BULK_UPSERT` operation, receives the entities definitions of some new entities or entities that needs to be updated.
* Get catalog entities - invoked with the `GET` operation, receives the identifier of an existing entity and retrieves it for use in your CI.
* Search catalog entities - invoked with the `SEARCH` operation, receives a query and retrieves the entities for use in your CI.
* Delete catalog entities - invoked with the `DELETE` operation, receives the identifier of an existing entity and deletes it.
* Update a running action - invoked with the `PATCH_RUN` operation, receives the identifier of an existing action run along with other properties of the run that need to be updated.
* Create an action run - invoked with the `CREATE_RUN` operation, receives the identifier of an existing blueprint, action and entity (optional), along with input properties to run the action with.
- Create/Update Entity
- Bulk Create/Update Entities
- Get Entity
- Search Entities
- Delete Entity
- Update Running Action
- Create Action Run
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: UPSERT
identifier: myEntity
icon: myIcon
blueprint: myBlueprint
team: "['myTeam']"
properties: |-
{
"myStringProp": "My value",
"myNumberProp": 1,
"myBooleanProp": true,
"myArrayProp": ["myVal1", "myVal2"],
"myObjectProp": {"myKey": "myVal", "myExtraKey": "myExtraVal"}
}
```
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: BULK_UPSERT
runId: myRunId
entities: |-
[
{
"identifier": "myEntity",
"icon": "myIcon",
"blueprint": "myBlueprint",
"team": [
"myTeam"
],
"properties": {
"myStringProp": "My value",
"myNumberProp": 1,
"myBooleanProp": true,
"myArrayProp": [
"myVal1",
"myVal2"
],
"myObjectProp": {
"myKey": "myVal",
"myExtraKey": "myExtraVal"
}
}
}
]
```
```
get-entity:
runs-on: ubuntu-latest
outputs:
entity: ${{ steps.port-github-action.outputs.entity }}
steps:
- id: port-github-action
uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: GET
identifier: myEntity
blueprint: myBlueprint
use-entity:
runs-on: ubuntu-latest
needs: get-entity
steps:
- run: echo '${{needs.get-entity.outputs.entity}}' | jq .properties.myProp
```
```
search-entities:
runs-on: ubuntu-latest
outputs:
entities: ${{ steps.port-github-action.outputs.entities }}
steps:
- id: port-github-action
uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: SEARCH
query: |-
{
"rules": [
{
"operator": "=",
"value": "myEntity",
"property": "$identifier"
}
],
"combinator": "and"
}
use-entities:
runs-on: ubuntu-latest
needs: search-entities
steps:
- run: echo '${{needs.search-entities.outputs.entities}}' | jq .[0].myProp
```
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: DELETE
identifier: myEntity
blueprint: myBlueprint
```
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: PATCH_RUN
runId: myRunId
status: "SUCCESS"
logMessage: "My log message"
summary: "My summary"
link: '["https://mylink.com"]'
```
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: CREATE_RUN
icon: GithubActions
blueprint: myBlueprint
action: myAction
identifier: myEntity
properties: |-
{
"text": "test",
"number": 1,
"boolean": true
}
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Examples[](#examples "Direct link to Examples")
Refer to the [examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/github-workflow/examples/.md) page for practical examples of Port's GitHub action.
---
# Examples
## Import Gradle dependencies[](#import-gradle-dependencies "Direct link to Import Gradle dependencies")
[This GitHub repository](https://github.com/matarpeles/extract-gradle-plugins-example) contains an implementation of a workflow that uses Port's GitHub action and a supporting Python script to import [Gradle](https://gradle.org/) dependencies into Port.
The workflow achieves the following:
* Extract plugins and their versions from a Gradle build file.
* Map the extracted plugins as package entities in Port.
* Automatically create or update a service entity in Port, connecting it to its plugin dependencies.
See the [repository](https://github.com/matarpeles/extract-gradle-plugins-example) for the full implementation and a detailed README describing how to use it.
## Basic create/update example[](#basic-createupdate-example "Direct link to Basic create/update example")
In this example you will create blueprints for `ciJob` and `image` entities, and a relation between them. Using Port's GitHub action you will create new entities every time the GitHub workflow runs:
**Image blueprint (click to expand)**
Create in Port
```
{
"identifier": "image",
"title": "Image",
"icon": "Docker",
"schema": {
"properties": {
"synkHighVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk High Vaulnerabilities"
},
"synkMediumVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk Medium Vaulnerabilities"
},
"imageTag": {
"type": "string",
"title": "Image Tag"
},
"gitRepoUrl": {
"type": "string",
"format": "url",
"title": "Git Url",
"description": "Git Url for the sourcecode"
},
"imageRegistry": {
"type": "string",
"format": "url",
"title": "Image Registry",
"description": "Docker registry"
},
"unitTestCoverage": {
"type": "number",
"title": "Unit Test coverage (%)",
"description": "The unit test coverage pecentage"
},
"integTestCoverage": {
"type": "number",
"title": "Integ Test coverage (%)",
"description": "The integration test coverage pecentage"
},
"size": {
"type": "number",
"title": "Image Size (GB)",
"description": "The image size in Gigabyte"
}
},
"required": []
},
"calculationProperties": {}
}
```
**CI Job blueprint (including the image relation) (click to expand)**
Create in Port
```
{
"identifier": "ciJob",
"title": "CI Job",
"icon": "CICD",
"schema": {
"properties": {
"triggeredBy": {
"type": "string",
"icon": "TwoUsers",
"title": "Triggered By",
"description": "The user who triggered the run"
},
"commitHash": {
"type": "string",
"title": "Commit Hash"
},
"jobBranch": {
"type": "string",
"icon": "Git",
"format": "url",
"title": "Job branch"
},
"runLink": {
"type": "string",
"format": "url",
"title": "Action Run Link"
}
},
"required": []
},
"relations": {
"image": {
"title": "Job Images",
"target": "image",
"required": false,
"many": true
}
},
"calculationProperties": {}
}
```
After creating the blueprints, you can add the following snippet to your GitHub workflow `yml` file to create the `ciJob` entity in your GitHub workflow:
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: UPSERT
identifier: new-cijob-run
icon: GithubActions
blueprint: ciJob
properties: |
{
"commitHash": "${{ env.GITHUB_SHA }}",
"jobBranch": "${{ env.GITHUB_SERVER_URL }}/${{ env.GITHUB_REPOSITORY }}/tree/${{ env.GITHUB_REF_NAME }}",
"runLink": "${{ env.GITHUB_SERVER_URL }}/${{ env.GITHUB_REPOSITORY }}/actions/runs/${{ env.GITHUB_RUN_ID }}",
"triggeredBy": "${{ env.GITHUB_ACTOR }}"
}
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Store credentials as GitHub Secrets
For security reasons it is recommended to save the `CLIENT_ID` and `CLIENT_SECRET` as [GitHub Secrets](https://docs.github.com/en/actions/security-guides/encrypted-secrets), and access them as shown in the example above.
## Basic get example[](#basic-get-example "Direct link to Basic get example")
The following example gets the `ciJob` entity from the previous example. This can be useful if your CI process needs to reference data from the ciJob (for example, the user who triggered the last job) when deploying the latest version of your service.
Add the following jobs to your GitHub workflow `yml` file:
```
get-entity:
runs-on: ubuntu-latest
outputs:
entity: ${{ steps.port-github-action.outputs.entity }}
steps:
- id: port-github-action
uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: GET
identifier: new-cijob-run
blueprint: ciJob
use-entity:
runs-on: ubuntu-latest
needs: get-entity
steps:
- run: echo '${{needs.get-entity.outputs.entity}}' | jq .properties.triggeredBy
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
The first job `get-entity`, uses the GitHub action to get the `new-cijob-run` entity. The second job `use-entity`, uses the output from the first job, and prints the `triggeredBy` property of the entity.
## Relation example[](#relation-example "Direct link to Relation example")
The following example adds an `image` entity, in addition to the `ciJob` entity shown in the previous example. The `image` entity represents an artifact generated by the ciJob run.
Add the following snippet to your GitHub workflow `yml` file:
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: UPSERT
identifier: example-image
title: Example Image
icon: Docker
blueprint: image
properties: |
{
"imageTag": "v1",
"synkHighVulnerabilities": "0",
"synkMediumVulnerabilities": "0",
"gitRepoUrl": "https://github.com/my-org/my-cool-repo",
"imageRegistry": "docker.io/cool-image",
"size": "0.71",
"unitTestCoverage": "20",
"unitTestCoverage": "50",
}
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
All that’s left is to map the new `image` entity to the `ciJob` , thus making it possible to know which image was created by the ciJob.
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: UPSERT
identifier: new-cijob-run
icon: GithubActions
blueprint: ciJob
relations: |
{
"image": ["example-image"]
}
```
That's it! The entities are updated and visible in the UI.
## Basic update run example[](#basic-update-run-example "Direct link to Basic update run example")
In this example you will create a self-service action that deploys the latest version of your service, and updates the action run with the deployment status.
Add the following action to your `image` blueprint actions:
**Deploy image action (click to expand)**
Create in Port
```
{
"identifier": "deploy_image",
"title": "Deploy image",
"icon": "DefaultProperty",
"description": "Deploy image version",
"trigger": {
"type": "self-service",
"operation": "DAY-2",
"userInputs": {
"properties": {},
"required": [],
"order": []
},
"blueprintIdentifier": "image"
},
"invocationMethod": {
"type": "WEBHOOK",
"url": "https://example.com",
"agent": false,
"synchronized": false,
"method": "POST",
"headers": {
"RUN_ID": "{{ .run.id }}"
},
"body": {
"action": "{{ .action }}",
"trigger": "{{ .trigger | {by, origin, at} }}",
"port_context": {
"entity": "{{.entity.identifier}}",
"blueprint": "{{.action.blueprint}}",
"runId": "{{.run.id}}",
"operation": "{{.trigger.operation}}"
}
}
},
"requiredApproval": false
}
```
GitHub workflow required
The example here is meant to show a common flow when using a Port self-service action and then using Port's GitHub action to update its logs, status and other information.
In order to use Port's GitHub action to make these updates, you will need your backend to either be a GitHub workflow or for a different backend of your choosing to trigger a GitHub workflow as part of its logic
After triggering the action in Port, a new action run will be created in Port (and a matching `runId` will be generated). The runId can be used to update the action status and reports logs to Port.
To update the new self-service action run, add the following snippet to your GitHub workflow `yml` file (note you will need to pass the correct `runId` to the action):
```
- uses: port-labs/port-github-action@v1
with:
clientId: ${{ secrets.CLIENT_ID }}
clientSecret: ${{ secrets.CLIENT_SECRET }}
baseUrl: https://api.port.io
operation: PATCH_RUN
runId: ${{ env.PORT_RUN_ID }}
icon: GithubActions
status: "SUCCESS"
logMessage: "Deployment completed successfully"
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Update status last
The example above shows how to update the status and add a new log message to the action run, but it is also possible to update just a specific field of an action run.
For example it is possible to trigger the GitHub action and just update the log, without changing its status.
Note that once a Port action run has a status, it can no longer be updated and changes made to the catalog can no longer be tied to that action, so it is considered a best practice to update the status of an action only when it has finished performing all of its catalog changes and logic
That's it! The action status and logs are updated in Port.
---
# Gitlab CI Pipelines
Using Gitlab CI Pipelines, you can easily create/update and query entities in Port.
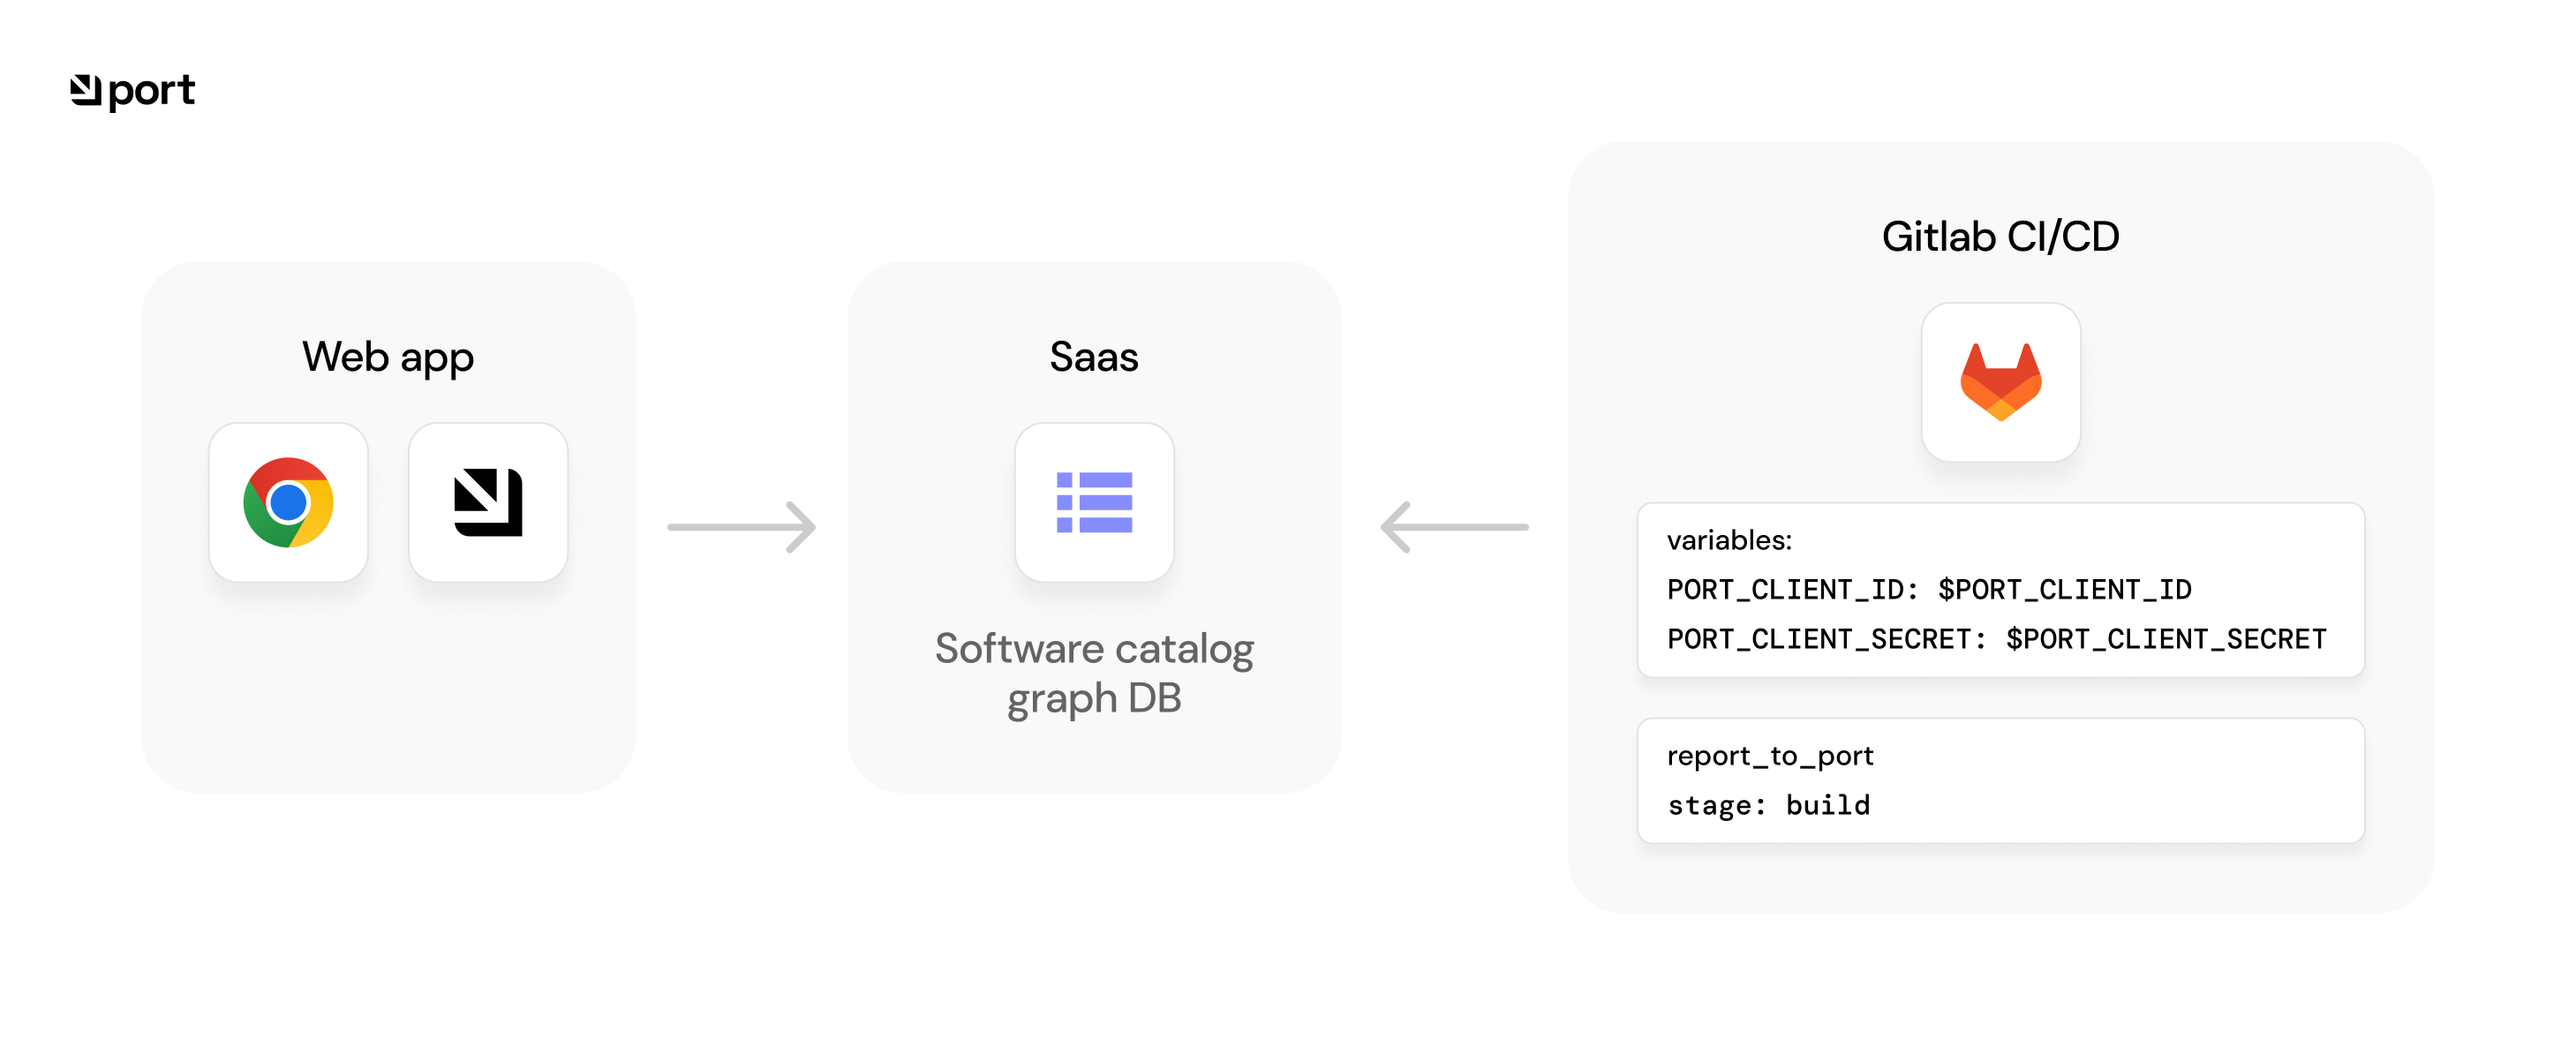
## 💡 Common Gitlab CI Pipelines usage[](#-common-gitlab-ci-pipelines-usage "Direct link to 💡 Common Gitlab CI Pipelines usage")
Port's API allows for easy integration between Port and your Gitlab CI Pipeline jobs, for example:
* Report the status of a running **CI job**.
* Update the software catalog about a new **build version** for a **microservice**.
* Get existing **entities**.
## Setup[](#setup "Direct link to Setup")
To interact with Port using Gitlab CI Pipeline, you will first need to [define your Port credentials](https://docs.gitlab.com/ee/ci/variables/index.html#define-a-cicd-variable-in-the-ui) as variables for your pipeline. Then, pass the defined variables to your ci pipeline script, for example, `Python`:
```
image: python:3.9
variables:
PORT_CLIENT_ID: $PORT_CLIENT_ID # The variable name for your Port clientId
PORT_CLIENT_SECRET: $PORT_CLIENT_SECRET # The variable name for your Port clientSecret
report_to_port:
stage: build
script:
- python main.py
```
Make sure you have an existing [Blueprint](/context-lake/data-model/setup-blueprint/overview/.md) in your Port installation to create/update entities.
## Working with Port's API[](#working-with-ports-api "Direct link to Working with Port's API")
Here is an example snippet showing how to integrate a job that uses Port's API with your existing Gitlab CI pipelines using Python:
Add the following task to your Gitlab pipeline:
**Gitlab pipeline YAML (click to expand)**
```
image: python:3.9
variables:
PORT_CLIENT_ID: $PORT_CLIENT_ID
PORT_CLIENT_SECRET: $PORT_CLIENT_SECRET
stages:
- build
report_to_port:
stage: build
before_script:
- python -m pip install --upgrade pip
- pip install -r requirements.txt
script:
- python main.py
```
Python dependencies required
In the following example, we use Python modules which need to be installed. You can use the following `requirements.txt`:
**port\_requirements.txt (click to expand)**
```
requests>=2.28.2
```
* Create/Update
* Get
Create the following Python script in your repository to create or update Port entities as part of your pipeline:
```
import os
import requests
import json
# These are the credentials passed by the variables of your pipeline to your tasks and in to your env
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
API_URL = 'https://api.port.io/v1'
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
# use this access token + header for all http requests to Port
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
entity_json = {
"identifier": "example-entity",
"properties": {
"myStringProp": "My value",
"myNumberProp": 1,
"myBooleanProp": true,
"myArrayProp": ["myVal1", "myVal2"],
"myObjectProp": {"myKey": "myVal", "myExtraKey": "myExtraVal"}
}
}
# request url : {API_URL}/blueprints//entities
create_response = requests.post(f'{API_URL}/blueprints/test-blueprint/entities?upsert=true', json=entity_json, headers=headers)
print(json.dumps(create_response.json(), indent=4))
```
Create the following Python script in your repository to get Port entities as part of your pipeline:
```
import os
import requests
import json
# These are the credentials passed by the variables of your pipeline to your tasks and in to your env
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
API_URL = 'https://api.port.io/v1'
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f'{API_URL}/auth/access_token', json=credentials)
# use this access token + header for all http requests to Port
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
# request url : {API_URL}/blueprints//entities/
get_response = requests.get(f"{API_URL}/blueprints/test-blueprint/entities/test-entity", headers=headers)
print(json.dumps(get_response.json(), indent=4))
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Examples[](#examples "Direct link to Examples")
Refer to the [examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/gitlab-pipelines/examples/.md) page for practical examples of working with Port using Gitlab CI Pipelines.
---
# Examples
## Basic create/update example[](#basic-createupdate-example "Direct link to Basic create/update example")
In this example you will create blueprints for `ciJob` and `image` entities, and a relation between them. Then you will add some Python code to create new entities in Port every time the Gitlab Pipeline is triggered:
**Image blueprint (click to expand)**
Create in Port
```
{
"identifier": "image",
"title": "Image",
"icon": "Docker",
"schema": {
"properties": {
"synkHighVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk High Vaulnerabilities"
},
"synkMediumVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk Medium Vaulnerabilities"
},
"imageTag": {
"type": "string",
"title": "Image Tag"
},
"gitRepoUrl": {
"type": "string",
"format": "url",
"title": "Git Url",
"description": "Git Url for the sourcecode"
},
"imageRegistry": {
"type": "string",
"format": "url",
"title": "Image Registry",
"description": "Docker registry"
},
"unitTestCoverage": {
"type": "number",
"title": "Unit Test coverage (%)",
"description": "The unit test coverage pecentage"
},
"integTestCoverage": {
"type": "number",
"title": "Integ Test coverage (%)",
"description": "The integration test coverage pecentage"
},
"size": {
"type": "number",
"title": "Image Size (GB)",
"description": "The image size in Gigabyte"
}
},
"required": []
},
"calculationProperties": {}
}
```
**CI Job blueprint (including the image relation) (click to expand)**
Create in Port
```
{
"identifier": "ciJob",
"title": "CI Job",
"icon": "CICD",
"schema": {
"properties": {
"triggeredBy": {
"type": "string",
"icon": "TwoUsers",
"title": "Triggered By",
"description": "The user who triggered the run"
},
"commitHash": {
"type": "string",
"title": "Commit Hash"
},
"jobBranch": {
"type": "string",
"icon": "Git",
"format": "url",
"title": "Job branch"
},
"runLink": {
"type": "string",
"format": "url",
"title": "Action Run Link"
}
},
"required": []
},
"relations": {
"image": {
"title": "Job Images",
"target": "image",
"required": false,
"many": true
}
},
"calculationProperties": {}
}
```
After creating the blueprint, you can add a Python script for creating/updating a Port entity:
```
import os
import requests
import json
# Env vars passed by the pipeline variables
CLIENT_ID = os.environ['PORT_CLIENT_ID']
CLIENT_SECRET = os.environ['PORT_CLIENT_SECRET']
API_URL = 'https://api.port.io/v1'
credentials = {
'clientId': CLIENT_ID,
'clientSecret': CLIENT_SECRET
}
token_response = requests.post(f"{API_URL}/auth/access_token", json=credentials)
# use this access token + header for all http requests to Port
access_token = token_response.json()['accessToken']
headers = {
'Authorization': f'Bearer {access_token}'
}
entity_json = {
"identifier": "new-cijob-run",
"properties": {
"triggeredBy": os.environ['QUEUED_BY'],
"commitHash": os.environ['GIT_SHA'],
"actionJob": os.environ['JOB_NAME'],
"jobLink": os.environ['JOB_URL']
},
"relations": {
"image": ["example-image"]
}
}
create_response = requests.post(f'{API_URL}/blueprints/{blueprint_id}/entities?upsert=true&create_missing_related_entities=true', json=entity_json, headers=headers)
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Relation auto-created
Please notice that you have also created the `image` relation, and added a related image entity called `example-image`. This is the artifact of the ciJob, and you will update it later. The creation was done using the `create_missing_related_entities=true` flag in the API url, allowing the relation to be created even though the `example-image` entity doesn't exist yet.
After adding your new Python script to your repository, add the following code to your Gitlab pipeline `yml` file to call your script and update/create a new `ciJob` entity:
```
image: python:3.9
variables:
PORT_CLIENT_ID: $PORT_CLIENT_ID
PORT_CLIENT_SECRET: $PORT_CLIENT_SECRET
QUEUED_BY: $CI_COMMIT_AUTHOR
GIT_SHA: $CI_COMMIT_SHA
JOB_NAME: $CI_JOB_NAME
RUN_LINK: $CI_PIPELINE_URL
stages:
- build
report_to_port:
stage: build
before_script:
- python -m pip install --upgrade pip
- pip install -r requirements.txt
script:
- python main.py
```
## Basic get example[](#basic-get-example "Direct link to Basic get example")
The following example gets the `new-cijob-run` entity from the previous example, this can be useful if your CI process creates a build artifact and then references some of its data (for example, the run link of the latest `ciJob`).
Add the following snippet to your Python code:
```
entity_id = "new-cijob-run"
blueprint_id = "ciJob"
get_response = requests.get(f"{API_URL}/blueprints/{blueprint_id}/entities/{entity_id}",
headers=headers)
entity = get_response.json()['entity']
print(f"Image tag is: {entity['properties']['runLink']}")
```
## Relation example[](#relation-example "Direct link to Relation example")
The following example demonstrates how to update the `example-image` entity that was automatically created when creating the `ciJob` entity shown in the previous example.
Add the following snippet to your Python code:
```
image_entity_json = {
"identifier": "example-image",
"team": [],
"properties": {
"imageTag": "v1",
"synkHighVulnerabilities": "0",
"synkMediumVulnerabilities": "0",
"gitRepoUrl": "https://github.com/my-org/my-cool-repo",
"imageRegistry": "docker.io/cool-image",
"size": "0.71",
"unitTestCoverage": "20",
"unitTestCoverage": "50"
},
"relations": {}
}
create_image_response = requests.post(f'{API_URL}/blueprints/image/entities?upsert=true', json=image_entity_json, headers=headers)
```
That's it! The entity is created or updated and is visible in the UI.
---
# Jenkins Deployment
Available Ocean integration
Port provides an [Ocean integration](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/jenkins/.md) for Jenkins, which allows you to automatically sync your Jenkins resources with Port and provides more configuration options. This is the **recommended** way to integrate Port with Jenkins.
If you would still prefer to use Port's API, follow this page.
Using Jenkins build, you can easily create/update and query entities in Port.
## 💡 Common Jenkins build usage[](#-common-jenkins-build-usage "Direct link to 💡 Common Jenkins build usage")
Port's API allows for easy integration between Port and your Jenkins builds, for example:
* Report the status of a running **CI job**.
* Update the software catalog about a new **build version** for a **microservice**.
* Get existing **entities**.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
1. This example makes use of the following Jenkins plugins:
* [Plain Credentials](https://plugins.jenkins.io/credentials-binding/) (>=143.v1b\_df8b\_d3b\_e48)
* [HTTP Request](https://plugins.jenkins.io/http_request/) (>=1.16)
2. The following methods are used in the example, and these signatures need to be approved:
```
new groovy.json.JsonSlurperClassic
method groovy.json.JsonSlurperClassic parseText java.lang.String
```
3. Add your `PORT_CLIENT_ID` and `PORT_CLIENT_SECRET` as [Jenkins Credentials](https://www.jenkins.io/doc/book/using/using-credentials/) to use them in your CI pipelines.
4. Make sure you have an existing [Blueprint](/context-lake/data-model/setup-blueprint/overview/.md) in your Port installation to create/update entities.
## Set up[](#set-up "Direct link to Set up")
API routes reference
All Port API routes used in this guide can be found in Port's [API documentation](/api-reference/port-api/).
To interact with Port inside your Jenkins builds, follow these steps:
### Fetching your API token[](#fetching-your-api-token "Direct link to Fetching your API token")
The following snippet shows you how to pass your `PORT_CLIENT_ID` and `PORT_CLIENT_SECRET` credentials to your build using `withCredentials`, which utilizes the Plain Credentials plugin to bind credentials to variables.
The snippet provided also includes saving Port's API URL as an environment variable for use in future stages and makes a request to Port's API using the credentials to get an access token:
**Get API token (click to expand)**
```
pipeline {
agent any
environment {
API_URL = "https://api.port.io"
}
...
withCredentials([
string(credentialsId: 'port-client-id', variable: 'PORT_CLIENT_ID'),
string(credentialsId: 'port-client-secret', variable: 'PORT_CLIENT_SECRET')
]){
// Token request body
auth_body = """
{
"clientId": "${PORT_CLIENT_ID}",
"clientSecret": "${PORT_CLIENT_SECRET}"
}
"""
// Make a request to fetch Port API's token
token_response = httpRequest contentType: 'APPLICATION_JSON',
httpMode: "POST",
requestBody: auth_body,
url: "${API_URL}/v1/auth/access_token"
// Parse the response to get the accessToken
def slurped_response = new JsonSlurperClassic().parseText(token_response.content)
def token = slurped_response.accessToken // Use this token for authentication with Port
...
}
```
### Working with Port's API[](#working-with-ports-api "Direct link to Working with Port's API")
Add the following code to your Jenkins build, to either create/update an entity, or get an existing one:
* Create/Update
* Get
```
import groovy.json.JsonSlurperClassic
...
auth_body = """
{
"clientId": "${PORT_CLIENT_ID}",
"clientSecret": "${PORT_CLIENT_SECRET}"
}
"""
token_response = httpRequest contentType: 'APPLICATION_JSON',
httpMode: "POST",
requestBody: auth_body,
url: "${API_URL}/v1/auth/access_token"
def slurped_response = new JsonSlurperClassic().parseText(token_response.content)
def token = slurped_response.accessToken // Port's access token
entity_body = """
{
"identifier": "example-entity",
"properties": {
"myStringProp": "My value",
"myNumberProp": 1,
"myBooleanProp": true,
"myArrayProp": ["myVal1", "myVal2"],
"myObjectProp": {"myKey": "myVal", "myExtraKey": "myExtraVal"}
}
}
"""
// request url : {API_URL}/blueprints//entities/
response = httpRequest contentType: "APPLICATION_JSON", httpMode: "POST",
url: "${API_URL}/v1/blueprints/blueprint/entities?upsert=true&merge=true",
requestBody: entity_body,
customHeaders: [
[name: "Authorization", value: "Bearer ${token}"],
]
println(response.content)
```
```
import groovy.json.JsonSlurperClassic
...
auth_body = """
{
"clientId": "${PORT_CLIENT_ID}",
"clientSecret": "${PORT_CLIENT_SECRET}"
}
"""
token_response = httpRequest contentType: 'APPLICATION_JSON',
httpMode: "POST",
requestBody: auth_body,
url: "${API_URL}/v1/auth/access_token"
def slurped_response = new JsonSlurperClassic().parseText(token_response.content)
def token = slurped_response.accessToken // Port's access token
response = httpRequest contentType: 'APPLICATION_JSON', httpMode: "GET",
url: "${API_URL}/v1/blueprints/blueprint/entities/entity-example",
customHeaders: [
[name: "Authorization", value: "Bearer ${token}"],
]
println(response.content)
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Examples[](#examples "Direct link to Examples")
Refer to the [examples](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/jenkins-deployment/examples/.md) page for practical examples for using Port with Jenkins.
---
# Examples
## Basic create/update example[](#basic-createupdate-example "Direct link to Basic create/update example")
Build user vars plugin required
For this example, the following plugin is a dependency:
* build user vars plugin (>=v1.9)
In this example you will create blueprints for `ciJob` and `image` entities, and a relation between them. Then you will add some Groovy code to create new entities in Port every time the Jenkins pipeline is triggered:
**Image blueprint (click to expand)**
Create in Port
```
{
"identifier": "image",
"title": "Image",
"icon": "Docker",
"schema": {
"properties": {
"synkHighVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk High Vaulnerabilities"
},
"synkMediumVulnerabilities": {
"type": "string",
"icon": "Snyk",
"title": "Synk Medium Vaulnerabilities"
},
"imageTag": {
"type": "string",
"title": "Image Tag"
},
"gitRepoUrl": {
"type": "string",
"format": "url",
"title": "Git Url",
"description": "Git Url for the sourcecode"
},
"imageRegistry": {
"type": "string",
"format": "url",
"title": "Image Registry",
"description": "Docker registry"
},
"unitTestCoverage": {
"type": "number",
"title": "Unit Test coverage (%)",
"description": "The unit test coverage pecentage"
},
"integTestCoverage": {
"type": "number",
"title": "Integ Test coverage (%)",
"description": "The integration test coverage pecentage"
},
"size": {
"type": "number",
"title": "Image Size (GB)",
"description": "The image size in Gigabyte"
}
},
"required": []
},
"calculationProperties": {}
}
```
**CI Job blueprint (including the image relation) (click to expand)**
Create in Port
```
{
"identifier": "ciJob",
"title": "CI Job",
"icon": "CICD",
"schema": {
"properties": {
"triggeredBy": {
"type": "string",
"icon": "TwoUsers",
"title": "Triggered By",
"description": "The user who triggered the run"
},
"commitHash": {
"type": "string",
"title": "Commit Hash"
},
"jobBranch": {
"type": "string",
"icon": "Git",
"format": "url",
"title": "Job branch"
},
"runLink": {
"type": "string",
"format": "url",
"title": "Action Run Link"
}
},
"required": []
},
"relations": {
"image": {
"title": "Job Images",
"target": "image",
"required": false,
"many": true
}
},
"calculationProperties": {}
}
```
Token and API\_URL from setup
The variables `token` and `API_URL` are used in the following examples. Click [here](/context-lake/ingestion/ingest-data-into-port/api/ci-cd/jenkins-deployment/.md#fetching-your-api-token) to see how they were defined.
After creating the blueprint, you can add the following snippet to your Jenkins build to create the new build entity:
```
// Use the `build users` plugin to fetch the triggering user's ID
wrap([$class: 'BuildUser']) {
def user = env.BUILD_USER_ID
}
def body = """
{
"identifier": "new-cijob-run",
"properties": {
"triggeredBy": "${user}",
"runLink": "${env.BUILD_URL}",
},
"relations": {
"image": ["example-image"]
}
}
"""
response = httpRequest contentType: "APPLICATION_JSON", httpMode: "POST",
url: "${API_URL}/v1/blueprints/ciJob/entities?upsert=true&merge=true&create_missing_related_entities=true",
requestBody: body,
customHeaders: [
[name: "Authorization", value: "Bearer ${token}"],
]
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Relation auto-created
Please notice that you have also created the `image` relation, and added a related image entity called `example-image`. This is the artifact of the ciJob, and you will update it later. The creation was done using the `create_missing_related_entities=true` flag in the API url, allowing the relation to be created even though the `example-image` entity doesn't exist yet.
## Basic get example[](#basic-get-example "Direct link to Basic get example")
The following example gets the `new-cijob-run` entity from the previous example, this can be useful if your CI process creates a build artifact and then references some of its data (for example, the run link of the latest `ciJob`).
Add the following code to your Jenkins build:
```
response = httpRequest contentType: "APPLICATION_JSON", httpMode: "GET",
url: "${API_URL}/v1/blueprints/ciJob/entities/new-cijob-run",
customHeaders: [
[name: "Authorization", value: "Bearer ${token}"],
]
println(response.content)
```
## Relation example[](#relation-example "Direct link to Relation example")
The following example demonstrates how to update the `example-image` entity that was automatically created when creating the `ciJob` entity shown in the previous example.
Add the following snippet to your Jenkins Pipeline:
```
def body = """
{
"identifier": "example-image",
"properties": {
"imageTag": "v1",
"synkHighVulnerabilities": "0",
"synkMediumVulnerabilities": "0",
"gitRepoUrl": "https://github.com/my-org/my-cool-repo",
"imageRegistry": "docker.io/cool-image",
"size": "0.71",
"unitTestCoverage": "20",
"unitTestCoverage": "50"
},
"relations": {}
}
"""
response = httpRequest contentType: "APPLICATION_JSON", httpMode: "POST",
url: "${API_URL}/v1/blueprints/image/entities?upsert=true&merge=true",
requestBody: body,
customHeaders: [
[name: "Authorization", value: "Bearer ${token}"],
]
```
That's it! The entity is created or updated and is visible in the UI.
---
# Ingest via API
Port's [API](/api-reference/port-api/) is a generic interface to model your software catalog, ingest data, invoke actions, query scorecards and more.
## 💡 Common Port API usage[](#-common-port-api-usage "Direct link to 💡 Common Port API usage")
Since Port API is a generic interface, anything that can be done with Port is possible through the API, for example:
* Update the software catalog using a script.
* Import your existing asset inventory from a CSV file.
* Integrate Port with your custom CI/CD.
* Report the status of a running **CI job**.
* Update the software catalog about a new **build version** for a **microservice**.
* Get existing data from your software catalog.
## Get API Token[](#get-api-token "Direct link to Get API Token")
In order to interact with the API you will need an API token.
Getting an API token involves 2 steps:
1. Finding your Port API credentials.
2. Making an API request to generate a valid token.
### Find your Port credentials[](#find-your-port-credentials "Direct link to Find your Port credentials")
To get your Port credentials, open the [Credentials](https://app.port.io/organization/home?openModal=credentials) modal. Here you can view and copy your `CLIENT_ID` and `CLIENT_SECRET`:
### Generate an API token[](#generate-an-api-token "Direct link to Generate an API token")
Here are some code examples showing how to generate an API token in various programming languages:
* Python
* Javascript
* cURL
```
# Dependencies to install:
# $ python -m pip install requests
import requests
CLIENT_ID = 'YOUR_CLIENT_ID'
CLIENT_SECRET = 'YOUR_CLIENT_SECRET'
API_URL = 'https://api.port.io/v1'
credentials = {'clientId': CLIENT_ID, 'clientSecret': CLIENT_SECRET}
token_response = requests.post(f'{API_URL}/auth/access_token', json=credentials)
access_token = token_response.json()['accessToken']
# You can now use the value in access_token when making further requests
```
```
// Dependencies to install:
// $ npm install axios --save
const axios = require("axios").default;
const CLIENT_ID = "YOUR_CLIENT_ID";
const CLIENT_SECRET = "YOUR_CLIENT_SECRET";
const API_URL = "https://api.port.io/v1";
(async () => {
const response = await axios.post(`${API_URL}/auth/access_token`, {
clientId: CLIENT_ID,
clientSecret: CLIENT_SECRET,
});
const accessToken = response.data.accessToken;
// You can now use the value in accessToken when making further requests
})();
```
```
# Dependencies to install:
# For apt:
# $ sudo apt-get install jq
# For yum:
# $ sudo yum install jq
access_token=$(curl --location --request POST 'https://api.port.io/v1/auth/access_token' \
--header 'Content-Type: application/json' \
--data-raw '{
"clientId": "CLIENT_ID",
"clientSecret": "CLIENT_SECRET"
}' | jq '.accessToken' | sed 's/"//g')
# The token will be available in the access_token variable
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Ingest data via API[](#ingest-data-via-api "Direct link to Ingest data via API")
Since Port is API-first it is possible to create and update entities using simple REST calls from any platform you use.
### Setup[](#setup "Direct link to Setup")
To use Port's REST API you need to perform the following steps:
1. Find your [Port credentials](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md#find-your-port-credentials).
2. Save them as secrets or in some other same manner such that you can reference them in your code or CI/CD flow.
3. Make sure you have an HTTP-capable client.
1. For example: cURL, python with the requests package, nodejs with fetch/axios, etc.
### Usage[](#usage "Direct link to Usage")
Since you are using Port's REST API directly, any method that the API provides is at your disposal.
We will focus on three specific use cases:
* **Get** catalog entities - available by making HTTP GET requests to `https://api.port.io/v1/blueprints/{blueprint_identifier}/entities/{entity_identifier}`, receives the identifier of an existing entity and retrieves it for use in your CI.
* **Create/Update** catalog entities - available by making HTTP POST requests to `https://api.port.io/v1/blueprints/{blueprint_identifier}/entities/`, receives the identifier and other properties of a new entity or an entity that needs to be updated.
* **Delete** catalog entities - available by making HTTP DELETE requests to `https://api.port.io/v1/blueprints/{blueprint_identifier}/entities/{entity_identifier}`, receives the identifier of an existing entity and deletes it.
- Get
- Create
- Create/Update
- Create/Override
- Delete
- Delete All
* Python
* Javascript
* cURL
```
# Dependencies to install:
# $ python -m pip install requests
import requests
CLIENT_ID = 'YOUR_CLIENT_ID'
CLIENT_SECRET = 'YOUR_CLIENT_SECRET'
API_URL = 'https://api.port.io/v1'
credentials = {'clientId': CLIENT_ID, 'clientSecret': CLIENT_SECRET}
token_response = requests.post(f'{API_URL}/auth/access_token', json=credentials)
access_token = token_response.json()['accessToken']
# You can now use the value in access_token when making further requests
headers = {
'Authorization': f'Bearer {access_token}'
}
blueprint_id = 'MY_BLUEPRINT'
entity_id = 'MY_ENTITY_IDENTIFIER'
response = requests.get(f'{API_URL}/blueprints/{blueprint_id}/entities/{entity_id}', headers=headers)
# Entity is in response.json()["entity"]
```
```
// Dependencies to install:
// $ npm install axios --save
const axios = require("axios").default;
const CLIENT_ID = "YOUR_CLIENT_ID";
const CLIENT_SECRET = "YOUR_CLIENT_SECRET";
const API_URL = "https://api.port.io/v1";
(async () => {
const response = await axios.post(`${API_URL}/auth/access_token`, {
clientId: CLIENT_ID,
clientSecret: CLIENT_SECRET,
});
const accessToken = response.data.accessToken;
// You can now use the value in accessToken when making further requests
const blueprintId = "MY_BLUEPRINT";
const entityId = "MY_ENTITY_IDENTIFIER";
const config = {
headers: {
Authorization: `Bearer ${accessToken}`,
},
};
const getResponse = await axios.get(
`${API_URL}/blueprints/${blueprintId}/entities/${entityId}`,
config
);
// Entity is in getResponse.data.entity
})();
```
```
# Dependencies to install:
# for brew:
# brew install jq
# For apt:
# $ sudo apt-get install jq
# For yum:
# $ sudo yum install jq
access_token=$(curl --location --request POST 'https://api.port.io/v1/auth/access_token' \
--header 'Content-Type: application/json' \
--data-raw '{
"clientId": "CLIENT_ID",
"clientSecret": "CLIENT_SECRET"
}' | jq '.accessToken' | sed 's/"//g')
# The token will be available in the access_token variable
blueprint_id='MY_BLUEPRINT'
entity_id='MY_ENTITY_IDENTIFIER'
curl --location --request GET "https://api.port.io/v1/blueprints/${blueprint_id}/entities/${entity_id}" \
--header "Authorization: Bearer $access_token" \
--header "Content-Type: application/json"
# Use jq '.entity' to read the entity
```
A basic create request will create a new entity if one with the provided `identifier` doesn't exist yet, and will fail with a `409 CONFLICT` status code otherwise.
A basic create request is noted by providing no query parameters, or providing the `upsert` query parameter with its value set to `false`.
* Python
* Javascript
* cURL
```
# Dependencies to install:
# $ python -m pip install requests
import requests
CLIENT_ID = 'YOUR_CLIENT_ID'
CLIENT_SECRET = 'YOUR_CLIENT_SECRET'
API_URL = 'https://api.port.io/v1'
credentials = {'clientId': CLIENT_ID, 'clientSecret': CLIENT_SECRET}
token_response = requests.post(f'{API_URL}/auth/access_token', json=credentials)
access_token = token_response.json()['accessToken']
# You can now use the value in access_token when making further requests
headers = {
'Authorization': f'Bearer {access_token}'
}
blueprint_id = 'MY_BLUEPRINT'
entity = {
'identifier': 'MY_ENTITY_IDENTIFIER',
'title': 'MY TITLE',
'properties': {
'MY_STRING_PROP': 'MY VALUE',
'MY_BOOLEAN_PROP': False
},
'relations': {}
}
response = requests.post(f'{API_URL}/blueprints/{blueprint_id}/entities', json=entity, headers=headers)
# Entity is in response.json()["entity"]
```
```
// Dependencies to install:
// $ npm install axios --save
const axios = require("axios").default;
const CLIENT_ID = "YOUR_CLIENT_ID";
const CLIENT_SECRET = "YOUR_CLIENT_SECRET";
const API_URL = "https://api.port.io/v1";
(async () => {
const response = await axios.post(`${API_URL}/auth/access_token`, {
clientId: CLIENT_ID,
clientSecret: CLIENT_SECRET,
});
const accessToken = response.data.accessToken;
// You can now use the value in accessToken when making further requests
const blueprintId = "MY_BLUEPRINT";
const config = {
headers: {
Authorization: `Bearer ${accessToken}`,
},
};
const entity = {
identifier: "MY_ENTITY_IDENTIFIER",
title: "MY TITLE",
properties: {
MY_STRING_PROP: "MY VALUE",
MY_BOOLEAN_PROP: false,
},
relations: {},
};
const postResponse = await axios.post(
`${API_URL}/blueprints/${blueprintId}/entities`,
entity,
config
);
// Entity is in postResponse.data.entity
})();
```
```
# Dependencies to install:
# For apt:
# $ sudo apt-get install jq
# For yum:
# $ sudo yum install jq
access_token=$(curl --location --request POST 'https://api.port.io/v1/auth/access_token' \
--header 'Content-Type: application/json' \
--data-raw '{
"clientId": "CLIENT_ID",
"clientSecret": "CLIENT_SECRET"
}' | jq '.accessToken' | sed 's/"//g')
# The token will be available in the access_token variable
blueprint_id='MY_BLUEPRINT'
curl --location --request POST "https://api.port.io/v1/blueprints/${blueprint_id}/entities" \
--header "Authorization: Bearer $access_token" \
--header "Content-Type: application/json" \
--data-raw '{
"identifier": "MY_ENTITY_IDENTIFIER",
"title": "MY ENTITY TITLE",
"properties": {
"MY_STRING_PROP": "MY VALUE",
"MY_BOOLEAN_PROP": false
}
}'
# Use jq '.entity' to read the entity
```
A create/update request will create a new entity if one with the provided `identifier` doesn't exist yet, and will only update the values of fields provided in the request, if an entity with the `identifier` already exists.
A create/update request is noted by providing the query parameter: `upsert=true&merge=true`.
* Python
* Javascript
* cURL
```
# Dependencies to install:
# $ python -m pip install requests
import requests
CLIENT_ID = 'YOUR_CLIENT_ID'
CLIENT_SECRET = 'YOUR_CLIENT_SECRET'
API_URL = 'https://api.port.io/v1'
credentials = {'clientId': CLIENT_ID, 'clientSecret': CLIENT_SECRET}
token_response = requests.post(f'{API_URL}/auth/access_token', json=credentials)
access_token = token_response.json()['accessToken']
# You can now use the value in access_token when making further requests
headers = {
'Authorization': f'Bearer {access_token}'
}
blueprint_id = 'MY_BLUEPRINT'
entity = {
'identifier': 'MY_ENTITY_IDENTIFIER',
'title': 'MY TITLE',
'properties': {
'MY_STRING_PROP': 'MY VALUE',
'MY_BOOLEAN_PROP': False
},
'relations': {}
}
# Note the ?upsert=true&merge=true query parameters
response = requests.post(f'{API_URL}/blueprints/{blueprint_id}/entities?upsert=true&merge=true', json=entity, headers=headers)
# Entity is in response.json()["entity"]
```
```
// Dependencies to install:
// $ npm install axios --save
const axios = require("axios").default;
const CLIENT_ID = "YOUR_CLIENT_ID";
const CLIENT_SECRET = "YOUR_CLIENT_SECRET";
const API_URL = "https://api.port.io/v1";
(async () => {
const response = await axios.post(`${API_URL}/auth/access_token`, {
clientId: CLIENT_ID,
clientSecret: CLIENT_SECRET,
});
const accessToken = response.data.accessToken;
// You can now use the value in accessToken when making further requests
const blueprintId = "MY_BLUEPRINT";
const config = {
headers: {
Authorization: `Bearer ${accessToken}`,
},
};
const entity = {
identifier: "MY_ENTITY_IDENTIFIER",
title: "MY TITLE",
properties: {
MY_STRING_PROP: "MY VALUE",
MY_BOOLEAN_PROP: false,
},
relations: {},
};
// Note the ?upsert=true&merge=true query parameters
const postResponse = await axios.post(
`${API_URL}/blueprints/${blueprintId}/entities?upsert=true&merge=true`,
entity,
config
);
// Entity is in postResponse.data.entity
})();
```
```
# Dependencies to install:
# For apt:
# $ sudo apt-get install jq
# For yum:
# $ sudo yum install jq
access_token=$(curl --location --request POST 'https://api.port.io/v1/auth/access_token' \
--header 'Content-Type: application/json' \
--data-raw '{
"clientId": "CLIENT_ID",
"clientSecret": "CLIENT_SECRET"
}' | jq '.accessToken' | sed 's/"//g')
# The token will be available in the access_token variable
blueprint_id='MY_BLUEPRINT'
# Note the ?upsert=true&merge=true query parameters
curl --location --request POST "https://api.port.io/v1/blueprints/${blueprint_id}/entities?upsert=true&merge=true" \
--header "Authorization: Bearer $access_token" \
--header "Content-Type: application/json" \
--data-raw '{
"identifier": "MY_ENTITY_IDENTIFIER",
"title": "MY ENTITY TITLE",
"properties": {
"MY_STRING_PROP": "MY VALUE",
"MY_BOOLEAN_PROP": false
}
}'
# Use jq '.entity' to read the entity
```
A create/override request will create a new entity if one with the provided `identifier` doesn't exist yet, and will override all existing values if an entity with the `identifier` already exists, keeping only the values of fields provided in the request.
A create/override request is noted by providing the query parameter: `upsert=true`, while not including the `merge` parameter (or setting its value to `false`)
* Python
* Javascript
* cURL
```
# Dependencies to install:
# $ python -m pip install requests
import requests
CLIENT_ID = 'YOUR_CLIENT_ID'
CLIENT_SECRET = 'YOUR_CLIENT_SECRET'
API_URL = 'https://api.port.io/v1'
credentials = {'clientId': CLIENT_ID, 'clientSecret': CLIENT_SECRET}
token_response = requests.post(f'{API_URL}/auth/access_token', json=credentials)
access_token = token_response.json()['accessToken']
# You can now use the value in access_token when making further requests
headers = {
'Authorization': f'Bearer {access_token}'
}
blueprint_id = 'MY_BLUEPRINT'
entity = {
'identifier': 'MY_ENTITY_IDENTIFIER',
'title': 'MY TITLE',
'properties': {
'MY_STRING_PROP': 'MY VALUE',
'MY_BOOLEAN_PROP': False
},
'relations': {}
}
# Note the ?upsert=true query parameter
response = requests.post(f'{API_URL}/blueprints/{blueprint_id}/entities?upsert=true', json=entity, headers=headers)
# Entity is in response.json()["entity"]
```
```
// Dependencies to install:
// $ npm install axios --save
const axios = require("axios").default;
const CLIENT_ID = "YOUR_CLIENT_ID";
const CLIENT_SECRET = "YOUR_CLIENT_SECRET";
const API_URL = "https://api.port.io/v1";
(async () => {
const response = await axios.post(`${API_URL}/auth/access_token`, {
clientId: CLIENT_ID,
clientSecret: CLIENT_SECRET,
});
const accessToken = response.data.accessToken;
// You can now use the value in accessToken when making further requests
const blueprintId = "MY_BLUEPRINT";
const config = {
headers: {
Authorization: `Bearer ${accessToken}`,
},
};
const entity = {
identifier: "MY_ENTITY_IDENTIFIER",
title: "MY TITLE",
properties: {
MY_STRING_PROP: "MY VALUE",
MY_BOOLEAN_PROP: false,
},
relations: {},
};
// Note the ?upsert=true query parameter
const postResponse = await axios.post(
`${API_URL}/blueprints/${blueprintId}/entities?upsert=true`,
entity,
config
);
// Entity is in postResponse.data.entity
})();
```
```
# Dependencies to install:
# For apt:
# $ sudo apt-get install jq
# For yum:
# $ sudo yum install jq
access_token=$(curl --location --request POST 'https://api.port.io/v1/auth/access_token' \
--header 'Content-Type: application/json' \
--data-raw '{
"clientId": "CLIENT_ID",
"clientSecret": "CLIENT_SECRET"
}' | jq '.accessToken' | sed 's/"//g')
# The token will be available in the access_token variable
blueprint_id='MY_BLUEPRINT'
# Note the ?upsert=true query parameter
curl --location --request POST "https://api.port.io/v1/blueprints/${blueprint_id}/entities?upsert=true" \
--header "Authorization: Bearer $access_token" \
--header "Content-Type: application/json" \
--data-raw '{
"identifier": "MY_ENTITY_IDENTIFIER",
"title": "MY ENTITY TITLE",
"properties": {
"MY_STRING_PROP": "MY VALUE",
"MY_BOOLEAN_PROP": false
}
}'
# Use jq '.entity' to read the entity
```
* Python
* Javascript
* cURL
```
# Dependencies to install:
# $ python -m pip install requests
import requests
CLIENT_ID = 'YOUR_CLIENT_ID'
CLIENT_SECRET = 'YOUR_CLIENT_SECRET'
API_URL = 'https://api.port.io/v1'
credentials = {'clientId': CLIENT_ID, 'clientSecret': CLIENT_SECRET}
token_response = requests.post(f'{API_URL}/auth/access_token', json=credentials)
access_token = token_response.json()['accessToken']
# You can now use the value in access_token when making further requests
headers = {
'Authorization': f'Bearer {access_token}'
}
blueprint_id = 'MY_BLUEPRINT'
entity_id = 'MY_ENTITY'
response = requests.delete(f'{API_URL}/blueprints/{blueprint_id}/entities/{entity_id}', headers=headers)
# response.json() is {"ok": true}
```
```
// Dependencies to install:
// $ npm install axios --save
const axios = require("axios").default;
const CLIENT_ID = "YOUR_CLIENT_ID";
const CLIENT_SECRET = "YOUR_CLIENT_SECRET";
const API_URL = "https://api.port.io/v1";
(async () => {
const response = await axios.post(`${API_URL}/auth/access_token`, {
clientId: CLIENT_ID,
clientSecret: CLIENT_SECRET,
});
const accessToken = response.data.accessToken;
// You can now use the value in accessToken when making further requests
const blueprintId = "MY_BLUEPRINT";
const entityId = "MY_ENTITY";
const config = {
headers: {
Authorization: `Bearer ${accessToken}`,
},
};
const deleteResponse = await axios.delete(
`${API_URL}/blueprints/${blueprintId}/entities/${entityId}`,
config
);
// deleteResponse.data is {ok: true}
})();
```
```
# Dependencies to install:
# For apt:
# $ sudo apt-get install jq
# For yum:
# $ sudo yum install jq
access_token=$(curl --location --request POST 'https://api.port.io/v1/auth/access_token' \
--header 'Content-Type: application/json' \
--data-raw '{
"clientId": "CLIENT_ID",
"clientSecret": "CLIENT_SECRET"
}' | jq '.accessToken' | sed 's/"//g')
# The token will be available in the access_token variable
blueprint_id='MY_BLUEPRINT'
entity_id='MY_ENTITY'
curl --location --request DELETE "https://api.port.io/v1/blueprints/${blueprint_id}/entities/${entity_id}" \
--header "Authorization: Bearer $access_token"
# Response is {"ok": true}
```
It is possible to delete all entities of a blueprint with a single request using a dedicated route.
It is also possible to delete the blueprint containing the entities within the same delete operation by adding the `delete_blueprint=true` query parameter, for example: `https://api.port.io/v1/blueprints//all-entities?delete_blueprint=true`.
limitation
The delete all route can only be used if the blueprint does not have required relations.
* Python
* Javascript
* cURL
```
# Dependencies to install:
# $ python -m pip install requests
import requests
CLIENT_ID = 'YOUR_CLIENT_ID'
CLIENT_SECRET = 'YOUR_CLIENT_SECRET'
API_URL = 'https://api.port.io/v1'
credentials = {'clientId': CLIENT_ID, 'clientSecret': CLIENT_SECRET}
token_response = requests.post(f'{API_URL}/auth/access_token', json=credentials)
access_token = token_response.json()['accessToken']
# You can now use the value in access_token when making further requests
headers = {
'Authorization': f'Bearer {access_token}'
}
blueprint_id = 'MY_BLUEPRINT'
response = requests.delete(f'{API_URL}/blueprints/{blueprint_id}/all-entities', headers=headers)
# response.json() is {"ok": true}
```
```
// Dependencies to install:
// $ npm install axios --save
const axios = require("axios").default;
const CLIENT_ID = "YOUR_CLIENT_ID";
const CLIENT_SECRET = "YOUR_CLIENT_SECRET";
const API_URL = "https://api.port.io/v1";
(async () => {
const response = await axios.post(`${API_URL}/auth/access_token`, {
clientId: CLIENT_ID,
clientSecret: CLIENT_SECRET,
});
const accessToken = response.data.accessToken;
// You can now use the value in accessToken when making further requests
const blueprintId = "MY_BLUEPRINT";
const config = {
headers: {
Authorization: `Bearer ${accessToken}`,
},
};
const deleteResponse = await axios.delete(
`${API_URL}/blueprints/${blueprintId}/all-entities`,
config
);
// deleteResponse.data is {ok: true}
})();
```
```
# Dependencies to install:
# For apt:
# $ sudo apt-get install jq
# For yum:
# $ sudo yum install jq
access_token=$(curl --location --request POST 'https://api.port.io/v1/auth/access_token' \
--header 'Content-Type: application/json' \
--data-raw '{
"clientId": "CLIENT_ID",
"clientSecret": "CLIENT_SECRET"
}' | jq '.accessToken' | sed 's/"//g')
# The token will be available in the access_token variable
blueprint_id='MY_BLUEPRINT'
curl --location --request DELETE "https://api.port.io/v1/blueprints/${blueprint_id}/all-entities" \
--header "Authorization: Bearer $access_token"
# Response is {"ok": true}
```
Delete all entities via the UI
It is also possible to delete all entities using Port's web UI:
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Click on the "Delete All `BLUEPRINT_NAME`" button on the desired blueprint.
3. Follow the instructions.
**Note:** only users with the [admin](/platform-administration/users-and-teams/manage-users-teams/.md#roles--permissions) role can use Port's UI to perform the delete all operation.
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Rate limits[](#rate-limits "Direct link to Rate limits")
For more information about Port's rate limits and how to avoid them, check out the [rate limits page](/api-reference/rate-limits/).
---
# Implement an API client
The API client is the only place that should talk to the third-party system. Keep authentication, pagination, and rate limiting there, and call the client from resync handlers and live event processors.
## Use Ocean's async HTTP client[](#use-oceans-async-http-client "Direct link to Use Ocean's async HTTP client")
Prefer `http_async_client` from Ocean instead of `requests` or a new `httpx.AsyncClient`. Ocean's client is shared, async-friendly, and aligned with Ocean's retries, timeouts, and logging.
```
from httpx import Timeout
from port_ocean.context.ocean import ocean
from port_ocean.utils import http_async_client
class MyClient:
def __init__(self) -> None:
self.base_url = ocean.integration_config["apiBaseUrl"].rstrip("/")
self.client = http_async_client
self.client.headers["Authorization"] = (
f"Bearer {ocean.integration_config['apiToken']}"
)
self.client.timeout = Timeout(30)
```
Read secrets and settings from `ocean.integration_config`. Keys match the camelCase `name` values in `.port/spec.yaml`.
## Pagination and batching[](#pagination-and-batching "Direct link to Pagination and batching")
Fetch pages from the third-party API and yield batches of raw objects (lists of dicts). Do not load the entire dataset into memory when the API supports pagination.
```
from typing import Any, AsyncGenerator
async def get_paginated_items(self) -> AsyncGenerator[list[dict[str, Any]], None]:
url = f"{self.base_url}/items"
params: dict[str, Any] = {"limit": 100}
while url:
response = await self.client.get(url, params=params)
response.raise_for_status()
body = response.json()
yield body["items"]
url = body.get("next")
params = {}
```
## Practices[](#practices "Direct link to Practices")
* Keep I/O async so you do not block Ocean's event loop.
* Centralize request helpers so auth headers and error handling stay consistent.
* If you register webhooks in the third-party system on startup, put that logic on the client and call it from `@ocean.on_start()`.
* Return API payloads as close to the source as practical. Enrich with custom fields only under keys that start with `__` (for example `__team_id`) so they do not collide with upstream fields.
## Next steps[](#next-steps "Direct link to Next steps")
* [Handle resyncs](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/resyncs/.md).
* [Development guidelines](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/guidelines/.md).
---
# Define configuration files
Ocean loads resources from the `.port` directory when the integration starts. The scaffold creates this layout:
```
my-integration/
└── .port/
├── spec.yaml
└── resources/
├── blueprints.json
└── port-app-config.yaml
```
| File | Required | Role |
| -------------------------------- | -------- | ------------------------------------------------------------------------------------------- |
| `spec.yaml` | Yes | Integration type, supported kinds, user config schema, and features. |
| `resources/blueprints.json` | No | Default blueprints created or updated on start (when `initializePortResources` is enabled). |
| `resources/port-app-config.yaml` | No | Default [mapping](/context-lake/ingestion/configure-mapping/overview/.md) for those kinds. |
File names
Scaffolds may use `.yaml` or `.yml`. Use the names your scaffold generated.
## `spec.yaml`[](#specyaml "Direct link to specyaml")
`spec.yaml` declares how Port presents the integration and which parameters users must provide.
Typical sections:
.port/spec.yaml
```
type: myIntegration
description: My integration for Port
icon: Default
features:
- type: exporter
section: Other
resources:
- kind: my-kind
configurations:
- name: apiBaseUrl
required: true
type: url
description: Base URL of the third-party API
- name: apiToken
required: true
type: string
sensitive: true
description: API token for the third-party API
```
| Field | Purpose |
| ---------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `type` | Integration type identifier (also used for image naming conventions). |
| `features[].resources` | Kinds your resync handlers support. |
| `configurations` | User-facing parameters. Validated at startup. See [configuration validation](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/configuration-validation/.md). |
For each `configurations` entry, set `name` (camelCase), `required`, `type` (`string`, `integer`, `boolean`, `object`, `url`, and related types), `description`, and `sensitive` when the value is a secret.
## Default blueprints and mapping[](#default-blueprints-and-mapping "Direct link to Default blueprints and mapping")
`blueprints.json` and `port-app-config.yaml` are optional. When present and `initializePortResources` is `true` (default), Ocean creates or updates them in Port on start.
Author mapping so that:
* Each `kind` matches a `@ocean.on_resync` handler (or a live event kind you support).
* JQ expressions read fields from the **raw** objects your code yields.
* Users can later edit the mapping in Port without changing your integration code.
See [configure mapping](/context-lake/ingestion/configure-mapping/overview/.md) for mapping structure and JQ patterns.
Changing defaults after install
After the first install, changing `.port/resources/` on disk does not always overwrite what is already in Port. Update blueprints and mapping in the Port UI or API when the integration is already installed.
## Next steps[](#next-steps "Direct link to Next steps")
* [Implement an API client](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/api-client/.md).
* [Kinds and selectors](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/kinds-and-selectors/.md) if you need custom mapping fields.
---
# Configuration validation
Ocean validates integration configuration against `.port/spec.yaml` before the integration starts its work. Invalid types or missing required fields prevent a bad config from running mid-sync.
Declare parameters under `configurations` in `spec.yaml`. See [define configuration files](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/configuration-files/.md).
## Supported types[](#supported-types "Direct link to Supported types")
| Type | Example value |
| --------- | ------------------------- |
| `string` | `my-token` |
| `integer` | `123` |
| `boolean` | `true` |
| `object` | `{"key": "value"}` |
| `url` | `https://api.example.com` |
.port/spec.yaml
```
configurations:
- name: apiBaseUrl
type: url
required: true
description: Base URL of the third-party API
- name: enableFeature
type: boolean
required: false
description: Toggle an optional feature
```
If a user sets `enableFeature` to a non-boolean value, Ocean rejects the configuration at startup.
Values arrive in your code through `ocean.integration_config` after validation. For local runs, set the matching `OCEAN__INTEGRATION__CONFIG__*` environment variables as described in [test and run locally](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/testing/.md).
---
# Ocean and event contexts
Ocean exposes two context objects you can import in integration code.
## Ocean context[](#ocean-context "Direct link to Ocean context")
Import `ocean` from `port_ocean.context.ocean`. Common attributes and helpers:
| Access | Purpose |
| -------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------ |
| `ocean.integration_config` | User configuration from `spec.yaml` / env (camelCase keys). |
| `ocean.config` | Full Ocean settings object. |
| `ocean.port_client` | Client Ocean uses to talk to Port's API. |
| `ocean.router` | FastAPI router for custom HTTP routes under the integration. |
| `ocean.on_resync` | Decorator to register resync handlers. |
| `ocean.on_start` | Decorator for startup hooks. |
| `ocean.on_probe` | Decorator for [connection probe](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/connection-probe/.md) checks. |
| `ocean.add_webhook_processor` | Register a live event processor. |
| `ocean.register_action_executor` | Register an [action](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/actions-processing/.md) executor. |
| `ocean.event_listener_type` | Active listener type (for example `POLLING` or `ONCE`). |
```
from port_ocean.context.ocean import ocean
from port_ocean.core.ocean_types import ASYNC_GENERATOR_RESYNC_TYPE
@ocean.on_resync("project")
async def on_resync_projects(kind: str) -> ASYNC_GENERATOR_RESYNC_TYPE:
base_url = ocean.integration_config["apiBaseUrl"]
...
```
## Event context[](#event-context "Direct link to Event context")
Import `event` from `port_ocean.context.event`. It is available only while Ocean is handling an event (resync, start, or HTTP request).
| Access | Purpose |
| ----------------------- | ------------------------------------------------------------------------- |
| `event.type` | Event type (for example `resync`, `start`, `http_request`). |
| `event.trigger_type` | How the event was triggered (for example `manual`, `machine`, `request`). |
| `event.resource_config` | Mapping entry for the current kind during a resync. |
| `event.port_app_config` | Full Port app config for the resync. |
| `event.attributes` | Per-event dict for caching shared lookups during that event. |
```
from port_ocean.context.event import event
resource_config = event.resource_config
event_type = event.type
```
---
# Deploy a custom-coded Ocean integration
Scaffolds include a `Dockerfile`. Build your own image, then run it with Docker or deploy it with the Ocean Helm chart using that image.
## Build a Docker image[](#build-a-docker-image "Direct link to Build a Docker image")
From the integration directory (adjust the tag as needed):
```
docker build -t my-custom-coded-ocean-integration:latest .
```
The scaffold Dockerfile installs Poetry dependencies and runs the Ocean process. Keep secrets out of the image. Pass Port credentials and integration config as environment variables or Kubernetes secrets at runtime.
### Run with Docker[](#run-with-docker "Direct link to Run with Docker")
```
docker run --rm \
-e OCEAN__PORT__CLIENT_ID="" \
-e OCEAN__PORT__CLIENT_SECRET="" \
-e OCEAN__INTEGRATION__IDENTIFIER="my-private-integration" \
-e OCEAN__INTEGRATION__TYPE="myIntegration" \
-e OCEAN__EVENT_LISTENER__TYPE="POLLING" \
-e OCEAN__INTEGRATION__CONFIG__API_BASE_URL="https://api.example.com" \
-e OCEAN__INTEGRATION__CONFIG__API_TOKEN="" \
-p 8000:8000 \
my-custom-coded-ocean-integration:latest
```
Use the same env var naming as in [test and run locally](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/testing/.md).
## Deploy with Helm[](#deploy-with-helm "Direct link to Deploy with Helm")
1. Push your image to a registry your cluster can pull.
2. Add the Port Helm repository:
```
helm repo add port-labs https://port-labs.github.io/helm-charts
helm repo update
```
3. Install the `port-ocean` chart and point it at your image. The chart uses `imageRegistry` plus `image` (repository path and tag, without the registry prefix):
```
helm upgrade --install my-private-integration port-labs/port-ocean \
--set port.clientId="" \
--set port.clientSecret="" \
--set initializePortResources=true \
--set integration.identifier="my-private-integration" \
--set integration.type="myIntegration" \
--set integration.eventListener.type="POLLING" \
--set imageRegistry="YOUR_REGISTRY" \
--set image="my-custom-coded-ocean-integration:latest" \
--set integration.secrets.apiToken="" \
--set integration.config.apiBaseUrl="https://api.example.com"
```
See the [port-ocean chart values](https://github.com/port-labs/helm-charts/blob/main/charts/port-ocean/values.yaml) for the full list of knobs.
For listener choices, scheduled resync, proxies, TLS, and health endpoints, use:
* [Event listeners](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md).
* [Advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
## After deploy[](#after-deploy "Direct link to After deploy")
Confirm the integration appears under [Connectors](https://app.port.io/settings/data-sources), that a resync completes, and that entities match your [mapping](/context-lake/ingestion/configure-mapping/overview/.md). Use the integration's sync status and event log when troubleshooting.
---
# Development guidelines
## Stay mapping-agnostic[](#stay-mapping-agnostic "Direct link to Stay mapping-agnostic")
Yield raw third-party objects. Let users shape catalog entities through [mapping](/context-lake/ingestion/configure-mapping/overview/.md). If you add computed fields, prefix them with `__` (for example `__owners`) so they do not collide with upstream API fields.
## Use async HTTP[](#use-async-http "Direct link to Use async HTTP")
Use `http_async_client` from Ocean. Avoid synchronous `requests` calls on the event loop. See [implement an API client](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/api-client/.md).
## Stream with generators[](#stream-with-generators "Direct link to Stream with generators")
In `@ocean.on_resync` handlers, `yield` batches instead of returning one giant list. That keeps memory stable and lets Ocean process data as it arrives.
```
@ocean.on_resync("project")
async def on_resync_projects(kind: str) -> ASYNC_GENERATOR_RESYNC_TYPE:
client = MyClient()
async for batch in client.get_paginated_projects():
yield batch
```
## Logging[](#logging "Direct link to Logging")
Use `loguru`:
```
from loguru import logger
logger.info("Fetched batch of {} projects", len(projects))
```
## Live events[](#live-events "Direct link to Live events")
Do not treat the webhook payload as the same shape as a resync response unless the third-party API guarantees that. Fetch the current resource in `handle_event` and return that raw object (or a delete). See [implement live events](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/live-events/.md).
## Configuration access[](#configuration-access "Direct link to Configuration access")
Read user settings from `ocean.integration_config` (camelCase keys from `spec.yaml`). During a resync, use `event.resource_config` for per-kind selectors.
## Lint and types[](#lint-and-types "Direct link to Lint and types")
Run `make lint` (or your scaffold's equivalent) before you deploy. Keep type hints on public handlers and client methods.
## Related runtime docs[](#related-runtime-docs "Direct link to Related runtime docs")
* [Event listeners](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md).
* [Actions processing](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/actions-processing/.md) if you register action executors.
* [Advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md) for proxies, TLS, and base URL.
---
# Implement incremental sync
[Incremental sync](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/incremental-sync/.md) runs on a short interval in parallel to the full resync. It fetches only objects created or updated since the last run for the kinds you opt in.
Your job is to register `@ocean.on_incremental_resync` handlers that use the active cursor when calling the third-party API, and yield batches of raw objects (same shape as a full resync). Port applies your [mapping](/context-lake/ingestion/configure-mapping/overview/.md) to those objects. Incremental sync does not run reconciliation - deletions still rely on a full resync.
## Register an incremental handler[](#register-an-incremental-handler "Direct link to Register an incremental handler")
Use `@ocean.on_incremental_resync` for each kind that can sync incrementally. You can stack it with `@ocean.on_resync` when the same function supports both modes:
```
from port_ocean.context.ocean import ocean
from port_ocean.core.incremental.cursor_context import active_incremental_cursor
from port_ocean.core.ocean_types import ASYNC_GENERATOR_RESYNC_TYPE
from client import MyClient
from kinds import ObjectKind
@ocean.on_incremental_resync(ObjectKind.ISSUE)
@ocean.on_resync(ObjectKind.ISSUE)
async def resync_issues(kind: str) -> ASYNC_GENERATOR_RESYNC_TYPE:
client = MyClient()
cursor = active_incremental_cursor()
async for batch in client.get_paginated_issues(updated_since=cursor):
yield batch
```
`active_incremental_cursor()` returns a `datetime` during an incremental run, and `None` during a full resync. Pass that into your API client as a filter when it is set.
Only kinds with an `@ocean.on_incremental_resync` handler participate in incremental sync. Other kinds in the mapping are skipped on incremental runs and continue to update via full resync (and live events, if you implemented them).
## Strategies[](#strategies "Direct link to Strategies")
Ocean provides helpers in `port_ocean.core.incremental.strategies` to turn a cursor into API parameters.
### Server-side filter[](#server-side-filter "Direct link to Server-side filter")
Use when the third-party API accepts a "changed since" query parameter:
```
from port_ocean.core.incremental.strategies import (
ServerSideTimestampStrategy,
paginate_with_strategy,
)
ISSUE_INCREMENTAL = ServerSideTimestampStrategy(param_key="since")
@ocean.on_incremental_resync(ObjectKind.ISSUE)
async def incremental_resync_issues(kind: str) -> ASYNC_GENERATOR_RESYNC_TYPE:
client = MyClient()
cursor = active_incremental_cursor()
params = ISSUE_INCREMENTAL.merge_params({"state": "all"}, cursor)
async for batch in paginate_with_strategy(
client.get_paginated_issues(params),
cursor=cursor,
strategy=ISSUE_INCREMENTAL,
):
yield batch
```
### Client-side cutoff[](#client-side-cutoff "Direct link to Client-side cutoff")
Use when the API has no time filter but can return items newest-first. Sort descending, yield items newer than the cursor, and stop paging when you hit older items:
```
from port_ocean.core.incremental.strategies import (
ClientSideCutoffStrategy,
paginate_with_strategy,
)
PR_INCREMENTAL = ClientSideCutoffStrategy(
stop_field="updated_at",
query_params={"sort": "updated", "direction": "desc"},
)
@ocean.on_incremental_resync(ObjectKind.PULL_REQUEST)
async def incremental_resync_pull_requests(
kind: str,
) -> ASYNC_GENERATOR_RESYNC_TYPE:
client = MyClient()
cursor = active_incremental_cursor()
params = PR_INCREMENTAL.merge_params({}, cursor)
async for batch in paginate_with_strategy(
client.get_paginated_pull_requests(params),
cursor=cursor,
strategy=PR_INCREMENTAL,
):
yield batch
```
## Enable incremental sync[](#enable-incremental-sync "Direct link to Enable incremental sync")
For self-hosted and private deployments, set:
```
OCEAN__INTEGRATION__INCREMENTAL_SYNC_ENABLED=true
OCEAN__INTEGRATION__INCREMENTAL_SYNC_INTERVAL=15
```
`INCREMENTAL_SYNC_INTERVAL` must be `15`, `30`, or `60` (minutes). The default interval is 15.
For Port-hosted integrations, enable incremental sync and set the interval under **Advanced configuration** on the [connectors](https://app.port.io/settings/data-sources) page.
With a `ONCE` [event listener](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md), an enabled incremental sync runs an incremental pass instead of a full resync.
## Limitations to design for[](#limitations-to-design-for "Direct link to Limitations to design for")
* No reconciliation on incremental runs - design handlers to fetch creates and updates only.
* The first incremental run looks back one interval - rely on a preceding full resync for older data.
* Keep incremental raw shapes consistent with full resync shapes so the same mapping works for both.
See [incremental sync](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/incremental-sync/.md) for platform behavior and [sync interactions](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/sync-interactions/.md) for how incremental runs overlap with full resyncs and live events.
---
# Kinds and selectors
Kinds are the resource types your integration syncs (for example `project` or `issue`). Each kind can have a resync handler and, optionally, custom fields in the mapping YAML that control how you call the third-party API.
When you can skip this page
If every kind uses fixed API parameters and you do not need user-defined filters in the mapping, you can skip custom selectors. Declare kinds in `.port/spec.yaml` and implement `@ocean.on_resync` handlers only.
## Layers[](#layers "Direct link to Layers")
| Layer | Role |
| -------------------------- | --------------------------------------------------------------------- |
| `Selector` | User-facing fields for one kind (filters, expand flags, field lists). |
| `ResourceConfig` | Binds a selector to a kind literal. |
| `PortAppConfig` | Lists the resource configs your integration accepts. |
| `BaseIntegration` subclass | Wires your `PortAppConfig` into Ocean via `integration.py`. |
## Example[](#example "Direct link to Example")
integration.py
```
from typing import Literal
from port_ocean.core.handlers.port_app_config.api import APIPortAppConfig
from port_ocean.core.handlers.port_app_config.models import (
PortAppConfig,
ResourceConfig,
Selector,
)
from port_ocean.core.integrations.base import BaseIntegration
from pydantic import Field
class ProjectSelector(Selector):
expand: str | None = Field(
default=None,
description="Optional expand parameter passed to the third-party API",
)
class ProjectResourceConfig(ResourceConfig):
kind: Literal["project"]
selector: ProjectSelector
class MyPortAppConfig(PortAppConfig):
resources: list[ProjectResourceConfig | ResourceConfig] = Field(
default_factory=list
)
class MyIntegration(BaseIntegration):
class AppConfigHandlerClass(APIPortAppConfig):
CONFIG_CLASS = MyPortAppConfig
```
Users can then set the selector in mapping YAML:
```
resources:
- kind: project
selector:
query: "true"
expand: "description"
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"project"'
properties: {}
```
In the resync handler, read `event.resource_config` and pass selector values into your client. See [handle resyncs](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/resyncs/.md#use-selector-config-during-resync).
## Mapping reference[](#mapping-reference "Direct link to Mapping reference")
For entity mapping fields (`identifier`, `title`, `properties`, `relations`, `itemsToParse`, and related options), see [configure mapping](/context-lake/ingestion/configure-mapping/overview/.md). Your integration should keep yielding raw API objects; the mapping decides how those objects become catalog entities.
---
# Implement live events
Live events keep the catalog up to date between resyncs. In code they are webhook processors: HTTP `POST` handlers that authenticate the request, decide which kinds are affected, and return updated or deleted **raw** objects.
For how Ocean queues, routes, and retries live events at runtime, see [live events processing](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/live-events-processing/.md).
## Processor interface[](#processor-interface "Direct link to Processor interface")
Subclass `AbstractWebhookProcessor` and implement:
| Method | Purpose |
| ---------------------- | ---------------------------------------------------- |
| `should_process_event` | Return whether this processor handles the event. |
| `get_matching_kinds` | Return the kinds the event affects. |
| `authenticate` | Verify the request (signature, token, and similar). |
| `validate_payload` | Reject malformed payloads. |
| `handle_event` | Fetch current data if needed and return raw results. |
`handle_event` must return `WebhookEventRawResults` with:
* `updated_raw_results` - raw objects to upsert via mapping.
* `deleted_raw_results` - raw objects that identify deletes.
Prefer fetching the latest resource from the third-party API instead of registering the webhook payload as-is. Webhook bodies are often partial and can diverge from resync shapes.
## Example[](#example "Direct link to Example")
```
from port_ocean.core.handlers.port_app_config.models import ResourceConfig
from port_ocean.core.handlers.webhook.abstract_webhook_processor import (
AbstractWebhookProcessor,
)
from port_ocean.core.handlers.webhook.webhook_event import (
EventHeaders,
EventPayload,
WebhookEvent,
WebhookEventRawResults,
)
from client import MyClient
from kinds import ObjectKind
class ProjectWebhookProcessor(AbstractWebhookProcessor):
async def should_process_event(self, event: WebhookEvent) -> bool:
return event.payload.get("eventType", "").startswith("project.")
async def get_matching_kinds(self, event: WebhookEvent) -> list[str]:
return [ObjectKind.PROJECT]
async def authenticate(
self, payload: EventPayload, headers: EventHeaders
) -> bool:
return True
async def validate_payload(self, payload: EventPayload) -> bool:
return "project" in payload
async def handle_event(
self, payload: EventPayload, resource_config: ResourceConfig
) -> WebhookEventRawResults:
client = MyClient()
project_id = payload["project"]["id"]
if payload.get("eventType") == "project.deleted":
return WebhookEventRawResults(
updated_raw_results=[],
deleted_raw_results=[payload["project"]],
)
project = await client.get_project(project_id)
if not project:
return WebhookEventRawResults(
updated_raw_results=[],
deleted_raw_results=[payload["project"]],
)
return WebhookEventRawResults(
updated_raw_results=[project],
deleted_raw_results=[],
)
```
## Register processors[](#register-processors "Direct link to Register processors")
Register processors on a fixed path under the integration's `/integration` prefix (for example `/webhook`):
main.py
```
from port_ocean.context.ocean import ocean
from webhook_processors.project_webhook_processor import ProjectWebhookProcessor
ocean.add_webhook_processor("/webhook", ProjectWebhookProcessor)
```
Register the matching webhook URL in the third-party system from `@ocean.on_start()`, using your public base URL. See [advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md) for base URL and path prefix settings.
Kinds must be in the mapping
Ocean processes live events only for kinds that exist in the integration's mapping. If you remove a kind from the mapping, live events for it are ignored.
---
# Write your own Ocean integration
After [scaffolding](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/getting-started/.md), implement the third-party logic, configuration, and deployment for your custom-coded Ocean integration.
Your code should return **raw** objects from the third-party API. Keep those objects mapping-agnostic so users can change how data appears in Port without changing your Python code. Port applies the [mapping configuration](/context-lake/ingestion/configure-mapping/overview/.md) and updates the catalog.
## Build flow[](#build-flow "Direct link to Build flow")
1. [Define configuration files](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/configuration-files/.md) - `.port/spec.yaml`, optional blueprints and default mapping.
2. [Implement an API client](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/api-client/.md) - authenticate and paginate with Ocean's async HTTP client.
3. [Handle resyncs](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/resyncs/.md) - `@ocean.on_resync` handlers that yield batches of raw data.
4. [Implement incremental sync](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/incremental-sync/.md) - optional `@ocean.on_incremental_resync` handlers for changed-since fetches.
5. [Kinds and selectors](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/kinds-and-selectors/.md) - optional custom mapping fields in `integration.py`.
6. [Implement live events](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/live-events/.md) - optional webhook processors.
7. [Test and run locally](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/testing/.md) - env vars, `make run`, and resync triggers.
8. [Development guidelines](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/guidelines/.md) - httpx, logging, performance, and raw-data practices.
9. [Deploy](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/deploy/.md) - Docker and Helm with your private image.
## Reference[](#reference "Direct link to Reference")
* [Ocean and event contexts](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/contexts/.md) - `ocean` and `event` globals.
* [Configuration validation](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/configuration-validation/.md) - types in `spec.yaml`.
* [Ocean framework](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/overview/.md) - event listeners, live events runtime, actions, probe, and advanced configuration.
---
# Handle resyncs
A resync asks your integration to fetch current data for one or more kinds. You implement that with `@ocean.on_resync` handlers in `main.py`.
Ocean calls your handler for each matching kind in the mapping. You yield batches of raw objects. Port applies the [mapping](/context-lake/ingestion/configure-mapping/overview/.md) and updates the catalog. For when resyncs are triggered and which listener types exist, see [event listeners and resync triggers](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md).
## Resync handler pattern[](#resync-handler-pattern "Direct link to Resync handler pattern")
main.py
```
from port_ocean.context.ocean import ocean
from port_ocean.core.ocean_types import ASYNC_GENERATOR_RESYNC_TYPE
from client import MyClient
@ocean.on_resync("project")
async def on_resync_projects(kind: str) -> ASYNC_GENERATOR_RESYNC_TYPE:
client = MyClient()
async for projects in client.get_paginated_projects():
yield projects
```
Requirements:
* The `kind` string matches a kind in your mapping and in `spec.yaml`.
* Each `yield` is a **list of objects** (dicts), not a single object.
* Prefer async generators so Ocean can stream batches as you fetch them.
## Kind-specific handlers[](#kind-specific-handlers "Direct link to Kind-specific handlers")
Use an enum for kind names and register one handler per kind (or a generic handler when the client API is uniform):
```
from enum import StrEnum
from port_ocean.context.event import event
from port_ocean.context.ocean import ocean
from port_ocean.core.ocean_types import ASYNC_GENERATOR_RESYNC_TYPE
class ObjectKind(StrEnum):
PROJECT = "project"
ISSUE = "issue"
@ocean.on_resync(ObjectKind.PROJECT)
async def on_resync_projects(kind: str) -> ASYNC_GENERATOR_RESYNC_TYPE:
client = MyClient()
async for batch in client.get_paginated_projects():
yield batch
```
## Use selector config during resync[](#use-selector-config-during-resync "Direct link to Use selector config during resync")
If you defined custom selectors in `integration.py`, read them from `event.resource_config` while the resync runs:
```
from typing import cast
from port_ocean.context.event import event
from integration import ProjectResourceConfig
@ocean.on_resync(ObjectKind.PROJECT)
async def on_resync_projects(kind: str) -> ASYNC_GENERATOR_RESYNC_TYPE:
client = MyClient()
selector = cast(ProjectResourceConfig, event.resource_config).selector
async for batch in client.get_paginated_projects(expand=selector.expand):
yield batch
```
See [kinds and selectors](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/kinds-and-selectors/.md).
## Startup hook[](#startup-hook "Direct link to Startup hook")
Use `@ocean.on_start()` for one-time setup, such as registering webhooks in the third-party system. Skip webhook registration when the listener is `ONCE` (CI-style single resync).
```
@ocean.on_start()
async def on_start() -> None:
if ocean.event_listener_type == "ONCE":
return
await MyClient().ensure_webhook()
```
## Next steps[](#next-steps "Direct link to Next steps")
* [Implement incremental sync](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/incremental-sync/.md).
* [Implement live events](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/live-events/.md).
* [Test and run locally](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/testing/.md).
---
# Test and run locally
## Map configuration to environment variables[](#map-configuration-to-environment-variables "Direct link to Map configuration to environment variables")
Parameters in `.port/spec.yaml` become environment variables with this pattern:
* Port credentials: `OCEAN__PORT__CLIENT_ID`, `OCEAN__PORT__CLIENT_SECRET` (and optional `OCEAN__PORT__BASE_URL`).
* Integration config: `OCEAN__INTEGRATION__CONFIG__`.
Example: `apiBaseUrl` in `spec.yaml` maps to `OCEAN__INTEGRATION__CONFIG__API_BASE_URL`.
.env
```
OCEAN__PORT__CLIENT_ID=
OCEAN__PORT__CLIENT_SECRET=
OCEAN__INTEGRATION__CONFIG__API_BASE_URL=https://api.example.com
OCEAN__INTEGRATION__CONFIG__API_TOKEN=
OCEAN__EVENT_LISTENER__TYPE=POLLING
```
Find Port credentials in [Find your Port credentials](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md#find-your-port-credentials).
## Run the integration[](#run-the-integration "Direct link to Run the integration")
```
cd ./my_integration
make install
source .venv/bin/activate
cp .env.example .env
# edit .env
make run
```
`make run` (or `ocean sail`) starts the integration, applies default resources when enabled, and begins listening for resync requests.
## Trigger a resync[](#trigger-a-resync "Direct link to Trigger a resync")
While the integration runs with `POLLING` (default):
* Open [Connectors](https://app.port.io/settings/data-sources), select the integration, and click **Resync**.
* Or change the mapping or configuration in Port so the next poll detects a change.
See [event listeners and resync triggers](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md) for scheduled resync and other listener types.
## Debug[](#debug "Direct link to Debug")
* Set `APPLICATION__LOG_LEVEL=DEBUG` in `.env` for verbose logs.
* Use the scaffolded `debug.py` with your IDE debugger if needed.
## Connection probe[](#connection-probe "Direct link to Connection probe")
To validate credentials and permissions without a full resync, implement `@ocean.on_probe()` and run `ocean probe`. See [connection probe](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/connection-probe/.md).
## Next steps[](#next-steps "Direct link to Next steps")
* [Deploy a custom-coded Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/deploy/.md).
* [Development guidelines](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/guidelines/.md).
---
# Getting started
Let's install the Ocean CLI, scaffold a custom-coded Ocean integration, and run it against your Port organization.
## Requirements[](#requirements "Direct link to Requirements")
* Python 3.12 or later.
* [Port API credentials](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md#find-your-port-credentials) (client ID and client secret).
## Install the Ocean CLI[](#install-the-ocean-cli "Direct link to Install the Ocean CLI")
```
python -m venv .venv
source .venv/bin/activate
pip install "port-ocean[cli]"
```
## Scaffold a custom-coded Ocean integration[](#scaffold-a-custom-coded-ocean-integration "Direct link to Scaffold a custom-coded Ocean integration")
`ocean new` scaffolds a custom-coded Ocean integration by default (an integration you maintain outside the Ocean monorepo, including a `Dockerfile`).
```
ocean new
```
The CLI prompts for the integration name, description, your Port credentials, and region. Accept the default custom-coded Ocean integration option unless you intend to contribute to the [Ocean monorepo](https://github.com/port-labs/ocean).
After scaffolding:
```
cd ./
make install
source .venv/bin/activate
cp .env.example .env
```
Update `.env` with your Port credentials and any integration-specific settings from `.port/spec.yaml`. See [test and run locally](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/testing/.md) for the environment variable naming convention.
## Project structure[](#project-structure "Direct link to Project structure")
A private scaffold typically looks like this:
```
my-integration/
├── Dockerfile
├── pyproject.toml
├── Makefile
├── main.py
├── .env.example
├── debug.py
├── tests/
└── .port/
├── spec.yaml
└── resources/
├── blueprints.json
└── port-app-config.yaml
```
| Path | Role |
| ------------------ | -------------------------------------------------------------------------------- |
| `main.py` | Resync handlers, startup hooks, and live event / action registration. |
| `.port/spec.yaml` | Integration type, supported kinds, and user-facing config schema. |
| `.port/resources/` | Default blueprints and mapping created when the integration starts (if enabled). |
| `Dockerfile` | Image build for private deployment. |
| `Makefile` | `make install`, `make run`, and lint helpers. |
## Run locally[](#run-locally "Direct link to Run locally")
```
make run
```
You can also run `ocean sail` from the integration directory. Ocean connects to Port, creates default resources if configured, starts the [event listener](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md) (default `POLLING`), and runs a resync when needed.
Interactive API docs
While the integration is running, open `http://localhost:8000/docs` for the built-in Swagger UI, or `http://localhost:8000/redoc` for ReDoc.
## Next steps[](#next-steps "Direct link to Next steps")
* [Write your own Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/overview/.md) - replace the sample resync logic with your API client, kinds, and deploy.
---
# Custom-coded Ocean integration
If the [no-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) does not meet your needs, you can build a custom-coded Ocean integration in Python using Port's open-source [Ocean](https://github.com/port-labs/ocean) framework.
Your integration's job is to **extract raw data** from a third-party system (and optionally handle live events and actions). You also author the [mapping configuration](/context-lake/ingestion/configure-mapping/overview/.md) that describes how that raw data becomes Port entities. Port applies the mapping and updates the catalog.
For how Ocean runs once installed (event listeners, live events, actions, and more), see the [Ocean framework](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/overview/.md) section.
## No-code vs custom-coded[](#no-code-vs-custom-coded "Direct link to No-code vs custom-coded")
| | [No-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) | Custom-coded Ocean integration |
| -------------------- | ------------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------ |
| **How you build it** | Configuration only (endpoints, auth, JQ mapping). | Python code with the Ocean framework. |
| **Best for** | REST APIs that return JSON over HTTP. | Complex auth, pagination, nested data, or non-standard APIs. |
| **Live events** | Currently not supported. | Full control via Ocean event processors. |
| **Maintenance** | Port hosts the runtime (or you run the generic custom image). | You own the app, image, and deployment. |
Start with the no-code option when it covers your API. Choose custom-coded when you need logic that configuration alone cannot express.
## When to build a custom-coded Ocean integration[](#when-to-build-a-custom-coded-ocean-integration "Direct link to When to build a custom-coded Ocean integration")
Choose a custom-coded Ocean integration when:
* You need custom authentication flows (OAuth2, JWT refresh, and similar).
* The API has complex pagination, nested data, or kind-specific selectors.
* You need live events that the no-code Ocean custom integration cannot express.
* You want a dedicated Python app for one system, maintained outside the Ocean monorepo.
If you only need to call a REST API with config and JQ mapping, start with the [no-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) instead.
## What you implement[](#what-you-implement "Direct link to What you implement")
| Responsibility | Where |
| ------------------------------ | --------------------------------------------------------------------- |
| Fetch raw data per `kind` | `@ocean.on_resync()` in `main.py`. |
| Optional incremental sync | `@ocean.on_incremental_resync()` handlers that use the active cursor. |
| Optional live events | Live event processors that return updated or deleted **raw** objects. |
| Optional actions | Action executors registered with Ocean. |
| Integration config schema | `.port/spec.yaml`. |
| Default blueprints and mapping | `.port/resources/`. |
| Custom mapping selectors | Optional `integration.py` classes. |
Ocean core handles connecting to Port, listening for resync requests, receiving webhooks, and reporting sync status. See [how an Ocean integration runs](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/overview/.md#how-an-ocean-integration-runs).
## Build path[](#build-path "Direct link to Build path")
1. [Getting started](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/getting-started/.md) - install the CLI, scaffold, and run locally.
2. [Write your own Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/build/overview/.md) - config, API client, resyncs, incremental sync, live events, testing, and deploy.
## Contribute publicly[](#contribute-publicly "Direct link to Contribute publicly")
To share an integration with the Port community, develop it in the [Ocean monorepo](https://github.com/port-labs/ocean) and follow the repository [contributing guide](https://github.com/port-labs/ocean/blob/main/CONTRIBUTING.md). Scaffolding with `ocean new` is the default for org-specific integrations.
---
# Configuration
In this page we will cover the configuration steps that apply to both installation methods (hosted by Port and self-hosted). We will walk through the prerequisites you need to gather, how to configure resource mapping, and advanced configuration options for complex scenarios.
## How it works[](#how-it-works "Direct link to How it works")
The No-code Ocean custom integration uses a [**two-step setup**](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md):
1. **Installation** - Configure connection settings that apply to all API calls ([hosted by Port](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md) or [self-hosted](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup/.md)).
2. **Resource mapping** - Define which endpoints to sync and how to map them to Port entities.
## Resource mapping[](#resource-mapping "Direct link to Resource mapping")
After installation, you define **which endpoints to sync** in your `port-app-config.yml` file (or using the integration's configuration in Port).
This is where you map each API endpoint to Port entities - similar to how you've mapped GitHub repositories or Jira issues in other integrations.
### Endpoint-as-kind feature[](#endpoint-as-kind-feature "Direct link to Endpoint-as-kind feature")
The `kind` field is now the **endpoint path itself**! This provides better visibility in Port's UI, allowing you to:
* ✅ Track each endpoint's sync status individually.
* ✅ Debug mapping issues per endpoint.
* ✅ Monitor data ingestion per API call.
### Example: Mapping two endpoints[](#example-mapping-two-endpoints "Direct link to Example: Mapping two endpoints")
```
resources:
# First endpoint: users
- kind: /api/v1/users
selector:
query: 'true' # JQ filter - 'true' means sync all entities
data_path: '.users' # Where to find the data array in the response
query_params: # Optional: add query parameters to the API call
active: "true"
department: "engineering"
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"user"'
properties:
email: .email
department: .department
active: .is_active
created: .created_at
# Second endpoint: projects
- kind: /api/v1/projects
selector:
query: 'true'
data_path: '.data.projects' # Nested data extraction
query_params:
status: "active"
port:
entity:
mappings:
identifier: .project_id
title: .project_name
blueprint: '"project"'
properties:
description: .description
owner: .owner.email
budget: .budget_amount
created: .created_date
```
### What each field does[](#what-each-field-does "Direct link to What each field does")
* **`kind`**: The API endpoint path (combined with your base URL).
* **`selector.query`**: JQ filter to include/exclude entities (use `'true'` to sync all).
* **`selector.data_path`**: JQ expression pointing to the array of items in the response (see [Data path extraction](#data-path-extraction) below).
* **`selector.query_params`**: (Optional) Query parameters added to the URL.
* **`selector.method`**: (Optional) HTTP method, defaults to `GET`.
* **`port.entity.mappings`**: How to map API fields to Port entity properties.
### Data path extraction[](#data-path-extraction "Direct link to Data path extraction")
The `data_path` field tells the integration where to find the array of items in your API response. Use a [JQ expression](https://jqlang.org/manual/) to point to the data array.
| Response structure | Example response | `data_path` value |
| ------------------ | -------------------------------------------------- | ----------------------- |
| Direct array | `[{"id": 1}, {"id": 2}]` | *(omit - not needed)* |
| Single nested | `{"data": [{"id": 1}], "meta": {...}}` | `.data` |
| Deeply nested | `{"response": {"users": {"items": [...]}}}` | `.response.users.items` |
| Array flattening | `{"groups": [{"rules": [...]}, {"rules": [...]}]}` | `.groups[].rules[]` |
Array flattening
Use JQ's `[]` operator to flatten nested arrays. For example, `.groups[].rules[]` extracts all rules from all groups into a single flat array.
## Advanced configurations[](#advanced-configurations "Direct link to Advanced configurations")
Once you have the basics working, these features handle more complex scenarios.
### Nested endpoints[](#nested-endpoints "Direct link to Nested endpoints")
Fetch data from dynamic endpoints that depend on other resources.
Use `.__` to access path parameter values in your entity mappings (e.g., `.__ticket_id` for a `{ticket_id}` parameter).
data\_path in path parameters
The `data_path` in `path_parameters` is not inherited from the parent kind's `data_path`. If not configured, it defaults to `.` (the root of the response).
**Example: Tickets and comments**
```
resources:
# Parent endpoint
- kind: /api/tickets
selector:
query: 'true'
data_path: '.tickets'
port:
entity:
mappings:
identifier: .id | tostring
title: .subject
blueprint: '"ticket"'
# Nested endpoint - fetches comments for each ticket
- kind: /api/tickets/{ticket_id}/comments
selector:
query: 'true'
data_path: '.comments'
path_parameters:
ticket_id:
endpoint: /api/tickets
field: .id
filter: 'true'
port:
entity:
mappings:
identifier: .id | tostring
blueprint: '"comment"'
properties:
content: .body
ticketId: .__ticket_id | tostring # Access path parameter value
relations:
ticket: .__ticket_id | tostring # Use for parent relation
```
The integration will:
1. Call `/api/tickets` → Get ticket IDs \[101, 102, 103].
2. Call `/api/tickets/101/comments`, `/api/tickets/102/comments`, etc.
3. Sync all comments with relations to their parent tickets.
**More examples:**
* `/projects/{project_id}/tasks` → Access `.__project_id` in task mappings.
* `/repositories/{repo_id}/pull-requests` → Access `.__repo_id` in PR mappings.
### Pagination[](#pagination "Direct link to Pagination")
For APIs that split data across multiple pages, configure how the integration fetches all pages.
Where pagination is configured
Pagination settings (`paginationType`, `lastPagePath`, `cursorPath`, etc.) are applied at the **integration level**, not inside the `resources` block of your `port-app-config.yml`. They are shared across all endpoints (kinds) defined in your resource mapping.
* **Hosted by Port:** set them in the **Pagination settings** section when configuring the integration (see [Pagination settings](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md#pagination-settings)).
* **Self-hosted:** pass them via Helm values such as `integration.config.paginationType` (see [Configuration parameters](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup/.md#configuration-parameters)).
The YAML snippets below show the field names and values to use in those locations.
#### Pagination types[](#pagination-types "Direct link to Pagination types")
**Offset-based** (like SQL):
```
GET /api/users?offset=0&limit=100
GET /api/users?offset=100&limit=100
```
**Page-based** (traditional):
```
GET /api/users?page=1&size=100
GET /api/users?page=2&size=100
```
**Cursor-based** (for large datasets):
```
GET /api/users?cursor=abc123&limit=100
GET /api/users?cursor=xyz789&limit=100
```
**Next-link / URL-based** (OData APIs like Microsoft Graph):
```
GET /api/users?$top=100
GET
```
**Header-link / RFC 5988** (GitHub, GitLab, Bitbucket):
```
GET /api/users?per_page=100
Response header: Link: ; rel="next", ; rel="last"
GET
```
#### Custom parameter names[](#custom-parameter-names "Direct link to Custom parameter names")
APIs often use different parameter names. You can configure:
* **Pagination parameter:** Use `skip` instead of `offset`, or `after` instead of `cursor`.
* **Size parameter:** Use `per_page` instead of `limit`, or `page_size` instead of `size`.
* **Start page:** Specify if pages start at 0 or 1.
**Example:**
```
# GitHub uses page/per_page
paginationType: page
paginationParam: page
sizeParam: per_page
startPage: 1
# Stripe uses limit/starting_after
paginationType: cursor
paginationParam: starting_after
sizeParam: limit
```
#### Last page indicator[](#last-page-indicator "Direct link to Last page indicator")
Some page-based APIs such as Spring Data REST and Harness, set a boolean field to `true` on the last page instead of using a `has_more` field that evaluates to `false`. To handle this, you can use `lastPagePath` to specify this field using dot-notation.
**Example API response:**
```
{
"content": [...],
"number": 0,
"size": 100,
"last": false
}
```
**Configuration:**
```
paginationType: page
lastPagePath: last
startPage: 0
```
For nested envelopes (e.g., `{"data": {"content": [...], "last": false}}`), use the full path: `lastPagePath: data.last`.
Precedence with `hasMorePath`
If both `hasMorePath` and `lastPagePath` are configured, `hasMorePath` takes precedence. If the configured field is missing from a response, pagination falls back to the default termination logic rather than stopping early.
#### Cursor path configuration[](#cursor-path-configuration "Direct link to Cursor path configuration")
For cursor-based pagination, tell the integration where to find the next cursor in responses:
**Example API response:**
```
{
"data": [...],
"meta": {
"after_cursor": "xyz123",
"has_more": true
}
}
```
**Configuration:**
```
cursorPath: meta.after_cursor
hasMorePath: meta.has_more
```
#### Next-link path configuration[](#next-link-path-configuration "Direct link to Next-link path configuration")
For APIs that return a full URL for the next page (like Microsoft Graph's `@odata.nextLink`), use `next_link` pagination:
**Example API response:**
```
{
"value": [...],
"@odata.nextLink": "https://graph.microsoft.com/v1.0/users?$top=100&page=2"
}
```
**Configuration:**
```
paginationType: next_link
nextLinkPath: "@odata.nextLink"
```
For APIs using different field names, configure `nextLinkPath` accordingly (e.g., `nextRecordsUrl` for Salesforce, `links.next` for nested paths).
#### Header-link configuration[](#header-link-configuration "Direct link to Header-link configuration")
For APIs that return the next page URL in the HTTP `Link` header (RFC 5988), use `header_link` pagination. This is common with GitHub, GitLab, and Bitbucket APIs.
**Example API response:**
```
HTTP/2 200 OK
Content-Type: application/json
Link: ; rel="next", ; rel="last"
[{"id": 1, "name": "repo1"}, {"id": 2, "name": "repo2"}]
```
**Configuration:**
```
paginationType: header_link
```
Custom rel value
Some APIs use a different `rel` value in the Link header. Configure `headerLinkRel` if your API uses something other than `next` (e.g., `nextPage`):
```
paginationType: header_link
headerLinkRel: nextPage
```
### Rate limiting[](#rate-limiting "Direct link to Rate limiting")
Control how the integration interacts with your API to prevent overwhelming it or hitting rate limits.
#### Request timeout[](#request-timeout "Direct link to Request timeout")
How long to wait for each API call to complete.
```
timeout: 30 # seconds (default: 30)
```
**When to adjust:**
* Increase for slow APIs or large responses (e.g., 60 seconds).
* Decrease for fast, local APIs (e.g., 10 seconds).
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
---
# Hosted by Port
Using this installation option means that the integration will be hosted by Port, with a customizable resync interval to ingest data into Port. Port manages the infrastructure, updates, and maintenance, allowing you to focus on configuring your API connection.
## Installation[](#installation "Direct link to Installation")
To install, follow these steps:
1. Go to the [connectors](https://app.port.io/settings/data-sources) page in Port.
2. Click on the **+ Connector** button in the top-right corner.
3. Click on the **Custom** integration in the list.
4. Under **Select your installation method**, choose **Hosted by Port**.
5. Configure the **integration settings** and **application settings** as you wish (see below for details).
## Application settings[](#application-settings "Direct link to Application settings")
Every integration hosted by Port has the following customizable application settings, which are configurable after installation:
* **Resync interval**: The frequency at which Port will ingest data from the integration. There are various options available, ranging from every 1 hour to once a day. If a sync is still in progress when the next one is due, the new sync will be skipped (up to 24 hours delay). This ensures that all kinds are fully synchronized and that cleanup of stale entities always takes place at the end of each sync.
* **Send raw data examples**: A boolean toggle (**enabled** by default). If enabled, raw data examples will be sent from the integration to Port. These examples are used when [testing your mapping configuration](/context-lake/ingestion/configure-mapping/configuration-methods/.md#test-your-mapping---jq-playground), they allow you to run your `jq` expressions against real data and see the results.
## Integration settings[](#integration-settings "Direct link to Integration settings")
The following integration settings are available for the custom integration. Each setting has an ⓘ icon next to it in the UI, which you can hover over to see a description.
### Connection settings[](#connection-settings "Direct link to Connection settings")
| Setting | Description | Required | Default |
| ------------- | --------------------------------------------------------------------- | -------- | ------- |
| **Base Url** | The base URL of your HTTP API, for example: `https://api.example.com` | ✅ | - |
| **Auth Type** | Authentication method: `none`, `bearer_token`, `basic`, or `api_key` | ❌ | `none` |
### Authentication settings[](#authentication-settings "Direct link to Authentication settings")
These settings are required based on your selected **Auth Type**:
| Setting | Description | Required When | Default |
| ------------------ | -------------------------------------- | ------------------------------- | ----------- |
| **Api Token** | Bearer token for authentication | **Auth Type** is `bearer_token` | - |
| **Username** | Username for basic authentication | **Auth Type** is `basic` | - |
| **Password** | Password for basic authentication | **Auth Type** is `basic` | - |
| **Api Key** | API key for authentication | **Auth Type** is `api_key` | - |
| **Api Key Header** | Header name for API key authentication | **Auth Type** is `api_key` | `X-API-Key` |
Port secrets
Settings marked with sensitive data (such as tokens, passwords, and API keys) use [Port secrets](/platform-administration/secrets-management/port-secrets/.md) to ensure your sensitive data is encrypted and secure. When filling in such a setting, its value will be obscured (shown as `••••••••`). Port will automatically create a secret in your organization for each sensitive setting.
### Pagination settings[](#pagination-settings "Direct link to Pagination settings")
| Setting | Description | Required | Default |
| -------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------- | ------- |
| **Pagination Type** | Pagination method: `none`, `offset`, `page`, or `cursor` | ❌ | `none` |
| **Page Size** | Number of items per page for pagination | ❌ | `100` |
| **Pagination Param** | Query parameter name for the main pagination value. For cursor: `cursor`, `page[after]`, `after`. For page: `page`, `pageNumber`. For offset: `offset`, `skip`. Defaults vary by paginationType. | ❌ | - |
| **Size Param** | Query parameter name for page size/limit. Examples: `limit`, `size`, `page[size]`, `per_page`. Defaults vary by paginationType. | ❌ | - |
| **Start Page** | Starting page number for page-based pagination (e.g., 0 or 1). Defaults to 1. | ❌ | `1` |
| **Cursor Path** | Dot-notation path to extract cursor from response for cursor pagination (e.g., `meta.after_cursor`, `links.next`). Defaults to common patterns if not specified. | ❌ | - |
| **Has More Path** | Dot-notation path to check if more pages exist (e.g., `meta.has_more`, `pagination.hasMore`). Works with all pagination types. Defaults to common patterns if not specified. | ❌ | - |
| **Last Page Path** | Dot-notation path to a boolean field that is truthy on the final page (inverse of **Has More Path**). Useful for APIs like Spring Data REST that return `last: true` on the last page (e.g., `last`, `data.last`). If **Last Page Path** and **Has More Path** are set, **Has More Path** takes precedence. | ❌ | - |
### Performance settings[](#performance-settings "Direct link to Performance settings")
| Setting | Description | Required | Default |
| --------------------------- | --------------------------------------------------------------------------------- | -------- | ------- |
| **Timeout** | Request timeout in seconds | ❌ | `30` |
| **Verify Ssl** | Whether to verify SSL certificates | ❌ | `true` |
| **Max Concurrent Requests** | Maximum concurrent API requests (uses Ocean's built-in rate limiting and caching) | ❌ | `10` |
## Port source IP addresses[](#port-source-ip-addresses "Direct link to Port source IP addresses")
When using this installation method, Port will make outbound calls to your API from static IP addresses. You may need to add these addresses to your allowlist, in order to allow Port to interact with your API:
* Europe (EU)
* United States (US)
```
54.73.167.226
63.33.143.237
54.76.185.219
```
```
3.234.37.33
54.225.172.136
3.225.234.99
```
## More resources[](#more-resources "Direct link to More resources")
For all configuration options, code examples, and advanced use cases, check out the [No-code Ocean custom integration repository on GitHub](https://github.com/port-labs/ocean/tree/main/integrations/custom).
---
# Build your integration
This interactive guide will help you generate everything you need to connect your API to Port.
**How it works:**
1. Configure your API connection settings
2. Choose an endpoint and select which fields to sync
3. Get your installation commands, blueprint, and mapping configuration
***
## Step 1: Configure your API[](#step-1-configure-your-api "Direct link to Step 1: Configure your API")
Set up the connection details for your API. These settings apply globally to all endpoints you'll sync from this API.
**What you're configuring:**
* **Base URL**: The root URL that all endpoint paths will be appended to
* **Authentication**: How your API verifies requests (bearer token, API key, basic auth, or none)
* **Pagination** (optional): How to fetch data across multiple pages if your API uses pagination
* **Performance settings** (optional): Timeouts, concurrent requests, SSL verification
Think of this as setting up the "connection" - these settings will be used for every API call the integration makes.
**Base URL**https\://api.example.com**Authentication**
\[x]Bearer Token\[ ]API Key\[ ]Basic Auth\[ ]None
•••••••••••••••••
**Advanced Configuration**
**Pagination (optional)**
\[x]None\[ ]Offset/Limit\[ ]Page/Size\[ ]Cursor
**Request Timeout (seconds)**30Maximum time to wait for API response (default: 30)**Max Concurrent Requests**10Maximum number of parallel API requests (default: 10)\[x]Verify SSL certificates
***
## Step 2: Choose what data to sync[](#step-2-choose-what-data-to-sync "Direct link to Step 2: Choose what data to sync")
Now that your API connection is configured, let's define what data to sync. This step helps you map a specific API endpoint to a Port blueprint.
**What you'll do:**
1. **Specify the endpoint path** (e.g., `/api/v1/users`) that you want to sync
2. **Paste a sample API response** so we can detect the data structure
3. **Select the data path** - tell us where the array of items is in the response (e.g., `.data`, `.users`, or root array)
4. **Configure the blueprint** - give it an identifier and title
5. **Choose which fields to sync** - select the fields you want to ingest and mark which field is the unique identifier
The builder will automatically detect field types (string, number, boolean, email, date, URL) from your sample response.
### 1️⃣ Enter Your Endpoint
/api/v1/users
### 2️⃣ Paste API Response
Test your endpoint (e.g., with `curl`) and paste a sample response here:
{
"data": \[
{
"id": 1,
"name": "John Doe",
"email": "john\@example.com",
"role": "admin"
},
{
"id": 2,
"name": "Jane Smith",
"email": "jane\@example.com",
"role": "user"
}
],
"meta": {
"total": 2,
"page": 1
}
}
### 3️⃣ Select Data Path
**Select the array** that contains the items you want to sync to Port:
\[ ]data2
items
***
## Step 3: Install and create in Port[](#step-3-install-and-create-in-port "Direct link to Step 3: Install and create in Port")
You're all set! Based on your configuration, we've generated everything you need:
**What you'll get:**
* **Installation commands** (Helm or Docker) with all your settings pre-configured
* **Blueprint JSON** to create the data model in Port
* **Mapping YAML** to configure which fields to sync
Simply copy and run these in order to complete your integration setup.
#### 📋 Complete Step 2 to generate your configuration
You need to:
* **Enter a Blueprint Identifier** (e.g., "user", "project")
* **Select an Identifier field** (click "ID" button next to a field)
Once complete, this section will show your installation commands, blueprint JSON, and mapping configuration.
Port credentials needed
Get your `PORT_CLIENT_ID` and `PORT_CLIENT_SECRET` from [Port Settings → Credentials](https://app.port.io/settings).
---
# Custom authentication
Self-hosted only
Custom authentication is only available for self-hosted installations. It is not supported for integrations hosted by Port.
The custom authentication feature enables you to configure OAuth2, JWT, and other dynamic token-based authentication flows beyond the standard authentication types (`bearer_token`, `basic`, `api_key`, `none`).
## Supported authentication methods[](#supported-authentication-methods "Direct link to Supported authentication methods")
The table below summarizes which authentication methods are supported by the no-code Ocean custom integration:
| Method | Supported | Notes |
| ------------------------------------------------- | --------- | ---------------------------------- |
| Bearer token (static) | ✅ | Use `authType: bearer_token` |
| API key (header) | ✅ | Use `authType: api_key` |
| Basic auth | ✅ | Use `authType: basic` |
| OAuth2 client credentials (`client_secret_basic`) | ✅ | Use custom auth with form body |
| OAuth2 client credentials (`client_secret_post`) | ✅ | Use custom auth with JSON body |
| JWT-based authentication | ✅ | Use custom auth with JWT endpoint |
| Custom header authentication | ✅ | Use custom auth `headers` template |
| OAuth2 `private_key_jwt` (RFC 7523) | ❌ | Not natively supported |
| mTLS / certificate-based auth | ❌ | Not supported |
private\_key\_jwt not supported
The `private_key_jwt` client authentication method (RFC 7523 / JWT Bearer assertion) requires the client to sign JWT assertions with a private key. This is **not natively supported** by the no-code Ocean custom integration because:
* The integration cannot generate signed JWTs dynamically.
* Private key storage and management is not available.
**Workaround:** If your API requires `private_key_jwt` authentication, consider using a proxy service that handles JWT signing. Your proxy can accept simple credentials from the Ocean integration and translate them into properly signed JWT assertions for the target API.
## How it works[](#how-it-works "Direct link to How it works")
When `authType` is set to `"custom"`, you configure two parts:
1. **How to authenticate** (`customAuthRequest`) - defines the authentication endpoint, HTTP method, headers, and body.
2. **How to use the token** (`customAuthRequestTemplate`) - defines where to inject authentication values in subsequent requests using template syntax.
The integration automatically:
* Authenticates on startup
* Caches evaluated templates for performance
* Refreshes tokens proactively (if `reauthenticateIntervalSeconds` is configured) or reactively on 401 errors
* Handles concurrent requests safely with locking
## Configuration[](#configuration "Direct link to Configuration")
### customAuthRequest[](#customauthrequest "Direct link to customAuthRequest")
Defines how to make the authentication request. This is configured as a JSON object.
| Field | Type | Description | Required |
| ------------------------------- | ------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------- |
| `endpoint` | string | Authentication endpoint. Can be a relative path (e.g., `/oauth/token`) appended to your base URL, or a full URL (e.g., `https://auth.example.com/token`) | ✅ |
| `method` | string | HTTP method for the authentication request. Allowed values: `GET`, `POST`, `PUT`, `PATCH`, `DELETE`. Default: `POST` | ❌ |
| `headers` | object | HTTP headers to send with the authentication request (key-value pairs) | ❌ |
| `body` | object | JSON request body for the authentication request. Mutually exclusive with `bodyForm` | ❌ |
| `bodyForm` | string | Form-encoded request body (e.g., `grant_type=client_credentials&client_id=...`). Mutually exclusive with `body` | ❌ |
| `queryParams` | object | Query parameters to send with the authentication request (key-value pairs) | ❌ |
| `reauthenticateIntervalSeconds` | integer | Token validity duration in seconds. If provided, tokens refresh 60 seconds before expiration. If not provided, tokens only refresh on 401 errors. Must be >= 1 | ❌ |
Body configuration
You cannot specify both `body` and `bodyForm` in `customAuthRequest`. Use `body` for JSON payloads and `bodyForm` for form-encoded payloads.
### customAuthRequestTemplate[](#customauthrequesttemplate "Direct link to customAuthRequestTemplate")
Defines how to use the authentication response in subsequent API requests. Use template syntax `{{.jq_path}}` to extract values from the auth response. At least one field must be provided.
| Field | Type | Description | Required |
| ------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | -------- |
| `headers` | object | HTTP headers to add or override in subsequent API requests. Use template syntax to inject values (e.g., `{"Authorization": "Bearer {{.access_token}}"}`) | ❌ |
| `queryParams` | object | Query parameters to add or override in subsequent API requests. Use template syntax to inject values (e.g., `{"api_key": "{{.access_token}}"}`) | ❌ |
| `body` | object | Request body fields to add or override in subsequent API requests. Merged with request body if present. Use template syntax to inject values (e.g., `{"token": "{{.accessToken}}"}`) | ❌ |
#### Template syntax[](#template-syntax "Direct link to Template syntax")
Use `{{.jq_path}}` to extract values from the authentication response JSON. The path uses dot notation to access nested fields:
* `{{.access_token}}` - Extracts the `access_token` field from the root
* `{{.data.token}}` - Extracts the `token` field from a nested `data` object
* `{{.nested.field.value}}` - Extracts deeply nested values
The template syntax is validated at configuration time, so errors fail fast before runtime.
## Installation examples[](#installation-examples "Direct link to Installation examples")
### Using Helm[](#using-helm "Direct link to Using Helm")
When using Helm, pass the custom authentication configuration as a JSON string in the `integration.config.customAuthRequest` and `integration.config.customAuthRequestTemplate` parameters:
```
helm install ocean-custom port-labs/port-ocean \
--set port.clientId="" \
--set port.clientSecret="" \
--set port.baseUrl="https://api.port.io" \
--set integration.identifier="ocean-custom" \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.config.baseUrl="https://api.yourcompany.com" \
--set integration.config.authType="custom" \
--set-json integration.config.customAuthRequest='{"endpoint":"/oauth/token","method":"POST","headers":{"Content-Type":"application/x-www-form-urlencoded"},"bodyForm":"grant_type=client_credentials&client_id=&client_secret=","reauthenticateIntervalSeconds":3600}' \
--set-json integration.config.customAuthRequestTemplate='{"headers":{"Authorization":"Bearer {{.access_token}}"}}'
```
### Using Docker[](#using-docker "Direct link to Using Docker")
When using Docker, pass the configuration as JSON strings in environment variables:
```
docker run -i --rm \
-e OCEAN__PORT__CLIENT_ID="" \
-e OCEAN__PORT__CLIENT_SECRET="" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
-e OCEAN__INTEGRATION__IDENTIFIER="ocean-custom" \
-e OCEAN__INTEGRATION__TYPE="custom" \
-e OCEAN__EVENT_LISTENER='{"type":"POLLING"}' \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="https://api.yourcompany.com" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="custom" \
-e OCEAN__INTEGRATION__CONFIG__CUSTOM_AUTH_REQUEST='{"endpoint":"/oauth/token","method":"POST","headers":{"Content-Type":"application/x-www-form-urlencoded"},"bodyForm":"grant_type=client_credentials&client_id=&client_secret=","reauthenticateIntervalSeconds":3600}' \
-e OCEAN__INTEGRATION__CONFIG__CUSTOM_AUTH_REQUEST_TEMPLATE='{"headers":{"Authorization":"Bearer {{.access_token}}"}}'
ghcr.io/port-labs/port-ocean-custom:latest
```
## Common examples[](#common-examples "Direct link to Common examples")
### OAuth2 client credentials flow[](#oauth2-client-credentials-flow "Direct link to OAuth2 client credentials flow")
Use this pattern for OAuth2 client credentials grants:
```
{
"customAuthRequest": {
"endpoint": "/oauth/token",
"method": "POST",
"headers": {
"Content-Type": "application/x-www-form-urlencoded"
},
"bodyForm": "grant_type=client_credentials&client_id=&client_secret=",
"reauthenticateIntervalSeconds": 3600
},
"customAuthRequestTemplate": {
"headers": {
"Authorization": "Bearer {{.access_token}}"
}
}
}
```
**Expected auth response:**
```
{
"access_token": "eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9...",
"token_type": "Bearer",
"expires_in": 3600
}
```
### API key in query parameter[](#api-key-in-query-parameter "Direct link to API key in query parameter")
For APIs that return an API key to use in query parameters:
```
{
"customAuthRequest": {
"endpoint": "/api/auth/login",
"method": "POST",
"headers": {
"Content-Type": "application/json"
},
"body": {
"username": "",
"password": ""
}
},
"customAuthRequestTemplate": {
"queryParams": {
"api_key": "{{.apiKey}}"
}
}
}
```
**Expected auth response:**
```
{
"apiKey": "abc123xyz789",
"userId": "12345"
}
```
### JWT token authentication[](#jwt-token-authentication "Direct link to JWT token authentication")
For JWT-based authentication systems:
```
{
"customAuthRequest": {
"endpoint": "/v1/auth/token",
"method": "POST",
"headers": {
"Content-Type": "application/json"
},
"body": {
"clientId": "",
"clientSecret": ""
}
},
"customAuthRequestTemplate": {
"headers": {
"Authorization": "Bearer {{.jwt}}",
"X-API-Version": "{{.version}}"
}
}
}
```
**Expected auth response:**
```
{
"jwt": "eyJhbGciOiJSUzI1NiIsInR5cCI6IkpXVCJ9...",
"version": "2.0",
"expiresAt": "2024-12-31T23:59:59Z"
}
```
### Nested response structure[](#nested-response-structure "Direct link to Nested response structure")
If your authentication service returns nested data, use dot notation:
```
{
"customAuthRequest": {
"endpoint": "/auth/login",
"method": "POST",
"body": {
"credentials": {
"username": "",
"password": ""
}
}
},
"customAuthRequestTemplate": {
"headers": {
"Authorization": "Bearer {{.data.token}}",
"X-Session-ID": "{{.data.sessionId}}"
}
}
}
```
**Expected auth response:**
```
{
"status": "success",
"data": {
"token": "eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9...",
"sessionId": "sess_abc123"
}
}
```
### Token in multiple places[](#token-in-multiple-places "Direct link to Token in multiple places")
You can inject the same token into headers, query params, and body simultaneously:
```
{
"customAuthRequest": {
"endpoint": "/v1/auth/token",
"method": "POST",
"body": {
"clientId": "",
"clientSecret": ""
}
},
"customAuthRequestTemplate": {
"headers": {
"Authorization": "Bearer {{.access_token}}"
},
"queryParams": {
"token": "{{.access_token}}"
},
"body": {
"auth_token": "{{.access_token}}"
}
}
}
```
## Token refresh behavior[](#token-refresh-behavior "Direct link to Token refresh behavior")
The integration handles token refresh in two ways:
### Proactive refresh[](#proactive-refresh "Direct link to Proactive refresh")
If `reauthenticateIntervalSeconds` is configured, tokens refresh automatically 60 seconds before expiration. For example, if you set `reauthenticateIntervalSeconds: 3600`, the integration will refresh the token after 3540 seconds (59 minutes).
### Reactive refresh[](#reactive-refresh "Direct link to Reactive refresh")
If `reauthenticateIntervalSeconds` is not configured, tokens only refresh when the integration receives a 401 (Unauthorized) response. The integration will:
1. Attempt to reauthenticate once
2. Retry the failed request with the new token
3. If reauthentication fails, throw an error visible in the logs
## Error handling[](#error-handling "Direct link to Error handling")
If authentication fails, errors are visible in the integration logs. Common failure scenarios:
* **Auth endpoint returns error**: The integration fails to start and logs the error
* **Missing token field**: If the expected field (e.g., `{{.access_token}}`) is not in the response, an error is thrown
* **Reauthentication fails**: If refresh fails after a 401 error, the integration logs the error and stops processing requests
### Verify configuration[](#verify-configuration "Direct link to Verify configuration")
Ensure your configuration follows these rules:
* At least one of `headers`, `queryParams`, or `body` must be provided in `customAuthRequestTemplate`
* `body` and `bodyForm` cannot both be specified in `customAuthRequest`
* Template paths (e.g., `{{.access_token}}`) must match fields in your auth response
* Replace placeholders (e.g., ``, ``) with your actual values
### Test the authentication endpoint[](#test-the-authentication-endpoint "Direct link to Test the authentication endpoint")
Before configuring the integration, test your authentication endpoint directly:
```
curl -X POST https://api.yourcompany.com/oauth/token \
-H "Content-Type: application/x-www-form-urlencoded" \
-d "grant_type=client_credentials&client_id=YOUR_ID&client_secret=YOUR_SECRET"
```
Verify that the response contains the fields you're trying to extract with template syntax.
---
# Setup
Using this installation option means that the integration will run in your own infrastructure, giving you full control over resources and configuration. You can deploy it using Helm or Docker, and it will run continuously in your environment to keep your data synchronized with Port.
High-scale environments
For high-scale environments with large datasets, allocate sufficient CPU and memory based on your data volume.
## Installation[](#installation "Direct link to Installation")
Choose your preferred deployment method:
* Helm
* Docker
To install the integration using Helm:
1. Go to the [custom connector page](https://app.port.io/settings/data-sources?section=EXPORTERS\&provider=Custom) in your portal.
2. Select the **Real-time and always on** method:
3. A `helm` command will be displayed, with default values already filled out (e.g. your Port client ID, client secret, etc). Copy the command, replace the placeholders with your values, then run it in your terminal to install the integration.
Alternatively, you can install manually using the following steps:
1. Add Port's Helm chart repository:
```
helm repo add --force-update port-labs https://port-labs.github.io/helm-charts
```
2. Install the Helm chart with your configuration:
```
helm install ocean-custom port-labs/port-ocean \
--set port.clientId="" \
--set port.clientSecret="" \
--set port.baseUrl="https://api.port.io" \
--set initializePortResources=true \
--set scheduledResyncInterval=60 \
--set integration.identifier="ocean-custom" \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.config.baseUrl="https://api.yourcompany.com" \
--set integration.config.authType="bearer_token" \
--set integration.secrets.apiToken="" \
--set integration.config.paginationType="page" \
--set integration.config.pageSize=100
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
To install the integration using Docker:
1. Pull the Docker image:
```
docker pull ghcr.io/port-labs/port-ocean-custom:latest
```
2. Run the container with your configuration:
```
docker run -i --rm \
-e OCEAN__PORT__CLIENT_ID="" \
-e OCEAN__PORT__CLIENT_SECRET="" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
-e OCEAN__INITIALIZE_PORT_RESOURCES=true \
-e OCEAN__SCHEDULED_RESYNC_INTERVAL=60 \
-e OCEAN__INTEGRATION__IDENTIFIER="ocean-custom" \
-e OCEAN__INTEGRATION__TYPE="custom" \
-e OCEAN__EVENT_LISTENER='{"type":"POLLING"}' \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="https://api.yourcompany.com" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="bearer_token" \
-e OCEAN__INTEGRATION__CONFIG__API_TOKEN="" \
-e OCEAN__INTEGRATION__CONFIG__PAGINATION_TYPE="page" \
-e OCEAN__INTEGRATION__CONFIG__PAGE_SIZE=100 \
ghcr.io/port-labs/port-ocean-custom:latest
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Health check endpoints
All Ocean integrations expose liveness and readiness endpoints at `/health/live` and `/health/ready`. The readiness endpoint returns `503` until the integration finishes starting up.
For example, if your integration is accessible at `https://your-integration-host:8000`, use `https://your-integration-host:8000/health/ready` for your readiness probe. See [integration endpoints](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md#integration-endpoints) for details.
## Configuration parameters[](#configuration-parameters "Direct link to Configuration parameters")
This table summarizes the available parameters for the installation.
| Parameter | Description | Example | Required |
| ----------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ----------------------------- | -------- |
| `port.clientId` | Your port [client id](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials) | | ✅ |
| `port.clientSecret` | Your port [client secret](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials) | | ✅ |
| `port.baseUrl` | Your Port API URL - `https://api.port.io` for EU, `https://api.us.port.io` for US | | ✅ |
| `integration.config.baseUrl` | The root URL of your API (e.g., `https://api.yourcompany.com`) | | ✅ |
| `integration.config.authType` | Authentication type: `bearer_token`, `api_key`, `basic`, `custom`, or `none`. For custom authentication (OAuth2, JWT, etc.), see [custom authentication](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/custom-authentication/.md) | bearer\_token | ✅ |
| `integration.secrets.apiToken` | Bearer token for authentication (required when `authType` is `bearer_token`) | | ❌ |
| `integration.config.paginationType` | Pagination type: `offset`, `page`, `cursor`, or `none` | page | ❌ |
| `integration.config.pageSize` | Number of items per page (for offset/page pagination) | 100 | ❌ |
| `integration.config.timeout` | Request timeout in seconds (default: 30) | 30 | ❌ |
| `integration.eventListener.type` | The event listener type. Read more about [event listeners](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md) | POLLING | ✅ |
| `integration.type` | The integration to be installed | custom | ✅ |
| `scheduledResyncInterval` | The number of minutes between each resync. When not set the integration will resync for each event listener resync event. Read more about [scheduledResyncInterval](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md#scheduled-resync) | 60 | ❌ |
| `initializePortResources` | Controls legacy initialization behavior. Do not set this parameter to `false` to prevent default resource creation; use `createPortResourcesOrigin` instead. | true | ❌ |
| `createPortResourcesOrigin` | Set to `Empty` to register only the integration without creating default blueprints or mappings. For Docker, set `OCEAN__CREATE_PORT_RESOURCES_ORIGIN="Empty"`. | Empty | ❌ |
| `sendRawDataExamples` | Enable sending raw data examples from the third party API to port for testing and managing the integration mapping. Default is true | true | ❌ |
Start without default resources
For Helm deployments, set `createPortResourcesOrigin: Empty` in your values file or pass `--set createPortResourcesOrigin="Empty"`. The integration registers in Port, but it does not create default blueprints or mappings.
## Recommended resource sizes
To ensure optimal performance and avoid out-of-memory (OOM) errors, we recommend the following resources for this integration:
* **CPU Limit**: `800m`
* **CPU Request**: `400m`
* **Memory Limit**: `4Gi`
* **Memory Request**: `4Gi`
### Set resource values
```
helm install my-integration port-labs/port-ocean \
# ... other parameters
--set resources.limits.cpu=800m \
--set resources.limits.memory=4Gi \
--set resources.requests.cpu=400m \
--set resources.requests.memory=4Gi
```
## Authentication[](#authentication "Direct link to Authentication")
The integration supports several authentication types:
* **Bearer token**: Use `authType: "bearer_token"` with an API token
* **API key**: Use `authType: "api_key"` with an API key and optional custom header name
* **Basic auth**: Use `authType: "basic"` with username and password
* **Custom authentication**: Use `authType: "custom"` for OAuth2, JWT, and other dynamic token-based flows. See [custom authentication](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/custom-authentication/.md) for details.
* **None**: Use `authType: "none"` for public APIs without authentication
## Ready to build?[](#ready-to-build "Direct link to Ready to build?")
Head to [build your integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/build-your-integration/.md) for a step-by-step guide with an interactive configuration builder.
## More resources[](#more-resources "Direct link to More resources")
For all configuration options, code examples, and advanced use cases, check out the [No-code Ocean custom integration repository on GitHub](https://github.com/port-labs/ocean/tree/main/integrations/custom).
---
# No-code Ocean integration
The no-code Ocean integration lets you connect Port to any custom API, internal system, or HTTP service without writing code. Each integration instance connects to one API backend, and you can map multiple endpoints through standard Ocean resource configuration.
If your API needs custom auth, complex pagination, live events, or other logic that configuration cannot express, use a [custom-coded Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/overview/.md) instead.
## Video walkthroughs[](#video-walkthroughs "Direct link to Video walkthroughs")
See the no-code Ocean custom integration in action:
**Tracking Cursor adoption using the no-code Ocean custom integration**
[YouTube video player](https://www.youtube.com/embed/XvhNsbp4p-U)
**Creating a Pokedex in Port using Pokemon open API**
[YouTube video player](https://www.youtube.com/embed/OVVKySiXaOg)
## When to use this integration[](#when-to-use-this-integration "Direct link to When to use this integration")
This integration is ideal when:
* No native Port integration exists for your tool or service.
* You're working with internal or custom-built APIs.
* Your API follows REST conventions (JSON responses, HTTP methods).
* You want a configuration-only solution without custom code.
### No-code vs custom-coded[](#no-code-vs-custom-coded "Direct link to No-code vs custom-coded")
| | No-code Ocean custom integration | [Custom-coded Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/overview/.md) |
| -------------------- | ------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- |
| **How you build it** | Configuration only (endpoints, auth, JQ mapping). | Python code with the Ocean framework. |
| **Best for** | REST APIs that return JSON over HTTP. | Complex auth, pagination, nested data, or non-standard APIs. |
| **Live events** | Currently not supported. | Full control via Ocean event processors. |
| **Maintenance** | Port hosts the runtime (or you run the generic custom image). | You own the app, image, and deployment. |
Start with the no-code option when it covers your API. Choose custom-coded when you need logic that configuration alone cannot express.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
Before installing, gather this information about your API:
### 1. Authentication[](#1-authentication "Direct link to 1. Authentication")
How does your API verify requests?
* **Bearer Token:** OAuth2 tokens, personal access tokens (most modern APIs).
* **API Key:** Custom header like `X-API-Key` or `Authorization`.
* **Basic Auth:** Username and password (legacy systems).
* **Custom Authentication:** OAuth2 client credentials, JWT, and other dynamic token-based flows (self-hosted only).
See [custom authentication](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/custom-authentication/.md) for details and a full list of [supported authentication methods](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/custom-authentication/.md#supported-authentication-methods).
* **None:** Public APIs.
**Where to find it:** Check your API's documentation or settings page. Look for sections titled "API Keys," "Access Tokens," or "Authentication."
Authentication limitations
Some advanced authentication methods like `private_key_jwt` (RFC 7523) and mTLS are not natively supported. See the [authentication capabilities table](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/custom-authentication/.md#supported-authentication-methods) for workarounds.
### 2. Endpoints[](#2-endpoints "Direct link to 2. Endpoints")
Which API endpoint returns the data you want to ingest?
**Example:** `/api/v1/users`, `/v2/projects`, `/tickets`
**How to find it:** Check your API documentation for available endpoints. Look for GET endpoints that return lists of resources.
### 3. Data structure[](#3-data-structure "Direct link to 3. Data structure")
Where is the actual data in your API's response?
**Direct array:**
```
[
{"id": 1, "name": "Alice"},
{"id": 2, "name": "Bob"}
]
```
**Nested data:**
```
{
"data": [
{"id": 1, "name": "Alice"},
{"id": 2, "name": "Bob"}
]
}
```
**Deeply nested:**
```
{
"response": {
"users": {
"items": [
{"id": 1, "name": "Alice"}
]
}
}
}
```
You will use a [JQ](https://jqlang.org/manual/) `data_path` expression in your mapping to tell the integration where to find the array of items (e.g., `.data`, `.users.items`).
## Installation methods[](#installation-methods "Direct link to Installation methods")
The no-code Ocean custom integration can be installed in two ways, depending on your requirements and infrastructure preferences:
* [Hosted by Port](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md)
* [Self-hosted](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup/.md)
### Hosted by Port[](#hosted-by-port "Direct link to Hosted by Port")
Port hosts and manages the integration infrastructure for you. This is the simplest option, you configure the connection settings through the Port UI, and Port handles the rest. The integration runs on Port's infrastructure with a customizable resync interval to keep your data up to date.
**Best for:** Quick setup, or when you prefer a managed solution.
### Self-hosted[](#self-hosted "Direct link to Self-hosted")
You run the integration in your own infrastructure using Helm or Docker. This gives you full control over resources, configuration, and performance tuning. The integration runs continuously in your environment and can be customized to meet your specific needs.
**Best for:** High-scale environments with large datasets that require better control over resources and performance tuning.
## Available integrations[](#available-integrations "Direct link to Available integrations")
The following integrations were built using the no-code Ocean custom integration framework:
**AI usage metrics**
* [OpenAI](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/openai/.md)
**APM & alerting**
* [Azure Monitor](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/azure-monitor/.md)
* [Prometheus](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/prometheus/.md)
**Automation platforms**
* [n8n](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/automation-platforms/n8n/.md)
* [Zapier](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/automation-platforms/zapier/.md)
**Code quality & security**
* [BrowserStack](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/browserstack/.md)
**Identity providers**
* [Microsoft Entra ID](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/identity-providers/azure-ad/.md)
**Incident management**
* [Incident.io](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/incident-io/.md)
* [Jira Service Management](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/jira-service-management/.md)
* [Rootly](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/rootly/.md)
**Other**
* [Slack](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/slack/.md)
## Next steps[](#next-steps "Direct link to Next steps")
**[Review the configuration guide](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/configuration/.md)** - Learn about prerequisites, resource mapping, and advanced configuration options that apply to both installation methods.
---
# Create a custom integration
Port allows you to create custom integrations to ingest data from any tool or platform. You can model the data in Port any way you like, and ingest data using one of the supported methods described in this page.
## Why create a custom integration?[](#why-create-a-custom-integration "Direct link to Why create a custom integration?")
* The tool you want to integrate with is not yet available in our [integrations library](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#available-plug--play-integrations).
* You wish to create your own data model and/or ingest data using a different method than the one provided in our integrations.
* You wish to integrate Port with an internal tool in your organization.
## How to create a custom integration[](#how-to-create-a-custom-integration "Direct link to How to create a custom integration")
Generally, integrating a platform/tool with Port consists of 3 steps:
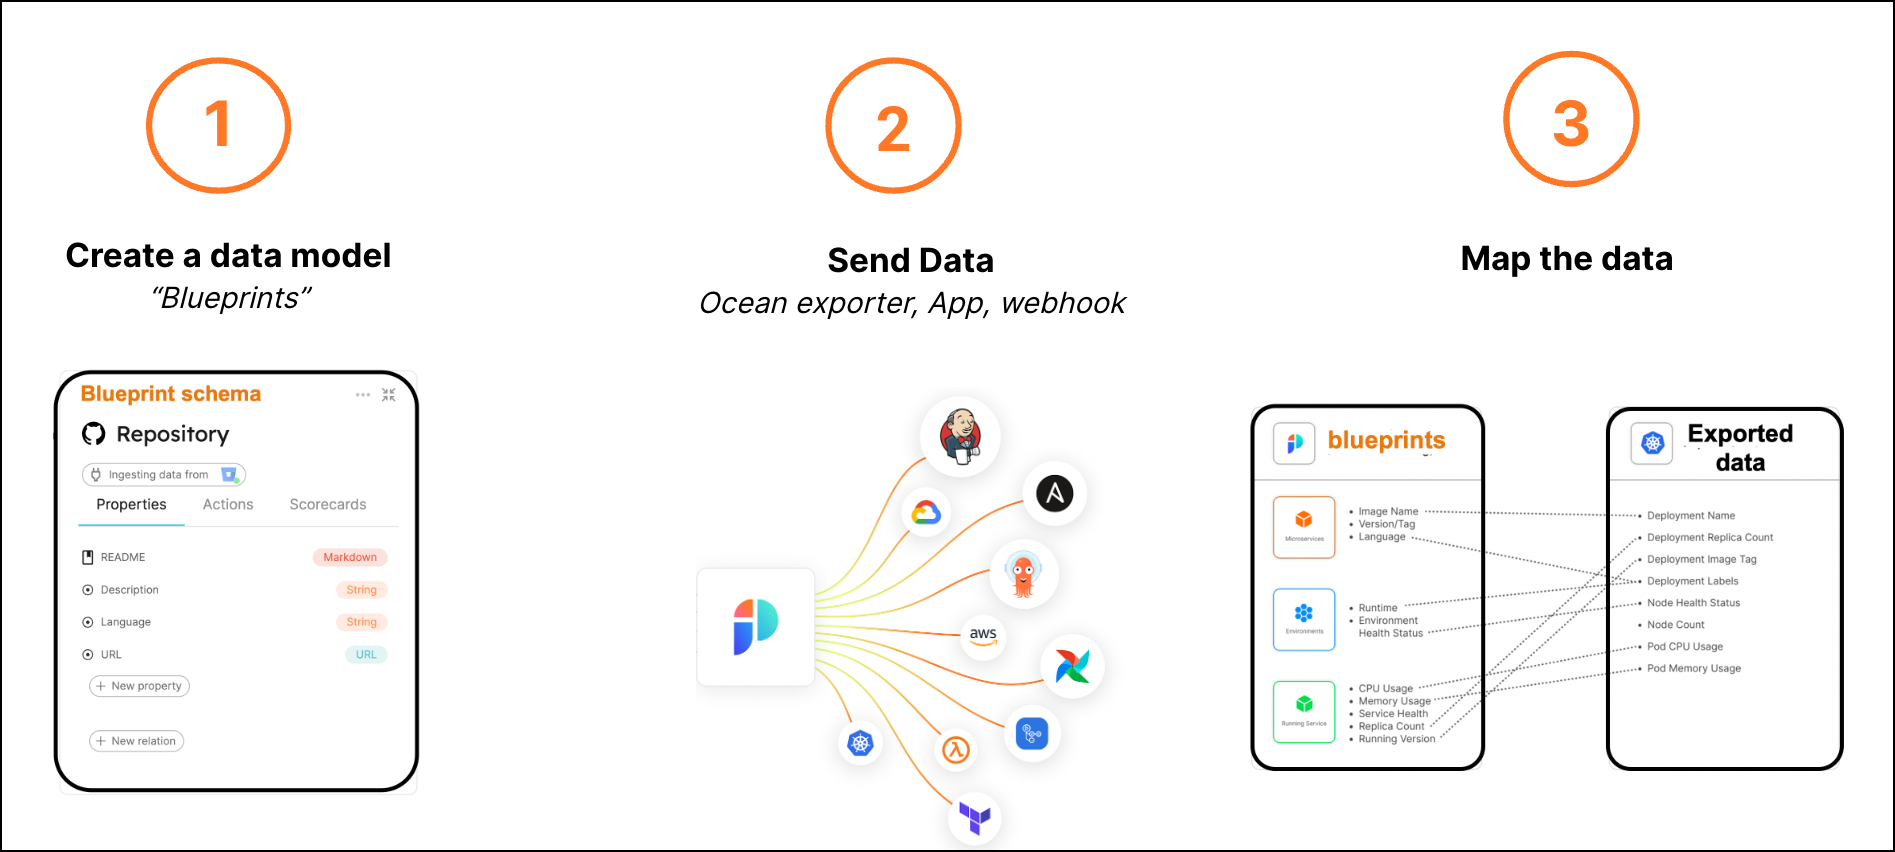
### 1. Define your data model[](#1-define-your-data-model "Direct link to 1. Define your data model")
* Define how your data will be represented in Port, by creating one or more [blueprints](/context-lake/data-model/setup-blueprint/overview/.md) and their properties.
* Determine the relationships between your new blueprints and other data models in your catalog, using [relations](/context-lake/data-model/setup-blueprint/relate-blueprints/.md).
### 2. Ingest data to catalog[](#2-ingest-data-to-catalog "Direct link to 2. Ingest data to catalog")
Use one of the supported methods to ingest data from your tool into Port:
* [No-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) **(recommended!)** - connect a REST API with configuration only.
* [Custom-coded Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/overview/.md) - write Python with the Ocean framework when the no-code option is not enough.
* [Webhooks](/context-lake/ingestion/ingest-data-into-port/webhook/ingest-via-webhooks-overview/.md).
* [Port API](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md).
* [IaC](/context-lake/ingestion/ingest-data-into-port/other/iac/.md).
### 3. Configure the integration[](#3-configure-the-integration "Direct link to 3. Configure the integration")
* When using a webhook, the last step is to [configure the integration's mapping](/context-lake/ingestion/configure-mapping/overview/.md), in order to tell your integration where to find the data in your tool, and how to map it to your blueprint/s.
* When using Port's API, there is no need to configure mapping. Since you are directly interacting with the software catalog, the mapping is done as part of the ingestion process.
## Choose an Ocean approach[](#choose-an-ocean-approach "Direct link to Choose an Ocean approach")
Most of Port's integrations were developed using the **Ocean framework**.
Ocean is an open-source framework that simplifies connecting external tools to Port.
Use the [no-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) when you can describe the API with endpoints, auth, and JQ mapping. Use a [custom-coded Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/custom-coded-ocean-integration/overview/.md) when you need custom Python logic for auth, pagination, live events, or actions.
To contribute a public integration to the community, see the [Ocean repository contributing guide](https://github.com/port-labs/ocean/blob/main/CONTRIBUTING.md).
---
# Available integrations
Browse all available Port native integrations. Click an integration to open its documentation.
Search integrations...
All64Git7Kubernetes stack8Argo CD1Cloud providers4Project management3CI/CD2Feature management1APM & alerting6Incident management8Code quality & security8Terraform1Cloud cost2Event processing1AI usage metrics4Automation platforms2Identity providers2Other4
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/.md)
### [GitHub (Ocean)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github-ocean/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/)
### [GitHub (sunset)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/.md)
### [GitLab v2](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab-v2/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab/.md)
### [GitLab (deprecated)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/gitlab/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-cloud/.md)
### [BitBucket](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-cloud/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-server/.md)
### [BitBucket server](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/bitbucket/bitbucket-server/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/azure-devops/.md)
### [AzureDevops](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/azure-devops/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/jenkins/.md)
### [Jenkins](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/jenkins/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/octopus-deploy/.md)
### [Octopus Deploy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/octopus-deploy/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/argocd/.md)
### [ArgoCD](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/argocd/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/komodor/.md)
### [Komodor](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/komodor/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/.md)
### [Kubernetes](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/istio/.md)
### [Istio](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/istio/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/fluxcd/.md)
### [FluxCD](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/fluxcd/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/knative/.md)
### [Knative](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/knative/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/kyverno/.md)
### [Kyverno](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/kyverno/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/openshift/.md)
### [OpenShift](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/openshift/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/trivy/.md)
### [Trivy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/kubernetes-stack/kubernetes/templates/trivy/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira/.md)
### [Jira](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira-server/.md)
### [Jira server (self-hosted)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/jira-server/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/linear/.md)
### [Linear](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/project-management/linear/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/.md)
### [AWS Legacy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/Overview/.md)
### [AWS](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/Overview/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure/.md)
### [Azure](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/gcp/.md)
### [GCP](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/gcp/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/terraform-cloud/.md)
### [Terraform](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/terraform-cloud/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog/.md)
### [Datadog](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/newrelic/.md)
### [New Relic](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/newrelic/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/sentry/.md)
### [Sentry](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/sentry/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/prometheus/.md)
### [Prometheus](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/prometheus/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/dynatrace/.md)
### [Dynatrace](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/dynatrace/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/azure-monitor/.md)
### [Azure Monitor](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/azure-monitor/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/snyk/.md)
### [Snyk](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/snyk/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/wiz/.md)
### [Wiz](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/wiz/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/mend/.md)
### [Mend.io](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/mend/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/sonarqube/.md)
### [SonarQube](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/sonarqube/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/aikido/.md)
### [Aikido](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/aikido/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/checkmarx/.md)
### [Checkmarx](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/checkmarx/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/armorcode/.md)
### [Armorcode](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/armorcode/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/browserstack/.md)
### [BrowserStack](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/code-quality-security/browserstack/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/feature-management/launchdarkly/.md)
### [Launchdarkly](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/feature-management/launchdarkly/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/pagerduty/.md)
### [PagerDuty](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/pagerduty/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/statuspage/.md)
### [StatusPage](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/statuspage/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/firehydrant/.md)
### [FireHydrant](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/firehydrant/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/opsgenie/.md)
### [OpsGenie](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/opsgenie/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/servicenow/.md)
### [ServiceNow](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/servicenow/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/rootly/.md)
### [Rootly](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/rootly/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/incident-io/.md)
### [Incident.io](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/incident-io/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/jira-service-management/.md)
### [Jira Service Management](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/incident-management/jira-service-management/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost/.md)
### [Kubecost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/opencost/.md)
### [Opencost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/opencost/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/event-processing/kafka/.md)
### [Kafka](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/event-processing/kafka/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/identity-providers/okta/.md)
### [Okta](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/identity-providers/okta/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/identity-providers/azure-ad/.md)
### [Microsoft Entra ID](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/identity-providers/azure-ad/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/amplication/.md)
### [Amplication](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/amplication/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/backstage/.md)
### [Backstage](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/backstage/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/slack/.md)
### [Slack](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/other/slack/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/automation-platforms/zapier/.md)
### [Zapier](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/automation-platforms/zapier/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/automation-platforms/n8n/.md)
### [n8n](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/automation-platforms/n8n/.md)
[](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md)
### [Ocean custom](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/github-copilot/.md)
### [Github Copilot](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/github-copilot/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/claude/.md)
### [Claude AI](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/claude/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/cursor/.md)
### [Cursor](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/cursor/.md)
[](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/openai/.md)
### [OpenAI](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/ai-usage-metrics/openai/.md)
---
# Claude AI metrics

Loading version...
Port's Claude integration allows you to ingest Claude AI (Enterprise) and Claude Platform usage, cost, skill adoption, and Claude Code analytics metrics into your software catalog.
Supported resources [claude-ai-user-activity](https://support.claude.com/en/articles/13703965-claude-enterprise-analytics-api-reference-guide)[claude-ai-user-usage](https://support.claude.com/en/articles/13703965-claude-enterprise-analytics-api-reference-guide)[claude-ai-user-cost](https://support.claude.com/en/articles/13703965-claude-enterprise-analytics-api-reference-guide)[claude-ai-skill-usage](https://platform.claude.com/docs/en/api/admin/analytics/skills/list)[claude-platform-usage-record](https://platform.claude.com/docs/en/api/admin/usage_report/retrieve_messages)[claude-usage-record](https://platform.claude.com/docs/en/api/admin/usage_report/retrieve_messages)[claude-platform-cost-record](https://platform.claude.com/docs/en/api/admin/cost_report/retrieve)[claude-cost-record](https://platform.claude.com/docs/en/api/admin/cost_report/retrieve)[claude-platform-code-analytics](https://platform.claude.com/docs/en/api/admin/usage_report/retrieve_claude_code)[claude-code-analytics](https://platform.claude.com/docs/en/api/admin/usage_report/retrieve_claude_code)
## Deployment modes[](#deployment-modes "Direct link to Deployment modes")
The integration runs in one of two deployment modes, controlled by the `isClaudeEnterprise` configuration option. Each mode targets a different set of Claude API endpoints and requires an API key with a different scope.
| Mode | `isClaudeEnterprise` | Resources synced | Required API key scope |
| ---------------------- | -------------------- | ------------------------------------------------------------------------------------------------- | ---------------------- |
| Claude AI (Enterprise) | `true` (default) | `claude-ai-user-activity`, `claude-ai-user-usage`, `claude-ai-user-cost`, `claude-ai-skill-usage` | `read:analytics` |
| Claude Platform | `false` | `claude-platform-usage-record`, `claude-platform-cost-record`, `claude-platform-code-analytics` | `api:admin` |
Use **Claude AI (Enterprise)** mode to track per-user engagement, token usage, cost, and skill adoption for everyday Claude usage such as the web app and Claude Code. Use **Claude Platform** mode to track aggregated usage and cost for Claude Platform API consumption, typically used by developers.
Blueprints for both modes
When `initializePortResources` is enabled, the integration creates the default blueprints for **both** Claude AI and Claude Platform, regardless of the selected mode. Only the resources for the active mode are populated with data.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
* An Anthropic API key for the deployment mode you want to use:
* **Claude AI (Enterprise)** mode requires an analytics API key with the `read:analytics` scope, minted by a Primary Owner from `claude.ai/analytics/api-keys`.
* **Claude Platform** mode requires an [Admin API key](https://platform.claude.com/docs/en/manage-claude/admin-api-keys) with the `api:admin` scope and access to the usage and cost reports.
* Your Port user role is set to `Admin`.
## Setup[](#setup "Direct link to Setup")
Choose one of the installation methods below. If you are not sure which option to use, review the [installation methods overview](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Customizable resync interval for data ingestion
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party API into Port.
The mapping uses the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to transform fields and shape incoming Claude data into Port entities.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration. It maps the Claude AI (Enterprise) resources, which are synced in the default deployment mode:
**Default mapping configuration (click to expand)**
```
resources:
- kind: claude-ai-user-activity
selector:
query: 'true'
timeFrame: 30
port:
entity:
mappings:
identifier: .user.id + "-" + .__date
title: (.user.email_address // .user.id) + " - " + .__date
blueprint: '"claude_ai_user_activity"'
properties:
record_date: .__date + "T00:00:00Z"
user_id: .user.id
email: .user.email_address
chat_conversation_count: (.chat_metrics.distinct_conversation_count // 0)
chat_message_count: (.chat_metrics.message_count // 0)
chat_thinking_message_count: (.chat_metrics.thinking_message_count // 0)
chat_skills_used_count: (.chat_metrics.distinct_skills_used_count // 0)
chat_connectors_used_count: (.chat_metrics.connectors_used_count // 0)
code_session_count: (.claude_code_metrics.core_metrics.distinct_session_count // 0)
code_commit_count: (.claude_code_metrics.core_metrics.commit_count // 0)
code_pull_request_count: (.claude_code_metrics.core_metrics.pull_request_count // 0)
lines_added: (.claude_code_metrics.core_metrics.lines_of_code.added_count // 0)
lines_removed: (.claude_code_metrics.core_metrics.lines_of_code.removed_count // 0)
edit_tool_accepted: (.claude_code_metrics.tool_actions.edit_tool.accepted_count // 0)
edit_tool_rejected: (.claude_code_metrics.tool_actions.edit_tool.rejected_count // 0)
write_tool_accepted: (.claude_code_metrics.tool_actions.write_tool.accepted_count // 0)
write_tool_rejected: (.claude_code_metrics.tool_actions.write_tool.rejected_count // 0)
multi_edit_tool_accepted: (.claude_code_metrics.tool_actions.multi_edit_tool.accepted_count // 0)
multi_edit_tool_rejected: (.claude_code_metrics.tool_actions.multi_edit_tool.rejected_count // 0)
notebook_edit_tool_accepted: (.claude_code_metrics.tool_actions.notebook_edit_tool.accepted_count // 0)
notebook_edit_tool_rejected: (.claude_code_metrics.tool_actions.notebook_edit_tool.rejected_count // 0)
web_search_count: (.web_search_count // 0)
chat_projects_used_count: (.chat_metrics.distinct_projects_used_count // 0)
chat_projects_created_count: (.chat_metrics.distinct_projects_created_count // 0)
chat_artifacts_created_count: (.chat_metrics.distinct_artifacts_created_count // 0)
chat_files_uploaded_count: (.chat_metrics.distinct_files_uploaded_count // 0)
chat_shared_conversations_viewed_count: (.chat_metrics.shared_conversations_viewed_count // 0)
office_session_count: >-
([.office_metrics.excel.distinct_session_count,
.office_metrics.powerpoint.distinct_session_count,
.office_metrics.word.distinct_session_count,
.office_metrics.outlook.distinct_session_count] | map(. // 0) | add)
office_message_count: >-
([.office_metrics.excel.message_count,
.office_metrics.powerpoint.message_count,
.office_metrics.word.message_count,
.office_metrics.outlook.message_count] | map(. // 0) | add)
cowork_session_count: (.cowork_metrics.distinct_session_count // 0)
cowork_message_count: (.cowork_metrics.message_count // 0)
design_session_count: (.design_metrics.distinct_session_count // 0)
design_message_count: (.design_metrics.message_count // 0)
- kind: claude-ai-user-usage
selector:
query: 'true'
startingAt: '2026-01-01T00:00:00Z'
port:
entity:
mappings:
identifier: >-
.actor.user_id + "-" + .__starting_at[:10] + "-" + (.product // "all")
+ "-" + (.model // "all")
title: (.actor.name // .actor.email // .actor.user_id) + " - " + .__starting_at[:10]
blueprint: '"claude_ai_user_usage"'
properties:
record_date: .__starting_at
range_end: .__ending_at
user_id: .actor.user_id
user_name: .actor.name
email: .actor.email
deleted: (.actor.deleted // false)
product: .product
model: .model
context_window: .context_window
inference_geo: .inference_geo
speed: .speed
uncached_input_tokens: (.uncached_input_tokens // 0)
cache_creation_1h_tokens: (.cache_creation.ephemeral_1h_input_tokens // 0)
cache_creation_5m_tokens: (.cache_creation.ephemeral_5m_input_tokens // 0)
cache_read_input_tokens: (.cache_read_input_tokens // 0)
output_tokens: (.output_tokens // 0)
total_tokens: (.total_tokens // 0)
web_search_requests: (.server_tool_use.web_search_requests // 0)
requests: (.requests // 0)
- kind: claude-ai-user-cost
selector:
query: 'true'
startingAt: '2026-01-01T00:00:00Z'
port:
entity:
mappings:
identifier: >-
.actor.user_id + "-" + .__starting_at[:10] + "-" + (.product // "all")
+ "-" + (.model // "all")
title: (.actor.name // .actor.email // .actor.user_id) + " - " + .__starting_at[:10]
blueprint: '"claude_ai_user_cost"'
properties:
record_date: .__starting_at
range_end: .__ending_at
user_id: .actor.user_id
user_name: .actor.name
email: .actor.email
deleted: (.actor.deleted // false)
product: .product
model: .model
currency: (.currency // "USD")
amount: ((.amount // "0") | tonumber) / 100
list_amount: ((.list_amount // "0") | tonumber) / 100
requests: (.requests // 0)
- kind: claude-ai-skill-usage
selector:
query: 'true'
timeFrame: 30
port:
entity:
mappings:
identifier: >-
((.skill_name // "unknown") + "-" + .__date
| gsub("[^A-Za-z0-9@_.+:\\\\/='-]"; "_"))
title: ((.skill_display_name // .skill_name // "unknown") + " - " + .__date)
blueprint: '"claude_ai_skill_usage"'
properties:
record_date: .__date + "T00:00:00Z"
skill_name: (.skill_name // "unknown")
skill_display_name: .skill_display_name
distinct_user_count: .distinct_user_count
enable_count: .enable_count
invocation_count: .invocation_count
share_status: .share_status
currency: (.currency // "USD")
estimated_overage_spend: (if .estimated_overage_spend then (.estimated_overage_spend | tonumber) / 100 else null end)
attributed_list_price: (if .attributed_list_price then (.attributed_list_price | tonumber) / 100 else null end)
chat_conversation_skill_used_count: .chat_metrics.distinct_conversation_skill_used_count
code_session_skill_used_count: .claude_code_metrics.distinct_session_skill_used_count
cowork_session_skill_used_count: .cowork_metrics.distinct_session_skill_used_count
excel_session_skill_used_count: .office_metrics.excel.distinct_session_skill_used_count
powerpoint_session_skill_used_count: .office_metrics.powerpoint.distinct_session_skill_used_count
word_session_skill_used_count: .office_metrics.word.distinct_session_skill_used_count
outlook_session_skill_used_count: .office_metrics.outlook.distinct_session_skill_used_count
```
### Advanced selector configuration[](#advanced-selector-configuration "Direct link to Advanced selector configuration")
The available selectors depend on the active deployment mode. **`query`** applies to all resource kinds in both modes and defaults to `'true'`.
* Claude AI (Enterprise)
* Claude Platform
#### `claude-ai-user-activity`
This resource returns data for one specific day per call. The endpoint only returns data that is at least three days old, so the date window always ends roughly three days ago. To control the start of the window, provide one of `timeFrame` or `startingDate` (mutually exclusive). When you set neither, the integration defaults to a 30-day lookback.
| Field | Format | Description |
| -------------- | ------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `timeFrame` | `number` | Number of days to look back, ending around three days ago. Must be greater than `0`. Mutually exclusive with `startingDate`. Defaults to `30` when neither field is set. |
| `startingDate` | `YYYY-MM-DD` | Iterates from this date once per day up to around three days ago, clamped to `2026-01-01` (the earliest available data). Use for historical backfills. Mutually exclusive with `timeFrame`. |
Using `timeFrame` (recommended for ongoing syncs):
```
selector:
query: 'true'
timeFrame: 30 # look back 30 days, one API call per day
```
Using `startingDate` (for a historical backfill):
```
selector:
query: 'true'
startingDate: '2026-01-01' # iterate from this date, one API call per day
```
#### `claude-ai-skill-usage`
This resource returns org-level [skill usage](https://platform.claude.com/docs/en/api/admin/analytics/skills/list) for one specific day per call. The endpoint only returns data once it is available, typically with a 1-2 day lag, and is no earlier than `2026-01-01`. To control the start of the window, provide one of `timeFrame` or `startingDate` (mutually exclusive). When you set neither, the integration defaults to a 30-day lookback.
| Field | Format | Description |
| -------------- | ------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `timeFrame` | `number` | Number of days to look back, ending around two days ago. Must be greater than `0`. Mutually exclusive with `startingDate`. Defaults to `30` when neither field is set. |
| `startingDate` | `YYYY-MM-DD` | Iterates from this date once per day up to around two days ago, clamped to `2026-01-01` (the earliest available data). Use for historical backfills. Mutually exclusive with `timeFrame`. |
| `groupBy` | `array` | Optional. Break skill usage out by one dimension at a time. Allowed values: `user_id`, `product`, `rbac_group_id`. Leave empty for org-level totals. `product` is one of `chat`, `claude_code`, `cowork`, or `office_agent`. See [Breaking down analytics on user and team level](#breaking-down-analytics-on-user-and-team-level). |
Using `timeFrame` (recommended for ongoing syncs):
```
selector:
query: 'true'
timeFrame: 30 # look back 30 days, one API call per day
```
Using `startingDate` (for a historical backfill):
```
selector:
query: 'true'
startingDate: '2026-01-01' # iterate from this date, one API call per day
```
#### `claude-ai-user-usage` and `claude-ai-user-cost`
These resources return per-user data across a date range and share the same selector fields.
| Field | Type | Description |
| --------------------- | --------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `startingAt` | `string` | RFC 3339 UTC start of the range (inclusive), e.g. `2026-01-01T00:00:00Z`. Automatically clamped to the last 31 days and no earlier than `2026-01-01`. Defaults to `2026-01-01T00:00:00Z`. |
| `endingAt` | `string` | RFC 3339 UTC end of the range (exclusive). Defaults to now. The range spans at most 31 days. |
| `excludeDeletedUsers` | `boolean` | When `true`, rows for deleted users are omitted. Defaults to `false`. |
| `products` | `array` | Filter to specific seat-based product surfaces. Allowed values: `chat`, `claude_code`, `cowork`, `office_agent`, `claude_in_chrome`, `claude_design`. |
| `models` | `array` | Filter to specific model names. |
| `groupBy` | `array` | Break each user's row out by the given dimensions. Allowed values: `product`, `model`, `context_window`, `inference_geo`, `speed`. |
| `contextWindows` | `array` | Filter to specific context-window pricing tiers. Allowed values: `0-200k`, `200k-1M`. |
| `inferenceGeos` | `array` | Filter to specific inference regions. Allowed values: `global`, `us`, `not_available`. |
| `speeds` | `array` | Filter to fast or standard inference mode. Allowed values: `fast`, `standard`. |
```
selector:
query: 'true'
startingAt: '2026-01-01T00:00:00Z'
endingAt: '2026-01-31T00:00:00Z'
excludeDeletedUsers: false
products: [chat, claude_code]
groupBy: [product, model]
```
The Claude Platform selectors behave as follows:
* **`startingDate`** is required for `claude-platform-usage-record` and `claude-platform-cost-record`. For `claude-platform-code-analytics`, either `startingDate` or `timeFrame` must be provided (mutually exclusive).
* **`bucketWidth`** controls time granularity for usage and cost resources.
* **`groupBy`** is available for `claude-platform-usage-record` and lets you break down usage by dimensions.
#### `claude-platform-usage-record`
```
selector:
query: 'true'
startingDate: '2026-01-01T00:00:00Z'
bucketWidth: 1d # supported: 1m | 1h | 1d
groupBy: [workspace_id]
```
* `startingDate` must use ISO-8601 UTC format (`YYYY-MM-DDTHH:MM:SSZ`).
* `bucketWidth` supports `1m`, `1h`, and `1d` for usage records.
* `groupBy` supports dimensions such as `api_key_id`, `workspace_id`, `context_window`, `speed`, `inference_geo`, `account_id`, `service_account_id`, `model`, and `service_tier`.
#### `claude-platform-cost-record`
```
selector:
query: 'true'
startingDate: '2026-01-01T00:00:00Z'
bucketWidth: 1d
```
* `startingDate` must use ISO-8601 UTC format (`YYYY-MM-DDTHH:MM:SSZ`).
* `bucketWidth` supports `1d` only for cost records in this integration.
#### `claude-platform-code-analytics`
The API returns data for one specific day per call. To control the date window, provide exactly one of the following fields:
| Field | Format | Description |
| -------------- | ------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `timeFrame` | `number` | Number of days to look back from today. The integration calls the API once per day for each of the last N days. Recommended for ongoing syncs. |
| `startingDate` | `YYYY-MM-DD` | Iterates from this date to today, calling the API once per day. Use for historical backfills. A warning is logged and no data is fetched if the date is in the future. |
Mutually exclusive
`timeFrame` and `startingDate` cannot both be set on `claude-platform-code-analytics`. Providing neither or both will cause a validation error.
Using `timeFrame` (recommended for ongoing syncs):
```
selector:
query: 'true'
timeFrame: 30 # fetch the last 30 days, one API call per day
```
Using `startingDate` (for a historical backfill):
```
selector:
query: 'true'
startingDate: '2026-01-01' # iterate from this date to today
```
## Mapping & examples per resource[](#mapping--examples-per-resource "Direct link to Mapping & examples per resource")
To view and test the integration mapping against sample API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources).
* Claude AI (Enterprise)
* Claude Platform
claude-ai-user-activityclaude-ai-user-usageclaude-ai-user-costclaude-ai-skill-usage
BlueprintJSON
Create in Port
```
{
"identifier": "claude_ai_user_activity",
"description": "Per-user Claude (chat) and Claude Code engagement metrics for a single day",
"title": "Claude AI User Activity",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Record Date (UTC)"
},
"user_id": {
"type": "string",
"title": "User ID"
},
"email": {
"type": "string",
"format": "user",
"title": "Email"
},
"chat_conversation_count": {
"type": "number",
"title": "Chat Conversations"
},
"chat_message_count": {
"type": "number",
"title": "Chat Messages"
},
"chat_thinking_message_count": {
"type": "number",
"title": "Chat Thinking Messages"
},
"chat_skills_used_count": {
"type": "number",
"title": "Chat Skills Used"
},
"chat_connectors_used_count": {
"type": "number",
"title": "Chat Connectors Used"
},
"code_session_count": {
"type": "number",
"title": "Claude Code Sessions"
},
"code_commit_count": {
"type": "number",
"title": "Claude Code Commits"
},
"code_pull_request_count": {
"type": "number",
"title": "Claude Code Pull Requests"
},
"lines_added": {
"type": "number",
"title": "Lines Added"
},
"lines_removed": {
"type": "number",
"title": "Lines Removed"
},
"edit_tool_accepted": {
"type": "number",
"title": "Edit Tool Accepted"
},
"edit_tool_rejected": {
"type": "number",
"title": "Edit Tool Rejected"
},
"write_tool_accepted": {
"type": "number",
"title": "Write Tool Accepted"
},
"write_tool_rejected": {
"type": "number",
"title": "Write Tool Rejected"
},
"web_search_count": {
"type": "number",
"title": "Web Search Count"
},
"chat_projects_used_count": {
"type": "number",
"title": "Chat Projects Used"
},
"chat_projects_created_count": {
"type": "number",
"title": "Chat Projects Created"
},
"chat_artifacts_created_count": {
"type": "number",
"title": "Chat Artifacts Created"
},
"chat_files_uploaded_count": {
"type": "number",
"title": "Chat Files Uploaded"
},
"chat_shared_conversations_viewed_count": {
"type": "number",
"title": "Chat Shared Conversations Viewed"
},
"multi_edit_tool_accepted": {
"type": "number",
"title": "Multi-Edit Tool Accepted"
},
"multi_edit_tool_rejected": {
"type": "number",
"title": "Multi-Edit Tool Rejected"
},
"notebook_edit_tool_accepted": {
"type": "number",
"title": "Notebook Edit Tool Accepted"
},
"notebook_edit_tool_rejected": {
"type": "number",
"title": "Notebook Edit Tool Rejected"
},
"office_session_count": {
"type": "number",
"title": "Office Sessions (Excel/PPT/Word/Outlook)"
},
"office_message_count": {
"type": "number",
"title": "Office Messages"
},
"cowork_session_count": {
"type": "number",
"title": "Cowork Sessions"
},
"cowork_message_count": {
"type": "number",
"title": "Cowork Messages"
},
"design_session_count": {
"type": "number",
"title": "Design Sessions"
},
"design_message_count": {
"type": "number",
"title": "Design Messages"
}
},
"required": [
"record_date"
]
},
"mirrorProperties": {},
"calculationProperties": {
"total_lines_changed": {
"title": "Total Lines Changed",
"calculation": ".properties.lines_added + .properties.lines_removed",
"type": "number"
},
"edit_acceptance_rate": {
"title": "Edit Acceptance Rate",
"calculation": "if (.properties.edit_tool_accepted + .properties.edit_tool_rejected) > 0 then (.properties.edit_tool_accepted / (.properties.edit_tool_accepted + .properties.edit_tool_rejected)) * 100 else 0 end",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-ai-user-activity
selector:
query: 'true'
timeFrame: 30
port:
entity:
mappings:
identifier: .user.id + "-" + .__date
title: (.user.email_address // .user.id) + " - " + .__date
blueprint: '"claude_ai_user_activity"'
properties:
record_date: .__date + "T00:00:00Z"
user_id: .user.id
email: .user.email_address
chat_conversation_count: (.chat_metrics.distinct_conversation_count // 0)
chat_message_count: (.chat_metrics.message_count // 0)
chat_thinking_message_count: (.chat_metrics.thinking_message_count // 0)
chat_skills_used_count: (.chat_metrics.distinct_skills_used_count // 0)
chat_connectors_used_count: (.chat_metrics.connectors_used_count // 0)
code_session_count: (.claude_code_metrics.core_metrics.distinct_session_count // 0)
code_commit_count: (.claude_code_metrics.core_metrics.commit_count // 0)
code_pull_request_count: (.claude_code_metrics.core_metrics.pull_request_count // 0)
lines_added: (.claude_code_metrics.core_metrics.lines_of_code.added_count // 0)
lines_removed: (.claude_code_metrics.core_metrics.lines_of_code.removed_count // 0)
edit_tool_accepted: (.claude_code_metrics.tool_actions.edit_tool.accepted_count // 0)
edit_tool_rejected: (.claude_code_metrics.tool_actions.edit_tool.rejected_count // 0)
write_tool_accepted: (.claude_code_metrics.tool_actions.write_tool.accepted_count // 0)
write_tool_rejected: (.claude_code_metrics.tool_actions.write_tool.rejected_count // 0)
multi_edit_tool_accepted: (.claude_code_metrics.tool_actions.multi_edit_tool.accepted_count // 0)
multi_edit_tool_rejected: (.claude_code_metrics.tool_actions.multi_edit_tool.rejected_count // 0)
notebook_edit_tool_accepted: (.claude_code_metrics.tool_actions.notebook_edit_tool.accepted_count // 0)
notebook_edit_tool_rejected: (.claude_code_metrics.tool_actions.notebook_edit_tool.rejected_count // 0)
web_search_count: (.web_search_count // 0)
chat_projects_used_count: (.chat_metrics.distinct_projects_used_count // 0)
chat_projects_created_count: (.chat_metrics.distinct_projects_created_count // 0)
chat_artifacts_created_count: (.chat_metrics.distinct_artifacts_created_count // 0)
chat_files_uploaded_count: (.chat_metrics.distinct_files_uploaded_count // 0)
chat_shared_conversations_viewed_count: (.chat_metrics.shared_conversations_viewed_count // 0)
office_session_count: >-
([.office_metrics.excel.distinct_session_count,
.office_metrics.powerpoint.distinct_session_count,
.office_metrics.word.distinct_session_count,
.office_metrics.outlook.distinct_session_count] | map(. // 0) | add)
office_message_count: >-
([.office_metrics.excel.message_count,
.office_metrics.powerpoint.message_count,
.office_metrics.word.message_count,
.office_metrics.outlook.message_count] | map(. // 0) | add)
cowork_session_count: (.cowork_metrics.distinct_session_count // 0)
cowork_message_count: (.cowork_metrics.message_count // 0)
design_session_count: (.design_metrics.distinct_session_count // 0)
design_message_count: (.design_metrics.message_count // 0)
```
Sample payloadJSON
```
{
"user": {
"id": "user_01VxtsnMPZAsxdeoXJB9BFp1",
"email_address": "dev@domain.io"
},
"distinct_user_count": null,
"chat_metrics": {
"distinct_conversation_count": 2,
"message_count": 4,
"thinking_message_count": 0,
"distinct_projects_used_count": 0,
"distinct_projects_created_count": 0,
"distinct_artifacts_created_count": 0,
"distinct_skills_used_count": 0,
"connectors_used_count": 0,
"distinct_files_uploaded_count": 0,
"shared_conversations_viewed_count": 0,
"distinct_shared_artifacts_viewed_count": 0
},
"claude_code_metrics": {
"core_metrics": {
"distinct_session_count": 0,
"commit_count": 0,
"pull_request_count": 0,
"lines_of_code": {
"added_count": 0,
"removed_count": 0
}
},
"tool_actions": {
"edit_tool": {
"accepted_count": 0,
"rejected_count": 0
},
"multi_edit_tool": {
"accepted_count": 0,
"rejected_count": 0
},
"write_tool": {
"accepted_count": 0,
"rejected_count": 0
},
"notebook_edit_tool": {
"accepted_count": 0,
"rejected_count": 0
}
}
},
"office_metrics": {
"excel": {
"distinct_session_count": 0,
"message_count": 0,
"skills_used_count": 0,
"distinct_skills_used_count": 0,
"connectors_used_count": 0,
"distinct_connectors_used_count": 0
},
"powerpoint": {
"distinct_session_count": 0,
"message_count": 0,
"skills_used_count": 0,
"distinct_skills_used_count": 0,
"connectors_used_count": 0,
"distinct_connectors_used_count": 0
},
"word": {
"distinct_session_count": 0,
"message_count": 0,
"skills_used_count": 0,
"distinct_skills_used_count": 0,
"connectors_used_count": 0,
"distinct_connectors_used_count": 0
},
"outlook": {
"distinct_session_count": 0,
"message_count": 0,
"skills_used_count": 0,
"distinct_skills_used_count": 0,
"connectors_used_count": 0,
"distinct_connectors_used_count": 0
}
},
"cowork_metrics": {
"distinct_session_count": 0,
"action_count": 0,
"file_edit_count": null,
"edit_tool_count": null,
"multi_edit_tool_count": null,
"write_tool_count": null,
"notebook_edit_tool_count": null,
"sessions_with_file_edits_count": null,
"dispatch_turn_count": 0,
"message_count": 0,
"skills_used_count": 0,
"distinct_skills_used_count": 0,
"connectors_used_count": 0,
"distinct_connectors_used_count": 0
},
"design_metrics": {
"distinct_session_count": 0,
"distinct_projects_used_count": 0,
"distinct_projects_created_count": 0,
"message_count": 0
},
"web_search_count": 0,
"__date": "2026-05-14"
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_ai_user_usage",
"description": "Per-user token usage across a date range",
"title": "Claude AI User Usage",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Range Start (UTC)"
},
"range_end": {
"type": "string",
"format": "date-time",
"title": "Range End (UTC)"
},
"user_id": {
"type": "string",
"title": "User ID"
},
"user_name": {
"type": "string",
"title": "User Name"
},
"email": {
"type": "string",
"format": "user",
"title": "Email"
},
"deleted": {
"type": "boolean",
"title": "Deleted User"
},
"product": {
"type": "string",
"title": "Product"
},
"model": {
"type": "string",
"title": "Model"
},
"context_window": {
"type": "string",
"title": "Context Window"
},
"inference_geo": {
"type": "string",
"title": "Inference Geo"
},
"speed": {
"type": "string",
"title": "Speed"
},
"uncached_input_tokens": {
"type": "number",
"title": "Uncached Input Tokens"
},
"cache_creation_1h_tokens": {
"type": "number",
"title": "Cache Creation (1hr) Tokens"
},
"cache_creation_5m_tokens": {
"type": "number",
"title": "Cache Creation (5min) Tokens"
},
"cache_read_input_tokens": {
"type": "number",
"title": "Cache Read Input Tokens"
},
"output_tokens": {
"type": "number",
"title": "Output Tokens"
},
"total_tokens": {
"type": "number",
"title": "Total Tokens"
},
"web_search_requests": {
"type": "number",
"title": "Web Search Requests"
},
"requests": {
"type": "number",
"title": "Requests"
}
},
"required": [
"record_date"
]
},
"mirrorProperties": {},
"calculationProperties": {
"total_input_tokens": {
"title": "Total Input Tokens",
"description": "Sum of uncached input and cache read tokens",
"calculation": ".properties.uncached_input_tokens + .properties.cache_read_input_tokens",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-ai-user-usage
selector:
query: 'true'
startingAt: '2026-01-01T00:00:00Z'
port:
entity:
mappings:
identifier: >-
.actor.user_id + "-" + .__starting_at[:10] + "-" + (.product // "all")
+ "-" + (.model // "all")
title: (.actor.name // .actor.email // .actor.user_id) + " - " + .__starting_at[:10]
blueprint: '"claude_ai_user_usage"'
properties:
record_date: .__starting_at
range_end: .__ending_at
user_id: .actor.user_id
user_name: .actor.name
email: .actor.email
deleted: (.actor.deleted // false)
product: .product
model: .model
context_window: .context_window
inference_geo: .inference_geo
speed: .speed
uncached_input_tokens: (.uncached_input_tokens // 0)
cache_creation_1h_tokens: (.cache_creation.ephemeral_1h_input_tokens // 0)
cache_creation_5m_tokens: (.cache_creation.ephemeral_5m_input_tokens // 0)
cache_read_input_tokens: (.cache_read_input_tokens // 0)
output_tokens: (.output_tokens // 0)
total_tokens: (.total_tokens // 0)
web_search_requests: (.server_tool_use.web_search_requests // 0)
requests: (.requests // 0)
```
Sample payloadJSON
```
{
"product": null,
"model": null,
"context_window": null,
"inference_geo": null,
"speed": null,
"slack_channel_id": null,
"starting_at": null,
"ending_at": null,
"actor": {
"type": "user_actor",
"user_id": "user_01NeewegJNLKFDPGpYhvhus8",
"name": "Oded Doek",
"email": "dev@domain.io",
"deleted": false
},
"uncached_input_tokens": 889770,
"cache_creation": {
"ephemeral_1h_input_tokens": 10563402,
"ephemeral_5m_input_tokens": 3777036
},
"cache_read_input_tokens": 734635224,
"output_tokens": 2649149,
"total_tokens": 752514581,
"server_tool_use": {
"web_search_requests": 22
},
"requests": 5048,
"__starting_at": "2026-05-15T22:24:54Z",
"__ending_at": "2026-06-15T22:24:54Z"
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_ai_user_cost",
"description": "Per-user USD cost across a date range",
"title": "Claude AI User Cost",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Range Start (UTC)"
},
"range_end": {
"type": "string",
"format": "date-time",
"title": "Range End (UTC)"
},
"user_id": {
"type": "string",
"title": "User ID"
},
"user_name": {
"type": "string",
"title": "User Name"
},
"email": {
"type": "string",
"format": "user",
"title": "Email"
},
"deleted": {
"type": "boolean",
"title": "Deleted User"
},
"product": {
"type": "string",
"title": "Product"
},
"model": {
"type": "string",
"title": "Model"
},
"currency": {
"type": "string",
"title": "Currency"
},
"amount": {
"type": "number",
"title": "Discounted Amount"
},
"list_amount": {
"type": "number",
"title": "List Amount"
},
"requests": {
"type": "number",
"title": "Requests"
}
},
"required": [
"record_date"
]
},
"mirrorProperties": {},
"calculationProperties": {
"discount_amount": {
"title": "Discount Amount",
"description": "List price minus discounted price",
"calculation": ".properties.list_amount - .properties.amount",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-ai-user-cost
selector:
query: 'true'
startingAt: '2026-01-01T00:00:00Z'
port:
entity:
mappings:
identifier: >-
.actor.user_id + "-" + .__starting_at[:10] + "-" + (.product // "all")
+ "-" + (.model // "all")
title: (.actor.name // .actor.email // .actor.user_id) + " - " + .__starting_at[:10]
blueprint: '"claude_ai_user_cost"'
properties:
record_date: .__starting_at
range_end: .__ending_at
user_id: .actor.user_id
user_name: .actor.name
email: .actor.email
deleted: (.actor.deleted // false)
product: .product
model: .model
currency: (.currency // "USD")
amount: ((.amount // "0") | tonumber) / 100
list_amount: ((.list_amount // "0") | tonumber) / 100
requests: (.requests // 0)
```
Sample payloadJSON
```
{
"product": null,
"model": null,
"context_window": null,
"inference_geo": null,
"speed": null,
"slack_channel_id": null,
"starting_at": null,
"ending_at": null,
"actor": {
"type": "user_actor",
"user_id": "user_01Vj49ahTgzCedehnXJBhatu",
"name": "Aaron Taylor",
"email": "dev@domain.io",
"deleted": false
},
"currency": "USD",
"amount": "53865.538742",
"list_amount": "54964.570145",
"cost_type": null,
"token_type": null,
"requests": 6380,
"__starting_at": "2026-05-15T22:25:03Z",
"__ending_at": "2026-06-15T22:25:03Z"
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_ai_skill_usage",
"description": "Org-level Claude skill usage metrics for a single day",
"title": "Claude AI Skill Usage",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Record Date (UTC)"
},
"skill_name": {
"type": "string",
"title": "Skill Name"
},
"skill_display_name": {
"type": "string",
"title": "Skill Display Name"
},
"distinct_user_count": {
"type": "number",
"title": "Distinct Users"
},
"enable_count": {
"type": "number",
"title": "Enable Count"
},
"invocation_count": {
"type": "number",
"title": "Invocation Count"
},
"share_status": {
"type": "string",
"title": "Share Status"
},
"currency": {
"type": "string",
"title": "Currency"
},
"estimated_overage_spend": {
"type": "number",
"title": "Estimated Overage Spend"
},
"attributed_list_price": {
"type": "number",
"title": "Attributed List Price"
},
"chat_conversation_skill_used_count": {
"type": "number",
"title": "Chat Conversation Skill Uses"
},
"code_session_skill_used_count": {
"type": "number",
"title": "Claude Code Session Skill Uses"
},
"cowork_session_skill_used_count": {
"type": "number",
"title": "Cowork Session Skill Uses"
},
"excel_session_skill_used_count": {
"type": "number",
"title": "Excel Session Skill Uses"
},
"powerpoint_session_skill_used_count": {
"type": "number",
"title": "PowerPoint Session Skill Uses"
},
"word_session_skill_used_count": {
"type": "number",
"title": "Word Session Skill Uses"
},
"outlook_session_skill_used_count": {
"type": "number",
"title": "Outlook Session Skill Uses"
}
},
"required": [
"record_date",
"skill_name"
]
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-ai-skill-usage
selector:
query: 'true'
timeFrame: 30
port:
entity:
mappings:
identifier: >-
((.skill_name // "unknown") + "-" + .__date
| gsub("[^A-Za-z0-9@_.+:\\\\/='-]"; "_"))
title: ((.skill_display_name // .skill_name // "unknown") + " - " + .__date)
blueprint: '"claude_ai_skill_usage"'
properties:
record_date: .__date + "T00:00:00Z"
skill_name: (.skill_name // "unknown")
skill_display_name: .skill_display_name
distinct_user_count: .distinct_user_count
enable_count: .enable_count
invocation_count: .invocation_count
share_status: .share_status
currency: (.currency // "USD")
estimated_overage_spend: (if .estimated_overage_spend then (.estimated_overage_spend | tonumber) / 100 else null end)
attributed_list_price: (if .attributed_list_price then (.attributed_list_price | tonumber) / 100 else null end)
chat_conversation_skill_used_count: .chat_metrics.distinct_conversation_skill_used_count
code_session_skill_used_count: .claude_code_metrics.distinct_session_skill_used_count
cowork_session_skill_used_count: .cowork_metrics.distinct_session_skill_used_count
excel_session_skill_used_count: .office_metrics.excel.distinct_session_skill_used_count
powerpoint_session_skill_used_count: .office_metrics.powerpoint.distinct_session_skill_used_count
word_session_skill_used_count: .office_metrics.word.distinct_session_skill_used_count
outlook_session_skill_used_count: .office_metrics.outlook.distinct_session_skill_used_count
```
Sample payloadJSON
```
{
"skill_name": "pptx",
"skill_display_name": null,
"distinct_user_count": 1,
"enable_count": 0,
"invocation_count": 1,
"share_status": "public",
"currency": "USD",
"estimated_overage_spend": "55.2334",
"attributed_list_price": "55.2618",
"chat_metrics": {
"distinct_conversation_skill_used_count": 1
},
"claude_code_metrics": {
"distinct_session_skill_used_count": 0
},
"office_metrics": {
"excel": {
"distinct_session_skill_used_count": 0
},
"powerpoint": {
"distinct_session_skill_used_count": 0
},
"word": {
"distinct_session_skill_used_count": 0
},
"outlook": {
"distinct_session_skill_used_count": 0
}
},
"cowork_metrics": {
"distinct_session_skill_used_count": 0
},
"__date": "2026-07-11"
}
```
claude-platform-usage-recordclaude-platform-cost-recordclaude-platform-usage-record (groupBy: workspace\_id)claude-platform-usage-record (groupBy: model)claude-platform-code-analytics
BlueprintJSON
Create in Port
```
{
"identifier": "claude_platform_usage_record",
"description": "Daily Claude Platform API usage metrics",
"title": "Claude Platform Usage Record",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Record Date (UTC)"
},
"uncached_input_tokens": {
"type": "number",
"title": "Uncached Input Tokens"
},
"output_tokens": {
"type": "number",
"title": "Output Tokens"
},
"cache_read_input_tokens": {
"type": "number",
"title": "Cache Read Input Tokens"
},
"cache_creation_5m_tokens": {
"type": "number",
"title": "Cache Creation (5min) Tokens"
},
"cache_creation_1h_tokens": {
"type": "number",
"title": "Cache Creation (1hr) Tokens"
},
"web_search_requests": {
"type": "number",
"title": "Web Search Requests"
}
},
"required": [
"record_date"
]
},
"mirrorProperties": {},
"calculationProperties": {
"total_input_tokens": {
"title": "Total Input Tokens",
"description": "Sum of uncached input and cache read tokens",
"calculation": ".properties.uncached_input_tokens + .properties.cache_read_input_tokens",
"type": "number"
},
"total_tokens": {
"title": "Total Tokens",
"description": "Sum of all input and output tokens",
"calculation": ".properties.uncached_input_tokens + .properties.cache_read_input_tokens + .properties.output_tokens",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-platform-usage-record
selector:
query: .results | length > 0
startingDate: '2026-01-01T00:00:00Z'
bucketWidth: 1d
groupBy: []
port:
entity:
mappings:
identifier: .starting_at[:10] + "-usage"
title: '"Claude Usage - " + .starting_at[:10]'
blueprint: '"claude_platform_usage_record"'
properties:
record_date: .starting_at
uncached_input_tokens: (.results[0].uncached_input_tokens // 0)
output_tokens: (.results[0].output_tokens // 0)
cache_read_input_tokens: (.results[0].cache_read_input_tokens // 0)
cache_creation_5m_tokens: (.results[0].cache_creation.ephemeral_5m_input_tokens // 0)
cache_creation_1h_tokens: (.results[0].cache_creation.ephemeral_1h_input_tokens // 0)
web_search_requests: (.results[0].server_tool_use.web_search_requests // 0)
```
Sample payloadJSON
```
{
"starting_at": "2026-01-04T00:00:00Z",
"ending_at": "2026-01-05T00:00:00Z",
"results": [
{
"uncached_input_tokens": 10158,
"cache_creation": {
"ephemeral_1h_input_tokens": 0,
"ephemeral_5m_input_tokens": 183637
},
"cache_read_input_tokens": 1207221,
"output_tokens": 16925,
"server_tool_use": {
"web_search_requests": 0
},
"api_key_id": null,
"workspace_id": null,
"account_id": null,
"service_account_id": null,
"model": null,
"service_tier": null,
"context_window": null,
"inference_geo": null
}
]
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_platform_cost_record",
"description": "Daily cost tracking for Claude Platform API usage",
"title": "Claude Platform Cost Record",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Record Date (UTC)"
},
"amount": {
"type": "number",
"title": "Cost Amount"
},
"currency": {
"type": "string",
"title": "Currency"
}
},
"required": [
"record_date"
]
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-platform-cost-record
selector:
query: .results | length > 0
startingDate: '2026-01-01T00:00:00Z'
bucketWidth: 1d
port:
entity:
mappings:
identifier: .starting_at[:10] + "-cost"
title: '"Claude Cost - " + .starting_at[:10]'
blueprint: '"claude_platform_cost_record"'
properties:
record_date: .starting_at
amount: ((.results[0].amount // "0") | tonumber)
currency: (.results[0].currency // "USD")
```
Sample payloadJSON
```
{
"starting_at": "2026-01-01T00:00:00Z",
"ending_at": "2026-01-02T00:00:00Z",
"results": [
{
"currency": "USD",
"amount": "536.07566",
"workspace_id": null,
"description": null,
"cost_type": null,
"context_window": null,
"model": null,
"service_tier": null,
"token_type": null,
"inference_geo": null
}
]
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_platform_workspace_usage",
"description": "Usage metrics broken down by workspace",
"title": "Claude Platform Workspace Usage",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Record Date (UTC)"
},
"workspace_id": {
"type": "string",
"title": "Workspace ID"
},
"uncached_input_tokens": {
"type": "number",
"title": "Uncached Input Tokens"
},
"output_tokens": {
"type": "number",
"title": "Output Tokens"
},
"cache_read_input_tokens": {
"type": "number",
"title": "Cache Read Input Tokens"
},
"cache_creation_5m_tokens": {
"type": "number",
"title": "Cache Creation (5min) Tokens"
},
"cache_creation_1h_tokens": {
"type": "number",
"title": "Cache Creation (1hr) Tokens"
},
"web_search_requests": {
"type": "number",
"title": "Web Search Requests"
}
},
"required": [
"record_date",
"workspace_id"
]
},
"mirrorProperties": {},
"calculationProperties": {
"total_tokens": {
"title": "Total Tokens",
"calculation": ".properties.uncached_input_tokens + .properties.cache_read_input_tokens + .properties.output_tokens",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-platform-usage-record
selector:
query: .results | length > 0
startingDate: '2026-01-01T00:00:00Z'
bucketWidth: 1d
groupBy:
- workspace_id
port:
itemsToParse: .results
itemsToParseTopLevelTransform: false
entity:
mappings:
identifier: (.item.workspace_id // "default") + "-" + .starting_at[:10]
title: (.item.workspace_id // "default") + " - " + .starting_at[:10]
blueprint: '"claude_platform_workspace_usage"'
properties:
record_date: .starting_at
workspace_id: (.item.workspace_id // "default")
uncached_input_tokens: (.item.uncached_input_tokens // 0)
output_tokens: (.item.output_tokens // 0)
cache_read_input_tokens: (.item.cache_read_input_tokens // 0)
cache_creation_5m_tokens: (.item.cache_creation.ephemeral_5m_input_tokens // 0)
cache_creation_1h_tokens: (.item.cache_creation.ephemeral_1h_input_tokens // 0)
web_search_requests: (.item.server_tool_use.web_search_requests // 0)
```
Sample payloadJSON
```
{
"starting_at": "2026-01-01T00:00:00Z",
"ending_at": "2026-01-02T00:00:00Z",
"results": [
{
"uncached_input_tokens": 163662,
"cache_creation": {
"ephemeral_1h_input_tokens": 0,
"ephemeral_5m_input_tokens": 229562
},
"cache_read_input_tokens": 7287271,
"output_tokens": 40898,
"server_tool_use": {
"web_search_requests": 0
},
"api_key_id": null,
"workspace_id": "wrkspc_01R8i1bkxHiD5qiiY4SrhsRC",
"account_id": null,
"service_account_id": null,
"model": null,
"service_tier": null,
"context_window": null,
"inference_geo": null
}
]
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_platform_model_usage",
"description": "Usage metrics broken down by Claude model type",
"title": "Claude Platform Model Usage",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Record Date (UTC)"
},
"model": {
"type": "string",
"title": "Model"
},
"uncached_input_tokens": {
"type": "number",
"title": "Uncached Input Tokens"
},
"output_tokens": {
"type": "number",
"title": "Output Tokens"
},
"cache_read_input_tokens": {
"type": "number",
"title": "Cache Read Input Tokens"
},
"cache_creation_5m_tokens": {
"type": "number",
"title": "Cache Creation (5min) Tokens"
},
"cache_creation_1h_tokens": {
"type": "number",
"title": "Cache Creation (1hr) Tokens"
},
"web_search_requests": {
"type": "number",
"title": "Web Search Requests"
}
},
"required": [
"record_date",
"model"
]
},
"mirrorProperties": {},
"calculationProperties": {
"total_tokens": {
"title": "Total Tokens",
"calculation": ".properties.uncached_input_tokens + .properties.cache_read_input_tokens + .properties.output_tokens",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-platform-usage-record
selector:
query: .results | length > 0
startingDate: '2026-01-01T00:00:00Z'
bucketWidth: 1d
groupBy:
- model
port:
itemsToParse: .results
itemsToParseTopLevelTransform: false
entity:
mappings:
identifier: .item.model + "-" + .starting_at[:10]
title: .item.model + " - " + .starting_at[:10]
blueprint: '"claude_platform_model_usage"'
properties:
record_date: .starting_at
model: .item.model
uncached_input_tokens: (.item.uncached_input_tokens // 0)
output_tokens: (.item.output_tokens // 0)
cache_read_input_tokens: (.item.cache_read_input_tokens // 0)
cache_creation_5m_tokens: (.item.cache_creation.ephemeral_5m_input_tokens // 0)
cache_creation_1h_tokens: (.item.cache_creation.ephemeral_1h_input_tokens // 0)
web_search_requests: (.item.server_tool_use.web_search_requests // 0)
```
Sample payloadJSON
```
{
"starting_at": "2026-01-04T00:00:00Z",
"ending_at": "2026-01-05T00:00:00Z",
"results": [
{
"uncached_input_tokens": 7678,
"cache_creation": {
"ephemeral_1h_input_tokens": 0,
"ephemeral_5m_input_tokens": 35867
},
"cache_read_input_tokens": 74329,
"output_tokens": 2435,
"server_tool_use": {
"web_search_requests": 0
},
"api_key_id": null,
"workspace_id": null,
"account_id": null,
"service_account_id": null,
"model": "claude-haiku-4-5-20251001",
"service_tier": null,
"context_window": null,
"inference_geo": null
},
{
"uncached_input_tokens": 1629,
"cache_creation": {
"ephemeral_1h_input_tokens": 0,
"ephemeral_5m_input_tokens": 133486
},
"cache_read_input_tokens": 1132892,
"output_tokens": 14321,
"server_tool_use": {
"web_search_requests": 0
},
"api_key_id": null,
"workspace_id": null,
"account_id": null,
"service_account_id": null,
"model": "claude-opus-4-5-20251101",
"service_tier": null,
"context_window": null,
"inference_geo": null
},
{
"uncached_input_tokens": 851,
"cache_creation": {
"ephemeral_1h_input_tokens": 0,
"ephemeral_5m_input_tokens": 14284
},
"cache_read_input_tokens": 0,
"output_tokens": 169,
"server_tool_use": {
"web_search_requests": 0
},
"api_key_id": null,
"workspace_id": null,
"account_id": null,
"service_account_id": null,
"model": "claude-sonnet-4-5-20250929",
"service_tier": null,
"context_window": null,
"inference_geo": null
}
]
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "claude_platform_code_analytics",
"description": "Daily Claude Code usage metrics including sessions, lines of code, commits, and PRs",
"title": "Claude Platform Code Analytics",
"icon": "Claude",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Record Date (UTC)"
},
"organization_id": {
"type": "string",
"title": "Organization ID"
},
"actor_type": {
"type": "string",
"title": "Actor Type"
},
"actor_name": {
"type": "string",
"title": "Actor Name"
},
"terminal_type": {
"type": "string",
"title": "Terminal Type"
},
"num_sessions": {
"type": "number",
"title": "Sessions"
},
"lines_added": {
"type": "number",
"title": "Lines Added"
},
"lines_removed": {
"type": "number",
"title": "Lines Removed"
},
"commits": {
"type": "number",
"title": "Commits by Claude Code"
},
"pull_requests": {
"type": "number",
"title": "Pull Requests by Claude Code"
},
"edit_tool_accepted": {
"type": "number",
"title": "Edit Tool Accepted"
},
"edit_tool_rejected": {
"type": "number",
"title": "Edit Tool Rejected"
},
"write_tool_accepted": {
"type": "number",
"title": "Write Tool Accepted"
},
"write_tool_rejected": {
"type": "number",
"title": "Write Tool Rejected"
},
"models_used": {
"type": "array",
"items": {
"type": "string"
},
"title": "Models Used"
},
"model_input_tokens": {
"type": "number",
"title": "Model Input Tokens"
},
"model_output_tokens": {
"type": "number",
"title": "Model Output Tokens"
},
"model_cache_read_tokens": {
"type": "number",
"title": "Model Cache Read Tokens"
},
"model_cache_creation_tokens": {
"type": "number",
"title": "Model Cache Creation Tokens"
},
"estimated_cost": {
"type": "number",
"title": "Estimated Cost (USD)"
},
"currency": {
"type": "string",
"title": "Currency"
}
},
"required": [
"record_date",
"organization_id"
]
},
"mirrorProperties": {},
"calculationProperties": {
"total_lines_changed": {
"title": "Total Lines Changed",
"calculation": ".properties.lines_added + .properties.lines_removed",
"type": "number"
},
"edit_acceptance_rate": {
"title": "Edit Acceptance Rate",
"calculation": "if (.properties.edit_tool_accepted + .properties.edit_tool_rejected) > 0 then (.properties.edit_tool_accepted / (.properties.edit_tool_accepted + .properties.edit_tool_rejected)) * 100 else 0 end",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: claude-platform-code-analytics
selector:
query: 'true'
startingDate: '2026-01-01'
port:
entity:
mappings:
identifier: .organization_id + "-" + (.actor.api_key_name // .actor.email // "unknown") + "-" + .date[:10]
title: (.actor.api_key_name // .actor.email // "unknown") + " - " + .date[:10]
blueprint: '"claude_platform_code_analytics"'
properties:
record_date: .date
organization_id: .organization_id
actor_type: .actor.type
actor_name: (.actor.api_key_name // .actor.email // "unknown")
terminal_type: .terminal_type
num_sessions: (.core_metrics.num_sessions // 0)
lines_added: (.core_metrics.lines_of_code.added // 0)
lines_removed: (.core_metrics.lines_of_code.removed // 0)
commits: (.core_metrics.commits_by_claude_code // 0)
pull_requests: (.core_metrics.pull_requests_by_claude_code // 0)
edit_tool_accepted: (.tool_actions.edit_tool.accepted // 0)
edit_tool_rejected: (.tool_actions.edit_tool.rejected // 0)
write_tool_accepted: (.tool_actions.write_tool.accepted // 0)
write_tool_rejected: (.tool_actions.write_tool.rejected // 0)
models_used: ([(.model_breakdown // [])[].model] | unique)
model_input_tokens: ([(.model_breakdown // [])[].tokens.input] | map(. // 0) | add)
model_output_tokens: ([(.model_breakdown // [])[].tokens.output] | map(. // 0) | add)
model_cache_read_tokens: ([(.model_breakdown // [])[].tokens.cache_read] | map(. // 0) | add)
model_cache_creation_tokens: ([(.model_breakdown // [])[].tokens.cache_creation] | map(. // 0) | add)
estimated_cost: ([(.model_breakdown // [])[].estimated_cost.amount] | map(. // 0) | add)
currency: ((.model_breakdown // [])[0].estimated_cost.currency // "USD")
```
Sample payloadJSON
```
{
"date": "2026-01-01T00:00:00Z",
"actor": {
"type": "api_actor",
"api_key_name": "matan-tdd-agent"
},
"organization_id": "6d236493-6408-4d45-bc06-c65f19c17ba9",
"terminal_type": "iTerm.app",
"customer_type": "api",
"subscription_type": null,
"core_metrics": {
"num_sessions": 1,
"lines_of_code": {
"added": 508,
"removed": 61
},
"commits_by_claude_code": 0,
"pull_requests_by_claude_code": 0
},
"tool_actions": {
"edit_tool": {
"accepted": 10,
"rejected": 0
},
"multi_edit_tool": {
"accepted": 0,
"rejected": 0
},
"write_tool": {
"accepted": 3,
"rejected": 0
},
"notebook_edit_tool": {
"accepted": 0,
"rejected": 0
}
},
"model_breakdown": [
{
"model": "claude-opus-4-5-20251101",
"tokens": {
"input": 1231,
"output": 2207,
"cache_read": 0,
"cache_creation": 0
},
"estimated_cost": {
"currency": "USD",
"amount": 6
}
},
{
"model": "claude-opus-4-5",
"tokens": {
"input": 12,
"output": 26406,
"cache_read": 6494720,
"cache_creation": 160361
},
"estimated_cost": {
"currency": "USD",
"amount": 491
}
},
{
"model": "claude-haiku-4-5-20251001",
"tokens": {
"input": 162419,
"output": 12285,
"cache_read": 792551,
"cache_creation": 69201
},
"estimated_cost": {
"currency": "USD",
"amount": 39
}
}
]
}
```
## Breaking down analytics on user and team level[](#breaking-down-analytics-on-user-and-team-level "Direct link to Breaking down analytics on user and team level")
The default `claude-ai-skill-usage` mapping stores org-level totals (one row per skill per day). You can break the same metrics out by user, team, or product by setting `groupBy` to one of `user_id`, `rbac_group_id`, or `product`. Use one dimension at a time.
To ingest user- or team-level rows, add two properties to the existing `claude_ai_skill_usage` blueprint, then update the kind mapping. Grouped identifiers include the user or team, so they do not overwrite org-level records.
### Add blueprint properties[](#add-blueprint-properties "Direct link to Add blueprint properties")
1. Go to your [data model](https://app.port.io/settings/data-model) page.
2. Find and expand the **Claude AI Skill Usage** (`claude_ai_skill_usage`) blueprint.
3. Click the `...` button, then **Edit Blueprint**.
4. Add the following properties to the blueprint `schema.properties` object, then click **Save**.
```
"user_id": {
"type": "string",
"title": "User ID"
},
"rbac_group_id": {
"type": "string",
"title": "RBAC Group ID"
},
"rbac_group_name": {
"type": "string",
"title": "RBAC Group Name"
}
```
### Update the mapping[](#update-the-mapping "Direct link to Update the mapping")
1. Go to your [connectors](https://app.port.io/settings/data-sources) page.
2. Select your Claude AI integration, then open the **Mapping** tab.
3. Update the `claude-ai-skill-usage` kind: set `groupBy` to one of the three dimensions. Then click **Save & Resync**.
* User
* Team
Set `groupBy` to `user_id` and map the `user_id` property:
```
- kind: claude-ai-skill-usage
selector:
query: 'true'
timeFrame: 30
groupBy:
- user_id
port:
entity:
mappings:
identifier: >-
((.skill_name // "unknown") + "-" + .__date + (if .user_id then "-" + .user_id else "" end) | gsub("[^A-Za-z0-9@_.+:\\\\/='-]"; "_"))
title: >-
((.skill_display_name // .skill_name // "unknown") + " - " + .__date + (if .user_id then " - " + .user_id else "" end))
blueprint: '"claude_ai_skill_usage"'
properties:
record_date: .__date + "T00:00:00Z"
skill_name: (.skill_name // "unknown")
skill_display_name: .skill_display_name
user_id: .user_id
distinct_user_count: .distinct_user_count
enable_count: .enable_count
invocation_count: .invocation_count
share_status: .share_status
currency: (.currency // "USD")
estimated_overage_spend: (if .estimated_overage_spend then (.estimated_overage_spend | tonumber) / 100 else null end)
attributed_list_price: (if .attributed_list_price then (.attributed_list_price | tonumber) / 100 else null end)
chat_conversation_skill_used_count: .chat_metrics.distinct_conversation_skill_used_count
code_session_skill_used_count: .claude_code_metrics.distinct_session_skill_used_count
cowork_session_skill_used_count: .cowork_metrics.distinct_session_skill_used_count
excel_session_skill_used_count: .office_metrics.excel.distinct_session_skill_used_count
powerpoint_session_skill_used_count: .office_metrics.powerpoint.distinct_session_skill_used_count
word_session_skill_used_count: .office_metrics.word.distinct_session_skill_used_count
outlook_session_skill_used_count: .office_metrics.outlook.distinct_session_skill_used_count
```
Set `groupBy` to `rbac_group_id` and map the `rbac_group_id` and `rbac_group_name` properties:
```
- kind: claude-ai-skill-usage
selector:
query: 'true'
timeFrame: 30
groupBy:
- rbac_group_id
port:
entity:
mappings:
identifier: >-
((.skill_name // "unknown") + "-" + .__date + (if .rbac_group_id then "-" + .rbac_group_id else "" end) | gsub("[^A-Za-z0-9@_.+:\\\\/='-]"; "_"))
title: >-
((.skill_display_name // .skill_name // "unknown") + " - " + .__date + (if .rbac_group_name then " - " + .rbac_group_name elif .rbac_group_id then " - " + .rbac_group_id else "" end))
blueprint: '"claude_ai_skill_usage"'
properties:
record_date: .__date + "T00:00:00Z"
skill_name: (.skill_name // "unknown")
skill_display_name: .skill_display_name
rbac_group_id: .rbac_group_id
rbac_group_name: .rbac_group_name
distinct_user_count: .distinct_user_count
enable_count: .enable_count
invocation_count: .invocation_count
share_status: .share_status
currency: (.currency // "USD")
estimated_overage_spend: (if .estimated_overage_spend then (.estimated_overage_spend | tonumber) / 100 else null end)
attributed_list_price: (if .attributed_list_price then (.attributed_list_price | tonumber) / 100 else null end)
chat_conversation_skill_used_count: .chat_metrics.distinct_conversation_skill_used_count
code_session_skill_used_count: .claude_code_metrics.distinct_session_skill_used_count
cowork_session_skill_used_count: .cowork_metrics.distinct_session_skill_used_count
excel_session_skill_used_count: .office_metrics.excel.distinct_session_skill_used_count
powerpoint_session_skill_used_count: .office_metrics.powerpoint.distinct_session_skill_used_count
word_session_skill_used_count: .office_metrics.word.distinct_session_skill_used_count
outlook_session_skill_used_count: .office_metrics.outlook.distinct_session_skill_used_count
```
RBAC group overlap
When grouping by `rbac_group_id`, a user is attributed to every group they held during that UTC day. Grouped rows are not an exclusive partition and can sum above org-level totals.
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Migration guide[](#migration-guide "Direct link to Migration guide")
If you currently ingest Claude metrics through a custom Ocean integration, migrate to the dedicated Claude AI integration:
1. Create the new **Claude AI** connector from your [connectors page](https://app.port.io/settings/data-sources).
2. Copy your existing Claude API credentials into the new integration setup.
3. Move your custom blueprint and mapping configuration into the dedicated integration.
4. Run a sync and validate that records are ingested for all enabled resources.
5. Disable the legacy custom Ocean Claude integration after validation.
## Related pages[](#related-pages "Direct link to Related pages")
* [Skills usage analytics](/agent-management/ai-registry/skills/skills-usage-analytics/.md): high-level guide to analyzing skill adoption across Cursor and Claude.
* [Visualize Claude metrics](/guides/all/visualize-claude-metrics/.md): dashboards for Claude usage and cost.
---
# Cursor metrics

Loading version...
Port's Cursor integration allows you to ingest daily usage, usage events, model usage, and skill adoption analytics into your software catalog.
Supported resources [cursor-daily-usage](https://cursor.com/docs/account/teams/admin-api#get-daily-usage-data)[cursor-usage-event](https://cursor.com/docs/account/teams/admin-api#get-usage-events-data)[cursor-team-model-usage](https://cursor.com/docs/account/teams/analytics-api#model-usage)[cursor-user-model-usage](https://cursor.com/docs/account/teams/analytics-api#model-usage-by-user)[cursor-team-skill-usage](https://cursor.com/docs/account/teams/analytics-api#skills-adoption)
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
* A [Cursor API key](https://cursor.com/docs/api#creating-api-keys) with permissions to read organization or team usage metrics.
* A Cursor Teams or Cursor Enterprise plan. Please refer to the [Cursor API availability docs](https://cursor.com/docs/api#available-apis) to see what is available with Teams and Enterprise licenses.
* Your Port user role is set to `Admin`.
## Setup[](#setup "Direct link to Setup")
Choose one of the installation methods below. If you are not sure which option to use, review the [installation methods overview](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Customizable resync interval for data ingestion
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/overview/.md) to ingest data from third-party APIs into Port.
The mapping uses the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to transform fields and shape incoming Cursor data into Port entities.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
resources:
- kind: cursor-daily-usage
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
entity:
mappings:
identifier: (.userId + "-" + .day)
title: (.email + " " + .day)
blueprint: '"cursorDailyUsage"'
properties:
day: (if .day then (.day + "T00:00:00Z") else null end)
user_id: .userId
email: .email
is_active: .isActive
total_lines_added: .totalLinesAdded
total_lines_deleted: .totalLinesDeleted
accepted_lines_added: .acceptedLinesAdded
accepted_lines_deleted: .acceptedLinesDeleted
total_applies: .totalApplies
total_accepts: .totalAccepts
total_rejects: .totalRejects
total_tabs_shown: .totalTabsShown
total_tabs_accepted: .totalTabsAccepted
composer_requests: .composerRequests
chat_requests: .chatRequests
agent_requests: .agentRequests
most_used_model: .mostUsedModel
subscription_included_reqs: .subscriptionIncludedReqs
api_key_reqs: .apiKeyReqs
usage_based_reqs: .usageBasedReqs
bugbot_usages: .bugbotUsages
- kind: cursor-usage-event
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
entity:
mappings:
identifier: ((.timestamp + "-" + .userEmail + "-" + .model + "-" + .kind) | gsub("[^A-Za-z0-9@_.+:\\\\/='-]"; "_"))
title: (.userEmail + " " + .model + " " + .kind)
blueprint: '"cursorUsageEvent"'
properties:
timestamp: (.timestamp | tonumber / 1000 | todate)
model: .model
kind: .kind
max_mode: .maxMode
requests_costs: .requestsCosts
is_token_based_call: .isTokenBasedCall
token_usage: .tokenUsage
user_email: .userEmail
cursor_token_fee: .cursorTokenFee
is_headless: .isHeadless
charged_amount: (if .chargedCents then (.chargedCents / 100) else null end)
- kind: cursor-team-model-usage
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
itemsToParse: (.model_breakdown // {} | to_entries)
entity:
mappings:
identifier: (.date + "-" + .item.key)
title: (.date + " " + .item.key)
blueprint: '"cursorTeamModelUsage"'
properties:
date: (if .date then (.date + "T00:00:00Z") else null end)
model: .item.key
messages: .item.value.messages
users: .item.value.users
- kind: cursor-user-model-usage
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
itemsToParse: (.model_breakdown // {} | to_entries)
entity:
mappings:
identifier: (.userEmail + "-" + .date + "-" + .item.key)
title: (.userEmail + " " + .item.key)
blueprint: '"cursorUserModelUsage"'
properties:
date: (if .date then (.date + "T00:00:00Z") else null end)
user_email: .userEmail
model: .item.key
messages: .item.value.messages
- kind: cursor-team-skill-usage
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
entity:
mappings:
identifier: >-
((.event_date + "-" + (.skill_name // "unknown"))
| gsub("[^A-Za-z0-9@_.+:\\\\/='-]"; "_"))
title: ((.skill_name // "unknown") + " - " + .event_date)
blueprint: '"cursorTeamSkillUsage"'
properties:
event_date: (if .event_date then (.event_date + "T00:00:00Z") else null end)
skill_name: .skill_name
usage: .usage
```
### Advanced selector configuration[](#advanced-selector-configuration "Direct link to Advanced selector configuration")
* `query` applies to all Cursor resource kinds and defaults to `'true'`.
* `startDate` is a relative start date in days, for example `7d`. The default is `30d`. This cannot exceed 30 days.
* `endDate` is a relative end date in days, for example `0d` for now. The default is `0d`.
* `users` is an optional comma-separated list of user emails or user IDs. It is supported on `cursor-team-skill-usage` and filters skill adoption metrics to the specified users.
Below is an example usage:
```
- kind: cursor-daily-usage
selector:
query: 'true'
startDate: 7d
endDate: 0d
```
Filter skill usage to specific users:
```
- kind: cursor-team-skill-usage
selector:
query: 'true'
startDate: 14d
endDate: 0d
users: alice@example.com,user_abc123
```
## Mapping and examples per resource[](#mapping-and-examples-per-resource "Direct link to Mapping and examples per resource")
To view and test the integration mapping against sample API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources).
Cursor Enterprise required for analytics kinds
The `cursor-team-model-usage`, `cursor-user-model-usage`, and `cursor-team-skill-usage` kinds rely on the Cursor Analytics API, which is available only on the Cursor Enterprise tier. Add these kinds to your mapping only if your Cursor license includes Enterprise analytics access.
cursor-daily-usagecursor-usage-eventcursor-team-model-usagecursor-user-model-usagecursor-team-skill-usage
BlueprintJSON
Create in Port
```
{
"identifier": "cursorDailyUsage",
"description": "Daily team usage metrics from Cursor Admin API",
"title": "Cursor Daily Usage",
"icon": "Cursor",
"schema": {
"properties": {
"day": {
"type": "string",
"format": "date-time",
"title": "Day"
},
"user_id": {
"type": "string",
"title": "User ID"
},
"email": {
"type": "string",
"title": "User Email",
"format": "email"
},
"is_active": {
"type": "boolean",
"title": "Active"
},
"total_lines_added": {
"type": "number",
"title": "Total Lines Added"
},
"total_lines_deleted": {
"type": "number",
"title": "Total Lines Deleted"
},
"accepted_lines_added": {
"type": "number",
"title": "Accepted Lines Added"
},
"accepted_lines_deleted": {
"type": "number",
"title": "Accepted Lines Deleted"
},
"total_applies": {
"type": "number",
"title": "Total Applies"
},
"total_accepts": {
"type": "number",
"title": "Total Accepts"
},
"total_rejects": {
"type": "number",
"title": "Total Rejects"
},
"composer_requests": {
"type": "number",
"title": "Composer Requests"
},
"chat_requests": {
"type": "number",
"title": "Chat Requests"
},
"agent_requests": {
"type": "number",
"title": "Agent Requests"
},
"most_used_model": {
"type": "string",
"title": "Most Used Model"
},
"total_tabs_shown": {
"type": "number",
"title": "Total Tabs Shown"
},
"total_tabs_accepted": {
"type": "number",
"title": "Total Tabs Accepted"
},
"subscription_included_reqs": {
"type": "number",
"title": "Subscription Included Requests"
},
"api_key_reqs": {
"type": "number",
"title": "API Key Requests"
},
"usage_based_reqs": {
"type": "number",
"title": "Usage-based Requests"
},
"bugbot_usages": {
"type": "number",
"title": "Bugbot Usages"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {
"acceptance_rate": {
"title": "Acceptance Rate",
"description": "Accepted AI suggestions as a percentage of accepted + rejected suggestions",
"calculation": "if (.properties.total_accepts + .properties.total_rejects) > 0 then (.properties.total_accepts / (.properties.total_accepts + .properties.total_rejects)) * 100 else 0 end",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: cursor-daily-usage
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
entity:
mappings:
identifier: (.userId + "-" + .day)
title: (.email + " " + .day)
blueprint: '"cursorDailyUsage"'
properties:
day: (if .day then (.day + "T00:00:00Z") else null end)
user_id: .userId
email: .email
is_active: .isActive
total_lines_added: .totalLinesAdded
total_lines_deleted: .totalLinesDeleted
accepted_lines_added: .acceptedLinesAdded
accepted_lines_deleted: .acceptedLinesDeleted
total_applies: .totalApplies
total_accepts: .totalAccepts
total_rejects: .totalRejects
total_tabs_shown: .totalTabsShown
total_tabs_accepted: .totalTabsAccepted
composer_requests: .composerRequests
chat_requests: .chatRequests
agent_requests: .agentRequests
most_used_model: .mostUsedModel
subscription_included_reqs: .subscriptionIncludedReqs
api_key_reqs: .apiKeyReqs
usage_based_reqs: .usageBasedReqs
bugbot_usages: .bugbotUsages
```
Sample payloadJSON
```
{
"date": 1778371200000,
"day": "2026-05-10",
"userId": "user_LGgY21zt4XsBFMZYi2VpfNdAUv",
"email": "dev@getport.io",
"isActive": true,
"totalLinesAdded": 27,
"totalLinesDeleted": 28,
"acceptedLinesAdded": 27,
"acceptedLinesDeleted": 28,
"totalApplies": 2,
"totalAccepts": 2,
"totalRejects": 0,
"totalTabsShown": 1,
"totalTabsAccepted": 0,
"composerRequests": 0,
"chatRequests": 0,
"agentRequests": 11,
"cmdkUsages": 0,
"subscriptionIncludedReqs": 11,
"apiKeyReqs": 0,
"usageBasedReqs": 0,
"bugbotUsages": 0,
"mostUsedModel": "claude-4.6-sonnet-medium-thinking",
"applyMostUsedExtension": "py",
"tabMostUsedExtension": "py",
"clientVersion": "3.1.17"
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "cursorUsageEvent",
"description": "Detailed Cursor usage events with model and cost metadata",
"title": "Cursor Usage Event",
"icon": "Cursor",
"schema": {
"properties": {
"timestamp": {
"type": "string",
"title": "Timestamp",
"format": "date-time"
},
"model": {
"type": "string",
"title": "Model"
},
"kind": {
"type": "string",
"title": "Kind"
},
"max_mode": {
"type": "boolean",
"title": "Max Mode"
},
"requests_costs": {
"type": "number",
"title": "Request Cost"
},
"is_token_based_call": {
"type": "boolean",
"title": "Token Based Call"
},
"token_usage": {
"type": "object",
"title": "Token Usage"
},
"user_email": {
"type": "string",
"title": "User Email",
"format": "email"
},
"cursor_token_fee": {
"type": "number",
"title": "Cursor Token Fee"
},
"is_headless": {
"type": "boolean",
"title": "Headless"
},
"charged_amount": {
"type": "number",
"title": "Charged Amount (USD)"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: cursor-usage-event
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
entity:
mappings:
identifier: ((.timestamp + "-" + .userEmail + "-" + .model + "-" + .kind) | gsub("[^A-Za-z0-9@_.+:\\\\/='-]"; "_"))
title: (.userEmail + " " + .model + " " + .kind)
blueprint: '"cursorUsageEvent"'
properties:
timestamp: (.timestamp | tonumber / 1000 | todate)
model: .model
kind: .kind
max_mode: .maxMode
requests_costs: .requestsCosts
is_token_based_call: .isTokenBasedCall
token_usage: .tokenUsage
user_email: .userEmail
cursor_token_fee: .cursorTokenFee
is_headless: .isHeadless
charged_amount: (if .chargedCents then (.chargedCents / 100) else null end)
```
Sample payloadJSON
```
{
"timestamp": "1781029736938",
"model": "claude-4.6-opus-high-thinking",
"kind": "Included in Business",
"maxMode": false,
"requestsCosts": 1.9,
"isTokenBasedCall": true,
"tokenUsage": {
"inputTokens": 3961,
"outputTokens": 1415,
"cacheWriteTokens": 1245,
"cacheReadTokens": 125256,
"totalCents": 7.708795
},
"userEmail": "dev@getport.io",
"cursorTokenFee": 4.351941,
"isChargeable": true,
"serviceAccountId": "null",
"isHeadless": false,
"chargedCents": 12.060736
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "cursorTeamModelUsage",
"description": "Daily team-level model usage from the Cursor Analytics API",
"title": "Cursor Team Model Usage",
"icon": "Cursor",
"schema": {
"properties": {
"date": {
"type": "string",
"format": "date-time",
"title": "Date"
},
"model": {
"type": "string",
"title": "Model"
},
"messages": {
"type": "number",
"title": "Messages"
},
"users": {
"type": "number",
"title": "Users"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: cursor-team-model-usage
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
itemsToParse: (.model_breakdown // {} | to_entries)
entity:
mappings:
identifier: (.date + "-" + .item.key)
title: (.date + " " + .item.key)
blueprint: '"cursorTeamModelUsage"'
properties:
date: (if .date then (.date + "T00:00:00Z") else null end)
model: .item.key
messages: .item.value.messages
users: .item.value.users
```
Sample payloadJSON
```
{
"date": "2026-05-10",
"model_breakdown": {
"claude-opus-4-7-thinking-high": {
"messages": 18,
"users": 1
},
"claude-opus-4-7-thinking-xhigh": {
"messages": 17,
"users": 3
},
"gpt-5.5-high": {
"messages": 23,
"users": 1
},
"composer-2-fast": {
"messages": 90,
"users": 15
},
"default": {
"messages": 265,
"users": 15
},
"claude-opus-4-7-thinking-medium": {
"messages": 2,
"users": 1
},
"claude-4.6-sonnet-medium": {
"messages": 89,
"users": 3
},
"claude-4.6-opus-high": {
"messages": 2,
"users": 2
},
"gpt-5.3-codex": {
"messages": 40,
"users": 2
},
"claude-4.6-opus-high-thinking": {
"messages": 39,
"users": 4
},
"claude-4.5-opus-high": {
"messages": 3,
"users": 1
},
"claude-4.5-sonnet": {
"messages": 45,
"users": 2
},
"github_bugbot": {
"messages": 0,
"users": 1
},
"composer-2": {
"messages": 47,
"users": 4
},
"claude-4.6-sonnet-medium-thinking": {
"messages": 192,
"users": 18
},
"claude-4.5-opus-high-thinking": {
"messages": 43,
"users": 6
},
"claude-4.5-sonnet-thinking": {
"messages": 6,
"users": 1
},
"gpt-5.5-medium": {
"messages": 3,
"users": 1
}
}
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "cursorUserModelUsage",
"description": "Daily per-user model usage from the Cursor Analytics API",
"title": "Cursor User Model Usage",
"icon": "Cursor",
"schema": {
"properties": {
"date": {
"type": "string",
"format": "date-time",
"title": "Date"
},
"user_email": {
"type": "string",
"format": "email",
"title": "User Email"
},
"model": {
"type": "string",
"title": "Model"
},
"messages": {
"type": "number",
"title": "Messages"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: cursor-user-model-usage
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
itemsToParse: (.model_breakdown // {} | to_entries)
entity:
mappings:
identifier: (.userEmail + "-" + .date + "-" + .item.key)
title: (.userEmail + " " + .item.key)
blueprint: '"cursorUserModelUsage"'
properties:
date: (if .date then (.date + "T00:00:00Z") else null end)
user_email: .userEmail
model: .item.key
messages: .item.value.messages
```
Sample payloadJSON
```
{
"userEmail": "dev@getport.io",
"date": "2026-06-01",
"model_breakdown": {
"default": {
"messages": 15
},
"composer-2.5": {
"messages": 3
}
}
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "cursorTeamSkillUsage",
"description": "Daily team-level skill adoption metrics from the Cursor Analytics API",
"title": "Cursor Team Skill Usage",
"icon": "Cursor",
"schema": {
"properties": {
"event_date": {
"type": "string",
"format": "date-time",
"title": "Event Date"
},
"skill_name": {
"type": "string",
"title": "Skill Name"
},
"usage": {
"type": "number",
"title": "Usage Count"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: cursor-team-skill-usage
selector:
query: 'true'
startDate: 30d
endDate: 0d
port:
entity:
mappings:
identifier: >-
((.event_date + "-" + (.skill_name // "unknown"))
| gsub("[^A-Za-z0-9@_.+:\\\\/='-]"; "_"))
title: ((.skill_name // "unknown") + " - " + .event_date)
blueprint: '"cursorTeamSkillUsage"'
properties:
event_date: (if .event_date then (.event_date + "T00:00:00Z") else null end)
skill_name: .skill_name
usage: .usage
```
Sample payloadJSON
```
{
"event_date": "2026-08-08",
"skill_name": "nr-investigate",
"usage": 9
}
```
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Migration guide[](#migration-guide "Direct link to Migration guide")
If you currently ingest Cursor metrics through a custom Ocean integration, migrate to the dedicated Cursor integration:
1. Create the new **Cursor** connector from your [connectors page](https://app.port.io/settings/data-sources).
2. Copy your existing Cursor API credentials into the new integration setup.
3. Replace legacy custom kinds with the native kinds: `cursor-daily-usage`, `cursor-usage-event`, `cursor-team-model-usage`, `cursor-user-model-usage`, and `cursor-team-skill-usage`.
4. Run a sync and validate that records are ingested for all enabled resources.
5. Disable the legacy custom Ocean Cursor integration after validation.
## Related pages[](#related-pages "Direct link to Related pages")
* [Skills usage analytics](/agent-management/ai-registry/skills/skills-usage-analytics/.md): high-level guide to analyzing skill adoption across Cursor and Claude.
* [Visualize Cursor metrics](/guides/all/visualize-cursor-metrics/.md): dashboards for Cursor adoption and impact.
---
# GitHub Copilot metrics

Loading version...
Port's GitHub Copilot integration allows you to ingest organization-level and enterprise-level GitHub Copilot usage metrics into your software catalog.
Supported resources [organization-usage-metrics](https://docs.github.com/en/rest/copilot/copilot-usage-metrics)[user-usage-metrics](https://docs.github.com/en/enterprise-cloud@latest/rest/copilot/copilot-usage-metrics?apiVersion=2026-03-10#get-copilot-users-usage-metrics)[organization-user-usage-metrics](https://docs.github.com/en/enterprise-cloud@latest/rest/copilot/copilot-usage-metrics?apiVersion=2026-03-10#get-copilot-users-usage-metrics)[enterprise-usage-metrics](https://docs.github.com/en/enterprise-cloud@latest/rest/copilot/copilot-usage-metrics?apiVersion=2026-03-10#get-copilot-enterprise-usage-metrics)[enterprise-user-usage-metrics](https://docs.github.com/en/enterprise-cloud@latest/rest/copilot/copilot-usage-metrics?apiVersion=2026-03-10#get-copilot-users-usage-metrics)
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
### GitHub token[](#github-token "Direct link to GitHub token")
Port's GitHub Copilot integration requires a classic GitHub token **generated by organization owners or parent enterprise owners and billing managers** with at least one of the following scopes enabled:
* `manage_billing:copilot`
* `read:org`
* `read:enterprise`
In addition, the Copilot Metrics API access policy must be enabled for the organization within GitHub settings.
## Setup[](#setup "Direct link to Setup")
Choose one of the following installation methods: Not sure which method is right for your use case? Check the available [installation methods](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Customizable resync interval for data ingestion
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
entityDeletionThreshold: 0
resources:
- kind: organization-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.__organization.login + "@" + .day)
title: (.__organization.login + " copilot-metrics " + .day)
blueprint: '"githubCopilotOrganizationUsage"'
properties:
record_date: .day + "T00:00:00Z"
daily_active_users: .daily_active_users
weekly_active_users: .weekly_active_users
monthly_active_chat_users: .monthly_active_chat_users
monthly_active_agent_users: .monthly_active_agent_users
user_initiated_interaction_count: .user_initiated_interaction_count
code_generation_activity_count: .code_generation_activity_count
code_acceptance_activity_count: .code_acceptance_activity_count
loc_suggested_to_add_sum: .loc_suggested_to_add_sum
loc_added_sum: .loc_added_sum
loc_suggested_to_delete_sum: .loc_suggested_to_delete_sum
loc_deleted_sum: .loc_deleted_sum
prs_created_by_copilot: .pull_requests.total_created_by_copilot
prs_reviewed_by_copilot: .pull_requests.total_reviewed_by_copilot
prs_merged_by_copilot: .pull_requests.total_merged_created_by_copilot
total_copilot_applied_suggestions: .pull_requests.total_copilot_applied_suggestions
git_hub_org: .__organization.login
- kind: organization-user-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.user_login + "@" + .__organization.login + "@" + .day)
title: (.user_login + "@" + .__organization.login + "@" + .day)
blueprint: '"githubCopilotUserUsage"'
properties:
record_date: .day + "T00:00:00Z"
code_generation_activity_count: .code_generation_activity_count
code_acceptance_activity_count: .code_acceptance_activity_count
loc_suggested_to_add_sum: .loc_suggested_to_add_sum
loc_suggested_to_delete_sum: .loc_suggested_to_delete_sum
loc_added_sum: .loc_added_sum
loc_deleted_sum: .loc_deleted_sum
user_initiated_interaction_count: .user_initiated_interaction_count
git_hub_org: .__organization.login
used_agent: .used_agent
used_chat: .used_chat
username: .user_login
- kind: enterprise-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.__enterprise.slug + "@" + .day)
title: (.__enterprise.slug + " copilot-metrics " + .day)
blueprint: '"githubCopilotOrganizationUsage"'
properties:
record_date: .day + "T00:00:00Z"
daily_active_users: .daily_active_users
weekly_active_users: .weekly_active_users
monthly_active_agent_users: .monthly_active_agent_users
monthly_active_chat_users: .monthly_active_chat_users
user_initiated_interaction_count: .user_initiated_interaction_count
code_generation_activity_count: .code_generation_activity_count
code_acceptance_activity_count: .code_acceptance_activity_count
loc_suggested_to_add_sum: .loc_suggested_to_add_sum
loc_added_sum: .loc_added_sum
loc_suggested_to_delete_sum: .loc_suggested_to_delete_sum
loc_deleted_sum: .loc_deleted_sum
prs_created_by_copilot: .pull_requests.total_created_by_copilot
prs_reviewed_by_copilot: .pull_requests.total_reviewed_by_copilot
prs_merged_by_copilot: .pull_requests.total_merged_created_by_copilot
total_copilot_applied_suggestions: .pull_requests.total_copilot_applied_suggestions
- kind: enterprise-user-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.user_login + "@" + .__enterprise.slug + "@" + .day)
title: (.user_login + "@" + .__enterprise.slug + "@" + .day)
blueprint: '"githubCopilotUserUsage"'
properties:
record_date: .day + "T00:00:00Z"
code_generation_activity_count: .code_generation_activity_count
code_acceptance_activity_count: .code_acceptance_activity_count
loc_suggested_to_add_sum: .loc_suggested_to_add_sum
loc_suggested_to_delete_sum: .loc_suggested_to_delete_sum
loc_added_sum: .loc_added_sum
loc_deleted_sum: .loc_deleted_sum
user_initiated_interaction_count: .user_initiated_interaction_count
git_hub_org: .__enterprise.slug
used_agent: .used_agent
used_chat: .used_chat
username: .user_login
relations:
github_team:
combinator: '"and"'
rules:
- property: '"member_logins"'
operator: '"contains"'
value: .user_login
```
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
To view and test the integration's mapping against examples of the third-party API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources). Find the integration in the list of connectors and click on it to open the playground.
organization-usage-metricsorganization-user-usage-metricsenterprise-usage-metricsenterprise-user-usage-metrics
BlueprintJSON
Create in Port
```
{
"identifier": "githubCopilotOrganizationUsage",
"title": "Github Copilot Org Usage",
"icon": "Github",
"schema": {
"properties": {
"record_date": {
"title": "Record Date",
"type": "string",
"format": "date-time"
},
"daily_active_users": { "title": "Daily Active Users", "type": "number" },
"weekly_active_users": { "title": "Weekly Active Users", "type": "number" },
"monthly_active_users": { "title": "Monthly Active Users", "type": "number" },
"monthly_active_chat_users": { "title": "Monthly Active Chat Users", "type": "number" },
"monthly_active_agent_users": { "title": "Monthly Active Agent Users", "type": "number" },
"user_initiated_interaction_count": { "title": "User Initiated Interaction Count", "type": "number" },
"code_generation_activity_count": { "title": "Code Generation Activity Count", "type": "number" },
"code_acceptance_activity_count": { "title": "Code Acceptance Activity Count", "type": "number" },
"loc_suggested_to_add_sum": { "title": "LOC Suggested To Add", "type": "number" },
"loc_added_sum": { "title": "LOC Added", "type": "number" },
"loc_suggested_to_delete_sum": { "title": "LOC Suggested To Delete", "type": "number" },
"loc_deleted_sum": { "title": "LOC Deleted", "type": "number" },
"prs_created_by_copilot": { "title": "PRs Created by Copilot", "icon": "DefaultProperty", "type": "number" },
"prs_reviewed_by_copilot": { "title": "PRs Reviewed By Copilot", "icon": "DefaultProperty", "type": "number" },
"prs_merged_by_copilot": { "title": "PRs Merged By Copilot", "icon": "DefaultProperty", "type": "number" },
"total_copilot_applied_suggestions": { "title": "Total Suggestions Applied By Copilot", "type": "number" },
"git_hub_org": { "title": "GitHub Org", "type": "string" },
"daily_active_cli_users": { "title": "Daily Active CLI Users", "type": "number" },
"daily_active_copilot_cloud_agent_users": { "title": "Daily Active Cloud Agent Users", "type": "number" },
"weekly_active_copilot_cloud_agent_users": { "title": "Weekly Active Cloud Agent Users", "type": "number" },
"monthly_active_copilot_cloud_agent_users": { "title": "Monthly Active Cloud Agent Users", "type": "number" },
"daily_active_copilot_code_review_users": { "title": "Daily Active Code Review Users", "type": "number" },
"weekly_active_copilot_code_review_users": { "title": "Weekly Active Code Review Users", "type": "number" },
"monthly_active_copilot_code_review_users": { "title": "Monthly Active Code Review Users", "type": "number" },
"daily_passive_copilot_code_review_users": { "title": "Daily Passive Code Review Users", "type": "number" },
"weekly_passive_copilot_code_review_users": { "title": "Weekly Passive Code Review Users", "type": "number" },
"monthly_passive_copilot_code_review_users": { "title": "Monthly Passive Code Review Users", "type": "number" },
"totals_by_ide": { "title": "Totals by IDE", "type": "array" },
"totals_by_feature": { "title": "Totals by Feature", "type": "array" },
"totals_by_language_feature": { "title": "Totals by Language & Feature", "type": "array" },
"totals_by_language_model": { "title": "Totals by Language & Model", "type": "array" },
"totals_by_model_feature": { "title": "Totals by Model & Feature", "type": "array" },
"totals_by_ai_adoption_phase": { "title": "Totals by AI Adoption Phase", "type": "array" },
"pull_requests": { "title": "Pull Requests", "type": "object" },
"totals_by_cli": { "title": "Totals by CLI", "type": "object" }
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {
"acceptance_rate": {
"title": "Acceptance Rate",
"icon": "DefaultProperty",
"calculation": "if (.properties.code_generation_activity_count == 0) then 0 else ((.properties.code_acceptance_activity_count / .properties.code_generation_activity_count) * 100 | round) end",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: organization-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.__organization.login + "@" + .day)
blueprint: '"githubCopilotOrganizationUsage"'
title: (.__organization.login + " copilot-metrics " + .day)
properties:
record_date: .day + "T00:00:00Z"
daily_active_users: .daily_active_users
weekly_active_users: .weekly_active_users
monthly_active_users: .monthly_active_users
monthly_active_chat_users: .monthly_active_chat_users
monthly_active_agent_users: .monthly_active_agent_users
daily_active_cli_users: .daily_active_cli_users
daily_active_copilot_cloud_agent_users: .daily_active_copilot_cloud_agent_users
weekly_active_copilot_cloud_agent_users: .weekly_active_copilot_cloud_agent_users
monthly_active_copilot_cloud_agent_users: .monthly_active_copilot_cloud_agent_users
daily_active_copilot_code_review_users: .daily_active_copilot_code_review_users
weekly_active_copilot_code_review_users: .weekly_active_copilot_code_review_users
monthly_active_copilot_code_review_users: .monthly_active_copilot_code_review_users
daily_passive_copilot_code_review_users: .daily_passive_copilot_code_review_users
weekly_passive_copilot_code_review_users: .weekly_passive_copilot_code_review_users
monthly_passive_copilot_code_review_users: .monthly_passive_copilot_code_review_users
user_initiated_interaction_count: .user_initiated_interaction_count
code_generation_activity_count: .code_generation_activity_count
code_acceptance_activity_count: .code_acceptance_activity_count
loc_suggested_to_add_sum: .loc_suggested_to_add_sum
loc_added_sum: .loc_added_sum
loc_suggested_to_delete_sum: .loc_suggested_to_delete_sum
loc_deleted_sum: .loc_deleted_sum
prs_created_by_copilot: .pull_requests.total_created_by_copilot
prs_reviewed_by_copilot: .pull_requests.total_reviewed_by_copilot
prs_merged_by_copilot: .pull_requests.total_merged_created_by_copilot
total_copilot_applied_suggestions: .pull_requests.total_copilot_applied_suggestions
git_hub_org: .__organization.login
totals_by_ide: .totals_by_ide
totals_by_feature: .totals_by_feature
totals_by_language_feature: .totals_by_language_feature
totals_by_language_model: .totals_by_language_model
totals_by_model_feature: .totals_by_model_feature
totals_by_ai_adoption_phase: .totals_by_ai_adoption_phase
pull_requests: .pull_requests
totals_by_cli: .totals_by_cli
```
Sample payloadJSON
```
{
"day": "2026-03-05",
"organization_id": "216844958",
"enterprise_id": "232528",
"daily_active_users": 3,
"weekly_active_users": 5,
"monthly_active_users": 5,
"monthly_active_chat_users": 4,
"monthly_active_agent_users": 3,
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 187,
"code_acceptance_activity_count": 48,
"totals_by_ide": [
{
"ide": "neovim",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 185,
"code_acceptance_activity_count": 47,
"loc_suggested_to_add_sum": 250,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 66,
"loc_deleted_sum": 0
},
{
"ide": "intellij",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 2,
"code_acceptance_activity_count": 1,
"loc_suggested_to_add_sum": 2,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 1,
"loc_deleted_sum": 0
}
],
"totals_by_feature": [
{
"feature": "code_completion",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 187,
"code_acceptance_activity_count": 48,
"loc_suggested_to_add_sum": 252,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 67,
"loc_deleted_sum": 0
}
],
"totals_by_language_feature": [
{
"language": "python",
"feature": "code_completion",
"code_generation_activity_count": 167,
"code_acceptance_activity_count": 47,
"loc_suggested_to_add_sum": 232,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 66,
"loc_deleted_sum": 0
},
{
"language": "dotenv",
"feature": "code_completion",
"code_generation_activity_count": 5,
"code_acceptance_activity_count": 1,
"loc_suggested_to_add_sum": 5,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 1,
"loc_deleted_sum": 0
},
{
"language": "markdown",
"feature": "code_completion",
"code_generation_activity_count": 6,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 6,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0
},
{
"language": "yaml",
"feature": "code_completion",
"code_generation_activity_count": 5,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 5,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0
},
{
"language": "typescript",
"feature": "code_completion",
"code_generation_activity_count": 3,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 3,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0
},
{
"language": "toml",
"feature": "code_completion",
"code_generation_activity_count": 1,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 1,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0
}
],
"totals_by_language_model": [],
"totals_by_model_feature": [],
"loc_suggested_to_add_sum": 252,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 67,
"loc_deleted_sum": 0,
"pull_requests": {
"total_reviewed": 0,
"total_created": 0,
"total_created_by_copilot": 0,
"total_reviewed_by_copilot": 0,
"total_merged": 0,
"total_suggestions": 0,
"total_applied_suggestions": 0,
"total_merged_created_by_copilot": 0,
"total_copilot_suggestions": 0,
"total_copilot_applied_suggestions": 0
},
"__organization": {
"login": "idp-app-dev",
"id": 216844958,
"node_id": "O_kgDODOzKng",
"url": "https://api.github.com/orgs/idp-app-dev",
"repos_url": "https://api.github.com/orgs/idp-app-dev/repos",
"events_url": "https://api.github.com/orgs/idp-app-dev/events",
"hooks_url": "https://api.github.com/orgs/idp-app-dev/hooks",
"issues_url": "https://api.github.com/orgs/idp-app-dev/issues",
"members_url": "https://api.github.com/orgs/idp-app-dev/members{/member}",
"public_members_url": "https://api.github.com/orgs/idp-app-dev/public_members{/member}",
"avatar_url": "https://avatars.githubusercontent.com/u/216844958?v=4",
"description": ""
}
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "githubCopilotUserUsage",
"title": "GitHub Copilot User Usage",
"icon": "Github",
"schema": {
"properties": {
"record_date": {
"type": "string",
"title": "Record Date",
"format": "date-time"
},
"user_initiated_interaction_count": {
"type": "number",
"title": "User Initiated Interaction Count"
},
"code_generation_activity_count": {
"type": "number",
"title": "Code Generation Activity Count"
},
"code_acceptance_activity_count": {
"type": "number",
"title": "Code Acceptance Activity Count"
},
"loc_suggested_to_add_sum": {
"type": "number",
"title": "LOC Suggested To Add"
},
"loc_suggested_to_delete_sum": {
"type": "number",
"title": "LOC Suggested To Delete"
},
"loc_added_sum": {
"type": "number",
"title": "LOC Added"
},
"loc_deleted_sum": {
"type": "number",
"title": "LOC Deleted"
},
"git_hub_org": {
"type": "string",
"title": "GitHub Org"
},
"username": {
"type": "string",
"title": "Username"
},
"used_agent": {
"type": "boolean",
"title": "Used Agent"
},
"used_chat": {
"type": "boolean",
"title": "Used Chat"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {
"acceptance_rate": {
"title": "Acceptance Rate",
"icon": "DefaultProperty",
"calculation": "if (.properties.code_generation_activity_count == 0) then 0 else ((.properties.code_acceptance_activity_count / .properties.code_generation_activity_count) * 100 | round) end",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: organization-user-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.user_login + "@" + .__organization.login + "@" + .day)
title: (.user_login + "@" + .__organization.login + "@" + .day)
blueprint: '"githubCopilotUserUsage"'
properties:
record_date: .day + "T00:00:00Z"
code_generation_activity_count: .code_generation_activity_count
code_acceptance_activity_count: .code_acceptance_activity_count
loc_suggested_to_add_sum: .loc_suggested_to_add_sum
loc_suggested_to_delete_sum: .loc_suggested_to_delete_sum
loc_added_sum: .loc_added_sum
loc_deleted_sum: .loc_deleted_sum
user_initiated_interaction_count: .user_initiated_interaction_count
git_hub_org: .__organization.login
used_agent: .used_agent
used_chat: .used_chat
username: .user_login
```
Sample payloadJSON
```
{
"report_start_day": "2026-02-27",
"report_end_day": "2026-03-26",
"day": "2026-03-16",
"organization_id": "216844958",
"enterprise_id": "232528",
"user_id": 24739630,
"user_login": "johnsmith",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 53,
"code_acceptance_activity_count": 6,
"totals_by_ide": [
{
"ide": "neovim",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 53,
"code_acceptance_activity_count": 6,
"loc_suggested_to_add_sum": 71,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 6,
"loc_deleted_sum": 0,
"last_known_plugin_version": {
"sampled_at": "2026-03-16T21:19:46.369Z",
"plugin": "copilot.vim",
"plugin_version": "1.59.0"
},
"last_known_ide_version": {
"sampled_at": "2026-03-16T21:19:46.369Z",
"ide_version": "0.11.5"
}
}
],
"totals_by_feature": [
{
"feature": "code_completion",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 53,
"code_acceptance_activity_count": 6,
"loc_suggested_to_add_sum": 71,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 6,
"loc_deleted_sum": 0
}
],
"totals_by_language_feature": [
{
"language": "python",
"feature": "code_completion",
"code_generation_activity_count": 19,
"code_acceptance_activity_count": 3,
"loc_suggested_to_add_sum": 24,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 3,
"loc_deleted_sum": 0
},
{
"language": "lua",
"feature": "code_completion",
"code_generation_activity_count": 20,
"code_acceptance_activity_count": 1,
"loc_suggested_to_add_sum": 31,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 1,
"loc_deleted_sum": 0
},
{
"language": "markdown",
"feature": "code_completion",
"code_generation_activity_count": 12,
"code_acceptance_activity_count": 2,
"loc_suggested_to_add_sum": 14,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 2,
"loc_deleted_sum": 0
},
{
"language": "dotenv",
"feature": "code_completion",
"code_generation_activity_count": 2,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 2,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0
}
],
"totals_by_language_model": [],
"totals_by_model_feature": [],
"used_agent": false,
"used_chat": false,
"loc_suggested_to_add_sum": 71,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 6,
"loc_deleted_sum": 0,
"__organization": {
"login": "idp-app-dev",
"id": 216844958,
"node_id": "O_kgDODOzKng",
"url": "https://api.github.com/orgs/idp-app-dev",
"repos_url": "https://api.github.com/orgs/idp-app-dev/repos",
"events_url": "https://api.github.com/orgs/idp-app-dev/events",
"hooks_url": "https://api.github.com/orgs/idp-app-dev/hooks",
"issues_url": "https://api.github.com/orgs/idp-app-dev/issues",
"members_url": "https://api.github.com/orgs/idp-app-dev/members{/member}",
"public_members_url": "https://api.github.com/orgs/idp-app-dev/public_members{/member}",
"avatar_url": "https://avatars.githubusercontent.com/u/216844958?v=4",
"description": ""
}
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "githubCopilotOrganizationUsage",
"title": "Github Copilot Org Usage",
"icon": "Github",
"schema": {
"properties": {
"record_date": {
"title": "Record Date",
"type": "string",
"format": "date-time"
},
"daily_active_users": { "title": "Daily Active Users", "type": "number" },
"weekly_active_users": { "title": "Weekly Active Users", "type": "number" },
"monthly_active_users": { "title": "Monthly Active Users", "type": "number" },
"monthly_active_chat_users": { "title": "Monthly Active Chat Users", "type": "number" },
"monthly_active_agent_users": { "title": "Monthly Active Agent Users", "type": "number" },
"user_initiated_interaction_count": { "title": "User Initiated Interaction Count", "type": "number" },
"code_generation_activity_count": { "title": "Code Generation Activity Count", "type": "number" },
"code_acceptance_activity_count": { "title": "Code Acceptance Activity Count", "type": "number" },
"loc_suggested_to_add_sum": { "title": "LOC Suggested To Add", "type": "number" },
"loc_added_sum": { "title": "LOC Added", "type": "number" },
"loc_suggested_to_delete_sum": { "title": "LOC Suggested To Delete", "type": "number" },
"loc_deleted_sum": { "title": "LOC Deleted", "type": "number" },
"prs_created_by_copilot": { "title": "PRs Created by Copilot", "icon": "DefaultProperty", "type": "number" },
"prs_reviewed_by_copilot": { "title": "PRs Reviewed By Copilot", "icon": "DefaultProperty", "type": "number" },
"prs_merged_by_copilot": { "title": "PRs Merged By Copilot", "icon": "DefaultProperty", "type": "number" },
"total_copilot_applied_suggestions": { "title": "Total Suggestions Applied By Copilot", "type": "number" },
"git_hub_org": { "title": "GitHub Org", "type": "string" },
"daily_active_cli_users": { "title": "Daily Active CLI Users", "type": "number" },
"daily_active_copilot_cloud_agent_users": { "title": "Daily Active Cloud Agent Users", "type": "number" },
"weekly_active_copilot_cloud_agent_users": { "title": "Weekly Active Cloud Agent Users", "type": "number" },
"monthly_active_copilot_cloud_agent_users": { "title": "Monthly Active Cloud Agent Users", "type": "number" },
"daily_active_copilot_code_review_users": { "title": "Daily Active Code Review Users", "type": "number" },
"weekly_active_copilot_code_review_users": { "title": "Weekly Active Code Review Users", "type": "number" },
"monthly_active_copilot_code_review_users": { "title": "Monthly Active Code Review Users", "type": "number" },
"daily_passive_copilot_code_review_users": { "title": "Daily Passive Code Review Users", "type": "number" },
"weekly_passive_copilot_code_review_users": { "title": "Weekly Passive Code Review Users", "type": "number" },
"monthly_passive_copilot_code_review_users": { "title": "Monthly Passive Code Review Users", "type": "number" },
"totals_by_ide": { "title": "Totals by IDE", "type": "array" },
"totals_by_feature": { "title": "Totals by Feature", "type": "array" },
"totals_by_language_feature": { "title": "Totals by Language & Feature", "type": "array" },
"totals_by_language_model": { "title": "Totals by Language & Model", "type": "array" },
"totals_by_model_feature": { "title": "Totals by Model & Feature", "type": "array" },
"totals_by_ai_adoption_phase": { "title": "Totals by AI Adoption Phase", "type": "array" },
"pull_requests": { "title": "Pull Requests", "type": "object" },
"totals_by_cli": { "title": "Totals by CLI", "type": "object" }
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {
"acceptance_rate": {
"title": "Acceptance Rate",
"icon": "DefaultProperty",
"calculation": "if (.properties.code_generation_activity_count == 0) then 0 else ((.properties.code_acceptance_activity_count / .properties.code_generation_activity_count) * 100 | round) end",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: enterprise-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.__enterprise.slug + "@" + .day)
title: (.__enterprise.slug + " copilot-metrics " + .day)
blueprint: '"githubCopilotOrganizationUsage"'
properties:
record_date: .day + "T00:00:00Z"
daily_active_users: .daily_active_users
weekly_active_users: .weekly_active_users
monthly_active_agent_users: .monthly_active_agent_users
monthly_active_chat_users: .monthly_active_chat_users
user_initiated_interaction_count: .user_initiated_interaction_count
code_generation_activity_count: .code_generation_activity_count
code_acceptance_activity_count: .code_acceptance_activity_count
loc_suggested_to_add_sum: .loc_suggested_to_add_sum
loc_added_sum: .loc_added_sum
loc_suggested_to_delete_sum: .loc_suggested_to_delete_sum
loc_deleted_sum: .loc_deleted_sum
prs_created_by_copilot: .pull_requests.total_created_by_copilot
prs_reviewed_by_copilot: .pull_requests.total_reviewed_by_copilot
prs_merged_by_copilot: .pull_requests.total_merged_created_by_copilot
total_copilot_applied_suggestions: .pull_requests.total_copilot_applied_suggestions
```
Sample payloadJSON
```
{
"day": "2026-04-06",
"enterprise_id": "232528",
"daily_active_users": 5,
"weekly_active_users": 6,
"monthly_active_users": 7,
"monthly_active_chat_users": 1,
"monthly_active_agent_users": 1,
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 151,
"code_acceptance_activity_count": 39,
"totals_by_ide": [
{
"ide": "intellij",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 133,
"code_acceptance_activity_count": 33,
"loc_suggested_to_add_sum": 158,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 44,
"loc_deleted_sum": 0
},
{
"ide": "neovim",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 18,
"code_acceptance_activity_count": 6,
"loc_suggested_to_add_sum": 18,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 7,
"loc_deleted_sum": 0
}
],
"totals_by_feature": [
{
"feature": "code_completion",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 151,
"code_acceptance_activity_count": 39,
"loc_suggested_to_add_sum": 176,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 51,
"loc_deleted_sum": 0
}
],
"totals_by_language_feature": [
{
"language": "tsx",
"feature": "code_completion",
"code_generation_activity_count": 122,
"code_acceptance_activity_count": 29,
"loc_suggested_to_add_sum": 144,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 34,
"loc_deleted_sum": 0
},
{
"language": "typescript",
"feature": "code_completion",
"code_generation_activity_count": 27,
"code_acceptance_activity_count": 10,
"loc_suggested_to_add_sum": 30,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 17,
"loc_deleted_sum": 0
},
{
"language": "zsh",
"feature": "code_completion",
"code_generation_activity_count": 2,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 2,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0
}
],
"totals_by_language_model": [],
"totals_by_model_feature": [],
"loc_suggested_to_add_sum": 176,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 51,
"loc_deleted_sum": 0,
"pull_requests": {
"total_reviewed": 118,
"total_created": 129,
"total_created_by_copilot": 0,
"total_reviewed_by_copilot": 15,
"total_merged": 95,
"median_minutes_to_merge": 35.45,
"total_suggestions": 37,
"total_applied_suggestions": 2,
"total_merged_created_by_copilot": 0,
"total_copilot_suggestions": 30,
"total_copilot_applied_suggestions": 0
},
"__enterprise": {
"slug": "getport"
}
}
```
Sample Port entityJSON
```
{
"identifier": "getport@2026-04-16",
"title": "getport copilot-metrics 2026-04-16",
"properties": {
"record_date": "2026-04-16T00:00:00Z",
"daily_active_users": 10,
"code_generation_activity_count": 24,
"code_acceptance_activity_count": 3,
"loc_suggested_to_add_sum": 24,
"loc_added_sum": 3,
"user_initiated_interaction_count": 0,
"weekly_active_users": 12,
"monthly_active_agent_users": 1,
"loc_suggested_to_delete_sum": 0,
"loc_deleted_sum": 0,
"prs_created_by_copilot": 0,
"prs_reviewed_by_copilot": 8,
"prs_merged_by_copilot": 0,
"total_copilot_applied_suggestions": 0,
"monthly_active_chat_users": 1,
"acceptance_rate": 13
},
"relations": {},
"icon": "Github"
}
```
BlueprintJSON
Create in Port
```
{
"identifier": "githubCopilotUserUsage",
"title": "GitHub Copilot User Usage",
"icon": "Github",
"schema": {
"properties": {
"record_date": {
"type": "string",
"title": "Record Date",
"format": "date-time"
},
"user_initiated_interaction_count": {
"type": "number",
"title": "User Initiated Interaction Count"
},
"code_generation_activity_count": {
"type": "number",
"title": "Code Generation Activity Count"
},
"code_acceptance_activity_count": {
"type": "number",
"title": "Code Acceptance Activity Count"
},
"loc_suggested_to_add_sum": {
"type": "number",
"title": "LOC Suggested To Add"
},
"loc_suggested_to_delete_sum": {
"type": "number",
"title": "LOC Suggested To Delete"
},
"loc_added_sum": {
"type": "number",
"title": "LOC Added"
},
"loc_deleted_sum": {
"type": "number",
"title": "LOC Deleted"
},
"git_hub_org": {
"type": "string",
"title": "GitHub Org"
},
"username": {
"type": "string",
"title": "Username"
},
"used_agent": {
"type": "boolean",
"title": "Used Agent"
},
"used_chat": {
"type": "boolean",
"title": "Used Chat"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {
"acceptance_rate": {
"title": "Acceptance Rate",
"icon": "DefaultProperty",
"calculation": "if (.properties.code_generation_activity_count == 0) then 0 else ((.properties.code_acceptance_activity_count / .properties.code_generation_activity_count) * 100 | round) end",
"type": "number"
}
},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: enterprise-user-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.user_login + "@" + .__enterprise.slug + "@" + .day)
title: (.user_login + "@" + .__enterprise.slug + "@" + .day)
blueprint: '"githubCopilotUserUsage"'
properties:
record_date: .day + "T00:00:00Z"
code_generation_activity_count: .code_generation_activity_count
code_acceptance_activity_count: .code_acceptance_activity_count
loc_suggested_to_add_sum: .loc_suggested_to_add_sum
loc_suggested_to_delete_sum: .loc_suggested_to_delete_sum
loc_added_sum: .loc_added_sum
loc_deleted_sum: .loc_deleted_sum
user_initiated_interaction_count: .user_initiated_interaction_count
git_hub_org: .__enterprise.slug
used_agent: .used_agent
used_chat: .used_chat
username: .user_login
relations:
github_team:
combinator: '"and"'
rules:
- property: '"member_logins"'
operator: '"contains"'
value: .user_login
```
Sample payloadJSON
```
{
"report_start_day": "2026-04-02",
"report_end_day": "2026-04-29",
"day": "2026-04-15",
"enterprise_id": "232528",
"user_id": 253551706,
"user_login": "jasonnwakaeze-debug",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 1,
"code_acceptance_activity_count": 0,
"totals_by_ide": [
{
"ide": "intellij",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 1,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 3,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0,
"last_known_plugin_version": {
"sampled_at": "2026-04-15T17:29:55.273Z",
"plugin": "copilot-intellij",
"plugin_version": "1.5.66-243"
},
"last_known_ide_version": {
"sampled_at": "2026-04-15T17:29:55.273Z",
"ide_version": "253.29346.142"
}
}
],
"totals_by_feature": [
{
"feature": "code_completion",
"user_initiated_interaction_count": 0,
"code_generation_activity_count": 1,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 3,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0
}
],
"totals_by_language_feature": [
{
"language": "json",
"feature": "code_completion",
"code_generation_activity_count": 1,
"code_acceptance_activity_count": 0,
"loc_suggested_to_add_sum": 3,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0
}
],
"totals_by_language_model": [],
"totals_by_model_feature": [],
"used_agent": false,
"used_chat": false,
"loc_suggested_to_add_sum": 3,
"loc_suggested_to_delete_sum": 0,
"loc_added_sum": 0,
"loc_deleted_sum": 0,
"used_cli": false,
"used_copilot_coding_agent": false,
"used_copilot_cloud_agent": false,
"used_copilot_code_review_active": false,
"used_copilot_code_review_passive": true,
"__enterprise": {
"slug": "getport"
}
}
```
Sample Port entityJSON
```
{
"identifier": "jasonnwakaeze-debug@getport@2026-03-08",
"title": "jasonnwakaeze-debug@getport@2026-03-08",
"properties": {
"record_date": "2026-03-08T00:00:00Z",
"code_generation_activity_count": 9,
"code_acceptance_activity_count": 2,
"loc_suggested_to_add_sum": 9,
"loc_added_sum": 2,
"user_initiated_interaction_count": 0,
"git_hub_org": "getport",
"loc_suggested_to_delete_sum": 0,
"loc_deleted_sum": 0,
"username": "jasonnwakaeze-debug",
"used_agent": false,
"used_chat": false,
"acceptance_rate": 22
},
"relations": {
"github_team": []
},
"icon": "Github"
}
```
GitHub integration required
The `github_team` relation on enterprise user usage metrics requires the [GitHub integration](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/git/github/) to be installed and syncing `githubTeam` entities with the `member_logins` property populated.
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Track AI credit cost[](#track-ai-credit-cost "Direct link to Track AI credit cost")
GitHub's Copilot usage metrics API includes an `ai_credits_used` field on user-level reports. It is the total AI credits a user consumed for that day, across all Copilot activity. The field is available on both organization and enterprise user reports. See GitHub's [changelog announcement](https://github.blog/changelog/2026-06-19-ai-credits-consumed-per-user-now-in-the-copilot-usage-metrics-api/).
You can map that field into a dedicated blueprint to monitor spend, compare consumption across users, and estimate USD cost next to request volume.
Metrics signal, not a billed total
`ai_credits_used` is an overall per-user total. GitHub does not break it down by feature, model, or surface. Treat `amount` as a consumption estimate for analysis, not an invoice line. The mapping multiplies credits by `0.01` to store an estimated USD value.
Add this mapping **in addition to** the default `organization-user-usage-metrics` (or `enterprise-user-usage-metrics`) block. Ocean can ingest the same kind twice into different blueprints.
### Create the cost usage blueprint
1. Go to the [data model](https://app.port.io/settings/data-model) page in Port.
2. Click **+ Blueprint**.
3. Click the `{...} Edit JSON` button.
4. Copy and paste the following JSON configuration:
**GitHub Copilot cost usage blueprint (click to expand)**
Create in Port
```
{
"identifier": "githubCopilotCostUsage",
"description": "Per-user USD cost across a date range",
"title": "GitHub Copilot Cost Usage",
"icon": "GithubCopilot",
"schema": {
"properties": {
"record_date": {
"type": "string",
"format": "date-time",
"title": "Range Start (UTC)"
},
"range_end": {
"type": "string",
"format": "date-time",
"title": "Range End (UTC)"
},
"user_name": {
"type": "string",
"title": "User Name"
},
"currency": {
"type": "string",
"title": "Currency"
},
"amount": {
"type": "number",
"title": "AI Credit Amount"
},
"requests": {
"type": "number",
"title": "Requests"
}
},
"required": [
"record_date"
]
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
5. Click **Save**.
### Add the mapping
1. Go to the [connectors](https://app.port.io/settings/data-sources) page in Port.
2. Open your GitHub Copilot integration and select the **Mapping** tab.
3. Add one of the following resource blocks, then click **Save & Resync**.
* Organization
* Enterprise
**Organization cost mapping (click to expand)**
```
- kind: organization-user-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.user_login + "@" + .__organization.login + "@" + .day)
title: (.user_login + "@" + .__organization.login + "@" + .day)
blueprint: '"githubCopilotCostUsage"'
properties:
record_date: .report_start_day + "T00:00:00Z"
range_end: .report_end_day + "T00:00:00Z"
user_name: .user_login
currency: '"USD"'
amount: (.ai_credits_used * 0.01)
requests: .user_initiated_interaction_count
```
**Enterprise cost mapping (click to expand)**
```
- kind: enterprise-user-usage-metrics
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.user_login + "@" + .__enterprise.slug + "@" + .day)
title: (.user_login + "@" + .__enterprise.slug + "@" + .day)
blueprint: '"githubCopilotCostUsage"'
properties:
record_date: .report_start_day + "T00:00:00Z"
range_end: .report_end_day + "T00:00:00Z"
user_name: .user_login
currency: '"USD"'
amount: (.ai_credits_used * 0.01)
requests: .user_initiated_interaction_count
```
## Migration Guide[](#migration-guide "Direct link to Migration Guide")
This guide covers the migration from the legacy `copilot-organization-metrics` kind to the new `organization-usage-metrics` kind. GitHub shut down the legacy Copilot Metrics API on **April 2, 2026**.
### What changed[](#what-changed "Direct link to What changed")
* The `copilot-organization-metrics` kind was replaced by `organization-usage-metrics`, which uses a new blueprint (`githubCopilotOrganizationUsage`) and features a restructured schema.
* GitHub discontinued support for team-level metrics. As a result, the `copilot-team-metrics` kind stopped functioning after the sunset date. There is no replacement for this functionality in the new API or the integration.
### Migrate from copilot-organization-metrics[](#migrate-from-copilot-organization-metrics "Direct link to Migrate from copilot-organization-metrics")
**1. Add the new blueprint**
Ensure you have the `githubCopilotOrganizationUsage` blueprint in Port. You can find the blueprint definition in the [Organization usage metrics](#organization-usage-metrics) section above.
**2. Add the new integration mapping**
In your Port connector configuration, add the `organization-usage-metrics` kind. You can find the full mapping in the [organization-usage-metrics](#organization-usage-metrics) resource section above.
**3. Verify token permissions**
Ensure you are using a classic PAT (fine-grained PATs are not supported) with at least one of the following scopes: `manage_billing:copilot` or `read:enterprise`. The token must be generated by an **Enterprise Administrator** or **Billing Manager**, or a user with the proper fine-grained permissions to access Copilot metrics. Also confirm that the **"Copilot usage metrics"** policy is set to **Enabled everywhere** in your enterprise settings under **AI Controls -> Copilot -> Metrics**.
**4. Remove legacy kinds**
Once data is flowing correctly via `organization-usage-metrics`, remove both `copilot-organization-metrics` and `copilot-team-metrics` from your mapping. Note that `copilot-team-metrics` has no replacement — it is simply being removed.
Existing entities
Entities already ingested under the `github_copilot_usage` blueprint will not be automatically deleted. A resync will auto-reconcile the environment.
## Related guide[](#related-guide "Direct link to Related guide")
[Visualize GitHub Copilot metrics](/guides/all/visualize-github-copilot-metrics/.md)
---
# OpenAI metrics
Custom Ocean integration
This integration was created using the [custom Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework.
Please note that:
1. This integration will not be listed in the `Connectors` page of your Port application, and must be installed manually using the instructions on this page.
2. This integration will not create components (e.g. `blueprints`, `mapping`, etc.) in your portal automatically, you will need to create them manually using the instructions on this page.
Port's OpenAI integration ingests foundational OpenAI usage metrics into your software catalog using the [No-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework. It focuses on two reliable data sources: daily cost summaries and model-level usage statistics.
The integration tracks usage across all OpenAI models, including ChatGPT models (GPT-4, GPT-3.5, etc.) and other OpenAI API models.
## Supported resources[](#supported-resources "Direct link to Supported resources")
The OpenAI integration can ingest the following resources into Port:
* `openai_daily_usage` – Daily totals for requests, tokens, and spend from `/dashboard/billing/usage`.
* `openai_model_usage` – Model-level request and token breakdowns from `/usage`.
* `openai_model` – Available OpenAI models and their details from `/models`.
These resources provide visibility into your OpenAI usage, costs, and available models.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
To use this integration, you need:
* An OpenAI API key with access to the usage and billing endpoints.
* Network access from the Ocean integration to `api.openai.com`.
**To create an OpenAI API key:**
1. Navigate to the [OpenAI Platform](https://platform.openai.com/) and sign in to your account.
2. Click on your profile icon in the top right corner and select **API keys**.
3. Click **Create new secret key**.
4. Give your key a name (e.g., "Port Integration") and click **Create secret key**.
5. Copy the API key immediately (it starts with `sk-`). You won't be able to see it again after closing the dialog.
API key security
Store your API key securely and never share it. The key provides access to your OpenAI account usage and billing data.
Review the [OpenAI usage docs](https://platform.openai.com/docs/api-reference/usage) to understand the exact response structure returned by each endpoint.
## Installation[](#installation "Direct link to Installation")
The no-code Ocean custom integration can be installed in two ways:
* **[Hosted by Port](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md)** — Port manages the infrastructure; configure the connection in the Port UI.
* **[Self-hosted](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup/.md)** — Run the integration in your own infrastructure using Helm or Docker.
Choose one of the following options:
* Hosted by Port
* Helm
* Docker
### Set up in Port
1. Go to the [custom connector page](https://app.port.io/settings/data-sources?section=EXPORTERS\&provider=Custom) and open the no-code Ocean custom integration form.
2. Configure:
* **Identifier**: `openai-integration`.
* **Base URL**: `https://api.openai.com/v1`.
* **Authentication type**: `bearer_token`.
* **Token**: your OpenAI API key (starts with `sk-`).
3. Click **Save & install**.
Continue with the mappings
After the integration is installed, continue to the **Configuration** section on this page and add the resource mappings.
## Prerequisites
* A Kubernetes cluster - the integration's container chart will be deployed to this cluster.
* [`kubectl`](https://kubernetes.io/docs/tasks/tools/#kubectl) and [`helm`](https://helm.sh/) must be installed on your machine. Your `kubectl` CLI must be connected to the Kubernetes cluster where you plan to install the integration.
## Installation
1. Add Port's Helm repo and install the no-code Ocean custom integration:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, and `YOUR_OPENAI_API_KEY`.
```
helm repo add --force-update port-labs https://port-labs.github.io/helm-charts
helm upgrade --install my-ocean-openai-integration port-labs/port-ocean \
--set port.clientId="YOUR_PORT_CLIENT_ID" \
--set port.clientSecret="YOUR_PORT_CLIENT_SECRET" \
--set port.baseUrl="https://api.port.io" \
--set initializePortResources=true \
--set integration.identifier="openai-integration" \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.config.baseUrl="https://api.openai.com/v1" \
--set integration.config.authType="bearer_token" \
--set integration.config.apiToken="YOUR_OPENAI_API_KEY"
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Configuration parameters
| Parameter | Description | Example | Required |
| -------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------- | -------- |
| `port.clientId` | Your Port [client id](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.clientSecret` | Your Port [client secret](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.baseUrl` | Your Port API URL (`https://api.port.io` for EU, `https://api.us.port.io` for US). | | ✅ |
| `integration.config.baseUrl` | Base URL for the OpenAI API. | | ✅ |
| `integration.config.authType` | Authentication type for OpenAI (use `bearer_token` for OpenAI). | bearer\_token | ✅ |
| `integration.config.apiToken` | OpenAI API key (starts with `sk-`). | sk-abc123 | ✅ |
| `integration.eventListener.type` | Event listener type for the integration. | POLLING | ✅ |
| `integration.type` | Integration type. Must be `custom`. | custom | ✅ |
| `integration.identifier` | Unique identifier for this integration instance. | openai-integration | ✅ |
| `initializePortResources` | Create default blueprints and mappings on first run. | true | ❌ |
| `scheduledResyncInterval` | Minutes between scheduled syncs. Defaults to event listener interval when omitted. | 120 | ❌ |
| `sendRawDataExamples` | Send sample payloads for easier mapping. | true | ❌ |
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
To run the integration using Docker for a one-time sync:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, and `YOUR_OPENAI_API_KEY`.
```
docker run -i --rm --platform=linux/amd64 \
-e OCEAN__EVENT_LISTENER='{"type":"ONCE"}' \
-e OCEAN__INITIALIZE_PORT_RESOURCES=true \
-e OCEAN__SEND_RAW_DATA_EXAMPLES=true \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="https://api.openai.com/v1" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="bearer_token" \
-e OCEAN__INTEGRATION__CONFIG__API_TOKEN="YOUR_OPENAI_API_KEY" \
-e OCEAN__PORT__CLIENT_ID="YOUR_PORT_CLIENT_ID" \
-e OCEAN__PORT__CLIENT_SECRET="YOUR_PORT_CLIENT_SECRET" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
ghcr.io/port-labs/port-ocean-custom:latest
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
## Set up data model[](#set-up-data-model "Direct link to Set up data model")
Before syncing data, create the blueprints that define your OpenAI entities (usage metrics and available models).
**To create the blueprints:**
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Click the `+ Blueprint` button.
3. Copy each blueprint JSON from the sections below.
**OpenAI daily usage blueprint (click to expand)**
Create in Port
```
{
"identifier": "openai_daily_usage",
"title": "OpenAI Daily Usage",
"icon": "OpenAI",
"schema": {
"properties": {
"date": {
"type": "string",
"format": "date",
"title": "Date"
},
"total_requests": {
"type": "number",
"title": "Total Requests"
},
"total_tokens": {
"type": "number",
"title": "Total Tokens"
},
"total_cost": {
"type": "number",
"title": "Total Cost (USD)"
}
},
"required": [
"date"
]
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**OpenAI model usage blueprint (click to expand)**
Create in Port
```
{
"identifier": "openai_model_usage",
"title": "OpenAI Model Usage",
"icon": "OpenAI",
"schema": {
"properties": {
"model": {
"type": "string",
"title": "Model Name"
},
"date": {
"type": "string",
"format": "date",
"title": "Date"
},
"requests": {
"type": "number",
"title": "Requests"
},
"tokens": {
"type": "number",
"title": "Tokens Used"
}
},
"required": [
"model",
"date"
]
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**OpenAI Model blueprint (click to expand)**
Create in Port
```
{
"identifier": "openai_model",
"title": "OpenAI Model",
"icon": "Claude",
"schema": {
"properties": {
"modelId": {
"type": "string",
"title": "Model ID"
},
"object": {
"type": "string",
"title": "Object Type"
},
"created": {
"type": "number",
"title": "Created Timestamp"
},
"ownedBy": {
"type": "string",
"title": "Owned By"
},
"permission": {
"type": "array",
"title": "Permissions"
}
},
"required": [
"modelId"
]
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
4. Click `Save` after each blueprint is added.
## Configuration[](#configuration "Direct link to Configuration")
Each resource maps an OpenAI endpoint to the Port entities defined above.
**Key mapping components:**
* **`kind`** – API endpoint path appended to `https://api.openai.com/v1`.
* **`selector`** – Request payload, pagination controls, and data selection logic.
* **`port.entity.mappings`** – JQ expressions that transform the API payload into Port entities.
**Daily usage summary mapping (click to expand)**
```
resources:
- kind: /dashboard/billing/usage
selector:
query: 'true'
query_params:
start_date: '((now | floor) - (86400 * 30)) | strftime("%Y-%m-%d")'
end_date: '(now | floor) | strftime("%Y-%m-%d")'
port:
entity:
mappings:
identifier: "daily-" + (.timestamp // .aggregation_timestamp // "unknown")
title: "OpenAI Usage " + (.timestamp // .aggregation_timestamp // "unknown")
blueprint: '"openai_daily_usage"'
properties:
date: (.timestamp // .aggregation_timestamp // "" | split("T")[0])
total_requests: .total_requests // 0
total_tokens: .total_tokens // 0
total_cost: (.total_usage // 0) / 100
```
Cost units
`/dashboard/billing/usage` returns costs in cents. Divide by `100` to store USD.
**Model usage breakdown mapping (click to expand)**
```
resources:
- kind: /usage
selector:
query: 'true'
query_params:
date: '(now | floor) | strftime("%Y-%m-%d")'
port:
entity:
mappings:
identifier: .snapshot_id + "-" + ((.aggregation_timestamp // 0) | tostring)
title: .snapshot_id + " usage"
blueprint: '"openai_model_usage"'
properties:
model: .snapshot_id
date: (.aggregation_timestamp // 0 | strftime("%Y-%m-%d"))
requests: .n_requests // 0
tokens: (.n_context_tokens_total // 0) + (.n_generated_tokens_total // 0)
```
Snapshot identifiers
`snapshot_id` typically corresponds to the model name (for example, `gpt-4o`). Use it for both the identifier and the model property to keep the mapping simple.
**OpenAI Models mapping (click to expand)**
```
resources:
- kind: /models
selector:
query: 'true'
data_path: '.data'
port:
entity:
mappings:
identifier: .id
title: .id
blueprint: '"openai_model"'
properties:
modelId: .id
object: .object
ownedBy: .owned_by
permission: .permission
```
Models endpoint
The `/models` endpoint returns a list of all available OpenAI models. This is useful for cataloging which models are available in your account and tracking model availability over time.
5. Click `Save` to persist the mapping.
## Customization[](#customization "Direct link to Customization")
If you want to expand beyond the starter resources, use the [interactive builder](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/build-your-integration/.md) to:
1. Test additional OpenAI endpoints.
2. Explore the response shape and detected property types.
3. Generate blueprint JSON and mapping snippets automatically.
4. Export installation commands with your configuration pre-filled.
Start with the daily and model usage entities above, then add more resources (such as per-organization or per-team reports) once you verify the value.
---
# APM & alerting
Port's APM & alerting integrations make it easy to keep your software catalog up to date based on information stored in your preferred APM & alerting tool.
For more information, check out the documentation for your respective tool:
## [🗃Datadog](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog/.md)
[1 item](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog/.md)
## [📄️Dynatrace](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/dynatrace/.md)
[Sync Dynatrace monitoring data, problems, and services into Port's software catalog.](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/dynatrace/.md)
## [📄️New Relic](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/newrelic/.md)
[Sync New Relic monitoring data, alerts, and services into Port's software catalog.](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/newrelic/.md)
## [📄️Sentry](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/sentry/.md)
[Sync Sentry projects, issues, and error tracking data into Port's software catalog.](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/sentry/.md)
## [📄️Azure Monitor](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/azure-monitor/.md)
[Learn how to ingest Azure Monitor alerts, activity logs, and metrics into Port using the no-code Ocean custom integration framework.](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/azure-monitor/.md)
## [📄️Prometheus](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/prometheus/.md)
[Learn how to ingest Prometheus alerts, rules, and scrape targets into Port using the no-code Ocean custom integration framework.](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/prometheus/.md)
---
# Azure Monitor
Custom Ocean integration
This integration was created using the [custom Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework.
Please note that:
1. This integration will not be listed in the `Connectors` page of your Port application, and must be installed manually using the instructions on this page.
2. This integration will not create components (e.g. `blueprints`, `mapping`, etc.) in your portal automatically, you will need to create them manually using the instructions on this page.
Port's Azure Monitor integration allows you to ingest Azure Monitor resources into your software catalog using the [No-code Ocean custom integration](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview) framework. After installing this integration, you can visualize metrics, alerts, activity logs, and diagnostic settings from your Azure resources.
## Supported resources[](#supported-resources "Direct link to Supported resources")
The Azure Monitor integration can ingest the following resources into Port. It is possible to reference any field that appears in the API responses in the mapping configuration. For detailed API documentation, see the [Azure Monitor REST API documentation](https://learn.microsoft.com/en-us/rest/api/monitor/).
* **Metric Alerts** - Alert rules from [`/subscriptions/{subscriptionId}/providers/Microsoft.Insights/metricAlerts`](https://learn.microsoft.com/en-us/rest/api/monitor/metricalerts/listbysubscription).
* **Activity Logs** - Activity log events from [`/subscriptions/{subscriptionId}/providers/Microsoft.Insights/eventtypes/management/values`](https://learn.microsoft.com/en-us/rest/api/monitor/activity-logs/list).
* **Diagnostic Settings** - Diagnostic settings from resource-specific endpoints (varies by resource type).
* **Metrics** - Resource metrics from resource-specific endpoints (requires resource-specific paths).
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
To use this integration, the following prerequisites are required:
* An Azure subscription with appropriate permissions.
* A Microsoft Entra ID application registration with appropriate API permissions.
* A client secret for the application.
* Admin consent for the required permissions.
* An access token (bearer token) for Azure Resource Manager API.
**Register an application in Microsoft Entra ID**
1. Log in to the [Azure Portal](https://portal.azure.com).
2. Navigate to **Microsoft Entra ID** > **App registrations**.
3. Click **New registration**.
4. Provide a name for your application (e.g., "Port Azure Monitor Integration").
5. Select **Accounts in this organizational directory only**.
6. Click **Register**.
7. Note the **Application (client) ID** and **Directory (tenant) ID**.
**Create a client secret**
1. In your app registration, navigate to **Certificates & secrets**.
2. Click **New client secret**.
3. Provide a description (e.g., "Port Azure Monitor Secret").
4. Select an expiration period.
5. Click **Add**.
6. **Copy the secret value immediately** - it will not be shown again.
Secret security
Store your client secret securely and never share it. The secret provides access to your Azure resources.
**Grant API permissions:**
1. In your app registration, navigate to **API permissions**.
2. Click **Add a permission**.
3. Select **Azure Service Management**.
4. Select **Application permissions**.
5. Add the following permission:
* `user_impersonation` - Access Azure Service Management as organization users.
6. Click **Add permissions**.
7. Click **Grant admin consent for \[Your Organization]**.
Admin consent required
You need an Entra ID administrator to grant consent for these permissions before the integration can access Azure Monitor data.
**Generate an access token (bearer token)**
To authenticate with Azure Resource Manager API we need to obtain an OAuth2 access token. We can use the following curl command to get a token:
```
curl -X POST "https://login.microsoftonline.com/YOUR_TENANT_ID/oauth2/v2.0/token" \
-H "Content-Type: application/x-www-form-urlencoded" \
-d "client_id=YOUR_CLIENT_ID" \
-d "client_secret=YOUR_CLIENT_SECRET" \
-d "scope=https://management.azure.com/.default" \
-d "grant_type=client_credentials" | jq -r '.access_token'
```
Replace:
* `YOUR_TENANT_ID` with your Directory (tenant) ID.
* `YOUR_CLIENT_ID` with your Application (client) ID.
* `YOUR_CLIENT_SECRET` with your client secret value.
Token expiration
Access tokens typically expire after 1 hour. For production use, consider implementing automatic token refresh or using OAuth2 client credentials flow with automatic token management.
**To find your subscription ID:**
1. Log in to the [Azure Portal](https://portal.azure.com).
2. Navigate to **Subscriptions**.
3. Copy the **Subscription ID** you want to monitor.
## Installation[](#installation "Direct link to Installation")
The no-code Ocean custom integration can be installed in two ways:
* **[Hosted by Port](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md)** — Port manages the infrastructure; configure the connection in the Port UI.
* **[Self-hosted](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup/.md)** — Run the integration in your own infrastructure using Helm or Docker.
Choose one of the following options:
* Hosted by Port
* Helm
* Docker
### Set up in Port
1. Go to the [custom connector page](https://app.port.io/settings/data-sources?section=EXPORTERS\&provider=Custom) and open the no-code Ocean custom integration form.
2. Configure:
* **Identifier**: `azure-monitor-integration`.
* **Base URL**: `https://management.azure.com`.
* **Authentication type**: `bearer_token`.
* **Token**: your Azure Resource Manager bearer token (see the Prerequisites section for how to generate it).
3. Click **Save & install**.
Continue with the mappings
After the integration is installed, continue to the **Configuration** section on this page and add the resource mappings.
## Prerequisites
* A Kubernetes cluster - the integration's container chart will be deployed to this cluster.
* [`kubectl`](https://kubernetes.io/docs/tasks/tools/#kubectl) and [`helm`](https://helm.sh/) must be installed on your machine. Your `kubectl` CLI must be connected to the Kubernetes cluster where you plan to install the integration.
## Installation
Add Port's Helm repo and install the no-code Ocean custom integration:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, and `YOUR_BEARER_TOKEN`. Get your bearer token using the curl command in the Prerequisites section.
```
helm repo add --force-update port-labs https://port-labs.github.io/helm-charts
helm upgrade --install my-ocean-azure-monitor-integration port-labs/port-ocean \
--set port.clientId="YOUR_PORT_CLIENT_ID" \
--set port.clientSecret="YOUR_PORT_CLIENT_SECRET" \
--set port.baseUrl="https://api.port.io" \
--set initializePortResources=true \
--set scheduledResyncInterval=120 \
--set integration.identifier="azure-monitor-integration" \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.config.baseUrl="https://management.azure.com" \
--set integration.config.authType="bearer_token" \
--set integration.config.apiToken="YOUR_BEARER_TOKEN"
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Configuration parameters
This table summarizes the available parameters for the installation.
| Parameter | Description | Example | Required |
| ----------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------- | -------- |
| `port.clientId` | Your Port [client id](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.clientSecret` | Your Port [client secret](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.baseUrl` | Your Port API URL (`https://api.port.io` for EU, `https://api.us.port.io` for US). | | ✅ |
| `integration.config.baseUrl` | Base URL of the Azure Resource Manager API. | | ✅ |
| `integration.config.authType` | Authentication type for the API (use `bearer_token` for Azure Monitor). | bearer\_token | ✅ |
| `integration.config.apiToken` | Azure Resource Manager API bearer token created via the OAuth2 client credentials flow. | eyJ0eXAiOiJKV1QiLCJub25jZSI6... | ✅ |
| `integration.config.paginationType` | How the API handles pagination (offset, page, cursor, or none). | none | ❌ |
| `integration.eventListener.type` | Event listener type. See [event listeners](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md). | POLLING | ✅ |
| `integration.type` | Integration type (must be `custom`). | custom | ✅ |
| `integration.identifier` | Unique identifier for the integration instance. | azure-monitor-integration | ✅ |
| `scheduledResyncInterval` | Minutes between scheduled syncs. When omitted, the event listener interval is used. | 120 | ❌ |
| `initializePortResources` | When true, creates default blueprints and mappings on first run. | true | ❌ |
| `sendRawDataExamples` | Sends sample payloads from the API to Port for easier mapping. | true | ❌ |
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
To run the integration using Docker for a one-time sync:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, and `YOUR_BEARER_TOKEN`. Get your bearer token using the curl command in the Prerequisites section.
```
docker run -i --rm --platform=linux/amd64 \
-e OCEAN__EVENT_LISTENER='{"type":"ONCE"}' \
-e OCEAN__INITIALIZE_PORT_RESOURCES=true \
-e OCEAN__SEND_RAW_DATA_EXAMPLES=true \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="https://management.azure.com" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="bearer_token" \
-e OCEAN__INTEGRATION__CONFIG__API_TOKEN="YOUR_BEARER_TOKEN" \
-e OCEAN__PORT__CLIENT_ID="YOUR_PORT_CLIENT_ID" \
-e OCEAN__PORT__CLIENT_SECRET="YOUR_PORT_CLIENT_SECRET" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
ghcr.io/port-labs/port-ocean-custom:latest
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
## Set up data model[](#set-up-data-model "Direct link to Set up data model")
Before the integration can sync data, you need to create the required blueprints in Port. These blueprints define the data model for your Azure Monitor resources.
**To create the blueprints:**
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Click on the `+ Blueprint` button.
3. Copy and paste each blueprint JSON from the sections below.
**Azure monitor alert blueprint (click to expand)**
Metric alert rules:
Create in Port
```
{
"identifier": "azure-monitor-alert",
"title": "Azure Monitor Alert",
"icon": "Microsoft",
"schema": {
"properties": {
"name": {
"title": "Name",
"type": "string"
},
"description": {
"title": "Description",
"type": "string"
},
"severity": {
"title": "Severity",
"type": "string"
},
"enabled": {
"title": "Enabled",
"type": "boolean"
},
"evaluationFrequency": {
"title": "Evaluation Frequency",
"type": "string"
},
"windowSize": {
"title": "Window Size",
"type": "string"
},
"targetResourceType": {
"title": "Target Resource Type",
"type": "string"
},
"targetResourceRegion": {
"title": "Target Resource Region",
"type": "string"
},
"subscriptionId": {
"title": "Subscription ID",
"type": "string"
},
"resourceGroup": {
"title": "Resource Group",
"type": "string"
},
"createdAt": {
"title": "Created At",
"type": "string",
"format": "date-time"
},
"updatedAt": {
"title": "Updated At",
"type": "string",
"format": "date-time"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**Azure monitor activity log blueprint (click to expand)**
Activity log events:
Create in Port
```
{
"identifier": "azure-monitor-activity-log",
"title": "Azure Monitor Activity Log",
"icon": "Microsoft",
"schema": {
"properties": {
"eventName": {
"title": "Event Name",
"type": "string"
},
"resourceId": {
"title": "Resource ID",
"type": "string"
},
"resourceGroupName": {
"title": "Resource Group Name",
"type": "string"
},
"resourceProviderName": {
"title": "Resource Provider Name",
"type": "string"
},
"status": {
"title": "Status",
"type": "string"
},
"subStatus": {
"title": "Sub Status",
"type": "string"
},
"eventTimestamp": {
"title": "Event Timestamp",
"type": "string",
"format": "date-time"
},
"caller": {
"title": "Caller",
"type": "string"
},
"operationName": {
"title": "Operation Name",
"type": "string"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
## Configuration[](#configuration "Direct link to Configuration")
After installation, define which endpoints to sync in your integration configuration. Each resource maps an API endpoint to Port entities using [JQ expressions](https://stedolan.github.io/jq/manual/) to transform the data.
**Key mapping components:**
* **`kind`**: The API endpoint path (combined with your base URL).
* **`selector.query`**: JQ filter to include/exclude entities (use `'true'` to sync all).
* **`selector.data_path`**: JQ expression pointing to the array of items in the response.
* **`port.entity.mappings`**: How to map API fields to Port entity properties.
For more details on how the no-code Ocean custom integration works, see the [How it works](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview#how-it-works) section in the custom integration overview.
**Azure Monitor API response format:**
Azure Monitor API responses typically follow this structure:
```
{
"value": [
{
"id": "/subscriptions/.../providers/Microsoft.Insights/metricAlerts/alert-name",
"name": "alert-name",
"type": "Microsoft.Insights/metricAlerts",
"properties": {
"description": "Alert description",
"severity": 2,
"enabled": true,
...
}
}
]
}
```
The actual data array is in the `.value` property.
**To configure the mappings:**
1. Go to your [connectors page](https://app.port.io/settings/data-sources).
2. Find your Azure Monitor integration in the list.
3. Click on the integration to open the mapping editor.
4. Add the resource mapping configurations below.
**Metric Alerts mapping (click to expand)**
```
resources:
- kind: /subscriptions/YOUR_SUBSCRIPTION_ID/providers/Microsoft.Insights/metricAlerts
selector:
query: 'true'
data_path: .value
query_params:
api-version: '2018-03-01'
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"azure-monitor-alert"'
properties:
name: .name
description: .properties.description
severity: .properties.severity
enabled: .properties.enabled
evaluationFrequency: .properties.evaluationFrequency
windowSize: .properties.windowSize
targetResourceType: .properties.targetResourceType
targetResourceRegion: .properties.targetResourceRegion
subscriptionId: (.id | split("/")[2])
resourceGroup: (.properties.scopes[0] | split("/")[4] // "")
createdAt: .properties.createdAt
updatedAt: .properties.updatedAt
```
Subscription ID
Replace `YOUR_SUBSCRIPTION_ID` in the `kind` path with your actual Azure subscription ID.
**Activity Logs mapping (click to expand)**
```
resources:
- kind: /subscriptions/YOUR_SUBSCRIPTION_ID/providers/Microsoft.Insights/eventtypes/management/values
selector:
query: 'true'
data_path: .value
query_params:
api-version: '2015-04-01'
$filter: "eventTimestamp ge '2025-12-01T00:00:00Z'"
port:
entity:
mappings:
identifier: .id
title: .eventName.localizedValue // .operationName.localizedValue
blueprint: '"azure-monitor-activity-log"'
properties:
eventName: .eventName.localizedValue
resourceId: .resourceId
resourceGroupName: .resourceGroupName
resourceProviderName: .resourceProviderName.value
status: .status.localizedValue
subStatus: .subStatus.localizedValue
eventTimestamp: .eventTimestamp
caller: .caller
operationName: .operationName.localizedValue
```
Activity log filtering
Activity logs can be very large and the API requires a date filter. Use the `$filter` query parameter to limit results by date range. The start time cannot be more than 90 days in the past. Replace the date in the filter with a date within the last 90 days.
5. Click `Save` to save the mapping.
## Customization[](#customization "Direct link to Customization")
If you want to customize your setup or test different API endpoints before committing to a configuration, use the [interactive builder](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/build-your-integration).
**The interactive builder helps you:**
1. Test your Azure Monitor API endpoints with live data.
2. Automatically detect the data structure and field types.
3. Generate blueprints and resource mappings tailored to your preferences.
4. Get installation commands with your configuration pre-filled.
Simply provide your Azure Monitor API details, and the builder will generate everything you need to install and create the integration in Port.
## Troubleshooting[](#troubleshooting "Direct link to Troubleshooting")
### Authentication errors[](#authentication-errors "Direct link to Authentication errors")
**Symptom:** 401 "InvalidAuthenticationToken" or "Lifetime validation failed, the token is expired" errors.
**Solution:**
* Access tokens expire after 1 hour
* For production use, implement automatic token refresh or use OAuth2 client credentials flow with automatic token management
* See the [prerequisites](#prerequisites) section for token generation commands.
### API version errors[](#api-version-errors "Direct link to API version errors")
**Symptom:** 400 "Bad Request" errors with API version messages.
**Solution:**
* Azure Monitor API requires the `api-version` query parameter.
* Ensure you include `api-version` in your `query_params` (e.g., `api-version: "2018-03-01"`).
* Check the [Azure Monitor REST API documentation](https://learn.microsoft.com/en-us/rest/api/monitor/) for the correct API version for your endpoint.
### Subscription access errors[](#subscription-access-errors "Direct link to Subscription access errors")
**Symptom:** 403 "Forbidden" or "Authorization failed" errors.
**Solution:**
* Ensure your application has the correct permissions in Azure.
* Verify the subscription ID is correct.
* Check that admin consent has been granted for the API permissions.
* Verify your application has "Reader" role or appropriate permissions on the subscription.
### Activity log size issues[](#activity-log-size-issues "Direct link to Activity log size issues")
**Symptom:** Very large responses or timeouts when fetching activity logs.
**Solution:**
* Use `$filter` query parameter to limit results by date range.
* Consider syncing only recent activity logs (e.g., last 7 days).
* Use pagination if available for the specific endpoint.
* Adjust `scheduledResyncInterval` to sync less frequently.
---
# Datadog

Loading version...
Port's Datadog integration allows you to model Datadog resources in Port and ingest data into them.
Supported resources [Monitor](https://docs.datadoghq.com/api/latest/monitors/#get-all-monitor-details)[Service](https://docs.datadoghq.com/api/latest/service-definition/#get-all-service-definitions)[SLO](https://docs.datadoghq.com/api/latest/service-level-objectives/#get-all-slos)[SLO History](https://docs.datadoghq.com/api/latest/service-level-objectives/#get-an-slos-history)[Service Metric](https://docs.datadoghq.com/api/latest/metrics/#query-timeseries-points)[User](https://docs.datadoghq.com/api/latest/users/#list-all-users)[Role](https://docs.datadoghq.com/api/latest/roles/#list-roles)[Team](https://docs.datadoghq.com/api/latest/teams/#get-all-teams)[Service Dependency](https://docs.datadoghq.com/api/latest/service-dependencies/#get-all-service-dependencies)[Organization](https://docs.datadoghq.com/api/latest/organizations/list-your-managed-organizations/)[Host](https://docs.datadoghq.com/api/latest/hosts/#get-all-hosts-for-your-organization)
## Core support
[Live eventsSee supported resources](#set-up-live-events)
**SLO History**, **Service Metric** and **Service Dependency** resources are not collected out of the box.
Follow the examples [here](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog/examples) to configure blueprints and resource mappings.
## Setup[](#setup "Direct link to Setup")
Choose your preferred installation method below. Not sure which to pick? See the [installation methods overview](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Real-time updates + customizable resync interval
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: monitor
selector:
query: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .name
blueprint: '"datadogMonitor"'
properties:
tags: .tags
monitorType: .type
overallState: .overall_state
thresholds: .thresholds
priority: .priority
createdBy: .creator.email
createdAt: .created
updatedAt: .modified
link: (\"https://app.datadoghq.com/monitors/\" + (.id | tostring))
relations:
owner_team_datadog: .tags | map(select(startswith("team:"))) | unique | map(split(":")[1])
service_datadog: .tags | map(select(startswith("service:"))) | unique | map(split(":")[1])
service:
combinator: '"and"'
rules:
- property: '"datadog_service_id"'
operator: '"in"'
value: .tags | map(select(startswith("service:"))) | unique | map(split(":")[1])
- kind: service
selector:
query: "true"
port:
entity:
mappings:
identifier: .attributes.schema.\"dd-service\"
title: .attributes.schema.\"dd-service\"
blueprint: '"datadogService"'
properties:
application: .attributes.schema.application
languages: .attributes.schema.languages
description: .attributes.schema.description
tags: .attributes.schema.tags
type: .attributes.schema.type
links: (\"https://app.datadoghq.com/services?selectedService=\" + (.attributes.schema.\"dd-service\"))
owners: '[.attributes.schema.contacts[]? | select(.type == "email") | .contact]'
relations:
owner_team_datadog: .team_it_doesnt_work_yet
- kind: slo
selector:
query: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .name
blueprint: '"datadogSlo"'
properties:
tags: .tags
sloType: .type
description: .description
warningThreshold: .warning_threshold
targetThreshold: .target_threshold
createdBy: .creator.email
createdAt: .created_at | todate
updatedAt: .modified_at | todate
link: (\"https://app.datadoghq.com/slo/manage?sp=\" + (\"%5B%7B%22p%22%3A%7B%22id%22%3A%22\" + (.id | tostring) + \"%22%7D%2C%22i%22%3A%22slo-panel%22%7D%5D\"))
relations:
monitors: .monitor_ids | map(tostring)
owner_team_datadog: .monitor_tags + .tags | map(select(startswith("team:"))) | unique | map(split(":")[1])
service_datadog: .monitor_tags + .tags | map(select(startswith("service:"))) | unique | map(split(":")[1])
service:
combinator: '"and"'
rules:
- property: '"datadog_service_id"'
operator: '"in"'
value: .monitor_tags + .tags | map(select(startswith("service:"))) | unique | map(split(":")[1])
- kind: host
selector:
query: '[.sources[] | . as $source | ["azure", "gcp", "gce", "aws"] | contains([$source])] | any(.)'
port:
entity:
mappings:
identifier: .id | tostring
title: .aws_name // .host_name
blueprint: '"datadogCloudResource"'
properties:
up: .up
host_name: .host_name
platform: .meta.platform
is_muted: .is_muted
machine: .meta.machine
description: .description
sources: .sources
cpu_cores: .meta.cpuCores
agent_version: .meta.agent_version
tags: .tags_by_source
- kind: host
selector:
query: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .aws_name // .host_name
blueprint: '"datadogHost"'
properties:
up: .up
host_name: .host_name
platform: .meta.platform
is_muted: .is_muted
machine: .meta.machine
description: .description
sources: .sources
cpu_cores: .meta.cpuCores
agent_version: .meta.agent_version
tags: .tags_by_source
- kind: user
selector:
query: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogUser"'
properties:
email: .attributes.email
handle: .attributes.handle
status: .attributes.status
disabled: .attributes.disabled
verified: .attributes.verified
createdAt: .attributes.created_at | todate
- kind: team
selector:
query: "true"
port:
entity:
mappings:
identifier: .id
title: .id
blueprint: '"datadogTeam"'
- kind: team
selector:
query: "true"
includeMembers: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogTeam"'
properties:
description: .attributes.description
handle: .attributes.handle
userCount: .attributes.user_count
summary: .attributes.summary
createdAt: .attributes.created_at | todate
relations:
members: if .__members then .__members[].id else [] end
- kind: role
selector:
query: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogRole"'
properties:
createdAt: .attributes.created_at | todate
modifiedAt: .attributes.modified_at | todate
custom: if .attributes.managed == true then false else true end
userCount: .attributes.user_count
```
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
Use the explorer below to view sample payloads and the resulting Port entities for each resource type. For additional resources and advanced configurations, see the [examples page](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog/examples/.md).
MonitorServiceSLOSLO HistoryService MetricUserRoleTeamService DependencyOrganization
Default mappingYAML
```
- kind: monitor
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id | tostring
title: .name
blueprint: '"datadogMonitor"'
properties:
tags: .tags
monitorType: .type
overallState: .overall_state
thresholds: .thresholds
priority: .priority
createdBy: .creator.email
createdAt: .created
updatedAt: .modified
link: (\"https://app.datadoghq.com/monitors/\" + (.id | tostring))
relations:
owner_team_datadog: .tags | map(select(startswith("team:"))) | unique | map(split(":")[1])
service_datadog: .tags | map(select(startswith("service:"))) | unique | map(split(":")[1])
service:
combinator: '"and"'
rules:
- property: '"datadog_service_id"'
operator: '"in"'
value: .tags | map(select(startswith("service:"))) | unique | map(split(":")[1])
```
Sample payloadJSON
```
{
"id":15173866,
"org_id":1000147697,
"type":"query alert",
"name":"A change @webhook-PORT",
"message":"A change has happened",
"tags":[
"app:webserver"
],
"query":"change(avg(last_5m),last_1h):avg:datadog.agent.running{local} by {version,host} > 40",
"options":{
"thresholds":{
"critical":40.0,
"warning":30.0
},
"notify_audit":false,
"include_tags":true,
"new_group_delay":60,
"notify_no_data":false,
"timeout_h":0,
"silenced":{
}
},
"multi":true,
"created_at":1706707941000,
"created":"2024-01-31T13:32:21.270116+00:00",
"modified":"2024-02-02T16:31:40.516062+00:00",
"deleted": null,
"restricted_roles": [
"83659eba-5ce6-11f1-b7ce-da7ad0900002",
"dbd83320-396e-11ef-bf24-da7ad0900002"
],
"priority":5,
"overall_state_modified":"2024-03-08T20:52:46+00:00",
"overall_state":"No Data",
"creator":{
"name":"John Doe",
"email":"john.doe@gmail.com",
"handle":"john.doe@gmail.com",
"id":1001199545
},
"matching_downtimes":[
]
}
```
Port entityJSON
```
{
"identifier": "15173866",
"title": "A change @webhook-PORT",
"icon": "Datadog",
"blueprint": "datadogMonitor",
"team": [],
"properties": {
"tags": [
"app:webserver"
],
"overallState": "No Data",
"priority": "5",
"createdAt": "2024-01-31T13:32:21.270116+00:00",
"updatedAt": "2024-02-02T16:31:40.516062+00:00",
"createdBy": "john.doe@gmail.com",
"monitorType": "query alert"
},
"relations": {},
"createdAt": "2024-05-29T09:43:34.750Z",
"createdBy": "",
"updatedAt": "2024-05-29T09:43:34.750Z",
"updatedBy": ""
}
```
Default mappingYAML
```
- kind: service
selector:
query: 'true'
port:
entity:
mappings:
identifier: .attributes.schema.\"dd-service\"
title: .attributes.schema.\"dd-service\"
blueprint: '"datadogService"'
properties:
application: .attributes.schema.application
languages: .attributes.schema.languages
description: .attributes.schema.description
tags: .attributes.schema.tags
type: .attributes.schema.type
links: (\"https://app.datadoghq.com/services?selectedService=\" + (.attributes.schema.\"dd-service\"))
owners: '[.attributes.schema.contacts[]? | select(.type == "email") | .contact]'
relations:
owner_team_datadog: .team_it_doesnt_work_yet
```
Sample payloadJSON
```
{
"type":"service-definition",
"id":"04fbab48-a233-4592-8c53-d1bfe282e6c3",
"attributes":{
"meta":{
"last-modified-time":"2024-05-29T10:31:06.833444245Z",
"github-html-url":"",
"ingestion-source":"api",
"origin":"unknown",
"origin-detail":"",
"warnings":[
{
"keyword-location":"/properties/integrations/properties/opsgenie/properties/service-url/pattern",
"instance-location":"/integrations/opsgenie/service-url",
"message":"does not match pattern '^(https?://)?[a-zA-Z\\\\d_\\\\-.]+\\\\.opsgenie\\\\.com/service/([a-zA-Z\\\\d_\\\\-]+)/?$'"
},
{
"keyword-location":"/properties/integrations/properties/pagerduty/properties/service-url/pattern",
"instance-location":"/integrations/pagerduty/service-url",
"message":"does not match pattern '^(https?://)?[a-zA-Z\\\\d_\\\\-.]+\\\\.pagerduty\\\\.com/service-directory/(P[a-zA-Z\\\\d_\\\\-]+)/?$'"
}
],
"ingested-schema-version":"v2.1"
},
"schema":{
"schema-version":"v2.2",
"dd-service":"inventory-management",
"team":"Inventory Management Team",
"application":"Inventory System",
"tier":"Tier 1",
"description":"Service for managing product inventory and stock levels.",
"lifecycle":"production",
"contacts":[
{
"name":"Inventory Team",
"type":"email",
"contact":"inventory-team@example.com"
},
{
"name":"Warehouse Support",
"type":"email",
"contact":"warehouse-support@example.com"
}
],
"links":[
{
"name":"Repository",
"type":"repo",
"provider":"GitHub",
"url":"https://github.com/example/inventory-service"
},
{
"name":"Runbook",
"type":"runbook",
"provider":"Confluence",
"url":"https://wiki.example.com/runbooks/inventory-service"
}
],
"tags":[
"inventory",
"stock"
],
"integrations":{
"pagerduty":{
"service-url":"https://pagerduty.com/services/inventory"
},
"opsgenie":{
"service-url":"https://opsgenie.com/services/inventory",
"region":"US"
}
},
"extensions":{
"qui_6":{
}
}
}
}
}
}
```
Port entityJSON
```
{
"identifier": "inventory-management",
"title": "inventory-management",
"icon": "Datadog",
"blueprint": "datadogService",
"team": [],
"properties": {
"owners": [
"inventory-team@example.com",
"warehouse-support@example.com"
],
"links": [
"https://github.com/example/inventory-service",
"https://wiki.example.com/runbooks/inventory-service"
],
"description": "Service for managing product inventory and stock levels.",
"tags": [
"inventory",
"stock"
],
"application": "Inventory System"
},
"relations": {},
"createdAt": "2024-05-29T10:31:44.283Z",
"createdBy": "",
"updatedAt": "2024-05-29T10:31:44.283Z",
"updatedBy": ""
}
```
Default mappingYAML
```
- kind: slo
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id | tostring
title: .name
blueprint: '"datadogSlo"'
properties:
tags: .tags
sloType: .type
description: .description
warningThreshold: .warning_threshold
targetThreshold: .target_threshold
createdBy: .creator.email
createdAt: .created_at | todate
updatedAt: .modified_at | todate
link: (\"https://app.datadoghq.com/slo/manage?sp=\" + (\"%5B%7B%22p%22%3A%7B%22id%22%3A%22\" + (.id | tostring) + \"%22%7D%2C%22i%22%3A%22slo-panel%22%7D%5D\"))
relations:
monitors: .monitor_ids | map(tostring)
owner_team_datadog: .monitor_tags + .tags | map(select(startswith("team:"))) | unique | map(split(":")[1])
service_datadog: .monitor_tags + .tags | map(select(startswith("service:"))) | unique | map(split(":")[1])
service:
combinator: '"and"'
rules:
- property: '"datadog_service_id"'
operator: '"in"'
value: .monitor_tags + .tags | map(select(startswith("service:"))) | unique | map(split(":")[1])
```
Sample payloadJSON
```
{
"id":"b6869ae6189d59baa421feb8b437fe9e",
"name":"Availability SLO for shopping-cart service",
"tags":[
"service:shopping-cart",
"env:none"
],
"monitor_tags":[
],
"thresholds":[
{
"timeframe":"7d",
"target":99.9,
"target_display":"99.9"
}
],
"type":"monitor",
"type_id":0,
"description":"This SLO tracks the availability of the shopping-cart service. Availability is measured as the number of successful requests divided by the number of total requests for the service",
"timeframe":"7d",
"target_threshold":99.9,
"monitor_ids":[
15173866,
15216083,
15254771
],
"creator":{
"name":"John Doe",
"handle":"john.doe@gmail.com",
"email":"john.doe@gmail.com"
},
"created_at":1707215619,
"modified_at":1707215619
}
```
Port entityJSON
```
{
"identifier": "b6869ae6189d59baa421feb8b437fe9e",
"title": "Availability SLO for shopping-cart service",
"icon": "Datadog",
"blueprint": "datadogSlo",
"team": [],
"properties": {
"description": "This SLO tracks the availability of the shopping-cart service. Availability is measured as the number of successful requests divided by the number of total requests for the service",
"updatedAt": "2024-02-06T10:33:39Z",
"createdBy": "ahosea15@gmail.com",
"sloType": "monitor",
"targetThreshold": "99.9",
"tags": [
"service:shopping-cart",
"env:none"
],
"createdAt": "2024-02-06T10:33:39Z"
},
"relations": {
"monitors": [
"15173866",
"15216083",
"15254771"
],
"services": [
"shopping-cart"
]
},
"createdAt": "2024-05-29T09:43:51.946Z",
"createdBy": "",
"updatedAt": "2024-05-29T12:02:01.559Z",
"updatedBy": ""
}
```
Default mappingYAML
```
- kind: sloHistory
selector:
query: "true"
timeframe: 7
periodOfTimeInMonths: 6
port:
entity:
mappings:
identifier: .slo.id | tostring
title: .slo.name
blueprint: '"datadogSloHistory"'
properties:
monitory_type: .type
sampling_start_date: .from_ts | todate
sampling_end_date: .to_ts | todate
sliValue: .overall.sli_value
relations:
slo: .slo.id
```
Sample payloadJSON
```
{
"thresholds": {
"7d": {
"timeframe": "7d",
"target": 99,
"target_display": "99."
}
},
"from_ts": 1719254776,
"to_ts": 1719859576,
"type": "monitor",
"type_id": 0,
"slo": {
"id": "5ec82408e83c54b4b5b2574ee428a26c",
"name": "Host {{host.name}} with IP {{host.ip}} is not having enough memory",
"tags": [
"p69hx03",
"pages-laptop"
],
"monitor_tags": [],
"thresholds": [
{
"timeframe": "7d",
"target": 99,
"target_display": "99."
}
],
"type": "monitor",
"type_id": 0,
"description": "Testing SLOs from DataDog",
"timeframe": "7d",
"target_threshold": 99,
"monitor_ids": [
147793
],
"creator": {
"name": "John Doe",
"handle": "janesmith@gmail.com",
"email": "janesmith@gmail.com"
},
"created_at": 1683878238,
"modified_at": 1684773765
},
"overall": {
"name": "Host {{host.name}} with IP {{host.ip}} is not having enough memory",
"preview": false,
"monitor_type": "query alert",
"monitor_modified": 1683815332,
"errors": null,
"span_precision": 2,
"history": [
[
1714596313,
1
]
],
"uptime": 3,
"sli_value": 10,
"precision": {
"custom": 2,
"7d": 2
},
"corrections": [],
"state": "breached"
}
}
```
Port entityJSON
```
{
"identifier": "5ec82408e83c54b4b5b2574ee428a26c",
"title": "Host {{host.name}} with IP {{host.ip}} is not having enough memory",
"icon": "Datadog",
"blueprint": "datadogSloHistory",
"team": [],
"properties": {
"sampling_end_date": "2024-07-01T18:46:16Z",
"sliValue": 10,
"sampling_start_date": "2024-06-24T18:46:16Z"
},
"relations": {
"slo": "5ec82408e83c54b4b5b2574ee428a26c"
},
"createdAt": "2024-07-01T09:43:51.946Z",
"createdBy": "",
"updatedAt": "2024-07-01T12:02:01.559Z",
"updatedBy": ""
}
```
Default mappingYAML
```
- kind: serviceMetric
selector:
query: "true"
datadogSelector:
metric: "avg:system.mem.used"
env:
tag: env
value: "*"
service:
tag: servicename
value: "*"
timeframe: 10
port:
entity:
mappings:
blueprint: '"datadogServiceMetric"'
identifier: .__query_id
title: .query
properties:
query: .__query
series: .series
res_type: .res_type
from_date: ".from_date / 1000 | todate"
to_date: ".to_date / 1000 | todate"
env: .__env
relations:
service: .__service
- kind: serviceMetric
selector:
query: "true"
datadogSelector:
metric: "avg:system.disk.used"
env:
tag: env
value: "prod"
service:
tag: servicename
value: "*"
timeframe: 5
port:
entity:
mappings:
blueprint: '"datadogServiceMetric"'
identifier: .__query_id
title: .query
properties:
query: .__query
series: .series
res_type: .res_type
from_date: ".from_date / 1000 | todate"
to_date: ".to_date / 1000 | todate"
env: .__env
relations:
service: .__service
```
Sample payloadJSON
Response Enrichment
The Datadog response is enriched with a variety of metadata fields, including:
* `__service`: The name or identifier of the service generating the data.
* `__query_id`: A unique identifier for the query that generated the data.
* `__query`: The original query used to retrieve the data.
* `__env`: The environment associated with the data (e.g., production, staging).
This enrichment significantly enhances the usability of the Datadog response by providing valuable context and facilitating easier analysis and troubleshooting.
```
{
"status": "ok",
"res_type": "time_series",
"resp_version": 1,
"query": "avg:system.mem.used{service:inventory-management,env:staging}",
"from_date": 1723796537000,
"to_date": 1723797137000,
"series": [
{
"unit": [
{
"family": "bytes",
"id": 2,
"name": "byte",
"short_name": "B",
"plural": "bytes",
"scale_factor": 1.0
}
],
"query_index": 0,
"aggr": "avg",
"metric": "system.mem.used",
"tag_set": [],
"expression": "avg:system.mem.used{env:staging,service:inventory-management}",
"scope": "env:staging,service:inventory-management",
"interval": 2,
"length": 39,
"start": 1723796546000,
"end": 1723797117000,
"pointlist": [
[1723796546000.0, 528986112.0],
[1723796562000.0, 531886080.0],
[1723796576000.0, 528867328.0],
[1723796592000.0, 522272768.0],
[1723796606000.0, 533704704.0],
[1723796846000.0, 533028864.0],
[1723796862000.0, 527417344.0],
[1723796876000.0, 531513344.0],
[1723796892000.0, 533577728.0],
[1723796906000.0, 533471232.0],
[1723796922000.0, 528125952.0],
[1723796936000.0, 530542592.0],
[1723796952000.0, 530767872.0],
[1723796966000.0, 526966784.0],
[1723796982000.0, 528560128.0],
[1723796996000.0, 530792448.0],
[1723797012000.0, 527384576.0],
[1723797026000.0, 529534976.0],
[1723797042000.0, 521650176.0],
[1723797056000.0, 531001344.0],
[1723797072000.0, 525955072.0],
[1723797086000.0, 529469440.0],
[1723797102000.0, 532279296.0],
[1723797116000.0, 526979072.0]
],
"display_name": "system.mem.used",
"attributes": {}
}
],
"values": [],
"times": [],
"message": "",
"group_by": [],
"__service": "inventory-management",
"__query_id": "avg:system.mem.used/service:inventory-management/env:staging",
"__query": "avg:system.mem.used",
"__env": "staging"
}
```
Port entityJSON
```
{
"identifier": "avg:system.disk.used/service:inventory-management/env:prod",
"title": "avg:system.disk.used{service:inventory-management,env:prod}",
"icon": "Datadog",
"blueprint": "datadogServiceMetric",
"team": [],
"properties": {
"query": "avg:system.disk.used",
"series": [],
"res_type": "time_series",
"from_date": "2024-08-16T07:32:00Z",
"to_date": "2024-08-16T08:02:00Z",
"env": "prod"
},
"relations": {
"service": "inventory-management"
},
"createdAt": "2024-08-15T15:54:36.638Z",
"createdBy": "",
"updatedAt": "2024-08-16T08:02:02.399Z",
"updatedBy": ""
}
```
Default mappingYAML
```
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogUser"'
properties:
email: .attributes.email
handle: .attributes.handle
status: .attributes.status
disabled: .attributes.disabled
verified: .attributes.verified
createdAt: .attributes.created_at | todate
```
Sample payloadJSON
```
{
"type": "users",
"id": "468a7e28-4d70-11ef-9b68-c2d109cdf094",
"attributes": {
"name": "",
"handle": "john.doe@example.com",
"created_at": "2024-07-29T06:03:28.693227+00:00",
"modified_at": "2024-07-29T06:05:30.392353+00:00",
"email": "john.doe@example.com",
"icon": "",
"title": "",
"verified": true,
"service_account": false,
"disabled": false,
"allowed_login_methods": [],
"status": "Active",
"mfa_enabled": false
},
"relationships": {
"roles": {
"data": [
{
"type": "roles",
"id": "dbc3577a-396e-11ef-b12b-da7ad0900002"
}
]
},
"org": {
"data": {
"type": "orgs",
"id": "dbb758e9-396e-11ef-800c-bea43249b5f6"
}
}
}
}
```
Port entityJSON
```
{
"identifier": "1e675d18-b002-11ef-9df4-2a2722803530",
"title": "Matan Grady",
"team": [],
"properties": {
"email": "john.doe@example.com",
"handle": "john.doe@example.com",
"status": "Active",
"disabled": false,
"verified": true
},
"relations": {
"team": []
},
"icon": "Datadog"
}
```
Default mappingYAML
```
- kind: role
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogRole"'
properties:
createdAt: .attributes.created_at | todate
modifiedAt: .attributes.modified_at | todate
custom: if .attributes.managed == true then false else true end
userCount: .attributes.user_count
```
Sample payloadJSON
```
{
"id": "dbc3577a-396e-11ef-b12b-da7ad0900002",
"type": "roles",
"attributes": {
"created_at": "2024-07-03T19:02:56.796169Z",
"managed": true,
"modified_at": "2024-07-03T19:02:56.797067Z",
"name": "Datadog Admin Role",
"team_count": 0,
"user_count": 59
},
"relationships": {
"permissions": {
"data": [
{
"id": "0137c052-2957-11f1-a9fb-da7ad0900002",
"type": "permissions"
}
]
}
}
}
```
Port entityJSON
```
{
"identifier": "dbc3577a-396e-11ef-b12b-da7ad0900002",
"title": "Datadog Admin Role",
"icon": "Datadog",
"blueprint": "datadogRole",
"team": [],
"properties": {
"createdAt": "2024-07-03T19:02:56.796169+00:00",
"modifiedAt": "2024-07-03T19:02:56.797067+00:00",
"custom": false,
"userCount": 59
},
"relations": {}
}
```
Default mappingYAML
```
- kind: team
selector:
query: 'true'
port:
entity:
mappings:
identifier: .id
title: .id
blueprint: '"datadogTeam"'
- kind: team
selector:
query: 'true'
includeMembers: 'true'
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogTeam"'
properties:
description: .attributes.description
handle: .attributes.handle
userCount: .attributes.user_count
summary: .attributes.summary
createdAt: .attributes.created_at | todate
relations:
members: if .__members then .__members[].id else [] end
```
Sample payloadJSON
```
{
"type": "team",
"attributes": {
"description": "",
"modified_at": "2024-12-09T08:44:00.526954+00:00",
"is_managed": false,
"link_count": 0,
"user_count": 3,
"name": "Dummy",
"created_at": "2024-12-09T08:44:00.526949+00:00",
"handle": "Dummy",
"summary": null
},
"relationships": {
"user_team_permissions": {
"links": {
"related": "/api/v2/team/b7c4d123-a981-4b75-cd5b-86e246513f3c/permission-settings"
}
},
"team_links": {
"links": {
"related": "/api/v2/team/b7c4d123-a981-4b75-cd5b-86e246513f3c/links"
}
}
},
"id": "b7c4d123-a981-4b75-cd5b-86e246513f3c",
"__members": [
{
"type": "users",
"id": "579e8a70-4d70-11ef-b68c-f276c989c0b2",
"attributes": {
"name": "John Doe",
"handle": "john.doe@example.com",
"email": "john.doe@example.com",
"icon": "",
"disabled": false,
"service_account": false
}
}
]
}
```
Port entityJSON
```
{
"identifier": "b7c4d123-a981-4b75-cd5b-86e246513f3c",
"title": "Dummy",
"team": [],
"properties": {
"description": "",
"handle": "Dummy",
"userCount": 3
},
"relations": {
"members": [
"579e8a70-4d70-11ef-b68c-f276c989c0b2"
]
},
"icon": "Datadog"
}
```
Default mappingYAML
```
- kind: serviceDependency
selector:
query: 'true'
environment: 'dev'
startTime: 1
port:
entity:
mappings:
identifier: .name | tostring
title: .name
blueprint: '"datadogServiceDependency"'
properties:
sourceService: .name
relations:
dependencies: '[.calls[] | tostring]'
```
Sample payloadJSON
```
{
"service_a": {
"calls": [
"service_b",
"service_c"
]
},
"service_b": {
"calls": [
"service_o"
]
},
"service_c": {
"calls": [
"service_o"
]
},
"service_o": {
"calls": []
}
}
```
Port entityJSON
```
{
"identifier": "service_a",
"title": "Dummy",
"icon": "Datadog",
"relations": {
"dependencies": [
"service_b",
"service_c"
]
}
}
```
Default mappingYAML
```
resources:
- kind: organization
selector:
query: 'true'
port:
entity:
mappings:
identifier: .public_id | tostring
title: .name
blueprint: '"datadogOrganization"'
properties:
name: .name
description: .description
created: .created | gsub(" "; "T") | . + "Z"
setting: .settings
```
Sample payloadJSON
```
{
"public_id": "ad50beeb-64d6-11f1-8f1b-22b858bbc981",
"name": "Port integrations demo",
"description": null,
"created": "2026-06-10 14:14:21",
"subscription": {
"id": null,
"billing_plan_id": 0,
"started": 1781100863,
"expires": 1782396863,
"finished": null,
"type": "trial",
"is_custom": false,
"is_trial": true,
"is_expired": false
},
"billing": {
"type": "unavailable"
},
"settings": {
"default_landing_page": "Get Started",
"saml": {
"enabled": false
},
"saml_can_be_enabled": false,
"saml_login_url": null,
"saml_idp_metadata_uploaded": false,
"saml_idp_endpoint": null,
"saml_idp_metadata_valid_until": null,
"custom_landing_page": null,
"saml_idp_initiated_login": {
"enabled": false
},
"saml_strict_mode": {
"enabled": false
},
"saml_autocreate_access_role": "st",
"saml_autocreate_users_domains": {
"enabled": false,
"domains": []
},
"private_widget_share": false,
"manage_reports": "false"
}
}
```
Port entityJSON
```
{
"identifier": "ad50beeb-64d6-11f1-8f1b-22b858bbc981",
"title": "Port integrations demo",
"blueprint": "datadog_organization",
"properties": {
"name": "Port integrations demo",
"description": null,
"created": "2026-06-10T14:14:21Z",
"setting": {
"saml": {
"enabled": false
},
"manage_reports": "false",
"saml_strict_mode": {
"enabled": false
},
"saml_can_be_enabled": false,
"default_landing_page": "Get Started",
"private_widget_share": false,
"saml_idp_initiated_login": {
"enabled": false
},
"saml_idp_metadata_uploaded": false,
"saml_autocreate_access_role": "st",
"saml_autocreate_users_domains": {
"domains": [],
"enabled": false
}
}
},
"relations": {},
"createdAt": "2026-06-18T17:29:13.938Z",
"createdBy": "YmYqw8lGnF6zDB0fQfNDb3nKgLO84I32",
"updatedAt": "2026-06-18T17:29:13.938Z",
"updatedBy": "YmYqw8lGnF6zDB0fQfNDb3nKgLO84I32"
}
```
Service definitions vs APM services
Port's Datadog integration syncs **Service** entities from [service definitions](https://docs.datadoghq.com/api/latest/service-definition/#get-all-service-definitions) in the Datadog Service Catalog API (via the `GET /api/v2/services/definitions` endpoint).
That is separate from [APM services](https://docs.datadoghq.com/tracing/services/service_page/), which Datadog discovers automatically from APM tracing. The integration **does not** fetch APM-discovered services.
## Set up live events[](#set-up-live-events "Direct link to Set up live events")
* Hosted by Port
* Self-hosted
The Datadog integration keeps your catalog up to date in near real time through two complementary channels. Both are available for all installation methods.
The two channels carry different event types and are not interchangeable. Configure both for full coverage:
| Channel | Carries |
| ------------------------- | ---------------------------------------------------------------------------------------------------- |
| 1. Monitor notifications | Monitor **state transitions** (for example `OK` → `Alert` → `OK`) and service dependency updates |
| 2. Audit trail forwarding | **Configuration** changes to monitors, SLOs, users, roles and teams, plus restriction policy changes |
Monitor state transitions are only available through channel 1
The Datadog audit trail records user and API initiated actions, so a monitor changing state on its own does not appear in it. The `overallState` property on your monitor entities is therefore updated in real time only through channel 1; with channel 2 alone it refreshes on the next scheduled resync.
### Live events base URL
For integrations installed using the **Hosted by Port** method, you can obtain the live events base URL from the [Get an integration](/api-reference/get-an-integration/) API. The response includes `liveEventsUuid` and `liveEventsIngestHostname` in the `appSpec` section.
Call the endpoint with your integration's identifier:
```
curl -X GET \
'https://api.port.io/v1/integration/' \
-H 'Authorization: Bearer '
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
In the response, look for the following fields under `spec.appSpec`:
```
{
"spec": {
"appSpec": {
"liveEventsUuid": "abcdefghijk",
"liveEventsIngestHostname": "ingest.ocean.getport.io"
}
}
}
```
Combine them to build the live events base URL:
```
https:///live-events/
```
For example, with the values above, the live events base URL is:
```
https://ingest.ocean.getport.io/live-events/abcdefghijk
```
This is the same URL configured for the integration.
### 1. Monitor notifications (automatic)
When the integration starts, it automatically registers a Datadog webhook and creates a monitor notification rule. Any monitor matching the configured scope sends state change events directly to Port - no manual setup required.
Required application key permissions
To register these objects automatically, the Datadog application key used by the integration must have the following permissions:
| Permission | Used for |
| ----------------------------- | ---------------------------------------------- |
| `integrations_read` | Read existing webhook configuration |
| `create_webhooks` | Create the Port webhook |
| `manage_integrations` | Update the Port webhook |
| `monitors_read` | List existing notification rules |
| `monitor_config_policy_write` | Create or update the monitor notification rule |
The following monitor alert types are supported: `ci_pipelines_alert`, `ci_tests_alert`, `composite_monitor`, `error_tracking_alert`, `event_alert`, `event_v2_alert`, `log_alert`, `monitor_slo_alert`, `metric_slo_alert`, `outlier_monitor`, `process_alert`, `query_alert_monitor`, `rum_alert`, `service_check`, `synthetics_alert`, `trace_analytics_alert`.
Use the `monitorNotificationRuleScope` configuration parameter to control which monitors trigger notifications (default: `service:*`, which captures all service monitors).
Example values:
* `service:*` - all service monitors (default).
* `service:my-service AND env:prod` - monitors for a specific service and environment only.
Note that the default scope only matches monitors carrying a `service` tag. If your monitors are tagged differently, widen the scope accordingly, or those monitors will not send state change events to Port.
#### Manual registration (optional)
The webhook and the notification rule can also be created by a Datadog administrator rather than by the integration. The integration consumes the resulting events either way - automatic registration is a convenience, not a requirement.
You might prefer manual registration if you:
* manage Datadog resources as code, or through a change management process
* want explicit control over the naming, scope, and lifecycle of both objects
* want to reuse an existing webhook or notification rule instead of having a second one created
* cannot grant the application key the write permissions listed above, for example under a read-only credential policy
Automatic registration is the only part being replaced. You still need a live events base URL configured, and the application key still needs read access to monitors so the integration can fetch each monitor when an event arrives.
**Registration steps (click to expand)**
**Step 1: Create the webhook in Datadog**
1. In Datadog, go to **Integrations** > **Webhooks**.
2. Click **New Webhook** and fill in the following:
* **Name**: Any name you choose. Note it down - you will reference it in the next step.
* **URL**:
Append `/integration/webhook/monitor-events` to your [live events base URL](#live-events-base-url).
* **Payload**: Enable **Encode as JSON** and enter the payload below exactly as shown.
* **Custom headers**: If you have set a `webhookSecret`, add the following, replacing `` with its value. Skip this if you have not set a webhook secret.
```
{"X-Port-Ocean-Webhook-Secret": ""}
```
3. Save the webhook.
The payload template:
```
{
"id": "$ID",
"message": "$TEXT_ONLY_MSG",
"priority": "$PRIORITY",
"last_updated": "$LAST_UPDATED",
"event_type": "$EVENT_TYPE",
"event_url": "$LINK",
"service": "$HOSTNAME",
"service_id": "$SERVICE_ID",
"service_name": "$SERVICE_NAME",
"creator": "$USER",
"title": "$EVENT_TITLE",
"date": "$DATE",
"org_id": "$ORG_ID",
"org_name": "$ORG_NAME",
"alert_id": "$ALERT_ID",
"alert_metric": "$ALERT_METRIC",
"alert_status": "$ALERT_STATUS",
"alert_title": "$ALERT_TITLE",
"alert_type": "$ALERT_TYPE",
"tags": "$TAGS",
"body": "$EVENT_MSG"
}
```
Use the payload exactly as shown
Events missing `event_type` or `alert_id` are discarded, as are events missing `org_name` in multi-organization installations. Discards are silent, so an altered payload is difficult to diagnose.
**Step 2: Create the monitor notification rule**
1. In Datadog, go to **Monitors** > **Settings** > **Notification Rules**.
2. Create a new rule and add the webhook from step 1 as a recipient. Webhook recipients take the form `@webhook-`, where `` is the webhook name from step 1.
3. Set the rule's scope to match the monitors you want to send state change events to Port.
4. Save the rule.
Alternatively, add `@webhook-` to the notification message of each individual monitor you want covered. A notification rule is usually preferable, since it applies to many monitors at once.
**Step 3: Disable automatic registration**
Set the `skipWebhookCreation` configuration parameter to `true` (`integration.config.skipWebhookCreation` for Helm installations), so the integration no longer attempts automatic registration on startup. It continues to receive and process live events normally.
### 2. Audit trail forwarding (manual setup required)
The integration processes Datadog audit trail events to reflect near-real-time changes to monitors, users, teams, SLOs, and roles in your catalog.
| Catalog entity | Datadog audit event |
| -------------- | -------------------------------------- |
| Monitor | Monitor |
| Monitor | Access Management (restriction policy) |
| SLO | SLO |
| SLO | Access Management (restriction policy) |
| User | Access Management |
| Role | Access Management |
| Team | Teams Management |
Manual setup required
Datadog does not support managing audit trail forwarding destinations via its API. You must configure this destination manually in the Datadog UI, as described below.
**To configure audit trail forwarding in Datadog:**
1. In Datadog, go to **Organization Settings** > **Compliance** > **Audit Trail Settings**.
2. Under **Forward Audit Events** > **Custom Destinations**, click **New Destination**.
3. Choose **HTTP** as the destination type and fill in the following:
* **Destination URL**:
Append `/integration/webhook/audit-trail` to your [live events base URL](#live-events-base-url).
* **Query filter**: Enter the following query so that only events this integration handles are forwarded:
```
@asset.type:(monitor OR slo) OR @evt.name:("Access Management" OR "Teams Management")
```
* **Authentication**: Select **Request Header** and provide:
* **Header name**: `X-Port-Ocean-Webhook-Secret`
* **Header value**: The value of your `webhookSecret` configuration. If you have not set a webhook secret, enter any random string - Datadog requires a non-empty value, and the integration will accept all requests regardless.
* **Enable GZIP compression for payloads**: Disable this option. It is enabled by default, but the integration expects uncompressed payloads.
4. Save the destination.
### BaseUrl & webhook configuration[](#baseurl--webhook-configuration "Direct link to BaseUrl & webhook configuration")
To enable real-time updates of the data in your software catalog, you need to define the `liveEvents.baseUrl` parameter.
This parameter should be set to the URL of your Datadog integration instance, which needs to have the option to setup webhooks via HTTP requests/receive HTTP requests, so ensure the network is configured accordingly.
* **If Datadog and the integration are in the same cluster/network**: Use an internal URL (e.g., a Kubernetes service DNS name).
For Kubernetes deployments, create a service to expose the integration pod and use the service URL as `liveEvents.baseUrl`. If both the source system and integration are in the same cluster, an internal ClusterIP service is sufficient.
* **If Datadog is external to the integration's network**: The integration must be exposed via an ingress, load balancer, or public URL that
Datadog
can reach.
Scaling for high-volume, self-hosted deployments
If you're running high volumes of live events in a self-hosted deployment and want better reliability, event durability, or horizontal scalability, you can optionally set up Port's dedicated live events infrastructure. See [live events at scale](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/live-events/.md#live-events-at-scale) for details.
If `liveEvents.baseUrl` is not provided, the integration will continue to function correctly. In such a configuration, to retrieve the latest information from the target system, the [`scheduledResyncInterval`](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md#scheduled-resync) parameter has to be set, or a manual resync will need to be triggered through Port's UI.
Debugging local integrations
To test webhooks or live event delivery to your local environment, expose your local pod or service to the internet using ngrok (e.g. `ngrok http http://localhost:8000`)
The Datadog integration keeps your catalog up to date in near real time through two complementary channels. Both are available for all installation methods.
The two channels carry different event types and are not interchangeable. Configure both for full coverage:
| Channel | Carries |
| ------------------------- | ---------------------------------------------------------------------------------------------------- |
| 1. Monitor notifications | Monitor **state transitions** (for example `OK` → `Alert` → `OK`) and service dependency updates |
| 2. Audit trail forwarding | **Configuration** changes to monitors, SLOs, users, roles and teams, plus restriction policy changes |
Monitor state transitions are only available through channel 1
The Datadog audit trail records user and API initiated actions, so a monitor changing state on its own does not appear in it. The `overallState` property on your monitor entities is therefore updated in real time only through channel 1; with channel 2 alone it refreshes on the next scheduled resync.
### 1. Monitor notifications (automatic)
When the integration starts, it automatically registers a Datadog webhook and creates a monitor notification rule. Any monitor matching the configured scope sends state change events directly to Port - no manual setup required.
Required application key permissions
To register these objects automatically, the Datadog application key used by the integration must have the following permissions:
| Permission | Used for |
| ----------------------------- | ---------------------------------------------- |
| `integrations_read` | Read existing webhook configuration |
| `create_webhooks` | Create the Port webhook |
| `manage_integrations` | Update the Port webhook |
| `monitors_read` | List existing notification rules |
| `monitor_config_policy_write` | Create or update the monitor notification rule |
The following monitor alert types are supported: `ci_pipelines_alert`, `ci_tests_alert`, `composite_monitor`, `error_tracking_alert`, `event_alert`, `event_v2_alert`, `log_alert`, `monitor_slo_alert`, `metric_slo_alert`, `outlier_monitor`, `process_alert`, `query_alert_monitor`, `rum_alert`, `service_check`, `synthetics_alert`, `trace_analytics_alert`.
Use the `monitorNotificationRuleScope` configuration parameter to control which monitors trigger notifications (default: `service:*`, which captures all service monitors).
Example values:
* `service:*` - all service monitors (default).
* `service:my-service AND env:prod` - monitors for a specific service and environment only.
Note that the default scope only matches monitors carrying a `service` tag. If your monitors are tagged differently, widen the scope accordingly, or those monitors will not send state change events to Port.
#### Manual registration (optional)
The webhook and the notification rule can also be created by a Datadog administrator rather than by the integration. The integration consumes the resulting events either way - automatic registration is a convenience, not a requirement.
You might prefer manual registration if you:
* manage Datadog resources as code, or through a change management process
* want explicit control over the naming, scope, and lifecycle of both objects
* want to reuse an existing webhook or notification rule instead of having a second one created
* cannot grant the application key the write permissions listed above, for example under a read-only credential policy
Automatic registration is the only part being replaced. You still need a live events base URL configured, and the application key still needs read access to monitors so the integration can fetch each monitor when an event arrives.
**Registration steps (click to expand)**
**Step 1: Create the webhook in Datadog**
1. In Datadog, go to **Integrations** > **Webhooks**.
2. Click **New Webhook** and fill in the following:
* **Name**: Any name you choose. Note it down - you will reference it in the next step.
* **URL**:
Append `/integration/webhook/monitor-events` to the base URL you configured in the `liveEvents.baseUrl` Helm parameter.
* **Payload**: Enable **Encode as JSON** and enter the payload below exactly as shown.
* **Custom headers**: If you have set a `webhookSecret`, add the following, replacing `` with its value. Skip this if you have not set a webhook secret.
```
{"X-Port-Ocean-Webhook-Secret": ""}
```
3. Save the webhook.
The payload template:
```
{
"id": "$ID",
"message": "$TEXT_ONLY_MSG",
"priority": "$PRIORITY",
"last_updated": "$LAST_UPDATED",
"event_type": "$EVENT_TYPE",
"event_url": "$LINK",
"service": "$HOSTNAME",
"service_id": "$SERVICE_ID",
"service_name": "$SERVICE_NAME",
"creator": "$USER",
"title": "$EVENT_TITLE",
"date": "$DATE",
"org_id": "$ORG_ID",
"org_name": "$ORG_NAME",
"alert_id": "$ALERT_ID",
"alert_metric": "$ALERT_METRIC",
"alert_status": "$ALERT_STATUS",
"alert_title": "$ALERT_TITLE",
"alert_type": "$ALERT_TYPE",
"tags": "$TAGS",
"body": "$EVENT_MSG"
}
```
Use the payload exactly as shown
Events missing `event_type` or `alert_id` are discarded, as are events missing `org_name` in multi-organization installations. Discards are silent, so an altered payload is difficult to diagnose.
**Step 2: Create the monitor notification rule**
1. In Datadog, go to **Monitors** > **Settings** > **Notification Rules**.
2. Create a new rule and add the webhook from step 1 as a recipient. Webhook recipients take the form `@webhook-`, where `` is the webhook name from step 1.
3. Set the rule's scope to match the monitors you want to send state change events to Port.
4. Save the rule.
Alternatively, add `@webhook-` to the notification message of each individual monitor you want covered. A notification rule is usually preferable, since it applies to many monitors at once.
**Step 3: Disable automatic registration**
Set the `skipWebhookCreation` configuration parameter to `true` (`integration.config.skipWebhookCreation` for Helm installations), so the integration no longer attempts automatic registration on startup. It continues to receive and process live events normally.
### 2. Audit trail forwarding (manual setup required)
The integration processes Datadog audit trail events to reflect near-real-time changes to monitors, users, teams, SLOs, and roles in your catalog.
| Catalog entity | Datadog audit event |
| -------------- | -------------------------------------- |
| Monitor | Monitor |
| Monitor | Access Management (restriction policy) |
| SLO | SLO |
| SLO | Access Management (restriction policy) |
| User | Access Management |
| Role | Access Management |
| Team | Teams Management |
Manual setup required
Datadog does not support managing audit trail forwarding destinations via its API. You must configure this destination manually in the Datadog UI, as described below.
**To configure audit trail forwarding in Datadog:**
1. In Datadog, go to **Organization Settings** > **Compliance** > **Audit Trail Settings**.
2. Under **Forward Audit Events** > **Custom Destinations**, click **New Destination**.
3. Choose **HTTP** as the destination type and fill in the following:
* **Destination URL**:
Append `/integration/webhook/audit-trail` to the base URL you configured in the `liveEvents.baseUrl` Helm parameter.
* **Query filter**: Enter the following query so that only events this integration handles are forwarded:
```
@asset.type:(monitor OR slo) OR @evt.name:("Access Management" OR "Teams Management")
```
* **Authentication**: Select **Request Header** and provide:
* **Header name**: `X-Port-Ocean-Webhook-Secret`
* **Header value**: The value of your `webhookSecret` configuration. If you have not set a webhook secret, enter any random string - Datadog requires a non-empty value, and the integration will accept all requests regardless.
* **Enable GZIP compression for payloads**: Disable this option. It is enabled by default, but the integration expects uncompressed payloads.
4. Save the destination.
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Examples[](#examples "Direct link to Examples")
To view and test the integration's mapping against examples of the third-party API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources). Find the integration in the list of connectors and click on it to open the playground.
Examples of blueprints and the relevant integration configurations can be found on the datadog [examples page](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/datadog/examples/.md)
## Relevant Guides[](#relevant-guides "Direct link to Relevant Guides")
For relevant guides and examples, see the [guides section](https://docs.port.io/guides?tags=Datadog).
---
# Examples
To view and test the integration's mapping against examples of the third-party API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources). Find the integration in the list of connectors and click on it to open the playground.
## Monitor[](#monitor "Direct link to Monitor")
**Monitor blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogMonitor",
"description": "This blueprint represents a datadog monitor",
"title": "Datadog Monitor",
"icon": "Datadog",
"schema": {
"properties": {
"monitorType": {
"type": "string",
"title": "Monitor Type"
},
"tags": {
"type": "array",
"title": "Tags"
},
"overallState": {
"type": "string",
"title": "Overall state",
"enum": [
"Alert",
"Ignored",
"No Data",
"OK",
"Skipped",
"Unknown",
"Warn"
],
"enumColors": {
"Alert": "red",
"Ignored": "darkGray",
"No Data": "lightGray",
"OK": "green",
"Skipped": "yellow",
"Unknown": "purple",
"Warn": "orange"
}
},
"priority": {
"type": "string",
"title": "Priority"
},
"thresholds": {
"type": "object",
"title": "Thresholds"
},
"createdBy": {
"type": "string",
"title": "Creator"
},
"createdAt": {
"title": "Created At",
"type": "string",
"format": "date-time"
},
"updatedAt": {
"title": "Updated At",
"type": "string",
"format": "date-time"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: monitor
selector:
query: "true"
port:
entity:
mappings:
blueprint: '"datadogMonitor"'
identifier: .id | tostring
title: .name
properties:
tags: .tags
monitorType: .type
overallState: .overall_state
thresholds: .thresholds
priority: .priority
createdBy: .creator.email
createdAt: .created
updatedAt: .modified
```
### Restriction policy enrichment[](#restriction-policy-enrichment "Direct link to Restriction policy enrichment")
Set `includeRestrictionPolicy: "true"` in the selector to enrich each resource with its [Datadog restriction policy](https://docs.datadoghq.com/api/latest/restriction-policies/). This adds three custom fields to the raw data:
| Field | Description |
| ---------------------- | --------------------------------------------------------------- |
| `.__restrictionPolicy` | The full restriction policy object, including all bindings. |
| `.__restrictedUsers` | Deduplicated list of user IDs that have access to the resource. |
| `.__restrictedTeams` | Deduplicated list of team IDs that have access to the resource. |
Role IDs are already present in the native payload as `.restricted_roles` without enabling this option.
Performance note
Enrichment requires one extra API call per resource and is disabled by default.
## Service[](#service "Direct link to Service")
**Service blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogService",
"description": "This blueprint represents a Datadog service",
"title": "Datadog Service",
"icon": "Datadog",
"schema": {
"properties": {
"application": {
"title": "Application",
"type": "string"
},
"description": {
"title": "Description",
"type": "string"
},
"tags": {
"type": "array",
"items": {
"type": "string"
},
"title": "Tags"
},
"languages": {
"items": {
"type": "string"
},
"title": "Languages",
"type": "array"
},
"type": {
"title": "Type",
"type": "string",
"enum": [
"web",
"db",
"custom",
"cache",
"function",
"browser",
"mobile"
],
"enumColors": {
"web": "lightGray",
"db": "lightGray",
"custom": "lightGray",
"cache": "lightGray",
"function": "lightGray",
"browser": "lightGray",
"mobile": "lightGray"
}
},
"owners": {
"type": "array",
"title": "Service Owners",
"items": {
"type": "string"
}
},
"links": {
"title": "Service Links",
"type": "array",
"description": "Links to external resources and repositories",
"items": {
"type": "string",
"format": "url"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: service
selector:
query: "true"
port:
entity:
mappings:
blueprint: '"datadogService"'
identifier: .attributes.schema."dd-service"
title: .attributes.schema."dd-service"
properties:
application: .attributes.schema.application
languages: .attributes.schema.languages
description: .attributes.schema.description
tags: .attributes.schema.tags
type: .attributes.schema.type
links: .attributes.schema.links | map(.url)
owners: '[.attributes.schema.contacts[] | select(.type == "email") | .contact]'
```
Service definitions vs APM services
Port's Datadog integration syncs **Service** entities from [service definitions](https://docs.datadoghq.com/api/latest/service-definition/#get-all-service-definitions) in the Datadog Service Catalog API (via the `GET /api/v2/services/definitions` endpoint).
That is separate from [APM services](https://docs.datadoghq.com/tracing/services/service_page/), which Datadog discovers automatically from APM tracing. The integration **does not** fetch APM-discovered services.
## SLO[](#slo "Direct link to SLO")
**SLO blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogSlo",
"description": "This blueprint represents a datadog SLO",
"title": "Datadog SLO",
"icon": "Datadog",
"schema": {
"properties": {
"tags": {
"type": "array",
"title": "Tags"
},
"sloType": {
"title": "Type",
"type": "string"
},
"description": {
"title": "Description",
"type": "string"
},
"warningThreshold": {
"icon": "DefaultProperty",
"title": "Warning Threshold",
"type": "number"
},
"targetThreshold": {
"icon": "DefaultProperty",
"title": "Target Threshold",
"type": "number"
},
"createdAt": {
"title": "Created At",
"type": "string",
"format": "date-time"
},
"updatedAt": {
"title": "Updated At",
"type": "string",
"format": "date-time"
},
"createdBy": {
"title": "Creator",
"type": "string"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {
"sli_average": {
"title": "SLI Average",
"type": "number",
"target": "datadogSloHistory",
"calculationSpec": {
"func": "average",
"averageOf": "total",
"property": "sliValue",
"measureTimeBy": "$createdAt",
"calculationBy": "property"
}
}
},
"relations": {
"monitors": {
"title": "SLO Monitors",
"description": "The monitors tracking this SLO",
"target": "datadogMonitor",
"required": false,
"many": true
},
"services": {
"title": "Services",
"description": "The services tracked by this SLO",
"target": "datadogService",
"required": false,
"many": true
}
}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: slo
selector:
query: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .name
blueprint: '"datadogSlo"'
properties:
tags: .tags
sloType: .type
description: .description
warningThreshold: .warning_threshold
targetThreshold: .target_threshold
createdBy: .creator.email
createdAt: .created_at | todate
updatedAt: .modified_at | todate
relations:
monitors: .monitor_ids | map(tostring)
services: >-
.monitor_tags + .tags | map(select(startswith("service:"))) |
unique | map(split(":")[1])
```
Service Relation
Based on the [best practices for tagging infrastructure](https://www.datadoghq.com/blog/tagging-best-practices/), the default mapping connects SLOs to services using tags that starts with the `service` keyword.
### Restriction policy enrichment[](#restriction-policy-enrichment "Direct link to Restriction policy enrichment")
Set `includeRestrictionPolicy: "true"` in the selector to enrich each resource with its [Datadog restriction policy](https://docs.datadoghq.com/api/latest/restriction-policies/). This adds three custom fields to the raw data:
| Field | Description |
| ---------------------- | --------------------------------------------------------------- |
| `.__restrictionPolicy` | The full restriction policy object, including all bindings. |
| `.__restrictedUsers` | Deduplicated list of user IDs that have access to the resource. |
| `.__restrictedTeams` | Deduplicated list of team IDs that have access to the resource. |
Role IDs are already present in the native payload as `.restricted_roles` without enabling this option.
Performance note
Enrichment requires one extra API call per resource and is disabled by default.
## SLO history[](#slo-history "Direct link to SLO history")
**SLO history blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogSloHistory",
"description": "This blueprint represents a datadog SLO history",
"title": "Datadog SLO History",
"icon": "Datadog",
"schema": {
"properties": {
"monitor_type": {
"icon": "DefaultProperty",
"title": "Type",
"type": "string"
},
"sliValue": {
"icon": "DefaultProperty",
"title": "SLI Value",
"type": "number"
},
"sampling_start_date": {
"icon": "DefaultProperty",
"type": "string",
"title": "Sampling Start Date",
"format": "date-time"
},
"sampling_end_date": {
"icon": "DefaultProperty",
"type": "string",
"title": "Sampling End Date",
"format": "date-time"
}
},
"required": []
},
"mirrorProperties": {
"slo_target": {
"title": "SLO Target",
"path": "slo.targetThreshold"
},
"slo_warning_threshold": {
"title": "SLO Warning Threshold",
"path": "slo.warningThreshold"
}
},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"slo": {
"title": "SLO",
"description": "The SLO to which this history belongs to",
"target": "datadogSlo",
"required": false,
"many": false
}
}
}
```
**Integration configuration (click to expand)**
Configuration Options
The SLO history selector supports two time-related configurations:
* `timeframe`: How many days to look back for each SLO history data point. Must be greater than 0 (default: 7 days)
* `periodOfTimeInMonths`: How far back in time to fetch SLO history. Must be between 1-12 months (default: 6 months)
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: sloHistory
selector:
query: "true"
timeframe: 7
periodOfTimeInMonths: 6
port:
entity:
mappings:
identifier: .slo.id | tostring
title: .slo.name
blueprint: '"datadogSloHistory"'
properties:
monitory_type: .type
sampling_start_date: .from_ts | todate
sampling_end_date: .to_ts | todate
sliValue: .overall.sli_value
relations:
slo: .slo.id
```
## Service Metric[](#service-metric "Direct link to Service Metric")
**Service Metric blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogServiceMetric",
"description": "This blueprint represents a Datadog service metric",
"title": "Datadog Service Metric",
"icon": "Datadog",
"schema": {
"properties": {
"query": {
"type": "string",
"title": "Query",
"description": "The Datadog query used to retrieve this metric"
},
"series": {
"type": "array",
"title": "Series",
"description": "Array containing detailed information about the metric series"
},
"res_type": {
"type": "string",
"title": "Response Type",
"description": "The type of response from the Datadog API"
},
"from_date": {
"type": "string",
"format": "date-time",
"title": "From Date",
"description": "Unix timestamp of the start of the queried time period"
},
"to_date": {
"type": "string",
"format": "date-time",
"title": "To Date",
"description": "Unix timestamp of the end of the queried time period"
},
"env": {
"type": "string",
"title": "Environment",
"description": "The environment of the service"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {
"service": {
"title": "Service",
"description": "The service associated with this query",
"target": "datadogService",
"required": false,
"many": false
}
}
}
```
**Integration configuration (click to expand)**
Configuration Mapping for Flexible Metric Fetching
The `datadogSelector` section within each `serviceMetric` resource demonstrates how to fetch multiple metrics (e.g., `system.mem.used`, `system.disk.used`) from Datadog with a variety of filters. You can control the:
* **Metric:** Specify the exact metric name (e.g., `avg:system.mem.used`)
* **Environment:** Filter by specific environments (e.g., `prod`, or use `*` for all)
* **Service:** Filter by specific services in your [datadog service catalog](https://docs.datadoghq.com/service_catalog/) (use `*` for all)
* **Timeframe:** Define the time range for data retrieval (in minutes)
This configuration allows you to tailor your data fetching to specific needs and scenarios.
**Note**: The `env` and `service` filters let you specify custom tag names in your Datadog account. For example, your service tag could be `servicename`, and your environment tag could be `envt` or `environment`.
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: serviceMetric
selector:
query: "true"
datadogSelector:
metric: "avg:system.mem.used"
env:
tag: env
value: "*"
service:
tag: servicename
value: "*"
timeframe: 10
port:
entity:
mappings:
blueprint: '"datadogServiceMetric"'
identifier: .__query_id
title: .query
properties:
query: .__query
series: .series
res_type: .res_type
from_date: ".from_date / 1000 | todate"
to_date: ".to_date / 1000 | todate"
env: .__env
relations:
service: .__service
- kind: serviceMetric
selector:
query: "true"
datadogSelector:
metric: "avg:system.disk.used"
env:
tag: env
value: "prod"
service:
tag: servicename
value: "*"
timeframe: 5
port:
entity:
mappings:
blueprint: '"datadogServiceMetric"'
identifier: .__query_id
title: .query
properties:
query: .__query
series: .series
res_type: .res_type
from_date: ".from_date / 1000 | todate"
to_date: ".to_date / 1000 | todate"
env: .__env
relations:
service: .__service
```
Service Relation
Based on the [best practices for tagging infrastructure](https://www.datadoghq.com/blog/tagging-best-practices/), the default JQ maps service metrics to services using tags that starts with the `service` keyword
## Users[](#users "Direct link to Users")
**User blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogUser",
"description": "This blueprint represents a Datadog user account. Users can be assigned to teams, granted specific permissions, and can interact with various Datadog features based on their access levels.",
"title": "Datadog User",
"icon": "Datadog",
"schema": {
"properties": {
"email": {
"type": "string",
"format": "email",
"title": "Email",
"description": "The email address associated with the user account"
},
"handle": {
"type": "string",
"title": "Handle",
"description": "The unique handle identifier for the user within Datadog"
},
"status": {
"type": "string",
"title": "Status",
"description": "The current status of the user account (e.g., active, pending, disabled)"
},
"disabled": {
"type": "boolean",
"title": "Disabled",
"description": "Indicates whether the user account is currently disabled"
},
"verified": {
"type": "boolean",
"title": "Verified",
"description": "Indicates whether the user's email address has been verified"
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At",
"description": "The timestamp when the user account was created"
}
},
"required": []
}
}
```
**Integration configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
resources:
- kind: user
selector:
query: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogUser"'
properties:
email: .attributes.email
handle: .attributes.handle
status: .attributes.status
disabled: .attributes.disabled
verified: .attributes.verified
createdAt: .attributes.created_at
```
## Role[](#role "Direct link to Role")
**Role blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogRole",
"description": "This blueprint represents a Datadog role",
"title": "Datadog Role",
"icon": "Datadog",
"schema": {
"properties": {
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At",
"description": "The timestamp when the role was created"
},
"modifiedAt": {
"type": "string",
"format": "date-time",
"title": "Modified At",
"description": "The timestamp when the role was last modified"
},
"custom": {
"type": "boolean",
"title": "Custom role",
"description": "Indicates whether this is a user-defined role. When false, the role is a Datadog built-in role."
},
"userCount": {
"type": "number",
"title": "User Count",
"description": "The total number of users assigned to this role"
}
},
"required": []
}
}
```
**Integration configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
resources:
- kind: role
selector:
query: "true"
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogRole"'
properties:
createdAt: .attributes.created_at
modifiedAt: .attributes.modified_at
custom: if .attributes.managed == true then false else true end
userCount: .attributes.user_count
```
### Enrich roles with their users[](#enrich-roles-with-their-users "Direct link to Enrich roles with their users")
By default, roles are ingested without their associated users. To include them, set `includeUsers: true` in the selector:
```
resources:
- kind: role
selector:
query: "true"
includeUsers: true
```
When enabled, each role's raw data includes an additional field with the list of [users](https://docs.datadoghq.com/api/latest/roles/get-all-users-of-a-role/) assigned to that role:
| Field | Description |
| ---------- | ----------------------------------------------- |
| `.__users` | The list of users that have access to the role. |
Performance impact
This enrichment makes an additional API call for each role, which can slow down the sync. It is disabled by default.
## Team[](#team "Direct link to Team")
**Team blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogTeam",
"description": "This blueprint represents a Datadog team",
"title": "Datadog Team",
"icon": "Datadog",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description",
"description": "A description of the team's purpose and responsibilities"
},
"handle": {
"type": "string",
"title": "Handle",
"description": "The unique handle identifier for the team within Datadog"
},
"userCount": {
"type": "number",
"title": "User Count",
"description": "The total number of users that are members of this team"
},
"summary": {
"type": "string",
"title": "Summary",
"description": "A brief summary of the team's purpose or main responsibilities"
},
"createdAt": {
"type": "string",
"format": "date-time",
"title": "Created At",
"description": "The timestamp when the team was created"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"members": {
"target": "datadogUser",
"title": "Members",
"description": "Users who are members of this team",
"many": true,
"required": false
}
}
}
```
**Integration configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
resources:
- kind: team
selector:
query: 'true'
includeMembers: 'true'
port:
entity:
mappings:
identifier: .id | tostring
title: .attributes.name
blueprint: '"datadogTeam"'
properties:
description: .attributes.description
handle: .attributes.handle
userCount: .attributes.user_count
summary: .attributes.summary
createdAt: .attributes.created_at
relations:
members: if .__members then [.__members[] | .id] else [] end
```
## Service Dependency[](#service-dependency "Direct link to Service Dependency")
**Service Dependency blueprint (click to expand)**
Create in Port
```
{
"identifier": "datadogServiceDependency",
"description": "This blueprint represents a dependency relationship between Datadog services, where one service calls another.",
"title": "Datadog Service Dependency",
"icon": "Datadog",
"schema": {
"properties": {},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"dependencies": {
"title": "Depends on",
"description": "The services called by the source service",
"target": "datadogService",
"required": false,
"many": true
}
}
}
```
**Integration configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
resources:
- kind: serviceDependency
selector:
query: 'true'
environment: 'dev'
startTime: 1
port:
entity:
mappings:
identifier: .name | tostring
title: .name
blueprint: '"datadogServiceDependency"'
properties:
sourceService: .name
relations:
dependencies: '[.calls[] | tostring]'
```
* Include Environment
* Include Start Time
The `environment` selector is crucial for accurately mapping service dependencies from Datadog's Service Map.
Datadog's Service Map visualizes how services interact within a specific environment (e.g., `prod`, `staging`, `dev`). By specifying an `environment` in the selector, you ensure that only the dependencies relevant to that particular environment are fetched and mapped, preventing the inclusion of irrelevant or duplicate dependency information from other environments. By default, this selector is set to `prod`.
```
- kind: serviceDependency
selector:
query: 'true'
environment: 'dev'
startTime: 1
```
The `startTime` selector is crucial for fetching service dependency data from a specific point in time.
This value represents the number of hours to look back from the current time to fetch dependency data. By default, this selector is set to `1` hour.
```
- kind: serviceDependency
selector:
query: 'true'
environment: 'dev'
startTime: 1
```
---
# Dynatrace

Loading version...
Port's Dynatrace integration allows you to model Dynatrace resources in your software catalog and ingest data into them.
Supported resources [Problem](https://docs.dynatrace.com/docs/dynatrace-api/environment-api/problems-v2/problems/get-problems-list#definition--Problem)[Entity](https://docs.dynatrace.com/docs/dynatrace-api/environment-api/entity-v2/get-entities-list#definition--Entity)[SLO](https://docs.dynatrace.com/docs/dynatrace-api/environment-api/service-level-objectives/get-all#definition--SLO)[Team](https://docs.dynatrace.com/docs/discover-dynatrace/references/dynatrace-api/environment-api/settings/objects/get-object)
## Core support
[Live eventsSee supported resources](#configure-real-time-updates)
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
### Generate a Dynatrace API key[](#generate-a-dynatrace-api-key "Direct link to Generate a Dynatrace API key")
1. Navigate to `/ui/apps/dynatrace.classic.tokens/ui/access-tokens`. For example, if you access your Dynatrace instance at `https://npm82883.apps.dynatrace.com`, you should navigate to `https://npm82883.apps.dynatrace.com/ui/apps/dynatrace.classic.tokens/ui/access-tokens`.
2. Click **Generate new token** to create a new token. Ensure the permissions: `DataExport`, `Read entities`, `Read problems`, `Read SLO` and `Read settings` are assigned to the token. The `DataExport` permission allows Dynatrace to perform healthchecks before ingestion starts. The `Read settings` scope allows the integration to ingest teams.
### Construct your Dynatrace Host URL[](#construct-your-dynatrace-host-url "Direct link to Construct your Dynatrace Host URL")
Your Dynatrace host URL should be `https://.live.dynatrace.com`. Note that there is a difference between the instance URL and the API host URL. The former contains `apps` while the latter (as shown prior) uses `live`. This means if your environment ID is `npm82883`, your API host URL should be `https://npm82883.live.dynatrace.com`.
## Setup[](#setup "Direct link to Setup")
Choose one of the following installation methods: Not sure which method is right for your use case? Check the available [installation methods](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port
* ✧Port hosts and manages the integration
* ✧Customizable resync interval for data ingestion
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: entity
selector:
query: 'true'
entityFields: firstSeenTms,lastSeenTms,tags
entityTypes:
- APPLICATION
- SERVICE
port:
entity:
mappings:
identifier: .entityId
title: .displayName
blueprint: '"dynatraceEntity"'
properties:
firstSeen: (.firstSeenTms // 0) / 1000 | todate
lastSeen: (.lastSeenTms // 0) / 1000 | todate
type: .type
tags: '[(.tags // [])[].stringRepresentation]'
- kind: problem
selector:
query: 'true'
port:
entity:
mappings:
identifier: .problemId
title: .title
blueprint: '"dynatraceProblem"'
properties:
entityTags: .entityTags[].stringRepresentation
evidenceDetails: .evidenceDetails.details // [] | .[].displayName
managementZones: .managementZones[].name
problemFilters: .problemFilters[].name
severityLevel: .severityLevel
status: .status
startTime: .startTime / 1000 | todate
endTime: .endTime | if . == -1 then null else (./1000 | todate) end
relations:
impactedEntities: .impactedEntities[].entityId.id
linkedProblemInfo: .linkedProblemInfo.problemId
rootCauseEntity: .rootCauseEntity.entityId.id
- kind: slo
selector:
query: 'true'
attachRelatedEntities: true
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"dynatraceSlo"'
properties:
status: .status
target: .target
enabled: .enabled
warning: .warning
error: .error
errorBudget: .errorBudget
evaluatedPercentage: .evaluatedPercentage
evaluationType: .evaluationType
filter: .filter
relations:
entities: if .__entities != null then .__entities | map(.entityId) else [] end
```
### Ingest additional resource types[](#ingest-additional-resource-types "Direct link to Ingest additional resource types")
By default, the `entity` kind ingests only entities of type `APPLICATION` and `SERVICE` due to the large number of available resources. However, you can configure the `entity` kind mapping to ingest entities of other types.
To do this, use the `entityTypes` selector in the entity mapping like so:
**Mapping configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: entity
selector:
query: "true"
entityTypes: ["APPLICATION", "SERVICE"]
port:
entity:
mappings:
identifier: .entityId
title: .displayName
blueprint: '"dynatraceEntity"'
properties:
firstSeen: ".firstSeenTms / 1000 | todate"
lastSeen: ".lastSeenTms / 1000 | todate"
type: .type
tags: '[(.tags // [])[].stringRepresentation]'
managementZones: .managementZones[].name
properties: .properties
fromRelationships: .fromRelationships
toRelationships: .toRelationships
```
#### Available resource types[](#available-resource-types "Direct link to Available resource types")
You can retrieve a list of available resource types by using the [Dynatrace Entity Types API](https://docs.dynatrace.com/docs/dynatrace-api/environment-api/entity-v2/get-entity-type#definition--EntityType). Below is a list of resource types retrieved from the API:
**Dynatrace entity types (click to expand)**
* `APM_SECURITY_GATEWAY`
* `APPLICATION`
* `APPLICATION_METHOD`
* `APPLICATION_METHOD_GROUP`
* `APPMON_SERVER`
* `APPMON_SYSTEM_PROFILE`
* `AUTO_SCALING_GROUP`
* `AWS_APPLICATION_LOAD_BALANCER`
* `AWS_AVAILABILITY_ZONE`
* `AWS_CREDENTIALS`
* `AWS_LAMBDA_FUNCTION`
* `AWS_NETWORK_LOAD_BALANCER`
* `AZURE_API_MANAGEMENT_SERVICE`
* `AZURE_APPLICATION_GATEWAY`
* `AZURE_APP_SERVICE_PLAN`
* `AZURE_COSMOS_DB`
* `AZURE_CREDENTIALS`
* `AZURE_EVENT_HUB`
* `AZURE_EVENT_HUB_NAMESPACE`
* `AZURE_FUNCTION_APP`
* `AZURE_IOT_HUB`
* `AZURE_LOAD_BALANCER`
* `AZURE_MGMT_GROUP`
* `AZURE_REDIS_CACHE`
* `AZURE_REGION`
* `AZURE_SERVICE_BUS_NAMESPACE`
* `AZURE_SERVICE_BUS_QUEUE`
* `AZURE_SERVICE_BUS_TOPIC`
* `AZURE_SQL_DATABASE`
* `AZURE_SQL_ELASTIC_POOL`
* `AZURE_SQL_SERVER`
* `AZURE_STORAGE_ACCOUNT`
* `AZURE_SUBSCRIPTION`
* `AZURE_TENANT`
* `AZURE_VM`
* `AZURE_VM_SCALE_SET`
* `AZURE_WEB_APP`
* `BOSH_DEPLOYMENT`
* `BROWSER`
* `CF_FOUNDATION`
* `CINDER_VOLUME`
* `CLOUD_APPLICATION`
* `CLOUD_APPLICATION_INSTANCE`
* `CLOUD_APPLICATION_NAMESPACE`
* `CONTAINER_GROUP`
* `CONTAINER_GROUP_INSTANCE`
* `CUSTOM_APPLICATION`
* `CUSTOM_DEVICE`
* `CUSTOM_DEVICE_GROUP`
* `DATASTORE`
* `DCRUM_APPLICATION`
* `DCRUM_SERVICE`
* `DCRUM_SERVICE_INSTANCE`
* `DEVICE_APPLICATION_METHOD`
* `DEVICE_APPLICATION_METHOD_GROUP`
* `DISK`
* `DOCKER_CONTAINER_GROUP`
* `DOCKER_CONTAINER_GROUP_INSTANCE`
* `DYNAMO_DB_TABLE`
* `EBS_VOLUME`
* `EC2_INSTANCE`
* `ELASTIC_LOAD_BALANCER`
* `ENVIRONMENT`
* `EXTERNAL_SYNTHETIC_TEST`
* `EXTERNAL_SYNTHETIC_TEST_STEP`
* `GCP_ZONE`
* `GEOLOCATION`
* `GEOLOC_SITE`
* `GOOGLE_COMPUTE_ENGINE`
* `HOST`
* `HOST_GROUP`
* `HTTP_CHECK`
* `HTTP_CHECK_STEP`
* `HYPERVISOR`
* `HYPERVISOR_CLUSTER`
* `HYPERVISOR_DISK`
* `KUBERNETES_CLUSTER`
* `KUBERNETES_NODE`
* `KUBERNETES_SERVICE`
* `MOBILE_APPLICATION`
* `MULTIPROTOCOL_MONITOR`
* `NETWORK_INTERFACE`
* `NEUTRON_SUBNET`
* `OPENSTACK_AVAILABILITY_ZONE`
* `OPENSTACK_COMPUTE_NODE`
* `OPENSTACK_PROJECT`
* `OPENSTACK_REGION`
* `OPENSTACK_VM`
* `OS`
* `PROCESS_GROUP`
* `PROCESS_GROUP_INSTANCE`
* `QUEUE`
* `QUEUE_INSTANCE`
* `RELATIONAL_DATABASE_SERVICE`
* `RUNTIME_COMPONENT`
* `S3BUCKET`
* `SERVICE`
* `SERVICE_INSTANCE`
* `SERVICE_METHOD`
* `SERVICE_METHOD_GROUP`
* `SOFTWARE_COMPONENT`
* `SWIFT_CONTAINER`
* `SYNTHETIC_LOCATION`
* `SYNTHETIC_TEST`
* `SYNTHETIC_TEST_STEP`
* `VCENTER`
* `VIRTUALMACHINE`
* `VMWARE_DATACENTER`
* `cloud:aws:acmprivateca`
* `cloud:aws:api_gateway`
* `cloud:aws:app_runner`
* `cloud:aws:appstream`
* `cloud:aws:appsync`
* `cloud:aws:athena`
* `cloud:aws:aurora`
* `cloud:aws:autoscaling`
* `cloud:aws:billing`
* `cloud:aws:cassandra`
* `cloud:aws:chatbot`
* `cloud:aws:cloud_front`
* `cloud:aws:cloudhsm`
* `cloud:aws:cloudsearch`
* `cloud:aws:codebuild`
* `cloud:aws:cognito`
* `cloud:aws:connect`
* `cloud:aws:datasync`
* `cloud:aws:dax`
* `cloud:aws:dms`
* `cloud:aws:documentdb`
* `cloud:aws:dxcon`
* `cloud:aws:dynamodb`
* `cloud:aws:ebs`
* `cloud:aws:ec2_spot`
* `cloud:aws:ec2api`
* `cloud:aws:ecs`
* `cloud:aws:ecs:cluster`
* `cloud:aws:efs`
* `cloud:aws:eks:cluster`
* `cloud:aws:elasticache`
* `cloud:aws:elasticbeanstalk`
* `cloud:aws:elasticinference`
* `cloud:aws:elastictranscoder`
* `cloud:aws:emr`
* `cloud:aws:es`
* `cloud:aws:events`
* `cloud:aws:fsx`
* `cloud:aws:gamelift`
* `cloud:aws:glue`
* `cloud:aws:inspector`
* `cloud:aws:iot`
* `cloud:aws:iot_things_graph`
* `cloud:aws:iotanalytics`
* `cloud:aws:kafka`
* `cloud:aws:kinesis:data_analytics`
* `cloud:aws:kinesis:data_firehose`
* `cloud:aws:kinesis:data_stream`
* `cloud:aws:kinesis:video_stream`
* `cloud:aws:lambda`
* `cloud:aws:lex`
* `cloud:aws:logs`
* `cloud:aws:media_tailor`
* `cloud:aws:mediaconnect`
* `cloud:aws:mediaconvert`
* `cloud:aws:mediapackagelive`
* `cloud:aws:mediapackagevod`
* `cloud:aws:mq`
* `cloud:aws:nat_gateway`
* `cloud:aws:neptune`
* `cloud:aws:opsworks`
* `cloud:aws:polly`
* `cloud:aws:qldb`
* `cloud:aws:rds`
* `cloud:aws:redshift`
* `cloud:aws:rekognition`
* `cloud:aws:robomaker`
* `cloud:aws:route53`
* `cloud:aws:route53resolver`
* `cloud:aws:s3`
* `cloud:aws:sage_maker:batch_transform_job`
* `cloud:aws:sage_maker:endpoint`
* `cloud:aws:sage_maker:endpoint_instance`
* `cloud:aws:sage_maker:ground_truth`
* `cloud:aws:sage_maker:processing_job`
* `cloud:aws:sage_maker:training_job`
* `cloud:aws:servicecatalog`
* `cloud:aws:ses`
* `cloud:aws:sns`
* `cloud:aws:sqs`
* `cloud:aws:ssm-runcommand`
* `cloud:aws:states`
* `cloud:aws:storagegateway`
* `cloud:aws:swf`
* `cloud:aws:textract`
* `cloud:aws:transfer`
* `cloud:aws:transitgateway`
* `cloud:aws:translate`
* `cloud:aws:trustedadvisor`
* `cloud:aws:usage`
* `cloud:aws:vpn`
* `cloud:aws:waf`
* `cloud:aws:wafv2`
* `cloud:aws:workmail`
* `cloud:aws:workspaces`
* `cloud:azure:apimanagement:service`
* `cloud:azure:app:containerapps`
* `cloud:azure:app:managedenvironments`
* `cloud:azure:appconfiguration:configurationstores`
* `cloud:azure:appplatform:spring`
* `cloud:azure:automation:automationaccounts`
* `cloud:azure:batch:account`
* `cloud:azure:blockchain:blockchainmembers`
* `cloud:azure:cache:redis`
* `cloud:azure:cdn:cdnwebapplicationfirewallpolicies`
* `cloud:azure:cdn:profiles`
* `cloud:azure:classic_storage_account`
* `cloud:azure:classic_storage_account:blob`
* `cloud:azure:classic_storage_account:file`
* `cloud:azure:classic_storage_account:queue`
* `cloud:azure:classic_storage_account:table`
* `cloud:azure:classic_virtual_machine`
* `cloud:azure:cognitiveservices:allinone`
* `cloud:azure:cognitiveservices:anomalydetector`
* `cloud:azure:cognitiveservices:bingautosuggest`
* `cloud:azure:cognitiveservices:bingcustomsearch`
* `cloud:azure:cognitiveservices:bingentitysearch`
* `cloud:azure:cognitiveservices:bingsearch`
* `cloud:azure:cognitiveservices:bingspellcheck`
* `cloud:azure:cognitiveservices:computervision`
* `cloud:azure:cognitiveservices:contentmoderator`
* `cloud:azure:cognitiveservices:customvisionprediction`
* `cloud:azure:cognitiveservices:customvisiontraining`
* `cloud:azure:cognitiveservices:face`
* `cloud:azure:cognitiveservices:immersivereader`
* `cloud:azure:cognitiveservices:inkrecognizer`
* `cloud:azure:cognitiveservices:luis`
* `cloud:azure:cognitiveservices:luisauthoring`
* `cloud:azure:cognitiveservices:openai`
* `cloud:azure:cognitiveservices:personalizer`
* `cloud:azure:cognitiveservices:qnamaker`
* `cloud:azure:cognitiveservices:speech`
* `cloud:azure:cognitiveservices:textanalytics`
* `cloud:azure:cognitiveservices:translator`
* `cloud:azure:containerinstance:containergroup`
* `cloud:azure:containerregistry:registries`
* `cloud:azure:containerservice:managedcluster`
* `cloud:azure:datafactory:v1`
* `cloud:azure:datafactory:v2`
* `cloud:azure:datalakeanalytics:accounts`
* `cloud:azure:datalakestore:accounts`
* `cloud:azure:datashare:accounts`
* `cloud:azure:devices:iothubs`
* `cloud:azure:devices:provisioningservices`
* `cloud:azure:documentdb:databaseaccounts:global`
* `cloud:azure:documentdb:databaseaccounts:mongo`
* `cloud:azure:eventgrid:domains`
* `cloud:azure:eventgrid:systemtopics`
* `cloud:azure:eventgrid:topics`
* `cloud:azure:eventhub:clusters`
* `cloud:azure:frontdoor`
* `cloud:azure:hdinsight:cluster`
* `cloud:azure:hybridcompute:machines`
* `cloud:azure:insights:components`
* `cloud:azure:iotcentral:iotapps`
* `cloud:azure:keyvault:vaults`
* `cloud:azure:kusto:clusters`
* `cloud:azure:logic:integrationserviceenvironments`
* `cloud:azure:logic:workflows`
* `cloud:azure:machinelearningservices:workspaces`
* `cloud:azure:maps:accounts`
* `cloud:azure:mariadb:server`
* `cloud:azure:media:mediaservices`
* `cloud:azure:media:mediaservices:streamingendpoints`
* `cloud:azure:mysql:flexibleservers`
* `cloud:azure:mysql:server`
* `cloud:azure:netapp:netappaccounts:capacitypools`
* `cloud:azure:netapp:netappaccounts:capacitypools:volumes`
* `cloud:azure:network:applicationgateways`
* `cloud:azure:network:azurefirewalls`
* `cloud:azure:network:dnszones`
* `cloud:azure:network:expressroutecircuits`
* `cloud:azure:network:loadbalancers:basic`
* `cloud:azure:network:loadbalancers:gateway`
* `cloud:azure:network:loadbalancers:standard`
* `cloud:azure:network:networkinterfaces`
* `cloud:azure:network:networkwatchers:connectionmonitors`
* `cloud:azure:network:networkwatchers:connectionmonitors:previe`
* `cloud:azure:network:privatednszones`
* `cloud:azure:network:publicipaddresses`
* `cloud:azure:notificationhubs:namespaces:notificationhubs`
* `cloud:azure:postgresql:flexibleservers`
* `cloud:azure:postgresql:server`
* `cloud:azure:postgresql:serverv2`
* `cloud:azure:powerbidedicated:capacities`
* `cloud:azure:recoveryservices:vaults`
* `cloud:azure:relay:namespaces`
* `cloud:azure:search:searchservices`
* `cloud:azure:servicefabricmesh:applications`
* `cloud:azure:signalrservice:signalr`
* `cloud:azure:sql:managed`
* `cloud:azure:sql:servers`
* `cloud:azure:sql:servers:databases:datawarehouse`
* `cloud:azure:sql:servers:databases:dtu`
* `cloud:azure:sql:servers:databases:hyperscale`
* `cloud:azure:sql:servers:databases:vcore`
* `cloud:azure:sql:servers:elasticpools:dtu`
* `cloud:azure:sql:servers:elasticpools:vcore`
* `cloud:azure:storage:storageaccounts`
* `cloud:azure:storage:storageaccounts:blob`
* `cloud:azure:storage:storageaccounts:file`
* `cloud:azure:storage:storageaccounts:queue`
* `cloud:azure:storage:storageaccounts:table`
* `cloud:azure:storagesync:storagesyncservices`
* `cloud:azure:streamanalytics:streamingjobs`
* `cloud:azure:synapse:workspaces`
* `cloud:azure:synapse:workspaces:bigdatapools`
* `cloud:azure:synapse:workspaces:sqlpools`
* `cloud:azure:timeseriesinsights:environments`
* `cloud:azure:timeseriesinsights:eventsources`
* `cloud:azure:traffic_manager_profile`
* `cloud:azure:virtual_network_gateway`
* `cloud:azure:web:appslots`
* `cloud:azure:web:functionslots`
* `cloud:azure:web:hostingenvironments:v2`
* `cloud:azure:web:serverfarms`
* `cloud:gcp:autoscaler`
* `cloud:gcp:bigquery_biengine_model`
* `cloud:gcp:cloud_function`
* `cloud:gcp:cloud_run_revision`
* `cloud:gcp:cloudsql_database`
* `cloud:gcp:filestore_instance`
* `cloud:gcp:gae_app`
* `cloud:gcp:gce_instance`
* `cloud:gcp:gcs_bucket`
* `cloud:gcp:https_lb`
* `cloud:gcp:instance_group`
* `cloud:gcp:internal_http_lb_rule`
* `cloud:gcp:internal_network_lb_rule`
* `cloud:gcp:k8s_cluster`
* `cloud:gcp:k8s_container`
* `cloud:gcp:k8s_node`
* `cloud:gcp:k8s_pod`
* `cloud:gcp:network_lb_rule`
* `cloud:gcp:project`
* `cloud:gcp:pubsub_snapshot`
* `cloud:gcp:pubsub_subscription`
* `cloud:gcp:pubsub_topic`
* `cloud:gcp:pubsublite_subscription_partition`
* `cloud:gcp:pubsublite_topic_partition`
* `cloud:gcp:tcp_ssl_proxy_rule`
* `cloud:gcp:tpu_worker`
* `os:service`
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
EntityProblemSLOTeam
Default mappingYAML
```
- kind: entity
selector:
query: 'true'
entityFields: firstSeenTms,lastSeenTms,tags
entityTypes:
- APPLICATION
- SERVICE
port:
entity:
mappings:
identifier: .entityId
title: .displayName
blueprint: '"dynatraceEntity"'
properties:
firstSeen: (.firstSeenTms // 0) / 1000 | todate
lastSeen: (.lastSeenTms // 0) / 1000 | todate
type: .type
tags: '[(.tags // [])[].stringRepresentation]'
```
Sample payloadJSON
```
{
"displayName": "my host",
"entityId": "HOST-06F288EE2A930951",
"firstSeenTms": 1574697667547,
"fromRelationships": {
"isInstanceOf": [
{
"id": "HOST_GROUP-0E489369D663A4BF",
"type": "HOST_GROUP"
}
]
},
"icon": {
"customIconPath": "host",
"primaryIconType": "linux",
"secondaryIconType": "microsoft-azure-signet"
},
"lastSeenTms": 1588242361417,
"managementZones": [
{
"id": "6239538939987181652",
"name": "main app"
}
],
"properties": {
"bitness": 64,
"cpuCores": 8,
"monitoringMode": "FULL_STACK",
"networkZoneId": "aws.us.east01",
"osArchitecture": "X86",
"osType": "LINUX"
},
"tags": [
{
"context": "CONTEXTLESS",
"key": "architecture",
"stringRepresentation": "architecture:x86",
"value": "x86"
},
{
"context": "ENVIRONMENT",
"key": "Infrastructure",
"stringRepresentation": "[ENVIRONMENT]Infrastructure:Linux",
"value": "Linux"
}
],
"toRelationships": {
"isDiskOf": [
{
"id": "DISK-0393340DCA3853B0",
"type": "DISK"
}
]
},
"type": "HOST"
}
```
Port entityJSON
```
{
"identifier": "HOST-06F288EE2A930951",
"title": "my host",
"blueprint": "dynatraceEntity",
"team": [],
"icon": "Dynatrace",
"properties": {
"firstSeen": "2019-11-25T14:14:27Z",
"lastSeen": "2020-04-30T14:52:41Z",
"type": "HOST",
"tags": ["architecture:x86", "[ENVIRONMENT]Infrastructure:Linux"]
},
"relations": {},
"createdAt": "2024-2-6T09:30:57.924Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2024-2-6T11:49:20.881Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| -------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `entityTypes` | `array` | List of Dynatrace entity types to fetch. See [Dynatrace Entity Types API](https://docs.dynatrace.com/docs/dynatrace-api/environment-api/entity-v2/get-all-entity-types) for all available types. Default: `["APPLICATION","SERVICE"]`. |
| `entityFields` | `string` | List of fields to include in each entity |
Default mappingYAML
```
- kind: problem
selector:
query: 'true'
port:
entity:
mappings:
identifier: .problemId
title: .title
blueprint: '"dynatraceProblem"'
properties:
entityTags: .entityTags[].stringRepresentation
evidenceDetails: .evidenceDetails.details // [] | .[].displayName
managementZones: .managementZones[].name
problemFilters: .problemFilters[].name
severityLevel: .severityLevel
status: .status
startTime: .startTime / 1000 | todate
endTime: .endTime | if . == -1 then null else (./1000 | todate) end
relations:
impactedEntities: .impactedEntities[].entityId.id
linkedProblemInfo: .linkedProblemInfo.problemId
rootCauseEntity: .rootCauseEntity.entityId.id
```
Sample payloadJSON
```
{
"affectedEntities": [
{
"entityId": {
"id": "string",
"type": "string"
},
"name": "string"
}
],
"displayId": "string",
"endTime": 1574697669865,
"entityTags": [
{
"context": "CONTEXTLESS",
"key": "architecture",
"stringRepresentation": "architecture:x86",
"value": "x86"
},
{
"context": "ENVIRONMENT",
"key": "Infrastructure",
"stringRepresentation": "[ENVIRONMENT]Infrastructure:Linux",
"value": "Linux"
}
],
"evidenceDetails": {
"details": [
{
"displayName": "Availability evidence",
"entity": {},
"evidenceType": "AVAILABILITY_EVIDENCE",
"groupingEntity": {},
"rootCauseRelevant": true,
"startTime": 1
},
{
"displayName": "User action evidence",
"entity": {},
"evidenceType": "USER_ACTION_EVIDENCE",
"groupingEntity": {},
"rootCauseRelevant": true,
"startTime": 1
}
],
"totalCount": 1
},
"impactAnalysis": {
"impacts": [
{
"estimatedAffectedUsers": 1,
"impactType": "APPLICATION",
"impactedEntity": {}
}
]
},
"impactLevel": "APPLICATION",
"impactedEntities": [{}],
"linkedProblemInfo": {
"displayId": "string",
"problemId": "string"
},
"managementZones": [
{
"id": "string",
"name": "HOST"
}
],
"problemFilters": [
{
"id": "E2A930951",
"name": "BASELINE"
}
],
"problemId": "06F288EE2A930951",
"recentComments": {
"comments": [
{
"authorName": "string",
"content": "string",
"context": "string",
"createdAtTimestamp": 1,
"id": "string"
}
],
"nextPageKey": "AQAAABQBAAAABQ==",
"pageSize": 1,
"totalCount": 1
},
"rootCauseEntity": {},
"severityLevel": "AVAILABILITY",
"startTime": 1574697667547,
"status": "CLOSED",
"title": "title"
}
```
Port entityJSON
```
{
"identifier": "06F288EE2A930951",
"title": "title",
"blueprint": "dynatraceProblem",
"team": [],
"icon": "Dynatrace",
"properties": {
"entityTags": ["architecture:x86", "[ENVIRONMENT]Infrastructure:Linux"],
"evidenceDetails": ["Availability evidence", "User action evidence"],
"managementZones": ["HOST"],
"problemFilters": ["BASELINE"],
"severityLevel": "AVAILABILITY",
"status": "CLOSED",
"startTime": "2019-11-25T14:14:27Z",
"endTime": "2020-04-30T14:52:41Z"
},
"relations": {
"impactedEntities": ["HOST-06F288EE2A930951"],
"linkedProblemInfo": "06F288EE2A930951",
"rootCauseEntity": "HOST-06F288EE2A930951"
},
"createdAt": "2024-2-6T09:30:57.924Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2024-2-6T11:49:20.881Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Default mappingYAML
```
- kind: slo
selector:
query: 'true'
attachRelatedEntities: true
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"dynatraceSlo"'
properties:
status: .status
target: .target
enabled: .enabled
warning: .warning
error: .error
errorBudget: .errorBudget
evaluatedPercentage: .evaluatedPercentage
evaluationType: .evaluationType
filter: .filter
relations:
entities: if .__entities != null then .__entities | map(.entityId) else [] end
```
Sample payloadJSON
```
{
"burnRateMetricKey": "func:slo.errorBudgetBurnRate.payment_service_availability",
"denominatorValue": 90,
"description": "Rate of successful payments per week",
"enabled": true,
"error": "NONE",
"errorBudget": 1.25,
"errorBudgetBurnRate": {
"burnRateType": "SLOW",
"burnRateValue": 1.25,
"burnRateVisualizationEnabled": true,
"estimatedTimeToConsumeErrorBudget": 24,
"fastBurnThreshold": 1.5,
"sloValue": 95
},
"errorBudgetMetricKey": "func:slo.errorBudget.payment_service_availability",
"evaluatedPercentage": 96.25,
"evaluationType": "AGGREGATE",
"filter": "type(\"SERVICE\")",
"id": "123e4567-e89b-42d3-a456-556642440000",
"metricDenominator": "builtin:service.requestCount.server",
"metricExpression": "(100)*(builtin:service.errors.server.successCount:splitBy())/(builtin:service.requestCount.server:splitBy())",
"metricKey": "func:slo.payment_service_availability",
"metricNumerator": "builtin:service.errors.server.successCount",
"metricRate": "builtin:service.successes.server.rate",
"name": "Payment service availability",
"normalizedErrorBudgetMetricKey": "func:slo.normalizedErrorBudget.payment_service_availability",
"numeratorValue": 80,
"problemFilters": "[type(\"SERVICE\")]",
"relatedOpenProblems": 1,
"relatedTotalProblems": 1,
"status": "WARNING",
"target": 95,
"timeframe": "-1d",
"useRateMetric": true,
"warning": 97.5,
"__entities": [{"entityId": "SERVICE-EF25D598399706BD", "type": "SERVICE", "displayName": "oidic-authentication-service"}]
}
```
Port entityJSON
```
{
"identifier": "123e4567-e89b-42d3-a456-556642440000",
"title": "Payment service availability",
"blueprint": "dynatraceSlo",
"team": [],
"icon": "Dynatrace",
"properties": {
"status": "WARNING",
"target": 95,
"enabled": true,
"warning": 97.5,
"error": "NONE",
"errorBudget": 1.25,
"evaluatedPercentage": 96.25,
"evaluationType": "AGGREGATE",
"filter": "type(\"SERVICE\")"
},
"relations": {
"entities": [
"SERVICE-EF25D598399706BD"
]
}
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| ----------------------- | --------- | ----------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `attachRelatedEntities` | `boolean` | Whether to attach related entities to SLO. The default is false Default: `false`. |
Default mappingYAML
```
- kind: team
selector:
query: 'true'
port:
entity:
mappings:
identifier: .value.identifier
title: .value.name
blueprint: '"dynatraceTeam"'
properties:
description: .value.descriptions
links: '[.value.links[] | .url]'
emailContact: .value.contactDetails[] | select(.integrationType == "EMAIL") | .email
productivityToolsContact: '[.value.contactDetails[] | select(.integrationType != "EMAIL" and .url != null) | .url]'
responsibilities: .value.responsibilities
additionalDetails: .value.additionalInformation
```
Sample payloadJSON
```
{
"objectId": "vu9U3hXa3q0AAAABABdidWlsdGluOm93bmVyc2hpcC50ZWFtcwAGdGVuYW50AAZ0ZW5hbnQAJDBkNGU5YjRmLWU3YzktM2Q2Ni1iYTlmLWUyNjRiMjhmZjI4ML7vVN4V2t6t",
"value": {
"name": "integration-devs",
"description": "Task to improve all integrations in Port",
"identifier": "integration-devs",
"supplementaryIdentifiers": [
{
"supplementaryIdentifier": "integral"
}
],
"responsibilities": {
"development": false,
"security": true,
"operations": false,
"infrastructure": false,
"lineOfBusiness": false
},
"contactDetails": [
{
"integrationType": "MS_TEAMS",
"msTeams": "internal developer portal",
"url": "https://microsoft.teams.com"
},
{
"integrationType": "JIRA",
"jira": {
"project": "DEMO",
"defaultAssignee": "support@devex.io"
},
"url": "https://mydomain.atlassian.net/jira/your-work"
},
{
"integrationType": "EMAIL",
"email": "support@port.io"
},
{
"integrationType": "SLACK",
"slackChannel": "devex",
"url": "https://app.slack.com/client/SOMEID"
}
],
"links": [
{
"linkType": "REPOSITORY",
"url": "https://github.com/getport"
},
{
"linkType": "URL",
"url": "https://myjira.io/teams/integration_bugs"
}
],
"additionalInformation": [
{
"key": "hero",
"value": "batman",
"url": "https://example.com"
}
]
}
}
```
Port entityJSON
```
{
"identifier": "integration-devs",
"title": "integration-devs",
"blueprint": "dynatraceTeam",
"properties": {
"description": "Task to improve all integrations in Port",
"links": [
"https://github.com/getport",
"https://myapp.io/teams/integration_bugs"
],
"emailContact": "support@devex.io",
"additionalDetails": [
{
"key": "hero",
"value": "batman",
"url": "https://example.com"
}
],
"productivityContactDetails": [
"https://microsoft.teams.com",
"https://mydomain.atlassian.net/jira/your-work",
"https://app.slack.com/client/SOMEID"
],
"responsibilities": {
"development": false,
"security": true,
"operations": false,
"infrastructure": false,
"lineOfBusiness": false
}
}
}
```
## Capabilities[](#capabilities "Direct link to Capabilities")
### Configure real-time updates[](#configure-real-time-updates "Direct link to Configure real-time updates")
Currently, the Dynatrace API lacks support for programmatic webhook creation. To set up a webhook configuration in Dynatrace for sending alert notifications to the Ocean integration, follow these steps:
Webhook configuration
Prepare a webhook `URL` using this format: `{app_host}/integration/webhook/problem`. The `app_host` parameter should match the ingress or external load balancer where the integration will be deployed. For example, if your ingress or load balancer exposes the Dynatrace Ocean integration at `https://myservice.domain.com`, your webhook `URL` should be `https://myservice.domain.com/integration/webhook/problem`.
1. Go to Dynatrace.
2. Go to **Settings** > **Integration** > **Problem notifications**.
3. Select **Add notification**.
4. Select **Custom integration** from the available notification types.
5. Configure the notification using the following details.
1. `Enabled` - ensure the notification is enabled.
2. `Display name` - use a meaningful name such as Port Ocean Webhook.
3. `Webhook URL` - enter the value of the `URL` you created above.
4. Enable **Call webhook is new events merge into existing problems**.
5. `Custom payload` - paste the following configuration:
```
{
"State":"{State}",
"ProblemID":"{ProblemID}",
"ProblemTitle":"{ProblemTitle}"
}
```
You can customize to your taste, the only important thing is the `ProblemID` key. The webhook integration will not work without it.
6. `Alerting profile` - select the corresponding alerting profile.
7. Leave the rest of the fields as is.
6. Click **Save changes**.
## Alternative installation via webhook[](#alternative-installation-via-webhook "Direct link to Alternative installation via webhook")
While the Ocean integration described above is the recommended installation method, you may prefer to use a webhook to ingest problem from Dynatrace. If so, use the following instructions:
**Note** that when using this method, data will be ingested into Port only when the webhook is triggered.
**Webhook installation (click to expand)**
## Port configuration
Create the following blueprint definitions:
**Dynatrace microservice blueprint (click to expand)**
Create in Port
```
{
"identifier": "microservice",
"title": "Microservice",
"icon": "Service",
"schema": {
"properties": {
"description": {
"title": "Description",
"type": "string"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
**Dynatrace problem blueprint (click to expand)**
Create in Port
```
{
"identifier": "dynatraceProblem",
"description": "This blueprint represents a Dynatrace problem in our software catalog",
"title": "Dynatrace Problem",
"icon": "Deployment",
"schema": {
"properties": {
"state": {
"type": "string",
"title": "Problem State"
},
"url": {
"type": "string",
"format": "url",
"title": "Problem URL"
},
"details": {
"type": "string",
"title": "Details"
},
"impact": {
"type": "string",
"title": "Problem Impact"
},
"severity": {
"type": "string",
"title": "Problem Severity"
},
"tags": {
"type": "array",
"items": {
"type": "string"
},
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {
"microservice": {
"title": "Impacted Services",
"target": "microservice",
"required": false,
"many": true
}
}
}
```
Create the following webhook configuration [using Port's UI](/context-lake/ingestion/ingest-data-into-port/webhook/ingest-via-webhooks-overview/.md?operation=ui#configuring-webhook-endpoints):
**Dynatrace problem webhook configuration (click to expand)**
1. **Basic details** tab - fill the following details:
1. Title : `Dynatrace Problem Mapper`.
2. Identifier : `dynatrace_problem_mapper`.
3. Description : `A webhook configuration for problem events from Dynatrace`.
4. Icon : `Dynatrace`.
2. **Integration configuration** tab - fill the following JQ mapping:
```
[
{
"blueprint": "dynatraceProblem",
"entity": {
"identifier": ".body.PID | tostring",
"title": ".body.ProblemTitle",
"properties": {
"state": ".body.State",
"url": ".body.ProblemURL",
"details": ".body.ProblemDetailsText",
"impact": ".body.ProblemImpact",
"severity": ".body.ProblemSeverity",
"tags": ".body.ProblemTags | split(\", \")"
},
"relations": {
"microservice": "[.body.ImpactedEntities[].entity]"
}
}
}
]
```
3. Click **Save** at the bottom of the page.
Match Dynatrace entity names
The webhook configuration's relation mapping will function properly only when the identifiers of the Port microservice entities match the names of the entities in your Dynatrace.
If there is a mismatch, you can utilize [Dynatrace Tags](https://www.dynatrace.com/support/help/manage/tags-and-metadata) to align the actual identifier in Port.
To do this, create a tag with the key `proj` and value `microservice_identifier`.
Then, update the relation JQ syntax to establish a connection between the Dynatrace problem and the Port microservice. Here is the updated JQ Mappings:
```
{
"blueprint": "dynatraceProblem",
"entity": {
...Properties mappings,
"relations": {
"microservice": ".body.ProblemTags | split(\", \") | map(select(test(\"proj:\")) | sub(\"proj:\";\"\"))"
}
}
}
```
Details
**JQ expression explained (click to expand)**
The above JQ expression will split the tags by comma and space, then filter the tags that start with `proj:` and remove the `proj:` prefix from the tag value.
## Create a webhook in Dynatrace
1. Log in to Dynatrace with your credentials.
2. Click on **Settings** at the left sidebar of the page.
3. Choose **Integration** and click on **Problem notifications**.
4. Select **Add notification**.
5. Select **Custom integration** from the available integration types.
6. Input the following details:
1. `Display name` - use a meaningful name such as Port Webhook.
2. `Webhook URL` - enter the value of the `url` key you received after creating the webhook configuration.
3. `Overview` - you can add an optional HTTP header to your webhook request.
4. `Custom payload` - When a problem is detected or resolved on your entity, this payload will be sent to the webhook URL. You can enter this JSON placeholder in the textbox:
```
{
"State":"{State}",
"PID":"{PID}",
"ProblemTitle":"{ProblemTitle}",
"ImpactedEntity": "{ImpactedEntity}",
"ProblemDetailsText": "{ProblemDetailsText}",
"ProblemImpact": "{ProblemImpact}",
"ProblemSeverity": "{ProblemSeverity}",
"ProblemURL": "{ProblemURL}",
"ProblemTags": "{ProblemTags}",
"ImpactedEntities": {ImpactedEntities}
}
```
5. `Alerting profile` - configure your preferred alerting rule or use the default one.
7. Click **Save changes** at the bottom of the page.
Dynatrace webhook events
To view the different payloads and events available in Dynatrace webhooks, [look here](https://www.dynatrace.com/support/help/observe-and-explore/notifications-and-alerting/problem-notifications/webhook-integration).
Done! Any problem detected on your Dynatrace entity will trigger a webhook event. Port will parse the events according to the mapping and update the catalog entities accordingly.
## Let's Test It
This section includes a sample response data from Dynatrace. In addition, it includes the entity created from the resync event based on the Ocean configuration provided in the previous section.
### Payload
Here is an example of the payload structure from Dynatrace:
**Problem response data (click to expand)**
```
{
"affectedEntities": [
{
"entityId": {
"id": "string",
"type": "string"
},
"name": "string"
}
],
"displayId": "string",
"endTime": 1574697669865,
"entityTags": [
{
"context": "CONTEXTLESS",
"key": "architecture",
"stringRepresentation": "architecture:x86",
"value": "x86"
},
{
"context": "ENVIRONMENT",
"key": "Infrastructure",
"stringRepresentation": "[ENVIRONMENT]Infrastructure:Linux",
"value": "Linux"
}
],
"evidenceDetails": {
"details": [
{
"displayName": "Availability evidence",
"entity": {},
"evidenceType": "AVAILABILITY_EVIDENCE",
"groupingEntity": {},
"rootCauseRelevant": true,
"startTime": 1
},
{
"displayName": "User action evidence",
"entity": {},
"evidenceType": "USER_ACTION_EVIDENCE",
"groupingEntity": {},
"rootCauseRelevant": true,
"startTime": 1
}
],
"totalCount": 1
},
"impactAnalysis": {
"impacts": [
{
"estimatedAffectedUsers": 1,
"impactType": "APPLICATION",
"impactedEntity": {}
}
]
},
"impactLevel": "APPLICATION",
"impactedEntities": [{}],
"linkedProblemInfo": {
"displayId": "string",
"problemId": "string"
},
"managementZones": [
{
"id": "string",
"name": "HOST"
}
],
"problemFilters": [
{
"id": "E2A930951",
"name": "BASELINE"
}
],
"problemId": "06F288EE2A930951",
"recentComments": {
"comments": [
{
"authorName": "string",
"content": "string",
"context": "string",
"createdAtTimestamp": 1,
"id": "string"
}
],
"nextPageKey": "AQAAABQBAAAABQ==",
"pageSize": 1,
"totalCount": 1
},
"rootCauseEntity": {},
"severityLevel": "AVAILABILITY",
"startTime": 1574697667547,
"status": "CLOSED",
"title": "title"
}
```
### Mapping Result
The combination of the sample payload and the Ocean configuration generates the following Port entity:
**Problem entity in Port (click to expand)**
```
{
"identifier": "06F288EE2A930951",
"title": "title",
"blueprint": "dynatraceProblem",
"team": [],
"icon": "Dynatrace",
"properties": {
"entityTags": ["architecture:x86", "[ENVIRONMENT]Infrastructure:Linux"],
"evidenceDetails": ["Availability evidence", "User action evidence"],
"managementZones": ["HOST"],
"problemFilters": ["BASELINE"],
"severityLevel": "AVAILABILITY",
"status": "CLOSED",
"startTime": "2019-11-25T14:14:27Z",
"endTime": "2020-04-30T14:52:41Z"
},
"relations": {
"impactedEntities": ["HOST-06F288EE2A930951"],
"linkedProblemInfo": "06F288EE2A930951",
"rootCauseEntity": "HOST-06F288EE2A930951"
},
"createdAt": "2024-2-6T09:30:57.924Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2024-2-6T11:49:20.881Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
## Ingest Dynatrace Entities
In this example, you will create a `dynatrace_entity` blueprint that ingests monitored entities from your Dynatrace account. You will then add a Python script to make API calls to Dynatrace REST API and fetch data for your account.
* [Code Repository Example](https://github.com/port-labs/example-dynatrace-entities)
---
# New Relic

Loading version...
Port's New Relic integration allows you to model New Relic resources in your software catalog and ingest data into them.
Supported resources [newRelicService](https://docs.newrelic.com/docs/new-relic-solutions/new-relic-one/core-concepts/what-entity-new-relic/)[newRelicAlert](https://docs.newrelic.com/docs/alerts-applied-intelligence/new-relic-alerts/get-started/alerts-ai-overview-page/#issues)[newRelicServiceLevel](https://docs.newrelic.com/docs/service-level-management/consume-slm/)[Alert Condition](https://docs.newrelic.com/docs/alerts/scale-automate/rest-api/rest-api-calls-alerts/)[entity](https://docs.newrelic.com/docs/new-relic-solutions/new-relic-one/core-concepts/what-entity-new-relic/)[entities](https://docs.newrelic.com/docs/new-relic-solutions/new-relic-one/core-concepts/what-entity-new-relic/)
## Core support
[Live eventsSee supported resources](#set-up-live-events)
## Setup[](#setup "Direct link to Setup")
Choose one of the following installation methods: Not sure which method is right for your use case? Check the available [installation methods](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Real-time updates + customizable resync interval
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Additional Configuration[](#additional-configuration "Direct link to Additional Configuration")
* **newRelicTypes** - An array of Newrelic entity types that will be fetched. The default value is \['SERVICE', 'APPLICATION']. This is related to the type field in the Newrelic entity.
* **calculateOpenIssueCount:**
* A boolean value that indicates if the integration should calculate the number of open issues for each entity. The default value is \`false\`\`.
* **NOTE** - This can cause a performance degradation as the integration will have to calculate the number of open issues for each entity, which unfortunately is not supported by the New Relic API.
* **entityQueryFilter:**
* A filter that will be applied to the New Relic API query. This will be placed inside the `query` field of the `entitySearch` query in the New Relic GraphQL API. For examples of query filters [click here](https://docs.newrelic.com/docs/apis/nerdgraph/examples/nerdgraph-entities-api-tutorial/#search-query).
* Not specifying this field will cause the integration to fetch all the entities and map them to the blueprint defined in the `kind`.
* Rule of thumb - Most of the time the `EntityQueryFilter` will be the same as the `NewRelicTypes`. For example, if we want to fetch all the services and applications we will set the `EntityQueryFilter` to `type in ('SERVICE','APPLICATION')` and the `NewRelicTypes` to `['SERVICE', 'APPLICATION']`.
* **entityExtraPropertiesQuery:**
* An optional property that allows defining extra properties to fetch for each Newrelic entity. This will be concatenated with the default query properties we are requesting under the `entities` section in the `entitySearch` query in the Newrelic GraphQL API. For examples of additional query properties [click here](https://docs.newrelic.com/docs/apis/nerdgraph/examples/nerdgraph-entities-api-tutorial/#apm-summary).
* The `port`, `entity` and the `mappings` keys are used to map the Newrelic object fields to Port entities. To create multiple mappings of the same kind, you can add another item in the `resources` array.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: newRelicService
selector:
query: 'true'
newRelicTypes:
- SERVICE
- APPLICATION
calculateOpenIssueCount: true
entityQueryFilter: type in ('SERVICE','APPLICATION')
entityExtraPropertiesQuery: |-
... on ApmApplicationEntityOutline {
guid
name
apmSummary {
apdexScore
errorRate
hostCount
instanceCount
responseTimeAverage
throughput
}
}
port:
entity:
mappings:
identifier: .guid
title: .name
blueprint: '"newRelicService"'
properties:
has_apm: if .domain | contains("APM") then "true" else "false" end
link: .permalink
open_issues_count: .open_issues_count
reporting: .reporting
tags: .tags
type: .type
throughput: .apmSummary.throughput
error_rate: .apmSummary.errorRate
response_time_avg: .apmSummary.responseTimeAverage
instance_count: .apmSummary.instanceCount
apdex: .apmSummary.apdexScore
- kind: newRelicAlert
selector:
query: .state == "ACTIVATED" or .state == "CREATED"
newRelicTypes:
- ISSUE
port:
entity:
mappings:
identifier: .issueId
title: .title[0]
blueprint: '"newRelicAlert"'
properties:
priority: .priority
state: .state
sources: .sources
conditionName: .conditionName
alertPolicyNames: .policyName
activatedAt: if .activatedAt == null then null else .activatedAt / 1000 | todate end
link: '"https://one.newrelic.com/launcher/nrai.launcher?pane=" + ("{\"isPhoton\": true, \"id\": \"\(.issueId)\", \"nerdletId\": \"nrai.issue-redirect\"}" | @base64)'
description: .description
relations:
alert_to_workload: .__APPLICATION.entity_guids + .__SERVICE.entity_guids
cloud_resource:
combinator: '"and"'
rules:
- property: '"guid"'
operator: '"in"'
value: .entityGuids
- kind: newRelicServiceLevel
selector:
query: 'true'
port:
entity:
mappings:
identifier: .serviceLevel.indicators[0].id
title: .serviceLevel.indicators[0].name
blueprint: '"newRelicServiceLevel"'
properties:
description: .serviceLevel.indicators[0].description
targetThreshold: .serviceLevel.indicators[0].objectives[0].target
createdAt: if .serviceLevel.indicators[0].createdAt != null then (.serviceLevel.indicators[0].createdAt | tonumber / 1000 | todate) else null end
updatedAt: if .serviceLevel.indicators[0].updatedAt != null then (.serviceLevel.indicators[0].updatedAt | tonumber / 1000 | todate) else null end
createdBy: .serviceLevel.indicators[0].createdBy.email
sli: .__SLI.SLI
tags: .tags
slo_compliance: .__SLI.SLI >= .serviceLevel.indicators[0].objectives[0].target
relations:
workload: .tags."nr.associatedEntityGuid"[0]
- kind: entity
selector:
query: 'true'
entityQueryFilter: >-
type IN ( 'AWSEC2INSTANCE', 'AWSS3BUCKET', 'AWSRDSDBINSTANCE', 'AWSLAMBDAFUNCTION', 'AWSELBLOADBALANCER', 'AZUREVIRTUALMACHINE', 'AZURESQLDATABASE', 'GCPCOMPUTEINSTANCE', 'GCPSTORAGEBUCKET', 'GCPSQLDATABASEINSTANCE' )
port:
entity:
mappings:
identifier: .guid
title: .name
blueprint: '"newRelicCloudResource"'
properties:
infrastructureIntegrationType: .type
reporting: .reporting
link: .permalink
tags: .tags
- kind: entities
selector:
query: 'true'
entityQueryFilter: type IN ( 'DASHBOARD' )
port:
entity:
mappings:
identifier: .guid
title: .name
blueprint: '"newRelicDashboards"'
properties:
dashboard_link: .permalink
- kind: newRelicService
selector:
query: 'true'
newRelicTypes:
- SERVICE
- APPLICATION
entityQueryFilter: type in ('SERVICE','APPLICATION')
port:
entity:
mappings:
identifier: .guid
title: .name
blueprint: '"workload"'
relations:
new_relic_workload: .guid
```
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
Use the explorer below to view sample payloads and the resulting Port entities for each resource type.
newRelicServicenewRelicAlertnewRelicServiceLevelentityentities
Default mappingYAML
```
- kind: newRelicService
selector:
query: 'true'
newRelicTypes:
- SERVICE
- APPLICATION
calculateOpenIssueCount: true
entityQueryFilter: type in ('SERVICE','APPLICATION')
entityExtraPropertiesQuery: |-
... on ApmApplicationEntityOutline {
guid
name
apmSummary {
apdexScore
errorRate
hostCount
instanceCount
responseTimeAverage
throughput
}
}
port:
entity:
mappings:
identifier: .guid
title: .name
blueprint: '"newRelicService"'
properties:
has_apm: if .domain | contains("APM") then "true" else "false" end
link: .permalink
open_issues_count: .open_issues_count
reporting: .reporting
tags: .tags
type: .type
throughput: .apmSummary.throughput
error_rate: .apmSummary.errorRate
response_time_avg: .apmSummary.responseTimeAverage
instance_count: .apmSummary.instanceCount
apdex: .apmSummary.apdexScore
- kind: newRelicService
selector:
query: 'true'
newRelicTypes:
- SERVICE
- APPLICATION
entityQueryFilter: type in ('SERVICE','APPLICATION')
port:
entity:
mappings:
identifier: .guid
title: .name
blueprint: '"workload"'
relations:
new_relic_workload: .guid
```
Sample payloadJSON
```
{
"accountId": 4444532,
"alertSeverity": "NOT_CONFIGURED",
"domain": "INFRA",
"entityType": "INFRASTRUCTURE_HOST_ENTITY",
"guid": "MTIzNDU2Nzg5fElORlJBfE5BfDY1MjQwNDc0NjE4MzUyMDkwOTU=",
"lastReportingChangeAt": 1715351571254,
"name": "UserMacbook",
"permalink": "https://one.eu.newrelic.com/redirect/entity/MTIzNDU2Nzg5fElORlJBfE5BfDY1MjQwNDc0NjE4MzUyMDkwOTU=",
"reporting": true,
"tags": [
{
"key": "account",
"values": [
"Account 4444831"
]
},
{
"key": "accountId",
"values": [
"4444831"
]
},
{
"key": "agentName",
"values": [
"Infrastructure"
]
},
{
"key": "agentVersion",
"values": [
"1.50.0"
]
},
{
"key": "coreCount",
"values": [
"8"
]
},
{
"key": "fullHostname",
"values": [
"usermacbook"
]
},
{
"key": "hostStatus",
"values": [
"running"
]
},
{
"key": "hostname",
"values": [
"Usermacbook"
]
},
{
"key": "instanceType",
"values": [
"MacBook Air MacBookAir10,1"
]
},
{
"key": "kernelVersion",
"values": [
"23.2.0"
]
},
{
"key": "linuxDistribution",
"values": [
"macOS 14.2.1"
]
},
{
"key": "operatingSystem",
"values": [
"macOS"
]
},
{
"key": "processorCount",
"values": [
"8"
]
},
{
"key": "systemMemoryBytes",
"values": [
"17179869184"
]
},
{
"key": "trustedAccountId",
"values": [
"4444532"
]
}
],
"type": "HOST"
}
```
Port entityJSON
```
{
"identifier": "MTIzNDU2Nzg5fElORlJBfE5BfDY1MjQwNDc0NjE4MzUyMDkwOTU=",
"title": "UserMacbook",
"blueprint": "newRelicAlert",
"team": [],
"icon": "NewRelic",
"properties": {
"has_apm": false,
"link": "https://one.eu.newrelic.com/redirect/entity/MTIzNDU2Nzg5fElORlJBfE5BfDY1MjQwNDc0NjE4MzUyMDkwOTU=",
"open_issues_count": null,
"reporting": true,
"tags": [
{
"key": "account",
"values": [
"Account 4444831"
]
},
{
"key": "accountId",
"values": [
"4444831"
]
},
{
"key": "agentName",
"values": [
"Infrastructure"
]
},
{
"key": "agentVersion",
"values": [
"1.50.0"
]
},
{
"key": "coreCount",
"values": [
"8"
]
},
{
"key": "fullHostname",
"values": [
"usermacbook"
]
},
{
"key": "hostStatus",
"values": [
"running"
]
},
{
"key": "hostname",
"values": [
"Usermacbook"
]
},
{
"key": "instanceType",
"values": [
"MacBook Air MacBookAir10,1"
]
},
{
"key": "kernelVersion",
"values": [
"23.2.0"
]
},
{
"key": "linuxDistribution",
"values": [
"macOS 14.2.1"
]
},
{
"key": "operatingSystem",
"values": [
"macOS"
]
},
{
"key": "processorCount",
"values": [
"8"
]
},
{
"key": "systemMemoryBytes",
"values": [
"17179869184"
]
},
{
"key": "trustedAccountId",
"values": [
"4444532"
]
}
],
"domain": "INFRA",
"type": "HOST"
},
"relations": {},
"createdAt": "2024-2-6T09:30:57.924Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2024-2-6T11:49:20.881Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Default mappingYAML
```
- kind: newRelicAlert
selector:
query: .state == "ACTIVATED" or .state == "CREATED"
newRelicTypes:
- ISSUE
port:
entity:
mappings:
identifier: .issueId
title: .title[0]
blueprint: '"newRelicAlert"'
properties:
priority: .priority
state: .state
sources: .sources
conditionName: .conditionName
alertPolicyNames: .policyName
activatedAt: if .activatedAt == null then null else .activatedAt / 1000 | todate end
link: '"https://one.newrelic.com/launcher/nrai.launcher?pane=" + ("{\"isPhoton\": true, \"id\": \"\(.issueId)\", \"nerdletId\": \"nrai.issue-redirect\"}" | @base64)'
description: .description
relations:
alert_to_workload: .__APPLICATION.entity_guids + .__SERVICE.entity_guids
cloud_resource:
combinator: '"and"'
rules:
- property: '"guid"'
operator: '"in"'
value: .entityGuids
```
Sample payloadJSON
```
{
"issueId": "MjQwNzIwN3xBUE18QVBQTElDQVRJT058MjIwMzEwNzV8MTA0NzYwNzA5",
"title": "My Issue",
"priority": "CRITICAL",
"state": "ACTIVATED",
"sources": ["My Source"],
"conditionName": ["My Condition"],
"policyName": ["My Policy"],
"activatedAt": "2022-01-01T00:00:00Z"
}
```
Port entityJSON
```
{
"identifier": "My Issue",
"title": "My Issue",
"blueprint": "newRelicAlert",
"team": [],
"icon": "NewRelic",
"properties": {
"priority": "CRITICAL",
"state": "ACTIVATED",
"sources": ["My Source"],
"conditionName": ["My Condition"],
"alertPolicyNames": ["My Policy"],
"activatedAt": "2022-01-01T00:00:00Z"
},
"relations": {
"newRelicService": "My Service"
},
"createdAt": "2024-2-6T09:30:57.924Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2024-2-6T11:49:20.881Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Default mappingYAML
```
- kind: newRelicServiceLevel
selector:
query: 'true'
port:
entity:
mappings:
identifier: .serviceLevel.indicators[0].id
title: .serviceLevel.indicators[0].name
blueprint: '"newRelicServiceLevel"'
properties:
description: .serviceLevel.indicators[0].description
targetThreshold: .serviceLevel.indicators[0].objectives[0].target
createdAt: if .serviceLevel.indicators[0].createdAt != null then (.serviceLevel.indicators[0].createdAt | tonumber / 1000 | todate) else null end
updatedAt: if .serviceLevel.indicators[0].updatedAt != null then (.serviceLevel.indicators[0].updatedAt | tonumber / 1000 | todate) else null end
createdBy: .serviceLevel.indicators[0].createdBy.email
sli: .__SLI.SLI
tags: .tags
slo_compliance: .__SLI.SLI >= .serviceLevel.indicators[0].objectives[0].target
relations:
workload: .tags."nr.associatedEntityGuid"[0]
```
Sample payloadJSON
```
{
"serviceLevel": {
"indicators": [
{
"createdAt": 1721030560937,
"createdBy": {
"email": "user@domain.com"
},
"description": "Proportion of requests that are served faster than a threshold.",
"guid": "NDM2OTY4MHxFWFR8U0VSVklDRV9MRVZFTHw1OTk0MzQ",
"id": "599434",
"name": "Service Level Name - Metric",
"objectives": [
{
"description": null,
"name": null,
"target": 95,
"timeWindow": {
"rolling": {
"count": 7,
"unit": "DAY"
}
}
}
],
"resultQueries": {
"indicator": {
"nrql": "SELECT clamp_max(sum(newrelic.sli.good) / sum(newrelic.sli.valid) * 100, 100) AS 'SLI' FROM Metric WHERE entity.guid = 'NDM2OTY4MHxFWFR8U0VSVklDRV9MRVZFTHw1OTk0MzQ' UNTIL 2 minutes AGO"
}
},
"updatedAt": null,
"updatedBy": null
}
]
},
"tags": {
"account": [
"Account [REDACTED]"
],
"accountId": [
"[REDACTED]"
],
"category": [
"latency"
],
"nr.associatedEntityGuid": [
"NDM2OTY4MHxBUE18QVBQTElDQVRJT058NTkxMTYyMjE0"
],
"nr.associatedEntityName": [
"Service Name 01"
],
"nr.associatedEntityType": [
"APM_APPLICATION"
],
"nr.sliComplianceCategory": [
"Non-compliant"
],
"nr.sloPeriod": [
"7d"
],
"nr.sloTarget": [
"95.0%"
],
"trustedAccountId": [
"[REDACTED]"
]
},
"__SLI": {
"SLI": 87.56
}
}
```
Port entityJSON
```
{
"blueprint": "newRelicServiceLevel",
"identifier": "599434",
"title": "Service Level Name - Metric",
"icon": "NewRelic",
"properties": {
"description": "Proportion of requests that are served faster than a threshold.",
"targetThreshold": 95,
"createdAt": "2024-07-15T08:02:40Z",
"updatedAt": null,
"createdBy": "user@domain.com",
"serviceLevelIndicator": 87.56,
"tags": {
"account": [
"Account [REDACTED]"
],
"accountId": [
"[REDACTED]"
],
"category": [
"latency"
],
"nr.associatedEntityGuid": [
"NDM2OTY4MHxBUE18QVBQTElDQVRJT058NTkxMTYyMjE0"
],
"nr.associatedEntityName": [
"Service Name 01"
],
"nr.associatedEntityType": [
"APM_APPLICATION"
],
"nr.sliComplianceCategory": [
"Non-compliant"
],
"nr.sloPeriod": [
"7d"
],
"nr.sloTarget": [
"95.0%"
],
"trustedAccountId": [
"[REDACTED]"
]
}
},
"relations": {
"newRelicService": "NDM2OTY4MHxFWFR8U0VSVklDRV9MRVZFTHw1OTk0MzQ"
},
"createdAt": "2024-08-06T09:30:57.924Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2024-08-06T09:49:20.881Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Default mappingYAML
```
- kind: entity
selector:
query: 'true'
entityQueryFilter: >-
type IN ( 'AWSEC2INSTANCE', 'AWSS3BUCKET', 'AWSRDSDBINSTANCE', 'AWSLAMBDAFUNCTION', 'AWSELBLOADBALANCER', 'AZUREVIRTUALMACHINE', 'AZURESQLDATABASE', 'GCPCOMPUTEINSTANCE', 'GCPSTORAGEBUCKET', 'GCPSQLDATABASEINSTANCE' )
port:
entity:
mappings:
identifier: .guid
title: .name
blueprint: '"newRelicCloudResource"'
properties:
infrastructureIntegrationType: .type
reporting: .reporting
link: .permalink
tags: .tags
```
Default mappingYAML
```
- kind: entities
selector:
query: 'true'
entityQueryFilter: type IN ( 'DASHBOARD' )
port:
entity:
mappings:
identifier: .guid
title: .name
blueprint: '"newRelicDashboards"'
properties:
dashboard_link: .permalink
```
## Set up live events[](#set-up-live-events "Direct link to Set up live events")
This integration supports live events, allowing real-time updates to your software catalog without waiting for the next scheduled sync.
Note that different events are supported depending on the resource type.
Supported live event triggers (click to expand)
* Hosted by Port
* Self-hosted
### Live events base URL
For integrations installed using the **Hosted by Port** method, you can obtain the live events base URL from the [Get an integration](/api-reference/get-an-integration/) API. The response includes `liveEventsUuid` and `liveEventsIngestHostname` in the `appSpec` section.
Call the endpoint with your integration's identifier:
```
curl -X GET \
'https://api.port.io/v1/integration/' \
-H 'Authorization: Bearer '
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
In the response, look for the following fields under `spec.appSpec`:
```
{
"spec": {
"appSpec": {
"liveEventsUuid": "abcdefghijk",
"liveEventsIngestHostname": "ingest.ocean.getport.io"
}
}
}
```
Combine them to build the live events base URL:
```
https:///live-events/
```
For example, with the values above, the live events base URL is:
```
https://ingest.ocean.getport.io/live-events/abcdefghijk
```
This is the same URL configured for the integration.
### BaseUrl & webhook configuration[](#baseurl--webhook-configuration "Direct link to BaseUrl & webhook configuration")
To enable real-time updates of the data in your software catalog, you need to define the `liveEvents.baseUrl` parameter.
This parameter should be set to the URL of your New Relic integration instance, which needs to have the option to setup webhooks via HTTP requests/receive HTTP requests, so ensure the network is configured accordingly.
* **If New Relic and the integration are in the same cluster/network**: Use an internal URL (e.g., a Kubernetes service DNS name).
For Kubernetes deployments, create a service to expose the integration pod and use the service URL as `liveEvents.baseUrl`. If both the source system and integration are in the same cluster, an internal ClusterIP service is sufficient.
* **If New Relic is external to the integration's network**: The integration must be exposed via an ingress, load balancer, or public URL that
New Relic
can reach.
Scaling for high-volume, self-hosted deployments
If you're running high volumes of live events in a self-hosted deployment and want better reliability, event durability, or horizontal scalability, you can optionally set up Port's dedicated live events infrastructure. See [live events at scale](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/live-events/.md#live-events-at-scale) for details.
If `liveEvents.baseUrl` is not provided, the integration will continue to function correctly. In such a configuration, to retrieve the latest information from the target system, the [`scheduledResyncInterval`](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md#scheduled-resync) parameter has to be set, or a manual resync will need to be triggered through Port's UI.
Debugging local integrations
To test webhooks or live event delivery to your local environment, expose your local pod or service to the internet using ngrok (e.g. `ngrok http http://localhost:8000`)
### Securing Your Webhooks
The `integration.secrets.webhookUsername,integration.secrets.webhookSecret` parameters secure your webhooks. If not provided, the integration will process webhooks without validating the source of the events.
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Capabilities[](#capabilities "Direct link to Capabilities")
### Tags[](#tags "Direct link to Tags")
Some Newrelic `entities` have a property named `tags` which contains potentially useful information such as machine information, hostname, agent name & version, and more. For example:
```
"tags": [
{
"key": "coreCount",
"values": [
"10"
]
},
{
"key": "hostStatus",
"values": [
"running"
]
},
]
```
Before mapping, this integration performs a transformation on each `tag`, after which the example above would look like this:
```
tags = ["coreCount":"10","hostStatus":"running"]
```
## Examples[](#examples "Direct link to Examples")
Examples of blueprints and the relevant integration configurations:
### Service (Entity)[](#service-entity "Direct link to Service (Entity)")
**Service blueprint (click to expand)**
Create in Port
```
{
"identifier": "newRelicService",
"description": "This blueprint represents a New Relic service or application in our software catalog",
"title": "New Relic Service",
"icon": "NewRelic",
"schema": {
"properties": {
"has_apm": {
"title": "Has APM",
"type": "boolean"
},
"open_issues_count": {
"title": "Open Issues Count",
"type": "number",
"default": 0
},
"link": {
"title": "Link",
"type": "string",
"format": "url"
},
"reporting": {
"title": "Reporting",
"type": "boolean"
},
"tags": {
"title": "Tags",
"type": "object"
},
"account_id": {
"title": "Account ID",
"type": "string"
},
"type": {
"title": "Type",
"type": "string"
},
"domain": {
"title": "Domain",
"type": "string"
},
"throughput": {
"title": "Throughput",
"type": "number"
},
"response_time_avg": {
"title": "Response Time AVG",
"type": "number"
},
"error_rate": {
"title": "Error Rate",
"type": "number"
},
"instance_count": {
"title": "Instance Count",
"type": "number"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: newRelicService
selector:
query: "true"
newRelicTypes: ["SERVICE", "APPLICATION"]
calculateOpenIssueCount: true
entityQueryFilter: "type in ('SERVICE','APPLICATION')"
entityExtraPropertiesQuery: |
... on ApmApplicationEntity {
guid
name
alertSeverity
applicationId
apmBrowserSummary {
ajaxRequestThroughput
ajaxResponseTimeAverage
jsErrorRate
pageLoadThroughput
pageLoadTimeAverage
}
apmSummary {
apdexScore
errorRate
hostCount
instanceCount
nonWebResponseTimeAverage
nonWebThroughput
responseTimeAverage
throughput
webResponseTimeAverage
webThroughput
}
}
port:
entity:
mappings:
blueprint: '"newRelicService"'
identifier: .guid
title: .name
properties:
has_apm: 'if .domain | contains("APM") then "true" else "false" end'
link: .permalink
open_issues_count: .__open_issues_count
reporting: .reporting
tags: .tags
domain: .domain
type: .type
```
### Issue[](#issue "Direct link to Issue")
**Issue blueprint (click to expand)**
Create in Port
```
{
"identifier": "newRelicAlert",
"description": "This blueprint represents a New Relic alert in our software catalog",
"title": "New Relic Alert",
"icon": "NewRelic",
"schema": {
"properties": {
"priority": {
"type": "string",
"title": "Priority",
"enum": ["CRITICAL", "HIGH", "MEDIUM", "LOW"],
"enumColors": {
"CRITICAL": "red",
"HIGH": "red",
"MEDIUM": "yellow",
"LOW": "green"
}
},
"state": {
"type": "string",
"title": "State",
"enum": ["ACTIVATED", "CLOSED", "CREATED"],
"enumColors": {
"ACTIVATED": "yellow",
"CLOSED": "green",
"CREATED": "lightGray"
}
},
"trigger": {
"type": "string",
"title": "Trigger"
},
"sources": {
"type": "array",
"title": "Sources"
},
"alertPolicyNames": {
"type": "array",
"title": "Alert Policy Names"
},
"conditionName": {
"type": "array",
"title": "Condition Name"
},
"activatedAt": {
"type": "string",
"title": "Time Issue was activated"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {
"newRelicService": {
"title": "New Relic Service",
"target": "newRelicService",
"required": false,
"many": true
}
}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: newRelicAlert
selector:
query: "true"
newRelicTypes: ["ISSUE"]
port:
entity:
mappings:
blueprint: '"newRelicAlert"'
identifier: .issueId
title: .title[0]
properties:
priority: .priority
state: .state
sources: .sources
conditionName: .conditionName
alertPolicyNames: .policyName
activatedAt: .activatedAt
relations:
newRelicService: .__APPLICATION.entity_guids + .__SERVICE.entity_guids
```
### Service Level[](#service-level "Direct link to Service Level")
**Service Level blueprint (click to expand)**
Create in Port
```
{
"identifier": "newRelicServiceLevel",
"description": "This blueprint represents a New Relic Service Level",
"title": "New Relic Service Level",
"icon": "NewRelic",
"schema": {
"properties": {
"description": {
"title": "Description",
"type": "string"
},
"targetThreshold": {
"icon": "DefaultProperty",
"title": "Target Threshold",
"type": "number"
},
"createdAt": {
"title": "Created At",
"type": "string",
"format": "date-time"
},
"updatedAt": {
"title": "Updated At",
"type": "string",
"format": "date-time"
},
"createdBy": {
"title": "Creator",
"type": "string",
"format": "user"
},
"sli": {
"type": "number",
"title": "SLI"
},
"tags": {
"type": "object",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"newRelicService": {
"title": "New Relic service",
"target": "newRelicService",
"required": false,
"many": false
}
}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: newRelicServiceLevel
selector:
query: 'true'
port:
entity:
mappings:
blueprint: '"newRelicServiceLevel"'
identifier: .serviceLevel.indicators[0].id
title: .serviceLevel.indicators[0].name
properties:
description: .serviceLevel.indicators[0].description
targetThreshold: .serviceLevel.indicators[0].objectives[0].target
createdAt: if .serviceLevel.indicators[0].createdAt != null then (.serviceLevel.indicators[0].createdAt | tonumber / 1000 | todate) else null end
updatedAt: if .serviceLevel.indicators[0].updatedAt != null then (.serviceLevel.indicators[0].updatedAt | tonumber / 1000 | todate) else null end
createdBy: .serviceLevel.indicators[0].createdBy.email
sli: .__SLI.SLI
tags: .tags
relations:
newRelicService: .serviceLevel.indicators[0].guid
```
---
# Prometheus
Custom Ocean integration
This integration was created using the [custom Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework.
Please note that:
1. This integration will not be listed in the `Connectors` page of your Port application, and must be installed manually using the instructions on this page.
2. This integration will not create components (e.g. `blueprints`, `mapping`, etc.) in your portal automatically, you will need to create them manually using the instructions on this page.
Port's Prometheus integration allows you to ingest Prometheus monitoring and alerting data into your software catalog using the [No-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework. After installing this integration, you can visualize your Prometheus alerts, alerting rules, and scrape targets using Port's dashboards.
## Supported resources[](#supported-resources "Direct link to Supported resources")
The Prometheus integration can ingest the following resources into Port. It is possible to reference any field that appears in the API responses in the mapping configuration. For detailed API documentation, see the [Prometheus HTTP API documentation](https://prometheus.io/docs/prometheus/latest/querying/api/).
* **Alerts** - Active alerts from [`/api/v1/alerts`](https://prometheus.io/docs/prometheus/latest/querying/api/#getting-alerts).
* **Rules** - Alerting and recording rules from [`/api/v1/rules`](https://prometheus.io/docs/prometheus/latest/querying/api/#rules).
* **Targets** - Scrape targets and their health status from [`/api/v1/targets`](https://prometheus.io/docs/prometheus/latest/querying/api/#targets).
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
To use this integration, you need:
* A Prometheus instance accessible via HTTP/HTTPS.
* Network access to the Prometheus API endpoints.
* If authentication is enabled, appropriate credentials (API token, username/password, or bearer token).
**Prometheus authentication:**
Prometheus does not require authentication by default. However, if your Prometheus instance has authentication enabled, you can use:
* **Basic Authentication** - Username and password.
* **Bearer Token** - API token in the Authorization header.
* **No Authentication** - If authentication is disabled (default).
## Installation[](#installation "Direct link to Installation")
The no-code Ocean custom integration can be installed in two ways:
* **[Hosted by Port](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md)** — Port manages the infrastructure; configure the connection in the Port UI.
* **[Self-hosted](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup/.md)** — Run the integration in your own infrastructure using Helm or Docker.
Choose one of the following options:
* Hosted by Port
* Helm
* Docker
### Set up in Port
1. Go to the [custom connector page](https://app.port.io/settings/data-sources?section=EXPORTERS\&provider=Custom) and open the no-code Ocean custom integration form.
2. Configure:
* **Identifier**: `prometheus-integration`.
* **Base URL**: your Prometheus server URL (for example `http://prometheus:9090`).
* **Authentication type**: `none`, `basic`, or `bearer_token`, depending on how your Prometheus instance is secured.
* **Credentials**: provide username/password or token if authentication is enabled.
3. Click **Save & install**.
Network access
When using Hosted by Port, Port makes outbound calls to your API from [static IP addresses](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md#port-source-ip-addresses). Your Prometheus instance must be reachable from those addresses.
After the integration is installed, continue to the **Configuration** section on this page and add the resource mappings.
## Prerequisites
* A Kubernetes cluster - the integration's container chart will be deployed to this cluster.
* [`kubectl`](https://kubernetes.io/docs/tasks/tools/#kubectl) and [`helm`](https://helm.sh/) must be installed on your machine. Your `kubectl` CLI must be connected to the Kubernetes cluster where you plan to install the integration.
## Installation
Add Port's Helm repo and install the no-code Ocean custom integration:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, and your Prometheus base URL. If authentication is enabled, also replace `YOUR_PROMETHEUS_USERNAME` and `YOUR_PROMETHEUS_PASSWORD` (or use bearer token).
**Without authentication:**
```
helm repo add --force-update port-labs https://port-labs.github.io/helm-charts
helm upgrade --install my-ocean-prometheus-integration port-labs/port-ocean \
--set port.clientId="YOUR_PORT_CLIENT_ID" \
--set port.clientSecret="YOUR_PORT_CLIENT_SECRET" \
--set port.baseUrl="https://api.port.io" \
--set createPortResourcesOrigin="Empty" \
--set scheduledResyncInterval=120 \
--set integration.identifier="prometheus-integration" \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.config.baseUrl="http://prometheus:9090" \
--set integration.config.authType="none"
```
**With basic authentication:**
```
helm repo add --force-update port-labs https://port-labs.github.io/helm-charts
helm upgrade --install my-ocean-prometheus-integration port-labs/port-ocean \
--set port.clientId="YOUR_PORT_CLIENT_ID" \
--set port.clientSecret="YOUR_PORT_CLIENT_SECRET" \
--set port.baseUrl="https://api.port.io" \
--set createPortResourcesOrigin="Empty" \
--set scheduledResyncInterval=120 \
--set integration.identifier="prometheus-integration" \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.config.baseUrl="http://prometheus:9090" \
--set integration.config.authType="basic" \
--set integration.config.username="YOUR_PROMETHEUS_USERNAME" \
--set integration.config.password="YOUR_PROMETHEUS_PASSWORD"
```
**With bearer token:**
```
helm repo add --force-update port-labs https://port-labs.github.io/helm-charts
helm upgrade --install my-ocean-prometheus-integration port-labs/port-ocean \
--set port.clientId="YOUR_PORT_CLIENT_ID" \
--set port.clientSecret="YOUR_PORT_CLIENT_SECRET" \
--set port.baseUrl="https://api.port.io" \
--set createPortResourcesOrigin="Empty" \
--set scheduledResyncInterval=120 \
--set integration.identifier="prometheus-integration" \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.config.baseUrl="http://prometheus:9090" \
--set integration.config.authType="bearer_token" \
--set integration.config.apiToken="YOUR_PROMETHEUS_BEARER_TOKEN"
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Configuration parameters
This table summarizes the available parameters for the installation.
| Parameter | Description | Example | Required |
| -------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------ | -------- |
| `port.clientId` | Your Port [client id](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.clientSecret` | Your Port [client secret](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.baseUrl` | Your Port API URL (`https://api.port.io` for EU, `https://api.us.port.io` for US). | | ✅ |
| `integration.config.baseUrl` | Base URL of your Prometheus instance. | | ✅ |
| `integration.config.authType` | Authentication type (`none`, `basic`, or `bearer_token`). | none | ✅ |
| `integration.config.username` | Username for basic authentication (required if `authType` is `basic`). | | ❌ |
| `integration.config.password` | Password for basic authentication (required if `authType` is `basic`). | | ❌ |
| `integration.config.apiToken` | Bearer token for authentication (required if `authType` is `bearer_token`). | | ❌ |
| `integration.eventListener.type` | Event listener type. See [event listeners](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md). | POLLING | ✅ |
| `integration.type` | Integration type (must be `custom`). | custom | ✅ |
| `integration.identifier` | Unique identifier for the integration instance. | prometheus-integration | ✅ |
| `scheduledResyncInterval` | Minutes between scheduled syncs. When omitted, the event listener interval is used. | 120 | ❌ |
| `createPortResourcesOrigin` | Set to `Empty` to register only the integration without creating default blueprints or mappings. | Empty | ❌ |
| `sendRawDataExamples` | Sends sample payloads from the API to Port for easier mapping. | true | ❌ |
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
To run the integration using Docker for a one-time sync:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, and your Prometheus base URL. If authentication is enabled, also replace the authentication credentials.
**Without authentication:**
```
docker run -i --rm --platform=linux/amd64 \
-e OCEAN__EVENT_LISTENER='{"type":"ONCE"}' \
-e OCEAN__CREATE_PORT_RESOURCES_ORIGIN="Empty" \
-e OCEAN__SEND_RAW_DATA_EXAMPLES=true \
-e OCEAN__INTEGRATION__IDENTIFIER="prometheus-integration" \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="http://prometheus:9090" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="none" \
-e OCEAN__PORT__CLIENT_ID="YOUR_PORT_CLIENT_ID" \
-e OCEAN__PORT__CLIENT_SECRET="YOUR_PORT_CLIENT_SECRET" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
ghcr.io/port-labs/port-ocean-custom:latest
```
**With basic authentication:**
```
docker run -i --rm --platform=linux/amd64 \
-e OCEAN__EVENT_LISTENER='{"type":"ONCE"}' \
-e OCEAN__CREATE_PORT_RESOURCES_ORIGIN="Empty" \
-e OCEAN__SEND_RAW_DATA_EXAMPLES=true \
-e OCEAN__INTEGRATION__IDENTIFIER="prometheus-integration" \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="http://prometheus:9090" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="basic" \
-e OCEAN__INTEGRATION__CONFIG__USERNAME="YOUR_PROMETHEUS_USERNAME" \
-e OCEAN__INTEGRATION__CONFIG__PASSWORD="YOUR_PROMETHEUS_PASSWORD" \
-e OCEAN__PORT__CLIENT_ID="YOUR_PORT_CLIENT_ID" \
-e OCEAN__PORT__CLIENT_SECRET="YOUR_PORT_CLIENT_SECRET" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
ghcr.io/port-labs/port-ocean-custom:latest
```
**With bearer token:**
```
docker run -i --rm --platform=linux/amd64 \
-e OCEAN__EVENT_LISTENER='{"type":"ONCE"}' \
-e OCEAN__CREATE_PORT_RESOURCES_ORIGIN="Empty" \
-e OCEAN__SEND_RAW_DATA_EXAMPLES=true \
-e OCEAN__INTEGRATION__IDENTIFIER="prometheus-integration" \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="http://prometheus:9090" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="bearer_token" \
-e OCEAN__INTEGRATION__CONFIG__API_TOKEN="YOUR_PROMETHEUS_BEARER_TOKEN" \
-e OCEAN__PORT__CLIENT_ID="YOUR_PORT_CLIENT_ID" \
-e OCEAN__PORT__CLIENT_SECRET="YOUR_PORT_CLIENT_SECRET" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
ghcr.io/port-labs/port-ocean-custom:latest
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
## Set up data model[](#set-up-data-model "Direct link to Set up data model")
Before the integration can sync data, you need to create the required blueprints in Port. These blueprints define the data model for your Prometheus resources.
**To create the blueprints:**
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Click on the `+ Blueprint` button.
3. Copy and paste each blueprint JSON from the sections below.
**Prometheus Alert Blueprint (click to expand)**
Active alerts from Prometheus:
Create in Port
```
{
"identifier": "prometheus-alert",
"title": "Prometheus Alert",
"icon": "Prometheus",
"schema": {
"properties": {
"alertname": {
"title": "Alert Name",
"type": "string"
},
"state": {
"title": "State",
"type": "string"
},
"severity": {
"title": "Severity",
"type": "string"
},
"summary": {
"title": "Summary",
"type": "string"
},
"description": {
"title": "Description",
"type": "string"
},
"activeAt": {
"title": "Active At",
"type": "string",
"format": "date-time"
},
"labels": {
"title": "Labels",
"type": "object"
},
"annotations": {
"title": "Annotations",
"type": "object"
},
"value": {
"title": "Value",
"type": "string"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**Prometheus Rule Blueprint (click to expand)**
Alerting and recording rules:
Create in Port
```
{
"identifier": "prometheus-rule",
"title": "Prometheus Rule",
"icon": "Prometheus",
"schema": {
"properties": {
"name": {
"title": "Name",
"type": "string"
},
"type": {
"title": "Type",
"type": "string"
},
"query": {
"title": "Query",
"type": "string"
},
"duration": {
"title": "Duration",
"type": "string"
},
"labels": {
"title": "Labels",
"type": "object"
},
"annotations": {
"title": "Annotations",
"type": "object"
},
"health": {
"title": "Health",
"type": "string"
},
"lastError": {
"title": "Last Error",
"type": "string"
},
"evaluationTime": {
"title": "Evaluation Time",
"type": "number"
},
"lastEvaluation": {
"title": "Last Evaluation",
"type": "string",
"format": "date-time"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**Prometheus Target Blueprint (click to expand)**
Scrape targets and their health status:
Create in Port
```
{
"identifier": "prometheus-target",
"title": "Prometheus Target",
"icon": "Prometheus",
"schema": {
"properties": {
"scrapePool": {
"title": "Scrape Pool",
"type": "string"
},
"scrapeUrl": {
"title": "Scrape URL",
"type": "string",
"format": "url"
},
"health": {
"title": "Health",
"type": "string"
},
"lastError": {
"title": "Last Error",
"type": "string"
},
"lastScrape": {
"title": "Last Scrape",
"type": "string",
"format": "date-time"
},
"lastScrapeDuration": {
"title": "Last Scrape Duration",
"type": "number"
},
"labels": {
"title": "Labels",
"type": "object"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
## Configuration[](#configuration "Direct link to Configuration")
After installation, define which endpoints to sync in your integration configuration. Each resource maps an API endpoint to Port entities using [JQ expressions](https://stedolan.github.io/jq/manual/) to transform the data.
**Key mapping components:**
* **`kind`**: The API endpoint path (combined with your base URL).
* **`selector.query`**: JQ filter to include/exclude entities (use `'true'` to sync all).
* **`selector.data_path`**: JQ expression pointing to the array of items in the response.
* **`port.entity.mappings`**: How to map API fields to Port entity properties.
For more details on how the no-code Ocean custom integration works, see the [How it works](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview#how-it-works) section in the custom integration overview.
**Prometheus API response format:**
Prometheus API responses follow this structure:
```
{
"status": "success",
"data": {
"alerts": [
{
"labels": {
"alertname": "HighCPUUsage",
"severity": "warning"
},
"annotations": {
"summary": "CPU usage is above 80%"
},
"state": "firing",
"activeAt": "2024-01-15T10:30:00Z",
"value": "85.5"
}
]
}
}
```
The actual data array is typically nested under `.data.alerts`, `.data.groups` (for rules), or `.data.activeTargets` (for targets).
**To configure the mappings:**
1. Go to your [connectors page](https://app.port.io/settings/data-sources).
2. Find your Prometheus integration in the list.
3. Click on the integration to open the mapping editor.
4. Add the resource mapping configurations below.
**Alerts mapping (click to expand)**
Active alerts from `/api/v1/alerts`:
```
resources:
- kind: /api/v1/alerts
selector:
query: 'true'
data_path: '.data.alerts'
port:
entity:
mappings:
identifier: '"\(.labels.alertname)-\(.activeAt)"'
title: .labels.alertname
blueprint: '"prometheus-alert"'
properties:
alertname: .labels.alertname
state: .state
severity: (.labels.severity // "unknown")
summary: (.annotations.summary // "")
description: (.annotations.description // "")
activeAt: .activeAt
labels: .labels
annotations: .annotations
value: (.value // "")
```
Composite identifier
The identifier uses a composite of `alertname` and `activeAt` to ensure uniqueness, as the same alert can fire multiple times. This prevents alerts from overwriting each other.
**Rules mapping (click to expand)**
Alerting and recording rules from `/api/v1/rules`:
```
resources:
- kind: /api/v1/rules
selector:
query: 'true'
data_path: '.data.groups[].rules[]'
port:
entity:
mappings:
identifier: .name
title: .name
blueprint: '"prometheus-rule"'
properties:
name: .name
type: .type
query: .query
duration: (.duration // "")
labels: (.labels // {})
annotations: (.annotations // {})
health: .health
lastError: (.lastError // "")
evaluationTime: (.evaluationTime // 0)
lastEvaluation: .lastEvaluation
```
Rules structure
The `/api/v1/rules` endpoint returns rules grouped by rule group. The mapping uses `.data.groups[].rules[]` to flatten all rules from all groups into a single array.
**Targets mapping (click to expand)**
Scrape targets from `/api/v1/targets`:
```
resources:
- kind: /api/v1/targets
selector:
query: 'true'
data_path: '.data.activeTargets[]'
port:
entity:
mappings:
identifier: .scrapeUrl
title: (.labels.job // .scrapeUrl)
blueprint: '"prometheus-target"'
properties:
scrapePool: .scrapePool
scrapeUrl: .scrapeUrl
health: .health
lastError: (.lastError // "")
lastScrape: .lastScrape
lastScrapeDuration: (.lastScrapeDuration // 0)
labels: .labels
```
Targets structure
The `/api/v1/targets` endpoint returns both `activeTargets` and `droppedTargets`. This mapping only includes active targets. You can add a separate mapping for dropped targets if needed.
5. Click `Save` to save the mapping.
## Customization[](#customization "Direct link to Customization")
If you want to customize your setup or test different API endpoints before committing to a configuration, use the [interactive builder](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/build-your-integration/.md).
**The interactive builder helps you:**
1. Test your Prometheus API endpoints with live data.
2. Automatically detect the data structure and field types.
3. Generate blueprints and resource mappings tailored to your preferences.
4. Get installation commands with your configuration pre-filled.
Simply provide your Prometheus API details, and the builder will generate everything you need to install and create the integration in Port.
---
# Sentry

Loading version...
Port's Sentry integration allows you to model Sentry resources in your software catalog and ingest data into them.
Supported resources [User](https://docs.sentry.io/api/organizations/list-an-organizations-members/)[Team](https://docs.sentry.io/api/teams/list-an-organizations-teams/)[Project](https://docs.sentry.io/api/projects/)[Project Tag](https://docs.sentry.io/api/projects/list-a-tags-values/)[Issue](https://docs.sentry.io/api/events/list-a-projects-issues/)[Issue Tag](https://docs.sentry.io/api/events/list-a-tags-values-for-an-issue/)
## Core support
[Live eventsSee supported resources](#set-up-live-events)
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
* A Sentry account with access to the organization you want to sync.
* Your Port user role is set to `Admin`.
* A Sentry API token for resyncing data into Port.
**Required permissions (click to expand)**
* **Issue & Event**: Read (`event:read`) - for syncing issues and issue tags.
* **Member**: Read (`member:read`) - for syncing organization members and teams.
* **Organization**: Read (`org:read`) - for organization-level API access.
* **Project**: Read (`project:read`) - for syncing projects and project tags.
* **Team**: Read (`team:read`) - for syncing teams and team members.
## Setup[](#setup "Direct link to Setup")
Choose one of the following installation methods: Not sure which method is right for your use case? Check the available [installation methods](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Real-time updates + customizable resync interval
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .email
title: .user.name
blueprint: '"sentryUser"'
properties:
username: .user.username
isActive: .user.isActive
dateJoined: .user.dateJoined
lastLogin: .user.lastLogin
orgRole: .orgRole
inviteStatus: .inviteStatus
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .email
blueprint: '"_user"'
relations:
sentry_user: .email
- kind: project-tag
selector:
query: 'true'
tag: environment
port:
entity:
mappings:
identifier: .slug + "-" + .__tags.name
title: .name + "-" + .__tags.name
blueprint: '"sentryProjectEnvironment"'
properties:
dateCreated: .dateCreated
platform: .platform
status: .status
link: .organization.links.organizationUrl + "/projects/" + .name
- kind: issue-tag
selector:
query: 'true'
tag: environment
port:
entity:
mappings:
identifier: .id + "-" + .item.name
title: .title + " -" + " " + .item.name
blueprint: '"sentryIssue"'
properties:
link: .permalink + "?environment=" + .item.name
status: .status
isUnhandled: .isUnhandled
relations:
projectEnvironment: (.project.slug as $slug | .item | "\($slug)-\(.name)")
assignee:
combinator: '"and"'
rules:
- operator: '"="'
property: '"$identifier"'
value: .assignedTo.email
- kind: team
selector:
query: 'true'
includeMembers: true
port:
entity:
mappings:
identifier: .slug
title: .name
blueprint: '"sentryTeam"'
properties:
dateCreated: .dateCreated
memberCount: .memberCount
roles: .teamRole
projects: .projects | map (.slug)
relations:
members: if .__members != null then .__members | map(.user.email) | map(select(. != null)) else [] end
```
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
Examples of blueprints and the relevant integration configurations:
UserTeamProjectIssueProject Environment
Default mappingYAML
```
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .email
title: .user.name
blueprint: '"sentryUser"'
properties:
username: .user.username
isActive: .user.isActive
dateJoined: .user.dateJoined
lastLogin: .user.lastLogin
orgRole: .orgRole
inviteStatus: .inviteStatus
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .email
blueprint: '"_user"'
relations:
sentry_user: .email
```
Sample payloadJSON
```
{
"id": "10909027",
"email": "developer@getport.io",
"name": "Michael",
"user": {
"id": "1722098",
"name": "Michael",
"username": "developer@getport.io",
"email": "developer@getport.io",
"avatarUrl": "https://gravatar.com/avatar/9645cd28334383caa5efa6a681dddf7cba33f94ddaf234297ba13cb30d5c5718?s=32&d=mm",
"isActive": true,
"hasPasswordAuth": true,
"isManaged": false,
"dateJoined": "2022-01-18T22:38:13.946094Z",
"lastLogin": "2024-11-10T23:25:31.826834Z",
"has2fa": false,
"lastActive": "2024-11-11T07:32:23.490455Z",
"isSuperuser": false,
"isStaff": false,
"experiments": {},
"emails": [
{
"id": "1861335",
"email": "developer@getport.io",
"is_verified": false
}
],
"avatar": {
"avatarType": "letter_avatar",
"avatarUuid": null,
"avatarUrl": null
}
},
"orgRole": "owner",
"pending": false,
"expired": false,
"flags": {
"idp:provisioned": false,
"idp:role-restricted": false,
"sso:linked": true,
"sso:invalid": false,
"member-limit:restricted": false,
"partnership:restricted": false
},
"dateCreated": "2022-01-18T22:33:43.222734Z",
"inviteStatus": "approved",
"inviterName": "Port Admin",
"role": "owner",
"roleName": "Owner"
}
```
Port entityJSON
```
{
"identifier": "developer@getport.io",
"title": "Michael",
"blueprint": "sentryUser",
"icon": "Sentry",
"team": [],
"properties": {
"username": "developer@getport.io",
"isActive": true,
"dateJoined": "2022-01-18T22:38:13.946094Z",
"lastLogin": "2024-11-10T23:25:31.826834Z",
"orgRole": "owner",
"inviteStatus": "approved"
},
"relations": {},
"createdAt": "2024-11-06T08:49:17.700Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2024-11-06T08:59:11.446Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Default mappingYAML
Enable Team Members
The `includeMembers` flag is used to decide enrich the teams response with details about the members of the team. To turn this feature off, set it to `false`.
```
- kind: team
selector:
query: 'true'
includeMembers: true
port:
entity:
mappings:
identifier: .slug
title: .name
blueprint: '"sentryTeam"'
properties:
dateCreated: .dateCreated
memberCount: .memberCount
roles: .teamRole
projects: .projects | map (.slug)
relations:
members: if .__members != null then .__members | map(.user.email) | map(select(. != null)) else [] end
```
Sample payloadJSON
```
{
"id": "1275104",
"slug": "platform-team",
"name": "Developer Experience",
"dateCreated": "2021-11-16T13:25:53.617157Z",
"isMember": true,
"teamRole": "contributor",
"flags": {
"idp:provisioned": false
},
"access": [
"org:read",
"alerts:read",
"project:releases",
"event:write",
"event:read",
"project:read",
"team:read",
"member:read"
],
"hasAccess": true,
"isPending": false,
"memberCount": 43,
"avatar": {
"avatarType": "letter_avatar",
"avatarUuid": null
},
"externalTeams": [],
"projects": [
{
"id": "4504592557998080",
"slug": "admin-service",
"name": "admin-service",
"platform": "node",
"dateCreated": "2023-01-30T08:35:19.602158Z",
"isBookmarked": false,
"isMember": true,
"features": [
"first-event-severity-new-escalation",
"minidump",
"similarity-indexing",
"similarity-view",
"span-metrics-extraction",
"span-metrics-extraction-addons",
"releases"
],
"firstEvent": null,
"firstTransactionEvent": false,
"access": [
"org:read",
"alerts:read",
"project:releases",
"event:write",
"event:read",
"project:read",
"team:read",
"member:read"
],
"hasAccess": true,
"hasCustomMetrics": false,
"hasMinifiedStackTrace": false,
"hasMonitors": false,
"hasProfiles": false,
"hasReplays": false,
"hasFeedbacks": false,
"hasNewFeedbacks": false,
"hasSessions": false,
"hasInsightsHttp": false,
"hasInsightsDb": false,
"hasInsightsAssets": false,
"hasInsightsAppStart": false,
"hasInsightsScreenLoad": false,
"hasInsightsVitals": false,
"hasInsightsCaches": false,
"hasInsightsQueues": false,
"hasInsightsLlmMonitoring": false,
"isInternal": false,
"isPublic": false,
"avatar": {
"avatarType": "letter_avatar",
"avatarUuid": null
},
"color": "#3f8abf",
"status": "active"
},
{
"id": "4508444173533184",
"slug": "oauth-service",
"name": "oauth-service",
"platform": "node-fastify",
"dateCreated": "2024-12-10T13:51:48.350544Z",
"isBookmarked": false,
"isMember": true,
"features": [
"first-event-severity-new-escalation",
"minidump",
"similarity-indexing",
"similarity-view",
"span-metrics-extraction",
"span-metrics-extraction-addons",
"releases"
],
"firstEvent": null,
"firstTransactionEvent": false,
"access": [
"org:read",
"alerts:read",
"project:releases",
"event:write",
"event:read",
"project:read",
"team:read",
"member:read"
],
"hasAccess": true,
"hasCustomMetrics": false,
"hasMinifiedStackTrace": false,
"hasMonitors": false,
"hasProfiles": false,
"hasReplays": false,
"hasFeedbacks": false,
"hasNewFeedbacks": false,
"hasSessions": false,
"hasInsightsHttp": false,
"hasInsightsDb": false,
"hasInsightsAssets": false,
"hasInsightsAppStart": false,
"hasInsightsScreenLoad": false,
"hasInsightsVitals": false,
"hasInsightsCaches": false,
"hasInsightsQueues": false,
"hasInsightsLlmMonitoring": false,
"isInternal": false,
"isPublic": false,
"avatar": {
"avatarType": "letter_avatar",
"avatarUuid": null
},
"color": "#60bf3f",
"status": "active"
}
],
"__members": [
{
"id": "11033546",
"email": "danny@domain.io",
"name": "danny@domain.io",
"user": {
"id": "1823521",
"name": "danny@domain.io",
"username": "6032da5ae6c84433bb139023b23e3774",
"email": "danny@domain.io",
"avatarUrl": "https://gravatar.com/avatar/6fd8727dde707fd7bbf59ddde0f2a803416b082a2ddf538f6edfb0f9535a6dec?s=32&d=mm",
"isActive": true,
"hasPasswordAuth": false,
"isManaged": false,
"dateJoined": "2022-03-21T09:44:08.054654Z",
"lastLogin": "2024-12-09T07:42:25.535883Z",
"has2fa": false,
"lastActive": "2024-12-18T13:02:41.565988Z",
"isSuperuser": false,
"isStaff": false,
"experiments": {},
"emails": [
{
"id": "1965065",
"email": "danny@domain.io",
"is_verified": false
}
],
"avatar": {
"avatarType": "letter_avatar",
"avatarUuid": null,
"avatarUrl": null
}
},
"orgRole": "member",
"pending": false,
"expired": false,
"flags": {
"idp:provisioned": false,
"idp:role-restricted": false,
"sso:linked": true,
"sso:invalid": false,
"member-limit:restricted": false,
"partnership:restricted": false
},
"dateCreated": "2022-03-21T09:44:09.037845Z",
"inviteStatus": "approved",
"inviterName": null,
"role": "member",
"roleName": "Member",
"teamRole": null,
"teamSlug": "getport"
}
]
}
```
Port entityJSON
```
{
"identifier": "platform-team",
"title": "Developer Experience",
"blueprint": "sentryTeam",
"icon": "Sentry",
"properties": {
"dateCreated": "2022-11-16T13:25:53.617157Z",
"memberCount": 1,
"roles": "contributor",
"projects": [
"admin-service",
"oauth-service"
]
},
"relations": {
"members": [
"danny@domain.io"
]
},
"createdAt": "2023-11-06T08:49:17.700Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2023-11-06T08:59:11.446Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| -------------------- | --------- | ----------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `includeMembers` | `boolean` | Whether to include the members of the team, defaults to false Default: `false`. |
Default mappingYAML
```
- kind: project
selector:
query: "true"
port:
entity:
mappings:
identifier: .slug
title: .name
blueprint: '"sentryProject"'
properties:
dateCreated: .dateCreated
platform: .platform
status: .status
link: .organization.links.organizationUrl + "/projects/" + .name
```
Sample payloadJSON
```
{
"id": "4504931759095808",
"slug": "python-fastapi",
"name": "python-fastapi",
"platform": "python-fastapi",
"dateCreated": "2023-03-31T06:18:37.290732Z",
"isBookmarked": false,
"isMember": false,
"features": [
"alert-filters",
"minidump",
"race-free-group-creation",
"similarity-indexing",
"similarity-view",
"span-metrics-extraction",
"span-metrics-extraction-resource",
"releases"
],
"firstEvent": "2023-03-31T06:25:54.666640Z",
"firstTransactionEvent": false,
"access": [],
"hasAccess": true,
"hasMinifiedStackTrace": false,
"hasMonitors": false,
"hasProfiles": false,
"hasReplays": false,
"hasFeedbacks": false,
"hasSessions": false,
"isInternal": false,
"isPublic": false,
"avatar": {
"avatarType": "letter_avatar",
"avatarUuid": null
},
"color": "#913fbf",
"status": "active",
"organization": {
"id": "4504931754901504",
"slug": "test-org",
"status": {
"id": "active",
"name": "active"
},
"name": "Test Org",
"dateCreated": "2023-03-31T06:17:33.619189Z",
"isEarlyAdopter": false,
"require2FA": false,
"requireEmailVerification": false,
"avatar": {
"avatarType": "letter_avatar",
"avatarUuid": null,
"avatarUrl": null
},
"features": [
"performance-tracing-without-performance",
"performance-consecutive-http-detector",
"performance-large-http-payload-detector",
"escalating-issues",
"minute-resolution-sessions",
"performance-issues-render-blocking-assets-detector",
"event-attachments"
],
"links": {
"organizationUrl": "https://test-org.sentry.io",
"regionUrl": "https://us.sentry.io"
},
"hasAuthProvider": false
}
}
```
Port entityJSON
```
{
"identifier": "python-fastapi",
"title": "python-fastapi",
"icon": "Sentry",
"blueprint": "sentryProject",
"team": [],
"properties": {
"dateCreated": "2023-03-31T06:18:37.290732Z",
"platform": "python-fastapi",
"status": "active",
"link": "https://test-org.sentry.io/projects/python-fastapi"
},
"relations": {},
"createdAt": "2023-11-06T08:49:17.700Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2023-11-06T08:59:11.446Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| -------------------- | -------- | ------------------------------------------------------------------------------------------------------------ |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `tag` | `string` | The name of the tag used to filter the resources. The default value is environment Default: `"environment"`. |
Default mappingYAML
```
- kind: issue
selector:
query: "true"
port:
entity:
mappings:
identifier: ".id"
title: ".title"
blueprint: '"sentryIssue"'
properties:
link: ".permalink"
status: ".status"
isUnhandled: ".isUnhandled"
relations:
projectEnvironment: ".project.slug"
assignedTo: .assignedTo.email
```
* Include Archived
You can use the `includeArchived` selector to filter archived/ignored issues. By default, this selector is set to `true`
```
- kind: issue
selector:
query: "true"
includeArchived: false
```
Sample payloadJSON
```
{
"id": "4605173695",
"shareId": "None",
"shortId": "PYTHON-FASTAPI-2",
"title": "ZeroDivisionError: division by zero",
"culprit": "index",
"permalink": "https://test-org.sentry.io/issues/4605173695/",
"logger": "None",
"level": "error",
"status": "unresolved",
"statusDetails": {},
"substatus": "new",
"isPublic": false,
"platform": "python",
"project": {
"id": "4504931759095808",
"name": "python-fastapi",
"slug": "python-fastapi",
"platform": "python-fastapi"
},
"type": "error",
"metadata": {
"value": "division by zero",
"type": "ZeroDivisionError",
"filename": "app.py",
"function": "index",
"display_title_with_tree_label": false,
"in_app_frame_mix": "mixed"
},
"numComments": 0,
"assignedTo": {
"email": "danny@domain.io",
"id": "11033546",
"name": "danny@domain.io"
},
"isBookmarked": false,
"isSubscribed": false,
"subscriptionDetails": "None",
"hasSeen": false,
"annotations": [],
"issueType": "error",
"issueCategory": "error",
"isUnhandled": true,
"count": "1",
"userCount": 0,
"firstSeen": "2023-11-06T08:31:27.058163Z",
"lastSeen": "2023-11-06T08:31:27.058163Z",
"stats": {
"24h": [
[1699174800, 0],
[1699178400, 0],
[1699182000, 0],
[1699250400, 0],
[1699254000, 0],
[1699257600, 1]
]
}
}
```
Port entityJSON
```
{
"identifier": "4605173695",
"title": "ZeroDivisionError: division by zero",
"icon": "Sentry",
"blueprint": "sentryIssue",
"team": [],
"properties": {
"link": "https://test-org.sentry.io/issues/4605173695/",
"status": "unresolved",
"isUnhandled": true
},
"relations": {
"project": "python-fastapi",
"assignedTo": "danny@domain.io"
},
"createdAt": "2023-11-06T08:49:20.406Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2023-11-06T08:49:20.406Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| -------------------- | --------- | ------------------------------------------------------------------------------------------------------------ |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `tag` | `string` | The name of the tag used to filter the resources. The default value is environment Default: `"environment"`. |
| `includeArchived` | `boolean` | Whether to include the archived issues, defaults to true Default: `true`. |
Default mappingYAML
Environment tags
The `selector.tag` key in the `project-tag` kind defines which Sentry tag data is synced to Port. In the configuration provided below, you will ingest all `environment` tag from your Sentry account to Port. For instance, if a Sentry project has 3 environments namely development, staging and production, this configuration will create 3 entities in the `Sentry Project Environment` catalog. You will then use the `issue-tag` kind to connect each issue to its environment.
```
- kind: project-tag
selector:
query: 'true'
tag: environment
port:
entity:
mappings:
identifier: .slug + "-" + .__tags.name
title: .name + "-" + .__tags.name
blueprint: '"sentryProjectEnvironment"'
properties:
dateCreated: .dateCreated
platform: .platform
status: .status
link: .organization.links.organizationUrl + "/projects/" + .name
- kind: issue-tag
selector:
query: 'true'
tag: environment
port:
entity:
mappings:
identifier: .id + "-" + .item.name
title: .title + " -" + " " + .item.name
blueprint: '"sentryIssue"'
properties:
link: .permalink + "?environment=" + .item.name
status: .status
isUnhandled: .isUnhandled
relations:
projectEnvironment: (.project.slug as $slug | .item | "\($slug)-\(.name)")
assignee:
combinator: '"and"'
rules:
- operator: '"="'
property: '"$identifier"'
value: .assignedTo.email
```
Sample payloadJSON
```
{
"id":"4504931759095808",
"slug":"python-fastapi",
"name":"python-fastapi",
"platform":"python-fastapi",
"dateCreated":"2023-03-31T06:18:37.290732Z",
"isBookmarked":false,
"isMember":false,
"features":[
"alert-filters",
"minidump",
"race-free-group-creation",
"similarity-indexing",
"similarity-view",
"span-metrics-extraction",
"span-metrics-extraction-resource",
"releases"
],
"firstEvent":"2023-03-31T06:25:54.666640Z",
"firstTransactionEvent":false,
"access":[
],
"hasAccess":true,
"hasMinifiedStackTrace":false,
"hasMonitors":false,
"hasProfiles":false,
"hasReplays":false,
"hasFeedbacks":false,
"hasSessions":false,
"isInternal":false,
"isPublic":false,
"avatar":{
"avatarType":"letter_avatar",
"avatarUuid":null
},
"color":"#913fbf",
"status":"active",
"organization":{
"id":"4504931754901504",
"slug":"pages-org",
"status":{
"id":"active",
"name":"active"
},
"name":"Pages Org",
"dateCreated":"2023-03-31T06:17:33.619189Z",
"isEarlyAdopter":false,
"require2FA":false,
"requireEmailVerification":false,
"avatar":{
"avatarType":"letter_avatar",
"avatarUuid":null,
"avatarUrl":null
},
"links":{
"organizationUrl":"https://pages-org.sentry.io",
"regionUrl":"https://us.sentry.io"
},
"hasAuthProvider":false
},
"__tags":{
"key":"environment",
"name":"production",
"value":"production",
"count":10,
"lastSeen":"2024-03-04T17:17:33Z",
"firstSeen":"2024-03-04T17:14:22Z"
}
}
```
Port entityJSON
```
{
"identifier": "python-fastapi-production",
"title": "python-fastapi-production",
"icon": "Sentry",
"blueprint": "sentryProjectEnvironment",
"team": [],
"properties": {
"dateCreated": "2023-03-31T06:18:37.290732Z",
"platform": "python-fastapi",
"status": "active",
"link": "https://test-org.sentry.io/projects/python-fastapi"
},
"relations": {
"team": [
"platform-team"
]
},
"createdAt": "2024-03-07T12:18:17.111Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2024-03-07T12:31:52.041Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
## Set up live events[](#set-up-live-events "Direct link to Set up live events")
This integration supports live events, allowing real-time updates to your software catalog without waiting for the next scheduled sync.
Note that different events are supported depending on the resource type.
Supported live event triggers (click to expand)
* Hosted by Port
* Self-hosted
### Live events base URL
For integrations installed using the **Hosted by Port** method, you can obtain the live events base URL from the [Get an integration](/api-reference/get-an-integration/) API. The response includes `liveEventsUuid` and `liveEventsIngestHostname` in the `appSpec` section.
Call the endpoint with your integration's identifier:
```
curl -X GET \
'https://api.port.io/v1/integration/' \
-H 'Authorization: Bearer '
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
In the response, look for the following fields under `spec.appSpec`:
```
{
"spec": {
"appSpec": {
"liveEventsUuid": "abcdefghijk",
"liveEventsIngestHostname": "ingest.ocean.getport.io"
}
}
}
```
Combine them to build the live events base URL:
```
https:///live-events/
```
For example, with the values above, the live events base URL is:
```
https://ingest.ocean.getport.io/live-events/abcdefghijk
```
This is the same URL configured for the integration.
### BaseUrl & webhook configuration[](#baseurl--webhook-configuration "Direct link to BaseUrl & webhook configuration")
To enable real-time updates of the data in your software catalog, you need to define the `liveEvents.baseUrl` parameter.
This parameter should be set to the URL of your Sentry integration instance, which needs to have the option to setup webhooks via HTTP requests/receive HTTP requests, so ensure the network is configured accordingly.
* **If Sentry and the integration are in the same cluster/network**: Use an internal URL (e.g., a Kubernetes service DNS name).
For Kubernetes deployments, create a service to expose the integration pod and use the service URL as `liveEvents.baseUrl`. If both the source system and integration are in the same cluster, an internal ClusterIP service is sufficient.
* **If Sentry is external to the integration's network**: The integration must be exposed via an ingress, load balancer, or public URL that
Sentry
can reach.
Scaling for high-volume, self-hosted deployments
If you're running high volumes of live events in a self-hosted deployment and want better reliability, event durability, or horizontal scalability, you can optionally set up Port's dedicated live events infrastructure. See [live events at scale](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/live-events/.md#live-events-at-scale) for details.
If `liveEvents.baseUrl` is not provided, the integration will continue to function correctly. In such a configuration, to retrieve the latest information from the target system, the [`scheduledResyncInterval`](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md#scheduled-resync) parameter has to be set, or a manual resync will need to be triggered through Port's UI.
Debugging local integrations
To test webhooks or live event delivery to your local environment, expose your local pod or service to the internet using ngrok (e.g. `ngrok http http://localhost:8000`)
To update Port in real time when Sentry issues change, create an internal integration in Sentry and configure it to send issue webhooks to Port.
### Get the webhook URL[](#get-the-webhook-url "Direct link to Get the webhook URL")
* Hosted by Port
* Self-hosted
First create a custom webhook integration in Port, then connect it to Sentry in [Create the internal integration in Sentry](#create-the-internal-integration-in-sentry):
1. Go to the [connectors](https://app.port.io/settings/data-sources) page in Port.
2. Select the **Webhook** tab.
3. Click **Custom integration**. For more details, see the [custom webhook integration](/context-lake/ingestion/ingest-data-into-port/webhook/ingest-via-webhooks-overview/.md) guide.
4. Enter a name for the integration (e.g Sentry Webhook).
5. Enter a description for the integration.
6. Click **Next**.
7. After the custom integration is created, open its card.
8. Select the **Mapping** tab.
9. In the **Configure Webhook event** section, copy the webhook URL. You'll paste it in the [Sentry internal integration](#create-the-internal-integration-in-sentry) steps below.
10. In the **Map the data from the external system into Port** section, add a mapping for Sentry issue events. The mapping uses [JQ](https://stedolan.github.io/jq/manual/#Basicfilters) to select and transform fields from the webhook payload.
Test your mapping
Use the **Test mapping** section to verify that the JQ mapping works with a Sentry webhook payload before saving.
Configure `liveEvents.baseUrl` and webhook security in the **Self-hosted** tab above. Use the resulting webhook URL when you [create the internal integration in Sentry](#create-the-internal-integration-in-sentry) below.
**Example mapping (click to expand)**
```
[
{
"blueprint": "sentryIssue",
"operation": "create",
"filter": ".body.data.issue.id != null",
"entity": {
"identifier": ".body.data.issue.id",
"title": ".body.data.issue.title",
"properties": {
"link": ".body.data.issue.permalink",
"status": ".body.data.issue.status",
"isUnhandled": ".body.data.issue.isUnhandled"
},
"relations": {
"projectEnvironment": ".body.data.issue.project.slug"
}
}
}
]
```
**Example webhook payload (click to expand)**
```
{
"body": {
"action": "resolved",
"data": {
"issue": {
"id": "7324623130",
"shortId": "PROJECT-8V",
"title": "N+1 Query",
"permalink": "https://example.sentry.io/issues/7324623130/",
"level": "info",
"status": "resolved",
"isUnhandled": false,
"project": {
"id": "4509038422523904",
"name": "example-api",
"slug": "example-api",
"platform": "python-django"
},
"firstSeen": "2026-03-10T14:44:04.743762Z",
"lastSeen": "2026-06-09T11:20:54.358658Z"
}
},
"actor": {
"type": "user",
"name": "Example User"
}
},
"headers": {
"Sentry-Hook-Resource": "issue",
"Sentry-Hook-Signature": "",
"Sentry-Hook-Timestamp": "1781025505"
},
"queryParams": {}
}
```
### Create the internal integration in Sentry[](#create-the-internal-integration-in-sentry "Direct link to Create the internal integration in Sentry")
1. Log in to Sentry with your organization's credentials.
2. Click the gear icon (Setting) at the left sidebar of the page.
3. Under **Integrations**, click **Custom Integrations**.
4. At the upper corner of this page, click on **Create New Integration**.
5. Sentry provides two types of integrations: Internal and Public. For the purpose of this guide, choose **Internal Integration** and click on the **Next** button.
6. Under **Internal Integration Details**, input the following details:
* **Name** - use a meaningful name such as "Port Webhook".
* **Webhook URL** - paste the URL from the [webhook URL instructions](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/apm-alerting/sentry/.md?webhook-method=hosted-by-port#get-the-webhook-url) for your installation method.
7. Under **Permissions**, grant **Read** permissions for the **Issue & Event** category.
8. Under **Webhooks**, enable the **issues** checkbox to allow Sentry to report issue events to Port.
9. Click **Save Changes** at the bottom of the page.
Save the client secret
After saving the internal integration, Sentry displays a client secret. Copy it if you want Port to verify the signature of webhook requests from Sentry.
For more details on setting up internal integrations in Sentry, see the [Sentry documentation](https://docs.sentry.io/organization/integrations/integration-platform/#internal-integrations).
### Verify webhook signatures[](#verify-webhook-signatures "Direct link to Verify webhook signatures")
Signature verification is optional. To enable it, use the client secret generated by Sentry when you created the internal integration.
* Hosted by Port
* Self-hosted
1. Select the custom webhook integration's **Settings** tab.
2. Paste the client secret from Sentry's internal integration in the **Secret** field.
3. Set **Signature Header Name** to `Sentry-Hook-Signature`.
4. Set **Signature Algorithm** to `sha256`.
5. Click **Save**.
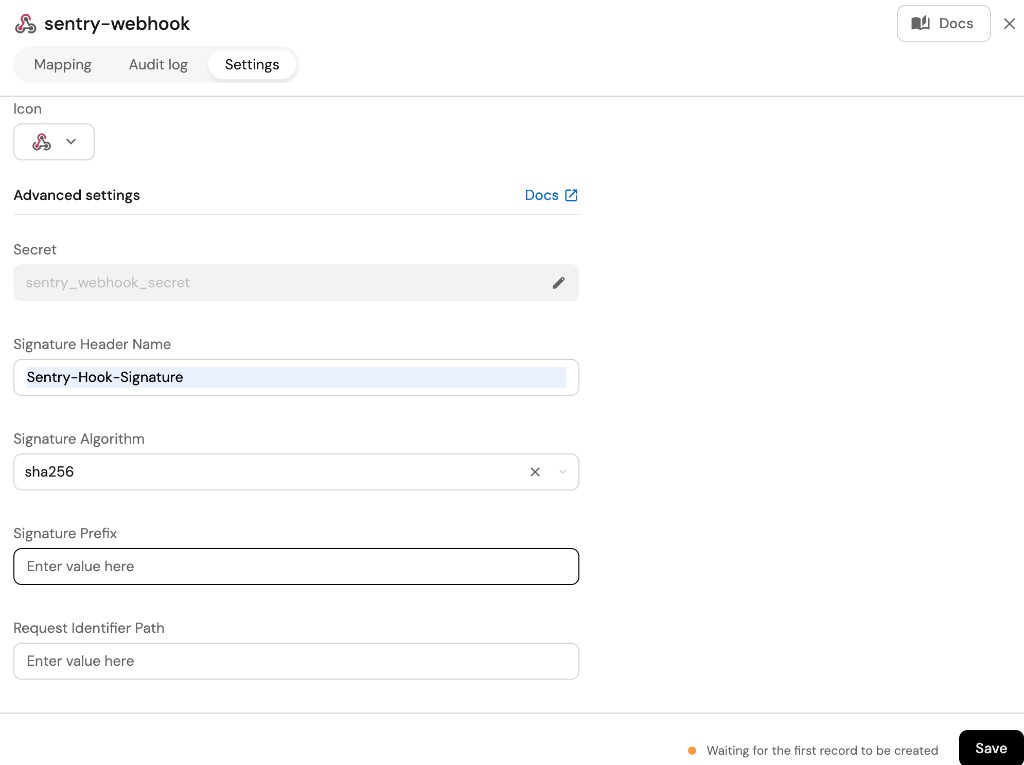
Configure `integration.secrets.sentryWebhookSecret` with the client secret — see the optional parameters in [Setup](#setup).
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
---
# Argo CD

Loading version...
Port's ArgoCD integration allows you to model ArgoCD resources in your software catalog and ingest data into them.
Supported resources [cluster](https://cd.apps.argoproj.io/swagger-ui#operation/ClusterService_List)[project](https://cd.apps.argoproj.io/swagger-ui#operation/ProjectService_List)[application](https://cd.apps.argoproj.io/swagger-ui#operation/ApplicationService_List)[deployment-history](https://cd.apps.argoproj.io/swagger-ui#operation/ApplicationService_List)[kubernetes-resource](https://cd.apps.argoproj.io/swagger-ui#operation/ApplicationService_List)[managed-resource](https://cd.apps.argoproj.io/swagger-ui#operation/ApplicationService_ManagedResources)
## Core support
[Live eventsSee supported resources](#configure-real-time-updates)
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
### ArgoCD API token[](#argocd-api-token "Direct link to ArgoCD API token")
To generate a token:
1. Navigate to `/settings/accounts/`. For example, if you access your ArgoCD at `https://localhost:8080`, you should navigate to `https://localhost:8080/settings/accounts/`
2. The user should have `apiKey` capabilities to allow generating authentication tokens for API access. If you don't have a user created yet, follow the guide on [how to create a new ArgoCD user](https://argo-cd.readthedocs.io/en/stable/operator-manual/user-management/#create-new-user)
3. Newly created users may have limited scope to resources by default. For that reason, You will need to configure the RBAC policy for the new user by following [this guide](https://argo-cd.readthedocs.io/en/stable/operator-manual/rbac/)
4. Ensure that the policy definition grants enough permission to `read` resources such as `applications`, `clusters`, `projects`, `repositories` etc.
5. Under **Tokens** on your ArgoCD UI, Click **Generate New** to create a new token for the user or use the CLI:
```
argocd account generate-token --account
```
6. Create an ArgoCD user with readonly permissions
1. Create an `argocd-user.yaml` file with the below manifest to create a new user `port-ocean-user`
**Create user manifest (click to expand)**
```
apiVersion: v1
kind: ConfigMap
metadata:
name: argocd-cm
namespace: argocd
labels:
app.kubernetes.io/name: argocd-cm
app.kubernetes.io/part-of: argocd
data:
# add an additional local user with apiKey and login capabilities
# apiKey - allows generating API keys
# login - allows to login using UI
accounts.port-ocean-user: apiKey, login
accounts.port-ocean-user.enabled: "true"
```
2. Apply the manifest with `kubectl` to create the user:
```
kubectl apply -f argocd-user.yaml
```
3. Grant read only RBAC policy to the new user using the below manifest file (`argocd-rbac-cm.yaml`)
**RBAC policy to grant readonly role to the new user (click to expand)**
```
apiVersion: v1
kind: ConfigMap
metadata:
name: argocd-rbac-cm
namespace: argocd
data:
policy.default: role:readonly
policy.csv: |
p, role:read-only-role, applications, get, */*, allow
p, role:read-only-role, clusters, get, *, allow
p, role:read-only-role, projects, get, *, allow
p, role:read-only-role, repositories, get, *, allow
g, port-ocean-user, role:read-only-role
```
4. Apply the `argocd-rbac-cm.yaml` manifest with `kubectl`:
```
kubectl apply -f argocd-rbac-cm.yaml
```
5. Go to your ArgoCD UI to generate a new token for the user or use the CLI
```
argocd account generate-token --account
```
## Setup[](#setup "Direct link to Setup")
Choose one of the following installation methods: Not sure which method is right for your use case? Check the available [installation methods](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Self-hosted2Prerequisites3Install
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Prerequisites
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .name
title: .name
blueprint: '"argocdCluster"'
properties:
applicationsCount: .info.applicationsCount
serverVersion: .serverVersion
labels: .labels
updatedAt: .connectionState.attemptedAt
server: .server
- kind: cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .name + "-" + .item | tostring
title: .name + "-" + .item
blueprint: '"argocdNamespace"'
relations:
cluster: .name
itemsToParse: .namespaces
- kind: project
selector:
query: 'true'
port:
entity:
mappings:
identifier: .metadata.name
title: .metadata.name
blueprint: '"argocdProject"'
properties:
createdAt: .metadata.creationTimestamp
description: .spec.description
- kind: application
selector:
query: 'true'
port:
entity:
mappings:
identifier: .metadata.uid
title: .metadata.name
blueprint: '"argocdApplication"'
properties:
gitRepo: .spec.source.repoURL
gitPath: .spec.source.path
destinationServer: .spec.destination.server
revision: .status.sync.revision
targetRevision: .spec.source.targetRevision
syncStatus: .status.sync.status
healthStatus: .status.health.status
createdAt: .metadata.creationTimestamp
labels: .metadata.labels
annotations: .metadata.annotations
relations:
project: .spec.project
namespace: .metadata.namespace
environment:
combinator: '"and"'
rules:
- operator: '"="'
property: '"argoCluster"'
value: .spec.destination.server
cluster:
combinator: '"and"'
rules:
- operator: '"="'
property: '"server"'
value: .spec.destination.server
- kind: application
selector:
query: 'true'
port:
entity:
mappings:
identifier: .metadata.uid + "-" + (.item.id | tostring)
title: .metadata.name + "-" + (.item.id | tostring)
blueprint: '"argocdDeploymentHistory"'
properties:
deployedAt: .item.deployedAt
deployStartedAt: .item.deployStartedAt
revision: .item.source.repoURL + "/commit/" + .item.revision
initiatedBy: .item.initiatedBy.username
repoURL: .item.source.repoURL
sourcePath: .item.source.path
relations:
application: .metadata.uid
anotherRelation: .item.source.repoURL
itemsToParse: .status.history // []
```
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
To view and test the integration's mapping against examples of the third-party API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources). Find the integration in the list of connectors and click on it to open the playground.
Examples of blueprints and the relevant integration configurations can be found on the argocd [examples page](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/argocd/example/.md).
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Capabilities[](#capabilities "Direct link to Capabilities")
### Configure real-time updates[](#configure-real-time-updates "Direct link to Configure real-time updates")
Currently, the ArgoCD REST API lacks support for programmatic webhook creation. To set up a webhook configuration in ArgoCD for sending notifications to the Ocean integration, follow these steps:
1. Install ArgoCD notifications manifest.
```
kubectl apply -n argocd -f https://raw.githubusercontent.com/argoproj-labs/argocd-notifications/release-1.0/manifests/install.yaml
```
2. Install ArgoCD triggers and templates manifest.
```
kubectl apply -n argocd -f https://raw.githubusercontent.com/argoproj-labs/argocd-notifications/release-1.0/catalog/install.yaml
```
3. Use `kubectl` to connect to the Kubernetes cluster where your ArgoCD instance is deployed.
```
kubectl config use-context
```
4. Set the current namespace to your ArgoCD namespace, use the following command.
```
kubectl config set-context --current --namespace=
```
5. Create a YAML file (e.g. `argocd-webhook-config.yaml`) that configures the webhook notification service.
Set up the following components to send real-time events whenever ArgoCD applications are updated:
* Notification service definition.
* Template for the webhook message body.
* Trigger definitions.
* Subscriptions to the notifications.
Use the manifest below and replace `` with the ingress or service URL that exposes your Ocean integration. Keep `/integration/webhook` unchanged because Ocean uses this path for incoming webhook events.
**Webhook manifest file (click to expand)**
```
apiVersion: v1
kind: ConfigMap
metadata:
name: argocd-notifications-cm
data:
trigger.on-sync-operation-change: |
- description: Application syncing has updated
send:
- app-status-change
when: app.status.operationState.phase in ['Error', 'Failed', 'Succeeded', 'Running']
trigger.on-deployed: |
- description: Application is synced and healthy
send:
- app-status-change
when: app.status.operationState.phase in ['Succeeded'] and app.status.health.status == 'Healthy'
trigger.on-health-degraded: |
- description: Application has degraded
send:
- app-status-change
when: app.status.health.status == 'Degraded'
service.webhook.port-ocean: |
url:
headers:
- name: Content-Type
value: application/json
template.app-status-change: |
webhook:
port-ocean:
method: POST
path: /integration/webhook
body: |
{
"action": "upsert",
"application_name": "{{.app.metadata.name}}"
}
subscriptions: |
- recipients:
- port-ocean
triggers:
- on-deployed
- on-health-degraded
- on-sync-operation-change
```
6. Use `kubectl` to apply the YAML file to your cluster. Run the following command, replacing `` with your ArgoCD namespace and `` with the actual path to your YAML file:
```
kubectl apply -n -f
```
This command deploys the webhook notification configuration to your ArgoCD notification configmap (`argocd-notifications-cm`), allowing Ocean to receive real-time events.
### Ocean streaming[](#ocean-streaming "Direct link to Ocean streaming")
The ArgoCD API does not support pagination. This can lead to high memory consumption in large environments when fetching all resources in a single request. To prevent this, you can enable streaming. When enabled, the integration saves the API response to disk and processes it in chunks, which significantly reduces memory usage.
#### Enable streaming[](#enable-streaming "Direct link to Enable streaming")
Add the `streamingEnabled` parameter to the `helm upgrade` command:
```
--set streamingEnabled=true
```
#### Configure streaming[](#configure-streaming "Direct link to Configure streaming")
The streaming process uses a buffer to hold data chunks in memory. A larger buffer can speed up synchronization but also increases memory consumption. By default, the buffer size is 20MB and the chunk size is 64KB.
You can customize these values using the following environment variables:
```
# Example: set chunk size to 64KB (65536 bytes)
OCEAN__STREAMING__CHUNK_SIZE=65536
# Example: set max buffer size to 10MB (1024 * 1024 * 10)
OCEAN__STREAMING__MAX_BUFFER_SIZE_MB=10485760
```
## Examples[](#examples "Direct link to Examples")
To view and test the integration's mapping against examples of the third-party API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources). Find the integration in the list of connectors and click on it to open the playground.
Examples of blueprints and the relevant integration configurations can be found on the argocd [examples page](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/argocd/example/.md)
## Relevant Guides[](#relevant-guides "Direct link to Relevant Guides")
For relevant guides and examples, see the [guides section](https://docs.port.io/guides?tags=ArgoCD).
---
# Examples
To view and test the integration's mapping against examples of the third-party API responses, use the jq playground in your [connectors page](https://app.port.io/settings/data-sources). Find the integration in the list of connectors and click on it to open the playground.
## Cluster[](#cluster "Direct link to Cluster")
**Cluster blueprint (click to expand)**
Create in Port
```
{
"identifier": "argocdCluster",
"description": "This blueprint represents an ArgoCD cluster",
"title": "ArgoCD Cluster",
"icon": "Argo",
"schema": {
"properties": {
"applicationsCount": {
"title": "Applications Count",
"type": "number",
"description": "The number of applications managed by Argo CD on the cluster",
"icon": "DefaultProperty"
},
"serverVersion": {
"title": "Server Version",
"type": "string",
"description": "Contains information about the Kubernetes version of the cluster",
"icon": "DefaultProperty"
},
"labels": {
"title": "Labels",
"type": "object",
"description": "Contains information about cluster metadata",
"icon": "DefaultProperty"
},
"updatedAt": {
"icon": "DefaultProperty",
"title": "Updated At",
"type": "string",
"format": "date-time"
},
"server": {
"title": "Server",
"description": "The API server URL of the Kubernetes cluster",
"type": "string",
"icon": "DefaultProperty"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: cluster
selector:
query: "true"
port:
entity:
mappings:
identifier: .name
title: .name
blueprint: '"argocdCluster"'
properties:
applicationsCount: .info.applicationsCount
serverVersion: .serverVersion
labels: .labels
updatedAt: .connectionState.attemptedAt
server: .server
```
## Namespace[](#namespace "Direct link to Namespace")
**Namespace blueprint (click to expand)**
Create in Port
```
{
"identifier": "argocdNamespace",
"description": "This blueprint represents an ArgoCD namespace",
"title": "ArgoCD Namespace",
"icon": "Argo",
"schema": {
"properties": {},
"required": []
},
"aggregationProperties": {},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {
"cluster": {
"title": "ArgoCD Cluster",
"target": "argocdCluster",
"required": false,
"many": false
}
}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: cluster
selector:
query: "true"
port:
itemsToParse: .namespaces
entity:
mappings:
identifier: .name + "-" + .item | tostring
title: .name + "-" + .item
blueprint: '"argocdNamespace"'
properties: {}
relations:
cluster: .name
```
## Project[](#project "Direct link to Project")
**Project blueprint (click to expand)**
Create in Port
```
{
"identifier": "argocdProject",
"description": "This blueprint represents an ArgoCD Project",
"title": "ArgoCD Project",
"icon": "Argo",
"schema": {
"properties": {
"createdAt": {
"title": "Created At",
"type": "string",
"format": "date-time",
"icon": "DefaultProperty"
},
"description": {
"title": "Description",
"description": "Project description",
"type": "string",
"icon": "DefaultProperty"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: project
selector:
query: "true"
port:
entity:
mappings:
identifier: .metadata.name
title: .metadata.name
blueprint: '"argocdProject"'
properties:
createdAt: .metadata.creationTimestamp
description: .spec.description
```
## Application[](#application "Direct link to Application")
Breaking changes
By default, ArgoCD retrieves applications using a server-side filter in the form of `selector: cluster=`. This means only applications with a matching cluster label are returned, and any applications without this label are excluded.
Starting from version 0.3.0 of the integration, this behavior can be customized. You can enable server-side filtering using the optional queryParams field, which allows you to define your own filtering criteria. The supported format follows the structure described in the [ArgoCD API documentation](https://argo-cd.readthedocs.io/en/latest/developer-guide/api-docs/).
**Application blueprint (click to expand)**
Create in Port
```
{
"identifier": "argocdApplication",
"description": "This blueprint represents an ArgoCD Application",
"title": "Running Service",
"icon": "Argo",
"schema": {
"properties": {
"gitRepo": {
"type": "string",
"icon": "Git",
"title": "Repository URL",
"description": "The URL of the Git repository containing the application source code"
},
"gitPath": {
"type": "string",
"title": "Path",
"description": "The path within the Git repository where the application manifests are located"
},
"destinationServer": {
"type": "string",
"title": "Destination Server",
"description": "The URL of the target cluster's Kubernetes control plane API"
},
"revision": {
"type": "string",
"title": "Revision",
"description": "Revision contains information about the revision the comparison has been performed to"
},
"targetRevision": {
"type": "string",
"title": "Target Revision",
"description": "Target Revision defines the revision of the source to sync the application to. In case of Git, this can be commit, tag, or branch"
},
"syncStatus": {
"type": "string",
"title": "Sync Status",
"enum": [
"Synced",
"OutOfSync",
"Unknown"
],
"enumColors": {
"Synced": "green",
"OutOfSync": "red",
"Unknown": "lightGray"
},
"description": "Status is the sync state of the comparison"
},
"healthStatus": {
"type": "string",
"title": "Health Status",
"enum": [
"Healthy",
"Missing",
"Suspended",
"Degraded",
"Progressing",
"Unknown"
],
"enumColors": {
"Healthy": "green",
"Missing": "yellow",
"Suspended": "purple",
"Degraded": "red",
"Progressing": "blue",
"Unknown": "lightGray"
},
"description": "Status holds the status code of the application or resource"
},
"createdAt": {
"title": "Created At",
"type": "string",
"format": "date-time",
"description": "The created timestamp of the application"
},
"labels": {
"type": "object",
"title": "Labels",
"description": "Map of string keys and values that can be used to organize and categorize object"
},
"annotations": {
"type": "object",
"title": "Annotations",
"description": "Annotations are unstructured key value map stored with a resource that may be set by external tools to store and retrieve arbitrary metadata"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {
"project": {
"title": "ArgoCD Project",
"target": "argocdProject",
"required": false,
"many": false
},
"cluster": {
"title": "ArgoCD Cluster",
"target": "argocdCluster",
"required": false,
"many": false
},
"namespace": {
"title": "ArgoCD Namespace",
"target": "argocdNamespace",
"required": false,
"many": false
}
}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: application
selector:
query: "true"
port:
entity:
mappings:
identifier: .metadata.uid
title: .metadata.name
blueprint: '"argocdApplication"'
properties:
gitRepo: .spec.source.repoURL
gitPath: .spec.source.path
destinationServer: .spec.destination.server
revision: .status.sync.revision
targetRevision: .spec.source.targetRevision
syncStatus: .status.sync.status
healthStatus: .status.health.status
createdAt: .metadata.creationTimestamp
labels: .metadata.labels
annotations: .metadata.annotations
relations:
project: .spec.project
namespace: .metadata.namespace
cluster: .spec.destination.name
```
### Include Query Parameters[](#include-query-parameters "Direct link to Include Query Parameters")
The optional `queryParams` field enables server-side filtering when retrieving ArgoCD applications. It supports the following ArgoCD application query parameters:
* repo
* appNamespace
* selector
* projects
* resourceVersion
This field is not applied by default and must be explicitly defined.
For example, given an application with labels like:
```
{
"metadata": {
"name": "test-application-001",
"namespace": "argocd",
"labels": {
"app-type": "analytics-svc",
"cluster": "prod-ap-northeast-1-006",
"env": "prod",
"instance": "001"
}
}
}
```
You can apply server-side filtering using the `selector` parameter within `queryParams`. The configuration below filters applications belonging to the `argocd` namespace and limits results to those with the label `cluster=prod-ap-northeast-1-006`:
```
- kind: application
selector:
query: "true"
queryParams:
selector: "cluster=prod-ap-northeast-1-006"
appNamespace: "argocd"
startTime: 1
```
## Deployment history[](#deployment-history "Direct link to Deployment history")
Deployment history requires sync operations
Deployment history data in ArgoCD is populated only after sync operations occur on an application. If your application has never been synced, the `.status.history` field will be empty and no deployment history entities will appear in Port.
You do not need to explicitly set `revisionHistoryLimit` in your ArgoCD Application manifest, ArgoCD applies a default value of 10 internally. Once sync operations have been performed, history entries will be recorded and ingested by the integration automatically.
**Deployment history blueprint (click to expand)**
Create in Port
```
{
"identifier": "argocdDeploymentHistory",
"description": "This blueprint represents an ArgoCD deployment history",
"title": "ArgoCD Deployment History",
"icon": "Argo",
"schema": {
"properties": {
"deployedAt": {
"title": "Deployed At",
"type": "string",
"format": "date-time"
},
"deployStartedAt": {
"title": "Deploy Started At",
"type": "string",
"format": "date-time"
},
"revision": {
"title": "Revision",
"type": "string"
},
"initiatedBy": {
"title": "Initiated By",
"type": "string"
},
"repoURL": {
"title": "Repository URL",
"type": "string"
},
"sourcePath": {
"title": "Source Path",
"type": "string"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"application": {
"title": "Application",
"target": "argocdApplication",
"required": false,
"many": false
}
}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: application
selector:
query: "true"
port:
itemsToParse: .status.history
entity:
mappings:
identifier: .metadata.uid + "-" + (.item.id | tostring)
title: .metadata.name + "-" + (.item.id | tostring)
blueprint: '"argocdDeploymentHistory"'
properties:
deployedAt: .item.deployedAt
deployStartedAt: .item.deployStartedAt
revision: .item.source.repoURL + "/commit/" + .item.revision
initiatedBy: .item.initiatedBy.username
repoURL: .item.source.repoURL
sourcePath: .item.source.path
relations:
application: .metadata.uid
```
## Kubernetes Resource[](#kubernetes-resource "Direct link to Kubernetes Resource")
**Images blueprint (click to expand)**
Create in Port
```
{
"identifier": "image",
"description": "This blueprint represents an image",
"title": "Image",
"icon": "AWS",
"schema": {
"properties": {},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**Kubernetes resource blueprint (click to expand)**
Create in Port
```
{
"identifier": "argocdKubernetesResource",
"description": "This blueprint represents an ArgoCD kubernetes resource",
"title": "Kubernetes Resource",
"icon": "Argo",
"schema": {
"properties": {
"kind": {
"title": "Kind",
"type": "string"
},
"version": {
"title": "Version",
"type": "string"
},
"namespace": {
"title": "Namespace",
"type": "string"
},
"labels": {
"type": "object",
"title": "Labels"
},
"annotations": {
"type": "object",
"title": "Annotations"
}
},
"required": []
},
"mirrorProperties": {
"healthStatus": {
"title": "Health Status",
"path": "application.healthStatus"
},
"syncStatus": {
"title": "Sync Status",
"path": "application.syncStatus"
}
},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"application": {
"title": "Application",
"target": "argocdApplication",
"required": false,
"many": false
},
"image": {
"title": "Image",
"target": "image",
"required": false,
"many": false
}
}
}
```
**Integration configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: managed-resource
selector:
query: "true"
port:
entity:
mappings:
identifier: .__application.metadata.uid + "-" + .kind + "-" + .name
title: .__application.metadata.name + "-" + .kind + "-" + .name
blueprint: '"argocdKubernetesResource"'
properties:
kind: .kind
namespace: .namespace
version: if .kind == "Deployment" then .resourceVersion else null end
annotations: (.liveState // .targetState) | fromjson | .metadata.annotations
labels: (.liveState // .targetState) | fromjson | .metadata.labels
relations:
application: .__application.metadata.uid
image: >-
if .kind == "Deployment" then (.liveState // .targetState) |
fromjson | .spec.template.spec.containers[0].image else null end
```
### Include App Filters[](#include-app-filters "Direct link to Include App Filters")
The optional `appFilters` field enables server-side filtering when retrieving ArgoCD applications. It supports the following parameters:
* repo
* appNamespace
* selector
* projects
* resourceVersion
This field is not applied by default and must be explicitly defined.
For example, given an application with labels like:
```
{
"metadata": {
"name": "test-application-001",
"namespace": "argocd",
"labels": {
"app-type": "analytics-svc",
"cluster": "prod-ap-northeast-1-006",
"env": "prod",
"instance": "001"
}
}
}
```
You can apply server-side filtering using the `selector` parameter within `queryParams`. The configuration below filters applications belonging to the `argocd` namespace and limits results to those with the label `cluster=prod-ap-northeast-1-006`:
```
- kind: managed-resource
selector:
query: "true"
appFilters:
selector: "cluster=prod-ap-northeast-1-006"
appNamespace: "argocd"
```
---
# n8n
Custom Ocean integration
This integration was created using the [custom Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework.
Please note that:
1. This integration will not be listed in the `Connectors` page of your Port application, and must be installed manually using the instructions on this page.
2. This integration will not create components (e.g. `blueprints`, `mapping`, etc.) in your portal automatically, you will need to create them manually using the instructions on this page.
Port's n8n integration ingests n8n resources into your software catalog using the [No-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework. It focuses on three key data sources: users, projects, and workflows.
## Supported resources[](#supported-resources "Direct link to Supported resources")
The n8n integration can ingest the following resources into Port:
* `n8nUser` – n8n users from `/v1/users`.
* `n8nProject` – n8n projects from `/v1/projects`.
* `n8nWorkflow` – n8n workflows from `/v1/workflows`.
These resources provide visibility into your n8n automation platform, including user management, project organization, and workflow definitions.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
To use this integration, you need:
1. Port credentials (`CLIENT_ID` and `CLIENT_SECRET`)
2. n8n instance URL (e.g., `https://your-instance.com/api`)
3. n8n API key (see [n8n API docs](https://docs.n8n.io/api/authentication/))
**To create an n8n API key:**
1. Navigate to your n8n instance and sign in to your account.
2. Go to **Settings** → **API**.
3. Click **Create API Key**.
4. Give your key a name (e.g., "Port Integration") and copy the API key.
5. Store the API key securely.
API key security
Store your API key securely and never share it. The key provides access to your n8n instance data.
Review the [n8n API reference](https://docs.n8n.io/api/api-reference/) to understand the exact response structure returned by each endpoint.
## Installation[](#installation "Direct link to Installation")
The no-code Ocean custom integration can be installed in two ways:
* **[Hosted by Port](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md)** — Port manages the infrastructure; configure the connection in the Port UI.
* **[Self-hosted](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup/.md)** — Run the integration in your own infrastructure using Helm or Docker.
Choose one of the following options:
* Hosted by Port
* Helm
* Docker
### Set up in Port
1. Go to the [custom connector page](https://app.port.io/settings/data-sources?section=EXPORTERS\&provider=Custom) and open the no-code Ocean custom integration form.
2. Configure:
* **Identifier**: `n8n-integration`.
* **Base URL**: your n8n instance API URL (for example `https://your-instance.com/api`).
* **Authentication type**: `api_key`.
* **API key header**: `X-N8N-API-KEY`.
* **API key**: your n8n API key.
3. Expand **Advanced configuration** and set:
* **Pagination type**: `cursor`.
* **Pagination parameter**: `cursor`.
* **Page size parameter**: `limit`.
* **Page size**: `100`.
* **Cursor path**: `nextCursor`.
* **Has more path**: `nextCursor`.
4. Click **Save & install**.
Continue with the mappings
After the integration is installed, continue to the **Configuration** section on this page and add the resource mappings.
## Prerequisites
* A Kubernetes cluster - the integration's container chart will be deployed to this cluster.
* [`kubectl`](https://kubernetes.io/docs/tasks/tools/#kubectl) and [`helm`](https://helm.sh/) must be installed on your machine. Your `kubectl` CLI must be connected to the Kubernetes cluster where you plan to install the integration.
## Installation
Add Port's Helm repo and install the no-code Ocean custom integration:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, `YOUR_N8N_INSTANCE_URL`, and `YOUR_N8N_API_KEY`.
```
helm repo add port-labs https://port-labs.github.io/helm-charts
helm repo update
helm install n8n-integration port-labs/port-ocean \
--set initializePortResources=true \
--set scheduledResyncInterval=120 \
--set sendRawDataExamples=true \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.identifier=n8n-integration \
--set integration.config.baseUrl=https://your-instance.com/api \
--set integration.config.authType=api_key \
--set integration.config.apiKeyHeader=X-N8N-API-KEY \
--set integration.secrets.apiKey=YOUR_N8N_API_KEY \
--set integration.config.paginationType=cursor \
--set integration.config.paginationParam=cursor \
--set integration.config.sizeParam=limit \
--set integration.config.pageSize=100 \
--set integration.config.cursorPath=nextCursor \
--set integration.config.hasMorePath=nextCursor \
--set port.clientId=YOUR_PORT_CLIENT_ID \
--set port.clientSecret=YOUR_PORT_CLIENT_SECRET \
--set port.baseUrl="https://api.port.io"
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Configuration parameters
| Parameter | Description | Example | Required |
| ------------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------- | -------- |
| `port.clientId` | Your Port [client id](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.clientSecret` | Your Port [client secret](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.baseUrl` | Your Port API URL (`https://api.port.io` for EU, `https://api.us.port.io` for US). | | ✅ |
| `integration.config.baseUrl` | Base URL for your n8n instance API. | | ✅ |
| `integration.config.authType` | Authentication type for n8n (use `api_key` for n8n). | api\_key | ✅ |
| `integration.config.apiKeyHeader` | Header name for the API key. | X-N8N-API-KEY | ✅ |
| `integration.secrets.apiKey` | n8n API key. | | ✅ |
| `integration.config.paginationType` | Pagination type used by n8n API. | cursor | ✅ |
| `integration.config.paginationParam` | Query parameter name for pagination cursor. | cursor | ✅ |
| `integration.config.sizeParam` | Query parameter name for page size. | limit | ✅ |
| `integration.config.pageSize` | Number of items per page. | 100 | ✅ |
| `integration.config.cursorPath` | JSON path to cursor value in response. | nextCursor | ✅ |
| `integration.config.hasMorePath` | JSON path to check if more pages exist. | nextCursor | ✅ |
| `integration.eventListener.type` | The event listener type. Read more about [event listeners](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md) | POLLING | ✅ |
| `integration.type` | The integration type (must be `custom` for the no-code Ocean custom integration).. | custom | ✅ |
| `integration.identifier` | Unique identifier for this integration instance. | n8n-integration | ✅ |
| `initializePortResources` | Create default blueprints and mappings on first run. | true | ❌ |
| `sendRawDataExamples` | Send sample payloads for easier mapping. | true | ❌ |
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
To run the integration using Docker for a one-time sync:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, `YOUR_N8N_INSTANCE_URL`, and `YOUR_N8N_API_KEY`.
```
docker run -i --rm --platform=linux/amd64 \
-e OCEAN__EVENT_LISTENER='{"type":"ONCE"}' \
-e OCEAN__INITIALIZE_PORT_RESOURCES=true \
-e OCEAN__SEND_RAW_DATA_EXAMPLES=true \
-e OCEAN__INTEGRATION__IDENTIFIER=n8n-integration \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="https://your-instance.com/api" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="api_key" \
-e OCEAN__INTEGRATION__CONFIG__API_KEY_HEADER="X-N8N-API-KEY" \
-e OCEAN__INTEGRATION__CONFIG__API_KEY="YOUR_N8N_API_KEY" \
-e OCEAN__INTEGRATION__CONFIG__PAGINATION_TYPE="cursor" \
-e OCEAN__INTEGRATION__CONFIG__PAGINATION_PARAM="cursor" \
-e OCEAN__INTEGRATION__CONFIG__SIZE_PARAM="limit" \
-e OCEAN__INTEGRATION__CONFIG__PAGE_SIZE="100" \
-e OCEAN__INTEGRATION__CONFIG__CURSOR_PATH="nextCursor" \
-e OCEAN__INTEGRATION__CONFIG__HAS_MORE_PATH="nextCursor" \
-e OCEAN__PORT__CLIENT_ID="YOUR_PORT_CLIENT_ID" \
-e OCEAN__PORT__CLIENT_SECRET="YOUR_PORT_CLIENT_SECRET" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
ghcr.io/port-labs/port-ocean-custom:latest
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
## Set up data model[](#set-up-data-model "Direct link to Set up data model")
Before syncing data, create the blueprints that define your n8n entities (users, projects, and workflows).
**To create the blueprints:**
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Click the `+ Blueprint` button.
3. Copy each blueprint JSON from the sections below.
**n8n User blueprint (click to expand)**
Create in Port
```
{
"identifier": "n8nUser",
"description": "This blueprint represents an n8n user",
"title": "n8n User",
"icon": "User",
"schema": {
"properties": {
"created_at": {
"type": "string",
"title": "Created At",
"format": "date-time"
},
"is_active": {
"type": "boolean",
"title": "Is Active"
},
"email": {
"type": "string",
"title": "Email"
},
"full_name": {
"type": "string",
"title": "Full Name"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**n8n Project blueprint (click to expand)**
Create in Port
```
{
"identifier": "n8nProject",
"description": "This blueprint represents an n8n project",
"title": "n8n Project",
"icon": "OpenFolder",
"schema": {
"properties": {},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**n8n Workflow blueprint (click to expand)**
Create in Port
```
{
"identifier": "n8nWorkflow",
"description": "This blueprint represents an n8n workflow",
"title": "n8n Workflow",
"icon": "Pipeline",
"schema": {
"properties": {
"created_at": {
"type": "string",
"title": "Created At",
"format": "date-time"
},
"updated_at": {
"type": "string",
"title": "Updated At",
"format": "date-time"
},
"is_active": {
"type": "boolean",
"title": "Is Active"
},
"is_archived": {
"type": "boolean",
"title": "Is Archived"
},
"nodes": {
"items": {
"type": "object"
},
"icon": "DefaultProperty",
"type": "array",
"title": "Nodes"
},
"connections": {
"type": "object",
"title": "Connections"
},
"trigger_count": {
"type": "number",
"title": "Trigger Count"
},
"tags": {
"items": {
"type": "string"
},
"type": "array",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"project": {
"title": "Project",
"target": "n8nProject",
"required": false,
"many": false
}
}
}
```
4. Click `Save` after each blueprint is added.
## Configuration[](#configuration "Direct link to Configuration")
Each resource maps an n8n endpoint to the Port entities defined above.
**Key mapping components:**
* **`kind`** – API endpoint path appended to your n8n base URL.
* **`selector`** – Request payload, pagination controls, and data selection logic.
* **`port.entity.mappings`** – JQ expressions that transform the API payload into Port entities.
To configure the mapping:
1. Go to the [connectors page](https://app.port.io/settings/data-sources) of your portal.
2. Find your n8n integration in the list.
3. Click on the integration to open the mapping editor.
4. Add the resource mapping configurations below.
**Complete n8n mapping configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: /v1/users
selector:
query: 'true'
data_path: .data
port:
entity:
mappings:
identifier: .id
title: .email
blueprint: '"n8nUser"'
properties:
full_name: >-
if (.firstName // null) != null or (.lastName // null) != null
then ((.firstName // "") + " " + (.lastName // "")) else .email
end
is_active: (.isPending | not)
created_at: .createdAt
email: .email
- kind: /v1/projects
selector:
query: 'true'
data_path: .data
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"n8nProject"'
properties: {}
- kind: /v1/workflows
selector:
query: 'true'
data_path: .data
port:
entity:
mappings:
identifier: .id
title: .name
blueprint: '"n8nWorkflow"'
properties:
nodes: .nodes
connections: .connections
trigger_count: .triggerCount
is_active: .active
is_archived: .isArchived
tags: (.tags | map(.name))
created_at: .createdAt
updated_at: .updatedAt
relations:
project: .shared[0].projectId
```
5. Click `Save` to save the mapping.
## Customization[](#customization "Direct link to Customization")
If you want to expand beyond the starter resources, use the [interactive builder](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/build-your-integration/.md) to:
1. Test additional n8n endpoints.
2. Explore the response shape and detected property types.
3. Generate blueprint JSON and mapping snippets automatically.
4. Export installation commands with your configuration pre-filled.
Start with the users, projects, and workflows entities above, then add more resources (such as executions or credentials) once you verify the value.
## API Reference[](#api-reference "Direct link to API Reference")
* [n8n Projects API](https://docs.n8n.io/api/api-reference/#tag/projects/get/projects)
* [n8n Users API](https://docs.n8n.io/api/api-reference/#tag/user/get/users)
* [n8n Workflows API](https://docs.n8n.io/api/api-reference/#tag/workflow/get/workflows)
---
# Zapier
Custom Ocean integration
This integration was created using the [custom Ocean integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework.
Please note that:
1. This integration will not be listed in the `Connectors` page of your Port application, and must be installed manually using the instructions on this page.
2. This integration will not create components (e.g. `blueprints`, `mapping`, etc.) in your portal automatically, you will need to create them manually using the instructions on this page.
Port's Zapier integration lets you ingest Zapier apps and zaps into your software catalog using the [No-code Ocean custom integration](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/overview/.md) framework.
## Supported resources[](#supported-resources "Direct link to Supported resources")
This integration ingests the following resources:
* `zapierApp` from the `GET /v2/apps` endpoint.
* `zap` from the `GET /v2/zaps` endpoint.
It is possible to reference any field that appears in the API responses linked above in the mapping configuration.
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
To use this integration, make sure you have:
* A Zapier account with API access.
* A Port client ID and client secret.
* Permission to create blueprints and data-source mappings in Port.
## Authentication[](#authentication "Direct link to Authentication")
Zapier allows two authentication methods for this setup:
1. OAuth 2.0 Authorization Code flow (rolling refresh tokens).
2. Client id passed as a query parameter.
### User access token authentication[](#user-access-token-authentication "Direct link to User access token authentication")
Refresh token rotation
Zapier refresh tokens rotate: every refresh request can return a new refresh token and immediately invalidate the old one.
To keep sync working, you need an external workflow that refreshes tokens and updates the new refresh token in your Port secrets every time it changes.
#### Automate token refresh with GitHub Actions[](#automate-token-refresh-with-github-actions "Direct link to Automate token refresh with GitHub Actions")
You can use this scheduled GitHub Actions workflow to refresh your Zapier token and update repository secrets.
1. Add these repository secrets: `ZAPIER_CLIENT_ID`, `ZAPIER_CLIENT_SECRET`, `ZAPIER_OAUTH_REFRESH_TOKEN`, and `GH_ADMIN_TOKEN`.
2. Set `GH_ADMIN_TOKEN` to a GitHub personal access token with permission to update repository secrets.
3. Reference `ZAPIER_OAUTH_ACCESS_TOKEN` in your integration runtime.
**GitHub Actions workflow example (click to expand)**
```
name: Refresh Zapier OAuth token
on:
schedule:
- cron: "0 */6 * * *"
workflow_dispatch:
jobs:
refresh-token:
runs-on: ubuntu-latest
steps:
- name: Refresh Zapier access token
id: refresh
env:
CLIENT_ID: ${{ secrets.ZAPIER_CLIENT_ID }}
CLIENT_SECRET: ${{ secrets.ZAPIER_CLIENT_SECRET }}
REFRESH_TOKEN: ${{ secrets.ZAPIER_OAUTH_REFRESH_TOKEN }}
run: |
response=$(curl -sS -X POST "https://api.zapier.com/oauth/token" \
-H "Content-Type: application/x-www-form-urlencoded" \
--data-urlencode "grant_type=refresh_token" \
--data-urlencode "client_id=$CLIENT_ID" \
--data-urlencode "client_secret=$CLIENT_SECRET" \
--data-urlencode "refresh_token=$REFRESH_TOKEN")
access_token=$(echo "$response" | jq -r '.access_token')
refresh_token=$(echo "$response" | jq -r '.refresh_token')
if [ -z "$access_token" ] || [ "$access_token" = "null" ]; then
echo "Failed to refresh token: $response"
exit 1
fi
echo "access_token=$access_token" >> "$GITHUB_OUTPUT"
echo "refresh_token=$refresh_token" >> "$GITHUB_OUTPUT"
- name: Update GitHub secrets
env:
GH_TOKEN: ${{ secrets.GH_ADMIN_TOKEN }}
ACCESS_TOKEN: ${{ steps.refresh.outputs.access_token }}
REFRESH_TOKEN: ${{ steps.refresh.outputs.refresh_token }}
run: |
gh secret set ZAPIER_OAUTH_ACCESS_TOKEN --body "$ACCESS_TOKEN"
gh secret set ZAPIER_OAUTH_REFRESH_TOKEN --body "$REFRESH_TOKEN"
```
### Client ID Authentication[](#client-id-authentication "Direct link to Client ID Authentication")
The `GET /v2/apps` endpoint requires a `client_id` query parameter and does not require OAuth.
In No-code Ocean custom integration mappings, query params are typically not backed by Port secrets. Treat `client_id` as configuration and avoid placing sensitive values directly in mapping fields.
## Set up data model[](#set-up-data-model "Direct link to Set up data model")
Before data can sync, create the required blueprints in Port:
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Create blueprints for `zapierApp` and `zap`.
3. Copy and paste each blueprint JSON from the sections below.
4. Click **Save**.
**Zapier app blueprint (click to expand)**
Create in Port
```
{
"identifier": "zapierApp",
"title": "Zapier App",
"icon": "Zapier",
"schema": {
"properties": {
"description": {
"title": "Description",
"type": "string"
},
"image": {
"title": "Image",
"type": "string",
"format": "url"
},
"hex_color": {
"title": "Hex Color",
"type": "string"
},
"action_types": {
"title": "Action Types",
"type": "array"
},
"categories": {
"title": "Categories",
"type": "array"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**Zap blueprint (click to expand)**
Create in Port
```
{
"identifier": "zap",
"title": "Zap",
"icon": "Zapier",
"schema": {
"properties": {
"state": {
"title": "State",
"type": "string"
},
"url": {
"title": "Zap URL",
"type": "string",
"format": "url"
},
"modified_at": {
"title": "Modified At",
"type": "string",
"format": "date-time"
},
"trigger_app": {
"title": "Trigger App",
"type": "string"
},
"action_apps": {
"title": "Action Apps",
"type": "array"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
## Installation[](#installation "Direct link to Installation")
The no-code Ocean custom integration can be installed in two ways:
* **[Hosted by Port](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/hosted-by-port/.md)** — Port manages the infrastructure; configure the connection in the Port UI.
* **[Self-hosted](/context-lake/ingestion/ingest-data-into-port/custom-integration/ocean-custom-integration/installation-types/self-hosted/setup/.md)** — Run the integration in your own infrastructure using Helm or Docker.
Choose one of the following options:
* Hosted by Port
* Helm
* Docker
### Set up in Port
1. Go to the [custom connector page](https://app.port.io/settings/data-sources?section=EXPORTERS\&provider=Custom).
2. Click **+ Connector** and choose **No-code Ocean custom integration**.
3. In the configuration form, enter the following values:
* **Identifier**: `my-ocean-zapier-integration`.
* **Base URL**: `https://api.zapier.com`.
* **Authentication type**: `bearer_token`.
* **Token**: your Zapier OAuth access token.
* **Pagination type**: `link`.
* **Next link path**: `links.next`.
4. Click **Save & install**.
Continue with the mappings
After the integration is installed, continue to the **Resource mappings** section on this page.
## Prerequisites
* A Kubernetes cluster - the integration's container chart will be deployed to this cluster.
* [`kubectl`](https://kubernetes.io/docs/tasks/tools/#kubectl) and [`helm`](https://helm.sh/) must be installed on your machine. Your `kubectl` CLI must be connected to the Kubernetes cluster where you plan to install the integration.
## Installation
1. Add Port's Helm repo and install the no-code Ocean custom integration.
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, and `YOUR_ZAPIER_OAUTH_ACCESS_TOKEN`.
```
helm repo add --force-update port-labs https://port-labs.github.io/helm-charts
helm upgrade --install my-ocean-zapier-integration port-labs/port-ocean \
--set port.clientId="YOUR_PORT_CLIENT_ID" \
--set port.clientSecret="YOUR_PORT_CLIENT_SECRET" \
--set port.baseUrl="https://api.port.io" \
--set createPortResourcesOrigin="Empty" \
--set scheduledResyncInterval=60 \
--set integration.identifier="my-ocean-zapier-integration" \
--set integration.type="custom" \
--set integration.eventListener.type="POLLING" \
--set integration.config.baseUrl="https://api.zapier.com" \
--set integration.config.authType="bearer_token" \
--set integration.config.apiToken="YOUR_ZAPIER_OAUTH_ACCESS_TOKEN" \
--set integration.config.paginationType="link" \
--set integration.config.nextLinkPath="links.next"
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
## Configuration parameters
| Parameter | Description | Example | Required |
| ----------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------- | -------- |
| `port.clientId` | Your Port [client id](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.clientSecret` | Your Port [client secret](https://docs.port.io/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview#find-your-port-credentials). | | ✅ |
| `port.baseUrl` | Your Port API URL - `https://api.getport.io` for EU, `https://api.us.getport.io` for US. | | ✅ |
| `integration.config.baseUrl` | Zapier API base URL. | | ✅ |
| `integration.config.authType` | The authentication type for the API. Use `bearer_token` when you authenticate with an OAuth access token. | bearer\_token | ✅ |
| `integration.config.apiToken` | Zapier OAuth access token to use in `Authorization: Bearer `. | | ✅ |
| `integration.config.paginationType` | Pagination strategy. Use `link` to follow the next URL in Zapier responses. | link | ✅ |
| `integration.config.nextLinkPath` | Path to the next page URL in the response body for link pagination. | links.next | ✅ |
| `integration.eventListener.type` | The event listener type. Read more about [event listeners](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md). | POLLING | ✅ |
| `integration.type` | The integration type (must be `custom` for the no-code Ocean custom integration). | custom | ✅ |
| `integration.identifier` | Unique identifier for the integration instance. | my-ocean-zapier-integration | ✅ |
| `scheduledResyncInterval` | The number of minutes between each resync. When not set the integration will resync for each event listener resync event. Read more about [scheduledResyncInterval](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/event-listeners/.md#scheduled-resync). | 60 | ❌ |
| `createPortResourcesOrigin` | Set to `Empty` to register only the integration without creating default blueprints or mappings. This guide creates blueprints and mappings manually. | Empty | ❌ |
| `sendRawDataExamples` | Enable sending raw data examples from the third party API to Port for testing and managing the integration mapping. Default is true. | true | ❌ |
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
To run the integration using Docker for a one-time sync:
Replace placeholders
Remember to replace the placeholders for `YOUR_PORT_CLIENT_ID`, `YOUR_PORT_CLIENT_SECRET`, and `YOUR_ZAPIER_OAUTH_ACCESS_TOKEN`.
```
docker run -i --rm --platform=linux/amd64 \
-e OCEAN__EVENT_LISTENER='{"type":"ONCE"}' \
-e OCEAN__CREATE_PORT_RESOURCES_ORIGIN="Empty" \
-e OCEAN__SEND_RAW_DATA_EXAMPLES=true \
-e OCEAN__INTEGRATION__CONFIG__BASE_URL="https://api.zapier.com" \
-e OCEAN__INTEGRATION__CONFIG__AUTH_TYPE="bearer_token" \
-e OCEAN__INTEGRATION__CONFIG__API_TOKEN="YOUR_ZAPIER_OAUTH_ACCESS_TOKEN" \
-e OCEAN__INTEGRATION__CONFIG__PAGINATION_TYPE="link" \
-e OCEAN__INTEGRATION__CONFIG__NEXT_LINK_PATH="links.next" \
-e OCEAN__PORT__CLIENT_ID="YOUR_PORT_CLIENT_ID" \
-e OCEAN__PORT__CLIENT_SECRET="YOUR_PORT_CLIENT_SECRET" \
-e OCEAN__PORT__BASE_URL="https://api.port.io" \
ghcr.io/port-labs/port-ocean-custom:latest
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
Advanced integration configuration
For advanced configuration such as proxies or self-signed certificates, see [Ocean advanced configuration](/context-lake/ingestion/ingest-data-into-port/native-integrations/ocean-framework/advanced-configuration/.md).
## Resource mappings[](#resource-mappings "Direct link to Resource mappings")
Use the mappings below to ingest Zapier apps and zaps.
### Zapier apps (`GET /v2/apps`)[](#zapier-apps-get-v2apps "Direct link to zapier-apps-get-v2apps")
```
resources:
- kind: /v2/apps
selector:
query: 'true'
data_path: '.data'
query_params:
client_id: ""
port:
entity:
mappings:
identifier: .id
title: .title
blueprint: '"zapierApp"'
properties:
description: .description
image: .image
hex_color: .hex_color
action_types: .action_types
categories: '[.categories[].slug]'
```
### Zaps (`GET /v2/zaps`)[](#zaps-get-v2zaps "Direct link to zaps-get-v2zaps")
```
resources:
- kind: /v2/zaps
selector:
query: 'true'
data_path: '.data'
port:
entity:
mappings:
identifier: .id
title: .title
blueprint: '"zap"'
properties:
state: .is_enabled
url: .links.html_editor
modified_at: .updated_at
trigger_app: '[.steps[] | select(.type_of == "read")] | first | .app.title'
action_apps: '[.steps[] | select(.type_of == "write") | .app.title]'
```
## Configuration[](#configuration "Direct link to Configuration")
After installation, configure mappings in Port so Ocean can transform Zapier API responses into Port entities.
The mapping `resources[].kind` must match the endpoint path you want to call, relative to your `OCEAN__INTEGRATION__CONFIG__BASE_URL`.
You can use [JQ expressions](https://jqlang.org/manual/) in mappings to filter, reshape, and enrich Zapier data before sync.
## Next step[](#next-step "Direct link to Next step")
Once you pick your exact Zapier endpoints and blueprint schema, update the `resources[]` mappings to match the real request and response payloads from your Zapier account.
## References[](#references "Direct link to References")
* [Zapier API overview](https://docs.zapier.com/powered-by-zapier/api-reference/authentication).
* [Get apps \[v2\] (`GET /v2/apps`)](https://docs.zapier.com/powered-by-zapier/api-reference/apps/get-apps-%5Bv2%5D).
* [Get zaps \[v2\] (`GET /v2/zaps`)](https://docs.zapier.com/powered-by-zapier/api-reference/zaps/get-zaps-%5Bv2%5D).
* [OAuth v2 guide](https://docs.zapier.com/powered-by-zapier/api-reference/authentication).
---
# Jenkins

Loading version...
Port's Jenkins integration allows you to model Jenkins resources in your software catalog and ingest data into them.
Supported resources [Job](https://www.jenkins.io/doc/book/using/remote-access-api/)[Build](https://www.jenkins.io/doc/book/using/remote-access-api/)[User](https://www.jenkins.io/doc/book/using/remote-access-api/)[Stage](https://plugins.jenkins.io/pipeline-rest-api/)
## Prerequisites[](#prerequisites "Direct link to Prerequisites")
* **Jenkins API token** — In Jenkins, click your username and navigate to **Configure** > **API Token** to generate a token to use as the `JENKINS_TOKEN`.
* **Required plugins** — Install the following via **Manage Jenkins** > **Plugins**:
* [**People View**](https://plugins.jenkins.io/people-view/) — Required for user information API (Jenkins 2.452 and above).
* [**Pipeline: Stage View**](https://plugins.jenkins.io/pipeline-stage-view/) — Required for fetching pipeline stage data.
## Setup[](#setup "Direct link to Setup")
Choose your preferred installation method below. Not sure which to pick? See the [installation methods overview](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port
* ✧Port hosts and manages the integration
* ✧Customizable resync interval for data ingestion
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Create jenkins blueprints[](#create-jenkins-blueprints "Direct link to Create jenkins blueprints")
Before configuring the integration, create the following blueprints in your Port organization.
Follow the instructions below to create the blueprints:
1. Go to the [Data model](https://app.port.io/settings/data-model) page in Port.
2. Click on `+ Blueprint`.
3. Click on the `{...} Edit JSON` button.
4. Copy and paste the following JSON configuration:
Recommended order: job, then build, then user.
**Jenkins Job blueprint (click to expand)**
Create in Port
```
{
"identifier": "jenkinsJob",
"description": "This blueprint represents a job event from Jenkins",
"title": "Jenkins Job",
"icon": "Jenkins",
"schema": {
"properties": {
"jobName": {
"type": "string",
"title": "Job Name"
},
"jobStatus": {
"type": "string",
"title": "Job Status",
"enum": ["created", "unknown", "passing", "failing"],
"enumColors": {
"passing": "green",
"created": "darkGray",
"failing": "red",
"unknown": "orange"
}
},
"timestamp": {
"type": "string",
"format": "date-time",
"title": "Timestamp",
"description": "Last updated timestamp of the job"
},
"url": {
"type": "string",
"title": "Project URL"
},
"parentJob": {
"type": "object",
"title": "Parent Job"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
**Jenkins Build blueprint (click to expand)**
Create in Port
```
{
"identifier": "jenkinsBuild",
"description": "This blueprint represents a build event from Jenkins",
"title": "Jenkins Build",
"icon": "Jenkins",
"schema": {
"properties": {
"buildStatus": {
"type": "string",
"title": "Build Status",
"enum": ["SUCCESS", "FAILURE", "UNSTABLE", "ABORTED"],
"enumColors": {
"SUCCESS": "green",
"FAILURE": "red",
"UNSTABLE": "yellow",
"ABORTED": "darkGray"
}
},
"buildUrl": {
"type": "string",
"title": "Build URL",
"description": "URL to the build"
},
"timestamp": {
"type": "string",
"format": "date-time",
"title": "Timestamp",
"description": "Last updated timestamp of the build"
},
"buildDuration": {
"type": "number",
"title": "Build Duration",
"description": "Duration of the build"
}
},
"required": []
},
"mirrorProperties": {
"previousBuildStatus": {
"title": "Previous Build Status",
"path": "previousBuild.buildStatus"
}
},
"calculationProperties": {},
"relations": {
"parentJob": {
"title": "Jenkins Job",
"target": "jenkinsJob",
"required": false,
"many": false
},
"previousBuild": {
"title": "Previous Build",
"target": "jenkinsBuild",
"required": false,
"many": false
}
}
}
```
**Jenkins User blueprint (click to expand)**
Create in Port
```
{
"identifier": "jenkinsUser",
"description": "This blueprint represents a jenkins user",
"title": "Jenkins User",
"icon": "Jenkins",
"schema": {
"properties": {
"url": {
"type": "string",
"title": "URL",
"format": "url"
},
"lastUpdateTime": {
"type": "string",
"format": "date-time",
"title": "Last Update",
"description": "Last updated timestamp of the user"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
5. Click `Create` after copying each blueprint json to save it and repeat the process for the next blueprint.
Stage blueprint
The integration also supports mapping Jenkins pipeline stages, but there is no default `jenkinsStage` blueprint. If you want to ingest stage data, create a custom blueprint that matches the properties in the Stage mapping configuration below.
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: job
selector:
query: 'true'
port:
entity:
mappings:
identifier: .url | split("://")[1] | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") | gsub("/"; "-") | .[:-1]
title: .fullName
blueprint: '"jenkinsJob"'
properties:
jobName: .name
url: .url
jobStatus: '{"notbuilt": "created", "blue": "passing", "red": "failing"}[.color]'
timestamp: .time
parentJob: .__parentJob
- kind: build
selector:
query: 'true'
maxBuildsPerJob: 100
port:
entity:
mappings:
identifier: >-
.url | split("://")[1] | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") | gsub("/"; "-") | .[:-1]
title: .displayName
blueprint: '"jenkinsBuild"'
properties:
buildStatus: .result
buildUrl: .url
buildDuration: .duration
timestamp: .timestamp / 1000 | todate
relations:
parentJob: .url | split("://")[1] | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") | gsub("/"; "-") | .[:-1] | gsub("-[0-9]+$"; "")
previousBuild: >-
if .previousBuild then (.previousBuild.url | split("://")[1] |
sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") |
gsub("/"; "-") | .[:-1]) else null end
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .user.id
title: .user.fullName
blueprint: '"jenkinsUser"'
properties:
url: .user.absoluteUrl
lastUpdateTime: if .lastChange then (.lastChange/1000) else now end | strftime("%Y-%m-%dT%H:%M:%SZ")
```
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
Use the explorer below to view sample payloads and the resulting Port entities for each resource type.
JobBuildUserStage
Default mappingYAML
```
- kind: job
selector:
query: 'true'
port:
entity:
mappings:
identifier: .url | split("://")[1] | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") | gsub("/"; "-") | .[:-1]
title: .fullName
blueprint: '"jenkinsJob"'
properties:
jobName: .name
url: .url
jobStatus: '{"notbuilt": "created", "blue": "passing", "red": "failing"}[.color]'
timestamp: .time
parentJob: .__parentJob
```
Sample payloadJSON
```
{
"_class" : "hudson.model.FreeStyleProject",
"displayName" : "Hello Job",
"fullName" : "Hello Job",
"name" : "Hello Job",
"url" : "http://localhost:8080/job/Hello%20Job/",
"buildable" : true,
"builds" : [
{
"_class" : "hudson.model.FreeStyleBuild",
"displayName" : "#2",
"duration" : 221,
"fullDisplayName" : "Hello Job #2",
"id" : "2",
"number" : 2,
"result" : "SUCCESS",
"timestamp" : 1700569094576,
"url" : "http://localhost:8080/job/Hello%20Job/2/"
},
{
"_class" : "hudson.model.FreeStyleBuild",
"displayName" : "#1",
"duration" : 2214,
"fullDisplayName" : "Hello Job #1",
"id" : "1",
"number" : 1,
"result" : "SUCCESS",
"timestamp" : 1700567994163,
"url" : "http://localhost:8080/job/Hello%20Job/1/"
}
],
"color" : "blue"
}
```
Port entityJSON
```
{
"identifier": "hello-job",
"title": "Hello Job",
"icon": "Jenkins",
"blueprint": "jenkinsJob",
"properties": {
"jobName": "Hello Job",
"url": "http://localhost:8080/job/Hello%20Job/",
"jobStatus": "passing",
"timestamp": "2023-09-08T14:58:14Z"
},
"relations": {},
"createdAt": "2023-12-18T08:37:21.637Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2023-12-18T08:37:21.637Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Default mappingYAML
Build Limit
The `maxBuildsPerJob` selector is an optional parameter that limits the number of builds fetched per job. By default it is set to `100`, meaning the last 100 builds of each job will be fetched. You can increase or decrease this value to control how much build history is ingested.
```
- kind: build
selector:
query: 'true'
maxBuildsPerJob: 100
port:
entity:
mappings:
identifier: >-
.url | split("://")[1] | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") | gsub("/"; "-") | .[:-1]
title: .displayName
blueprint: '"jenkinsBuild"'
properties:
buildStatus: .result
buildUrl: .url
buildDuration: .duration
timestamp: .timestamp / 1000 | todate
relations:
parentJob: .url | split("://")[1] | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") | gsub("/"; "-") | .[:-1] | gsub("-[0-9]+$"; "")
previousBuild: >-
if .previousBuild then (.previousBuild.url | split("://")[1] |
sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") |
gsub("/"; "-") | .[:-1]) else null end
```
Sample payloadJSON
```
{
"_class" : "hudson.model.FreeStyleBuild",
"displayName" : "#2",
"duration" : 221,
"fullDisplayName" : "Hello Job #2",
"id" : "2",
"number" : 2,
"result" : "SUCCESS",
"timestamp" : 1700569094576,
"url" : "http://localhost:8080/job/Hello%20Job/2/"
}
```
Port entityJSON
```
{
"identifier": "hello-job-2",
"title": "Hello Job #2",
"icon": "Jenkins",
"blueprint": "jenkinsBuild",
"properties": {
"buildStatus": "SUCCESS",
"buildUrl": "http://localhost:8080/job/Hello%20Job/2/",
"buildDuration": 221,
"timestamp": "2023-09-08T14:58:14Z"
},
"relations": {
"parentJob": "hello-job"
},
"createdAt": "2023-12-18T08:37:21.637Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2023-12-18T08:37:21.637Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| -------------------- | --------- | ----------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `maxBuildsPerJob` | `integer` | Number of builds to fetch. Defaults to 100 Default: `100`. |
Default mappingYAML
```
- kind: user
selector:
query: 'true'
port:
entity:
mappings:
identifier: .user.id
title: .user.fullName
blueprint: '"jenkinsUser"'
properties:
url: .user.absoluteUrl
lastUpdateTime: if .lastChange then (.lastChange/1000) else now end | strftime("%Y-%m-%dT%H:%M:%SZ")
```
Sample payloadJSON
```
{
"user" : {
"absoluteUrl" : "http://localhost:8080/user/admin",
"fullName" : "admin",
"description" : "System Administrator",
"id" : "admin"
},
"lastChange" : 1700569094576
}
```
Port entityJSON
```
{
"identifier": "admin",
"title": "admin",
"icon": "Jenkins",
"blueprint": "jenkinsUser",
"properties": {
"url": "http://localhost:8080/user/admin",
"lastUpdateTime": "2023-09-08T14:58:14Z"
},
"relations": {},
"createdAt": "2023-12-18T08:37:21.637Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2023-12-18T08:37:21.637Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Default mappingYAML
Control Stage Fetching
To prevent overwhelming your Ocean instance with potentially thousands of stages from Jenkins, the integration requires you to specify a specific job. This ensures that Ocean only retrieves stages related to that job, keeping things focused and efficient.
**Important**: The integration will also fetch stages from all nested jobs within the specified job.
```
- kind: stage
selector:
query: 'true'
# Example jobUrl - replace with your own Jenkins job URL
jobUrl: http://your-jenkins-server/job/your-project/job/your-job
port:
entity:
mappings:
identifier: >-
._links.self.href | sub("^.*?/"; "") | gsub("%20"; "-") |
gsub("%252F"; "-") | gsub("/"; "-")
title: .name
blueprint: '"jenkinsStage"'
properties:
status: .status
startTimeMillis: .startTimeMillis
durationMillis: .durationMillis
stageUrl: env.OCEAN__INTEGRATION__CONFIG__JENKINS_HOST + ._links.self.href
relations:
parentBuild: >-
._links.self.href | sub("/execution/node/[0-9]+/wfapi/describe$";
"") | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") |
gsub("/"; "-")
# Additional stage configurations follow the same pattern.
- kind: stage
selector:
query: 'true'
# Example jobUrl - replace with your own Jenkins job URL
jobUrl: http://your-jenkins-server/job/your-project/job/another-job
port:
entity:
mappings:
identifier: >-
._links.self.href | sub("^.*?/"; "") | gsub("%20"; "-") |
gsub("%252F"; "-") | gsub("/"; "-")
title: .name
blueprint: '"jenkinsStage"'
properties:
status: .status
startTimeMillis: .startTimeMillis
durationMillis: .durationMillis
stageUrl: env.OCEAN__INTEGRATION__CONFIG__JENKINS_HOST + ._links.self.href
relations:
parentBuild: >-
._links.self.href | sub("/execution/node/[0-9]+/wfapi/describe$";
"") | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") |
gsub("/"; "-")
- kind: stage
selector:
query: 'true'
# Example jobUrl - replace with your own Jenkins job URL
jobUrl: http://your-jenkins-server/job/your-project/job/third-job
port:
entity:
mappings:
identifier: >-
._links.self.href | sub("^.*?/"; "") | gsub("%20"; "-") |
gsub("%252F"; "-") | gsub("/"; "-")
title: .name
blueprint: '"jenkinsStage"'
properties:
status: .status
startTimeMillis: .startTimeMillis
durationMillis: .durationMillis
stageUrl: env.OCEAN__INTEGRATION__CONFIG__JENKINS_HOST + ._links.self.href
relations:
parentBuild: >-
._links.self.href | sub("/execution/node/[0-9]+/wfapi/describe$";
"") | sub("^.*?/"; "") | gsub("%20"; "-") | gsub("%252F"; "-") |
gsub("/"; "-")
```
Sample payloadJSON
```
{
"_links": {
"self": {
"href": "/job/Phalbert/job/salesdash/job/master/227/execution/node/17/wfapi/describe"
}
},
"id": "17",
"name": "Declarative: Post Actions",
"execNode": "",
"status": "SUCCESS",
"startTimeMillis": 1717073271079,
"durationMillis": 51,
"pauseDurationMillis": 0
}
```
Port entityJSON
```
{
"identifier": "job-Phalbert-job-salesdash-job-master-229-execution-node-17-wfapi-describe",
"title": "Declarative: Post Actions",
"icon": "Jenkins",
"blueprint": "jenkinsStage",
"team": [],
"properties": {
"status": "SUCCESS",
"startTimeMillis": 1717073272012,
"durationMillis": 26,
"stageUrl": "http://localhost:8080/job/Phalbert/job/salesdash/job/master/229/execution/node/17/wfapi/describe"
},
"relations": {
"parentBuild": "job-Phalbert-job-salesdash-job-master-229"
},
"createdAt": "2024-08-28T10:27:33.549Z",
"createdBy": "",
"updatedAt": "2024-08-28T10:27:30.274Z",
"updatedBy": ""
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| -------------------- | -------- | ----------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `jobUrl` | `string` | The URL of the Jenkins job to fetch stages for. |
---
# Octopus Deploy Integration

Loading version...
Port's Octopus Deploy integration allows you to model Octopus Deploy resources in your software catalog and ingest data into them.
Supported resources [Space](https://octopus.com/docs/octopus-rest-api/examples/spaces)[Project](https://octopus.com/docs/octopus-rest-api/examples/projects)[Release](https://octopus.com/docs/octopus-rest-api/examples/releases)[Deployment](https://octopus.com/docs/octopus-rest-api/examples/deployments)[Machine](https://octopus.com/docs/infrastructure/deployment-targets)
## Core support
[Live eventsSee supported resources](#set-up-live-events)
Ingesting Additional Resources
The integration supports additional resources, see the [ingest additional resources](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/octopus-deploy/mapping-extra-resources/.md) page for more information.
## Setup[](#setup "Direct link to Setup")
Choose your preferred installation method below. Not sure which to pick? See the [installation methods overview](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Customizable resync interval for data ingestion
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: space
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusSpace"'
properties:
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .Id
description: .Description
- kind: project
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusProject"'
properties:
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .SpaceId + "/projects/" + .Id
description: .Description
isDisabled: .IsDisabled
tenantedDeploymentMode: .TenantedDeploymentMode
relations:
space: .SpaceId
- kind: release
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .ProjectId + "(" + .Version + ")"
blueprint: '"octopusRelease"'
properties:
version: .Version
assembledDate: .Assembled
channelId: .ChannelId
releaseNotes: .ReleaseNotes
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .SpaceId + "/releases/" + .Id
relations:
project: .ProjectId
- kind: deployment
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusDeployment"'
properties:
createdAt: .Created
deployedBy: .DeployedBy
taskId: .TaskId
failureEncountered: .FailureEncountered
comments: .Comments
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .SpaceId + "/deployments/" + .Id
relations:
release: .ReleaseId
project: .ProjectId
- kind: machine
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusMachine"'
properties:
roles: .Roles
status: .HealthStatus
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .SpaceId + "/infrastructure/machines/" + .Id + "/settings"
isDisabled: .IsDisabled
operatingSystem: .OperatingSystem
architecture: .Architecture
statusSummary: .StatusSummary
endpointType: .Endpoint.DeploymentTargetTypeId
communicationStyle: .Endpoint.CommunicationStyle
relations:
space: .SpaceId
```
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
Use the explorer below to view sample payloads and the resulting Port entities for each resource type. For additional resources and advanced configurations, see the [ingest additional resources](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/octopus-deploy/mapping-extra-resources/.md) page.
SpaceProjectReleaseDeploymentMachine
Default mappingYAML
```
- kind: space
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusSpace"'
properties:
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .Id
description: .Description
```
Sample payloadJSON
```
{
"Id": "Spaces-1",
"Name": "Default",
"Slug": "default",
"Description": "Description cannot be empty",
"IsDefault": true,
"IsPrivate": false,
"TaskQueueStopped": false,
"SpaceManagersTeams": [
"teams-administrators",
"teams-managers",
"teams-spacemanagers-Spaces-1"
],
"SpaceManagersTeamMembers": [],
"Icon": null,
"ExtensionSettings": [],
"LastModifiedOn": "0001-01-01T00:00:00.000+00:00",
"Links": {
"Self": "/api/spaces/Spaces-1",
"SpaceHome": "/api/Spaces-1",
"Web": "/app#/spaces/Spaces-1",
"Logo": "/api/spaces/Spaces-1/logo?cb=2024.3.10989",
"Search": "/api/spaces/Spaces-1/search"
}
}
```
Port entityJSON
```
{
"identifier": "Spaces-1",
"title": "Default",
"icon": "Octopus",
"blueprint": "octopusSpace",
"team": [],
"properties": {
"url": "https://testport.octopus.app/app#/Spaces-1",
"description": null
},
"relations": {},
"createdAt": "2024-08-22T14:27:34.746Z",
"createdBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT",
"updatedAt": "2024-08-22T14:27:34.746Z",
"updatedBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT"
}
```
Default mappingYAML
```
- kind: project
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusProject"'
properties:
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .SpaceId + "/projects/" + .Id
description: .Description
isDisabled: .IsDisabled
tenantedDeploymentMode: .TenantedDeploymentMode
relations:
space: .SpaceId
```
Sample payloadJSON
```
{
"Id": "Projects-1",
"SpaceId": "Spaces-1",
"VariableSetId": "variableset-Projects-1",
"DeploymentProcessId": "deploymentprocess-Projects-1",
"ClonedFromProjectId": null,
"DiscreteChannelRelease": false,
"IncludedLibraryVariableSetIds": [],
"DefaultToSkipIfAlreadyInstalled": false,
"TenantedDeploymentMode": "Untenanted",
"DefaultGuidedFailureMode": "EnvironmentDefault",
"VersioningStrategy": {
"Template": null,
"DonorPackage": null
},
"ReleaseCreationStrategy": {
"ChannelId": null,
"ReleaseCreationPackage": null,
"ReleaseCreationPackageStepId": null
},
"Templates": [],
"AutoDeployReleaseOverrides": [],
"ReleaseNotesTemplate": null,
"DeploymentChangesTemplate": null,
"ForcePackageDownload": false,
"Icon": {
"Id": "map-signs",
"Color": "#5E2EA2"
},
"AllowIgnoreChannelRules": true,
"ExecuteDeploymentsOnResilientPipeline": null,
"ExtensionSettings": [],
"Name": "Sample Project",
"Slug": "sample-project",
"Description": "Explore how to automate your deployments with Octopus Deploy.\n\nEdit the custom script step, tweak the variables, and run your first deployment. Experiment and make it your own!",
"IsDisabled": false,
"ProjectGroupId": "ProjectGroups-2",
"LifecycleId": "Lifecycles-2",
"AutoCreateRelease": false,
"IsVersionControlled": false,
"PersistenceSettings": {
"Type": "Database"
},
"ProjectConnectivityPolicy": {
"SkipMachineBehavior": "None",
"TargetRoles": [],
"AllowDeploymentsToNoTargets": false,
"ExcludeUnhealthyTargets": false
},
"Links": {
"Self": "/api/Spaces-1/projects/Projects-1",
"Variables": "/api/Spaces-1/projects/Projects-1/variables",
"Releases": "/api/Spaces-1/projects/Projects-1/releases{/version}{?skip,take,searchByVersion}",
"Channels": "/api/Spaces-1/projects/Projects-1/channels{/id}{?skip,take,partialName}",
"Triggers": "/api/Spaces-1/projects/Projects-1/triggers{?skip,take,partialName,triggerActionType,triggerActionCategory,runbooks}",
"ScheduledTriggers": "/api/Spaces-1/projects/Projects-1/triggers/scheduled{?skip,take,partialName,ids}",
"OrderChannels": "/api/Spaces-1/projects/Projects-1/channels/order",
"Progression": "/api/Spaces-1/projects/Projects-1/progression{?releaseHistoryCount}",
"RunbookTaskRunDashboardItemsTemplate": "/api/Spaces-1/progression/runbooks/taskRuns{?skip,take,ids,projectIds,runbookIds,environmentIds,tenantIds,taskIds}",
"DeploymentProcess": "/api/Spaces-1/projects/Projects-1/deploymentprocesses",
"DeploymentSettings": "/api/Spaces-1/projects/Projects-1/deploymentsettings",
"Web": "/app#/Spaces-1/projects/Projects-1",
"Logo": "/api/Spaces-1/projects/Projects-1/logo?cb=map-signs-%235E2EA2-2024.3.10989",
"Metadata": "/api/Spaces-1/projects/Projects-1/metadata",
"Runbooks": "/api/Spaces-1/projects/Projects-1/runbooks{?skip,take,partialName}",
"RunbookSnapshots": "/api/Spaces-1/projects/Projects-1/runbookSnapshots{/name}{?skip,take,searchByName}",
"Summary": "/api/Spaces-1/projects/Projects-1/summary",
"GitConnectionTest": "/api/Spaces-1/projects/Projects-1/git/connectivity-test",
"InsightsMetrics": "/api/Spaces-1/projects/Projects-1/insights/metrics{?channelId,environmentId,tenantId,tenantFilter,timeRange,granularity,timeZone}",
"GitCompatibilityReport": "/api/Spaces-1/projects/Projects-1/git/compatibility-report",
"ConvertToGit": "/api/Spaces-1/projects/Projects-1/git/convert",
"ConvertToVcs": "/api/Spaces-1/projects/Projects-1/git/convert"
}
}
```
Port entityJSON
```
{
"identifier": "Projects-1",
"title": "Sample Project",
"icon": "Octopus",
"blueprint": "octopusProject",
"team": [],
"properties": {
"slug": null,
"url": "https://testport.octopus.app/app#/Spaces-1/projects/Projects-1",
"description": "Explore how to automate your deployments with Octopus Deploy.\n\nEdit the custom script step, tweak the variables, and run your first deployment. Experiment and make it your own!",
"isDisabled": false,
"tenantedDeploymentMode": "Untenanted"
},
"relations": {},
"createdAt": "2024-08-22T14:27:37.814Z",
"createdBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT",
"updatedAt": "2024-08-22T14:27:37.814Z",
"updatedBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT"
}
```
Default mappingYAML
```
- kind: release
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .ProjectId + "(" + .Version + ")"
blueprint: '"octopusRelease"'
properties:
version: .Version
assembledDate: .Assembled
channelId: .ChannelId
releaseNotes: .ReleaseNotes
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .SpaceId + "/releases/" + .Id
relations:
project: .ProjectId
```
Sample payloadJSON
```
{
"Id": "Releases-44",
"SpaceId": "Spaces-1",
"ProjectId": "Projects-41",
"Version": "0.0.2",
"ChannelId": "Channels-41",
"ReleaseNotes": null,
"ProjectDeploymentProcessSnapshotId": "deploymentprocess-Projects-41-s-1-QXLY2",
"IgnoreChannelRules": false,
"BuildInformation": [],
"Assembled": "2024-08-21T16:17:46.750+00:00",
"LibraryVariableSetSnapshotIds": [],
"SelectedPackages": [],
"SelectedGitResources": [],
"ProjectVariableSetSnapshotId": "variableset-Projects-41-s-0-S6LJL",
"VersionControlReference": null,
"Links": {
"Self": "/api/Spaces-1/releases/Releases-44",
"Project": "/api/Spaces-1/projects/Projects-41",
"Channel": "/api/Spaces-1/projects/Projects-41/channels/Channels-41",
"Progression": "/api/Spaces-1/releases/Releases-44/progression",
"Deployments": "/api/Spaces-1/releases/Releases-44/deployments{?skip,take}",
"DeploymentTemplate": "/api/Spaces-1/releases/Releases-44/deployments/template",
"Artifacts": "/api/Spaces-1/artifacts?regarding=Releases-44",
"ProjectVariableSnapshot": "/api/Spaces-1/variables/variableset-Projects-41-s-0-S6LJL",
"ProjectDeploymentProcessSnapshot": "/api/Spaces-1/deploymentprocesses/deploymentprocess-Projects-41-s-1-QXLY2",
"Web": "/app#/Spaces-1/releases/Releases-44",
"SnapshotVariables": "/api/Spaces-1/releases/Releases-44/snapshot-variables",
"Defects": "/api/Spaces-1/releases/Releases-44/defects",
"ReportDefect": "/api/Spaces-1/releases/Releases-44/defects",
"ResolveDefect": "/api/Spaces-1/releases/Releases-44/defects/resolve",
"DeploymentPreviews": "/api/Spaces-1/releases/Releases-44/deployments/previews/",
"Variables": "/api/Spaces-1/projects/Projects-41/releases/Releases-44/variables"
}
}
```
Port entityJSON
```
{
"identifier": "Releases-44",
"title": "Projects-41(0.0.2)",
"icon": "Octopus",
"blueprint": "octopusRelease",
"team": [],
"properties": {
"version": "0.0.2",
"assembledDate": "2024-08-21T16:17:46.750+00:00",
"channelId": "Channels-41",
"releaseNotes": null,
"url": "https://testport.octopus.app/app#/Spaces-1/releases/Releases-44"
},
"relations": {},
"createdAt": "2024-08-22T14:27:41.697Z",
"createdBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT",
"updatedAt": "2024-08-22T14:27:41.697Z",
"updatedBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT"
}
```
Default mappingYAML
```
- kind: deployment
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusDeployment"'
properties:
createdAt: .Created
deployedBy: .DeployedBy
taskId: .TaskId
failureEncountered: .FailureEncountered
comments: .Comments
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .SpaceId + "/deployments/" + .Id
relations:
release: .ReleaseId
project: .ProjectId
```
Sample payloadJSON
```
{
"Id": "Deployments-1",
"SpaceId": "Spaces-1",
"ReleaseId": "Releases-1",
"ChannelId": "Channels-2",
"DeploymentProcessId": "deploymentprocess-Projects-1-s-1-CGNSF",
"Changes": [],
"ChangesMarkdown": null,
"EnvironmentId": "Environments-1",
"TenantId": null,
"ForcePackageDownload": false,
"ForcePackageRedeployment": false,
"Priority": "LifecycleDefault",
"SkipActions": [],
"SpecificMachineIds": [],
"ExcludedMachineIds": [],
"ManifestVariableSetId": null,
"TaskId": "ServerTasks-11599",
"ProjectId": "Projects-1",
"UseGuidedFailure": false,
"Comments": null,
"FormValues": {},
"QueueTime": null,
"QueueTimeExpiry": null,
"Name": "Deploy to Development",
"Created": "2024-08-02T05:07:42.445+00:00",
"TentacleRetentionPeriod": null,
"ChangeRequestSettings": null,
"DeployedBy": "System",
"DeployedById": null,
"FailureEncountered": false,
"DeployedToMachineIds": [],
"ExecutionPlanLogContext": {
"Steps": []
},
"Links": {
"Self": "/api/Spaces-1/deployments/Deployments-1",
"Release": "/api/Spaces-1/releases/Releases-1",
"Environment": "/api/Spaces-1/environments/Environments-1",
"Project": "/api/Spaces-1/projects/Projects-1",
"Task": "/api/tasks/ServerTasks-11599",
"Web": "/app#/Spaces-1/deployments/Deployments-1",
"Artifacts": "/api/Spaces-1/artifacts?regarding=Deployments-1",
"Interruptions": "/api/Spaces-1/interruptions?regarding=Deployments-1",
"DeploymentProcess": "/api/Spaces-1/deploymentprocesses/deploymentprocess-Projects-1-s-1-CGNSF"
}
}
```
Port entityJSON
```
{
"identifier": "Deployments-1",
"title": "Deploy to Development",
"icon": "Octopus",
"blueprint": "octopusDeployment",
"team": [],
"properties": {
"createdAt": "2024-08-02T05:07:42.445+00:00",
"deployedBy": "System",
"taskId": "ServerTasks-11599",
"failureEncountered": false,
"comments": null,
"url": "https://testport.octopus.app/app#/Spaces-1/deployments/Deployments-1"
},
"relations": {},
"createdAt": "2024-08-22T14:27:45.276Z",
"createdBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT",
"updatedAt": "2024-08-22T14:27:45.276Z",
"updatedBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT"
}
```
Default mappingYAML
```
- kind: machine
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusMachine"'
properties:
roles: .Roles
status: .HealthStatus
url: env.OCEAN__INTEGRATION__CONFIG__SERVER_URL + "/app#/" + .SpaceId + "/infrastructure/machines/" + .Id + "/settings"
isDisabled: .IsDisabled
operatingSystem: .OperatingSystem
architecture: .Architecture
statusSummary: .StatusSummary
endpointType: .Endpoint.DeploymentTargetTypeId
communicationStyle: .Endpoint.CommunicationStyle
relations:
space: .SpaceId
```
Sample payloadJSON
```
{
"Id": "Machines-4",
"EnvironmentIds": [
"Environments-1"
],
"Roles": [
"test-server"
],
"TenantedDeploymentParticipation": "Untenanted",
"TenantIds": [],
"TenantTags": [],
"SpaceId": "Spaces-1",
"Name": "ECS Instance Dev",
"Thumbprint": null,
"Uri": null,
"IsDisabled": false,
"MachinePolicyId": "MachinePolicies-1",
"HealthStatus": "Unhealthy",
"HasLatestCalamari": true,
"StatusSummary": "There was a problem communicating with this machine (last checked: Tuesday, 27 August 2024 5:39:57 PM +00:00)",
"IsInProcess": false,
"Endpoint": {
"CommunicationStyle": "StepPackage",
"DeploymentTargetTypeId": "aws-ecs-target",
"StepPackageId": "aws-ecs-target",
"StepPackageVersion": "3.0.1",
"LastSavedStepPackageVersion": "3.0.1",
"Inputs": {
"clusterName": " team-isaac",
"region": "eu-west-1",
"authentication": {
"credentials": {
"type": "account",
"account": "Accounts-1"
},
"role": {
"type": "noAssumedRole"
}
}
},
"DefaultWorkerPoolId": "",
"Id": null,
"LastModifiedOn": null,
"LastModifiedBy": null,
"Links": {
"Logo": "/api/steps/deploymenttargets/aws-ecs-target/3.0.1/logo"
}
},
"OperatingSystem": "Unknown",
"ShellName": "Unknown",
"ShellVersion": "Unknown",
"Architecture": "Unknown",
"Slug": "ecs-instance-dev",
"SkipInitialHealthCheck": false,
"Links": {
"Self": "/api/Spaces-1/machines/Machines-4",
"Connection": "/api/Spaces-1/machines/Machines-4/connection",
"TasksTemplate": "/api/Spaces-1/machines/Machines-4/tasks{?skip,take,type}",
"SinglyScopedVariableDetails": "/api/Spaces-1/machines/Machines-4/singlyScopedVariableDetails"
}
}
```
Port entityJSON
```
{
"identifier": "Machines-4",
"title": "ECS Instance Dev",
"icon": "Octopus",
"blueprint": "octopusMachine",
"team": [],
"properties": {
"roles": [
"test-server"
],
"status": "Unhealthy",
"url": "https://testport.octopus.app/app#/Spaces-1/infrastructure/machines/Machines-4/settings",
"isDisabled": false,
"operatingSystem": "Unknown",
"architecture": "Unknown",
"statusSummary": "There was a problem communicating with this machine (last checked: Monday, 26 August 2024 5:40:16 PM +00:00)",
"endpointType": "aws-ecs-target",
"communicationStyle": "StepPackage"
},
"relations": {},
"createdAt": "2024-08-22T14:27:53.944Z",
"createdBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT",
"updatedAt": "2024-08-27T12:29:12.362Z",
"updatedBy": "zhOWp1YybWfY12bAxNz3d1ByX18iA1yT"
}
```
## Set up live events[](#set-up-live-events "Direct link to Set up live events")
This integration supports live events, allowing real-time updates to your software catalog without waiting for the next scheduled sync.
Note that different events are supported depending on the resource type.
Supported live event triggers (click to expand)
* Hosted by Port
### Live events base URL
For integrations installed using the **Hosted by Port** method, you can obtain the live events base URL from the [Get an integration](/api-reference/get-an-integration/) API. The response includes `liveEventsUuid` and `liveEventsIngestHostname` in the `appSpec` section.
Call the endpoint with your integration's identifier:
```
curl -X GET \
'https://api.port.io/v1/integration/' \
-H 'Authorization: Bearer '
```
Selecting a Port API URL by account region
The `port_region`, `port.baseUrl`, `portBaseUrl`, `port_base_url` and `OCEAN__PORT__BASE_URL` parameters select which Port API instance to use:
* **EU** ([app.port.io](https://app.port.io)) → `https://api.port.io`
* **US** ([app.us.port.io](https://app.us.port.io)) → `https://api.us.port.io`
In the response, look for the following fields under `spec.appSpec`:
```
{
"spec": {
"appSpec": {
"liveEventsUuid": "abcdefghijk",
"liveEventsIngestHostname": "ingest.ocean.getport.io"
}
}
}
```
Combine them to build the live events base URL:
```
https:///live-events/
```
For example, with the values above, the live events base URL is:
```
https://ingest.ocean.getport.io/live-events/abcdefghijk
```
This is the same URL configured for the integration.
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
---
# Ingest additional resources
In addition to the supported resources listed in the [integration page](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cicd/octopus-deploy/.md), other resources can be ingested, as described on this page.
This page will help you understand what kind of Octopus Deploy resources are supported by the integration and how to map them into Port.
## Check if a resource is supported[](#check-if-a-resource-is-supported "Direct link to Check if a resource is supported")
The Octopus Deploy integration relies on Octopus' API-first architecture, which maintains a consistent pattern for most resources. This means that you can bring virtually any resource into Port, as long as it follows the standard API structure. Here’s how to determine if a resource is supported:
1. Visit the [Octopus Deploy API Swagger documentation](https://demo.octopus.com/swaggerui/index.html) to see the available resources and their API structure.
2. **Check the resource path**: Determine if the API of the resource you want to integrate follows the standard pattern **`GET /{spaceId}/{resources}`**
* **If the resource follows this pattern**: Great! It can be integrated.
* **If not**: Please contact us or contribute by [adding support](https://github.com/port-labs/ocean/blob/main/CONTRIBUTING.md) to [the integration](https://github.com/port-labs/ocean/tree/main/integrations/octopus) yourself.
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party API into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform, and perform other operations on existing fields and values from the integration API. ged
### Mapping the Resource to Port[](#mapping-the-resource-to-port "Direct link to Mapping the Resource to Port")
After determining that the resource is supported by the API, you can map it to Port by following these steps:
* **Define the resource kind**: The value of `kind` should be the value of the resource in the api pattern **`GET /{spaceId}/{resources}`** without the trailing `s`. For example, if API path is **`GET /{spaceId}/runbooks`**, the value of `kind` should be `runbook`.
* **Define the selector**: The selector is a JQ query that filters the resources you want to ingest. If the query evaluates to `false`, the resource will be skipped.
* **Define the properties**: The properties are the fields of the Port entity. You can map the resource fields to the entity properties using JQ queries.
* **Define the blueprint**: The blueprint is the name of the Port entity blueprint that you want to use for the resource.
* **Define the relations**: You can define `relations` between the resource and other resources in Port by mapping the related fields.
## Example configurations[](#example-configurations "Direct link to Example configurations")
Here are some examples of how to expand the integration to include additional resources
### Runbook[](#runbook "Direct link to Runbook")
**Runbook Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusRunbook",
"title": "Octopus Runbook",
"icon": "Octopus",
"description": "A runbook in Octopus Deploy",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description",
"description": "The description of the runbook"
},
"lastModifiedOn": {
"type": "string",
"title": "Last Modified On",
"format": "date-time",
"description": "The date and time when the runbook was last modified"
},
"environmentScope": {
"type": "string",
"title": "Environment Scope",
"description": "The scope of environments for the runbook"
},
"environments": {
"type": "array",
"items": {
"type": "string"
},
"title": "Environments",
"description": "The environments associated with the runbook"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
},
```
**Mapping configuration for Runbook (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: runbook
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusRunbook"'
properties:
description: .Description
lastModifiedOn: .LastModifiedOn
environmentScope: .EnvironmentScope
environments: .Environments
relations:
space: .SpaceId
```
### Task[](#task "Direct link to Task")
**Task Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusTask",
"title": "Octopus Task",
"icon": "Octopus",
"description": "A task in Octopus Deploy",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description",
"description": "The description of the task"
},
"state": {
"type": "string",
"title": "State",
"description": "The current state of the task"
},
"isCompleted": {
"type": "boolean",
"title": "Is Completed",
"description": "Indicates if the task is completed"
},
"completedTime": {
"type": "string",
"title": "Completed Time",
"format": "date-time",
"description": "The time when the task was completed"
},
"hasWarningsOrErrors": {
"type": "boolean",
"title": "Has Warnings or Errors",
"description": "Indicates if the task encountered warnings or errors"
},
"finishedSuccessfully": {
"type": "boolean",
"title": "Finished Successfully",
"description": "Indicates if the task finished successfully"
},
"duration": {
"type": "string",
"title": "Duration",
"description": "The duration of the task"
},
"queueTime": {
"type": "string",
"title": "Queue Time",
"format": "date-time",
"description": "The time when the task was queued"
},
"startTime": {
"type": "string",
"title": "Start Time",
"format": "date-time",
"description": "The time when the task started"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for Task (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: task
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusTask"'
properties:
description: .Description
state: .State
isCompleted: .IsCompleted
completedTime: .CompletedTime
hasWarningsOrErrors: .HasWarningsOrErrors
finishedSuccessfully: .FinishedSuccessfully
duration: .Duration
queueTime: .QueueTime
startTime: .StartTime
relations:
space: .SpaceId
```
### Team[](#team "Direct link to Team")
**Team Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusTeam",
"title": "Octopus Team",
"icon": "Octopus",
"description": "A team in Octopus Deploy",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description",
"description": "The description of the team"
},
"canBeDeleted": {
"type": "boolean",
"title": "Can Be Deleted",
"description": "Indicates if the team can be deleted"
},
"canBeRenamed": {
"type": "boolean",
"title": "Can Be Renamed",
"description": "Indicates if the team can be renamed"
},
"canChangeMembers": {
"type": "boolean",
"title": "Can Change Members",
"description": "Indicates if the team members can be changed"
},
"canChangeRoles": {
"type": "boolean",
"title": "Can Change Roles",
"description": "Indicates if the team roles can be changed"
},
"memberUserIds": {
"type": "array",
"items": {
"type": "string"
},
"title": "Member User IDs",
"description": "The IDs of the users who are members of the team"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for Team (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: team
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusTeam"'
properties:
description: .Description
canBeDeleted: .CanBeDeleted
canBeRenamed: .CanBeRenamed
canChangeMembers: .CanChangeMembers
canChangeRoles: .CanChangeRoles
memberUserIds: .MemberUserIds
relations:
space: .SpaceId
```
### WorkerPool[](#workerpool "Direct link to WorkerPool")
**WorkerPool Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusWorkerPool",
"title": "Octopus Worker Pool",
"icon": "Octopus",
"description": "A worker pool in Octopus Deploy",
"schema": {
"properties": {
"workerPoolType": {
"type": "string",
"title": "Worker Pool Type",
"description": "The type of the worker pool (e.g., StaticWorkerPool)"
},
"isDefault": {
"type": "boolean",
"title": "Is Default",
"description": "Indicates if the worker pool is the default"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for WorkerPool (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: workerpool
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusWorkerPool"'
properties:
workerPoolType: .WorkerPoolType
isDefault: .IsDefault
relations:
space: .SpaceId
```
### Worker[](#worker "Direct link to Worker")
**Worker Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusWorker",
"title": "Octopus Worker",
"icon": "Octopus",
"description": "A worker in Octopus Deploy",
"schema": {
"properties": {
"operatingSystem": {
"type": "string",
"title": "Operating System",
"description": "The operating system of the worker"
},
"healthStatus": {
"type": "string",
"title": "Health Status",
"description": "The health status of the worker"
},
"isDisabled": {
"type": "boolean",
"title": "Is Disabled",
"description": "Indicates if the worker is disabled"
},
"architecture": {
"type": "string",
"title": "Architecture",
"description": "The architecture of the worker"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for Team (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: worker
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusWorker"'
properties:
operatingSystem: .OperatingSystem
healthStatus: .HealthStatus
isDisabled: .IsDisabled
architecture: .Architecture
relations:
space: .SpaceId
```
### Environment[](#environment "Direct link to Environment")
**Environment Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusEnvironment",
"title": "Octopus Environment",
"icon": "Octopus",
"description": "An environment in Octopus Deploy",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description",
"description": "The description of the environment"
},
"allowDynamicInfrastructure": {
"type": "boolean",
"title": "Allow Dynamic Infrastructure",
"description": "Indicates if dynamic infrastructure is allowed in this environment"
},
"useGuidedFailure": {
"type": "boolean",
"title": "Use Guided Failure",
"description": "Indicates if guided failure mode is enabled for this environment"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for Environment (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: environment
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusEnvironment"'
properties:
description: .Description
allowDynamicInfrastructure: .AllowDynamicInfrastructure
useGuidedFailure: .UseGuidedFailure
relations:
space: .SpaceId
```
### Proxy[](#proxy "Direct link to Proxy")
**Proxy Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusProxy",
"title": "Octopus Proxy",
"icon": "Octopus",
"description": "A proxy configuration in Octopus Deploy",
"schema": {
"properties": {
"host": {
"type": "string",
"title": "Host",
"description": "The hostname of the proxy"
},
"port": {
"type": "integer",
"title": "Port",
"description": "The port used by the proxy"
},
"username": {
"type": "string",
"title": "Username",
"description": "The username for authentication with the proxy"
},
"proxyType": {
"type": "string",
"title": "Proxy Type",
"description": "The type of the proxy"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for Proxy (click to expand)**
Kind value
The value of `kind` should be `proxie` for Proxy resources. This is because of the pattern of the API endpoints discussed in the [mapping the resource to port](#mapping-the-resource-to-port) section.
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: proxie
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusProxy"'
properties:
host: .Host
port: .Port
username: .Username
proxyType: .ProxyType
relations:
space: .SpaceId
```
### Account[](#account "Direct link to Account")
**Account Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusAccount",
"title": "Octopus Account",
"icon": "Octopus",
"description": "An account configuration in Octopus Deploy",
"schema": {
"properties": {
"accountType": {
"type": "string",
"title": "Account Type",
"description": "The type of the account, e.g., AmazonWebServicesAccount"
},
"description": {
"type": "string",
"title": "Description",
"description": "The description of the account"
},
"environmentIds": {
"type": "array",
"items": {
"type": "string"
},
"title": "Environment IDs",
"description": "IDs of the environments associated with the account"
},
"tenantedDeploymentParticipation": {
"type": "string",
"title": "Tenanted Deployment Participation",
"description": "Indicates the participation of the account in tenanted deployments"
},
"tenantIds": {
"type": "array",
"items": {
"type": "string"
},
"title": "Tenant IDs",
"description": "IDs of the tenants associated with the account"
},
"tenantTags": {
"type": "array",
"items": {
"type": "string"
},
"title": "Tenant Tags",
"description": "Tags of tenants associated with the account"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for Account (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: account
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusAccount"'
properties:
accountType: .AccountType
description: .Description
environmentIds: .EnvironmentIds
tenantedDeploymentParticipation: .TenantedDeploymentParticipation
tenantIds: .TenantIds
tenantTags: .TenantTags
relations:
space: .SpaceId
```
### Package[](#package "Direct link to Package")
**Package Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusPackage",
"title": "Octopus Package",
"icon": "Octopus",
"description": "A package stored in Octopus Deploy",
"schema": {
"properties": {
"description": {
"type": "string",
"title": "Description",
"description": "The description of the package"
},
"feedId": {
"type": "string",
"title": "Feed ID",
"description": "ID of the feed associated with the package"
},
"fileExtension": {
"type": "string",
"title": "File Extension",
"description": "The file extension of the package"
},
"version": {
"type": "string",
"title": "Version",
"description": "The version of the package"
},
"hash": {
"type": "string",
"title": "Hash",
"description": "The hash of the package for verification"
},
"packageSizeBytes": {
"type": "integer",
"title": "Package Size (Bytes)",
"description": "The size of the package in bytes"
},
"published": {
"type": "string",
"title": "Published Date",
"format": "date-time",
"description": "The date the package was published"
},
"releaseNotes": {
"type": "string",
"title": "Release Notes",
"description": "Notes provided for the release of the package"
},
"summary": {
"type": "string",
"title": "Summary",
"description": "A summary of the package"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for Package (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: package
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Title
blueprint: '"octopusPackage"'
properties:
description: .Description
feedId: .FeedId
fileExtension: .FileExtension
version: .Version
hash: .Hash
packageSizeBytes: .PackageSizeBytes
published: .Published
releaseNotes: .ReleaseNotes
summary: .Summary
relations:
space: .SpaceId
```
### Subscription[](#subscription "Direct link to Subscription")
**Subscription Blueprint (click to expand)**
Create in Port
```
{
"identifier": "octopusSubscription",
"title": "Octopus Subscription",
"icon": "Octopus",
"description": "An event notification subscription in Octopus Deploy",
"schema": {
"properties": {
"name": {
"type": "string",
"title": "Name",
"description": "The name of the subscription"
},
"type": {
"type": "string",
"title": "Type",
"description": "The type of the subscription"
},
"isDisabled": {
"type": "boolean",
"title": "Is Disabled",
"description": "Indicates if the subscription is disabled"
},
"emailFrequencyPeriod": {
"type": "string",
"title": "Email Frequency Period",
"description": "The frequency at which email notifications are sent"
},
"emailPriority": {
"type": "string",
"title": "Email Priority",
"description": "The priority of email notifications"
},
"webhookURI": {
"type": "string",
"title": "Webhook URI",
"description": "The URI for the webhook"
},
"webhookTimeout": {
"type": "string",
"title": "Webhook Timeout",
"description": "The timeout setting for the webhook"
},
"lastModifiedBy": {
"type": "string",
"title": "Last Modified By",
"description": "The user who last modified the subscription"
},
"lastModifiedOn": {
"type": "string",
"title": "Last Modified On",
"format": "date-time",
"description": "The date and time when the subscription was last modified"
}
}
},
"calculationProperties": {},
"relations": {
"space": {
"title": "Space",
"description": "The space to which this project belongs",
"target": "octopusSpace",
"required": false,
"many": false
}
}
}
```
**Mapping configuration for Subscription (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: subscription
selector:
query: "true"
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"octopusSubscription"'
properties:
type: .Type
isDisabled: .IsDisabled
emailFrequencyPeriod: .EventNotificationSubscription.EmailFrequencyPeriod
emailPriority: .EventNotificationSubscription.EmailPriority
webhookURI: .EventNotificationSubscription.WebhookURI
webhookTimeout: .EventNotificationSubscription.WebhookTimeout
lastModifiedBy: .LastModifiedBy
lastModifiedOn: .LastModifiedOn
relations:
space: .SpaceId
```
---
# Cloud cost
Port's cloud cost integrations make it easy to keep your software catalog up to date based on information stored in your preferred cloud cost tool.
For more information, check out the documentation for your respective tool:
## [🗃Kubecost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost/.md)
[1 item](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost/.md)
## [📄️OpenCost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/opencost/.md)
[Sync OpenCost Kubernetes cost and resource spend data into Port's software catalog.](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/opencost/.md)
---
# Kubecost

Loading version...
Port's Kubecost integration allows you to model Kubecost resources in your software catalog and ingest data into them.
Supported resources [kubesystem](https://docs.kubecost.com/apis/monitoring-apis/api-allocation#allocation-api)[cloud](https://docs.kubecost.com/apis/monitoring-apis/cloud-cost-api#cloud-cost-querying-api)
## Setup[](#setup "Direct link to Setup")
Choose one of the following installation methods: Not sure which method is right for your use case? Check the available [installation methods](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Hosted by Port2Install
Hosted by Port (Recommended)
* ✧Port hosts and manages the integration
* ✧Customizable resync interval for data ingestion
* ✧Access control flexibility
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Install
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: kubesystem
selector:
query: 'true'
port:
entity:
mappings:
blueprint: '"kubecostResourceAllocation"'
identifier: .name
title: .name
properties:
cluster: .properties.cluster
namespace: .properties.namespace
startDate: .start
endDate: .end
cpuCoreHours: .cpuCoreHours
cpuCost: .cpuCost
cpuEfficiency: .cpuEfficiency
gpuHours: .gpuHours
gpuCost: .gpuCost
networkCost: .networkCost
loadBalancerCost: .loadBalancerCost
pvCost: .pvCost
pvBytes: .pvBytes
ramBytes: .ramBytes
ramCost: .ramCost
ramEfficiency: .ramEfficiency
sharedCost: .sharedCost
externalCost: .externalCost
totalCost: .totalCost
totalEfficiency: .totalEfficiency
- kind: cloud
selector:
query: 'true'
port:
entity:
mappings:
blueprint: '"kubecostCloudAllocation"'
identifier: .properties.provider + "/" + .properties.providerID + "/" + .properties.category + "/" + .properties.service | gsub("[^A-Za-z0-9@_.:\\\\/=-]"; "-")
title: .properties.provider + "/" + .properties.service
properties:
provider: .properties.provider
accountID: .properties.accountID
invoiceEntityID: .properties.invoiceEntityID
startDate: .window.start
endDate: .window.end
listCost: .listCost.cost
listCostPercent: .listCost.kubernetesPercent
netCost: .netCost.cost
netCostPercent: .netCost.kubernetesPercent
amortizedNetCost: .amortizedNetCost.cost
amortizedNetCostPercent: .amortizedNetCost.kubernetesPercent
invoicedCost: .invoicedCost.cost
invoicedCostPercent: .invoicedCost.kubernetesPercent
```
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
kubesystemcloud
Default mappingYAML
```
- kind: kubesystem
selector:
query: 'true'
port:
entity:
mappings:
blueprint: '"kubecostResourceAllocation"'
identifier: .name
title: .name
properties:
cluster: .properties.cluster
namespace: .properties.namespace
startDate: .start
endDate: .end
cpuCoreHours: .cpuCoreHours
cpuCost: .cpuCost
cpuEfficiency: .cpuEfficiency
gpuHours: .gpuHours
gpuCost: .gpuCost
networkCost: .networkCost
loadBalancerCost: .loadBalancerCost
pvCost: .pvCost
pvBytes: .pvBytes
ramBytes: .ramBytes
ramCost: .ramCost
ramEfficiency: .ramEfficiency
sharedCost: .sharedCost
externalCost: .externalCost
totalCost: .totalCost
totalEfficiency: .totalEfficiency
```
Sample payloadJSON
```
{
"name": "argocd",
"properties": {
"cluster": "cluster-one",
"node": "gke-my-regional-cluster-default-pool-e8093bfa-0bjg",
"namespace": "argocd",
"providerID": "gke-my-regional-cluster-default-pool-e8093bfa-0bjg",
"namespaceLabels": {
"kubernetes_io_metadata_name": "argocd"
}
},
"window": {
"start": "2023-10-30T00:00:00Z",
"end": "2023-10-30T01:00:00Z"
},
"start": "2023-10-30T00:00:00Z",
"end": "2023-10-30T01:00:00Z",
"minutes": 60,
"cpuCores": 0.00515,
"cpuCoreRequestAverage": 0,
"cpuCoreUsageAverage": 0.00514,
"cpuCoreHours": 0.00515,
"cpuCost": 0.00012,
"cpuCostAdjustment": 0,
"cpuEfficiency": 1,
"gpuCount": 0,
"gpuHours": 0,
"gpuCost": 0,
"gpuCostAdjustment": 0,
"networkTransferBytes": 2100541.53,
"networkReceiveBytes": 2077024.88318,
"networkCost": 0,
"networkCrossZoneCost": 0,
"networkCrossRegionCost": 0,
"networkInternetCost": 0,
"networkCostAdjustment": 0,
"loadBalancerCost": 0.02708,
"loadBalancerCostAdjustment": 0,
"pvBytes": 0,
"pvByteHours": 0,
"pvCost": 0,
"pvs": "None",
"pvCostAdjustment": 0,
"ramBytes": 135396181.33333,
"ramByteRequestAverage": 0,
"ramByteUsageAverage": 135394433.70477,
"ramByteHours": 135396181.33333,
"ramCost": 0.00041,
"ramCostAdjustment": 0,
"ramEfficiency": 1,
"externalCost": 0,
"sharedCost": 0,
"totalCost": 0.02761,
"totalEfficiency": 1,
"proportionalAssetResourceCosts": {},
"lbAllocations": {
"cluster-one/argocd/argocd-server": {
"service": "argocd/argocd-server",
"cost": 0.027083333333333334,
"private": false,
"ip": ""
}
},
"sharedCostBreakdown": {}
}
```
Port entityJSON
```
{
"identifier": "argocd",
"title": "argocd",
"icon": "Cluster",
"blueprint": "kubecostResourceAllocation",
"team": [],
"properties": {
"cluster": "cluster-one",
"namespace": "argocd",
"startDate": "2023-10-30T04:00:00.000Z",
"endDate": "2023-10-30T05:00:00.000Z",
"cpuCoreHours": 0.0051,
"cpuCost": 0.00012,
"cpuEfficiency": 1,
"gpuHours": 0,
"gpuCost": 0,
"networkCost": 0,
"loadBalancerCost": 0.02708,
"pvCost": 0,
"pvBytes": 0,
"ramBytes": 135396181.33333,
"ramCost": 0.00041,
"ramEfficiency": 1,
"sharedCost": 0,
"externalCost": 0,
"totalCost": 0.02761,
"totalEfficiency": 1
},
"relations": {},
"createdAt": "2023-10-30T13:25:42.717Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2023-10-30T13:28:37.379Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| ---------------------------- | --------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `window` | `string` | The time window for the query. Supported values: preset windows ('today', 'week', 'month', 'yesterday', 'lastweek', 'lastmonth', '30m', '12h', '7d'), an ISO8601 UTC date-time pair ('2026-03-30T00:00:00Z,2026-03-31T00:00:00Z'), or a Unix timestamp pair ('1711756800,1711843200'). Default: `"today"`. |
| `aggregate` | `string` | Field by which to aggregate the results. E.g. 'namespace', 'service', or 'label:app'. |
| `step` | `string` | Granularity of each time bucket in the results. For example, '1d' breaks a week-long window into daily buckets. Accepts seconds (s), minutes (m), hours (h), or days (d), e.g. '30m', '2h', '1d'. Defaults to the full window as a single bucket. |
| `accumulate` | `boolean` | If true, sum the entire range of sets into a single set. Default: `false`. |
| `idle` | `boolean` | If true, include idle cost (i.e. the cost of the un-allocated assets) as its own allocation Default: `true`. |
| `external` | `boolean` | If true, include external, or out-of-cluster costs in each allocation. Default is false. Default: `false`. |
| `filterClusters` | `string` | Comma-separated list of clusters to match; e.g. cluster-one,cluster-two will return results from only those two clusters. |
| `filterNodes` | `string` | Comma-separated list of nodes to match; e.g. node-one,node-two will return results from only those two nodes. |
| `filterNamespaces` | `string` | Comma-separated list of namespaces to match; e.g. namespace-one,namespace-two will return results from only those two namespaces. |
| `filterControllerKinds` | `string` | Comma-separated list of controller kinds to match; e.g. deployment, job will return results with only those two controller kinds. |
| `filterControllers` | `string` | Comma-separated list of controllers to match; e.g. deployment-one,statefulset-two will return results from only those two controllers. |
| `filterPods` | `string` | Comma-separated list of pods to match; e.g. pod-one,pod-two will return results from only those two pods. |
| `filterAnnotations` | `string` | Comma-separated list of annotations to match; e.g. name:annotation-one,name:annotation-two will return results with either of those two annotation key-value-pairs. |
| `filterLabels` | `string` | Comma-separated list of annotations to match; e.g. app:cost-analyzer, app:prometheus will return results with either of those two label key-value-pairs. |
| `filterServices` | `string` | Comma-separated list of services to match; e.g. frontend-one,frontend-two will return results with either of those two services |
| `shareIdle` | `boolean` | If true, idle cost is allocated proportionally across all non-idle allocations, per-resource. That is, idle CPU cost is shared with each non-idle allocation's CPU cost, according to the percentage of the total CPU cost represented. Default is false Default: `false`. |
| `splitIdle` | `boolean` | If true, and shareIdle == false, Idle Allocations are created on a per cluster or per node basis rather than being aggregated into a single idle allocation. Default is false Default: `false`. |
| `idleByNode` | `boolean` | f true, idle allocations are created on a per node basis. Which will result in different values when shared and more idle allocations when split. Default is false. Default: `false`. |
| `shareNamespaces` | `string` | Comma-separated list of namespaces to share; e.g. kube-system, kubecost will share the costs of those two namespaces with the remaining non-idle, unshared allocations. |
| `shareLabels` | `string` | Comma-separated list of labels to share; e.g. env:staging, app:test will share the costs of those two label values with the remaining non-idle, unshared allocations. |
| `shareCost` | `number` | Floating-point value representing a monthly cost to share with the remaining non-idle, unshared allocations; e.g. 30.42 ($1.00/day == $30.42/month) for the query yesterday (1 day) will split and distribute exactly $1.00 across the allocations. Default is 0.0. Default: `0`. |
| `offset` | `integer` | Number of items to skip before starting to collect the result set. |
| `limit` | `integer` | Maximum number of items to return in the result set. |
| `filter` | `string` | Filter results by any category which that can be aggregated by, can support multiple filterable items in the same category in a comma-separated list. E.g. 'namespace:kube-system,kubecost'. |
| `format` | `string` | Format of the output. Default is JSON. |
| `costMetric` | `string` | Cost metric format. Default: `"cummulative"`. |
| `includeSharedCostBreakdown` | `boolean` | If true, the cost breakdown for shared costs is included in the response. Default is false. Default: `true`. |
| `reconcile` | `boolean` | If true, pulls data from the Assets cache and corrects prices of Allocations according to their related Assets Default: `true`. |
| `shareTenancyCosts` | `boolean` | If true, share the cost of cluster overhead assets such as cluster management costs and node attached volumes across tenants of those resources. Default: `true`. |
| `shareSplit` | `string` | Determines how to split shared costs among non-idle, unshared allocations. Default: `"weighted"`. |
BlueprintJSON
Create in Port
```
{
"identifier": "kubecostCloudAllocation",
"description": "This blueprint represents an Kubecost cloud resource allocation in our software catalog",
"title": "Kubecost Cloud Allocation",
"icon": "Cluster",
"schema": {
"properties": {
"provider": {
"type": "string",
"title": "Provider"
},
"accountID": {
"type": "string",
"title": "Account ID"
},
"invoiceEntityID": {
"type": "string",
"title": "Invoice Entity ID"
},
"startDate": {
"title": "Start Date",
"type": "string",
"format": "date-time"
},
"endDate": {
"title": "End Date",
"type": "string",
"format": "date-time"
},
"listCost": {
"title": "List Cost Value",
"type": "number"
},
"listCostPercent": {
"title": "List Cost Percent",
"type": "number"
},
"netCost": {
"title": "Net Cost Value",
"type": "number"
},
"netCostPercent": {
"title": "Net Cost Percent",
"type": "number"
},
"amortizedNetCost": {
"title": "Amortized Net Cost",
"type": "number"
},
"amortizedNetCostPercent": {
"title": "Amortized Net Cost Percent",
"type": "number"
},
"invoicedCost": {
"title": "Invoice Cost",
"type": "number"
},
"invoicedCostPercent": {
"title": "Invoice Cost Percent",
"type": "number"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: cloud
selector:
query: 'true'
port:
entity:
mappings:
blueprint: '"kubecostCloudAllocation"'
identifier: .properties.provider + "/" + .properties.providerID + "/" + .properties.category + "/" + .properties.service | gsub("[^A-Za-z0-9@_.:\\\\/=-]"; "-")
title: .properties.provider + "/" + .properties.service
properties:
provider: .properties.provider
accountID: .properties.accountID
invoiceEntityID: .properties.invoiceEntityID
startDate: .window.start
endDate: .window.end
listCost: .listCost.cost
listCostPercent: .listCost.kubernetesPercent
netCost: .netCost.cost
netCostPercent: .netCost.kubernetesPercent
amortizedNetCost: .amortizedNetCost.cost
amortizedNetCostPercent: .amortizedNetCost.kubernetesPercent
invoicedCost: .invoicedCost.cost
invoicedCostPercent: .invoicedCost.kubernetesPercent
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| ------------------------ | --------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `window` | `string` | The time window for the query. Supported values: preset windows ('today', 'week', 'month', 'yesterday', 'lastweek', 'lastmonth', '30m', '12h', '7d'), an ISO8601 UTC date-time pair ('2026-03-30T00:00:00Z,2026-03-31T00:00:00Z'), or a Unix timestamp pair ('1711756800,1711843200'). Default: `"today"`. |
| `aggregate` | `string` | Field by which to aggregate the results. E.g. 'namespace', 'service', or 'label:app'. |
| `filterInvoiceEntityIDs` | `string` | GCP only, filter for projectID |
| `filterAccountIDs` | `string` | Filter for account |
| `filterProviders` | `string` | Filter for cloud service provider |
| `filterLabel` | `string` | Filter for a specific label. Does not support filtering for multiple labels at once. |
| `filterServices` | `string` | Comma-separated list of services to match; e.g. frontend-one,frontend-two will return results with either of those two services |
| `accumulate` | `boolean` | If true, sum the entire range of sets into a single set. Default: `false`. |
| `offset` | `integer` | Number of items to skip before starting to collect the result set. |
| `limit` | `integer` | Maximum number of items to return in the result set. |
| `filter` | `string` | Filter results by any category which that can be aggregated by, can support multiple filterable items in the same category in a comma-separated list. E.g. 'namespace:kube-system,kubecost'. |
## Advanced[](#advanced "Direct link to Advanced")
For advanced configuration including customizing how Kubecost kinds are ingested, read the [advanced section of Kubecost](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-cost/kubecost/advanced/.md) guide.
---
# Advanced configuration for Kubecost objects
This guide provides information for configuring how Kubecost objects are ingested into your Kubecost installation. The Kubecost integration uses a YAML configuration to describe the process of loading data into the developer portal.
Each kind has specific configuration for both the v1 and v2 of the Kubecost API
## Available configuration for `kubesystem` kind (v1)[](#available-configuration-for-kubesystem-kind-v1 "Direct link to available-configuration-for-kubesystem-kind-v1")
* **window** - Duration of time over which to query. Accepts: words like `today`, `week`, `month`, `yesterday`, `lastweek`, `lastmonth`; durations like `30m`, `12h`, `7d`; RFC3339 date pairs like `2021-01-02T15:04:05Z,2021-02-02T15:04:05Z`; Unix timestamps like `1578002645,1580681045`.
* **aggregate** - Field by which to aggregate the results. Accepts: `cluster`, `node`, `namespace`, `controllerKind`, `controller`, `service`, `pod`, `container`, `label:name`, and `annotation:name`. Also accepts comma-separated lists for multi-aggregation, like `namespace,label:app`.
* **step** - Duration of a single allocation set. If unspecified, this defaults to the window, so that you receive exactly one set for the entire window. If specified, such as `30m`, `2h`, `1d` etc, it works chronologically backward, querying in durations of step until the full window is covered. Default is `window`.
* **accumulate** - If true, sum the entire range of sets into a single set. Default value is `false`.
* **idle** - If true, include idle cost (i.e. the cost of the un-allocated assets) as its own allocation. Default is `true`.
* **external** - If true, include external, or out-of-cluster costs in each allocation. Default is `false`.
* **filterClusters** - Comma-separated list of clusters to match; e.g. `cluster-one,cluster-two` will return results from only those two clusters.
* **filterNodes** - Comma-separated list of nodes to match; e.g. `node-one,node-two` will return results from only those two nodes.
* **filterNamespaces** - Comma-separated list of namespaces to match; e.g. `namespace-one,namespace-two` will return results from only those two namespaces.
* **filterControllerKinds** - Comma-separated list of controller kinds to match; e.g. `deployment`, job will return results with only those two controller kinds.
* **filterControllers** - Comma-separated list of controllers to match; e.g. `deployment-one,statefulset-two` will return results from only those two controllers.
* **filterPods** - Comma-separated list of pods to match; e.g. `pod-one,pod-two` will return results from only those two pods.
* **filterAnnotations** - Comma-separated list of annotations to match; e.g. `name:annotation-one,name:annotation-two` will return results with either of those two annotation key-value-pairs.
* **filterControllerKinds** - Comma-separated list of controller kinds to match; e.g. `deployment`, job will return results with only those two controller kinds.
* **filterLabels** - Comma-separated list of annotations to match; e.g. `app:cost-analyzer, app:prometheus` will return results with either of those two label key-value-pairs.
* **filterServices** - Comma-separated list of services to match; e.g. `frontend-one,frontend-two` will return results with either of those two services.
* **shareIdle** - If true, idle cost is allocated proportionally across all non-idle allocations, per-resource. That is, idle CPU cost is shared with each non-idle allocation's CPU cost, according to the percentage of the total CPU cost represented. Default is `false`.
* **splitIdle** - If true, and shareIdle == false, Idle Allocations are created on a per cluster or per node basis rather than being aggregated into a single idle allocation. Default is `false`.
* **idleByNode** - If true, idle allocations are created on a per node basis. Which will result in different values when shared and more idle allocations when split. Default is `false`.
* And any query parameter that could be found in the [Kubecost allocation API](https://docs.kubecost.com/apis/apis-overview/api-allocation#allocation-api) and [Kubecost Cloud API](https://docs.kubecost.com/apis/apis-overview/cloud-cost-api#cloud-cost-aggregate-api)
**Mapping config example for v1 `kubesystem` kind (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: kubesystem
selector:
query: "true"
window: "7d"
aggregate: service
step: "1d" # this will result in 7 entries which is 1 day over the course of `window` time period: 7 days
accumulate: false
idle: true
external: false
filterLabels: "app:internal-service"
filterServices: "notification,account,functions"
port:
entity:
mappings:
blueprint: '"kubecostResourceAllocation"'
identifier: .name
title: .name
properties:
cluster: .properties.cluster
namespace: .properties.namespace
startDate: .start
endDate: .end
cpuCoreHours: .cpuCoreHours
cpuCost: .cpuCost
cpuEfficiency: .cpuEfficiency
gpuHours: .gpuHours
gpuCost: .gpuCost
networkCost: .networkCost
loadBalancerCost: .loadBalancerCost
pvCost: .pvCost
pvBytes: .pvBytes
ramBytes: .ramBytes
ramCost: .ramCost
ramEfficiency: .ramEfficiency
sharedCost: .sharedCost
externalCost: .externalCost
totalCost: .totalCost
totalEfficiency: .totalEfficiency
```
## Available configuration for `kubesystem` kind (v2)[](#available-configuration-for-kubesystem-kind-v2 "Direct link to available-configuration-for-kubesystem-kind-v2")
* **window** - Duration of time over which to query. Accepts: words like `today`, `week`, `month`, `yesterday`, `lastweek`, `lastmonth`; durations like `30m`, `12h`, `7d`; RFC3339 date pairs like `2021-01-02T15:04:05Z,2021-02-02T15:04:05Z`; Unix timestamps like `1578002645,1580681045`.
* **aggregate** - Field by which to aggregate the results. Accepts: `cluster`, `node`, `namespace`, `controllerKind`, `controller`, `service`, `pod`, `container`, `label:name`, and `annotation:name`. Also accepts comma-separated lists for multi-aggregation, like `namespace,label:app`.
* **step** - Duration of a single allocation set. If unspecified, this defaults to the window, so that you receive exactly one set for the entire window. If specified, such as `30m`, `2h`, `1d` etc, it works chronologically backward, querying in durations of step until the full window is covered. Default is `window`.
* **accumulate** - If true, sum the entire range of sets into a single set. Default value is `false`.
* **idle** - If true, include idle cost (i.e. the cost of the un-allocated assets) as its own allocation. Default is `true`.
* **external** - If true, include external, or out-of-cluster costs in each allocation. Default is `false`.
* **offset** - Refers to the number of line items you are offsetting. Pairs with limit. See [Kubecost docs on Using offset and limit parameters to parse payload results](https://docs.kubecost.com/apis/apis-overview#using-offset-and-limit-parameters-to-parse-payload-results) for more
* **limit** - Refers to the number of line items per page. Pair with the offset parameter to filter your payload to specific pages of line items.
* **filter** - Filter your results by any category which you can aggregate by, can support multiple filterable items in the same category in a comma-separated list. See the [Kubecost filter syntax guide](https://docs.kubecost.com/apis/filters-api) for more.
* **format** - Set to `csv` to download an accumulated version of the allocation results in CSV format. Set to `pdf` to download an accumulated version of the allocation results in PDF format. By default, results will be in JSON format.
* **costMetric** - Cost metric format. Learn about cost metric calculations in Kubecost Allocations Dashboard documentation. Possible values are `cumulative`, `hourly`, `daily`, and `monthly`. Default is `cumulative`.
* **shareIdle** - If `true`, idle cost is allocated proportionally across all non-idle allocations, per-resource. That is, idle CPU cost is shared with each non-idle allocation's CPU cost, according to the percentage of the total CPU cost represented. Default is `false`.
* **splitIdle** - If `true`, and `shareIdle == false`, idle allocations are created on a per cluster or per node basis rather than being aggregated into a single "idle" allocation. Default is `false`.
* **idleByNode** - If `true`, idle allocations are created on a per node basis. Which will result in different values when shared and more idle allocations when split. `splitIdle` should only be configured to `true` when aggregate is configured to `node` or `cluster`. Default is `false`.
* **includeSharedCostBreakdown** - Provides breakdown of cost metrics for any shared resources. Default is `true`.
* **reconcile** - If `true`, pulls data from the Assets cache and corrects prices of Allocations according to their related Assets. The corrections from this process are stored in each cost category's cost adjustment field. If the integration with your cloud provider's billing data has been set up, this will result in the most accurate costs for Allocations. Default is `true`.
* **shareTenancyCosts** - If `true`, share the cost of cluster overhead assets such as cluster management costs and node attached volumes across tenants of those resources. Results are added to the sharedCost field. Cluster management and attached volumes are shared by cluster. Default is `true`.
* **shareNamespaces** - Comma-separated list of namespaces to share; e.g. `namespace-one,namespace-two` will return results from only those two namespaces.
* **shareLabels** - Comma-separated list of labels to share; e.g. `env:staging`, `app:test` will share the costs of those two label values with the remaining non-idle, unshared allocations.
* **shareCost** - Floating-point value representing a monthly cost to share with the remaining non-idle, unshared allocations; e.g. `30.42` ($1.00/day == $30.42/month) for the query `yesterday` (1 day) will split and distribute exactly $1.00 across the allocations. Default is `0.0`.
* **shareSplit** - Determines how to split shared costs among non-idle, unshared allocations. By default, the split will be `weighted`; i.e. proportional to the cost of the allocation, relative to the total. The other option is `even`; i.e. each allocation gets an equal portion of the shared cost. Default is `weighted`.
**Mapping config example for v2 `kubesystem` kind (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: kubesystem
selector:
query: "true"
window: "7d"
aggregate: service
step: "1d" # this will result in 7 entries which is 1 day over the course of `window` time period: 7 days
accumulate: false
idle: true
filter: 'labels:"app:internal-service","app:service-2"+service:"notification","account","functions"' # replaces all `filter*` properties needed in v1
port:
entity:
mappings:
blueprint: '"kubecostResourceAllocation"'
identifier: .name
title: .name
properties:
cluster: .properties.cluster
namespace: .properties.namespace
startDate: .start
endDate: .end
cpuCoreHours: .cpuCoreHours
cpuCost: .cpuCost
cpuEfficiency: .cpuEfficiency
gpuHours: .gpuHours
gpuCost: .gpuCost
networkCost: .networkCost
loadBalancerCost: .loadBalancerCost
pvCost: .pvCost
pvBytes: .pvBytes
ramBytes: .ramBytes
ramCost: .ramCost
ramEfficiency: .ramEfficiency
sharedCost: .sharedCost
externalCost: .externalCost
totalCost: .totalCost
totalEfficiency: .totalEfficiency
```
## Available configuration for `cloud` kind (v1)[](#available-configuration-for-cloud-kind-v1 "Direct link to available-configuration-for-cloud-kind-v1")
* **window** - Duration of time over which to query. Accepts: words like `today`, `week`, `month`, `yesterday`, `lastweek`, `lastmonth`; durations like `30m`, `12h`, `7d`; RFC3339 date pairs like `2021-01-02T15:04:05Z,2021-02-02T15:04:05Z`; Unix timestamps like `1578002645,1580681045`.
* **aggregate** - Field by which to aggregate the results. Accepts: invoiceEntityID, accountID, provider, service, and label:\. Supports multi-aggregation using comma-separated lists. Example: `accountID,service`, `namespace,label:app`.
* **filterInvoiceEntityIDs** - Filter for account
* **filterAccountIDs** - GCP only, filter for projectID
* **filterProviders** - Filter for cloud service provider
* **filterLabel** - Filter for a specific label. Does not support filtering for multiple labels at once.
* **filterServices** - Comma-separated list of services to match; e.g. `frontend-one,frontend-two` will return results with either of those two services.
**Mapping config example for v1 `kubecostCloudAllocation` kind (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: cloud
selector:
query: "true"
window: 7d
aggregate: service
filterAccountIDs: "984573291056,374859201234"
filterLabel: label-one,label-two
filterServices: notification,account,chat
port:
entity:
mappings:
blueprint: '"kubecostCloudAllocation"'
identifier: .properties.provider + "/" + .properties.providerID + "/" + .properties.category + "/" + .properties.service | gsub("[^A-Za-z0-9@_.:\\\\/=-]"; "-")
title: .properties.provider + "/" + .properties.service
properties:
provider: .properties.provider
accountID: .properties.accountID
invoiceEntityID: .properties.invoiceEntityID
startDate: .window.start
endDate: .window.end
listCost: .listCost.cost
listCostPercent: .listCost.kubernetesPercent
netCost: .netCost.cost
netCostPercent: .netCost.kubernetesPercent
amortizedNetCost: .amortizedNetCost.cost
amortizedNetCostPercent: .amortizedNetCost.kubernetesPercent
invoicedCost: .invoicedCost.cost
invoicedCostPercent: .invoicedCost.kubernetesPercent
```
## Available configuration for `cloud` kind (v2)[](#available-configuration-for-cloud-kind-v2 "Direct link to available-configuration-for-cloud-kind-v2")
* **window** - Duration of time over which to query. Accepts: words like `today`, `week`, `month`, `yesterday`, `lastweek`, `lastmonth`; durations like `30m`, `12h`, `7d`; RFC3339 date pairs like `2021-01-02T15:04:05Z,2021-02-02T15:04:05Z`; Unix timestamps like `1578002645,1580681045`.
* **aggregate** - Field by which to aggregate the results. Accepts: invoiceEntityID, accountID, provider, service, and label:\. Supports multi-aggregation using comma-separated lists. Example: `accountID,service`, `namespace,label:app`.
* **accumulate** - If true, sum the entire range of sets into a single set. Default value is `false`.
* **offset** - Refers to the number of line items you are offsetting. Pairs with limit. See [Kubecost docs on Using offset and limit parameters to parse payload results](https://docs.kubecost.com/apis/apis-overview#using-offset-and-limit-parameters-to-parse-payload-results) for more
* **limit** - Refers to the number of line items per page. Pair with the offset parameter to filter your payload to specific pages of line items.
* **filter** - Filter your results by any category which you can aggregate by, can support multiple filterable items in the same category in a comma-separated list. See the [Kubecost filter syntax guide](https://docs.kubecost.com/apis/filters-api) for more.
**Mapping config example for v2 `kubecostCloudAllocation` kind (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: cloud
selector:
query: "true"
window: 7d
aggregate: service
accumulate: false
filter: 'labels:"app:internal-service","app:service-2"+service:"notification","account","functions"' # replaces all `filter*` properties needed in v1
port:
entity:
mappings:
blueprint: '"kubecostCloudAllocation"'
identifier: .properties.provider + "/" + .properties.providerID + "/" + .properties.category + "/" + .properties.service | gsub("[^A-Za-z0-9@_.:\\\\/=-]"; "-")
title: .properties.provider + "/" + .properties.service
properties:
provider: .properties.provider
accountID: .properties.accountID
invoiceEntityID: .properties.invoiceEntityID
startDate: .window.start
endDate: .window.end
listCost: .listCost.cost
listCostPercent: .listCost.kubernetesPercent
netCost: .netCost.cost
netCostPercent: .netCost.kubernetesPercent
amortizedNetCost: .amortizedNetCost.cost
amortizedNetCostPercent: .amortizedNetCost.kubernetesPercent
invoicedCost: .invoicedCost.cost
invoicedCostPercent: .invoicedCost.kubernetesPercent
```
---
# OpenCost

Loading version...
Port's Opencost integration allows you to model Opencost resources in your software catalog and ingest data into them.
Supported resources [Cost](https://www.opencost.io/docs/integrations/api-examples#allocation-examples)[Cloudcost](https://www.opencost.io/docs/integrations/api-examples#cloudcost-examples)
## Setup[](#setup "Direct link to Setup")
Choose one of the following installation methods: Not sure which method is right for your use case? Check the available [installation methods](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#installation-methods).
1Self-hosted2Prerequisites3Install
Self-hosted
* ✧Host and manage the integration in your infrastructure
* ✧Real-time updates via webhooks
* ✧Best for high-security or custom networking needs
CI
* ✧Run as a one-time job in your CI pipeline or on a scheduled basis
* ✧Minimal infrastructure management
Prerequisites
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration for this integration:
**Default mapping configuration (click to expand)**
```
createMissingRelatedEntities: true
deleteDependentEntities: true
resources:
- kind: cost
selector:
query: 'true'
port:
entity:
mappings:
blueprint: '"openCostResourceAllocation"'
identifier: .name
title: .name
properties:
cluster: .properties.cluster
namespace: .properties.namespace
startDate: .start
endDate: .end
cpuCoreHours: .cpuCoreHours
cpuCost: .cpuCost
cpuEfficiency: .cpuEfficiency
gpuHours: .gpuHours
gpuCost: .gpuCost
networkCost: .networkCost
loadBalancerCost: .loadBalancerCost
pvCost: .pvCost
ramBytes: .ramBytes
ramCost: .ramCost
ramEfficiency: .ramEfficiency
sharedCost: .sharedCost
externalCost: .externalCost
totalCost: .totalCost
totalEfficiency: .totalEfficiency
- kind: cloudcost
selector:
query: 'true'
cloudcostAggregate: provider
port:
entity:
mappings:
blueprint: '"openCostCloudcost"'
identifier: .properties.provider + "-" + .window.start + "-" + .window.end
title: .properties.provider + "-" + .window.start + "-" + .window.end
properties:
startDate: .window.start
endDate: .window.end
listCost: .listCost.cost
netCost: .netCost.cost
amortizedNetCost: .amortizedNetCost.cost
invoicedCost: .invoicedCost.cost
amortizedCost: .amortizedCost.cost
```
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
Examples of blueprints and the relevant integration configurations:
CostCloudcost
Default mappingYAML
```
- kind: cost
selector:
query: 'true'
port:
entity:
mappings:
blueprint: '"openCostResourceAllocation"'
identifier: .name
title: .name
properties:
cluster: .properties.cluster
namespace: .properties.namespace
startDate: .start
endDate: .end
cpuCoreHours: .cpuCoreHours
cpuCost: .cpuCost
cpuEfficiency: .cpuEfficiency
gpuHours: .gpuHours
gpuCost: .gpuCost
networkCost: .networkCost
loadBalancerCost: .loadBalancerCost
pvCost: .pvCost
ramBytes: .ramBytes
ramCost: .ramCost
ramEfficiency: .ramEfficiency
sharedCost: .sharedCost
externalCost: .externalCost
totalCost: .totalCost
totalEfficiency: .totalEfficiency
```
Sample payloadJSON
```
{
"name": "ingress-nginx",
"properties": {
"cluster": "cluster-one",
"node": "minikube",
"container": "controller",
"controller": "ingress-nginx-controller",
"controllerKind": "deployment",
"namespace": "ingress-nginx",
"pod": "ingress-nginx-controller-7799c6795f-29n7j",
"services": [
"ingress-nginx-controller-admission",
"ingress-nginx-controller"
],
"labels": {
"app_kubernetes_io_component": "controller",
"app_kubernetes_io_instance": "ingress-nginx",
"app_kubernetes_io_name": "ingress-nginx",
"gcp_auth_skip_secret": "true",
"kubernetes_io_metadata_name": "ingress-nginx",
"pod_template_hash": "7799c6795f"
},
"namespaceLabels": {
"app_kubernetes_io_instance": "ingress-nginx",
"app_kubernetes_io_name": "ingress-nginx",
"kubernetes_io_metadata_name": "ingress-nginx"
}
},
"window": {
"start": "2023-10-30T00:00:00Z",
"end": "2023-10-31T00:00:00Z"
},
"start": "2023-10-30T09:05:00Z",
"end": "2023-10-30T11:50:00Z",
"minutes": 165,
"cpuCores": 0.1,
"cpuCoreRequestAverage": 0.1,
"cpuCoreUsageAverage": 0,
"cpuCoreHours": 0.275,
"cpuCost": 0.00869,
"cpuCostAdjustment": 0,
"cpuEfficiency": 0,
"gpuCount": 0,
"gpuHours": 0,
"gpuCost": 0,
"gpuCostAdjustment": 0,
"networkTransferBytes": 0,
"networkReceiveBytes": 0,
"networkCost": 0,
"networkCrossZoneCost": 0,
"networkCrossRegionCost": 0,
"networkInternetCost": 0,
"networkCostAdjustment": 0,
"loadBalancerCost": 0,
"loadBalancerCostAdjustment": 0,
"pvBytes": 0,
"pvByteHours": 0,
"pvCost": 0,
"pvs": "None",
"pvCostAdjustment": 0,
"ramBytes": 94371840,
"ramByteRequestAverage": 94371840,
"ramByteUsageAverage": 0,
"ramByteHours": 259522560,
"ramCost": 0.00102,
"ramCostAdjustment": 0,
"ramEfficiency": 0,
"externalCost": 0,
"sharedCost": 0,
"totalCost": 0.00972,
"totalEfficiency": 0,
"lbAllocations": "None"
}
```
Port entityJSON
```
{
"identifier": "ingress-nginx",
"title": "ingress-nginx",
"blueprint": "openCostResourceAllocation",
"team": [],
"properties": {
"cluster": "cluster-one",
"namespace": "ingress-nginx",
"startDate": "2023-10-30T09:05:00.000Z",
"endDate": "2023-10-30T11:50:00.000Z",
"cpuCoreHours": 0.275,
"cpuCost": 0.00869,
"cpuEfficiency": 0,
"gpuHours": 0,
"gpuCost": 0,
"networkCost": 0,
"loadBalancerCost": 0,
"pvCost": 0,
"ramBytes": 94371840,
"ramCost": 0.00102,
"ramEfficiency": 0,
"sharedCost": 0,
"externalCost": 0,
"totalCost": 0.00972,
"totalEfficiency": 0
},
"relations": {},
"createdAt": "2023-10-15T09:30:57.924Z",
"createdBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW",
"updatedAt": "2023-10-30T11:49:20.881Z",
"updatedBy": "hBx3VFZjqgLPEoQLp7POx5XaoB0cgsxW"
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| -------------------- | -------- | ----------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `window` | `` | Time window for the OpenCost allocation query. Default: `"today"`. |
| `aggregate` | `string` | Field by which to aggregate the results. |
| `step` | `string` | Duration of a single allocation set (e.g., '30m', '2h', '1d'). Default is window. |
| `resolution` | `string` | Duration to use as resolution in Prometheus queries |
Default mappingYAML
```
- kind: cloudcost
selector:
query: 'true'
cloudcostAggregate: provider
port:
entity:
mappings:
blueprint: '"openCostCloudcost"'
identifier: .properties.provider + "-" + .window.start + "-" + .window.end
title: .properties.provider + "-" + .window.start + "-" + .window.end
properties:
startDate: .window.start
endDate: .window.end
listCost: .listCost.cost
netCost: .netCost.cost
amortizedNetCost: .amortizedNetCost.cost
invoicedCost: .invoicedCost.cost
amortizedCost: .amortizedCost.cost
```
Sample payloadJSON
```
{
"properties": {
"provider": "AWS",
"accountID": "123456789012",
"invoiceEntityID": "AWS-123456789012",
"service": "Amazon Elastic Compute Cloud",
"category": "Compute",
"region": "us-east-1",
"labels": {
"environment": "production",
"team": "platform"
}
},
"window": {
"start": "2024-03-01T00:00:00Z",
"end": "2024-03-31T23:59:59Z"
},
"listCost": {
"cost": 1250.75,
"kubernetesPercent": 0.85
},
"netCost": {
"cost": 1100.50,
"kubernetesPercent": 0.85
},
"amortizedNetCost": {
"cost": 1050.25,
"kubernetesPercent": 0.85
},
"invoicedCost": {
"cost": 1250.75,
"kubernetesPercent": 0.85
},
"amortizedCost": {
"cost": 1200.30,
"kubernetesPercent": 0.85
},
"items": [
{
"resourceId": "i-0abc123def456789",
"name": "eks-node-1",
"properties": {
"instanceType": "m5.xlarge",
"operatingSystem": "Linux"
},
"tags": {
"Name": "eks-node-1",
"kubernetes.io/cluster/my-cluster": "owned"
},
"cost": 625.37,
"start": "2024-03-01T00:00:00Z",
"end": "2024-03-31T23:59:59Z"
},
{
"resourceId": "i-0def456789abc1234",
"name": "eks-node-2",
"properties": {
"instanceType": "m5.xlarge",
"operatingSystem": "Linux"
},
"tags": {
"Name": "eks-node-2",
"kubernetes.io/cluster/my-cluster": "owned"
},
"cost": 625.38,
"start": "2024-03-01T00:00:00Z",
"end": "2024-03-31T23:59:59Z"
}
]
}
```
Port entityJSON
```
{
"identifier": "aws_2024_03_01_t_00_00_00_z_2024_03_31_t_23_59_59_z",
"title": "AWS-2024-03-01T00:00:00Z-2024-03-31T23:59:59Z",
"properties": {
"startDate": "2024-03-01T00:00:00Z",
"endDate": "2024-03-31T23:59:59Z",
"listCost": 1250.75,
"netCost": 1100.5,
"amortizedNetCost": 1050.25,
"invoicedCost": 1250.75,
"amortizedCost": 1200.3
},
"relations": {},
"icon": "Opencost"
}
```
Supported selectors
Below are the supported [selectors](/context-lake/ingestion/configure-mapping/overview/.md#selector) for this resource. Use them under the `selector` key in your integration mapping configuration to control which resources are returned from the API.
| Selector | Type | Description |
| -------------------- | -------- | ----------------------------------------------------------------------------------------------------------------------------------------------------- |
| `exportEnvVariables` | `array` | Environment variable names whose values should be included in lakehouse ingest payloads for DSP processing. |
| `window` | `` | Time window for the OpenCost cloud cost query. Default: `"today"`. |
| `aggregate` | `string` | Field by which to aggregate the results of cloudcost |
| `accumulate` | `string` | Step size of the accumulation. |
| `filter` | `string` | Filter results by any category which that can be aggregated by, can support multiple filterable items in the same category in a comma-separated list. |
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
---
# Cloud providers
Port's cloud integrations make it easy to keep your software catalog up to date based on information stored in your cloud provider.
For more information, check out the documentation for your respective provider:
## [🗃Azure](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure/.md)
[2 items](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/azure/.md)
## [🗃Google Cloud](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/gcp/.md)
[2 items](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/gcp/.md)
## [🗃AWS Legacy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/.md)
[4 items](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/.md)
## [🗃AWS](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/Overview/.md)
[3 items](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/Overview/.md)
---
# Installation
Loading version...
This page guides you through installing the AWS integration. Choose how you want to run it and the integration syncs your AWS resources into your Port catalog, keeping the catalog up to date through periodic resyncs and optional [live events](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/live-events/.md).
The integration supports two deployment options:
* **Hosted by Port**: Fully managed by Port with zero infrastructure to maintain. You create IAM roles via CloudFormation, and Port runs the integration on its servers, connecting to your AWS accounts using OIDC authentication.
* **Self-hosted**: Runs in your own AWS environment (ECS, EC2, EKS, or a one-off Docker run). You manage the deployment and the IAM roles that grant the integration read-only access.
## Setup[](#setup "Direct link to Setup")
Use the wizard below to select your deployment option and follow the steps. For self-hosted installations, you will first choose whether to sync a single account or multiple accounts across your AWS Organization.
1Hosted by Port2Single account3Prerequisites4Deploy CloudFormation stack5Configure integration in Port6Live events (optional)
Hosted by Port
* ✧Fully managed by Port — zero infrastructure to maintain
* ✧Create IAM roles via CloudFormation; Port runs the integration
* ✧Fastest way to get started
Self-hosted
* ✧Runs in your own AWS environment (ECS, EC2, EKS, or Docker)
* ✧You manage the deployment and IAM roles
* ✧Full control over where and how it runs
Single account
Querying specific AWS regions
You can control which AWS regions the integration queries using `regionPolicy`. See [Querying resources from specific regions](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/.md#querying-resources-from-specific-regions).
## Account discovery[](#account-discovery "Direct link to Account discovery")
Relevant for multi-account self-hosted setups
This section explains how the integration discovers accounts when you choose the **multi-account** self-hosted setup. It does not apply to single-account or Hosted by Port installations.
Account discovery is driven by **AWS Organizations**. The integration assumes a role in your **management account** to call the Organizations API, then assumes `PortOceanReadRole` in each discovered account to read and sync resources into your Port catalog. The account list is refreshed on every resync cycle and new accounts are picked up automatically, and removed accounts stop being synced.
How accounts are discovered depends on whether you provide a **Target OU ID** during installation:
### Sync all accounts (default)[](#sync-all-accounts-default "Direct link to Sync all accounts (default)")
Leave the **Target OU ID** field empty to sync every active member account in your organization.
**When to use:** You want full organization-wide visibility with no account filtering.
**How it works:**
1. The integration assumes a role in your management account.
2. It calls the AWS Organizations `ListAccounts` API to enumerate all active accounts in your organization.
3. It assumes `PortOceanReadRole` in each account and syncs resources into your Port catalog.
### Sync accounts in a specific OU[](#sync-accounts-in-a-specific-ou "Direct link to Sync accounts in a specific OU")
Set a **Target OU ID** (`ou-xxxx-xxxxxxxx`) during installation to scope discovery to a specific branch of your organization hierarchy. The integration will discover accounts in that OU and any nested sub-OUs.
**When to use:** You want to limit syncing to a subset of accounts. For example, only accounts in your `production` OU, or a single business unit's accounts.
**How it works:**
1. The integration assumes a role in your management account.
2. It calls `ListAccountsForParent` with your OU ID and recursively walks all nested sub-OUs to build the account list.
3. It assumes `PortOceanReadRole` in each discovered account and syncs resources into your Port catalog.
Find your OU ID in the [AWS Organizations console](https://us-east-1.console.aws.amazon.com/organizations/v2/home/accounts) under **Organizational structure** (format: `ou-xxxx-xxxxxxxx`).
## IAM role architecture[](#iam-role-architecture "Direct link to IAM role architecture")
The integration uses read-only IAM roles to access your AWS resources. How those roles are created and trusted depends on your deployment option. Select a tab below to see the role architecture for your setup.
* Hosted by Port
* Self-hosted
AWS uses a strategically designed IAM role that provides comprehensive read-only access to all AWS services. The role is created automatically by the CloudFormation template and uses the AWS managed `ReadOnlyAccess` policy for future-proofing and operational simplicity.
Role modifications
We recommend keeping the IAM role and its permissions unchanged after deployment. The integration is designed to work with the full `ReadOnlyAccess` policy, which ensures:
* **Complete resource discovery** across all AWS services.
* **Future compatibility** when Port adds support for new AWS services.
* **Reliable operation** without permission-related issues.
If you prefer to create the IAM role manually rather than using the CloudFormation template, the following sections describe the setup we implement. This will help you understand the reasoning behind our design choices and adapt them if you decide to configure the role differently.
### Role structure
For multi-account setups, the role structure is replicated across all target accounts.
#### OIDC identity provider
The CloudFormation template creates an OIDC identity provider that connects to Port's EKS cluster:
```
PortIntegrationOIDCProvider:
Type: AWS::IAM::OIDCProvider
Properties:
Url: 'https://oidc.eks.eu-west-1.amazonaws.com/id/56E5F51C07138118A9183ECEAA68FAF4'
ClientIdList:
- sts.amazonaws.com
Tags:
- Key: port:integration
Value: !Ref IntegrationIdentifier
```
**Key details**:
* **EKS OIDC URL**: Points to Port's production EKS cluster in EU-West-1.
* **Client ID**: Uses `sts.amazonaws.com` for IRSA authentication.
* **Reusable**: Can be shared across multiple integrations in the same account.
* **Optional**: Can be disabled if you already have a Port OIDC provider.
#### Trust policy
The IAM role uses an **OIDC (OpenID Connect) trust policy** with **IRSA (IAM Roles for Service Accounts)** that allows Port's EKS cluster to assume the role:
```
{
"Version": "2012-10-17",
"Statement": [{
"Effect": "Allow",
"Principal": {
"Federated": "arn:aws:iam::YOUR_ACCOUNT_ID:oidc-provider/oidc.eks.eu-west-1.amazonaws.com/id/56E5F51C07138118A9183ECEAA68FAF4"
},
"Action": "sts:AssumeRoleWithWebIdentity",
"Condition": {
"StringEquals": {
"oidc.eks.eu-west-1.amazonaws.com/id/56E5F51C07138118A9183ECEAA68FAF4:aud": "sts.amazonaws.com",
"oidc.eks.eu-west-1.amazonaws.com/id/56E5F51C07138118A9183ECEAA68FAF4:sub": "system:serviceaccount:org-YOUR_ORG_ID-port-oidc-sa"
}
}
}]
}
```
**Key security features**:
* **OIDC authentication**: Role is tied to Port's specific EKS service account.
* **Temporary credentials**: All access uses short-lived tokens (typically 1 hour).
#### Permissions policy
The role uses the **AWS managed `ReadOnlyAccess` policy**, which provides comprehensive read-only access to all AWS services:
```
ManagedPolicyArns:
- arn:aws:iam::aws:policy/ReadOnlyAccess
```
**Strategic benefits**:
* **Future-proof**: Automatically includes new AWS services without CloudFormation updates.
* **Operational simplicity**: No need to redeploy when adding support for new services.
* **Comprehensive coverage**: Access to all AWS services with read-only permissions.
* **AWS maintained**: AWS manages and updates the policy as needed.
* **Read-only security**: Only read permissions, no write/delete/create access.
### Security considerations
From a security view point the integration uses a **read-only** role. It can list/describe and read metadata/tags, but cannot create, modify, delete, or change any resource.
With self-hosted deployments you manage IAM resources directly; the hosted version manages them for you.
### Role structure
In every deployment, the integration uses one read-only role, **PortOceanReadRole**, with the AWS **ReadOnlyAccess** policy. Who can assume that role depends on where you run the integration: an ECS task, an EC2 instance, or a pod using your EKS cluster's OIDC identity. Select a tab below to see the trust policy for that method.
In all cases, the integration process gets an identity (task role, instance role, or OIDC-backed service account). That identity is allowed to assume **PortOceanReadRole**. The read-only role has **ReadOnlyAccess** and is used to call AWS APIs.
* IAM Role (ECS)
* IAM Role (EC2)
* IRSA (EKS)
The integration runs in an ECS task and assumes the read-only role **PortOceanReadRole** to call AWS APIs. Two roles apply:
* **Task role (PortOceanTaskRole)** — Attached to the task; its only permission is `sts:AssumeRole` on PortOceanReadRole.
* **Read-only role (PortOceanReadRole)** — Has the **ReadOnlyAccess** managed policy. Only the task role can assume it.
**Flow** — ECS injects the task role credentials into the container. The integration uses them to assume PortOceanReadRole, then calls AWS APIs with that role.
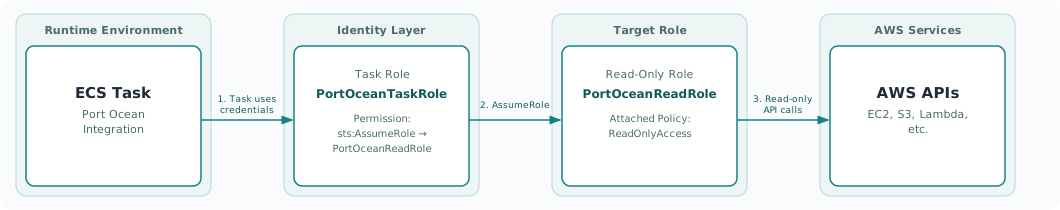
**Read-only role** trust policy. Only the task role can assume this role. Replace `TASK_ROLE_ARN` with your task role ARN:
```
{
"Version": "2012-10-17",
"Statement": [{
"Effect": "Allow",
"Principal": {
"AWS": "TASK_ROLE_ARN"
},
"Action": "sts:AssumeRole"
}]
}
```
**Key security features**: AWS provides temporary credentials to ECS tasks automatically. The task role has only assume-role permission; the read-only role holds **ReadOnlyAccess**. AWS STS automatically rotates credentials. ECS tasks can assume roles in other AWS accounts when you configure cross-account access.
The integration runs on an EC2 instance and assumes the read-only role **PortOceanReadRole** to call AWS APIs. Two roles apply:
* **Instance role (PortOceanInstanceRole)** — Attached to the instance; its only permission is `sts:AssumeRole` on PortOceanReadRole.
* **Read-only role (PortOceanReadRole)** — Has the **ReadOnlyAccess** managed policy. Only the instance role can assume it.
**Flow** — EC2 delivers the instance role credentials to the instance via the instance profile. The integration assumes PortOceanReadRole, then calls AWS APIs with that role.
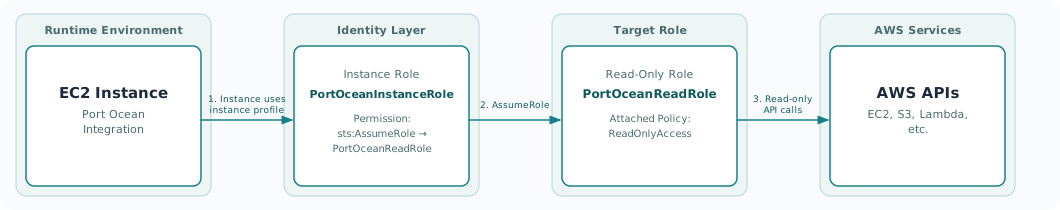
**Read-only role** trust policy. Only the instance role can assume this role. Replace `INSTANCE_ROLE_ARN` with your instance role ARN:
```
{
"Version": "2012-10-17",
"Statement": [{
"Effect": "Allow",
"Principal": {
"AWS": "INSTANCE_ROLE_ARN"
},
"Action": "sts:AssumeRole"
}]
}
```
**Key security features**: EC2 delivers temporary credentials to the instance via the instance profile. The instance role has only assume-role permission; the read-only role holds **ReadOnlyAccess**. AWS STS automatically rotates credentials.
With IRSA, the read-only role (**PortOceanReadRole**) trusts your EKS cluster's OIDC identity provider. There is no separate "task" or "instance" role; the pod receives a web identity token from the service account, and PortOceanReadRole trusts that token.
**Flow** — The pod uses a Kubernetes service account annotated with the IAM role ARN. EKS and the OIDC provider issue a short-lived token. The integration exchanges it for PortOceanReadRole credentials via `AssumeRoleWithWebIdentity`, then calls AWS APIs.
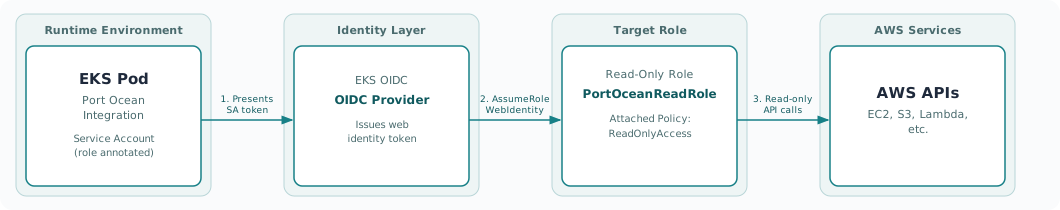
```
{
"Version": "2012-10-17",
"Statement": [{
"Effect": "Allow",
"Principal": {
"Federated": "arn:aws:iam::MEMBER_ACCOUNT_ID:oidc-provider/oidc.eks.YOUR_REGION.amazonaws.com/id/YOUR_OIDC_ID"
},
"Action": "sts:AssumeRoleWithWebIdentity",
"Condition": {
"StringEquals": {
"oidc.eks.YOUR_REGION.amazonaws.com/id/YOUR_OIDC_ID:aud": "sts.amazonaws.com",
"oidc.eks.YOUR_REGION.amazonaws.com/id/YOUR_OIDC_ID:sub": "system:serviceaccount:YOUR_NAMESPACE:YOUR_SERVICE_ACCOUNT"
}
}
}]
}
```
**Key security features**: OIDC federation provides secure identity federation without shared secrets. Roles are tied to specific Kubernetes service accounts, and pods receive short-lived tokens for the role.
### Permissions setup
In every deployment method, the integration calls AWS APIs using **PortOceanReadRole**. That role has the **AWS managed ReadOnlyAccess policy** attached, which gives read-only access to AWS services:
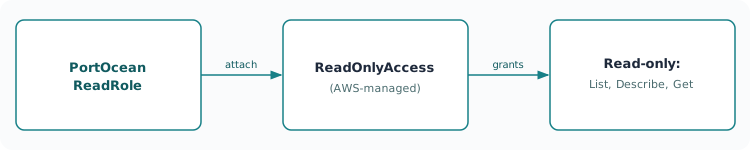
```
ManagedPolicyArns:
- arn:aws:iam::aws:policy/ReadOnlyAccess
```
**Benefits**: The policy automatically includes new AWS services so you do not need to redeploy when AWS adds services. AWS maintains and updates it. Access is read-only; create, modify, and delete actions are not allowed.
### Security considerations
Self-hosted integrations use **read-only** access with carefully configured trust relationships. You can list and describe resources and read metadata and tags; you cannot create, modify, delete, or change any resource.
## Troubleshooting[](#troubleshooting "Direct link to Troubleshooting")
Select your deployment option to troubleshoot installation and sync issues. Use **Interactive mode** to be guided through diagnostic checks, or **Quick reference** to scan the full list of issues and fixes.
* Hosted by Port
* Self-hosted
Interactive modeQuick reference
### What are you experiencing?
Select the issue that best matches your situation. We'll guide you through diagnosing and fixing it step by step.
CloudFormation stack creation failed
The CloudFormation stack that creates the IAM role shows CREATE\_FAILED or ROLLBACK\_COMPLETE
→
No resources appearing in Port
The stack completed successfully but no AWS resources are showing up in your Port catalog
→
Can I use an existing IAM role?
You want to reuse a role you already have instead of the CloudFormation-created one
→
* Single account
* Multi-account
Interactive modeQuick reference
### What are you experiencing?
Select the issue that best matches your situation. We'll guide you through diagnosing and fixing it step by step.
CloudFormation stack creation failed
The ECS, EC2, or EKS stack shows CREATE\_FAILED or ROLLBACK\_COMPLETE
→
No resources discovered
The integration is running but no AWS resources appear in your Port catalog
→
Invalid credentials (IAM User method)
Logs show authentication failures when using static access keys
→
Role or authentication errors
Logs show "Unable to assume role", AccessDenied, or AssumeRoleWithWebIdentity errors
→
Integration not connecting to Port or AWS
The stack completed but the container cannot reach APIs or exits immediately after starting
→
Interactive modeQuick reference
### What are you experiencing?
Select the issue that best matches your situation. We'll guide you through diagnosing and fixing it step by step.
General configuration check
Run through a comprehensive checklist to verify all setup steps are correct
→
Integration not connecting to Port or AWS
Stack completes successfully but the container cannot reach APIs or crashes immediately after starting
→
No resources appearing in Port catalog
Integration is running but no AWS resources are syncing to Port
→
Container keeps crashing or restarting
Integration starts but exits unexpectedly or restarts in a loop
→
Auth or permission errors
Seeing AccessDenied, "Unable to assume role", or InvalidClientTokenId errors in logs
→
Cannot access management account
You do not have access to the AWS Organizations management account to deploy StackSets
→
Unable to assume role errors
Logs show "Unable to assume role" or "AccessDenied" when trying to access member accounts
→
Resync failed: "Not authorized to perform sts:AssumeRoleWithWebIdentity" (IRSA)
Port shows a failed resync, the catalog is empty, and the integration logs contain an AssumeRoleWithWebIdentity AccessDenied error
→
Auth errors for specific AWS regions
Authentication works in most regions but fails for specific opt-in regions like ap-east-1 or me-south-1
→
Access denied to Organizations API
Logs show "AccessDenied" when trying to list or describe AWS Organizations accounts
→
---
# Live events
Live events keep your Port catalog up to date between scheduled resyncs. AWS records API calls as CloudTrail management events, EventBridge matches supported API calls, and forwards them to Port at `{LiveEventsUrl}/integration/webhook`. The integration authenticates each request with the live events API key and updates the matching catalog entity.
Live events are deployed with a **separate CloudFormation stack** from the integration IAM stack. They complement full resyncs but do not replace reconciliation. For how live events interact with resyncs, see [Sync interactions](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/sync-interactions/.md).
CloudTrail required
Ensure CloudTrail is logging **management events** in the accounts and regions where you deploy live events. Without CloudTrail events, EventBridge has nothing to forward.
To deploy the live events CloudFormation stack, follow the **Live events (optional)** step in the [installation wizard](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/installation/.md?step=live-events-optional).
## Supported resource kinds[](#supported-resource-kinds "Direct link to Supported resource kinds")
The integration forwards **CloudTrail management events** for these resource kinds:
| Resource kind | Live events |
| -------------------------------------- | -------------------------- |
| `AWS::S3::Bucket` | Create and delete |
| `AWS::Lambda::Function` | Create, update, and delete |
| `AWS::DynamoDB::Table` | Create, update, and delete |
| `AWS::RDS::DBInstance` | Create, update, and delete |
| `AWS::RDS::DBCluster` | Create, update, and delete |
| `AWS::ECR::Repository` | Create and delete |
| `AWS::ECS::Cluster` | Create, update, and delete |
| `AWS::ECS::Service` | Create, update, and delete |
| `AWS::ECS::TaskDefinition` | Register and deregister |
| `AWS::EKS::Cluster` | Create, update, and delete |
| `AWS::EC2::Instance` | Launch and terminate |
| `AWS::EC2::Volume` | Create, modify, and delete |
| `AWS::ElastiCache::Cluster` | Create, modify, and delete |
| `AWS::MemoryDB::User` | Create, update, and delete |
| `AWS::CodeBuild::Project` | Create, update, and delete |
| `AWS::CodeBuild::BuildRun` | Start, stop, and retry |
| `AWS::CodeDeploy::Deployment` | Create and stop |
| `AWS::CodePipeline::Pipeline` | Create, update, and delete |
| `AWS::CodePipeline::PipelineExecution` | Start and stop |
| `AWS::SNS::Topic` | Create, update, and delete |
| `AWS::SQS::Queue` | Create, update, and delete |
| `AWS::SES::EmailIdentity` | Create, update, and delete |
| `AWS::SES::ConfigurationSet` | Create, update, and delete |
## Unsupported resource kinds[](#unsupported-resource-kinds "Direct link to Unsupported resource kinds")
The following kinds are ingested during resyncs but **do not** receive live events today:
| Resource kind | Reason |
| ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------ |
| `AWS::Account::Info` | Account metadata is synced from account-level APIs, not from regional CloudTrail CRUD events. |
| `AWS::Organizations::Account` | Organization account lifecycle events are not mapped to live events yet. |
| `AWS::MSK::Cluster` | Same CloudTrail events also map to `AWS::MSK::ServerlessCluster`, so the kind cannot be identified reliably. |
| `AWS::MSK::ServerlessCluster` | Same CloudTrail events also map to `AWS::MSK::Cluster`, so the kind cannot be identified reliably. |
| `AWS::CodeDeploy::Application` | CloudTrail exposes mutable application names, not stable ARNs. |
| `AWS::CodeDeploy::DeploymentGroup` | CloudTrail exposes mutable group names, not stable ARNs. |
| `AWS::CodePipeline::Stage` | Derived from pipeline definitions; CloudTrail has no per-stage CRUD events. |
| `AWS::CodePipeline::Action` | Derived from pipeline definitions; CloudTrail has no per-action CRUD events. |
| `AWS::CodePipeline::ActionExecution` | No CloudTrail API events; lifecycle updates use CodePipeline EventBridge state-change events not supported by live events yet. |
## Troubleshooting[](#troubleshooting "Direct link to Troubleshooting")
### Events not appearing in Port
* Confirm the live events API key in Port matches the `LiveEventsApiKey` CloudFormation parameter.
* Verify CloudTrail is enabled and logging management events in the account and region where you changed the resource.
* Check that the resource kind is in the [supported list](#supported-resource-kinds). [Unsupported kinds](#unsupported-resource-kinds) update only during resyncs.
* For multi-account setups, confirm StackSet operations succeeded in the [StackSets console](https://console.aws.amazon.com/cloudformation/home#/stacksets).
* For self-hosted ECS or EC2 setups, confirm `EnableLiveEvents` is `true` on the Ocean stack and that your public HTTPS URL routes to Ocean on port `8000`.
* For self-hosted IRSA or IAM User setups, confirm `OCEAN__BASE_URL` and `OCEAN__INTEGRATION__CONFIG__LIVE_EVENTS_API_KEY` are set and ingress routes HTTPS traffic to `/integration/webhook`.
### Stack creation failed
* **Insufficient IAM permissions**: Ensure your AWS user can create CloudFormation stacks, IAM roles, EventBridge connections, and StackSets (for multi-account).
* **Regions not enabled**: Live events deploy only to enabled AWS regions. Enable the region in [Account settings](https://console.aws.amazon.com/billing/home#/account) or remove it from the `Regions` parameter.
* **Multi-account regions missing**: The `Regions` parameter is required for multi-account live events stacks.
---
# AWS

Loading version...
Port's AWS integration imports your AWS resources into Port, with flexible deployment options to match your needs. The integration syncs your AWS resources on a schedule and can optionally process live events so your Port catalog stays up to date with your AWS infrastructure.
Supported resources [AWS::SQS::Queue](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-sqs-queue.html)[AWS::S3::Bucket](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-s3-bucket.html)[AWS::EC2::Instance](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ec2-instance.html)[AWS::EC2::Volume](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ec2-volume.html)[AWS::ECR::Repository](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ecr-repository.html)[AWS::ECS::Cluster](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ecs-cluster.html)[AWS::ECS::Service](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ecs-service.html)[AWS::ECS::TaskDefinition](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ecs-taskdefinition.html)[AWS::EKS::Cluster](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-eks-cluster.html)[AWS::Organizations::Account](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-organizations-account.html)[AWS::RDS::DBInstance](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-rds-dbinstance.html)[AWS::RDS::DBCluster](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-rds-dbcluster.html)[AWS::Lambda::Function](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-lambda-function.html)[AWS::Account::Info](https://docs.aws.amazon.com/accounts/latest/reference/welcome.html)[AWS::MSK::Cluster](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-msk-cluster.html)[AWS::MSK::ServerlessCluster](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-msk-serverlesscluster.html)[AWS::ElastiCache::Cluster](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-elasticache-cachecluster.html)[AWS::MemoryDB::User](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-memorydb-user.html)[AWS::CodeBuild::Project](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-codebuild-project.html)[AWS::CodeBuild::BuildRun](https://docs.aws.amazon.com/codebuild/latest/APIReference/API_Build.html)[AWS::CodeDeploy::Application](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-codedeploy-application.html)[AWS::CodeDeploy::DeploymentGroup](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-codedeploy-deploymentgroup.html)[AWS::CodeDeploy::Deployment](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_DeploymentInfo.html)[AWS::CodeDeploy::DeploymentTarget](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_DeploymentTarget.html)[AWS::CodePipeline::Pipeline](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-codepipeline-pipeline.html)[AWS::CodePipeline::Stage](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_StageDeclaration.html)[AWS::CodePipeline::Action](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_ActionDeclaration.html)[AWS::CodePipeline::PipelineExecution](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_PipelineExecution.html)[AWS::CodePipeline::ActionExecution](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_ActionExecutionDetail.html)[AWS::DynamoDB::Table](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-dynamodb-table.html)[AWS::SES::EmailIdentity](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ses-emailidentity.html)[AWS::SES::ConfigurationSet](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ses-configurationset.html)[AWS::SNS::Topic](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-sns-topic.html)
Port's AWS integration is open source. View the source code [here](https://github.com/port-labs/ocean/tree/main/integrations/aws-v3).
Custom kinds not supported
AWS only syncs the resource kinds listed above. Unlike the [AWS Legacy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/.md) integration, it does not support defining custom kinds for other [Cloud Control API](https://docs.aws.amazon.com/cloudcontrolapi/latest/userguide/supported-resources.html) resources yet.
## Deployment options[](#deployment-options "Direct link to Deployment options")
The integration can be deployed using one of the following methods:
* **[Hosted by Port](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/installation/.md?troubleshoot=hosted\&method=hosted)**: Fully managed by Port with zero maintenance required. Simply create IAM roles via CloudFormation, and Port handles the rest.
* **[Self-hosted](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/installation/.md?method=self-hosted)**: Deploy the integration in your own infrastructure using ECS, EC2, EKS, or as a one-off Docker run for complete control.
For detailed information about the IAM role architecture, see the [IAM role architecture](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/installation/.md#iam-role-architecture) section of the installation page.
## Live events[](#live-events "Direct link to Live events")
You can optionally enable live events to update supported resource kinds in real time between resyncs. Live events use CloudTrail management events forwarded by EventBridge to Port.
Deploy live events with a separate CloudFormation stack after the integration is installed. Follow the **Live events (optional)** step in the [installation wizard](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/installation/.md?step=live-events-optional). Not every resource kind supports live events yet. See [supported](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/live-events/.md#supported-resource-kinds) and [unsupported](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/live-events/.md#unsupported-resource-kinds) resource kinds on the live events page.
GovCloud and on-premises support
The integration supports AWS GovCloud.
When running a self-hosted GovCloud integration, it is recommended to run using the **AssumeRole** mode.
If you run in **StaticCredentials** mode, you will need to set the `OCEAN__INTEGRATION__CONFIG__AWS_PARTITION` environment variable to specify your AWS partition (for example, `aws-us-gov` for GovCloud).
## Common use cases[](#common-use-cases "Direct link to Common use cases")
Easily fill your software catalog with data directly from your AWS Organization, for example:
* Map all the resources in your AWS Accounts, including **ECS Clusters**, **S3 Buckets**, and **EC2 Instances** with zero maintenance required.
* Keep your Port catalog synchronized with your AWS infrastructure through periodic updates and optional live events.
* Use relations to create complete, easily digestible views of your AWS infrastructure inside Port.
* Enjoy a fully managed experience with no infrastructure to maintain or updates to apply.
Multi-account support
The integration supports syncing resources across multiple AWS accounts using automatic account discovery via AWS Organizations. See the [account discovery](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/installation/.md#account-discovery) section of the installation page for details.
## Key advantages[](#key-advantages "Direct link to Key advantages")
AWS provides several advantages over the [AWS Legacy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/.md) integration:
* **Fully hosted**: No infrastructure to maintain, update, or monitor.
* **Simplified installation**: Just deploy CloudFormation templates to create IAM roles.
* **Complete data**: Ensures no missing or incomplete resource information.
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
Property naming conventions
The AWS integration returns all resource properties in **PascalCase** (for example: `Arn`, `BucketName`, `CreationDate`). When writing mappings and JQ expressions, reference properties using PascalCasing as shown in the examples below.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration you get after installing AWS.
**Default mapping configuration (click to expand)**
```
deleteDependentEntities: true
createMissingRelatedEntities: true
enableMergeEntity: true
resources:
- kind: AWS::Account::Info
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Id
title: .Properties.Name
blueprint: '"awsAccount"'
- kind: AWS::S3::Bucket
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Properties.BucketName
blueprint: '"s3Bucket"'
properties:
arn: .Properties.Arn
region: .Properties.LocationConstraint
creationDate: .Properties.CreationDate
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
- kind: AWS::EC2::Instance
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.InstanceId
title: .Properties.InstanceId
blueprint: '"ec2Instance"'
properties:
instanceType: .Properties.InstanceType
state: .Properties.State.Name
publicIpAddress: .Properties.PublicIpAddress
privateIpAddress: .Properties.PrivateIpAddress
tags: .Properties.Tags
arn: >-
"arn:aws:ec2:" + .__Region + ":" + .__AccountId + ":instance/" +
.Properties.InstanceId
relations:
account: .__ExtraContext.AccountId
- kind: AWS::ECS::Cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ClusterArn
title: .Properties.ClusterName
blueprint: '"ecsCluster"'
properties:
status: .Properties.Status
runningTasksCount: .Properties.RunningTasksCount
activeServicesCount: .Properties.ActiveServicesCount
pendingTasksCount: .Properties.PendingTasksCount
registeredContainerInstancesCount: .Properties.RegisteredContainerInstancesCount
capacityProviders: .Properties.CapacityProviders
clusterArn: .Properties.ClusterArn
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
The following sections show examples of blueprint definitions and mapping configurations for common AWS resources.
SQS QueueS3 BucketEC2 InstanceEC2 VolumeECR RepositoryECS ClusterECS ServiceECS Task DefinitionEKS ClusterOrganizations AccountRDS DB InstanceRDS DB ClusterLambda FunctionAWS Account InfoMSK ClusterMSK Serverless ClusterElastiCache ClusterMemoryDB UserCodeBuild ProjectCodeBuild Build RunCodeDeploy ApplicationCodeDeploy Deployment GroupCodeDeploy DeploymentCodeDeploy Deployment TargetCodePipeline PipelineCodePipeline StageCodePipeline ActionCodePipeline Pipeline ExecutionCodePipeline Action ExecutionDynamoDB TableSES Email IdentitySES Configuration Set
BlueprintJSON
Create in Port
```
{
"identifier": "sqsQueue",
"title": "SQS Queue",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN"
},
"region": {
"type": "string",
"title": "Region"
},
"queueUrl": {
"type": "string",
"title": "Queue URL"
},
"approximateNumberOfMessages": {
"type": "number",
"title": "Approx Number of Messages"
},
"visibilityTimeout": {
"type": "number",
"title": "Visibility Timeout (seconds)"
},
"messageRetentionPeriod": {
"type": "number",
"title": "Message Retention Period"
},
"sqsManagedSseEnabled": {
"type": "boolean",
"title": "SQS Managed SSE Enabled"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::SQS::Queue
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.QueueArn
title: .Properties.QueueUrl | split("/") | .[-1]
blueprint: '"sqsQueue"'
properties:
arn: .Properties.QueueArn
region: .__ExtraContext.Region
queueUrl: .Properties.QueueUrl
approximateNumberOfMessages: .Properties.ApproximateNumberOfMessages
visibilityTimeout: .Properties.VisibilityTimeout
messageRetentionPeriod: .Properties.MessageRetentionPeriod
sqsManagedSseEnabled: .Properties.SqsManagedSseEnabled
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "s3Bucket",
"title": "S3 Bucket",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN"
},
"creationDate": {
"type": "string",
"format": "date-time",
"title": "Creation Date"
},
"tags": {
"type": "array",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::S3::Bucket
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Properties.BucketName
blueprint: '"s3Bucket"'
properties:
arn: .Properties.Arn
creationDate: .Properties.CreationDate
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "ec2Instance",
"title": "EC2 Instance",
"icon": "AWS",
"schema": {
"properties": {
"instanceArn": {
"type": "string",
"title": "Instance ARN"
},
"instanceId": {
"type": "string",
"title": "Instance ID"
},
"instanceType": {
"type": "string",
"title": "Instance Type"
},
"availabilityZone": {
"type": "string",
"title": "Availability Zone"
},
"tags": {
"type": "array",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::EC2::Instance
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.InstanceId
title: .Properties.InstanceId
blueprint: '"ec2Instance"'
properties:
instanceArn: .Properties.InstanceArn
instanceId: .Properties.InstanceId
instanceType: .Properties.InstanceType
availabilityZone: .Properties.AvailabilityZone
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "ebsVolume",
"title": "EBS Volume",
"icon": "AWS",
"schema": {
"properties": {
"volumeType": {
"type": "string",
"title": "Volume Type",
"description": "The volume type (gp2, gp3, io1, io2, st1, sc1, standard)"
},
"size": {
"type": "number",
"title": "Size (GiB)",
"description": "The size of the volume in GiB"
},
"iops": {
"type": "number",
"title": "IOPS",
"description": "The number of I/O operations per second"
},
"throughput": {
"type": "number",
"title": "Throughput (MiB/s)",
"description": "The throughput provisioned for the volume in MiB/s"
},
"availabilityZone": {
"type": "string",
"title": "Availability Zone",
"description": "The Availability Zone in which the volume resides"
},
"state": {
"type": "string",
"title": "State",
"description": "The current state of the volume",
"enum": [
"creating",
"available",
"in-use",
"deleting",
"deleted",
"error"
]
},
"creationDate": {
"type": "string",
"title": "Creation Date",
"description": "The date and time the volume was created",
"format": "date-time"
},
"encrypted": {
"type": "boolean",
"title": "Encrypted",
"description": "Indicates whether the volume is encrypted"
},
"autoEnableIO": {
"type": "boolean",
"title": "Auto Enable IO",
"description": "Indicates whether the volume is auto-enabled for I/O operations"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the volume",
"items": {
"type": "object"
}
},
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the volume"
}
},
"required": []
},
"calculationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::EC2::Volume
selector:
query: 'true'
includeActions:
- DescribeVolumeAttributeAction
port:
entity:
mappings:
identifier: .Properties.VolumeId
title: '(.Properties.Tags // [] | map(select(.Key == "Name")) | first | .Value) // .Properties.VolumeId'
blueprint: '"ebsVolume"'
properties:
volumeType: .Properties.VolumeType
size: .Properties.Size
iops: .Properties.Iops
throughput: .Properties.Throughput
availabilityZone: .Properties.AvailabilityZone
state: .Properties.State
creationDate: .Properties.CreateTime
encrypted: .Properties.Encrypted
autoEnableIO: .Properties.AutoEnableIO
tags: .Properties.Tags
arn: '"arn:aws:ec2:" + .__ExtraContext.Region + ":" + .__ExtraContext.AccountId + ":volume/" + .Properties.VolumeId'
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "ecrRepository",
"title": "ECR Repository",
"icon": "AWS",
"schema": {
"properties": {
"repositoryUri": {
"type": "string",
"title": "Repository URI"
},
"registryId": {
"type": "string",
"title": "Registry ID"
},
"createdAt": {
"type": "string",
"title": "Created At"
},
"imageTagMutability": {
"type": "string",
"title": "Image Tag Mutability"
},
"imageScanningConfiguration": {
"type": "object",
"title": "Image Scanning Configuration"
},
"encryptionConfiguration": {
"type": "object",
"title": "Encryption Configuration"
},
"tags": {
"type": "array",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::ECR::Repository
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.RepositoryArn
title: .Properties.RepositoryName
blueprint: '"ecrRepository"'
properties:
repositoryUri: .Properties.RepositoryUri
registryId: .Properties.RegistryId
createdAt: .Properties.CreatedAt
imageTagMutability: .Properties.ImageTagMutability
imageScanningConfiguration: .Properties.ImageScanningConfiguration
encryptionConfiguration: .Properties.EncryptionConfiguration
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "ecsCluster",
"title": "ECS Cluster",
"icon": "AWS",
"schema": {
"properties": {
"status": {
"type": "string",
"title": "Status"
},
"runningTasksCount": {
"type": "number",
"title": "Running Tasks Count"
},
"activeServicesCount": {
"type": "number",
"title": "Active Services Count"
},
"pendingTasksCount": {
"type": "number",
"title": "Pending Tasks Count"
},
"registeredContainerInstancesCount": {
"type": "number",
"title": "Registered Container Instances Count"
},
"capacityProviders": {
"type": "array",
"title": "Capacity Providers"
},
"clusterArn": {
"type": "string",
"title": "Cluster ARN"
},
"tags": {
"type": "array",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::ECS::Cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ClusterArn
title: .Properties.ClusterName
blueprint: '"ecsCluster"'
properties:
status: .Properties.Status
runningTasksCount: .Properties.RunningTasksCount
activeServicesCount: .Properties.ActiveServicesCount
pendingTasksCount: .Properties.PendingTasksCount
registeredContainerInstancesCount: .Properties.RegisteredContainerInstancesCount
capacityProviders: .Properties.CapacityProviders
clusterArn: .Properties.ClusterArn
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "ecsService",
"title": "ECS Service",
"icon": "AWS",
"schema": {
"properties": {
"serviceName": {
"type": "string",
"title": "Service Name",
"description": "The name of the ECS service"
},
"serviceArn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the service"
},
"clusterArn": {
"type": "string",
"title": "Cluster ARN",
"description": "The ARN of the cluster that hosts the service"
},
"taskDefinition": {
"type": "string",
"title": "Task Definition",
"description": "The ARN of the task definition associated with the service"
},
"desiredCount": {
"type": "number",
"title": "Desired Count",
"description": "The desired number of tasks for the service"
},
"runningCount": {
"type": "number",
"title": "Running Count",
"description": "The number of tasks that are currently running"
},
"pendingCount": {
"type": "number",
"title": "Pending Count",
"description": "The number of tasks in the PENDING state"
},
"launchType": {
"type": "string",
"title": "Launch Type",
"description": "The launch type of the service",
"enum": [
"EC2",
"FARGATE",
"EXTERNAL"
]
},
"schedulingStrategy": {
"type": "string",
"title": "Scheduling Strategy",
"description": "The scheduling strategy to use for the service",
"enum": [
"REPLICA",
"DAEMON"
]
},
"status": {
"type": "string",
"title": "Status",
"description": "The current status of the service",
"enum": [
"ACTIVE",
"DRAINING",
"INACTIVE"
]
},
"deploymentConfiguration": {
"type": "object",
"title": "Deployment Configuration",
"description": "The deployment configuration for the service"
},
"deploymentController": {
"type": "object",
"title": "Deployment Controller",
"description": "The deployment controller type for the service"
},
"deployments": {
"type": "array",
"title": "Deployments",
"description": "The current deployments of the service",
"items": {
"type": "object"
}
},
"enableECSManagedTags": {
"type": "boolean",
"title": "ECS Managed Tags",
"description": "Whether to enable ECS managed tags"
},
"enableExecuteCommand": {
"type": "boolean",
"title": "Execute Command",
"description": "Whether to enable ECS Exec for the service"
},
"events": {
"type": "array",
"title": "Events",
"description": "The events associated with the service",
"items": {
"type": "object"
}
},
"healthCheckGracePeriodSeconds": {
"type": "number",
"title": "Health Check Grace Period",
"description": "The grace period for health checks in seconds"
},
"loadBalancers": {
"type": "array",
"title": "Load Balancers",
"description": "The load balancers associated with the service",
"items": {
"type": "object"
}
},
"networkConfiguration": {
"type": "object",
"title": "Network Configuration",
"description": "The network configuration for the service"
},
"placementConstraints": {
"type": "array",
"title": "Placement Constraints",
"description": "The placement constraints for the service",
"items": {
"type": "object"
}
},
"placementStrategy": {
"type": "array",
"title": "Placement Strategy",
"description": "The placement strategy for the service",
"items": {
"type": "object"
}
},
"platformFamily": {
"type": "string",
"title": "Platform Family",
"description": "The platform family for the service"
},
"platformVersion": {
"type": "string",
"title": "Platform Version",
"description": "The platform version for the service"
},
"propagateTags": {
"type": "string",
"title": "Propagate Tags",
"description": "Whether to propagate tags from the service or task definition",
"enum": [
"SERVICE",
"TASK_DEFINITION"
]
},
"roleArn": {
"type": "string",
"title": "Role ARN",
"description": "The ARN of the IAM role associated with the service"
},
"serviceRegistries": {
"type": "array",
"title": "Service Registries",
"description": "The service registries associated with the service",
"items": {
"type": "object"
}
},
"tags": {
"type": "array",
"title": "Tags",
"description": "The tags associated with the service",
"items": {
"type": "object"
}
},
"taskSets": {
"type": "array",
"title": "Task Sets",
"description": "The task sets associated with the service",
"items": {
"type": "object"
}
},
"capacityProviderStrategy": {
"type": "array",
"title": "Capacity Provider Strategy",
"description": "The capacity provider strategy for the service",
"items": {
"type": "object"
}
},
"availabilityZoneRebalancing": {
"type": "string",
"title": "Availability Zone Rebalancing",
"description": "Whether availability zone rebalancing is enabled",
"enum": [
"ENABLED",
"DISABLED"
]
},
"createdAt": {
"type": "string",
"title": "Created At",
"description": "The timestamp when the service was created",
"format": "date-time"
},
"createdBy": {
"type": "string",
"title": "Created By",
"description": "The ARN of the entity that created the service"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
},
"cluster": {
"title": "Cluster",
"target": "ecsCluster",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::ECS::Service
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ServiceArn
title: .Properties.ServiceName
blueprint: '"ecsService"'
properties:
serviceName: .Properties.ServiceName
serviceArn: .Properties.ServiceArn
clusterArn: .Properties.ClusterArn
taskDefinition: .Properties.TaskDefinition
desiredCount: .Properties.DesiredCount
runningCount: .Properties.RunningCount
pendingCount: .Properties.PendingCount
launchType: .Properties.LaunchType
schedulingStrategy: .Properties.SchedulingStrategy
status: .Properties.Status
deploymentConfiguration: .Properties.DeploymentConfiguration
deploymentController: .Properties.DeploymentController
deployments: .Properties.Deployments
enableECSManagedTags: .Properties.EnableECSManagedTags
enableExecuteCommand: .Properties.EnableExecuteCommand
events: .Properties.Events
healthCheckGracePeriodSeconds: .Properties.HealthCheckGracePeriodSeconds
loadBalancers: .Properties.LoadBalancers
networkConfiguration: .Properties.NetworkConfiguration
placementConstraints: .Properties.PlacementConstraints
placementStrategy: .Properties.PlacementStrategy
platformFamily: .Properties.PlatformFamily
platformVersion: .Properties.PlatformVersion
propagateTags: .Properties.PropagateTags
roleArn: .Properties.RoleArn
serviceRegistries: .Properties.ServiceRegistries
tags: .Properties.Tags
taskSets: .Properties.TaskSets
capacityProviderStrategy: .Properties.CapacityProviderStrategy
availabilityZoneRebalancing: .Properties.AvailabilityZoneRebalancing
createdAt: .Properties.CreatedAt
createdBy: .Properties.CreatedBy
relations:
account: .__ExtraContext.AccountId
cluster: .Properties.ClusterArn
```
BlueprintJSON
Create in Port
```
{
"identifier": "ecsTaskDefinition",
"title": "ECS Task Definition",
"icon": "AWS",
"schema": {
"properties": {
"taskDefinitionArn": {
"type": "string",
"title": "Task Definition ARN",
"description": "The full ARN of the task definition"
},
"family": {
"type": "string",
"title": "Family",
"description": "The family name of the task definition"
},
"revision": {
"type": "number",
"title": "Revision",
"description": "The revision number of the task definition"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the task definition",
"enum": [
"ACTIVE",
"INACTIVE",
"DELETE_IN_PROGRESS"
]
},
"containerDefinitions": {
"type": "array",
"title": "Container Definitions",
"description": "The container definitions that describe the containers in the task",
"items": {
"type": "object"
}
},
"cpu": {
"type": "string",
"title": "CPU",
"description": "The number of CPU units used by the task (e.g. 256, 512, 1024)"
},
"memory": {
"type": "string",
"title": "Memory",
"description": "The amount of memory (in MiB) used by the task (e.g. 512, 1024, 2048)"
},
"networkMode": {
"type": "string",
"title": "Network Mode",
"description": "The Docker networking mode to use for the containers",
"enum": [
"bridge",
"host",
"awsvpc",
"none"
]
},
"requiresCompatibilities": {
"type": "array",
"title": "Requires Compatibilities",
"description": "The task launch types the task definition was validated against",
"items": {
"type": "string"
}
},
"taskRoleArn": {
"type": "string",
"title": "Task Role ARN",
"description": "The ARN of the IAM role that grants containers permission to call AWS APIs"
},
"executionRoleArn": {
"type": "string",
"title": "Execution Role ARN",
"description": "The ARN of the task execution IAM role"
},
"volumes": {
"type": "array",
"title": "Volumes",
"description": "The list of data volume definitions for the task",
"items": {
"type": "object"
}
},
"placementConstraints": {
"type": "array",
"title": "Placement Constraints",
"description": "The placement constraint objects to use for tasks",
"items": {
"type": "object"
}
},
"tags": {
"type": "array",
"title": "Tags",
"description": "The tags associated with the task definition",
"items": {
"type": "object"
}
},
"registeredAt": {
"type": "string",
"title": "Registered At",
"format": "date-time",
"description": "The timestamp when the task definition was registered"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::ECS::TaskDefinition
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.TaskDefinitionArn
title: .Properties.Family + ":" + (.Properties.Revision | tostring)
blueprint: '"ecsTaskDefinition"'
properties:
taskDefinitionArn: .Properties.TaskDefinitionArn
family: .Properties.Family
revision: .Properties.Revision
status: .Properties.Status
containerDefinitions: .Properties.ContainerDefinitions
cpu: .Properties.Cpu
memory: .Properties.Memory
networkMode: .Properties.NetworkMode
requiresCompatibilities: .Properties.RequiresCompatibilities
taskRoleArn: .Properties.TaskRoleArn
executionRoleArn: .Properties.ExecutionRoleArn
volumes: .Properties.Volumes
placementConstraints: .Properties.PlacementConstraints
tags: .Properties.Tags
registeredAt: .Properties.RegisteredAt
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "eksCluster",
"title": "EKS Cluster",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN"
},
"name": {
"type": "string",
"title": "Name"
},
"version": {
"type": "string",
"title": "Kubernetes Version"
},
"status": {
"type": "string",
"title": "Status"
},
"endpoint": {
"type": "string",
"title": "Endpoint"
},
"roleArn": {
"type": "string",
"title": "Role ARN"
},
"tags": {
"type": "object",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::EKS::Cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Properties.Name
blueprint: '"eksCluster"'
properties:
arn: .Properties.Arn
name: .Properties.Name
version: .Properties.Version
status: .Properties.Status
endpoint: .Properties.Endpoint
roleArn: .Properties.RoleArn
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "awsOrganizationAccount",
"title": "Organizations Account",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN"
},
"email": {
"type": "string",
"title": "Email"
},
"status": {
"type": "string",
"title": "Status"
},
"joinedTimestamp": {
"type": "string",
"title": "Joined Timestamp"
},
"joinedMethod": {
"type": "string",
"title": "Joined Method"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: AWS::Organizations::Account
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Id
title: .Properties.AccountName
blueprint: '"awsOrganizationAccount"'
properties:
arn: .Properties.Arn
email: .Properties.Email
status: .Properties.Status
joinedTimestamp: .Properties.JoinedTimestamp
joinedMethod: .Properties.JoinedMethod
```
BlueprintJSON
Create in Port
```
{
"identifier": "rdsDbInstance",
"title": "RDS DB Instance",
"icon": "AWS",
"schema": {
"properties": {
"dbInstanceIdentifier": {
"type": "string",
"title": "DB Instance Identifier"
},
"dbInstanceArn": {
"type": "string",
"title": "ARN"
},
"engine": {
"type": "string",
"title": "Engine"
},
"dbInstanceClass": {
"type": "string",
"title": "Instance Class"
},
"dbInstanceStatus": {
"type": "string",
"title": "Status"
},
"multiAZ": {
"type": "boolean",
"title": "Multi-AZ"
},
"storageEncrypted": {
"type": "boolean",
"title": "Storage Encrypted"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::RDS::DBInstance
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DBInstanceArn
title: .Properties.DBInstanceIdentifier
blueprint: '"rdsDbInstance"'
properties:
dbInstanceIdentifier: .Properties.DBInstanceIdentifier
dbInstanceArn: .Properties.DBInstanceArn
engine: .Properties.Engine
dbInstanceClass: .Properties.DBInstanceClass
dbInstanceStatus: .Properties.DBInstanceStatus
multiAZ: .Properties.MultiAZ
storageEncrypted: .Properties.StorageEncrypted
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "rdsDbCluster",
"title": "RDS DB Cluster",
"icon": "AWS",
"schema": {
"properties": {
"activityStreamStatus": {
"type": "string",
"title": "Activity Stream Status",
"description": "The status of the database activity stream"
},
"associatedRoles": {
"type": "array",
"title": "Associated Roles",
"description": "The IAM roles associated with the DB cluster",
"items": {
"type": "object"
}
},
"autoMinorVersionUpgrade": {
"type": "boolean",
"title": "Auto Minor Version Upgrade",
"description": "Whether minor version upgrades are applied automatically"
},
"availabilityZones": {
"type": "array",
"title": "Availability Zones",
"description": "The Availability Zones where the DB cluster is deployed",
"items": {
"type": "string"
}
},
"backupRetentionPeriod": {
"type": "number",
"title": "Backup Retention Period",
"description": "The number of days to retain automated backups"
},
"clusterCreateTime": {
"type": "string",
"title": "Cluster Create Time",
"description": "The time when the DB cluster was created"
},
"copyTagsToSnapshot": {
"type": "boolean",
"title": "Copy Tags To Snapshot",
"description": "Whether to copy tags to snapshots"
},
"crossAccountClone": {
"type": "boolean",
"title": "Cross Account Clone",
"description": "Whether cross-account cloning is enabled"
},
"databaseName": {
"type": "string",
"title": "Database Name",
"description": "The name of the initial database"
},
"dbClusterArn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the DB cluster"
},
"dbClusterIdentifier": {
"type": "string",
"title": "DB Cluster Identifier",
"description": "The unique identifier of the RDS DB cluster"
},
"dbClusterMembers": {
"type": "array",
"title": "DB Cluster Members",
"description": "The DB instances that belong to the cluster",
"items": {
"type": "object"
}
},
"dbClusterResourceId": {
"type": "string",
"title": "DB Cluster Resource ID",
"description": "The unique resource identifier for the DB cluster"
},
"deletionProtection": {
"type": "boolean",
"title": "Deletion Protection",
"description": "Whether deletion protection is enabled"
},
"earliestRestorableTime": {
"type": "string",
"title": "Earliest Restorable Time",
"description": "The earliest time to which the DB cluster can be restored"
},
"endpoint": {
"type": "string",
"title": "Writer Endpoint",
"description": "The writer endpoint for the DB cluster"
},
"engine": {
"type": "string",
"title": "Engine",
"description": "The database engine type (e.g., aurora-mysql, aurora-postgresql)"
},
"engineMode": {
"type": "string",
"title": "Engine Mode",
"description": "The engine mode of the DB cluster (e.g., provisioned, serverless)"
},
"engineVersion": {
"type": "string",
"title": "Engine Version",
"description": "The version of the database engine"
},
"globalWriteForwardingStatus": {
"type": "string",
"title": "Global Write Forwarding Status",
"description": "The status of write forwarding for a secondary cluster in a global database"
},
"httpEndpointEnabled": {
"type": "boolean",
"title": "HTTP Endpoint Enabled",
"description": "Whether the HTTP endpoint (Data API) is enabled for Aurora Serverless"
},
"iamDatabaseAuthenticationEnabled": {
"type": "boolean",
"title": "IAM Database Authentication Enabled",
"description": "Whether IAM database authentication is enabled"
},
"kmsKeyId": {
"type": "string",
"title": "KMS Key ID",
"description": "The KMS key identifier for encryption"
},
"latestRestorableTime": {
"type": "string",
"title": "Latest Restorable Time",
"description": "The latest time to which the DB cluster can be restored"
},
"masterUsername": {
"type": "string",
"title": "Master Username",
"description": "The master username for the DB cluster"
},
"multiAZ": {
"type": "boolean",
"title": "Multi-AZ",
"description": "Whether the DB cluster is deployed across multiple Availability Zones"
},
"networkType": {
"type": "string",
"title": "Network Type",
"description": "The network type for the DB cluster"
},
"port": {
"type": "number",
"title": "Port",
"description": "The port number for the DB cluster"
},
"preferredBackupWindow": {
"type": "string",
"title": "Preferred Backup Window",
"description": "The preferred backup window"
},
"preferredMaintenanceWindow": {
"type": "string",
"title": "Preferred Maintenance Window",
"description": "The preferred maintenance window"
},
"readerEndpoint": {
"type": "string",
"title": "Reader Endpoint",
"description": "The reader endpoint for load-balancing read connections across cluster members"
},
"status": {
"type": "string",
"title": "Status",
"description": "The current status of the DB cluster",
"enum": [
"available",
"backing-up",
"creating",
"deleting",
"failing-over",
"inaccessible-encryption-credentials",
"maintenance",
"migrating",
"modifying",
"promoting",
"renaming",
"resetting-master-credentials",
"scaling",
"starting",
"stopped",
"stopping",
"upgrading"
]
},
"storageEncrypted": {
"type": "boolean",
"title": "Storage Encrypted",
"description": "Whether the DB cluster storage is encrypted"
},
"storageType": {
"type": "string",
"title": "Storage Type",
"description": "The storage type of the DB cluster"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "The tags associated with the DB cluster",
"items": {
"type": "object",
"properties": {
"Key": {
"type": "string"
},
"Value": {
"type": "string"
}
}
}
},
"vpcSecurityGroups": {
"type": "array",
"title": "VPC Security Groups",
"description": "The VPC security groups associated with the DB cluster",
"items": {
"type": "object"
}
},
"dbSubnetGroup": {
"type": "string",
"title": "DB Subnet Group",
"description": "The subnet group associated with the DB cluster"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::RDS::DBCluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DBClusterArn
title: .Properties.DBClusterIdentifier
blueprint: '"rdsDbCluster"'
properties:
activityStreamStatus: .Properties.ActivityStreamStatus
associatedRoles: .Properties.AssociatedRoles
autoMinorVersionUpgrade: .Properties.AutoMinorVersionUpgrade
availabilityZones: .Properties.AvailabilityZones
backupRetentionPeriod: .Properties.BackupRetentionPeriod
clusterCreateTime: .Properties.ClusterCreateTime
copyTagsToSnapshot: .Properties.CopyTagsToSnapshot
crossAccountClone: .Properties.CrossAccountClone
databaseName: .Properties.DatabaseName
dbClusterArn: .Properties.DBClusterArn
dbClusterIdentifier: .Properties.DBClusterIdentifier
dbClusterMembers: .Properties.DBClusterMembers
dbClusterResourceId: .Properties.DbClusterResourceId
deletionProtection: .Properties.DeletionProtection
earliestRestorableTime: .Properties.EarliestRestorableTime
endpoint: .Properties.Endpoint
engine: .Properties.Engine
engineMode: .Properties.EngineMode
engineVersion: .Properties.EngineVersion
globalWriteForwardingStatus: .Properties.GlobalWriteForwardingStatus
httpEndpointEnabled: .Properties.HttpEndpointEnabled
iamDatabaseAuthenticationEnabled: .Properties.IAMDatabaseAuthenticationEnabled
kmsKeyId: .Properties.KmsKeyId
latestRestorableTime: .Properties.LatestRestorableTime
masterUsername: .Properties.MasterUsername
multiAZ: .Properties.MultiAZ
networkType: .Properties.NetworkType
port: .Properties.Port
preferredBackupWindow: .Properties.PreferredBackupWindow
preferredMaintenanceWindow: .Properties.PreferredMaintenanceWindow
readerEndpoint: .Properties.ReaderEndpoint
status: .Properties.Status
storageEncrypted: .Properties.StorageEncrypted
storageType: .Properties.StorageType
tags: .Properties.Tags
vpcSecurityGroups: .Properties.VpcSecurityGroups
dbSubnetGroup: .Properties.DBSubnetGroup
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "lambdaFunction",
"title": "Lambda Function",
"icon": "AWS",
"schema": {
"properties": {
"functionName": {
"type": "string",
"title": "Function Name"
},
"functionArn": {
"type": "string",
"title": "Function ARN"
},
"runtime": {
"type": "string",
"title": "Runtime"
},
"handler": {
"type": "string",
"title": "Handler"
},
"memorySize": {
"type": "number",
"title": "Memory Size"
},
"timeout": {
"type": "number",
"title": "Timeout"
},
"state": {
"type": "string",
"title": "State"
},
"lastModified": {
"type": "string",
"title": "Last Modified"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::Lambda::Function
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.FunctionArn
title: .Properties.FunctionName
blueprint: '"lambdaFunction"'
properties:
functionName: .Properties.FunctionName
functionArn: .Properties.FunctionArn
runtime: .Properties.Runtime
handler: .Properties.Handler
memorySize: .Properties.MemorySize
timeout: .Properties.Timeout
state: .Properties.State
lastModified: .Properties.LastModified
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "awsAccount",
"title": "AWS Account",
"icon": "AWS",
"schema": {
"properties": {},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: AWS::Account::Info
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Id
title: .Properties.Name
blueprint: '"awsAccount"'
```
BlueprintJSON
Create in Port
```
{
"identifier": "mskCluster",
"title": "MSK Cluster",
"icon": "AWS",
"schema": {
"properties": {
"clusterArn": {
"type": "string",
"title": "ARN"
},
"state": {
"type": "string",
"title": "State"
},
"kafkaVersion": {
"type": "string",
"title": "Kafka Version"
},
"numberOfBrokerNodes": {
"type": "number",
"title": "Number of Broker Nodes"
},
"instanceType": {
"type": "string",
"title": "Instance Type"
},
"enhancedMonitoring": {
"type": "string",
"title": "Enhanced Monitoring"
},
"clientAuthentication": {
"type": "object",
"title": "Client Authentication"
},
"encryptionInTransit": {
"type": "string",
"title": "Encryption In Transit"
},
"creationTime": {
"type": "string",
"title": "Creation Time",
"format": "date-time"
},
"tags": {
"type": "object",
"title": "Tags"
}
},
"required": []
},
"calculationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::MSK::Cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ClusterArn
title: .Properties.ClusterName
blueprint: '"mskCluster"'
properties:
clusterArn: .Properties.ClusterArn
state: .Properties.State
kafkaVersion: .Properties.CurrentBrokerSoftwareInfo.KafkaVersion
numberOfBrokerNodes: .Properties.NumberOfBrokerNodes
instanceType: .Properties.BrokerNodeGroupInfo.InstanceType
enhancedMonitoring: .Properties.EnhancedMonitoring
clientAuthentication: .Properties.ClientAuthentication
encryptionInTransit: .Properties.EncryptionInfo.EncryptionInTransit.ClientBroker
creationTime: .Properties.CreationTime
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "mskServerlessCluster",
"title": "MSK Serverless Cluster",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the MSK serverless cluster"
},
"clusterName": {
"type": "string",
"title": "Cluster Name",
"description": "The name of the MSK serverless cluster"
},
"state": {
"type": "string",
"title": "State",
"description": "The current state of the cluster",
"enum": [
"ACTIVE",
"CREATING",
"DELETING",
"FAILED",
"HEALING",
"MAINTENANCE",
"REBOOTING_BROKER",
"UPDATING"
]
},
"creationTime": {
"type": "string",
"title": "Creation Time",
"description": "The date and time when the cluster was created",
"format": "date-time"
},
"currentVersion": {
"type": "string",
"title": "Current Version",
"description": "The current version of the MSK cluster"
},
"vpcConfigs": {
"type": "array",
"title": "VPC Configs",
"description": "The VPC configuration for the serverless cluster",
"items": {
"type": "object"
}
},
"clientAuthentication": {
"type": "object",
"title": "Client Authentication",
"description": "The client authentication configuration for the cluster"
},
"tags": {
"type": "object",
"title": "Tags",
"description": "Tags associated with the cluster"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::MSK::ServerlessCluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ClusterArn
title: .Properties.ClusterName
blueprint: '"mskServerlessCluster"'
properties:
arn: .Properties.ClusterArn
clusterName: .Properties.ClusterName
state: .Properties.State
creationTime: .Properties.CreationTime
currentVersion: .Properties.CurrentVersion
vpcConfigs: .Properties.Serverless.VpcConfigs
clientAuthentication: .Properties.Serverless.ClientAuthentication
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "elasticacheCluster",
"title": "ElastiCache Cluster",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN"
},
"cacheClusterId": {
"type": "string",
"title": "Cluster ID"
},
"cacheClusterStatus": {
"type": "string",
"title": "Status"
},
"cacheNodeType": {
"type": "string",
"title": "Node Type"
},
"engine": {
"type": "string",
"title": "Engine"
},
"engineVersion": {
"type": "string",
"title": "Engine Version"
},
"numCacheNodes": {
"type": "number",
"title": "Number of Nodes"
},
"preferredAvailabilityZone": {
"type": "string",
"title": "Availability Zone"
},
"cacheClusterCreateTime": {
"type": "string",
"title": "Created At",
"format": "date-time"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::ElastiCache::CacheCluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ARN
title: .Properties.CacheClusterId
blueprint: '"elasticacheCluster"'
properties:
arn: .Properties.ARN
cacheClusterId: .Properties.CacheClusterId
cacheClusterStatus: .Properties.CacheClusterStatus
cacheNodeType: .Properties.CacheNodeType
engine: .Properties.Engine
engineVersion: .Properties.EngineVersion
numCacheNodes: .Properties.NumCacheNodes
preferredAvailabilityZone: .Properties.PreferredAvailabilityZone
cacheClusterCreateTime: .Properties.CacheClusterCreateTime
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "memoryDbUser",
"title": "MemoryDB User",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the MemoryDB user"
},
"status": {
"type": "string",
"title": "Status",
"description": "The current status of the user (active, modifying, or deleting)"
},
"accessString": {
"type": "string",
"title": "Access String",
"description": "Access permissions string used for this user account"
},
"aclNames": {
"type": "array",
"title": "ACL Names",
"description": "The names of the Access Control Lists (ACLs) the user belongs to",
"items": {
"type": "string"
}
},
"minimumEngineVersion": {
"type": "string",
"title": "Minimum Engine Version",
"description": "The minimum engine version supported for the user"
},
"authentication": {
"type": "object",
"title": "Authentication",
"description": "The authentication mode for the user"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the MemoryDB user",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::MemoryDB::User
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ARN
title: .Properties.Name
blueprint: '"memoryDbUser"'
properties:
arn: .Properties.ARN
status: .Properties.Status
accessString: .Properties.AccessString
aclNames: .Properties.ACLNames
minimumEngineVersion: .Properties.MinimumEngineVersion
authentication: .Properties.Authentication
tags: .Properties.TagList
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codeBuildProject",
"title": "CodeBuild Project",
"icon": "AWS",
"schema": {
"properties": {
"name": {
"type": "string",
"title": "Project Name",
"description": "The name of the CodeBuild project"
},
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the CodeBuild project"
},
"description": {
"type": "string",
"title": "Description",
"description": "A description of the CodeBuild project"
},
"serviceRole": {
"type": "string",
"title": "Service Role",
"description": "The ARN of the AWS Identity and Access Management (IAM) service role"
},
"timeoutInMinutes": {
"type": "number",
"title": "Timeout (Minutes)",
"description": "How long, in minutes, from 5 to 480, for AWS CodeBuild to wait before timing out any related build"
},
"queuedTimeoutInMinutes": {
"type": "number",
"title": "Queued Timeout (Minutes)",
"description": "The number of minutes a build is allowed to be queued before timing out"
},
"encryptionKey": {
"type": "string",
"title": "Encryption Key",
"description": "The AWS Key Management Service (AWS KMS) customer master key (CMK) to be used for encrypting the build project artifacts"
},
"environment": {
"type": "object",
"title": "Build Environment",
"description": "Information about the build environment for the build project"
},
"source": {
"type": "object",
"title": "Source",
"description": "Information about the build input source code for the build project"
},
"artifacts": {
"type": "object",
"title": "Artifacts",
"description": "Information about the build output artifacts for the build project"
},
"created": {
"type": "string",
"title": "Created",
"description": "When the build project was created",
"format": "date-time"
},
"lastModified": {
"type": "string",
"title": "Last Modified",
"description": "When the build project was last modified",
"format": "date-time"
},
"projectVisibility": {
"type": "string",
"title": "Project Visibility",
"description": "The visibility setting for the project",
"enum": [
"PRIVATE",
"PUBLIC_READ"
]
},
"concurrentBuildLimit": {
"type": "number",
"title": "Concurrent Build Limit",
"description": "The maximum number of concurrent builds that are allowed for this project"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the CodeBuild project",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodeBuild::Project
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Properties.Name
blueprint: '"codeBuildProject"'
properties:
name: .Properties.Name
arn: .Properties.Arn
description: .Properties.Description
serviceRole: .Properties.ServiceRole
timeoutInMinutes: .Properties.TimeoutInMinutes
queuedTimeoutInMinutes: .Properties.QueuedTimeoutInMinutes
encryptionKey: .Properties.EncryptionKey
environment: .Properties.Environment
source: .Properties.Source
artifacts: .Properties.Artifacts
created: .Properties.Created
lastModified: .Properties.LastModified
projectVisibility: .Properties.ProjectVisibility
concurrentBuildLimit: .Properties.ConcurrentBuildLimit
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codeBuildBuildRun",
"title": "CodeBuild Build Run",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the build run"
},
"projectName": {
"type": "string",
"title": "Project Name",
"description": "The name of the CodeBuild project"
},
"buildNumber": {
"type": "number",
"title": "Build Number",
"description": "The build number"
},
"buildStatus": {
"type": "string",
"title": "Build Status",
"description": "The current status of the build",
"enum": [
"SUCCEEDED",
"FAILED",
"FAULT",
"TIMED_OUT",
"IN_PROGRESS",
"STOPPED"
]
},
"currentPhase": {
"type": "string",
"title": "Current Phase",
"description": "The current phase of the build"
},
"startTime": {
"type": "string",
"title": "Start Time",
"description": "The time the build started",
"format": "date-time"
},
"endTime": {
"type": "string",
"title": "End Time",
"description": "The time the build ended",
"format": "date-time"
},
"sourceVersion": {
"type": "string",
"title": "Source Version",
"description": "The version of the source code"
},
"buildComplete": {
"type": "boolean",
"title": "Build Complete",
"description": "Whether the build is complete"
},
"initiator": {
"type": "string",
"title": "Initiator",
"description": "The entity that initiated the build"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodeBuild::BuildRun
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Id
title: .Properties.ProjectName + " - Build " + (.Properties.BuildNumber | tostring)
blueprint: '"codeBuildBuildRun"'
properties:
arn: .Properties.Arn
projectName: .Properties.ProjectName
buildNumber: .Properties.BuildNumber
buildStatus: .Properties.BuildStatus
currentPhase: .Properties.CurrentPhase
startTime: .Properties.StartTime
endTime: .Properties.EndTime
sourceVersion: .Properties.SourceVersion
buildComplete: .Properties.BuildComplete
initiator: .Properties.Initiator
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codeDeployApplication",
"title": "CodeDeploy Application",
"icon": "AWS",
"schema": {
"properties": {
"applicationName": {
"type": "string",
"title": "Application Name"
},
"applicationId": {
"type": "string",
"title": "Application ID"
},
"createTime": {
"type": "string",
"title": "Create Time",
"format": "date-time"
},
"linkedToGitHub": {
"type": "boolean",
"title": "Linked To GitHub"
},
"gitHubAccountName": {
"type": "string",
"title": "GitHub Account Name"
},
"computePlatform": {
"type": "string",
"title": "Compute Platform"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the Application",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodeDeploy::Application
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ApplicationId
title: .Properties.ApplicationName
blueprint: '"codeDeployApplication"'
properties:
applicationName: .Properties.ApplicationName
applicationId: .Properties.ApplicationId
createTime: .Properties.CreateTime
linkedToGitHub: .Properties.LinkedToGitHub
gitHubAccountName: .Properties.GitHubAccountName
computePlatform: .Properties.ComputePlatform
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codedeployDeploymentGroup",
"title": "CodeDeploy Deployment Group",
"icon": "AWS",
"schema": {
"properties": {
"applicationName": {
"type": "string",
"title": "Application Name",
"description": "The CodeDeploy application name"
},
"deploymentGroupId": {
"type": "string",
"title": "Deployment Group ID",
"description": "The deployment group ID"
},
"serviceRoleArn": {
"type": "string",
"title": "Service Role ARN",
"description": "The ARN of the service role for the deployment group"
},
"computePlatform": {
"type": "string",
"title": "Compute Platform",
"description": "The compute platform for the deployment group",
"enum": [
"Server",
"Lambda",
"ECS"
]
},
"deploymentStyle": {
"type": "object",
"title": "Deployment Style",
"description": "Information about the type of deployment"
},
"autoScalingGroups": {
"type": "array",
"title": "Auto Scaling Groups",
"description": "A list of associated Auto Scaling groups",
"items": {
"type": "object"
}
},
"loadBalancerInfo": {
"type": "object",
"title": "Load Balancer Info",
"description": "Information about the load balancer used in the deployment"
},
"outdatedInstancesStrategy": {
"type": "string",
"title": "Outdated Instances Strategy",
"description": "Indicates what happens when new Amazon EC2 instances are launched",
"enum": [
"UPDATE",
"IGNORE"
]
},
"tags": {
"type": "array",
"title": "Tags",
"description": "The metadata tags associated with the deployment group",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodeDeploy::DeploymentGroup
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DeploymentGroupId
title: .Properties.ApplicationName + "/" + .Properties.DeploymentGroupName
blueprint: '"codedeployDeploymentGroup"'
properties:
applicationName: .Properties.ApplicationName
deploymentGroupId: .Properties.DeploymentGroupId
serviceRoleArn: .Properties.ServiceRoleArn
computePlatform: .Properties.ComputePlatform
deploymentStyle: .Properties.DeploymentStyle
autoScalingGroups: .Properties.AutoScalingGroups
loadBalancerInfo: .Properties.LoadBalancerInfo
outdatedInstancesStrategy: .Properties.OutdatedInstancesStrategy
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codeDeployDeployment",
"title": "CodeDeploy Deployment",
"icon": "AWS",
"schema": {
"properties": {
"deploymentId": {
"type": "string",
"title": "Deployment ID",
"description": "The unique ID of the deployment"
},
"applicationName": {
"type": "string",
"title": "Application Name",
"description": "The name of the application"
},
"deploymentGroupName": {
"type": "string",
"title": "Deployment Group",
"description": "The name of the deployment group"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the deployment",
"enum": [
"Created",
"Queued",
"InProgress",
"Succeeded",
"Failed",
"Stopped",
"Ready"
]
},
"creator": {
"type": "string",
"title": "Creator",
"description": "The user who created the deployment"
},
"createTime": {
"type": "string",
"title": "Create Time",
"description": "The time the deployment was created",
"format": "date-time"
},
"startTime": {
"type": "string",
"title": "Start Time",
"description": "The time the deployment started",
"format": "date-time"
},
"completeTime": {
"type": "string",
"title": "Complete Time",
"description": "The time the deployment completed",
"format": "date-time"
},
"description": {
"type": "string",
"title": "Description",
"description": "A comment about the deployment"
},
"deploymentStyle": {
"type": "object",
"title": "Deployment Style",
"description": "Information about the type of deployment"
},
"region": {
"type": "string",
"title": "Region",
"description": "AWS region where the deployment is located"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodeDeploy::Deployment
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DeploymentId
title: .Properties.ApplicationName + "/" + .Properties.DeploymentGroupName + "/" + .Properties.DeploymentId
blueprint: '"codeDeployDeployment"'
properties:
deploymentId: .Properties.DeploymentId
applicationName: .Properties.ApplicationName
deploymentGroupName: .Properties.DeploymentGroupName
status: .Properties.Status
creator: .Properties.Creator
createTime: .Properties.CreateTime
startTime: .Properties.StartTime
completeTime: .Properties.CompleteTime
description: .Properties.Description
deploymentStyle: .Properties.DeploymentStyle
region: .__ExtraContext.Region
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codedeployDeploymentTarget",
"title": "CodeDeploy Deployment Target",
"icon": "AWS",
"schema": {
"properties": {
"deploymentId": {
"type": "string",
"title": "Deployment ID",
"description": "The unique ID of the deployment"
},
"deploymentTargetType": {
"type": "string",
"title": "Deployment Target Type",
"description": "The deployment type that is specific to the deployment's compute platform",
"enum": [
"InstanceTarget",
"LambdaTarget",
"ECSTarget",
"CloudFormationTarget"
]
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodeDeploy::DeploymentTarget
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DeploymentId + "/" + .Properties.TargetId
title: .Properties.DeploymentId + "/" + .Properties.TargetId
blueprint: '"codedeployDeploymentTarget"'
properties:
deploymentId: .Properties.DeploymentId
deploymentTargetType: .Properties.DeploymentTargetType
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codePipeline",
"title": "CodePipeline Pipeline",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the pipeline"
},
"roleArn": {
"type": "string",
"title": "Role ARN",
"description": "The service role ARN for the pipeline"
},
"executionMode": {
"type": "string",
"title": "Execution Mode",
"description": "The execution mode of the pipeline"
},
"pipelineType": {
"type": "string",
"title": "Pipeline Type",
"description": "The type of the pipeline"
},
"version": {
"type": "number",
"title": "Version",
"description": "The version number of the pipeline"
},
"stages": {
"type": "array",
"title": "Stages",
"description": "The stages of the pipeline",
"items": {
"type": "object"
}
},
"created": {
"type": "string",
"title": "Created",
"description": "The date when the pipeline was created",
"format": "date-time"
},
"updated": {
"type": "string",
"title": "Updated",
"description": "The date when the pipeline was last updated",
"format": "date-time"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the pipeline",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodePipeline::Pipeline
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.PipelineArn
title: .Properties.Name
blueprint: '"codePipeline"'
properties:
arn: .Properties.PipelineArn
roleArn: .Properties.RoleArn
executionMode: .Properties.ExecutionMode
pipelineType: .Properties.PipelineType
version: .Properties.Version
stages: .Properties.Stages
created: .Properties.Created
updated: .Properties.Updated
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codePipelineStage",
"title": "CodePipeline Stage",
"icon": "AWS",
"schema": {
"properties": {
"pipelineName": {
"type": "string",
"title": "Pipeline Name",
"description": "The name of the CodePipeline pipeline this stage belongs to"
},
"pipelineArn": {
"type": "string",
"title": "Pipeline ARN",
"description": "The Amazon Resource Name (ARN) of the pipeline"
},
"actions": {
"type": "array",
"title": "Actions",
"description": "The list of actions that are part of this stage",
"items": {
"type": "object"
}
},
"name": {
"type": "string",
"title": "Name",
"description": "The name of the stage in the pipeline"
},
"order": {
"type": "number",
"title": "Order",
"description": "The sequential order of the stage within the pipeline"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodePipeline::Stage
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.Properties.PipelineArn + "/" + .Properties.Name)
title: (.Properties.PipelineName + "/" + .Properties.Name)
blueprint: '"codePipelineStage"'
properties:
pipelineName: .Properties.PipelineName
pipelineArn: .Properties.PipelineArn
name: .Properties.Name
order: .Properties.Order
actions: .Properties.Actions
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codePipelineAction",
"title": "CodePipeline Action",
"icon": "AWS",
"schema": {
"properties": {
"name": {
"type": "string",
"title": "Name",
"description": "The name of the action"
},
"provider": {
"type": "string",
"title": "Provider",
"description": "The action provider (e.g., S3, CodeBuild, CodeDeploy)"
},
"category": {
"type": "string",
"title": "Category",
"description": "The action category (Source, Build, Deploy, etc.)"
},
"owner": {
"type": "string",
"title": "Owner",
"description": "The action owner (AWS, ThirdParty, Custom)"
},
"version": {
"type": "string",
"title": "Version",
"description": "The action version"
},
"runOrder": {
"type": "number",
"title": "Run Order",
"description": "The order in which the action runs"
},
"configuration": {
"type": "object",
"title": "Configuration",
"description": "Action configuration parameters"
},
"inputArtifacts": {
"type": "array",
"title": "Input Artifacts",
"description": "Input artifacts for the action",
"items": {
"type": "object"
}
},
"outputArtifacts": {
"type": "array",
"title": "Output Artifacts",
"description": "Output artifacts produced by the action",
"items": {
"type": "object"
}
},
"roleArn": {
"type": "string",
"title": "Role ARN",
"description": "The ARN of the role used for the action"
},
"region": {
"type": "string",
"title": "Region",
"description": "The region where the action runs"
},
"pipelineName": {
"type": "string",
"title": "Pipeline Name",
"description": "The name of the pipeline containing this action"
},
"stageName": {
"type": "string",
"title": "Stage Name",
"description": "The name of the stage containing this action"
},
"pipelineArn": {
"type": "string",
"title": "Pipeline ARN",
"description": "The ARN of the pipeline"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodePipeline::Action
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.PipelineArn + "/" + .Properties.StageName + "/" + .Properties.Name
title: .Properties.PipelineName + "/" + .Properties.StageName + "/" + .Properties.Name
blueprint: '"codePipelineAction"'
properties:
name: .Properties.Name
provider: .Properties.ActionTypeId.Provider
category: .Properties.ActionTypeId.Category
owner: .Properties.ActionTypeId.Owner
version: .Properties.ActionTypeId.Version
runOrder: .Properties.RunOrder
configuration: .Properties.Configuration
inputArtifacts: .Properties.InputArtifacts
outputArtifacts: .Properties.OutputArtifacts
roleArn: .Properties.RoleArn
region: .Properties.Region
pipelineName: .Properties.PipelineName
stageName: .Properties.StageName
pipelineArn: .Properties.PipelineArn
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codePipelinePipelineExecution",
"title": "CodePipeline Pipeline Execution",
"icon": "AWS",
"schema": {
"properties": {
"pipelineName": {
"type": "string",
"title": "Pipeline Name",
"description": "The name of the pipeline"
},
"pipelineVersion": {
"type": "number",
"title": "Pipeline Version",
"description": "The version of the pipeline definition"
},
"pipelineExecutionId": {
"type": "string",
"title": "Execution ID",
"description": "The unique identifier for the pipeline execution"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the pipeline execution",
"enum": [
"InProgress",
"Stopped",
"Stopping",
"Succeeded",
"Superseded",
"Failed"
]
},
"statusSummary": {
"type": "string",
"title": "Status Summary",
"description": "A summary of the status of the pipeline execution"
},
"executionMode": {
"type": "string",
"title": "Execution Mode",
"description": "The execution mode for this pipeline execution",
"enum": [
"QUEUED",
"SUPERSEDED",
"PARALLEL"
]
},
"trigger": {
"type": "object",
"title": "Trigger",
"description": "The trigger that caused the pipeline execution"
},
"artifactRevisions": {
"type": "array",
"title": "Artifact Revisions",
"description": "A list of source code revisions for the pipeline execution",
"items": {
"type": "object"
}
},
"variables": {
"type": "array",
"items": {
"type": "object"
},
"title": "Variables",
"description": "Variables defined for the pipeline execution"
},
"lastUpdateTime": {
"type": "string",
"format": "date-time",
"title": "Last Update Time",
"description": "The time when the pipeline execution was last updated",
"dateFormat": "relative"
},
"startTime": {
"type": "string",
"format": "date-time",
"title": "StartTime",
"description": "The time when the pipeline execution started",
"dateFormat": "relative"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodePipeline::PipelineExecution
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.PipelineExecutionId
title: .Properties.PipelineName + "/" + .Properties.PipelineExecutionId
blueprint: '"codePipelinePipelineExecution"'
properties:
pipelineName: .Properties.PipelineName
pipelineVersion: .Properties.PipelineVersion
pipelineExecutionId: .Properties.PipelineExecutionId
status: .Properties.Status
statusSummary: .Properties.StatusSummary
executionMode: .Properties.ExecutionMode
trigger: .Properties.Trigger
artifactRevisions: .Properties.ArtifactRevisions
variables: .Properties.Variables
startTime: .Properties.StartTime
lastUpdateTime: .Properties.LastUpdateTime
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "codePipelineActionExecution",
"title": "CodePipeline Action Execution",
"icon": "AWS",
"schema": {
"properties": {
"actionExecutionId": {
"type": "string",
"title": "Action Execution ID",
"description": "The unique ID of the action execution"
},
"actionName": {
"type": "string",
"title": "Action Name",
"description": "The name of the action"
},
"stageName": {
"type": "string",
"title": "Stage Name",
"description": "The name of the stage containing the action"
},
"pipelineExecutionId": {
"type": "string",
"title": "Pipeline Execution ID",
"description": "The pipeline execution ID associated with this action execution"
},
"pipelineVersion": {
"type": "number",
"title": "Pipeline Version",
"description": "The version of the pipeline when the action was executed"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the action execution",
"enum": [
"InProgress",
"Abandoned",
"Succeeded",
"Failed"
]
},
"startTime": {
"type": "string",
"title": "Start Time",
"description": "The start time of the action execution",
"format": "date-time"
},
"lastUpdateTime": {
"type": "string",
"title": "Last Update Time",
"description": "The last update time of the action execution",
"format": "date-time"
},
"input": {
"type": "object",
"title": "Input",
"description": "Input details for the action execution"
},
"output": {
"type": "object",
"title": "Output",
"description": "Output details for the action execution"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::CodePipeline::ActionExecution
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ActionExecutionId
title: .Properties.ActionName + "/" + .Properties.ActionExecutionId
blueprint: '"codePipelineActionExecution"'
properties:
actionExecutionId: .Properties.ActionExecutionId
actionName: .Properties.ActionName
stageName: .Properties.StageName
pipelineExecutionId: .Properties.PipelineExecutionId
pipelineVersion: .Properties.PipelineVersion
status: .Properties.Status
startTime: .Properties.StartTime
lastUpdateTime: .Properties.LastUpdateTime
input: .Properties.Input
output: .Properties.Output
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "dynamodbTable",
"title": "DynamoDB Table",
"description": "This blueprint represents an AWS DynamoDB table in our software catalog",
"icon": "AmazonDynamoDB",
"schema": {
"properties": {
"tableArn": {
"type": "string",
"title": "Table ARN",
"description": "The Amazon Resource Name (ARN) of the DynamoDB table"
},
"tableStatus": {
"type": "string",
"title": "Status",
"description": "The current status of the table"
},
"billingMode": {
"type": "string",
"title": "Billing mode",
"description": "The billing mode of the table (PROVISIONED or PAY_PER_REQUEST)"
},
"itemCount": {
"type": "number",
"title": "Item count",
"description": "The number of items in the table"
},
"tableSizeBytes": {
"type": "number",
"title": "Table size (bytes)",
"description": "The total size of the table in bytes"
},
"creationDateTime": {
"type": "string",
"title": "Creation date",
"description": "The date and time when the table was created",
"format": "date-time"
},
"deletionProtectionEnabled": {
"type": "boolean",
"title": "Deletion protection",
"description": "Whether deletion protection is enabled for the table"
},
"encryptionType": {
"type": "string",
"title": "Encryption type",
"description": "The type of server-side encryption (AES256 or KMS)"
},
"region": {
"type": "string",
"title": "Region",
"description": "The AWS region where the table resides"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the table",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
Mapping configurationYAML
```
resources:
- kind: AWS::DynamoDB::Table
selector:
query: 'true'
includeActions:
- GetTableTagsAction
port:
entity:
mappings:
identifier: .Properties.TableArn
title: .Properties.TableName
blueprint: '"dynamodbTable"'
properties:
tableArn: .Properties.TableArn
tableStatus: .Properties.TableStatus
billingMode: .Properties.BillingModeSummary.BillingMode
itemCount: .Properties.ItemCount
tableSizeBytes: .Properties.TableSizeBytes
creationDateTime: .Properties.CreationDateTime
deletionProtectionEnabled: .Properties.DeletionProtectionEnabled
encryptionType: .Properties.SSEDescription.SSEType
region: .__ExtraContext.Region
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "sesEmailIdentity",
"title": "SES Email Identity",
"icon": "AWS",
"schema": {
"properties": {
"identityType": {
"type": "string",
"title": "Identity Type",
"description": "The type of the email identity (EMAIL_ADDRESS or DOMAIN)"
},
"verifiedForSendingStatus": {
"type": "boolean",
"title": "Verified For Sending Status",
"description": "Indicates whether the identity is verified for sending email"
},
"dkimEnabled": {
"type": "boolean",
"title": "DKIM Enabled",
"description": "Indicates whether DKIM signing is enabled for the identity"
},
"verificationStatus": {
"type": "string",
"title": "Verification Status",
"description": "The verification status of the email identity"
},
"configurationSetName": {
"type": "string",
"title": "Configuration Set Name",
"description": "The name of the configuration set associated with the email identity"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the email identity",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::SES::EmailIdentity
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.IdentityName
title: .Properties.IdentityName
blueprint: '"sesEmailIdentity"'
properties:
identityType: .Properties.IdentityType
verifiedForSendingStatus: .Properties.VerifiedForSendingStatus
dkimEnabled: .Properties.DkimAttributes.SigningEnabled
verificationStatus: .Properties.VerificationStatus
configurationSetName: .Properties.ConfigurationSetName
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "sesConfigurationSet",
"title": "SES Configuration Set",
"icon": "AWS",
"schema": {
"properties": {
"sendingEnabled": {
"type": "boolean",
"title": "Sending Enabled",
"description": "Indicates whether email sending is enabled for the configuration set"
},
"reputationMetricsEnabled": {
"type": "boolean",
"title": "Reputation Metrics Enabled",
"description": "Indicates whether reputation metrics tracking is enabled"
},
"tlsPolicy": {
"type": "string",
"title": "TLS Policy",
"description": "The TLS policy that applies to the configuration set (REQUIRE or OPTIONAL)"
},
"trackingDomain": {
"type": "string",
"title": "Tracking Domain",
"description": "The domain used to track open and click events"
},
"suppressionList": {
"type": "array",
"title": "Suppression List",
"description": "The reasons that email addresses are automatically added to the suppression list",
"items": {
"type": "string"
}
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the configuration set",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::SES::ConfigurationSet
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ConfigurationSetName
title: .Properties.ConfigurationSetName
blueprint: '"sesConfigurationSet"'
properties:
sendingEnabled: .Properties.SendingOptions.SendingEnabled
reputationMetricsEnabled: .Properties.ReputationOptions.ReputationMetricsEnabled
tlsPolicy: .Properties.DeliveryOptions.TlsPolicy
trackingDomain: .Properties.TrackingOptions.CustomRedirectDomain
suppressionList: .Properties.SuppressionOptions.SuppressedReasons
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
## Resource and property reference[](#resource-and-property-reference "Direct link to Resource and property reference")
Refer to the [resource and property reference](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/.md) page for details on available AWS resources, their properties, and mapping examples.
---
# AWS resource and property reference
Welcome to the reference guide for AWS resource, actions and properties, as supported by AWS CloudFormation and used in Port integrations.
## Supported resource types[](#supported-resource-types "Direct link to Supported resource types")
Explore detailed documentation for each AWS resource and action available for integration. For each resource type, you will find information about supported actions, required permissions, and usage best practices.
Resource type identifiers follow a standardized format, allowing you to easily recognize and reference each AWS entity:
```
service-provider::service-name::data-type-name
```
For example, an EC2 instance is identified as:
```
AWS::EC2::Instance
```
Refer to the sidebar or the list below to navigate to individual resource reference pages where you will find actionable integration details, sample configurations, and official AWS documentation links.
* [Amazon Simple Queue Service](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-simple-queue-service/.md)
* [Amazon Simple Storage Service](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-simple-storage-service/.md)
* [Amazon Elastic Compute Cloud](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elastic-compute-cloud/.md)
* [Amazon Elastic Container Service](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elastic-container-service/.md)
* [Amazon Elastic Container Registry](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elastic-container-registry/.md)
* [Amazon Elastic Kubernetes Service](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elastic-kubernetes-service/.md)
* [Amazon Relational Database Service](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-relational-database-service/.md)
* [AWS Lambda](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-lambda/.md)
* [AWS Account](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-account/.md)
* [AWS Organizations](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-organizations/.md)
* [Amazon Managed Streaming for Apache Kafka (MSK)](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-managed-streaming-for-apache-kafka/.md)
* [Amazon ElastiCache](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-elasticache/.md)
* [Amazon MemoryDB](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-memorydb/.md)
* [AWS CodeBuild](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-codebuild/.md)
* [AWS CodeDeploy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-codedeploy/.md)
* [AWS CodePipeline](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-codepipeline/.md)
* [Amazon DynamoDB](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/amazon-dynamodb/.md)
More resource types coming soon
We're continuously expanding support for additional AWS resource types to ensure comprehensive coverage of your AWS infrastructure.
If you need support for a specific AWS resource or action that isn’t yet available, please consider opening a feature request or reach out to us through chat, Slack, or our [Support Portal](http://support.port.io/).
Your feedback helps us prioritize what to build next.
## Actions[](#actions "Direct link to Actions")
**Actions** define the set of API operations performed to discover and fetch resources within your AWS environment. These actions are mapped directly to AWS API calls—for example, `DescribeInstances` for EC2 or `ListBuckets` for S3—which determine the resource data that Port can ingest and keep up to date.
Ensure required AWS permissions are granted
Each action requires specific AWS IAM permissions. Your integration’s AWS credentials must have these permissions; otherwise, the action will not succeed and its data will not be available in Port.
### How Actions Map to AWS Operations[](#how-actions-map-to-aws-operations "Direct link to How Actions Map to AWS Operations")
Each Port-supported resource type comes with a set of actions that align with AWS's official API operations. For instance:
* For **Amazon S3 Buckets**, the `ListBucketsAction` leverages the [ListBuckets API](https://docs.aws.amazon.com/AmazonS3/latest/API/API_ListBuckets.html), and additional actions like `GetBucketTaggingAction` or `GetBucketEncryptionAction` invoke their respective AWS endpoints.
* For **EC2 Instances**, `DescribeInstancesAction` maps to the [DescribeInstances API](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeInstances.html) and brings in detailed instance configuration.
These mappings ensure that only the properties available from the selected AWS actions are ingested into your Port catalog.
### Enabling and customizing actions[](#enabling-and-customizing-actions "Direct link to Enabling and customizing actions")
With Port, you have full control over which AWS resource properties are discovered and ingested into your catalog by specifying the actions to use for each resource type. Actions define what data you collect and the AWS permissions required.
* **Default Actions**: These are enabled automatically, ensuring basic discovery such as listing all S3 buckets or EC2 instances without additional configuration.
* **Optional Actions**: Enable these to collect more detailed properties for your AWS resources. You must explicitly add optional actions in your integration configuration for Port to use them.
To collect additional properties from AWS resources, add the optional actions you need to the `includeActions` field of your configuration. For example, to include status details from EC2 instances by enabling the `DescribeInstanceStatusAction`, add the following:
```
- kind: AWS::EC2::Instance
selector:
query: 'true'
includeActions:
- DescribeInstanceStatusAction
```
In this case, Port will enrich your catalog by fetching all properties returned by the [DescribeInstanceStatus API](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeInstanceStatus.html) for every EC2 instance.
Maximum actions per resource
You can include a **maximum of 3 optional actions per resource kind** (default actions excluded). To use more than 3 optional actions, configure multiple resource kinds in your integration.
### Querying resources from specific regions[](#querying-resources-from-specific-regions "Direct link to Querying resources from specific regions")
You can control which AWS regions Port queries for resources using the `regionPolicy` selector. This allows you to include or exclude specific regions per resource type.
* allow: List of regions explicitly permitted for querying
* deny: List of regions explicitly excluded from querying
#### How `regionPolicy` works[](#how-regionpolicy-works "Direct link to how-regionpolicy-works")
1. If both lists are empty, all regions are allowed.
2. If a region is listed in `deny`, it is excluded unless explicitly allowed.
3. If a region is listed in `allow`, it is included for querying.
4. If a region is present in both lists, it is excluded.
5. If only `deny` is specified, only the regions in `deny` are excluded.
6. If only `allow` is specified, only the regions in `allow` are included.
#### Example configuration[](#example-configuration "Direct link to Example configuration")
```
resources:
- kind: AWS::Lambda::Function
selector:
query: 'true'
regionPolicy:
allow: ["us-east-1", "eu-west-1"]
deny: ["us-west-2"]
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Properties.FunctionName
blueprint: '"lambda"'
properties:
region: .__Region
description: .Properties.Description
arn: .Properties.Arn
relations:
account: .__ExtraContext.AccountId
```
In this example, resources in `us-east-1` and `eu-west-1` are allowed, while `us-west-2` is denied.
Refer to the individual resource documentation pages for a table of actions, their AWS mapping, and necessary IAM permissions.
---
# Amazon DynamoDB
## AWS::DynamoDB::Table[](#awsdynamodbtable "Direct link to AWS::DynamoDB::Table")
The following example demonstrates how to ingest your AWS DynamoDB tables to Port.
#### DynamoDB Table supported actions[](#dynamodb-table-supported-actions "Direct link to DynamoDB Table supported actions")
The table below summarizes the available actions for ingesting Amazon DynamoDB Table resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------- | -------- | ------------------------------------ |
| [ListTablesAction](https://docs.aws.amazon.com/amazondynamodb/latest/APIReference/API_ListTables.html) | Discover DynamoDB tables in each region. | Default | `dynamodb:ListTables` |
| [GetTableDetailsAction](https://docs.aws.amazon.com/amazondynamodb/latest/APIReference/API_DescribeTable.html) | Retrieve detailed table configuration including status, billing mode, size, item count, encryption, and deletion protection. | Default | `dynamodb:DescribeTable` |
| [GetTableTagsAction](https://docs.aws.amazon.com/amazondynamodb/latest/APIReference/API_ListTagsOfResource.html) | Retrieve tags associated with each table. Required to populate the `tags` property. | Optional | `dynamodb:ListTagsOfResource` |
| [GetTableBackupStatusAction](https://docs.aws.amazon.com/amazondynamodb/latest/APIReference/API_DescribeContinuousBackups.html) | Retrieve continuous backup and point-in-time recovery status for each table. | Optional | `dynamodb:DescribeContinuousBackups` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**DynamoDB Table blueprint (click to expand)**
Create in Port
```
{
"identifier": "dynamodbTable",
"title": "DynamoDB Table",
"description": "This blueprint represents an AWS DynamoDB table in our software catalog",
"icon": "AmazonDynamoDB",
"schema": {
"properties": {
"tableArn": {
"type": "string",
"title": "Table ARN",
"description": "The Amazon Resource Name (ARN) of the DynamoDB table"
},
"tableStatus": {
"type": "string",
"title": "Status",
"description": "The current status of the table"
},
"billingMode": {
"type": "string",
"title": "Billing mode",
"description": "The billing mode of the table (PROVISIONED or PAY_PER_REQUEST)"
},
"itemCount": {
"type": "number",
"title": "Item count",
"description": "The number of items in the table"
},
"tableSizeBytes": {
"type": "number",
"title": "Table size (bytes)",
"description": "The total size of the table in bytes"
},
"creationDateTime": {
"type": "string",
"title": "Creation date",
"description": "The date and time when the table was created",
"format": "date-time"
},
"deletionProtectionEnabled": {
"type": "boolean",
"title": "Deletion protection",
"description": "Whether deletion protection is enabled for the table"
},
"encryptionType": {
"type": "string",
"title": "Encryption type",
"description": "The type of server-side encryption (AES256 or KMS)"
},
"region": {
"type": "string",
"title": "Region",
"description": "The AWS region where the table resides"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the table",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
**DynamoDB Table mapping configuration (click to expand)**
```
resources:
- kind: AWS::DynamoDB::Table
selector:
query: 'true'
includeActions:
- GetTableTagsAction
port:
entity:
mappings:
identifier: .Properties.TableArn
title: .Properties.TableName
blueprint: '"dynamodbTable"'
properties:
tableArn: .Properties.TableArn
tableStatus: .Properties.TableStatus
billingMode: .Properties.BillingModeSummary.BillingMode
itemCount: .Properties.ItemCount
tableSizeBytes: .Properties.TableSizeBytes
creationDateTime: .Properties.CreationDateTime
deletionProtectionEnabled: .Properties.DeletionProtectionEnabled
encryptionType: .Properties.SSEDescription.SSEType
region: .__ExtraContext.Region
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about DynamoDB table properties, refer to the [AWS DynamoDB API documentation](https://docs.aws.amazon.com/amazondynamodb/latest/APIReference/Welcome.html).
---
# Amazon Elastic Compute Cloud (EC2)
## AWS::EC2::Instance[](#awsec2instance "Direct link to AWS::EC2::Instance")
The following example demonstrates how to ingest your AWS EC2 instances to Port.
#### EC2 Instance supported actions[](#ec2-instance-supported-actions "Direct link to EC2 Instance supported actions")
The table below summarizes the available actions for ingesting Amazon EC2 Instance resources in Port:
| Action | Description | Type | Required AWS Permission |
| ----------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------- | -------- | ---------------------------- |
| [DescribeInstancesAction](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeInstances.html) | Discover EC2 instances and retrieve detailed configuration data. | Default | `ec2:DescribeInstances` |
| [GetInstanceStatusAction](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeInstanceStatus.html) | Retrieve instance status information. | Optional | `ec2:DescribeInstanceStatus` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**EC2 Instance blueprint (click to expand)**
Create in Port
```
{
"identifier": "ec2Instance",
"description": "This blueprint represents an AWS EC2 instance in our software catalog",
"title": "EC2 instance",
"icon": "AWS",
"schema": {
"properties": {
"instanceArn": {
"type": "string",
"title": "Instance ARN"
},
"instanceId": {
"type": "string",
"title": "Instance ID"
},
"instanceType": {
"type": "string",
"title": "Instance type"
},
"availabilityZone": {
"type": "string",
"title": "Availability zone"
},
"tags": {
"type": "array",
"title": "Tags",
"items": {
"type": "object",
"properties": {
"Key": {
"type": "string"
},
"Value": {
"type": "string"
}
}
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
**EC2 Instance mapping configuration (click to expand)**
```
resources:
- kind: AWS::EC2::Instance
selector:
query: 'true'
includeActions:
# Optional: Include up to 3 additional actions for more properties
# Choose based on which properties you need most
# - GetInstanceStatusAction
port:
entity:
mappings:
identifier: .Properties.InstanceId
title: .Properties.InstanceId
blueprint: '"ec2Instance"'
properties:
instanceArn: .Properties.InstanceArn
instanceId: .Properties.InstanceId
instanceType: .Properties.InstanceType
availabilityZone: .Properties.AvailabilityZone
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about EC2 instance properties, refer to the [AWS EC2 API documentation](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/Welcome.html).
## AWS::EC2::Volume[](#awsec2volume "Direct link to AWS::EC2::Volume")
The following example demonstrates how to ingest your AWS EBS (Elastic Block Store) volumes to Port.
#### EBS Volume supported actions[](#ebs-volume-supported-actions "Direct link to EBS Volume supported actions")
The table below summarizes the available actions for ingesting Amazon EBS Volume resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------ | -------- | ----------------------------- |
| [DescribeVolumesAction](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeVolumes.html) | Discover EBS volumes and retrieve core configuration data such as type, size, IOPS, throughput, availability zone, state, encryption status, and tags. | Default | `ec2:DescribeVolumes` |
| [DescribeVolumeAttributeAction](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeVolumeAttribute.html) | Retrieve the `AutoEnableIO` attribute for each volume. Required to populate the `autoEnableIO` property. | Optional | `ec2:DescribeVolumeAttribute` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**EBS Volume blueprint (click to expand)**
Create in Port
```
{
"identifier": "ebsVolume",
"title": "EBS Volume",
"icon": "AWS",
"schema": {
"properties": {
"volumeType": {
"type": "string",
"title": "Volume Type",
"description": "The volume type (gp2, gp3, io1, io2, st1, sc1, standard)"
},
"size": {
"type": "number",
"title": "Size (GiB)",
"description": "The size of the volume in GiB"
},
"iops": {
"type": "number",
"title": "IOPS",
"description": "The number of I/O operations per second"
},
"throughput": {
"type": "number",
"title": "Throughput (MiB/s)",
"description": "The throughput provisioned for the volume in MiB/s"
},
"availabilityZone": {
"type": "string",
"title": "Availability Zone",
"description": "The Availability Zone in which the volume resides"
},
"state": {
"type": "string",
"title": "State",
"description": "The current state of the volume",
"enum": [
"creating",
"available",
"in-use",
"deleting",
"deleted",
"error"
]
},
"creationDate": {
"type": "string",
"title": "Creation Date",
"description": "The date and time the volume was created",
"format": "date-time"
},
"encrypted": {
"type": "boolean",
"title": "Encrypted",
"description": "Indicates whether the volume is encrypted"
},
"autoEnableIO": {
"type": "boolean",
"title": "Auto Enable IO",
"description": "Indicates whether the volume is auto-enabled for I/O operations"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the volume",
"items": {
"type": "object"
}
},
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the volume"
}
},
"required": []
},
"calculationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**EBS Volume mapping configuration (click to expand)**
```
resources:
- kind: AWS::EC2::Volume
selector:
query: 'true'
includeActions:
# Optional: Include up to 3 additional actions for more properties
# Choose based on which properties you need most
# - DescribeVolumeAttributeAction
port:
entity:
mappings:
identifier: .Properties.VolumeId
title: '(.Properties.Tags // [] | map(select(.Key == "Name")) | first | .Value) // .Properties.VolumeId'
blueprint: '"ebsVolume"'
properties:
volumeType: .Properties.VolumeType
size: .Properties.Size
iops: .Properties.Iops
throughput: .Properties.Throughput
availabilityZone: .Properties.AvailabilityZone
state: .Properties.State
creationDate: .Properties.CreateTime
encrypted: .Properties.Encrypted
autoEnableIO: .Properties.AutoEnableIO
tags: .Properties.Tags
arn: '"arn:aws:ec2:" + .__ExtraContext.Region + ":" + .__ExtraContext.AccountId + ":volume/" + .Properties.VolumeId'
relations:
account: .__ExtraContext.AccountId
```
For more details about EBS volume properties, refer to the [AWS EC2 API documentation](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/Welcome.html).
---
# Amazon Elastic Container Registry (ECR)
## AWS::ECR::Repository[](#awsecrrepository "Direct link to AWS::ECR::Repository")
The following example demonstrates how to ingest your AWS ECR repositories to Port.
#### ECR Repository supported actions[](#ecr-repository-supported-actions "Direct link to ECR Repository supported actions")
The table below summarizes the available actions for ingesting Amazon ECR Repository resources in Port:
| Action | Description | Type | Required AWS Permission |
| --------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------- | -------- | -------------------------- |
| [DescribeRepositoriesAction](https://docs.aws.amazon.com/AmazonECR/latest/APIReference/API_DescribeRepositories.html) | Discover ECR repositories and retrieve detailed configuration data. | Default | `ecr:DescribeRepositories` |
| [GetRepositoryPolicyAction](https://docs.aws.amazon.com/AmazonECR/latest/APIReference/API_GetRepositoryPolicy.html) | Retrieve the repository policy for ECR repositories. | Optional | `ecr:GetRepositoryPolicy` |
| [GetLifecyclePolicyAction](https://docs.aws.amazon.com/AmazonECR/latest/APIReference/API_GetLifecyclePolicy.html) | Retrieve the lifecycle policy for ECR repositories. | Optional | `ecr:GetLifecyclePolicy` |
| [ListTagsForResourceAction](https://docs.aws.amazon.com/AmazonECR/latest/APIReference/API_ListTagsForResource.html) | Retrieve tags associated with ECR repositories. | Optional | `ecr:ListTagsForResource` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**ECR Repository blueprint (click to expand)**
Create in Port
```
{
"identifier": "ecrRepository",
"description": "This blueprint represents an AWS ECR repository in our software catalog",
"title": "ECR Repository",
"icon": "AWS",
"schema": {
"properties": {
"repositoryUri": {
"type": "string",
"title": "Repository URI"
},
"registryId": {
"type": "string",
"title": "Registry ID"
},
"createdAt": {
"type": "string",
"title": "Created At"
},
"imageTagMutability": {
"type": "string",
"title": "Image Tag Mutability"
},
"imageScanningConfiguration": {
"type": "object",
"title": "Image Scanning Configuration"
},
"encryptionConfiguration": {
"type": "object",
"title": "Encryption Configuration"
},
"lifecyclePolicy": {
"type": "object",
"title": "Lifecycle Policy"
},
"repositoryPolicyText": {
"type": "string",
"title": "Repository Policy Text"
},
"tags": {
"type": "array",
"title": "Tags",
"items": {
"type": "object",
"properties": {
"Key": {
"type": "string"
},
"Value": {
"type": "string"
}
}
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
**ECR Repository mapping configuration (click to expand)**
```
resources:
- kind: AWS::ECR::Repository
selector:
query: 'true'
includeActions:
# Optional: Include additional actions for more properties
# - GetRepositoryPolicyAction
# - GetLifecyclePolicyAction
# - ListTagsForResourceAction
port:
entity:
mappings:
identifier: .Properties.RepositoryArn
title: .Properties.RepositoryName
blueprint: '"ecrRepository"'
properties:
repositoryUri: .Properties.RepositoryUri
registryId: .Properties.RegistryId
createdAt: .Properties.CreatedAt
imageTagMutability: .Properties.ImageTagMutability
imageScanningConfiguration: .Properties.ImageScanningConfiguration
encryptionConfiguration: .Properties.EncryptionConfiguration
lifecyclePolicy: .Properties.LifecyclePolicy
repositoryPolicyText: .Properties.RepositoryPolicyText
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
#### Example response[](#example-response "Direct link to Example response")
The following example shows the structure of the response data that Port processes for an ECR repository.
**ECR Repository response example (click to expand)**
```
{
"Type": "AWS::ECR::Repository",
"Properties": {
"RepositoryName": "testing-actions",
"RepositoryArn": "arn:aws:ecr:us-west-2:123456789012:repository/testing-actions",
"RepositoryUri": "123456789012.dkr.ecr.us-west-2.amazonaws.com/testing-actions",
"RegistryId": "123456789012",
"CreatedAt": "2024-05-14T12:12:40.109000+03:00",
"ImageTagMutability": "MUTABLE",
"ImageScanningConfiguration": {
"scanOnPush": false
},
"EncryptionConfiguration": {
"encryptionType": "AES256"
},
"RepositoryPolicyText": "{\n \"Version\" : \"2012-10-17\",\n \"Statement\" : [ {\n \"Sid\" : \"new statement\",\n \"Effect\" : \"Allow\",\n \"Principal\" : {\n \"AWS\" : \"arn:aws:iam::123456789012:role/admin-access\"\n },\n \"Action\" : \"ecr:DescribeRepositories\"\n } ]\n}",
"LifecyclePolicy": {
"registryId": "123456789012",
"repositoryName": "testing-actions",
"lifecyclePolicyText": "{\"rules\":[{\"rulePriority\":1,\"selection\":{\"tagStatus\":\"tagged\",\"tagPatternList\":[\"testimagetag\"],\"countType\":\"sinceImagePushed\",\"countUnit\":\"days\",\"countNumber\":1},\"action\":{\"type\":\"expire\"}}]}",
"lastEvaluatedAt": "1970-01-01T03:00:00+03:00"
},
"Tags": [
{
"Key": "Environment",
"Value": "Production"
},
{
"Key": "Team",
"Value": "DevOps"
}
]
},
"__ExtraContext": {
"AccountId": "123456789012",
"Region": "us-west-2"
}
}
```
For more details about ECR repository properties, refer to the [AWS ECR API documentation](https://docs.aws.amazon.com/AmazonECR/latest/APIReference/Welcome.html).
---
# Amazon Elastic Container Service (ECS)
## AWS::ECS::Cluster[](#awsecscluster "Direct link to AWS::ECS::Cluster")
The following example demonstrates how to ingest your AWS ECS clusters to Port.
#### ECS Cluster supported actions[](#ecs-cluster-supported-actions "Direct link to ECS Cluster supported actions")
The table below summarizes the available actions for ingesting Amazon ECS Cluster resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------- | ------- | ------------------------------------------ |
| [DescribeClustersAction](https://docs.aws.amazon.com/AmazonECS/latest/APIReference/API_DescribeClusters.html) | Discover ECS clusters and retrieve detailed configuration data. | Default | `ecs:ListClusters`, `ecs:DescribeClusters` |
All properties available by default
ECS clusters expose their key properties via the default DescribeClusters action.
You can use the following Port blueprint definitions and integration configuration:
**ECS Cluster blueprint (click to expand)**
Create in Port
```
{
"identifier": "ecsCluster",
"description": "This blueprint represents an AWS ECS cluster in our software catalog",
"title": "ECS cluster",
"icon": "AWS",
"schema": {
"properties": {
"status": {
"type": "string",
"title": "Status"
},
"runningTasksCount": {
"type": "number",
"title": "Running tasks count"
},
"activeServicesCount": {
"type": "number",
"title": "Active services count"
},
"pendingTasksCount": {
"type": "number",
"title": "Pending tasks count"
},
"registeredContainerInstancesCount": {
"type": "number",
"title": "Registered container instances count"
},
"capacityProviders": {
"type": "array",
"title": "Capacity providers"
},
"clusterArn": {
"type": "string",
"title": "Cluster ARN"
},
"tags": {
"type": "array",
"title": "Tags",
"items": {
"type": "object",
"properties": {
"Key": {
"type": "string"
},
"Value": {
"type": "string"
}
}
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
**ECS Cluster mapping configuration (click to expand)**
```
resources:
- kind: AWS::ECS::Cluster
selector:
query: 'true'
# includeActions: No optional actions available for ECS clusters
# All properties are included by default via DescribeClustersAction
port:
entity:
mappings:
identifier: .Properties.ClusterArn
title: .Properties.ClusterName
blueprint: '"ecsCluster"'
properties:
status: .Properties.Status
runningTasksCount: .Properties.RunningTasksCount
activeServicesCount: .Properties.ActiveServicesCount
pendingTasksCount: .Properties.PendingTasksCount
registeredContainerInstancesCount: .Properties.RegisteredContainerInstancesCount
capacityProviders: .Properties.CapacityProviders
clusterArn: .Properties.ClusterArn
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
## AWS::ECS::Service[](#awsecsservice "Direct link to AWS::ECS::Service")
The following example demonstrates how to ingest your AWS ECS services to Port.
#### ECS Service supported actions[](#ecs-service-supported-actions "Direct link to ECS Service supported actions")
The table below summarizes the available actions for ingesting Amazon ECS Service resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------ | ------- | ------------------------------------------ |
| [DescribeServicesAction](https://docs.aws.amazon.com/AmazonECS/latest/APIReference/API_DescribeServices.html) | Discover ECS services within your clusters and retrieve detailed configuration data. | Default | `ecs:ListServices`, `ecs:DescribeServices` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**ECS Service blueprint (click to expand)**
Create in Port
```
{
"identifier": "ecsService",
"title": "ECS Service",
"icon": "AWS",
"schema": {
"properties": {
"serviceName": {
"type": "string",
"title": "Service Name",
"description": "The name of the ECS service"
},
"serviceArn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the service"
},
"clusterArn": {
"type": "string",
"title": "Cluster ARN",
"description": "The ARN of the cluster that hosts the service"
},
"taskDefinition": {
"type": "string",
"title": "Task Definition",
"description": "The ARN of the task definition associated with the service"
},
"desiredCount": {
"type": "number",
"title": "Desired Count",
"description": "The desired number of tasks for the service"
},
"runningCount": {
"type": "number",
"title": "Running Count",
"description": "The number of tasks that are currently running"
},
"launchType": {
"type": "string",
"title": "Launch Type",
"description": "The launch type of the service",
"enum": ["EC2", "FARGATE", "EXTERNAL"]
},
"status": {
"type": "string",
"title": "Status",
"description": "The current status of the service",
"enum": ["ACTIVE", "DRAINING", "INACTIVE"]
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
},
"cluster": {
"title": "Cluster",
"target": "ecsCluster",
"required": false,
"many": false
}
}
}
```
**ECS Service mapping configuration (click to expand)**
```
resources:
- kind: AWS::ECS::Service
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ServiceArn
title: .Properties.ServiceName
blueprint: '"ecsService"'
properties:
serviceName: .Properties.ServiceName
serviceArn: .Properties.ServiceArn
clusterArn: .Properties.ClusterArn
taskDefinition: .Properties.TaskDefinition
desiredCount: .Properties.DesiredCount
runningCount: .Properties.RunningCount
launchType: .Properties.LaunchType
status: .Properties.Status
relations:
account: .__ExtraContext.AccountId
cluster: .Properties.ClusterArn
```
## AWS::ECS::TaskDefinition[](#awsecstaskdefinition "Direct link to AWS::ECS::TaskDefinition")
The following example demonstrates how to ingest your AWS ECS task definitions to Port.
#### ECS Task Definition supported actions[](#ecs-task-definition-supported-actions "Direct link to ECS Task Definition supported actions")
The table below summarizes the available actions for ingesting Amazon ECS Task Definition resources in Port:
| Action | Description | Type | Required AWS Permission |
| -------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------- | ------- | ---------------------------- |
| [ListTaskDefinitionsAction](https://docs.aws.amazon.com/AmazonECS/latest/APIReference/API_ListTaskDefinitions.html) | List all active task definition ARNs in the account. | Default | `ecs:ListTaskDefinitions` |
| [DescribeTaskDefinitionsAction](https://docs.aws.amazon.com/AmazonECS/latest/APIReference/API_DescribeTaskDefinition.html) | Fetch full container configuration details for each task definition. | Default | `ecs:DescribeTaskDefinition` |
All properties available by default
ECS task definitions expose all key properties via the default ListTaskDefinitions and DescribeTaskDefinitions actions.
You can use the following Port blueprint definitions and integration configuration:
**ECS Task Definition blueprint (click to expand)**
```
[
{
"identifier": "ecsTaskDefinition",
"title": "ECS Task Definition",
"icon": "AWS",
"schema": {
"properties": {
"taskDefinitionArn": {
"type": "string",
"title": "Task Definition ARN",
"description": "The full ARN of the task definition"
},
"family": {
"type": "string",
"title": "Family",
"description": "The family name of the task definition"
},
"revision": {
"type": "number",
"title": "Revision",
"description": "The revision number of the task definition"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the task definition",
"enum": ["ACTIVE", "INACTIVE", "DELETE_IN_PROGRESS"]
},
"containerDefinitions": {
"type": "array",
"title": "Container Definitions",
"description": "The container definitions that describe the containers in the task",
"items": {
"type": "object"
}
},
"cpu": {
"type": "string",
"title": "CPU",
"description": "The number of CPU units used by the task (e.g. 256, 512, 1024)"
},
"memory": {
"type": "string",
"title": "Memory",
"description": "The amount of memory (in MiB) used by the task (e.g. 512, 1024, 2048)"
},
"networkMode": {
"type": "string",
"title": "Network Mode",
"description": "The Docker networking mode to use for the containers",
"enum": ["bridge", "host", "awsvpc", "none"]
},
"requiresCompatibilities": {
"type": "array",
"title": "Requires Compatibilities",
"description": "The task launch types the task definition was validated against",
"items": {
"type": "string"
}
},
"taskRoleArn": {
"type": "string",
"title": "Task Role ARN",
"description": "The ARN of the IAM role that grants containers permission to call AWS APIs"
},
"executionRoleArn": {
"type": "string",
"title": "Execution Role ARN",
"description": "The ARN of the task execution IAM role"
},
"volumes": {
"type": "array",
"title": "Volumes",
"description": "The list of data volume definitions for the task",
"items": {
"type": "object"
}
},
"placementConstraints": {
"type": "array",
"title": "Placement Constraints",
"description": "The placement constraint objects to use for tasks",
"items": {
"type": "object"
}
},
"tags": {
"type": "array",
"title": "Tags",
"description": "The tags associated with the task definition",
"items": {
"type": "object"
}
},
"registeredAt": {
"type": "string",
"title": "Registered At",
"format": "date-time",
"description": "The timestamp when the task definition was registered"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
]
```
**ECS Task Definition mapping configuration (click to expand)**
```
resources:
- kind: AWS::ECS::TaskDefinition
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.TaskDefinitionArn
title: .Properties.Family + ":" + (.Properties.Revision | tostring)
blueprint: '"ecsTaskDefinition"'
properties:
taskDefinitionArn: .Properties.TaskDefinitionArn
family: .Properties.Family
revision: .Properties.Revision
status: .Properties.Status
containerDefinitions: .Properties.ContainerDefinitions
cpu: .Properties.Cpu
memory: .Properties.Memory
networkMode: .Properties.NetworkMode
requiresCompatibilities: .Properties.RequiresCompatibilities
taskRoleArn: .Properties.TaskRoleArn
executionRoleArn: .Properties.ExecutionRoleArn
volumes: .Properties.Volumes
placementConstraints: .Properties.PlacementConstraints
tags: .Properties.Tags
registeredAt: .Properties.RegisteredAt
relations:
account: .__ExtraContext.AccountId
```
For more details about ECS cluster properties, refer to the [AWS ECS API documentation](https://docs.aws.amazon.com/AmazonECS/latest/APIReference/Welcome.html).
---
# Amazon Elastic Kubernetes Service (EKS)
## AWS::EKS::Cluster[](#awsekscluster "Direct link to AWS::EKS::Cluster")
The following example demonstrates how to ingest your AWS EKS clusters to Port.
#### EKS Cluster supported actions[](#eks-cluster-supported-actions "Direct link to EKS Cluster supported actions")
The table below summarizes the available actions for ingesting Amazon EKS Cluster resources in Port:
| Action | Description | Type | Required AWS Permission |
| ----------------------------------------------------------------------------------------------------- | ------------------------------------------------------ | ------- | ---------------------------------------- |
| [DescribeClusterAction](https://docs.aws.amazon.com/eks/latest/APIReference/API_DescribeCluster.html) | Retrieve detailed configuration data for each cluster. | Default | `eks:DescribeCluster` `eks:ListClusters` |
All properties available by default
EKS clusters expose their key properties via the default DescribeCluster action.
You can use the following Port blueprint definitions and integration configuration:
**EKS Cluster blueprint (click to expand)**
Create in Port
```
{
"identifier": "eksCluster",
"title": "EKS Cluster",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the EKS cluster"
},
"name": {
"type": "string",
"title": "Name",
"description": "The name of the EKS cluster"
},
"version": {
"type": "string",
"title": "Kubernetes Version",
"description": "The Kubernetes version of the EKS cluster"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the EKS cluster"
},
"endpoint": {
"type": "string",
"title": "Endpoint",
"description": "The endpoint URL for the EKS cluster"
},
"roleArn": {
"type": "string",
"title": "Role ARN",
"description": "The IAM role ARN associated with the EKS cluster"
},
"tags": {
"type": "object",
"title": "Tags",
"description": "Tags associated with the EKS cluster",
"additionalProperties": {
"type": "string"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**EKS Cluster mapping configuration (click to expand)**
```
resources:
- kind: AWS::EKS::Cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Properties.Name
blueprint: '"eksCluster"'
properties:
arn: .Properties.Arn
name: .Properties.Name
version: .Properties.Version
status: .Properties.Status
endpoint: .Properties.Endpoint
roleArn: .Properties.RoleArn
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about EKS cluster properties, refer to the [AWS EKS API documentation](https://docs.aws.amazon.com/eks/latest/APIReference/Welcome.html).
---
# Amazon ElastiCache
## AWS::ElastiCache::Cluster[](#awselasticachecluster "Direct link to AWS::ElastiCache::Cluster")
The following example demonstrates how to ingest your AWS ElastiCache clusters to Port.
#### ElastiCache Cluster supported actions[](#elasticache-cluster-supported-actions "Direct link to ElastiCache Cluster supported actions")
The table below summarizes the available actions for ingesting Amazon ElastiCache Cluster resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------- | -------- | ----------------------------------- |
| [DescribeCacheClustersAction](https://docs.aws.amazon.com/AmazonElastiCache/latest/APIReference/API_DescribeCacheClusters.html) | Discover all ElastiCache clusters and retrieve their configuration (nodes, engine, status). | Default | `elasticache:DescribeCacheClusters` |
| [ListTagsForResourceAction](https://docs.aws.amazon.com/AmazonElastiCache/latest/APIReference/API_ListTagsForResource.html) | Retrieve tags for each cluster. | Optional | `elasticache:ListTagsForResource` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**ElastiCache Cluster blueprint (click to expand)**
```
[
{
"identifier": "elasticacheCluster",
"title": "ElastiCache Cluster",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the cluster"
},
"cacheClusterId": {
"type": "string",
"title": "Cluster ID",
"description": "The unique identifier of the cache cluster"
},
"cacheClusterStatus": {
"type": "string",
"title": "Status",
"description": "The current status of the cluster",
"enum": ["available", "creating", "deleted", "deleting", "incompatible-network", "modifying", "rebooting cluster nodes", "restore-failed", "snapshotting"]
},
"cacheNodeType": {
"type": "string",
"title": "Node Type",
"description": "The compute and memory capacity of the nodes (e.g., cache.t4g.micro, cache.r6g.large)"
},
"engine": {
"type": "string",
"title": "Engine",
"description": "The cache engine (redis or memcached)"
},
"engineVersion": {
"type": "string",
"title": "Engine Version",
"description": "The version of the cache engine"
},
"numCacheNodes": {
"type": "number",
"title": "Number of Nodes",
"description": "The number of cache nodes in the cluster"
},
"preferredAvailabilityZone": {
"type": "string",
"title": "Availability Zone",
"description": "The preferred availability zone for the cluster"
},
"cacheClusterCreateTime": {
"type": "string",
"title": "Created At",
"description": "The date and time when the cluster was created",
"format": "date-time"
},
"preferredMaintenanceWindow": {
"type": "string",
"title": "Maintenance Window",
"description": "The weekly time range for maintenance"
},
"cacheParameterGroup": {
"type": "object",
"title": "Parameter Group",
"description": "The cache parameter group associated with the cluster"
},
"cacheSubnetGroupName": {
"type": "string",
"title": "Subnet Group",
"description": "The name of the cache subnet group"
},
"cacheNodes": {
"type": "array",
"title": "Cache Nodes",
"description": "The list of cache nodes in the cluster",
"items": {
"type": "object"
}
},
"autoMinorVersionUpgrade": {
"type": "boolean",
"title": "Auto Minor Version Upgrade",
"description": "Whether minor version upgrades are applied automatically"
},
"securityGroups": {
"type": "array",
"title": "Security Groups",
"description": "The VPC security groups associated with the cluster",
"items": {
"type": "object"
}
},
"replicationGroupId": {
"type": "string",
"title": "Replication Group ID",
"description": "The replication group this cluster belongs to"
},
"snapshotRetentionLimit": {
"type": "number",
"title": "Snapshot Retention Limit",
"description": "Number of days snapshots are retained (0 means backups are disabled)"
},
"snapshotWindow": {
"type": "string",
"title": "Snapshot Window",
"description": "The daily time range for automatic snapshots"
},
"authTokenEnabled": {
"type": "boolean",
"title": "Auth Token Enabled",
"description": "Whether Redis AUTH is enabled"
},
"transitEncryptionEnabled": {
"type": "boolean",
"title": "Transit Encryption",
"description": "Whether in-transit encryption is enabled"
},
"atRestEncryptionEnabled": {
"type": "boolean",
"title": "At-Rest Encryption",
"description": "Whether at-rest encryption is enabled"
},
"networkType": {
"type": "string",
"title": "Network Type",
"description": "The network type (ipv4, ipv6, or dual_stack)"
},
"ipDiscovery": {
"type": "string",
"title": "IP Discovery",
"description": "The IP discovery type"
},
"logDeliveryConfigurations": {
"type": "array",
"title": "Log Delivery Configurations",
"description": "The log delivery configurations",
"items": {
"type": "object"
}
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the cluster",
"items": {
"type": "object",
"properties": {
"Key": {
"type": "string"
},
"Value": {
"type": "string"
}
}
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
]
```
**ElastiCache Cluster mapping configuration (click to expand)**
```
resources:
- kind: AWS::ElastiCache::Cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ARN
title: .Properties.CacheClusterId
blueprint: '"elasticacheCluster"'
properties:
arn: .Properties.ARN
cacheClusterId: .Properties.CacheClusterId
cacheClusterStatus: .Properties.CacheClusterStatus
cacheNodeType: .Properties.CacheNodeType
engine: .Properties.Engine
engineVersion: .Properties.EngineVersion
numCacheNodes: .Properties.NumCacheNodes
preferredAvailabilityZone: .Properties.PreferredAvailabilityZone
cacheClusterCreateTime: .Properties.CacheClusterCreateTime
preferredMaintenanceWindow: .Properties.PreferredMaintenanceWindow
cacheParameterGroup: .Properties.CacheParameterGroup
cacheSubnetGroupName: .Properties.CacheSubnetGroupName
cacheNodes: .Properties.CacheNodes
autoMinorVersionUpgrade: .Properties.AutoMinorVersionUpgrade
securityGroups: .Properties.SecurityGroups
replicationGroupId: .Properties.ReplicationGroupId
snapshotRetentionLimit: .Properties.SnapshotRetentionLimit
snapshotWindow: .Properties.SnapshotWindow
authTokenEnabled: .Properties.AuthTokenEnabled
transitEncryptionEnabled: .Properties.TransitEncryptionEnabled
atRestEncryptionEnabled: .Properties.AtRestEncryptionEnabled
networkType: .Properties.NetworkType
ipDiscovery: .Properties.IpDiscovery
logDeliveryConfigurations: .Properties.LogDeliveryConfigurations
tags: .Properties.TagList
relations:
account: .__ExtraContext.AccountId
```
For more details about ElastiCache cluster properties, refer to the [AWS ElastiCache API documentation](https://docs.aws.amazon.com/AmazonElastiCache/latest/APIReference/Welcome.html).
---
# Amazon Managed Streaming for Apache Kafka (MSK)
## AWS::MSK::Cluster[](#awsmskcluster "Direct link to AWS::MSK::Cluster")
The following example demonstrates how to ingest your AWS MSK clusters to Port.
#### MSK Cluster supported actions[](#msk-cluster-supported-actions "Direct link to MSK Cluster supported actions")
The table below summarizes the available actions for ingesting Amazon MSK Cluster resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------ | --------------------------------------------------------------- | ------- | ----------------------- |
| [ListClustersAction](https://docs.aws.amazon.com/msk/1.0/apireference/clusters.html) | Discover MSK clusters and retrieve detailed configuration data. | Default | `kafka:ListClusters` |
You can use the following Port blueprint definitions and integration configuration:
**MSK Cluster blueprint (click to expand)**
```
[
{
"identifier": "mskCluster",
"title": "MSK Cluster",
"icon": "AWS",
"schema": {
"properties": {
"clusterArn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the MSK cluster"
},
"state": {
"type": "string",
"title": "State",
"description": "The current state of the cluster",
"enum": [
"ACTIVE",
"CREATING",
"DELETING",
"FAILED",
"HEALING",
"MAINTENANCE",
"REBOOTING_BROKER",
"UPDATING"
]
},
"kafkaVersion": {
"type": "string",
"title": "Kafka Version",
"description": "The version of Apache Kafka"
},
"numberOfBrokerNodes": {
"type": "number",
"title": "Number of Broker Nodes",
"description": "The number of broker nodes in the cluster"
},
"instanceType": {
"type": "string",
"title": "Instance Type",
"description": "The type of broker instances"
},
"enhancedMonitoring": {
"type": "string",
"title": "Enhanced Monitoring",
"description": "The level of enhanced monitoring"
},
"clientAuthentication": {
"type": "object",
"title": "Client Authentication",
"description": "Client authentication settings (IAM, SASL, TLS)"
},
"encryptionInTransit": {
"type": "string",
"title": "Encryption In Transit",
"description": "Encryption setting for data in transit between clients and brokers"
},
"creationTime": {
"type": "string",
"title": "Creation Time",
"description": "The time when the cluster was created",
"format": "date-time"
},
"tags": {
"type": "object",
"title": "Tags",
"description": "Tags associated with the cluster"
}
},
"required": []
},
"calculationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
]
```
**MSK Cluster mapping configuration (click to expand)**
```
resources:
- kind: AWS::MSK::Cluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ClusterArn
title: .Properties.ClusterName
blueprint: '"mskCluster"'
properties:
clusterArn: .Properties.ClusterArn
state: .Properties.State
kafkaVersion: .Properties.CurrentBrokerSoftwareInfo.KafkaVersion
numberOfBrokerNodes: .Properties.NumberOfBrokerNodes
instanceType: .Properties.BrokerNodeGroupInfo.InstanceType
enhancedMonitoring: .Properties.EnhancedMonitoring
clientAuthentication: .Properties.ClientAuthentication
encryptionInTransit: .Properties.EncryptionInfo.EncryptionInTransit.ClientBroker
creationTime: .Properties.CreationTime
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about MSK cluster properties, refer to the [AWS MSK API documentation](https://docs.aws.amazon.com/msk/latest/developerguide/what-is-msk.html).
## AWS::MSK::ServerlessCluster[](#awsmskserverlesscluster "Direct link to AWS::MSK::ServerlessCluster")
The following example demonstrates how to ingest your AWS MSK serverless clusters to Port.
#### MSK Serverless Cluster supported actions[](#msk-serverless-cluster-supported-actions "Direct link to MSK Serverless Cluster supported actions")
The table below summarizes the available actions for ingesting Amazon MSK Serverless Cluster resources in Port:
| Action | Description | Type | Required AWS Permission |
| ---------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------- | ------- | ----------------------- |
| [ListMskServerlessClustersAction](https://docs.aws.amazon.com/msk/1.0/apireference/clusters-v2.html) | Discover MSK serverless clusters and retrieve configuration data such as VPC settings, client authentication, and cluster state. | Default | `kafka:ListClustersV2` |
All properties available by default
MSK serverless clusters expose their key properties via the default ListMskServerlessClustersAction.
You can use the following Port blueprint definitions and integration configuration:
**MSK Serverless Cluster blueprint (click to expand)**
Create in Port
```
{
"identifier": "mskServerlessCluster",
"title": "MSK Serverless Cluster",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the MSK serverless cluster"
},
"clusterName": {
"type": "string",
"title": "Cluster Name",
"description": "The name of the MSK serverless cluster"
},
"state": {
"type": "string",
"title": "State",
"description": "The current state of the cluster",
"enum": [
"ACTIVE",
"CREATING",
"DELETING",
"FAILED",
"HEALING",
"MAINTENANCE",
"REBOOTING_BROKER",
"UPDATING"
]
},
"creationTime": {
"type": "string",
"title": "Creation Time",
"description": "The date and time when the cluster was created",
"format": "date-time"
},
"currentVersion": {
"type": "string",
"title": "Current Version",
"description": "The current version of the MSK cluster"
},
"vpcConfigs": {
"type": "array",
"title": "VPC Configs",
"description": "The VPC configuration for the serverless cluster",
"items": {
"type": "object"
}
},
"clientAuthentication": {
"type": "object",
"title": "Client Authentication",
"description": "The client authentication configuration for the cluster"
},
"tags": {
"type": "object",
"title": "Tags",
"description": "Tags associated with the cluster"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**MSK Serverless Cluster mapping configuration (click to expand)**
```
resources:
- kind: AWS::MSK::ServerlessCluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ClusterArn
title: .Properties.ClusterName
blueprint: '"mskServerlessCluster"'
properties:
arn: .Properties.ClusterArn
clusterName: .Properties.ClusterName
state: .Properties.State
creationTime: .Properties.CreationTime
currentVersion: .Properties.CurrentVersion
vpcConfigs: .Properties.Serverless.VpcConfigs
clientAuthentication: .Properties.Serverless.ClientAuthentication
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about MSK serverless cluster properties, refer to the [AWS MSK API documentation](https://docs.aws.amazon.com/msk/latest/developerguide/what-is-msk.html).
---
# Amazon MemoryDB
## AWS::MemoryDB::User[](#awsmemorydbuser "Direct link to AWS::MemoryDB::User")
The following example demonstrates how to ingest your AWS MemoryDB users to Port.
#### MemoryDB User supported actions[](#memorydb-user-supported-actions "Direct link to MemoryDB User supported actions")
The table below summarizes the available actions for ingesting Amazon MemoryDB User resources in Port:
| Action | Description | Type | Required AWS Permission |
| -------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------- | -------- | ------------------------ |
| [DescribeMemoryDbUsersAction](https://docs.aws.amazon.com/memorydb/latest/APIReference/API_DescribeUsers.html) | Discover MemoryDB users and retrieve configuration details such as access string, ACL names, and authentication mode. | Default | `memorydb:DescribeUsers` |
| [ListTagsForMemoryDbUserAction](https://docs.aws.amazon.com/memorydb/latest/APIReference/API_ListTags.html) | Retrieve tags for each MemoryDB user. | Optional | `memorydb:ListTags` |
Optional properties note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
### Supported regions[](#supported-regions "Direct link to Supported regions")
* `ap-east-1`.
* `ap-northeast-1`.
* `ap-northeast-2`.
* `ap-south-1`.
* `ap-southeast-1`.
* `ap-southeast-2`.
* `ca-central-1`.
* `eu-central-1`.
* `eu-north-1`.
* `eu-south-1`.
* `eu-south-2`.
* `eu-west-1`.
* `eu-west-2`.
* `eu-west-3`.
* `sa-east-1`.
* `us-east-1`.
* `us-east-2`.
* `us-west-1`.
* `us-west-2`.
* `us-gov-east-1`.
* `us-gov-west-1`.
You can use the following Port blueprint definitions and integration configuration:
**MemoryDB User blueprint (click to expand)**
Create in Port
```
{
"identifier": "memoryDbUser",
"title": "MemoryDB User",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the MemoryDB user"
},
"status": {
"type": "string",
"title": "Status",
"description": "The current status of the user (active, modifying, or deleting)"
},
"accessString": {
"type": "string",
"title": "Access String",
"description": "Access permissions string used for this user account"
},
"aclNames": {
"type": "array",
"title": "ACL Names",
"description": "The names of the Access Control Lists (ACLs) the user belongs to",
"items": {
"type": "string"
}
},
"minimumEngineVersion": {
"type": "string",
"title": "Minimum Engine Version",
"description": "The minimum engine version supported for the user"
},
"authentication": {
"type": "object",
"title": "Authentication",
"description": "The authentication mode for the user"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the MemoryDB user",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**MemoryDB User mapping configuration (click to expand)**
```
resources:
- kind: AWS::MemoryDB::User
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ARN
title: .Properties.Name
blueprint: '"memoryDbUser"'
properties:
arn: .Properties.ARN
status: .Properties.Status
accessString: .Properties.AccessString
aclNames: .Properties.ACLNames
minimumEngineVersion: .Properties.MinimumEngineVersion
authentication: .Properties.Authentication
tags: .Properties.TagList
relations:
account: .__ExtraContext.AccountId
```
For more details about MemoryDB user properties, refer to the [AWS MemoryDB API documentation](https://docs.aws.amazon.com/memorydb/latest/APIReference/Welcome.html).
---
# Amazon Relational Database Service (RDS)
## AWS::RDS::DBInstance[](#awsrdsdbinstance "Direct link to AWS::RDS::DBInstance")
The following example demonstrates how to ingest your AWS RDS DB instances to Port.
#### RDS DB Instance supported actions[](#rds-db-instance-supported-actions "Direct link to RDS DB Instance supported actions")
The table below summarizes the available actions for ingesting Amazon RDS DB Instance resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------- | -------- | ------------------------- |
| [DescribeDBInstancesAction](https://docs.aws.amazon.com/AmazonRDS/latest/APIReference/API_DescribeDBInstances.html) | Discover DB instances and retrieve configuration details. | Default | `rds:DescribeDBInstances` |
| [ListTagsForResourceAction](https://docs.aws.amazon.com/AmazonRDS/latest/APIReference/API_ListTagsForResource.html) | Retrieve tags for each DB instance. | Optional | `rds:ListTagsForResource` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**RDS DB Instance blueprint (click to expand)**
Create in Port
```
{
"identifier": "rdsDbInstance",
"title": "RDS DB Instance",
"icon": "AWS",
"schema": {
"properties": {
"dbInstanceIdentifier": {
"type": "string",
"title": "DB Instance Identifier",
"description": "The unique identifier of the RDS DB instance"
},
"dbInstanceArn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the DB instance"
},
"engine": {
"type": "string",
"title": "Engine",
"description": "The database engine type (e.g., mysql, postgres, oracle-ee)"
},
"dbInstanceClass": {
"type": "string",
"title": "Instance Class",
"description": "The compute and memory capacity of the DB instance (e.g., db.t3.micro, db.m4.xlarge)"
},
"dbInstanceStatus": {
"type": "string",
"title": "Status",
"description": "The current status of the DB instance",
"enum": [
"available",
"backing-up",
"creating",
"deleting",
"failed",
"incompatible-credentials",
"incompatible-network",
"incompatible-option-group",
"incompatible-parameters",
"incompatible-restore",
"maintenance",
"modifying",
"rebooting",
"renaming",
"resetting-master-credentials",
"restore-error",
"storage-full",
"storage-optimization",
"upgrading"
]
},
"multiAZ": {
"type": "boolean",
"title": "Multi-AZ",
"description": "Whether the DB instance is deployed in multiple Availability Zones"
},
"storageEncrypted": {
"type": "boolean",
"title": "Storage Encrypted",
"description": "Whether the DB instance storage is encrypted"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**RDS DB Instance mapping configuration (click to expand)**
```
resources:
- kind: AWS::RDS::DBInstance
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DBInstanceArn
title: .Properties.DBInstanceIdentifier
blueprint: '"rdsDbInstance"'
properties:
dbInstanceIdentifier: .Properties.DBInstanceIdentifier
dbInstanceArn: .Properties.DBInstanceArn
engine: .Properties.Engine
dbInstanceClass: .Properties.DBInstanceClass
dbInstanceStatus: .Properties.DBInstanceStatus
multiAZ: .Properties.MultiAZ
storageEncrypted: .Properties.StorageEncrypted
relations:
account: .__ExtraContext.AccountId
```
For more details about RDS DB instance properties, refer to the [AWS RDS API documentation](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/ProgrammingGuide.html).
## AWS::RDS::DBCluster[](#awsrdsdbcluster "Direct link to AWS::RDS::DBCluster")
The following example demonstrates how to ingest your AWS RDS DB clusters (for example, Aurora clusters) to Port.
#### RDS DB Cluster supported actions[](#rds-db-cluster-supported-actions "Direct link to RDS DB Cluster supported actions")
The table below summarizes the available actions for ingesting Amazon RDS DB Cluster resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------ | -------- | ------------------------- |
| [DescribeDBClustersAction](https://docs.aws.amazon.com/AmazonRDS/latest/APIReference/API_DescribeDBClusters.html) | Discover DB clusters and retrieve configuration details such as engine mode, endpoints, and cluster members. | Default | `rds:DescribeDBClusters` |
| [ListTagsForResourceAction](https://docs.aws.amazon.com/AmazonRDS/latest/APIReference/API_ListTagsForResource.html) | Retrieve tags for each DB cluster. | Optional | `rds:ListTagsForResource` |
Optional properties note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**RDS DB Cluster blueprint (click to expand)**
Create in Port
```
{
"identifier": "rdsDbCluster",
"title": "RDS DB Cluster",
"icon": "AWS",
"schema": {
"properties": {
"activityStreamStatus": {
"type": "string",
"title": "Activity Stream Status",
"description": "The status of the database activity stream"
},
"associatedRoles": {
"type": "array",
"title": "Associated Roles",
"description": "The IAM roles associated with the DB cluster",
"items": {
"type": "object"
}
},
"autoMinorVersionUpgrade": {
"type": "boolean",
"title": "Auto Minor Version Upgrade",
"description": "Whether minor version upgrades are applied automatically"
},
"availabilityZones": {
"type": "array",
"title": "Availability Zones",
"description": "The Availability Zones where the DB cluster is deployed",
"items": {
"type": "string"
}
},
"backupRetentionPeriod": {
"type": "number",
"title": "Backup Retention Period",
"description": "The number of days to retain automated backups"
},
"clusterCreateTime": {
"type": "string",
"title": "Cluster Create Time",
"description": "The time when the DB cluster was created"
},
"copyTagsToSnapshot": {
"type": "boolean",
"title": "Copy Tags To Snapshot",
"description": "Whether to copy tags to snapshots"
},
"crossAccountClone": {
"type": "boolean",
"title": "Cross Account Clone",
"description": "Whether cross-account cloning is enabled"
},
"databaseName": {
"type": "string",
"title": "Database Name",
"description": "The name of the initial database"
},
"dbClusterArn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the DB cluster"
},
"dbClusterIdentifier": {
"type": "string",
"title": "DB Cluster Identifier",
"description": "The unique identifier of the RDS DB cluster"
},
"dbClusterMembers": {
"type": "array",
"title": "DB Cluster Members",
"description": "The DB instances that belong to the cluster",
"items": {
"type": "object"
}
},
"dbClusterResourceId": {
"type": "string",
"title": "DB Cluster Resource ID",
"description": "The unique resource identifier for the DB cluster"
},
"deletionProtection": {
"type": "boolean",
"title": "Deletion Protection",
"description": "Whether deletion protection is enabled"
},
"earliestRestorableTime": {
"type": "string",
"title": "Earliest Restorable Time",
"description": "The earliest time to which the DB cluster can be restored"
},
"endpoint": {
"type": "string",
"title": "Writer Endpoint",
"description": "The writer endpoint for the DB cluster"
},
"engine": {
"type": "string",
"title": "Engine",
"description": "The database engine type (e.g., aurora-mysql, aurora-postgresql)"
},
"engineMode": {
"type": "string",
"title": "Engine Mode",
"description": "The engine mode of the DB cluster (e.g., provisioned, serverless)"
},
"engineVersion": {
"type": "string",
"title": "Engine Version",
"description": "The version of the database engine"
},
"globalWriteForwardingStatus": {
"type": "string",
"title": "Global Write Forwarding Status",
"description": "The status of write forwarding for a secondary cluster in a global database"
},
"httpEndpointEnabled": {
"type": "boolean",
"title": "HTTP Endpoint Enabled",
"description": "Whether the HTTP endpoint (Data API) is enabled for Aurora Serverless"
},
"iamDatabaseAuthenticationEnabled": {
"type": "boolean",
"title": "IAM Database Authentication Enabled",
"description": "Whether IAM database authentication is enabled"
},
"kmsKeyId": {
"type": "string",
"title": "KMS Key ID",
"description": "The KMS key identifier for encryption"
},
"latestRestorableTime": {
"type": "string",
"title": "Latest Restorable Time",
"description": "The latest time to which the DB cluster can be restored"
},
"masterUsername": {
"type": "string",
"title": "Master Username",
"description": "The master username for the DB cluster"
},
"multiAZ": {
"type": "boolean",
"title": "Multi-AZ",
"description": "Whether the DB cluster is deployed across multiple Availability Zones"
},
"networkType": {
"type": "string",
"title": "Network Type",
"description": "The network type for the DB cluster"
},
"port": {
"type": "number",
"title": "Port",
"description": "The port number for the DB cluster"
},
"preferredBackupWindow": {
"type": "string",
"title": "Preferred Backup Window",
"description": "The preferred backup window"
},
"preferredMaintenanceWindow": {
"type": "string",
"title": "Preferred Maintenance Window",
"description": "The preferred maintenance window"
},
"readerEndpoint": {
"type": "string",
"title": "Reader Endpoint",
"description": "The reader endpoint for load-balancing read connections across cluster members"
},
"status": {
"type": "string",
"title": "Status",
"description": "The current status of the DB cluster",
"enum": [
"available",
"backing-up",
"creating",
"deleting",
"failing-over",
"inaccessible-encryption-credentials",
"maintenance",
"migrating",
"modifying",
"promoting",
"renaming",
"resetting-master-credentials",
"scaling",
"starting",
"stopped",
"stopping",
"upgrading"
]
},
"storageEncrypted": {
"type": "boolean",
"title": "Storage Encrypted",
"description": "Whether the DB cluster storage is encrypted"
},
"storageType": {
"type": "string",
"title": "Storage Type",
"description": "The storage type of the DB cluster"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "The tags associated with the DB cluster",
"items": {
"type": "object",
"properties": {
"Key": {
"type": "string"
},
"Value": {
"type": "string"
}
}
}
},
"vpcSecurityGroups": {
"type": "array",
"title": "VPC Security Groups",
"description": "The VPC security groups associated with the DB cluster",
"items": {
"type": "object"
}
},
"dbSubnetGroup": {
"type": "string",
"title": "DB Subnet Group",
"description": "The subnet group associated with the DB cluster"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**RDS DB Cluster mapping configuration (click to expand)**
```
resources:
- kind: AWS::RDS::DBCluster
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DBClusterArn
title: .Properties.DBClusterIdentifier
blueprint: '"rdsDbCluster"'
properties:
activityStreamStatus: .Properties.ActivityStreamStatus
associatedRoles: .Properties.AssociatedRoles
autoMinorVersionUpgrade: .Properties.AutoMinorVersionUpgrade
availabilityZones: .Properties.AvailabilityZones
backupRetentionPeriod: .Properties.BackupRetentionPeriod
clusterCreateTime: .Properties.ClusterCreateTime
copyTagsToSnapshot: .Properties.CopyTagsToSnapshot
crossAccountClone: .Properties.CrossAccountClone
databaseName: .Properties.DatabaseName
dbClusterArn: .Properties.DBClusterArn
dbClusterIdentifier: .Properties.DBClusterIdentifier
dbClusterMembers: .Properties.DBClusterMembers
dbClusterResourceId: .Properties.DbClusterResourceId
deletionProtection: .Properties.DeletionProtection
earliestRestorableTime: .Properties.EarliestRestorableTime
endpoint: .Properties.Endpoint
engine: .Properties.Engine
engineMode: .Properties.EngineMode
engineVersion: .Properties.EngineVersion
globalWriteForwardingStatus: .Properties.GlobalWriteForwardingStatus
httpEndpointEnabled: .Properties.HttpEndpointEnabled
iamDatabaseAuthenticationEnabled: .Properties.IAMDatabaseAuthenticationEnabled
kmsKeyId: .Properties.KmsKeyId
latestRestorableTime: .Properties.LatestRestorableTime
masterUsername: .Properties.MasterUsername
multiAZ: .Properties.MultiAZ
networkType: .Properties.NetworkType
port: .Properties.Port
preferredBackupWindow: .Properties.PreferredBackupWindow
preferredMaintenanceWindow: .Properties.PreferredMaintenanceWindow
readerEndpoint: .Properties.ReaderEndpoint
status: .Properties.Status
storageEncrypted: .Properties.StorageEncrypted
storageType: .Properties.StorageType
tags: .Properties.Tags
vpcSecurityGroups: .Properties.VpcSecurityGroups
dbSubnetGroup: .Properties.DBSubnetGroup
relations:
account: .__ExtraContext.AccountId
```
For more details about RDS DB cluster properties, refer to the [AWS RDS API documentation](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/ProgrammingGuide.html).
---
# Amazon Simple Email Service (SES)
## AWS::SES::EmailIdentity[](#awssesemailidentity "Direct link to AWS::SES::EmailIdentity")
The following example demonstrates how to ingest your AWS SES email identities to Port.
#### SES Email Identity supported actions[](#ses-email-identity-supported-actions "Direct link to SES Email Identity supported actions")
The table below summarizes the available actions for ingesting Amazon SES EmailIdentity resources in Port:
| Action | Description | Type | Required AWS Permission |
| ---------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------- | ------- | ------------------------- |
| [ListEmailIdentitiesAction](https://docs.aws.amazon.com/ses/latest/APIReference-V2/API_ListEmailIdentities.html) | Discover all SES email identities across your AWS account. | Default | `ses:ListEmailIdentities` |
| [GetEmailIdentityAction](https://docs.aws.amazon.com/ses/latest/APIReference-V2/API_GetEmailIdentity.html) | Retrieve detailed configuration and verification data for each email identity, including DKIM signing status and tags. | Default | `ses:GetEmailIdentity` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**SES Email Identity blueprint (click to expand)**
Create in Port
```
{
"identifier": "sesEmailIdentity",
"title": "SES Email Identity",
"icon": "AWS",
"schema": {
"properties": {
"identityType": {
"type": "string",
"title": "Identity Type",
"description": "The type of the email identity (EMAIL_ADDRESS or DOMAIN)"
},
"verifiedForSendingStatus": {
"type": "boolean",
"title": "Verified For Sending Status",
"description": "Indicates whether the identity is verified for sending email"
},
"dkimEnabled": {
"type": "boolean",
"title": "DKIM Enabled",
"description": "Indicates whether DKIM signing is enabled for the identity"
},
"verificationStatus": {
"type": "string",
"title": "Verification Status",
"description": "The verification status of the email identity"
},
"configurationSetName": {
"type": "string",
"title": "Configuration Set Name",
"description": "The name of the configuration set associated with the email identity"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the email identity",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**SES Email Identity mapping configuration (click to expand)**
```
resources:
- kind: AWS::SES::EmailIdentity
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.IdentityName
title: .Properties.IdentityName
blueprint: '"sesEmailIdentity"'
properties:
identityType: .Properties.IdentityType
verifiedForSendingStatus: .Properties.VerifiedForSendingStatus
dkimEnabled: .Properties.DkimAttributes.SigningEnabled
verificationStatus: .Properties.VerificationStatus
configurationSetName: .Properties.ConfigurationSetName
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about SES email identity properties, refer to the [AWS SES API documentation](https://docs.aws.amazon.com/ses/latest/APIReference-V2/API_GetEmailIdentity.html).
## AWS::SES::ConfigurationSet[](#awssesconfigurationset "Direct link to AWS::SES::ConfigurationSet")
The following example demonstrates how to ingest your AWS SES configuration sets to Port.
#### SES Configuration Set supported actions[](#ses-configuration-set-supported-actions "Direct link to SES Configuration Set supported actions")
The table below summarizes the available actions for ingesting Amazon SES ConfigurationSet resources in Port:
| Action | Description | Type | Required AWS Permission |
| -------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------- | ------- | --------------------------- |
| [ListConfigurationSetsAction](https://docs.aws.amazon.com/ses/latest/APIReference-V2/API_ListConfigurationSets.html) | Discover all SES configuration sets across your AWS account. | Default | `ses:ListConfigurationSets` |
| [GetConfigurationSetAction](https://docs.aws.amazon.com/ses/latest/APIReference-V2/API_GetConfigurationSet.html) | Retrieve detailed sending, reputation, delivery, tracking, and suppression data for each configuration set. | Default | `ses:GetConfigurationSet` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**SES Configuration Set blueprint (click to expand)**
Create in Port
```
{
"identifier": "sesConfigurationSet",
"title": "SES Configuration Set",
"icon": "AWS",
"schema": {
"properties": {
"sendingEnabled": {
"type": "boolean",
"title": "Sending Enabled",
"description": "Indicates whether email sending is enabled for the configuration set"
},
"reputationMetricsEnabled": {
"type": "boolean",
"title": "Reputation Metrics Enabled",
"description": "Indicates whether reputation metrics tracking is enabled"
},
"tlsPolicy": {
"type": "string",
"title": "TLS Policy",
"description": "The TLS policy that applies to the configuration set (REQUIRE or OPTIONAL)"
},
"trackingDomain": {
"type": "string",
"title": "Tracking Domain",
"description": "The domain used to track open and click events"
},
"suppressionList": {
"type": "array",
"title": "Suppression List",
"description": "The reasons that email addresses are automatically added to the suppression list",
"items": {
"type": "string"
}
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the configuration set",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**SES Configuration Set mapping configuration (click to expand)**
```
resources:
- kind: AWS::SES::ConfigurationSet
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ConfigurationSetName
title: .Properties.ConfigurationSetName
blueprint: '"sesConfigurationSet"'
properties:
sendingEnabled: .Properties.SendingOptions.SendingEnabled
reputationMetricsEnabled: .Properties.ReputationOptions.ReputationMetricsEnabled
tlsPolicy: .Properties.DeliveryOptions.TlsPolicy
trackingDomain: .Properties.TrackingOptions.CustomRedirectDomain
suppressionList: .Properties.SuppressionOptions.SuppressedReasons
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about SES configuration set properties, refer to the [AWS SES API documentation](https://docs.aws.amazon.com/ses/latest/APIReference-V2/API_GetConfigurationSet.html).
---
# Amazon Simple Queue Service (SQS)
## AWS::SQS::Queue[](#awssqsqueue "Direct link to AWS::SQS::Queue")
The following example demonstrates how to ingest your AWS SQS queues to Port.
#### SQS Queue supported actions[](#sqs-queue-supported-actions "Direct link to SQS Queue supported actions")
The table below summarizes the available actions for ingesting Amazon SQS Queue resources in Port:
| Action | Description | Type | Required AWS Permission |
| ----------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------- | -------- | ------------------------ |
| [ListQueuesAction](https://docs.aws.amazon.com/AWSSimpleQueueService/latest/APIReference/API_ListQueues.html) | Discover all SQS queues across your AWS account. | Default | `sqs:ListQueues` |
| [GetQueueAttributesAction](https://docs.aws.amazon.com/AWSSimpleQueueService/latest/APIReference/API_GetQueueAttributes.html) | Retrieve detailed configuration and operational data for each queue. | Default | `sqs:GetQueueAttributes` |
| [ListQueueTagsAction](https://docs.aws.amazon.com/AWSSimpleQueueService/latest/APIReference/API_ListQueueTags.html) | Bring in custom tags assigned to your queues for advanced catalog filtering and grouping. | Optional | `sqs:ListQueueTags` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**SQS Queue blueprint (click to expand)**
Create in Port
```
{
"identifier": "sqsQueue",
"title": "SQS Queue",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the SQS queue"
},
"region": {
"type": "string",
"title": "Region",
"description": "The AWS region where the SQS queue is located"
},
"queueUrl": {
"type": "string",
"title": "Queue URL",
"description": "The URL of the SQS queue"
},
"approximateNumberOfMessages": {
"type": "number",
"title": "Approx Number of Messages",
"description": "The approximate number of messages available for retrieval from the queue"
},
"visibilityTimeout": {
"type": "number",
"title": "Visibility Timeout (seconds)",
"description": "The visibility timeout for the queue in seconds"
},
"messageRetentionPeriod": {
"type": "number",
"title": "Message Retention Period",
"description": "The length of time, in seconds, for which Amazon SQS retains a message"
},
"sqsManagedSseEnabled": {
"type": "boolean",
"title": "SQS Managed SSE Enabled",
"description": "Whether SQS managed server-side encryption is enabled"
},
"tags": {
"type": "object",
"title": "tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**SQS Queue mapping configuration (click to expand)**
```
- kind: AWS::SQS::Queue
selector:
query: 'true'
includeActions:
- ListQueueTagsAction
port:
entity:
mappings:
identifier: .Properties.QueueArn
title: .Properties.QueueUrl | split("/") | .[-1]
blueprint: '"sqsQueue"'
properties:
arn: .Properties.QueueArn
region: .__ExtraContext.Region
queueUrl: .Properties.QueueUrl
approximateNumberOfMessages: .Properties.ApproximateNumberOfMessages
visibilityTimeout: .Properties.VisibilityTimeout
messageRetentionPeriod: .Properties.MessageRetentionPeriod
sqsManagedSseEnabled: .Properties.SqsManagedSseEnabled
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about SQS queue properties, refer to the [AWS SQS API documentation](https://docs.aws.amazon.com/AWSSimpleQueueService/latest/APIReference/API_GetQueueAttributes.html).
---
# Amazon Simple Storage Service (S3)
## AWS::S3::Bucket[](#awss3bucket "Direct link to AWS::S3::Bucket")
The following example demonstrates how to ingest your AWS S3 buckets to Port.
#### S3 Bucket supported actions[](#s3-bucket-supported-actions "Direct link to S3 Bucket supported actions")
The table below summarizes the available actions for ingesting Amazon S3 Bucket resources in Port:
| Action | Description | Type | Required AWS Permission |
| ----------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------- | -------- | ------------------------------- |
| [ListBucketsAction](https://docs.aws.amazon.com/AmazonS3/latest/API/API_ListBuckets.html) | Discover all S3 buckets across your AWS account. | Default | `s3:ListAllMyBuckets` |
| [GetBucketTaggingAction](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketTagging.html) | Bring in bucket tags for catalog filtering and grouping. | Default | `s3:GetBucketTagging` |
| [GetBucketLocationAction](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketLocation.html) | Retrieve the bucket's region. | Optional | `s3:GetBucketLocation` |
| [GetBucketEncryptionAction](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketEncryption.html) | Retrieve server-side encryption configuration for the bucket. | Optional | `s3:GetBucketEncryption` |
| [GetBucketPublicAccessBlockAction](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetPublicAccessBlock.html) | Retrieve public access block configuration. | Optional | `s3:GetBucketPublicAccessBlock` |
| [GetBucketOwnershipControlsAction](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketOwnershipControls.html) | Retrieve bucket ownership controls. | Optional | `s3:GetBucketOwnershipControls` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**S3 Bucket blueprint (click to expand)**
Create in Port
```
{
"identifier": "s3Bucket",
"description": "This blueprint represents an AWS S3 bucket in our software catalog",
"title": "S3 bucket",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN"
},
"creationDate": {
"type": "string",
"format": "date-time",
"title": "Creation date"
},
"tags": {
"type": "array",
"title": "Tags",
"items": {
"type": "object",
"properties": {
"Key": {
"type": "string"
},
"Value": {
"type": "string"
}
}
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": true,
"many": false
}
}
}
```
**S3 Bucket mapping configuration (click to expand)**
```
resources:
- kind: AWS::S3::Bucket
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Properties.BucketName
blueprint: '"s3Bucket"'
properties:
arn: .Properties.Arn
creationDate: .Properties.CreationDate
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
For more details about S3 bucket properties, refer to the [AWS S3 API documentation](https://docs.aws.amazon.com/AmazonS3/latest/API/Welcome.html).
---
# AWS Account
## AWS::Account::Info[](#awsaccountinfo "Direct link to AWS::Account::Info")
The following example demonstrates how to ingest AWS account information using a custom resource designed for account resync without AWS Organizations permissions.
Custom Resource for Account Resync
Use `AWS::Account::Info` to resync AWS account data when you do not have organization-level permissions. If you do have AWS Organizations permissions and want to retrieve richer data (e.g., org account metadata, parents, and tags), see the AWS Organizations documentation under [AWS Organizations](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws-v3/resource-and-property-reference/aws-organizations/.md).
You can use the following Port blueprint definitions and integration configuration:
**AWS Account blueprint (click to expand)**
Create in Port
```
{
"identifier": "awsAccount",
"title": "AWS Account",
"icon": "AWS",
"schema": {
"properties": {},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**AWS Account info mapping configuration (click to expand)**
```
resources:
- kind: AWS::Account::Info
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Id
title: .Properties.Name
blueprint: '"awsAccount"'
```
---
# AWS CodeBuild
## AWS::CodeBuild::Project[](#awscodebuildproject "Direct link to AWS::CodeBuild::Project")
The following example demonstrates how to ingest your AWS CodeBuild projects to Port.
#### CodeBuild Project supported actions[](#codebuild-project-supported-actions "Direct link to CodeBuild Project supported actions")
The table below summarizes the available actions for ingesting AWS CodeBuild Project resources in Port:
| Action | Description | Type | Required AWS Permission |
| -------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------- | ------- | ------------------------------------------------------ |
| [GetProjectDetailsAction](https://docs.aws.amazon.com/codebuild/latest/APIReference/API_BatchGetProjects.html) | Discover CodeBuild projects and retrieve detailed configuration data such as source, environment, and artifacts. | Default | `codebuild:ListProjects`, `codebuild:BatchGetProjects` |
All properties available by default
CodeBuild projects expose their key properties via the default GetProjectDetailsAction.
You can use the following Port blueprint definitions and integration configuration:
**CodeBuild Project blueprint (click to expand)**
Create in Port
```
{
"identifier": "codeBuildProject",
"title": "CodeBuild Project",
"icon": "AWS",
"schema": {
"properties": {
"name": {
"type": "string",
"title": "Project Name",
"description": "The name of the CodeBuild project"
},
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the CodeBuild project"
},
"description": {
"type": "string",
"title": "Description",
"description": "A description of the CodeBuild project"
},
"serviceRole": {
"type": "string",
"title": "Service Role",
"description": "The ARN of the AWS Identity and Access Management (IAM) service role"
},
"timeoutInMinutes": {
"type": "number",
"title": "Timeout (Minutes)",
"description": "How long, in minutes, from 5 to 480, for AWS CodeBuild to wait before timing out any related build"
},
"queuedTimeoutInMinutes": {
"type": "number",
"title": "Queued Timeout (Minutes)",
"description": "The number of minutes a build is allowed to be queued before timing out"
},
"encryptionKey": {
"type": "string",
"title": "Encryption Key",
"description": "The AWS Key Management Service (AWS KMS) customer master key (CMK) to be used for encrypting the build project artifacts"
},
"environment": {
"type": "object",
"title": "Build Environment",
"description": "Information about the build environment for the build project"
},
"source": {
"type": "object",
"title": "Source",
"description": "Information about the build input source code for the build project"
},
"artifacts": {
"type": "object",
"title": "Artifacts",
"description": "Information about the build output artifacts for the build project"
},
"created": {
"type": "string",
"title": "Created",
"description": "When the build project was created",
"format": "date-time"
},
"lastModified": {
"type": "string",
"title": "Last Modified",
"description": "When the build project was last modified",
"format": "date-time"
},
"projectVisibility": {
"type": "string",
"title": "Project Visibility",
"description": "The visibility setting for the project",
"enum": [
"PRIVATE",
"PUBLIC_READ"
]
},
"concurrentBuildLimit": {
"type": "number",
"title": "Concurrent Build Limit",
"description": "The maximum number of concurrent builds that are allowed for this project"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the CodeBuild project",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodeBuild Project mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodeBuild::Project
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Properties.Name
blueprint: '"codeBuildProject"'
properties:
name: .Properties.Name
arn: .Properties.Arn
description: .Properties.Description
serviceRole: .Properties.ServiceRole
timeoutInMinutes: .Properties.TimeoutInMinutes
queuedTimeoutInMinutes: .Properties.QueuedTimeoutInMinutes
encryptionKey: .Properties.EncryptionKey
environment: .Properties.Environment
source: .Properties.Source
artifacts: .Properties.Artifacts
created: .Properties.Created
lastModified: .Properties.LastModified
projectVisibility: .Properties.ProjectVisibility
concurrentBuildLimit: .Properties.ConcurrentBuildLimit
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
## AWS::CodeBuild::BuildRun[](#awscodebuildbuildrun "Direct link to AWS::CodeBuild::BuildRun")
The following example demonstrates how to ingest your AWS CodeBuild build runs to Port.
#### CodeBuild Build Run supported actions[](#codebuild-build-run-supported-actions "Direct link to CodeBuild Build Run supported actions")
The table below summarizes the available actions for ingesting AWS CodeBuild Build Run resources in Port:
| Action | Description | Type | Required AWS Permission |
| ---------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------- | ------- | -------------------------- |
| [ListBuildsAction](https://docs.aws.amazon.com/codebuild/latest/APIReference/API_ListBuilds.html) | Discover build run IDs in the account. | Default | `codebuild:ListBuilds` |
| [GetBuildDetailsAction](https://docs.aws.amazon.com/codebuild/latest/APIReference/API_BatchGetBuilds.html) | Retrieve detailed build run data such as status, phase, and timing. | Default | `codebuild:BatchGetBuilds` |
All properties available by default
CodeBuild build runs expose their key properties via the default ListBuildsAction and GetBuildDetailsAction.
You can use the following Port blueprint definitions and integration configuration:
**CodeBuild Build Run blueprint (click to expand)**
Create in Port
```
{
"identifier": "codeBuildBuildRun",
"title": "CodeBuild Build Run",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the build run"
},
"projectName": {
"type": "string",
"title": "Project Name",
"description": "The name of the CodeBuild project"
},
"buildNumber": {
"type": "number",
"title": "Build Number",
"description": "The build number"
},
"buildStatus": {
"type": "string",
"title": "Build Status",
"description": "The current status of the build",
"enum": [
"SUCCEEDED",
"FAILED",
"FAULT",
"TIMED_OUT",
"IN_PROGRESS",
"STOPPED"
]
},
"currentPhase": {
"type": "string",
"title": "Current Phase",
"description": "The current phase of the build"
},
"startTime": {
"type": "string",
"title": "Start Time",
"description": "The time the build started",
"format": "date-time"
},
"endTime": {
"type": "string",
"title": "End Time",
"description": "The time the build ended",
"format": "date-time"
},
"sourceVersion": {
"type": "string",
"title": "Source Version",
"description": "The version of the source code"
},
"buildComplete": {
"type": "boolean",
"title": "Build Complete",
"description": "Whether the build is complete"
},
"initiator": {
"type": "string",
"title": "Initiator",
"description": "The entity that initiated the build"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodeBuild Build Run mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodeBuild::BuildRun
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Id
title: .Properties.ProjectName + " - Build " + (.Properties.BuildNumber | tostring)
blueprint: '"codeBuildBuildRun"'
properties:
arn: .Properties.Arn
projectName: .Properties.ProjectName
buildNumber: .Properties.BuildNumber
buildStatus: .Properties.BuildStatus
currentPhase: .Properties.CurrentPhase
startTime: .Properties.StartTime
endTime: .Properties.EndTime
sourceVersion: .Properties.SourceVersion
buildComplete: .Properties.BuildComplete
initiator: .Properties.Initiator
relations:
account: .__ExtraContext.AccountId
```
For more details about CodeBuild properties, refer to the [AWS CodeBuild API documentation](https://docs.aws.amazon.com/codebuild/latest/APIReference/Welcome.html).
---
# AWS CodeDeploy
## AWS::CodeDeploy::Application[](#awscodedeployapplication "Direct link to AWS::CodeDeploy::Application")
The following example demonstrates how to ingest your AWS CodeDeploy applications to Port.
#### CodeDeploy Application supported actions[](#codedeploy-application-supported-actions "Direct link to CodeDeploy Application supported actions")
The table below summarizes the available actions for ingesting AWS CodeDeploy Application resources in Port:
| Action | Description | Type | Required AWS Permission |
| --------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------- | ------- | ---------------------------------------------------------------- |
| [GetCodeDeployApplicationDetailsAction](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_BatchGetApplications.html) | Discover CodeDeploy applications and retrieve configuration details. | Default | `codedeploy:ListApplications`, `codedeploy:BatchGetApplications` |
| [GetCodeDeployApplicationTagsAction](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_ListTagsForResource.html) | Retrieve tags for each CodeDeploy application. | Default | `codedeploy:ListTagsForResource` |
All properties available by default
CodeDeploy applications expose their key properties, including tags, via the default actions.
You can use the following Port blueprint definitions and integration configuration:
**CodeDeploy Application blueprint (click to expand)**
Create in Port
```
{
"identifier": "codeDeployApplication",
"title": "CodeDeploy Application",
"icon": "AWS",
"schema": {
"properties": {
"applicationName": {
"type": "string",
"title": "Application Name"
},
"applicationId": {
"type": "string",
"title": "Application ID"
},
"createTime": {
"type": "string",
"title": "Create Time",
"format": "date-time"
},
"linkedToGitHub": {
"type": "boolean",
"title": "Linked To GitHub"
},
"gitHubAccountName": {
"type": "string",
"title": "GitHub Account Name"
},
"computePlatform": {
"type": "string",
"title": "Compute Platform"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the Application",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodeDeploy Application mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodeDeploy::Application
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ApplicationId
title: .Properties.ApplicationName
blueprint: '"codeDeployApplication"'
properties:
applicationName: .Properties.ApplicationName
applicationId: .Properties.ApplicationId
createTime: .Properties.CreateTime
linkedToGitHub: .Properties.LinkedToGitHub
gitHubAccountName: .Properties.GitHubAccountName
computePlatform: .Properties.ComputePlatform
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
## AWS::CodeDeploy::DeploymentGroup[](#awscodedeploydeploymentgroup "Direct link to AWS::CodeDeploy::DeploymentGroup")
The following example demonstrates how to ingest your AWS CodeDeploy deployment groups to Port.
#### CodeDeploy Deployment Group supported actions[](#codedeploy-deployment-group-supported-actions "Direct link to CodeDeploy Deployment Group supported actions")
The table below summarizes the available actions for ingesting AWS CodeDeploy Deployment Group resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------ | -------- | ------------------------------------------------------------------------------------------------------- |
| [GetDeploymentGroupDetailsAction](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_BatchGetDeploymentGroups.html) | Discover deployment groups and retrieve configuration details such as compute platform and deployment style. | Default | `codedeploy:ListApplications`, `codedeploy:ListDeploymentGroups`, `codedeploy:BatchGetDeploymentGroups` |
| [GetDeploymentGroupTags](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_ListTagsForResource.html) | Retrieve tags for each deployment group. | Optional | `codedeploy:ListTagsForResource` |
Optional properties and discovery
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
The integration lists CodeDeploy applications first, then fetches deployment groups for each application.
You can use the following Port blueprint definitions and integration configuration:
**CodeDeploy Deployment Group blueprint (click to expand)**
Create in Port
```
{
"identifier": "codedeployDeploymentGroup",
"title": "CodeDeploy Deployment Group",
"icon": "AWS",
"schema": {
"properties": {
"applicationName": {
"type": "string",
"title": "Application Name",
"description": "The CodeDeploy application name"
},
"deploymentGroupId": {
"type": "string",
"title": "Deployment Group ID",
"description": "The deployment group ID"
},
"serviceRoleArn": {
"type": "string",
"title": "Service Role ARN",
"description": "The ARN of the service role for the deployment group"
},
"computePlatform": {
"type": "string",
"title": "Compute Platform",
"description": "The compute platform for the deployment group",
"enum": [
"Server",
"Lambda",
"ECS"
]
},
"deploymentStyle": {
"type": "object",
"title": "Deployment Style",
"description": "Information about the type of deployment"
},
"autoScalingGroups": {
"type": "array",
"title": "Auto Scaling Groups",
"description": "A list of associated Auto Scaling groups",
"items": {
"type": "object"
}
},
"loadBalancerInfo": {
"type": "object",
"title": "Load Balancer Info",
"description": "Information about the load balancer used in the deployment"
},
"outdatedInstancesStrategy": {
"type": "string",
"title": "Outdated Instances Strategy",
"description": "Indicates what happens when new Amazon EC2 instances are launched",
"enum": [
"UPDATE",
"IGNORE"
]
},
"tags": {
"type": "array",
"title": "Tags",
"description": "The metadata tags associated with the deployment group",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodeDeploy Deployment Group mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodeDeploy::DeploymentGroup
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DeploymentGroupId
title: .Properties.ApplicationName + "/" + .Properties.DeploymentGroupName
blueprint: '"codedeployDeploymentGroup"'
properties:
applicationName: .Properties.ApplicationName
deploymentGroupId: .Properties.DeploymentGroupId
serviceRoleArn: .Properties.ServiceRoleArn
computePlatform: .Properties.ComputePlatform
deploymentStyle: .Properties.DeploymentStyle
autoScalingGroups: .Properties.AutoScalingGroups
loadBalancerInfo: .Properties.LoadBalancerInfo
outdatedInstancesStrategy: .Properties.OutdatedInstancesStrategy
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
## AWS::CodeDeploy::Deployment[](#awscodedeploydeployment "Direct link to AWS::CodeDeploy::Deployment")
The following example demonstrates how to ingest your AWS CodeDeploy deployments to Port.
#### CodeDeploy Deployment supported actions[](#codedeploy-deployment-supported-actions "Direct link to CodeDeploy Deployment supported actions")
The table below summarizes the available actions for ingesting AWS CodeDeploy Deployment resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------ | ---------------------------------------------------------------------- | ------- | ---------------------------- |
| [ListDeploymentsAction](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_ListDeployments.html) | Discover deployment IDs in the region. | Default | `codedeploy:ListDeployments` |
| [GetDeploymentAction](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_GetDeployment.html) | Retrieve detailed deployment data such as status, creator, and timing. | Default | `codedeploy:GetDeployment` |
All properties available by default
CodeDeploy deployments expose their key properties via the default ListDeploymentsAction and GetDeploymentAction.
You can use the following Port blueprint definitions and integration configuration:
**CodeDeploy Deployment blueprint (click to expand)**
Create in Port
```
{
"identifier": "codeDeployDeployment",
"title": "CodeDeploy Deployment",
"icon": "AWS",
"schema": {
"properties": {
"deploymentId": {
"type": "string",
"title": "Deployment ID",
"description": "The unique ID of the deployment"
},
"applicationName": {
"type": "string",
"title": "Application Name",
"description": "The name of the application"
},
"deploymentGroupName": {
"type": "string",
"title": "Deployment Group",
"description": "The name of the deployment group"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the deployment",
"enum": [
"Created",
"Queued",
"InProgress",
"Succeeded",
"Failed",
"Stopped",
"Ready"
]
},
"creator": {
"type": "string",
"title": "Creator",
"description": "The user who created the deployment"
},
"createTime": {
"type": "string",
"title": "Create Time",
"description": "The time the deployment was created",
"format": "date-time"
},
"startTime": {
"type": "string",
"title": "Start Time",
"description": "The time the deployment started",
"format": "date-time"
},
"completeTime": {
"type": "string",
"title": "Complete Time",
"description": "The time the deployment completed",
"format": "date-time"
},
"description": {
"type": "string",
"title": "Description",
"description": "A comment about the deployment"
},
"deploymentStyle": {
"type": "object",
"title": "Deployment Style",
"description": "Information about the type of deployment"
},
"region": {
"type": "string",
"title": "Region",
"description": "AWS region where the deployment is located"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodeDeploy Deployment mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodeDeploy::Deployment
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DeploymentId
title: .Properties.ApplicationName + "/" + .Properties.DeploymentGroupName + "/" + .Properties.DeploymentId
blueprint: '"codeDeployDeployment"'
properties:
deploymentId: .Properties.DeploymentId
applicationName: .Properties.ApplicationName
deploymentGroupName: .Properties.DeploymentGroupName
status: .Properties.Status
creator: .Properties.Creator
createTime: .Properties.CreateTime
startTime: .Properties.StartTime
completeTime: .Properties.CompleteTime
description: .Properties.Description
deploymentStyle: .Properties.DeploymentStyle
region: .__ExtraContext.Region
relations:
account: .__ExtraContext.AccountId
```
## AWS::CodeDeploy::DeploymentTarget[](#awscodedeploydeploymenttarget "Direct link to AWS::CodeDeploy::DeploymentTarget")
The following example demonstrates how to ingest your AWS CodeDeploy deployment targets to Port.
#### CodeDeploy Deployment Target supported actions[](#codedeploy-deployment-target-supported-actions "Direct link to CodeDeploy Deployment Target supported actions")
The table below summarizes the available actions for ingesting AWS CodeDeploy Deployment Target resources in Port:
| Action | Description | Type | Required AWS Permission |
| --------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------- | ------- | -------------------------------------------------------------------------------------------------------- |
| [GetDeploymentTargetDetailsAction](https://docs.aws.amazon.com/codedeploy/latest/APIReference/API_BatchGetDeploymentTargets.html) | Retrieve deployment target details for each deployment, including target type and platform-specific data. | Default | `codedeploy:ListDeployments`, `codedeploy:ListDeploymentTargets`, `codedeploy:BatchGetDeploymentTargets` |
Discovery flow
The integration lists deployments first, then fetches targets for each deployment. Deployments that have not started are skipped.
You can use the following Port blueprint definitions and integration configuration:
**CodeDeploy Deployment Target blueprint (click to expand)**
Create in Port
```
{
"identifier": "codedeployDeploymentTarget",
"title": "CodeDeploy Deployment Target",
"icon": "AWS",
"schema": {
"properties": {
"deploymentId": {
"type": "string",
"title": "Deployment ID",
"description": "The unique ID of the deployment"
},
"deploymentTargetType": {
"type": "string",
"title": "Deployment Target Type",
"description": "The deployment type that is specific to the deployment's compute platform",
"enum": [
"InstanceTarget",
"LambdaTarget",
"ECSTarget",
"CloudFormationTarget"
]
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodeDeploy Deployment Target mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodeDeploy::DeploymentTarget
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.DeploymentId + "/" + .Properties.TargetId
title: .Properties.DeploymentId + "/" + .Properties.TargetId
blueprint: '"codedeployDeploymentTarget"'
properties:
deploymentId: .Properties.DeploymentId
deploymentTargetType: .Properties.DeploymentTargetType
relations:
account: .__ExtraContext.AccountId
```
For more details about CodeDeploy properties, refer to the [AWS CodeDeploy API documentation](https://docs.aws.amazon.com/codedeploy/latest/APIReference/Welcome.html).
---
# AWS CodePipeline
## AWS::CodePipeline::Pipeline[](#awscodepipelinepipeline "Direct link to AWS::CodePipeline::Pipeline")
The following example demonstrates how to ingest your AWS CodePipeline pipelines to Port.
#### CodePipeline Pipeline supported actions[](#codepipeline-pipeline-supported-actions "Direct link to CodePipeline Pipeline supported actions")
The table below summarizes the available actions for ingesting AWS CodePipeline Pipeline resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------- | ------- | ---------------------------------- |
| [ListPipelinesAction](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_ListPipelines.html) | Discover CodePipeline pipelines in the region. | Default | `codepipeline:ListPipelines` |
| [GetPipelineDetailsAction](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_GetPipeline.html) | Retrieve detailed pipeline configuration such as stages, role ARN, and version. | Default | `codepipeline:GetPipeline` |
| [GetPipelineTagsAction](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_ListTagsForResource.html) | Retrieve tags for each pipeline. | Default | `codepipeline:ListTagsForResource` |
All properties available by default
CodePipeline pipelines expose their key properties, including tags, via the default actions.
You can use the following Port blueprint definitions and integration configuration:
**CodePipeline Pipeline blueprint (click to expand)**
Create in Port
```
{
"identifier": "codePipeline",
"title": "CodePipeline Pipeline",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN",
"description": "The Amazon Resource Name (ARN) of the pipeline"
},
"roleArn": {
"type": "string",
"title": "Role ARN",
"description": "The service role ARN for the pipeline"
},
"executionMode": {
"type": "string",
"title": "Execution Mode",
"description": "The execution mode of the pipeline"
},
"pipelineType": {
"type": "string",
"title": "Pipeline Type",
"description": "The type of the pipeline"
},
"version": {
"type": "number",
"title": "Version",
"description": "The version number of the pipeline"
},
"stages": {
"type": "array",
"title": "Stages",
"description": "The stages of the pipeline",
"items": {
"type": "object"
}
},
"created": {
"type": "string",
"title": "Created",
"description": "The date when the pipeline was created",
"format": "date-time"
},
"updated": {
"type": "string",
"title": "Updated",
"description": "The date when the pipeline was last updated",
"format": "date-time"
},
"tags": {
"type": "array",
"title": "Tags",
"description": "Tags associated with the pipeline",
"items": {
"type": "object"
}
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodePipeline Pipeline mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodePipeline::Pipeline
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.PipelineArn
title: .Properties.Name
blueprint: '"codePipeline"'
properties:
arn: .Properties.PipelineArn
roleArn: .Properties.RoleArn
executionMode: .Properties.ExecutionMode
pipelineType: .Properties.PipelineType
version: .Properties.Version
stages: .Properties.Stages
created: .Properties.Created
updated: .Properties.Updated
tags: .Properties.Tags
relations:
account: .__ExtraContext.AccountId
```
## AWS::CodePipeline::Stage[](#awscodepipelinestage "Direct link to AWS::CodePipeline::Stage")
The following example demonstrates how to ingest your AWS CodePipeline stages to Port.
#### CodePipeline Stage supported actions[](#codepipeline-stage-supported-actions "Direct link to CodePipeline Stage supported actions")
The table below summarizes the available actions for ingesting AWS CodePipeline Stage resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------- | ------- | -------------------------------------------------------- |
| [GetPipelineStagesAction](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_GetPipeline.html) | Discover pipeline stages by expanding each pipeline definition into individual stage records. | Default | `codepipeline:ListPipelines`, `codepipeline:GetPipeline` |
Discovery flow
The integration lists pipelines first, then expands each pipeline's `stages` array into separate stage entities with `pipelineName`, `pipelineArn`, and `order` metadata.
You can use the following Port blueprint definitions and integration configuration:
**CodePipeline Stage blueprint (click to expand)**
Create in Port
```
{
"identifier": "codePipelineStage",
"title": "CodePipeline Stage",
"icon": "AWS",
"schema": {
"properties": {
"pipelineName": {
"type": "string",
"title": "Pipeline Name",
"description": "The name of the CodePipeline pipeline this stage belongs to"
},
"pipelineArn": {
"type": "string",
"title": "Pipeline ARN",
"description": "The Amazon Resource Name (ARN) of the pipeline"
},
"actions": {
"type": "array",
"title": "Actions",
"description": "The list of actions that are part of this stage",
"items": {
"type": "object"
}
},
"name": {
"type": "string",
"title": "Name",
"description": "The name of the stage in the pipeline"
},
"order": {
"type": "number",
"title": "Order",
"description": "The sequential order of the stage within the pipeline"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodePipeline Stage mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodePipeline::Stage
selector:
query: 'true'
port:
entity:
mappings:
identifier: (.Properties.PipelineArn + "/" + .Properties.Name)
title: (.Properties.PipelineName + "/" + .Properties.Name)
blueprint: '"codePipelineStage"'
properties:
pipelineName: .Properties.PipelineName
pipelineArn: .Properties.PipelineArn
name: .Properties.Name
order: .Properties.Order
actions: .Properties.Actions
relations:
account: .__ExtraContext.AccountId
```
## AWS::CodePipeline::Action[](#awscodepipelineaction "Direct link to AWS::CodePipeline::Action")
The following example demonstrates how to ingest your AWS CodePipeline actions to Port.
#### CodePipeline Action supported actions[](#codepipeline-action-supported-actions "Direct link to CodePipeline Action supported actions")
The table below summarizes the available actions for ingesting AWS CodePipeline Action resources in Port:
| Action | Description | Type | Required AWS Permission |
| -------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------- | ------- | -------------------------------------------------------- |
| [GetPipelineActionsDetails](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_GetPipeline.html) | Discover pipeline actions by expanding each stage's `actions` array into individual action records. | Default | `codepipeline:ListPipelines`, `codepipeline:GetPipeline` |
Discovery flow
The integration lists pipelines first, then expands each stage's actions into separate action entities with `pipelineName`, `stageName`, and `pipelineArn` metadata.
You can use the following Port blueprint definitions and integration configuration:
**CodePipeline Action blueprint (click to expand)**
Create in Port
```
{
"identifier": "codePipelineAction",
"title": "CodePipeline Action",
"icon": "AWS",
"schema": {
"properties": {
"name": {
"type": "string",
"title": "Name",
"description": "The name of the action"
},
"provider": {
"type": "string",
"title": "Provider",
"description": "The action provider (e.g., S3, CodeBuild, CodeDeploy)"
},
"category": {
"type": "string",
"title": "Category",
"description": "The action category (Source, Build, Deploy, etc.)"
},
"owner": {
"type": "string",
"title": "Owner",
"description": "The action owner (AWS, ThirdParty, Custom)"
},
"version": {
"type": "string",
"title": "Version",
"description": "The action version"
},
"runOrder": {
"type": "number",
"title": "Run Order",
"description": "The order in which the action runs"
},
"configuration": {
"type": "object",
"title": "Configuration",
"description": "Action configuration parameters"
},
"inputArtifacts": {
"type": "array",
"title": "Input Artifacts",
"description": "Input artifacts for the action",
"items": {
"type": "object"
}
},
"outputArtifacts": {
"type": "array",
"title": "Output Artifacts",
"description": "Output artifacts produced by the action",
"items": {
"type": "object"
}
},
"roleArn": {
"type": "string",
"title": "Role ARN",
"description": "The ARN of the role used for the action"
},
"region": {
"type": "string",
"title": "Region",
"description": "The region where the action runs"
},
"pipelineName": {
"type": "string",
"title": "Pipeline Name",
"description": "The name of the pipeline containing this action"
},
"stageName": {
"type": "string",
"title": "Stage Name",
"description": "The name of the stage containing this action"
},
"pipelineArn": {
"type": "string",
"title": "Pipeline ARN",
"description": "The ARN of the pipeline"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodePipeline Action mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodePipeline::Action
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.PipelineArn + "/" + .Properties.StageName + "/" + .Properties.Name
title: .Properties.PipelineName + "/" + .Properties.StageName + "/" + .Properties.Name
blueprint: '"codePipelineAction"'
properties:
name: .Properties.Name
provider: .Properties.ActionTypeId.Provider
category: .Properties.ActionTypeId.Category
owner: .Properties.ActionTypeId.Owner
version: .Properties.ActionTypeId.Version
runOrder: .Properties.RunOrder
configuration: .Properties.Configuration
inputArtifacts: .Properties.InputArtifacts
outputArtifacts: .Properties.OutputArtifacts
roleArn: .Properties.RoleArn
region: .Properties.Region
pipelineName: .Properties.PipelineName
stageName: .Properties.StageName
pipelineArn: .Properties.PipelineArn
relations:
account: .__ExtraContext.AccountId
```
## AWS::CodePipeline::PipelineExecution[](#awscodepipelinepipelineexecution "Direct link to AWS::CodePipeline::PipelineExecution")
The following example demonstrates how to ingest your AWS CodePipeline pipeline executions to Port.
#### CodePipeline Pipeline Execution supported actions[](#codepipeline-pipeline-execution-supported-actions "Direct link to CodePipeline Pipeline Execution supported actions")
The table below summarizes the available actions for ingesting AWS CodePipeline Pipeline Execution resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------- | ------- | ------------------------------------------------------------------- |
| [ListPipelineExecutionsAction](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_ListPipelineExecutions.html) | Discover pipeline execution summaries for each pipeline. | Default | `codepipeline:ListPipelines`, `codepipeline:ListPipelineExecutions` |
| [GetPipelineExecutionDetailsAction](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_GetPipelineExecution.html) | Retrieve detailed execution data such as status, trigger, and artifact revisions. | Default | `codepipeline:GetPipelineExecution` |
Discovery flow
The integration lists pipelines first, then fetches executions for each pipeline.
You can use the following Port blueprint definitions and integration configuration:
**CodePipeline Pipeline Execution blueprint (click to expand)**
Create in Port
```
{
"identifier": "codePipelinePipelineExecution",
"title": "CodePipeline Pipeline Execution",
"icon": "AWS",
"schema": {
"properties": {
"pipelineName": {
"type": "string",
"title": "Pipeline Name",
"description": "The name of the pipeline"
},
"pipelineVersion": {
"type": "number",
"title": "Pipeline Version",
"description": "The version of the pipeline definition"
},
"pipelineExecutionId": {
"type": "string",
"title": "Execution ID",
"description": "The unique identifier for the pipeline execution"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the pipeline execution",
"enum": [
"InProgress",
"Stopped",
"Stopping",
"Succeeded",
"Superseded",
"Failed"
]
},
"statusSummary": {
"type": "string",
"title": "Status Summary",
"description": "A summary of the status of the pipeline execution"
},
"executionMode": {
"type": "string",
"title": "Execution Mode",
"description": "The execution mode for this pipeline execution",
"enum": [
"QUEUED",
"SUPERSEDED",
"PARALLEL"
]
},
"trigger": {
"type": "object",
"title": "Trigger",
"description": "The trigger that caused the pipeline execution"
},
"artifactRevisions": {
"type": "array",
"title": "Artifact Revisions",
"description": "A list of source code revisions for the pipeline execution",
"items": {
"type": "object"
}
},
"variables": {
"type": "array",
"items": {
"type": "object"
},
"title": "Variables",
"description": "Variables defined for the pipeline execution"
},
"lastUpdateTime": {
"type": "string",
"format": "date-time",
"title": "Last Update Time",
"description": "The time when the pipeline execution was last updated",
"dateFormat": "relative"
},
"startTime": {
"type": "string",
"format": "date-time",
"title": "StartTime",
"description": "The time when the pipeline execution started",
"dateFormat": "relative"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodePipeline Pipeline Execution mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodePipeline::PipelineExecution
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.PipelineExecutionId
title: .Properties.PipelineName + "/" + .Properties.PipelineExecutionId
blueprint: '"codePipelinePipelineExecution"'
properties:
pipelineName: .Properties.PipelineName
pipelineVersion: .Properties.PipelineVersion
pipelineExecutionId: .Properties.PipelineExecutionId
status: .Properties.Status
statusSummary: .Properties.StatusSummary
executionMode: .Properties.ExecutionMode
trigger: .Properties.Trigger
artifactRevisions: .Properties.ArtifactRevisions
variables: .Properties.Variables
startTime: .Properties.StartTime
lastUpdateTime: .Properties.LastUpdateTime
relations:
account: .__ExtraContext.AccountId
```
## AWS::CodePipeline::ActionExecution[](#awscodepipelineactionexecution "Direct link to AWS::CodePipeline::ActionExecution")
The following example demonstrates how to ingest your AWS CodePipeline action executions to Port.
#### CodePipeline Action Execution supported actions[](#codepipeline-action-execution-supported-actions "Direct link to CodePipeline Action Execution supported actions")
The table below summarizes the available actions for ingesting AWS CodePipeline Action Execution resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------------------------------------ | ----------------------------------------------------------- | ------- | ----------------------------------------------------------------- |
| [ListActionExecutionsAction](https://docs.aws.amazon.com/codepipeline/latest/APIReference/API_ListActionExecutions.html) | Discover action executions for each pipeline in the region. | Default | `codepipeline:ListPipelines`, `codepipeline:ListActionExecutions` |
Discovery flow
The integration lists pipelines first, then fetches action executions for each pipeline.
You can use the following Port blueprint definitions and integration configuration:
**CodePipeline Action Execution blueprint (click to expand)**
Create in Port
```
{
"identifier": "codePipelineActionExecution",
"title": "CodePipeline Action Execution",
"icon": "AWS",
"schema": {
"properties": {
"actionExecutionId": {
"type": "string",
"title": "Action Execution ID",
"description": "The unique ID of the action execution"
},
"actionName": {
"type": "string",
"title": "Action Name",
"description": "The name of the action"
},
"stageName": {
"type": "string",
"title": "Stage Name",
"description": "The name of the stage containing the action"
},
"pipelineExecutionId": {
"type": "string",
"title": "Pipeline Execution ID",
"description": "The pipeline execution ID associated with this action execution"
},
"pipelineVersion": {
"type": "number",
"title": "Pipeline Version",
"description": "The version of the pipeline when the action was executed"
},
"status": {
"type": "string",
"title": "Status",
"description": "The status of the action execution",
"enum": [
"InProgress",
"Abandoned",
"Succeeded",
"Failed"
]
},
"startTime": {
"type": "string",
"title": "Start Time",
"description": "The start time of the action execution",
"format": "date-time"
},
"lastUpdateTime": {
"type": "string",
"title": "Last Update Time",
"description": "The last update time of the action execution",
"format": "date-time"
},
"input": {
"type": "object",
"title": "Input",
"description": "Input details for the action execution"
},
"output": {
"type": "object",
"title": "Output",
"description": "Output details for the action execution"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**CodePipeline Action Execution mapping configuration (click to expand)**
```
resources:
- kind: AWS::CodePipeline::ActionExecution
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.ActionExecutionId
title: .Properties.ActionName + "/" + .Properties.ActionExecutionId
blueprint: '"codePipelineActionExecution"'
properties:
actionExecutionId: .Properties.ActionExecutionId
actionName: .Properties.ActionName
stageName: .Properties.StageName
pipelineExecutionId: .Properties.PipelineExecutionId
pipelineVersion: .Properties.PipelineVersion
status: .Properties.Status
startTime: .Properties.StartTime
lastUpdateTime: .Properties.LastUpdateTime
input: .Properties.Input
output: .Properties.Output
relations:
account: .__ExtraContext.AccountId
```
For more details about CodePipeline properties, refer to the [AWS CodePipeline API documentation](https://docs.aws.amazon.com/codepipeline/latest/APIReference/Welcome.html).
---
# AWS Lambda
## AWS::Lambda::Function[](#awslambdafunction "Direct link to AWS::Lambda::Function")
The following example demonstrates how to ingest your AWS Lambda functions to Port.
#### Lambda Function supported actions[](#lambda-function-supported-actions "Direct link to Lambda Function supported actions")
The table below summarizes the available actions for ingesting AWS Lambda Function resources in Port:
| Action | Description | Type | Required AWS Permission |
| ------------------------------------------------------------------------------------------- | ------------------------------------------------------ | -------- | ----------------------- |
| [ListFunctionsAction](https://docs.aws.amazon.com/lambda/latest/api/API_ListFunctions.html) | Discover all Lambda functions across your AWS account. | Default | `lambda:ListFunctions` |
| [ListTagsAction](https://docs.aws.amazon.com/lambda/latest/api/API_ListTags.html) | Retrieve tags for each function. | Optional | `lambda:ListTags` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**Lambda Function blueprint (click to expand)**
Create in Port
```
{
"identifier": "lambdaFunction",
"title": "Lambda Function",
"icon": "AWS",
"schema": {
"properties": {
"FunctionName": {
"type": "string",
"title": "Function Name",
"description": "The name of the Lambda function"
},
"FunctionArn": {
"type": "string",
"title": "Function ARN",
"description": "The Amazon Resource Name (ARN) of the Lambda function"
},
"Runtime": {
"type": "string",
"title": "Runtime",
"description": "The runtime environment for the Lambda function"
},
"Handler": {
"type": "string",
"title": "Handler",
"description": "The function entry point"
},
"MemorySize": {
"type": "number",
"title": "Memory Size",
"description": "The amount of memory available to the function in MB"
},
"Timeout": {
"type": "number",
"title": "Timeout",
"description": "The function execution time limit in seconds"
},
"State": {
"type": "string",
"title": "State",
"description": "The current state of the function"
},
"LastModified": {
"type": "string",
"title": "Last Modified",
"description": "The date and time the function was last modified"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"title": "Account",
"target": "awsAccount",
"required": false,
"many": false
}
}
}
```
**Lambda Function mapping configuration (click to expand)**
```
resources:
- kind: AWS::Lambda::Function
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.FunctionArn
title: .Properties.FunctionName
blueprint: '"lambdaFunction"'
properties:
FunctionName: .Properties.FunctionName
FunctionArn: .Properties.FunctionArn
Runtime: .Properties.Runtime
Handler: .Properties.Handler
MemorySize: .Properties.MemorySize
Timeout: .Properties.Timeout
State: .Properties.State
LastModified: .Properties.LastModified
relations:
account: .__ExtraContext.AccountId
```
For more details about Lambda function properties, refer to the [AWS Lambda API documentation](https://docs.aws.amazon.com/lambda/latest/api/welcome.html).
---
# AWS Organizations
## AWS::Organizations::Account[](#awsorganizationsaccount "Direct link to AWS::Organizations::Account")
The following example demonstrates how to ingest your AWS Organizations accounts to Port.
#### Organizations Account supported actions[](#organizations-account-supported-actions "Direct link to Organizations Account supported actions")
The table below summarizes the available actions for ingesting AWS Organizations Account resources in Port:
| Action | Description | Type | Required AWS Permission |
| ----------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------- | -------- | ----------------------------------- |
| [ListAccountsAction](https://docs.aws.amazon.com/organizations/latest/APIReference/API_ListAccounts.html) | Discover organization accounts and retrieve account metadata. | Default | `organizations:ListAccounts` |
| [ListTagsForResourceAction](https://docs.aws.amazon.com/organizations/latest/APIReference/API_ListTagsForResource.html) | Retrieve tags for the specified account. | Optional | `organizations:ListTagsForResource` |
| [ListParentsAction](https://docs.aws.amazon.com/organizations/latest/APIReference/API_ListParents.html) | Retrieve parent information for the specified account. | Optional | `organizations:ListParents` |
Optional Properties Note
Properties of optional actions will not appear in the response unless you explicitly include the action that provides them in your configuration.
You can use the following Port blueprint definitions and integration configuration:
**Organizations Account blueprint (click to expand)**
Create in Port
```
{
"identifier": "awsOrganizationAccount",
"description": "This blueprint represents an AWS Organizations Account in our software catalog",
"title": "Organizations Account",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN"
},
"email": {
"type": "string",
"title": "Email"
},
"status": {
"type": "string",
"title": "Status"
},
"joinedTimestamp": {
"type": "string",
"title": "Joined Timestamp"
},
"joinedMethod": {
"type": "string",
"title": "Joined Method"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
**Organizations Account mapping configuration (click to expand)**
```
resources:
- kind: AWS::Organizations::Account
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Properties.Id
title: .Properties.AccountName
blueprint: '"awsOrganizationAccount"'
properties:
arn: .Properties.Arn
email: .Properties.Email
status: .Properties.Status
joinedTimestamp: .Properties.JoinedTimestamp
joinedMethod: .Properties.JoinedMethod
```
For more details about Organizations accounts, refer to the [AWS Organizations API documentation](https://docs.aws.amazon.com/organizations/latest/APIReference/Welcome.html).
---
# AWS Legacy

Loading version...
Port's AWS Legacy integration allows you to import your AWS resources into Port, according to your configuration. After the initial import of data, the integration will also listen to live events from AWS to update data in Port in real time.
Supported resources [AWS::Organizations::Account](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-organizations-account.html)[AWS::ImageBuilder::Image](https://docs.aws.amazon.com/AWSCloudFormation/latest/TemplateReference/aws-resource-imagebuilder-image.html)[AWS::ACM::Certificate](https://docs.aws.amazon.com/AWSCloudFormation/latest/TemplateReference/aws-resource-certificatemanager-certificate.html)[AWS::CloudFormation::Stack](https://docs.aws.amazon.com/AWSCloudFormation/latest/TemplateReference/aws-resource-cloudformation-stack.html)[AWS::ElastiCache::Cluster](https://docs.aws.amazon.com/AWSCloudFormation/latest/TemplateReference/aws-resource-elasticache-cachecluster.html)[AWS::ELBV2::LoadBalancer](https://docs.aws.amazon.com/AWSCloudFormation/latest/TemplateReference/aws-resource-elasticloadbalancingv2-loadbalancer.html)[AWS::SQS::Queue](https://docs.aws.amazon.com/AWSCloudFormation/latest/TemplateReference/aws-resource-sqs-queue.html)[AWS::ResourceGroups::Group](https://docs.aws.amazon.com/AWSCloudFormation/latest/TemplateReference/aws-resource-resourcegroups-group.html)[AWS::S3::Bucket](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-s3-bucket.html)[AWS::EC2::Instance](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ec2-instance.html)[AWS::ECS::Cluster](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-resource-ecs-cluster.html)
## Core support
[Live eventsSee supported resources](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/live-events/.md)
## Common use cases[](#common-use-cases "Direct link to Common use cases")
Easily fill your software catalog with data directly from your AWS Organization, for example:
* Map all the resources in your AWS Accounts, including **ECS Clusters**, **S3 Buckets**, **EC2 Instances** and other AWS objects.
* Watch for AWS resources changes (create/update/delete) in real-time, and automatically apply the changes to your entities in Port.
* Use relations to create complete, easily digestible views of your AWS infrastructure inside Port.
## How it works[](#how-it-works "Direct link to How it works")
Port's AWS integration can retrieve all the resources supported by the [Cloud Control API](https://docs.aws.amazon.com/cloudcontrolapi/latest/userguide/supported-resources.html), and export them to Port as entities of existing blueprints.
The AWS integration allows you to perform extract, transform, load (ETL) on data from the Cloud Control API into the desired software catalog data model.
## Setup[](#setup "Direct link to Setup")
Choose one of the following installation methods:
1Helm2Prerequisites3IAM User4Install
Helm (scheduled)
* ✧Deploy on Kubernetes using Helm
* ✧Multiple authentication methods (IAM User, IRSA)
* ✧Scheduled resyncs of resources from AWS to Port
Terraform (real-time)
* ✧Deploy using Infrastructure as Code
* ✧Real-time updates via event-based triggers
* ✧Reproducible and version-controlled deployments
Docker (one-time)
* ✧Run as a Docker container on any platform
* ✧One-time or on-demand execution
* ✧Minimal setup requirements
Prerequisites
Additional setup guides
* **[Multiple account support](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/multi_account/.md)** : enable the integration to collect data from multiple AWS accounts.
* **[Live events](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/live-events/.md)** : set up real-time event processing after completing the installation.
### Recommended resource sizes
To ensure optimal performance and avoid out-of-memory (OOM) errors, we recommend the following resources for this integration:
* **CPU Limit**: `800m`
* **CPU Request**: `200m`
* **Memory Limit**: `2Gi`
* **Memory Request**: `2Gi`
Set resource values using the commands below:
```
helm install my-integration port-labs/port-ocean \
# ... other parameters
--set ocean.resources.limits.cpu=800m \
--set ocean.resources.limits.memory=2Gi \
--set ocean.resources.requests.cpu=200m \
--set ocean.resources.requests.memory=2Gi
```
## Configuration[](#configuration "Direct link to Configuration")
Port integrations use a [YAML mapping block](/context-lake/ingestion/configure-mapping/configuration-methods/.md#configuration-structure) to ingest data from the third-party api into Port.
The mapping makes use of the [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
### Default mapping configuration[](#default-mapping-configuration "Direct link to Default mapping configuration")
This is the default mapping configuration you get after installing the AWS Legacy integration.
**Default mapping configuration (click to expand)**
```
resources:
- kind: AWS::Organizations::Account
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"awsAccount"'
properties:
arn: .Arn
email: .Email
status: .Status
joined_method: .JoinedMethod
joined_timestamp: .JoinedTimestamp | sub(" "; "T")
- kind: AWS::S3::Bucket
selector:
query: 'true'
useGetResourceAPI: 'true'
port:
entity:
mappings:
identifier: .Identifier
title: .Identifier
blueprint: '"cloudResource"'
properties:
kind: .__Kind
region: .Properties.RegionalDomainName | capture(".*\\.(?[^\\.]+)\\.amazonaws\\.com")
| .region
tags: .Properties.Tags
arn: .Properties.Arn
link: .Properties | select(.Arn != null) | "https://console.aws.amazon.com/go/view?arn="
+ .Arn
relations:
account: .__AccountId
- kind: AWS::EC2::Instance
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Identifier
title: .Identifier
blueprint: '"cloudResource"'
properties:
kind: .__Kind
region: .__Region
tags: .Properties.Tags
arn: .Properties.Arn
link: .Properties | select(.Arn != null) | "https://console.aws.amazon.com/go/view?arn="
+ .Arn
relations:
account: .__AccountId
- kind: AWS::ECS::Cluster
selector:
query: 'true'
useGetResourceAPI: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Identifier
blueprint: '"cloudResource"'
properties:
kind: .__Kind
region: .__Region
tags: .Properties.Tags
arn: .Properties.Arn
link: .Properties | select(.Arn != null) | "https://console.aws.amazon.com/go/view?arn="
+ .Arn
relations:
account: .__AccountId
```
## Monitoring and sync status[](#monitoring-and-sync-status "Direct link to Monitoring and sync status")
To learn more about how to monitor and check the sync status of your integration, see the [relevant documentation](/context-lake/ingestion/ingest-data-into-port/native-integrations/sync-mechanisms/full-resync/.md#monitoring-and-sync-status).
## Mapping & selectors per resource[](#mapping--selectors-per-resource "Direct link to Mapping & selectors per resource")
Use the explorer below to view the mapping and blueprint definition for each resource type. For additional resources and advanced configurations, see the [examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/examples/.md) page.
AWS AccountS3 BucketEC2 InstanceECS Cluster
BlueprintJSON
Create in Port
```
{
"identifier": "awsAccount",
"title": "AWS Account",
"icon": "AWS",
"schema": {
"properties": {
"arn": {
"type": "string",
"title": "ARN"
},
"email": {
"type": "string",
"title": "Email"
},
"status": {
"type": "string",
"title": "Status",
"enum": ["ACTIVE", "SUSPENDED", "PENDING_CLOSURE"],
"enumColors": {
"ACTIVE": "green",
"SUSPENDED": "red",
"PENDING_CLOSURE": "yellow"
}
},
"joined_method": {
"type": "string",
"title": "Joined Method",
"enum": ["INVITED", "CREATED"]
},
"joined_timestamp": {
"type": "string",
"title": "Joined Timestamp",
"format": "date-time"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {}
}
```
Mapping configurationYAML
```
- kind: AWS::Organizations::Account
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Id
title: .Name
blueprint: '"awsAccount"'
properties:
arn: .Arn
email: .Email
status: .Status
joined_method: .JoinedMethod
joined_timestamp: .JoinedTimestamp | sub(" "; "T")
```
BlueprintJSON
Create in Port
```
{
"identifier": "cloudResource",
"title": "Cloud Resource",
"icon": "AWS",
"schema": {
"properties": {
"kind": {
"type": "string",
"title": "Kind"
},
"region": {
"type": "string",
"title": "Region"
},
"tags": {
"type": "array",
"title": "Tags"
},
"arn": {
"type": "string",
"title": "ARN"
},
"link": {
"type": "string",
"title": "Link",
"format": "url"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"target": "awsAccount",
"title": "Account",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::S3::Bucket
selector:
query: 'true'
useGetResourceAPI: 'true'
port:
entity:
mappings:
identifier: .Identifier
title: .Identifier
blueprint: '"cloudResource"'
properties:
kind: .__Kind
region: .Properties.RegionalDomainName | capture(".*\\.(?[^\\.]+)\\.amazonaws\\.com")
| .region
tags: .Properties.Tags
arn: .Properties.Arn
link: .Properties | select(.Arn != null) | "https://console.aws.amazon.com/go/view?arn="
+ .Arn
relations:
account: .__AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "cloudResource",
"title": "Cloud Resource",
"icon": "AWS",
"schema": {
"properties": {
"kind": {
"type": "string",
"title": "Kind"
},
"region": {
"type": "string",
"title": "Region"
},
"tags": {
"type": "array",
"title": "Tags"
},
"arn": {
"type": "string",
"title": "ARN"
},
"link": {
"type": "string",
"title": "Link",
"format": "url"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"target": "awsAccount",
"title": "Account",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::EC2::Instance
selector:
query: 'true'
port:
entity:
mappings:
identifier: .Identifier
title: .Identifier
blueprint: '"cloudResource"'
properties:
kind: .__Kind
region: .__Region
tags: .Properties.Tags
arn: .Properties.Arn
link: .Properties | select(.Arn != null) | "https://console.aws.amazon.com/go/view?arn="
+ .Arn
relations:
account: .__AccountId
```
BlueprintJSON
Create in Port
```
{
"identifier": "cloudResource",
"title": "Cloud Resource",
"icon": "AWS",
"schema": {
"properties": {
"kind": {
"type": "string",
"title": "Kind"
},
"region": {
"type": "string",
"title": "Region"
},
"tags": {
"type": "array",
"title": "Tags"
},
"arn": {
"type": "string",
"title": "ARN"
},
"link": {
"type": "string",
"title": "Link",
"format": "url"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"aggregationProperties": {},
"relations": {
"account": {
"target": "awsAccount",
"title": "Account",
"required": false,
"many": false
}
}
}
```
Mapping configurationYAML
```
- kind: AWS::ECS::Cluster
selector:
query: 'true'
useGetResourceAPI: 'true'
port:
entity:
mappings:
identifier: .Properties.Arn
title: .Identifier
blueprint: '"cloudResource"'
properties:
kind: .__Kind
region: .__Region
tags: .Properties.Tags
arn: .Properties.Arn
link: .Properties | select(.Arn != null) | "https://console.aws.amazon.com/go/view?arn="
+ .Arn
relations:
account: .__AccountId
```
## Further examples[](#further-examples "Direct link to Further examples")
Refer to the [examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/examples/.md) page for practical configurations and their corresponding blueprint definitions.
---
# AWS exporter
Deprecated
This exporter is deprecated, Port will discontinue support for organizations using it by Q2 2025.
To integrate Port with AWS, use the [Ocean AWS integration](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/.md).
Port's AWS integration provides the ability to export your AWS resources to Port, according to your configuration. You can define the integration to run both on schedule and on events.
The integration supports real-time event processing, this allows for an accurate **real-time** representation of your AWS infrastructure inside Port.
View the source code
Port's AWS exporter is open source, view the source code [**here**](https://github.com/port-labs/port-aws-exporter).
## Common use cases[](#common-use-cases "Direct link to Common use cases")
Our AWS exporter allows you to easily enrich your software catalog with data from your AWS accounts, for instance:
* Map resources in your accounts, including **S3 buckets**, **lambda functions**, **SQS queues**, **RDS DB instances**, **ECS services** and many other resource types.
* Use relations to create a complete, easily digestible map of your AWS accounts inside Port.
## How it works[](#how-it-works "Direct link to How it works")
Port's AWS exporter can retrieve all the resources supported by the [AWS Cloud Control API](https://docs.aws.amazon.com/cloudcontrolapi/latest/userguide/supported-resources.html).
The open source AWS exporter allows you to perform extract, transform, load (ETL) on data from AWS into the desired software catalog data model.
The exporter is deployed using an [AWS serverless application](https://aws.amazon.com/serverless/sam/) that is installed on the account.
[The serverless application](#exporter-aws-serverless-application) requires a [JSON configuration file](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/.md#exporter-configjson-file) to describe the ETL process to load data into the developer portal, and an [IAM policy](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/.md#iam-policy) with the necessary permissions to list and read the configured resources.
The exporter makes use of [JQ JSON processor](https://stedolan.github.io/jq/manual/) to select, modify, concatenate, transform and perform other operations on existing fields and values from the AWS objects.
### Exporter `config.json` file[](#exporter-configjson-file "Direct link to exporter-configjson-file")
The `config.json` file is how you specify the exact resources you want to export from your AWS account, and also which entities and which properties in Port, you want to fill in with data.
Here is an example snippet of the `config.json` file which demonstrates the ETL process for getting `lambda functions` data from the account into the software catalog:
**config.json example (click to expand)**
```
{
"resources": [
{
"kind": "AWS::Lambda::Function",
"selector": {
"aws": {
"regions": ["us-east-1", "us-west-1"]
}
},
"port": {
"entity": {
"mappings": [
{
"identifier": ".FunctionName",
"title": ".FunctionName",
"blueprint": "function",
"properties": {
"memory": ".MemorySize",
"timeout": ".Timeout",
"runtime": ".Runtime"
}
}
]
}
}
}
]
}
```
#### Structure[](#structure "Direct link to Structure")
* The root key of the `config.json` file is the `resources` key.
* The `kind` key is a specifier for a resource type from the AWS Cloud Control API following the `service-provider::service-name::data-type-name` format:
```
"resources": [
{
"kind": "AWS::Lambda::Function",
...
```
List supported resource types
To generate a list of supported resource types using AWS CLI, combine the results of the following commands:
```
aws cloudformation list-types --type RESOURCE --visibility PUBLIC --provisioning-type FULLY_MUTABLE
aws cloudformation list-types --type RESOURCE --visibility PUBLIC --provisioning-type IMMUTABLE
aws cloudformation list-types --type RESOURCE --visibility PRIVATE --provisioning-type FULLY_MUTABLE
aws cloudformation list-types --type RESOURCE --visibility PRIVATE --provisioning-type IMMUTABLE
```
To determine if a specific `` is supported, use this command (JQ required, output is `true` or `false`):
```
aws cloudformation describe-type --type RESOURCE --type-name --query "ProvisioningType" | jq -c '. == "FULLY_MUTABLE" or . == "IMMUTABLE"'
```
For more information, read [**here**](https://docs.aws.amazon.com/cloudcontrolapi/latest/userguide/resource-types.html#resource-types-determine-support).
* The `selector` key lets you filter exactly which objects from the specified `kind` will be ingested to the software catalog.
* The `query` key in the `selector` is a JQ boolean query. If evaluated to false for an object, the object will not be synced.
* The `aws` key in the `selector` lets you specify a list of `regions` to sync from.
```
"resources": [
{
"kind": "AWS::Lambda::Function",
"selector": {
"query": "true",
"aws": {
"regions": [
"us-east-1",
"us-west-1"
]
}
},
"port":
...
```
Multi-region support
You can choose to deploy the exporter per region, or in one region of your choice. The `regions` configuration key might be useful if you want to install the exporter in one region, but to export data from multiple regions.
Some example use cases:
* To sync all objects from the specified `kind` in the default region, do not specify a `selector`.
* To sync all lambdas that are not owned by AWS Amplify service:
```
query: .FunctionName | startswith("amplify") | not
```
Special resources
For some resources you have to provide additional information. For example, in order to sync all `AWS ELB Listeners` of a specific load balancer, use the `regions_config` and `resources_models` keys:
```
"selector": {
"aws": {
"regions": [
"eu-west-1"
],
"regions_config": {
"eu-west-1": {
"resources_models": [
"{\"LoadBalancerArn\": \"\"}"
]
}
}
}
}
```
The table of the special resources with the required properties can be found [here](https://docs.aws.amazon.com/cloudcontrolapi/latest/userguide/resource-operations-list.html#resource-operations-list-containers).
* The `port`, `entity` and the `mappings` keys open the section used to map the AWS resource fields to Port entities, the `mappings` key is an array where each object matches the structure of an [entity](/context-lake/ingestion/ingest-data-into-port/native-integrations/overview/.md#entity-json-structure).
* Each mapping value is a JQ query, except for `blueprint` which has to be a static string.
* The `itemsToParse` key in a mapping makes it possible to create multiple entities from a single AWS resource.
* Any JQ expression can be used here, as long as it evaluates to an array of items.
* `item` will be added to the JQ context as a key containing a reference to items in the array specified in `itemsToParse`. For an array of objects, keys from an object can be accessed using the `.item.KEY_NAME` syntax.
```
"resources": [
{
"kind": "AWS::Lambda::Function",
"selector": {
"aws": {
"regions": [
"us-east-1",
"us-west-1"
]
}
},
"port": {
"entity": {
"mappings": [
{
"identifier": ".FunctionName",
"title": ".FunctionName",
"blueprint": "function",
"properties": {
"memory": ".MemorySize",
"timeout": ".Timeout",
"runtime": ".Runtime"
}
},
{
"itemsToParse": ".Layers",
"identifier": ".item",
"title": ".item",
"blueprint": "functionLayer",
"properties": {}
}
]
}
}
}
...
```
Important
* **The order of the resources matters** when you have relations between resources. The AWS exporter will sync the resources in the same order as they appear in the `config.json`, so make sure to sort the resources by a logical order.
For example, if you have a relation from SNS Topic to lambda function, put the Lambda function configuration first.
* By its nature, the AWS exporter will keep the values of unmapped properties untouched. Go [here](/context-lake/ingestion/ingest-data-into-port/api/ingest-via-api-overview/.md?operation=create-update#usage) for further explanation about different entity creation strategies.
To view a resource type schema and use it to compose a mapping, use [this](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/aws-template-resource-type-ref.html) reference.
Note that not all of the resource types listed in the reference are available for use with the Cloud Control API. A method to determine if a resource type is available is discussed [here](#structure).
For additional options and information, read [here](https://docs.aws.amazon.com/cloudcontrolapi/latest/userguide/resource-types.html#resource-types-schemas).
#### Changing the configuration[](#changing-the-configuration "Direct link to Changing the configuration")
By default, the exporter saves a preconfigured `config.json` file to an [AWS S3 bucket](https://docs.aws.amazon.com/AmazonS3/latest/userguide/UsingBucket.html) upon installation. The S3 bucket is named `port-aws-exporter--`, and is created by the exporter.
To make a change to the configuration (e.g. change the mapping of a certain property):
1. Create a copy of the `config.json` file from the bucket, make the desired changes, and save it locally.
2. Use the AWS CLI to upload the file to the bucket, replacing the existing file. Replace `` and `` with your values, then run the following command:
```
aws s3api put-object --bucket "" --key "config.json" --body ""
```
### IAM policy[](#iam-policy "Direct link to IAM policy")
The AWS exporter uses an [AWS IAM policy](https://docs.aws.amazon.com/IAM/latest/UserGuide/access_policies.html) which specifies the permissions to `list` and `read` the AWS resources you want to export (the ones you configured in the [`config.json`](#exporter-configjson-file)).
For example, in order to export `lambda functions`, you need to create a policy with the following definition:
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"lambda:GetFunction",
"lambda:GetFunctionCodeSigningConfig",
"lambda:ListFunctions"
],
"Resource": "*"
}
]
}
```
Find resource actions for policy
In order to find the resource actions that should be added to the policy, you should view the resource type schema, and locate the permissions for the **read** and **list** `handlers`.
Use the following command to get the resource action for a specific `` (AWS CLI and JQ required):
```
aws cloudformation describe-type --type RESOURCE --type-name --query "Schema" | jq -c 'fromjson | .handlers | with_entries(select([.key] | inside(["list", "read"]))) | map(.permissions) | flatten'
```
More details can be found [here](https://docs.aws.amazon.com/cloudcontrolapi/latest/userguide/resource-types.html#resource-types-schemas).
### Port credentials secret[](#port-credentials-secret "Direct link to Port credentials secret")
In order to manage entities in Port, the exporter needs access to your Port credentials, these are provided to the exporter via an [AWS Secrets Manager](https://docs.aws.amazon.com/secretsmanager/latest/userguide/intro.html) secret.
The secret value should be in the following format:
```
{ "id": "", "clientSecret": "" }
```
Similarly to the bucket, you can create and manage your own secret, or delegate it to the exporter. Either way, you need to add Port's credentials to the secret on your own, when the secret is ready.
### Exporter AWS serverless application[](#exporter-aws-serverless-application "Direct link to Exporter AWS serverless application")
The `Exporter AWS serverless application` is how you install the exporter's [CloudFormation stack](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/stacks.html).
The stack consists of several components:
* [S3 bucket](#changing-the-configuration) — where the [`config.json`](#exporter-configjson-file) should be saved.
* [ASM secret](#port-credentials-secret) — where you should save your Port credentials (client id and secret), to allow the exporter to interact with Port's API.
* [Lambda function](https://docs.aws.amazon.com/lambda/latest/dg/gettingstarted-concepts.html#gettingstarted-concepts-function) — a resource that you can invoke to run the exporter code. The [IAM policy](#iam-policy) is attached to the execution role of the Lambda function.
* [SQS queue](https://docs.aws.amazon.com/AWSSimpleQueueService/latest/SQSDeveloperGuide/welcome.html) — a queue of events, to be consumed by the exporter. Read [here](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/event-based-updates/.md) to learn how to use the exporter to consume and act on live events from different AWS services.
* [EventsBridge scheduled rule](https://docs.aws.amazon.com/eventbridge/latest/userguide/eb-create-rule-schedule.html) — a rule to run the exporter on a schedule.
## Getting started[](#getting-started "Direct link to Getting started")
Continue to the [installation](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/installation/.md) section to setup the AWS exporter in your Port environment.
---
# Event-based updates
Our AWS integration allows you to trigger a sync of your AWS resources with Port based on real-time events (in addition to the standard scheduled sync). As a result, your software catalog will be updated shortly after a resource is created, updated or deleted.
## How it works[](#how-it-works "Direct link to How it works")
Many AWS services emit events to [AWS EventBridge](https://aws.amazon.com/eventbridge/) service, to the account’s default event bus. Furthermore, the [AWS CloudTrail](https://aws.amazon.com/cloudtrail/) service automatically emits events for API calls from most AWS services.
A user can create an [AWS EventBridge rule](https://docs.aws.amazon.com/eventbridge/latest/userguide/eb-rules.html) to consume and transform particular events, and send them to a target, such as an [AWS SQS Queue](https://aws.amazon.com/sqs/).
[The AWS exporter application](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/.md#exporter-aws-serverless-application) creates an SQS Queue as part of its installation process, and configures it as an event source for the exporter's lambda.
This allows you to set up an event rule, that consumes any events from the bus and sends them to the AWS exporter's queue.
Each event will have to be transformed as part of the event rule, before reaching the queue, to suit the exporter's lambda expected event structure. The transformation goal is to map an event to a single AWS resource, that the exporter can handle.
The events in the queue are consumed automatically by the exporter's lambda, that will sync the updated state of the relevant AWS resources with Port.
### Input structure for a single event[](#input-structure-for-a-single-event "Direct link to Input structure for a single event")
The AWS exporter's lambda accepts JSON events with the following structure:
* `resource_type` - a hardcoded string representing the AWS resource type that is configured in the [`config.json`](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/.md#exporter-configjson-file) of the AWS Exporter.
* `region` - a JQ query to get the region from the event, usually the value will be `"\"\""`.
* `action` (Optional, defaults to `upsert`) - a JQ query to define the desired action: `upsert` or `delete` the Port entity of the matching resource. Will usually be based on the event name, like in the example below.
* `identifier` - a JQ query to calculate the resource identifier. In case the action is `upsert`, it should be the AWS Cloud Control API resource identifier. Otherwise, for `delete` actions, it should be the Port entity identifier. It is recommended to use a Port entity identifier that is identical to the Cloud Control API resource identifier (when applicable), this will make it possible to use the same event rule both for upsert and delete events (while also saving the need for complex JQ filtering patterns).
An example for such a JSON event:
```
{
"requestFunctionName": "",
"responseFunctionName": "",
"eventName": "",
"resource_type": "AWS::Lambda::Function",
"region": "\"\"",
"action": "if .eventName | startswith(\"Delete\") then \"delete\" else \"upsert\" end",
"identifier": "if .responseFunctionName != \"\" then .responseFunctionName else .requestFunctionName end"
}
```
Find the identifier formula
To get the identifier formula of a specific resource type, like `AWS::Lambda::Function`, you can use the following command:
```
aws cloudformation describe-type --type RESOURCE --type-name AWS::Lambda::Function --query "Schema" | jq 'fromjson | .primaryIdentifier | join("|")'
# Result
"/properties/FunctionName"
```
Here you can see that the identifier of a lambda function is the function name.
Another example, for the `AWS::ECS::Service` resource type:
```
aws cloudformation describe-type --type RESOURCE --type-name AWS::ECS::Service --query "Schema" | jq 'fromjson | .primaryIdentifier | join("|")'
# Result
"/properties/ServiceArn|/properties/Cluster"
```
Here you have two properties in the formula: `/properties/ServiceArn` and `/properties/Cluster`. When there are multiple properties, the values in the identifier are separated by `|`.
For more information, read [**here**](https://docs.aws.amazon.com/cloudcontrolapi/latest/userguide/resource-identifier.html).
### Event rule[](#event-rule "Direct link to Event rule")
#### Definition[](#definition "Direct link to Definition")
The event rule is how you specify the exact events you want to consume, and define the target to send the modified event to (including the transformation to the input).
Before diving deep into the [event rule properties](#properties), here is a complete example of a `CloudFormation YAML template` to manage an event rule, for the AWS Exporter:
```
AWSTemplateFormatVersion: '2010-09-09'
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: '^[a-zA-Z][-a-zA-Z0-9]*$'
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.lambda
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- lambda.amazonaws.com
eventName:
- prefix: UpdateFunctionConfiguration
- prefix: CreateFunction
- prefix: DeleteFunction
Name: port-aws-exporter-sync-lambda-trails
State: ENABLED
Targets:
- Id: 'PortAWSExporterEventsQueue'
Arn:
{
'Fn::ImportValue':
{ 'Fn::Sub': '${PortAWSExporterStackName}-EventsQueueARN' },
}
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestFunctionName: $.detail.requestParameters.functionName
responseFunctionName: $.detail.responseElements.functionName
InputTemplate: |-
{
"resource_type": "AWS::Lambda::Function",
"requestFunctionName": "",
"responseFunctionName": "",
"eventName": "",
"region": "\"\"",
"identifier": "if .responseFunctionName != \"\" then .responseFunctionName else .requestFunctionName end",
"action": "if .eventName | startswith(\"Delete\") then \"delete\" else \"upsert\" end"
}
```
About this example
This example of CloudFormation stack can be used to act on changes of lambda functions. Moreover, it includes a parameter called `PortAWSExporterStackName`, that refers to the main exporter's stack name. That way, we can send the events to the existing exporter's events queue, to sync relevant AWS resources.
#### Properties[](#properties "Direct link to Properties")
Let's review the properties of the event rule resource from above.
* The `EventBusName` property value is `default`, as this is the bus that gets events from various AWS services automatically:
```
Properties:
EventBusName: default
...
```
* The `EventPattern` property defines which events to consume, including which event sources to process, which filters to apply based on the event structure. Here, we define the event pattern to consume Cloudtrail API calls, sourced from the lambda service; On top of that, we filter only the `UpdateFunctionConfiguration`, `CreateFunction` and `DeleteFunction` events:
```
Properties:
EventBusName: default
EventPattern:
source:
- aws.lambda
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- lambda.amazonaws.com
eventName:
- prefix: UpdateFunctionConfiguration
- prefix: CreateFunction
- prefix: DeleteFunction
```
Compose an event pattern
For composing an event pattern, learn more about events from AWS services, including different sources and event names [here](https://docs.aws.amazon.com/eventbridge/latest/userguide/eb-service-event.html).
For supported services in CloudTrail, click [here](https://docs.aws.amazon.com/awscloudtrail/latest/userguide/cloudtrail-aws-service-specific-topics.html).
* The `Targets` property defines the targets of the produced events. For the AWS exporter, we want to configure its own event queue as the target:
```
Properties:
...
Targets:
- Id: "PortAWSExporterEventsQueue"
Arn: { "Fn::ImportValue" : {"Fn::Sub": "${PortAWSExporterStackName}-EventsQueueARN" } }
...
```
* The `InputTransformer` key in the `Targets` property defines the transformation that will be applied to the event, before sending it to the target queue.
```
Properties:
...
Targets:
- Id: "PortAWSExporterEventsQueue"
Arn: { "Fn::ImportValue" : {"Fn::Sub": "${PortAWSExporterStackName}-EventsQueueARN" } }
InputTransformer:
...
```
* The `InputPathsMap` key in `InputTransformer` defines which fields to extract from the event. It makes use of [`JSONPath`](https://goessner.net/articles/JsonPath/index.html) syntax to configure the extraction:
```
Properties:
...
Targets:
- Id: "PortAWSExporterEventsQueue"
Arn: { "Fn::ImportValue" : {"Fn::Sub": "${PortAWSExporterStackName}-EventsQueueARN" } }
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestFunctionName: $.detail.requestParameters.functionName
responseFunctionName: $.detail.responseElements.functionName
...
```
For instance, the event sent to the EventBridge bus for the `CreateFunction` lambda API call has the following structure:
```
{
...
"detail": {
...
"eventSource": "lambda.amazonaws.com",
"eventName": "CreateFunction20150331",
"awsRegion": "eu-west-1",
...
"requestParameters": {
"functionName": "test-function",
...
},
"responseElements": {
"functionName": "test-function",
...
},
...
}
}
```
The `InputPathsMap` in the example below will extract only the `awsRegion`, `eventName`, and `functionName` from the API request and response.
* The `InputTemplate` key in `InputTransformer` defines a template of the final input that will be sent to the target queue, in the format the exporter's lambda [expects](#input-structure-for-a-single-event). The template is rendered using the values from the `InputPathsMap`:
```
Properties:
...
Targets:
- Id: "PortAWSExporterEventsQueue"
Arn: { "Fn::ImportValue" : {"Fn::Sub": "${PortAWSExporterStackName}-EventsQueueARN" } }
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestFunctionName: $.detail.requestParameters.functionName
responseFunctionName: $.detail.responseElements.functionName
InputTemplate: |-
{
"resource_type": "AWS::Lambda::Function",
"requestFunctionName": "",
"responseFunctionName": "",
"eventName": "",
"region": "\"\"",
"identifier": "if .responseFunctionName != \"\" then .responseFunctionName else .requestFunctionName end",
"action": "if .eventName | startswith(\"Delete\") then \"delete\" else \"upsert\" end"
}
```
Here, the `InputTemplate` takes the information extracted in the `InputPathsMap`, and constructs a message that will be sent to the SQS queue and consumed by the exporter’s lambda. The message includes:
* The hardcoded resource type (`AWS::Lambda::Function`).
* The `awsRegion` from the event.
* A JQ query to figure out the action (`upsert` or `delete` the Port entity), based on the `eventName`.
* A JQ query to calculate the identifier, based on the function name from the API response or request.
Learn more
To read more about input transformer in EventBridge, click [here](https://docs.aws.amazon.com/eventbridge/latest/userguide/eb-transform-target-input.html).
## Next steps[](#next-steps "Direct link to Next steps")
### Examples[](#examples "Direct link to Examples")
* Refer to the [examples](/context-lake/ingestion/ingest-data-into-port/native-integrations/available-integrations/cloud-providers/aws/aws-exporter/examples/.md) page for practical configurations and their corresponding blueprint definitions.
* Refer to the Event Bridge rule [Terraform example](https://github.com/port-labs/terraform-aws-port-exporter/tree/main/examples/terraform_deploy_eventbridge_rule).
---
# Examples
Use the index on the right side of the page to find an example for the resource/s you’re looking to export.
## ECS clusters and ECS services[](#ecs-clusters-and-ecs-services "Direct link to ECS clusters and ECS services")
In this step-by-step example, you will export your `ECS clusters` and `ECS services` to Port.
1. Create the following Port blueprint:
* **ECS Cluster** - will represent ECS clusters from the AWS account.
* **ECS Service** - will represent ECS services from the AWS account.
You may use the following definitions:
**ECS Cluster blueprint (click to expand)**
Create in Port
```
{
"identifier": "ecsCluster",
"description": "This blueprint represents an AWS ECS Cluster in our software catalog",
"title": "ECS Cluster",
"icon": "AWS",
"schema": {
"properties": {
"link": {
"type": "string",
"format": "url",
"title": "Link"
},
"capacityProviders": {
"type": "array",
"title": "Capacity Providers"
},
"defaultCapacityProviderStrategy": {
"type": "array",
"title": "Default Capacity Provider Strategy"
},
"clusterSettings": {
"type": "array",
"title": "Cluster Settings"
},
"tags": {
"type": "array",
"title": "Tags"
},
"arn": {
"type": "string",
"title": "ARN"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
**ECS Service blueprint (click to expand)**
Create in Port
```
{
"identifier": "ecsService",
"description": "This blueprint represents an AWS ECS Service in our software catalog",
"title": "ECS Service",
"icon": "Service",
"schema": {
"properties": {
"link": {
"type": "string",
"format": "url",
"title": "Link"
},
"desiredCount": {
"type": "number",
"title": "Desired Count"
},
"taskDefinition": {
"type": "string",
"title": "Task Definition"
},
"launchType": {
"type": "string",
"enum": ["EC2", "FARGATE", "EXTERNAL"],
"title": "Launch Type"
},
"schedulingStrategy": {
"type": "string",
"enum": ["REPLICA", "DAEMON"],
"title": "Scheduling Strategy"
},
"loadBalancers": {
"type": "array",
"title": "Load Balancers"
},
"securityGroups": {
"type": "array",
"title": "Security Groups"
},
"subnets": {
"type": "array",
"title": "Subnets"
},
"iamRole": {
"type": "string",
"format": "url",
"title": "IAM Role",
"icon": "Unlock"
},
"arn": {
"type": "string",
"title": "ARN"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {
"ecsCluster": {
"target": "ecsCluster",
"many": false,
"required": false
}
}
}
```
2. Upload the `config.json` file to the exporter's S3 bucket:
**Port AWS exporter config.json (click to expand)**
```
{
"resources": [
{
"kind": "AWS::ECS::Cluster",
"port": {
"entity": {
"mappings": [
{
"identifier": ".ClusterName",
"title": ".ClusterName",
"blueprint": "ecsCluster",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=\" + .Arn",
"capacityProviders": ".CapacityProviders",
"defaultCapacityProviderStrategy": ".DefaultCapacityProviderStrategy",
"clusterSettings": ".ClusterSettings",
"tags": ".Tags",
"arn": ".Arn"
}
}
]
}
}
},
{
"kind": "AWS::ECS::Service",
"port": {
"entity": {
"mappings": [
{
"identifier": ".ServiceName",
"title": ".ServiceName",
"blueprint": "ecsService",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=\" + .ServiceArn",
"desiredCount": ".DesiredCount",
"launchType": ".LaunchType",
"cluster": ".Cluster | split(\"/\")[-1]",
"schedulingStrategy": ".SchedulingStrategy",
"loadBalancers": ".LoadBalancers",
"securityGroups": ".NetworkConfiguration.AwsvpcConfiguration.SecurityGroups",
"subnets": ".NetworkConfiguration.AwsvpcConfiguration.Subnets",
"taskDefinition": ".TaskDefinition | split(\"/\")[-1]",
"iamRole": ".Role | if . == null then null else \"https://console.aws.amazon.com/go/view?arn=\" + . end",
"arn": ".ServiceArn"
},
"relations": {
"ecsCluster": ".Cluster | split(\"/\")[-1]"
}
}
]
}
}
}
]
}
```
3. Update the exporter's `IAM policy`:
**IAM Policy (click to expand)**
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"ecs:DescribeClusters",
"ecs:ListClusters",
"ecs:DescribeServices",
"ecs:ListServices"
],
"Resource": "*"
}
]
}
```
4. Optional: Create an event rule to trigger automatic syncing of changes in ECS clusters and ECS services.
You may use the following CloudFormation Template:
**Event Rule CloudFormation Template (click to expand)**
```
AWSTemplateFormatVersion: 2010-09-09
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: ^[a-zA-Z][-a-zA-Z0-9]*$
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.ecs
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- ecs.amazonaws.com
eventName:
- prefix: CreateCluster
- prefix: DeleteCluster
- prefix: UpdateCluster
- prefix: UpdateClusterSettings
- prefix: PutClusterCapacityProviders
- prefix: TagResource
- prefix: UntagResource
Name: port-aws-exporter-sync-ecs-cluster-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
clusterName: $.detail.responseElements.cluster.clusterName
eventName: $.detail.eventName
resourceArn: $.detail.requestParameters.resourceArn
InputTemplate: |-
{
"resource_type": "AWS::ECS::Cluster",
"region": "\"\"",
"identifier": "\"\" | if test(\"TagResource|UntagResource[^a-zA-Z]*$\") then \"\" | split(\"/\")[-1] else \"\" end",
"action": "if \"\" | test(\"DeleteCluster[^a-zA-Z]*$\") then \"delete\" else \"upsert\" end"
}
EventRule1:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
detail-type:
- AWS API Call via CloudTrail
source:
- aws.ecs
detail:
eventSource:
- ecs.amazonaws.com
eventName:
- prefix: CreateService
- prefix: UpdateService
- prefix: DeleteService
Name: port-aws-exporter-sync-ecs-service-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
clusterArn: $.detail.responseElements.service.clusterArn
eventName: $.detail.eventName
serviceArn: $.detail.responseElements.service.serviceArn
serviceName: $.detail.responseElements.service.serviceName
InputTemplate: >-
{
"resource_type": "AWS::ECS::Service",
"region": "\"\"",
"identifier": "if \"\" | startswith(\"Delete\") then \"\" else \"|\" end",
"action": "if \"\" | startswith(\"Delete\") then \"delete\" else \"upsert\" end"
}
```
Done! soon, you will be able to see any `ECS clusters` and `ECS services`.
## App Runner services[](#app-runner-services "Direct link to App Runner services")
In this step-by-step example, you will export your `App Runner services` to Port.
1. Create the following Port blueprint:
* **App Runner** - will represent App Runner services from the AWS account.
You may use the following definition:
**App Runner blueprint (click to expand)**
Create in Port
```
{
"identifier": "apprunner",
"description": "This blueprint represents an AWS App Runner service in our software catalog",
"title": "AppRunner",
"icon": "Service",
"schema": {
"properties": {
"link": {
"type": "string",
"format": "url",
"title": "Link"
},
"status": {
"type": "string",
"enum": [
"CREATE_FAILED",
"RUNNING",
"DELETED",
"DELETE_FAILED",
"PAUSED",
"OPERATION_IN_PROGRESS"
],
"enumColors": {
"CREATE_FAILED": "red",
"RUNNING": "green",
"DELETED": "red",
"DELETE_FAILED": "red",
"PAUSED": "yellow",
"OPERATION_IN_PROGRESS": "blue"
},
"title": "Status"
},
"memory": {
"type": "number",
"title": "Memory"
},
"cpu": {
"type": "number",
"title": "CPU"
},
"serviceUrl": {
"type": "string",
"format": "url",
"title": "Service URL"
},
"egressType": {
"type": "string",
"enum": ["DEFAULT", "VPC"],
"title": "Egress Type"
},
"isPubliclyAccessible": {
"type": "boolean",
"title": "Is Publicly Accessible"
},
"observabilityEnabled": {
"type": "boolean",
"title": "Observability Enabled"
},
"autoDeploymentsEnabled": {
"type": "boolean",
"title": "Auto Deployments Enabled"
},
"healthCheckConfiguration": {
"type": "object",
"title": "Health Check Configuration"
},
"imageConfiguration": {
"type": "object",
"title": "Image Configuration"
},
"imageIdentifier": {
"type": "string",
"title": "Image Identifier"
},
"iamRole": {
"type": "string",
"format": "url",
"title": "IAM Role",
"icon": "Unlock"
},
"arn": {
"type": "string",
"title": "ARN"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {}
}
```
2. Upload the `config.json` file to the exporter's S3 bucket:
**Port AWS exporter config.json (click to expand)**
```
{
"resources": [
{
"kind": "AWS::AppRunner::Service",
"port": {
"entity": {
"mappings": [
{
"identifier": ".ServiceId",
"title": ".ServiceName",
"blueprint": "apprunner",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=\" + .ServiceArn",
"status": ".Status",
"memory": ".InstanceConfiguration.Memory",
"cpu": ".InstanceConfiguration.Cpu",
"egressType": ".NetworkConfiguration.EgressConfiguration.EgressType",
"isPubliclyAccessible": ".NetworkConfiguration.IngressConfiguration.IsPubliclyAccessible",
"observabilityEnabled": ".ObservabilityConfiguration.ObservabilityEnabled",
"autoDeploymentsEnabled": ".SourceConfiguration.AutoDeploymentsEnabled",
"healthCheckConfiguration": ".HealthCheckConfiguration",
"imageConfiguration": ".SourceConfiguration.ImageRepository.ImageConfiguration",
"imageIdentifier": ".SourceConfiguration.ImageRepository.ImageIdentifier",
"serviceUrl": "\"https://\" + .ServiceUrl",
"iamRole": ".InstanceConfiguration.InstanceRoleArn | if . == null then null else \"https://console.aws.amazon.com/go/view?arn=\" + . end",
"arn": ".ServiceArn"
}
}
]
}
}
}
]
}
```
3. Update the exporter's `IAM policy`:
**IAM Policy (click to expand)**
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": ["apprunner:DescribeService", "apprunner:ListServices"],
"Resource": "*"
}
]
}
```
4. Optional: Create an event rule to trigger automatic syncing of changes in App Runner services.
You may use the following CloudFormation Template:
**Event Rule CloudFormation Template (click to expand)**
```
AWSTemplateFormatVersion: 2010-09-09
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: ^[a-zA-Z][-a-zA-Z0-9]*$
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
detail-type:
- AppRunner Service Operation Status Change
source:
- aws.apprunner
Name: port-aws-exporter-sync-apprunner-events
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
operationStatus: $.detail.operationStatus
region: $.region
resource: $.resources[0]
serviceId: $.detail.serviceId
InputTemplate: >-
{
"resource_type": "AWS::AppRunner::Service",
"region": "\"\"",
"identifier": "if \"\" == \"DeleteServiceCompletedSuccessfully\" then \"\" else \"\" end",
"action": "if \"\" == \"DeleteServiceCompletedSuccessfully\" then \"delete\" else \"upsert\" end"
}
```
Done! soon, you will be able to see any `App Runner services`.
## Lambda functions [](#lambda-functions--lambda- "Direct link to Lambda functions ")
In this step-by-step example, you will export your `Lambda functions` to Port.
1. Create the following Port blueprint:
* **Lambda** - will represent Lambda functions from the AWS account.
You may use the following definition:
**Lambda blueprint (click to expand)**
Create in Port
```
{
"identifier": "lambda",
"description": "This blueprint represents an AWS Lambda function in our software catalog",
"title": "Lambda",
"icon": "Lambda",
"schema": {
"properties": {
"link": {
"type": "string",
"format": "url",
"title": "Link"
},
"description": {
"type": "string",
"title": "Description"
},
"memorySize": {
"type": "number",
"title": "Memory Size"
},
"ephemeralStorageSize": {
"type": "number",
"title": "Ephemeral Storage Size"
},
"timeout": {
"type": "number",
"title": "Timeout"
},
"runtime": {
"type": "string",
"title": "Runtime"
},
"packageType": {
"type": "string",
"enum": ["Image", "Zip"],
"title": "Package Type"
},
"environment": {
"type": "object",
"title": "Environment"
},
"architectures": {
"type": "array",
"items": {
"type": "string",
"enum": ["x86_64", "arm64"]
},
"title": "Architectures"
},
"layers": {
"type": "array",
"title": "Layers"
},
"tags": {
"type": "array",
"title": "Tags"
},
"iamRole": {
"type": "string",
"format": "url",
"title": "IAM Role",
"icon": "Unlock"
},
"arn": {
"type": "string",
"title": "ARN"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
2. Upload the `config.json` file to the exporter's S3 bucket:
**Port AWS exporter config.json (click to expand)**
```
{
"resources": [
{
"kind": "AWS::Lambda::Function",
"port": {
"entity": {
"mappings": [
{
"identifier": ".FunctionName",
"title": ".FunctionName",
"blueprint": "lambda",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=\" + .Arn",
"description": ".Description",
"memorySize": ".MemorySize",
"ephemeralStorageSize": ".EphemeralStorage.Size",
"timeout": ".Timeout",
"runtime": ".Runtime",
"packageType": ".PackageType",
"environment": ".Environment",
"architectures": ".Architectures",
"layers": ".Layers",
"tags": ".Tags",
"iamRole": "\"https://console.aws.amazon.com/go/view?arn=\" + .Role",
"arn": ".Arn"
}
}
]
}
}
}
]
}
```
3. Update the exporter's `IAM policy`:
**IAM Policy (click to expand)**
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"lambda:ListFunctions",
"lambda:GetFunction",
"lambda:GetFunctionCodeSigningConfig"
],
"Resource": "*"
}
]
}
```
4. Optional: Create an event rule to trigger automatic syncing of changes in Lambda functions.
You may use the following CloudFormation Template:
**Event Rule CloudFormation Template (click to expand)**
```
AWSTemplateFormatVersion: '2010-09-09'
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: ^[a-zA-Z][-a-zA-Z0-9]*$
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
detail-type:
- AWS API Call via CloudTrail
source:
- aws.lambda
detail:
eventSource:
- lambda.amazonaws.com
eventName:
- prefix: CreateFunction
- prefix: UpdateFunctionConfiguration
- prefix: TagResource
- prefix: UntagResource
- prefix: DeleteFunction
Name: port-aws-exporter-sync-lambda-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestFunctionName: $.detail.requestParameters.functionName
requestResource: $.detail.requestParameters.resource
responseFunctionName: $.detail.responseElements.functionName
InputTemplate: |-
{
"resource_type": "AWS::Lambda::Function",
"region": "\"\"",
"identifier": "if \"\" != \"\" then \"\" elif \"\" != \"\" then \"\" | split(\":\")[-1] else \"\" end",
"action": "if \"\" | test(\"DeleteFunction[^a-zA-Z]*$\") then \"delete\" else \"upsert\" end"
}
```
Done! soon, you will be able to see any `Lambda functions`.
## SNS topics and SQS queues[](#sns-topics-and-sqs-queues "Direct link to SNS topics and SQS queues")
In this step-by-step example, you will export your `SNS topics` and `SQS queues` to Port.
1. Create the following Port blueprints:
* **SNS** - will represent SNS topics from the AWS account.
* **SQS** - will represent SQS queues from the AWS account.
You may use the following definitions:
**SQS blueprint (click to expand)**
Create in Port
```
{
"identifier": "sqs",
"description": "This blueprint represents an AWS SQS service in our software catalog",
"title": "SQS",
"icon": "AWS",
"schema": {
"properties": {
"link": {
"type": "string",
"format": "url",
"title": "Link"
},
"fifoQueue": {
"type": "boolean",
"title": "Fifo Queue"
},
"visibilityTimeout": {
"type": "number",
"title": "Visibility Timeout"
},
"messageRetentionPeriod": {
"type": "number",
"title": "Message Retention Period"
},
"maximumMessageSize": {
"type": "number",
"title": "Maximum Message Size"
},
"receiveMessageWaitTimeSeconds": {
"type": "number",
"title": "Receive Message Wait Time Seconds"
},
"delaySeconds": {
"type": "number",
"title": "Delay Seconds"
},
"tags": {
"type": "array",
"title": "Tags"
},
"arn": {
"type": "string",
"title": "ARN"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
**SNS blueprint (click to expand)**
Create in Port
```
{
"identifier": "sns",
"description": "This blueprint represents an AWS SNS topic in our software catalog",
"title": "SNS",
"icon": "SNS",
"schema": {
"properties": {
"link": {
"type": "string",
"format": "url",
"title": "Link"
},
"fifoTopic": {
"type": "boolean",
"title": "Fifo Topic"
},
"subscriptions": {
"type": "array",
"title": "Subscriptions"
},
"tags": {
"type": "array",
"title": "Tags"
},
"arn": {
"type": "string",
"title": "ARN"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {
"sqs": {
"target": "sqs",
"required": false,
"many": true
}
}
}
```
2. Upload the `config.json` file to the exporter's S3 bucket:
**Port AWS exporter config.json (click to expand)**
```
{
"resources": [
{
"kind": "AWS::SQS::Queue",
"port": {
"entity": {
"mappings": [
{
"identifier": ".QueueName",
"title": ".QueueName",
"blueprint": "sqs",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=\" + .Arn",
"fifoQueue": ".FifoQueue // false",
"visibilityTimeout": ".VisibilityTimeout",
"messageRetentionPeriod": ".MessageRetentionPeriod",
"maximumMessageSize": ".MaximumMessageSize",
"receiveMessageWaitTimeSeconds": ".ReceiveMessageWaitTimeSeconds",
"delaySeconds": ".DelaySeconds",
"tags": ".Tags",
"arn": ".Arn"
}
}
]
}
}
},
{
"kind": "AWS::SNS::Topic",
"port": {
"entity": {
"mappings": [
{
"identifier": ".TopicName",
"title": ".TopicName",
"blueprint": "sns",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=\" + .TopicArn",
"fifoTopic": ".FifoTopic // false",
"subscriptions": ".Subscription",
"tags": ".Tags",
"arn": ".TopicArn"
},
"relations": {
"sqs": ".Subscription // [] | map(select(.Protocol == \"sqs\") | .Endpoint | split(\":\")[-1])"
}
}
]
}
}
}
]
}
```
3. Update the exporter's `IAM policy`:
**IAM Policy (click to expand)**
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"sqs:GetQueueAttributes",
"sqs:ListQueueTags",
"sqs:ListQueues",
"sns:GetDataProtectionPolicy",
"sns:GetTopicAttributes",
"sns:ListSubscriptionsByTopic",
"sns:ListTagsForResource",
"sns:ListTopics"
],
"Resource": "*"
}
]
}
```
4. Optional: Create an event rule to trigger automatic syncing of changes in SNS topics and SNS queues.
You may use the following CloudFormation Template:
**Event Rule CloudFormation Template (click to expand)**
```
AWSTemplateFormatVersion: 2010-09-09
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: ^[a-zA-Z][-a-zA-Z0-9]*$
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.sns
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- sns.amazonaws.com
eventName:
- prefix: CreateTopic
- prefix: Subscribe
- prefix: Unsubscribe
- prefix: TagResource
- prefix: UntagResource
- prefix: DeleteTopic
Name: port-aws-exporter-sync-sns-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestResourceArn: $.detail.requestParameters.resourceArn
requestSubscriptionArn: $.detail.requestParameters.subscriptionArn
requestTopicArn: $.detail.requestParameters.topicArn
responseTopicArn: $.detail.responseElements.topicArn
InputTemplate: |-
{
"resource_type": "AWS::SNS::Topic",
"region": "\"\"",
"identifier": "\"\" | if test(\"CreateTopic[^a-zA-Z]*$\") then \"\" elif test(\"Unsubscribe[^a-zA-Z]*$\") then \"\"[:\"\" | rindex(\":\")] elif test(\"TagResource|UntagResource[^a-zA-Z]*$\") then \"\" elif test(\"DeleteTopic[^a-zA-Z]*$\") then \"\" | split(\":\")[-1] else \"\" end",
"action": "if \"\" | test(\"DeleteTopic[^a-zA-Z]*$\") then \"delete\" else \"upsert\" end"
}
EventRule1:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.sqs
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- sqs.amazonaws.com
eventName:
- prefix: CreateQueue
- prefix: SetQueueAttributes
- prefix: TagQueue
- prefix: UntagQueue
- prefix: DeleteQueue
Name: port-aws-exporter-sync-sqs-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestQueueUrl: $.detail.requestParameters.queueUrl
responseQueueUrl: $.detail.responseElements.queueUrl
InputTemplate: |-
{
"resource_type": "AWS::SQS::Queue",
"region": "\"\"",
"identifier": "\"\" | if test(\"CreateQueue[^a-zA-Z]*$\") then \"\" elif test(\"DeleteQueue[^a-zA-Z]*$\") then \"\" | split(\"/\")[-1] else \"\" end",
"action": "if \"\" | test(\"DeleteQueue[^a-zA-Z]*$\") then \"delete\" else \"upsert\" end"
}
```
Done! soon, you will be able to see any `SNS queue` and its `SQS queues` subscriptions.
## S3 buckets[](#s3-buckets "Direct link to S3 buckets")
In this step-by-step example, you will export your `S3 buckets` to Port.
1. Create the following Port blueprint:
* **S3** - will represent S3 buckets from the AWS account.
You may use the following definition:
**S3 blueprint (click to expand)**
Create in Port
```
{
"identifier": "s3",
"description": "This blueprint represents an AWS S3 bucket in our software catalog",
"title": "S3",
"icon": "Bucket",
"schema": {
"properties": {
"link": {
"type": "string",
"format": "url",
"title": "Link"
},
"regionalDomainName": {
"type": "string",
"title": "Regional Domain Name"
},
"versioningStatus": {
"type": "string",
"title": "Versioning Status",
"enum": ["Enabled", "Suspended"]
},
"encryption": {
"type": "array",
"title": "Encryption"
},
"lifecycleRules": {
"type": "array",
"title": "Lifecycle Rules"
},
"publicAccess": {
"type": "object",
"title": "Public Access"
},
"tags": {
"type": "array",
"title": "Tags"
},
"arn": {
"type": "string",
"title": "ARN"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
2. Upload the `config.json` file to the exporter's S3 bucket:
**Port AWS exporter config.json (click to expand)**
```
{
"resources": [
{
"kind": "AWS::S3::Bucket",
"port": {
"entity": {
"mappings": [
{
"identifier": ".BucketName",
"title": ".BucketName",
"blueprint": "s3",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=\" + .Arn",
"regionalDomainName": ".RegionalDomainName",
"versioningStatus": ".VersioningConfiguration.Status",
"encryption": ".BucketEncryption.ServerSideEncryptionConfiguration",
"lifecycleRules": ".LifecycleConfiguration.Rules",
"publicAccess": ".PublicAccessBlockConfiguration",
"tags": ".Tags",
"arn": ".Arn"
}
}
]
}
}
}
]
}
```
3. Update the exporter's `IAM policy`:
**IAM Policy (click to expand)**
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"S3:GetBucketWebsite",
"s3:GetAccelerateConfiguration",
"s3:GetAnalyticsConfiguration",
"s3:GetBucketCORS",
"s3:GetBucketLogging",
"s3:GetBucketNotification",
"s3:GetBucketObjectLockConfiguration",
"s3:GetBucketOwnershipControls",
"s3:GetBucketPublicAccessBlock",
"s3:GetBucketTagging",
"s3:GetBucketVersioning",
"s3:GetEncryptionConfiguration",
"s3:GetIntelligentTieringConfiguration",
"s3:GetInventoryConfiguration",
"s3:GetLifecycleConfiguration",
"s3:GetMetricsConfiguration",
"s3:GetReplicationConfiguration",
"s3:ListAllMyBuckets",
"s3:ListBucket"
],
"Resource": "*"
}
]
}
```
4. Optional: Create an event rule to trigger automatic syncing of changes in S3 buckets.
You may use the following CloudFormation Template:
**Event Rule CloudFormation Template (click to expand)**
```
AWSTemplateFormatVersion: '2010-09-09'
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: ^[a-zA-Z][-a-zA-Z0-9]*$
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.s3
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- s3.amazonaws.com
eventName:
- prefix: CreateBucket
- prefix: PutBucket
- prefix: DeleteBucket
Name: port-aws-exporter-sync-s3-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestBucketName: $.detail.requestParameters.bucketName
InputTemplate: |-
{
"resource_type": "AWS::S3::Bucket",
"region": "\"\"",
"identifier": "\"\"",
"action": "if \"\" | test(\"DeleteBucket[^a-zA-Z]*$\") then \"delete\" else \"upsert\" end"
}
```
Done! soon, you will be able to see any `S3 buckets`.
## API Gateway APIs[](#api-gateway-apis "Direct link to API Gateway APIs")
In this step-by-step example, you will export your `API Gateway APIs` to Port.
1. Create the following Port blueprint:
* **API Gateway** - will represent API Gateway APIs from the AWS account.
You may use the following definition:
**API Gateway blueprint (click to expand)**
Create in Port
```
{
"identifier": "apigateway",
"description": "This blueprint represents an AWS API Gateway API in our software catalog",
"title": "API Gateway",
"icon": "RestApi",
"schema": {
"properties": {
"link": {
"type": "string",
"format": "url",
"title": "Link"
},
"description": {
"type": "string",
"title": "Description"
},
"protocolType": {
"type": "string",
"title": "Protocol Type",
"enum": ["HTTP", "WEBSOCKET", "REST"]
},
"apiKeySourceType": {
"type": "string",
"title": "Api Key Source Type",
"enum": ["HEADER", "AUTHORIZER"]
},
"routeSelection": {
"type": "string",
"title": "Route Selection"
},
"apiEndpoint": {
"type": "string",
"title": "Api Endpoint"
},
"disableExecuteApi": {
"type": "boolean",
"title": "Disable Execute Api"
},
"cors": {
"type": "object",
"title": "Cors Configuration"
},
"endpointTypes": {
"type": "array",
"title": "Endpoint Types",
"items": {
"type": "string",
"enum": ["EDGE", "REGIONAL", "PRIVATE"]
}
},
"tags": {
"type": "array",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
2. Upload the `config.json` file to the exporter's S3 bucket:
**Port AWS exporter config.json (click to expand)**
```
{
"resources": [
{
"kind": "AWS::ApiGateway::RestApi",
"port": {
"entity": {
"mappings": [
{
"identifier": ".RestApiId",
"title": ".Name",
"blueprint": "apigateway",
"properties": {
"description": ".Description",
"protocolType": "\"REST\"",
"apiKeySourceType": ".ApiKeySourceType",
"disableExecuteApi": ".DisableExecuteApiEndpoint",
"endpointTypes": ".EndpointConfiguration.Types",
"tags": ".Tags"
}
}
]
}
}
},
{
"kind": "AWS::ApiGatewayV2::Api",
"port": {
"entity": {
"mappings": [
{
"identifier": ".ApiId",
"title": ".Name",
"blueprint": "apigateway",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=arn:aws:apigateway:\" + (.ApiEndpoint | split(\".\")[-3]) + \"::/apis/\" + .ApiId",
"description": ".Description",
"protocolType": ".ProtocolType",
"routeSelection": ".RouteSelectionExpression",
"apiEndpoint": ".ApiEndpoint",
"disableExecuteApi": ".DisableExecuteApiEndpoint",
"cors": ".CorsConfiguration",
"tags": ".Tags | to_entries"
}
}
]
}
}
}
]
}
```
3. Update the exporter's `IAM policy`:
**IAM Policy (click to expand)**
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": ["apigateway:GET"],
"Resource": "*"
}
]
}
```
4. Optional: Create an event rule to trigger automatic syncing of changes in API Gateway APIs.
You may use the following CloudFormation Template:
**Event Rule CloudFormation Template (click to expand)**
```
AWSTemplateFormatVersion: '2010-09-09'
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: ^[a-zA-Z][-a-zA-Z0-9]*$
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.apigateway
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- apigateway.amazonaws.com
eventName:
- prefix: CreateRestApi
- prefix: ImportRestApi
- prefix: PutRestApi
- prefix: UpdateRestApi
- prefix: DeleteRestApi
Name: port-aws-exporter-sync-apigateway-restapi-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestRestApiId: $.detail.requestParameters.restApiId
responseRestApiId: $.detail.responseElements.id
InputTemplate: |-
{
"resource_type": "AWS::ApiGateway::RestApi",
"region": "\"\"",
"identifier": "if \"\" != \"\" then \"\" else \"\" end",
"action": "if \"\" | test(\"DeleteRestApi[^a-zA-Z]*$\") then \"delete\" else \"upsert\" end"
}
EventRule1:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.apigateway
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- apigateway.amazonaws.com
eventName:
- prefix: CreateApi
- prefix: ImportApi
- prefix: ReimportApi
- prefix: UpdateApi
- prefix: DeleteApi
Name: port-aws-exporter-sync-apigateway-api-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestApiId: $.detail.requestParameters.apiId
responseApiId: $.detail.responseElements.apiId
InputTemplate: |-
{
"resource_type": "AWS::ApiGatewayV2::Api",
"region": "\"\"",
"identifier": "if \"\" != \"\" then \"\" else \"\" end",
"action": "if \"\" | test(\"DeleteApi[^a-zA-Z]*$\") then \"delete\" else \"upsert\" end"
}
```
Done! soon, you will be able to see any `API Gateway APIs`.
## Cloudfront distributions[](#cloudfront-distributions "Direct link to Cloudfront distributions")
In this step-by-step example, you will export your `Cloudfront distributions` to Port.
Important
Cloudfront is a global (not regional) service in AWS, that its events are recorded by AWS CloudTrail in the `us-east-1` region. Therefore, in order to automatically sync changes in Cloudfront distributions with an event rule (step 4 of this example), you need to choose one of the following methods:
1. Deploy the Port AWS exporter and the event rule in the `us-east-1` region.
2. Create a trail that will capture global service events in the same region that you've deployed the Port AWS exporter.
For more information, read [here](https://docs.aws.amazon.com/awscloudtrail/latest/userguide/cloudtrail-concepts.html#cloudtrail-concepts-global-service-events).
1. Create the following Port blueprint:
* **Cloudfront** - will represent Cloudfront distributions from the AWS account.
You may use the following definition:
**Cloudfront blueprint (click to expand)**
Create in Port
```
{
"identifier": "cloudfront",
"description": "This blueprint represents an AWS Cloudfront distribution in our software catalog",
"title": "Cloudfront",
"icon": "Cloud",
"schema": {
"properties": {
"link": {
"type": "string",
"title": "Link",
"format": "url"
},
"description": {
"type": "string",
"title": "Description"
},
"staging": {
"type": "boolean",
"title": "Staging"
},
"enabled": {
"type": "boolean",
"title": "Enabled"
},
"httpVersion": {
"type": "string",
"title": "Http Version",
"enum": ["http1.1", "http2", "http2and3", "http3"]
},
"priceClass": {
"type": "string",
"title": "Price Class",
"enum": ["PriceClass_100", "PriceClass_200", "PriceClass_All"]
},
"domainName": {
"type": "string",
"title": "Domain Name"
},
"aliases": {
"type": "array",
"title": "Aliases"
},
"origins": {
"type": "array",
"title": "Origins"
},
"viewerCertificate": {
"type": "object",
"title": "Viewer Certificate"
},
"defaultCacheBehavior": {
"type": "object",
"title": "Default Cache Behavior"
},
"tags": {
"type": "array",
"title": "Tags"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
2. Upload the `config.json` file to the exporter's S3 bucket:
**Port AWS exporter config.json (click to expand)**
```
{
"resources": [
{
"kind": "AWS::CloudFront::Distribution",
"port": {
"entity": {
"mappings": [
{
"identifier": ".Id",
"title": ".Id",
"blueprint": "cloudfront",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=arn:aws:cloudfront:::distribution/\" + .Id",
"description": ".DistributionConfig.Comment",
"staging": ".DistributionConfig.Staging",
"enabled": ".DistributionConfig.Enabled",
"httpVersion": ".DistributionConfig.HttpVersion",
"priceClass": ".DistributionConfig.PriceClass",
"domainName": ".DomainName",
"aliases": ".DistributionConfig.Aliases",
"origins": ".DistributionConfig.Origins",
"viewerCertificate": ".DistributionConfig.ViewerCertificate",
"defaultCacheBehavior": ".DistributionConfig.DefaultCacheBehavior",
"tags": ".Tags"
}
}
]
}
}
}
]
}
```
3. Update the exporter's `IAM policy`:
**IAM Policy (click to expand)**
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"cloudfront:GetDistribution*",
"cloudfront:ListDistributions*"
],
"Resource": "*"
}
]
}
```
4. Optional: Create an event rule to trigger automatic syncing of changes in Cloudfront distributions.
You may use the following CloudFormation Template:
**Event Rule CloudFormation Template (click to expand)**
```
AWSTemplateFormatVersion: '2010-09-09'
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: ^[a-zA-Z][-a-zA-Z0-9]*$
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.cloudfront
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- cloudfront.amazonaws.com
eventName:
- prefix: CreateDistribution
- prefix: CopyDistribution
- prefix: UpdateDistribution
- prefix: DeleteDistribution
Name: port-aws-exporter-sync-cloudfront-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestDistributionId: $.detail.requestParameters.id
responseDistributionId: $.detail.responseElements.distribution.id
InputTemplate: |-
{
"resource_type": "AWS::CloudFront::Distribution",
"region": "\"\"",
"identifier": "if \"\" != \"\" then \"\" else \"\" end",
"action": "if \"\" | test(\"DeleteDistribution[^a-zA-Z]*$\") then \"delete\" else \"upsert\" end"
}
```
Done! soon, you will be able to see any `Cloudfront distributions`.
## DynamoDB tables[](#dynamodb-tables "Direct link to DynamoDB tables")
In this step-by-step example, you will export your `DynamoDB tables` to Port.
1. Create the following Port blueprint:
* **DynamoDB** - will represent DynamoDB tables from the AWS account.
You may use the following definition:
**DynamoDB blueprint (click to expand)**
Create in Port
```
{
"identifier": "dynamodb",
"description": "This blueprint represents an AWS DynamoDB table in our software catalog",
"title": "DynamoDB",
"icon": "SQL",
"schema": {
"properties": {
"link": {
"type": "string",
"title": "Link",
"format": "url"
},
"writeCapacityUnits": {
"type": "number",
"title": "Write Capacity Units"
},
"readCapacityUnits": {
"type": "number",
"title": "Read Capacity Units"
},
"deletionProtectionEnabled": {
"type": "boolean",
"title": "Deletion Protection Enabled"
},
"pointInTimeRecoveryEnabled": {
"type": "boolean",
"title": "Point In Time Recovery Enabled"
},
"ttlEnabled": {
"type": "boolean",
"title": "TTL Enabled"
},
"ttlAttributeName": {
"type": "string",
"title": "TTL Attribute Name"
},
"billingMode": {
"type": "string",
"title": "Billing Mode",
"enum": ["PAY_PER_REQUEST", "PROVISIONED"]
},
"attributeDefinitions": {
"type": "array",
"title": "Attribute Definitions"
},
"keySchema": {
"type": "array",
"title": "Key Schema"
},
"tags": {
"type": "array",
"title": "Tags"
},
"arn": {
"type": "string",
"title": "ARN"
}
},
"required": []
},
"mirrorProperties": {},
"calculationProperties": {},
"relations": {}
}
```
2. Upload the `config.json` file to the exporter's S3 bucket:
**Port AWS exporter config.json (click to expand)**
```
{
"resources": [
{
"kind": "AWS::DynamoDB::Table",
"port": {
"entity": {
"mappings": [
{
"identifier": ".TableName",
"title": ".TableName",
"blueprint": "dynamodb",
"properties": {
"link": "\"https://console.aws.amazon.com/go/view?arn=\" + .Arn",
"writeCapacityUnits": ".ProvisionedThroughput.WriteCapacityUnits",
"readCapacityUnits": ".ProvisionedThroughput.ReadCapacityUnits",
"deletionProtectionEnabled": ".DeletionProtectionEnabled",
"pointInTimeRecoveryEnabled": ".PointInTimeRecoverySpecification.PointInTimeRecoveryEnabled",
"ttlEnabled": ".TimeToLiveSpecification.Enabled",
"ttlAttributeName": ".TimeToLiveSpecification.AttributeName",
"billingMode": ".BillingMode",
"attributeDefinitions": ".AttributeDefinitions",
"keySchema": ".KeySchema",
"tags": ".Tags",
"arn": ".Arn"
}
}
]
}
}
}
]
}
```
3. Update the exporter's `IAM policy`:
**IAM Policy (click to expand)**
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"dynamodb:DescribeContinuousBackups",
"dynamodb:DescribeContributorInsights",
"dynamodb:DescribeTable",
"dynamodb:DescribeTimeToLive",
"dynamodb:ListTables",
"dynamodb:ListTagsOfResource"
],
"Resource": "*"
}
]
}
```
4. Optional: Create an event rule to trigger automatic syncing of changes in DynamoDB tables.
You may use the following CloudFormation Template:
**Event Rule CloudFormation Template (click to expand)**
```
AWSTemplateFormatVersion: '2010-09-09'
Description: The template used to create event rules for the Port AWS exporter.
Parameters:
PortAWSExporterStackName:
Description: Name of the Port AWS exporter stack name
Type: String
MinLength: 1
MaxLength: 255
AllowedPattern: ^[a-zA-Z][-a-zA-Z0-9]*$
Default: serverlessrepo-port-aws-exporter
Resources:
EventRule0:
Type: AWS::Events::Rule
Properties:
EventBusName: default
EventPattern:
source:
- aws.dynamodb
detail-type:
- AWS API Call via CloudTrail
detail:
eventSource:
- dynamodb.amazonaws.com
eventName:
- prefix: CreateTable
- prefix: UpdateTable
- prefix: UpdateTimeToLive
- prefix: UpdateContinuousBackups
- prefix: TagResource
- prefix: UntagResource
- prefix: DeleteTable
Name: port-aws-exporter-sync-dynamodb-trails
State: ENABLED
Targets:
- Id: PortAWSExporterEventsQueue
Arn:
Fn::ImportValue:
Fn::Sub: ${PortAWSExporterStackName}-EventsQueueARN
InputTransformer:
InputPathsMap:
awsRegion: $.detail.awsRegion
eventName: $.detail.eventName
requestResourceArn: $.detail.requestParameters.resourceArn
requestTableName: $.detail.requestParameters.tableName
InputTemplate: |-
{
"resource_type": "AWS::DynamoDB::Table",
"region": "\"