Kafka


Port's Kafka integration allows you to model Kafka resources in your software catalog and ingest data into them.

Setup
Choose one of the following installation methods: Not sure which method is right for your use case? Check the available installation methods.
The prerequisites required for installation are listed below.
-
Go to the Kafka Connectors page in your portal.
-
Select the
Self-hostedmethod. -
A
helmcommand will be displayed, with default values already filled out (e.g. your Port client ID, client secret, etc). Copy the command, replace the placeholders with your values, then run it in your terminal to install the integration.
Live event support
Currently, live events are not supported for this integration.
Resyncs will be performed periodically (with a configurable interval), or manually triggered by you via Port's UI.
Therefore, real-time events (including GitOps) will not be ingested into Port immediately.
Live events support for this integration is WIP and will be supported in the near future.
The resync interval can be configured using the scheduledResyncInterval parameter. See the optional parameters section below for more details.
Required parameters:
port.clientId- Your Port client id.port.clientSecret- Your Port client secret.port.baseUrl- Your Port API URL -https://api.port.iofor EU,https://api.us.port.iofor US.integration.type- The integration to be installed.integration.eventListener.type- The event listener type. Read more about event listeners.integration.secrets.clusterConfMapping- JSON object mapping Kafka cluster names to their client configurations. Each cluster config should includebootstrap.servers,security.protocol, and authentication details. See Cluster configuration examples for detailed examples.
Optional parameters (click to expand)
scheduledResyncInterval- The number of minutes between each resync. When not set the integration will resync for each event listener resync event. Read more about scheduledResyncInterval.initializePortResources- Default true, When set to true the integration will create default blueprints and the port App config Mapping.sendRawDataExamples- Enable sending raw data examples from the third party API to port for testing and managing the integration mapping. Default is true.
- GitHub
- Jenkins
- Azure DevOps
- GitLab
- Go to the Kafka Connectors page in your portal.
- Under Select your installation method, choose your desired CI/CD platform.
- Copy the workflow and replace the placeholders with your values.
Below are the available parameters and their descriptions.
| Parameter | Description | Required? | Secret?Store this value as a GitHub Actions secret |
|---|---|---|---|
port_client_id | Your Port client ID (How to get the credentials). | ✓ | ✓ |
port_client_secret | Your Port client secret (How to get the credentials). | ✓ | ✓ |
port_base_url | Your Port API URL (https://api.port.io for EU, https://api.us.port.io for US). | ✓ | ✗ |
cluster_conf_mapping | JSON object mapping Kafka cluster names to their client configurations. Each cluster config should include bootstrap.servers, security.protocol, and authentication details. See Cluster configuration examples for detailed examples. | ✓ | ✓ |
initialize_port_resources | Default true. When set to true, the integration will create default blueprints and the Port app config mapping. | ✗ | ✗ |
integration_identifier | The identifier of the integration that will be installed. | ✗ | ✗ |
send_raw_data_examples | Enable sending raw data examples from the third-party API to Port for testing and managing the integration mapping. Default is true. | ✗ | ✗ |
Your Jenkins agent must be able to run Docker commands.
Below are the available parameters and their descriptions.
| Parameter | Description | Required? | Secret?Store this value as a Jenkins credential (Secret Text) |
|---|---|---|---|
OCEAN__ | Your Port client ID (How to get the credentials). | ✓ | ✓ |
OCEAN__ | Your Port client secret (How to get the credentials). | ✓ | ✓ |
OCEAN__ | Your Port API URL (https://api.port.io for EU, https://api.us.port.io for US). | ✓ | ✗ |
OCEAN__ | JSON object mapping Kafka cluster names to their client configurations. Each cluster config should include bootstrap.servers, security.protocol, and authentication details. See Cluster configuration examples for detailed examples. | ✓ | ✓ |
OCEAN__ | Default true. When set to true, the integration will create default blueprints and the Port app config mapping. | ✗ | ✗ |
OCEAN__ | The identifier of the integration that will be installed. | ✗ | ✗ |
OCEAN__ | Enable sending raw data examples from the third-party API to Port for testing and managing the integration mapping. Default is true. | ✗ | ✗ |
Here is an example for a Jenkinsfile pipeline file:Jenkins pipeline (click to expand)
Prerequisites
- Your Azure Devops agent should be able to run docker commands. Learn more about agents here.
- You must have permissions to create and manage Azure DevOps variable groups for storing credentials.
Set up your credentials
- Create a Variable Group: Name it port-ocean-credentials.
- Store the required variables (see the table below).
- Authorize Your Pipeline:
-
Go to "Library" -> "Variable groups."
-
Find port-ocean-credentials and click on it.
-
Select "Pipeline Permissions" and add your pipeline to the authorized list.
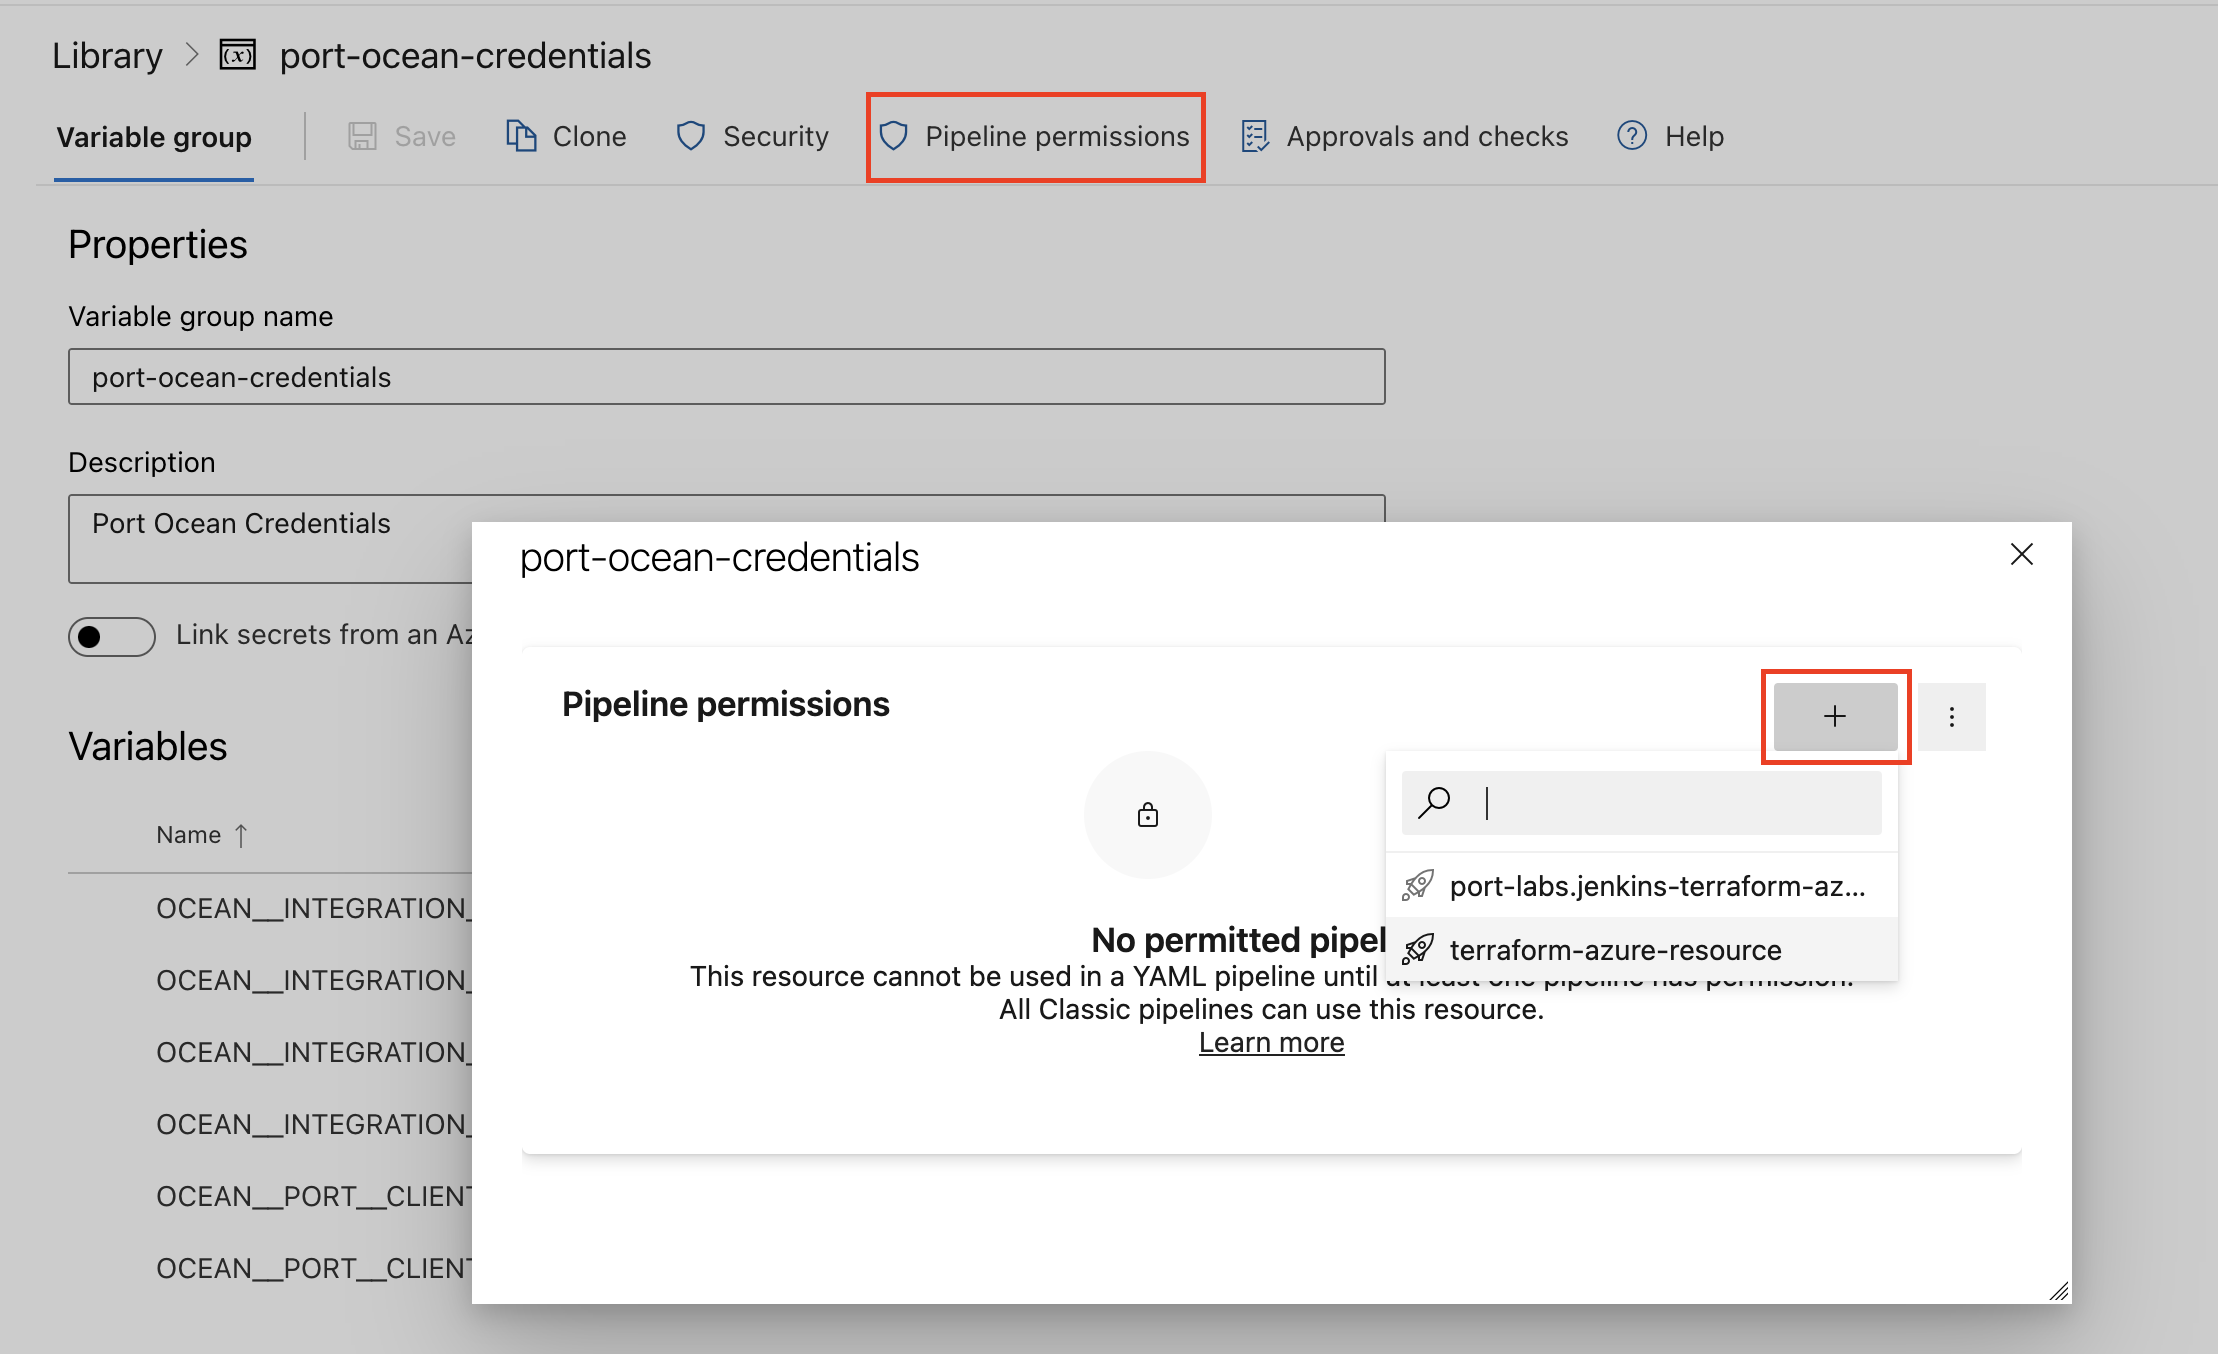
-
Below are the available parameters and their descriptions.
| Parameter | Description | Required? | Secret?Store this value as an Azure DevOps pipeline variable |
|---|---|---|---|
OCEAN__ | Your Port client ID (How to get the credentials). | ✓ | ✓ |
OCEAN__ | Your Port client secret (How to get the credentials). | ✓ | ✓ |
OCEAN__ | Your Port API URL (https://api.port.io for EU, https://api.us.port.io for US). | ✓ | ✗ |
OCEAN__ | JSON object mapping Kafka cluster names to their client configurations. Each cluster config should include bootstrap.servers, security.protocol, and authentication details. See Cluster configuration examples for detailed examples. | ✓ | ✓ |
OCEAN__ | Default true. When set to true, the integration will create default blueprints and the Port app config mapping. | ✗ | ✗ |
OCEAN__ | The identifier of the integration that will be installed. | ✗ | ✗ |
OCEAN__ | Enable sending raw data examples from the third-party API to Port for testing and managing the integration mapping. Default is true. | ✗ | ✗ |
Here is an example for a azure-pipeline.yml pipeline file:Azure pipeline (click to expand)
- Go to the Kafka Connectors page in your portal.
- Under Select your installation method, choose your desired CI/CD platform.
- Copy the workflow and replace the placeholders with your values.
Below are the available parameters and their descriptions.
| Parameter | Description | Required? | Secret?Store this value as a GitLab CI/CD variable |
|---|---|---|---|
OCEAN__ | Your Port client ID (How to get the credentials). | ✓ | ✓ |
OCEAN__ | Your Port client secret (How to get the credentials). | ✓ | ✓ |
OCEAN__ | Your Port API URL (https://api.port.io for EU, https://api.us.port.io for US). | ✓ | ✗ |
OCEAN__ | JSON object mapping Kafka cluster names to their client configurations. Each cluster config should include bootstrap.servers, security.protocol, and authentication details. See Cluster configuration examples for detailed examples. | ✓ | ✓ |
OCEAN__ | Default true. When set to true, the integration will create default blueprints and the Port app config mapping. | ✗ | ✗ |
OCEAN__ | The identifier of the integration that will be installed. | ✗ | ✗ |
OCEAN__ | Enable sending raw data examples from the third-party API to Port for testing and managing the integration mapping. Default is true. | ✗ | ✗ |
For advanced configuration such as proxies or self-signed certificates, see Ocean advanced configuration.
Cluster config mapping examples
The clusterConfMapping parameter is crucial for connecting to your Kafka clusters.
The cluster configuration mapping should be a JSON object with cluster names as keys and Kafka client configurations as values. Each client configuration follows the standard Kafka client properties format.
Below are some examples of how to configure the clusterConfMapping parameter for different Kafka cluster configurations.
Basic SASL_SSL authentication
For clusters with SASL authentication over SSL:
Basic SASL_SSL authentication (click to expand)
- Helm/ArgoCD
- CI/CD Environment Variable
integration:
  secrets:
    clusterConfMapping: |
      {
        "production-cluster": {
          "bootstrap.servers": "broker1:9092,broker2:9092,broker3:9092",
          "security.protocol": "SASL_SSL",
          "sasl.mechanism": "SCRAM-SHA-256",
          "sasl.username": "your-username",
          "sasl.password": "your-password"
        },
        "staging-cluster": {
          "bootstrap.servers": "staging-broker1:9092,staging-broker2:9092",
          "security.protocol": "SASL_SSL",
          "sasl.mechanism": "SCRAM-SHA-256",
          "sasl.username": "staging-username",
          "sasl.password": "staging-password"
        }
      }
export OCEAN__INTEGRATION__CONFIG__CLUSTER_CONF_MAPPING='{
  "production-cluster": {
    "bootstrap.servers": "broker1:9092,broker2:9092,broker3:9092",
    "security.protocol": "SASL_SSL",
    "sasl.mechanism": "SCRAM-SHA-256",
    "sasl.username": "your-username",
    "sasl.password": "your-password"
  },
  "staging-cluster": {
    "bootstrap.servers": "staging-broker1:9092,staging-broker2:9092",
    "security.protocol": "SASL_SSL",
    "sasl.mechanism": "SCRAM-SHA-256",
    "sasl.username": "staging-username",
    "sasl.password": "staging-password"
  }
}'
Plain text authentication
For clusters without SSL encryption:
Plain text authentication (click to expand)
- Helm/ArgoCD
- CI/CD Environment Variable
integration:
  secrets:
    clusterConfMapping: |
      {
        "internal-cluster": {
          "bootstrap.servers": "internal-broker1:9092,internal-broker2:9092",
          "security.protocol": "SASL_PLAINTEXT",
          "sasl.mechanism": "PLAIN",
          "sasl.username": "internal-username",
          "sasl.password": "internal-password"
        }
      }
export OCEAN__INTEGRATION__CONFIG__CLUSTER_CONF_MAPPING='{
  "internal-cluster": {
    "bootstrap.servers": "internal-broker1:9092,internal-broker2:9092",
    "security.protocol": "SASL_PLAINTEXT",
    "sasl.mechanism": "PLAIN",
    "sasl.username": "internal-username",
    "sasl.password": "internal-password"
  }
}'
mTLS authentication
For clusters with mutual TLS authentication:
mTLS authentication (click to expand)
- Helm/ArgoCD
- CI/CD Environment Variable
integration:
  secrets:
    clusterConfMapping: |
      {
        "secure-cluster": {
          "bootstrap.servers": "secure-broker1:9092,secure-broker2:9092",
          "security.protocol": "SSL",
          "ssl.ca.location": "/path/to/ca-cert.pem",
          "ssl.certificate.location": "/path/to/client-cert.pem",
          "ssl.key.location": "/path/to/client-key.pem",
          "ssl.key.password": "key-password"
        }
      }
export OCEAN__INTEGRATION__CONFIG__CLUSTER_CONF_MAPPING='{
  "secure-cluster": {
    "bootstrap.servers": "secure-broker1:9092,secure-broker2:9092",
    "security.protocol": "SSL",
    "ssl.ca.location": "/path/to/ca-cert.pem",
    "ssl.certificate.location": "/path/to/client-cert.pem",
    "ssl.key.location": "/path/to/client-key.pem",
    "ssl.key.password": "key-password"
  }
}'
Confluent cloud configuration
For Confluent Cloud clusters:
Confluent cloud configuration (click to expand)
- Helm/ArgoCD
- CI/CD Environment Variable
integration:
  secrets:
    clusterConfMapping: |
      {
        "confluent-cloud-cluster": {
          "bootstrap.servers": "pkc-abcd85.us-west-2.aws.confluent.cloud:9092",
          "security.protocol": "SASL_SSL",
          "sasl.mechanism": "PLAIN",
          "sasl.username": "your-api-key",
          "sasl.password": "your-api-secret"
        }
      }
export OCEAN__INTEGRATION__CONFIG__CLUSTER_CONF_MAPPING='{
  "confluent-cloud-cluster": {
    "bootstrap.servers": "pkc-abcd85.us-west-2.aws.confluent.cloud:9092",
    "security.protocol": "SASL_SSL",
    "sasl.mechanism": "PLAIN",
    "sasl.username": "your-api-key",
    "sasl.password": "your-api-secret"
  }
}'
Advanced configuration with custom properties
For clusters requiring additional custom properties:
Advanced configuration with custom properties (click to expand)
- Helm/ArgoCD
- CI/CD Environment Variable
integration:
  secrets:
    clusterConfMapping: |
      {
        "advanced-cluster": {
          "bootstrap.servers": "broker1:9092,broker2:9092,broker3:9092",
          "security.protocol": "SASL_SSL",
          "sasl.mechanism": "SCRAM-SHA-512",
          "sasl.username": "advanced-username",
          "sasl.password": "advanced-password",
          "ssl.ca.location": "/path/to/ca-cert.pem",
          "ssl.endpoint.identification.algorithm": "https",
          "request.timeout.ms": 30000,
          "session.timeout.ms": 10000,
          "enable.auto.commit": false
        }
      }
export OCEAN__INTEGRATION__CONFIG__CLUSTER_CONF_MAPPING='{
  "advanced-cluster": {
    "bootstrap.servers": "broker1:9092,broker2:9092,broker3:9092",
    "security.protocol": "SASL_SSL",
    "sasl.mechanism": "SCRAM-SHA-512",
    "sasl.username": "advanced-username",
    "sasl.password": "advanced-password",
    "ssl.ca.location": "/path/to/ca-cert.pem",
    "ssl.endpoint.identification.algorithm": "https",
    "request.timeout.ms": 30000,
    "session.timeout.ms": 10000,
    "enable.auto.commit": false
  }
}'
You can configure multiple clusters in the same mapping by adding additional cluster configurations as shown in the examples above. Each cluster will be processed independently by the integration.
- Store sensitive information like passwords and API keys securely using your platform's secret management system.
- For Kubernetes deployments, use Kubernetes secrets to store the
clusterConfMappingvalue. - For CI/CD pipelines, use environment variable encryption features provided by your CI/CD platform.
Configuration
Port integrations use a YAML mapping block to ingest data from the third-party api into Port.
The mapping makes use of the JQ JSON processor to select, modify, concatenate, transform and perform other operations on existing fields and values from the integration API.
Default mapping configuration
This is the default mapping configuration for this integration:
Default mapping configuration (click to expand)
resources:
- kind: cluster
  selector:
    query: 'true'
  port:
    entity:
      mappings:
        identifier: .name
        title: .name
        blueprint: '"kafkaCluster"'
        properties:
          controllerId: .controller_id
- kind: broker
  selector:
    query: 'true'
  port:
    entity:
      mappings:
        identifier: .cluster_name + "_" + (.id | tostring)
        title: .cluster_name + " " + (.id | tostring)
        blueprint: '"kafkaBroker"'
        properties:
          address: .address
          region: .config."broker.rack"
          version: .config."inter.broker.protocol.version"
          config: .config
        relations:
          cluster: .cluster_name
- kind: topic
  selector:
    query: 'true'
  port:
    entity:
      mappings:
        identifier: .cluster_name + "_" + .name
        title: .cluster_name + " " + .name
        blueprint: '"kafkaTopic"'
        properties:
          replicas: .partitions[0].replicas | length
          partitions: .partitions | length
          compaction: .config."cleanup.policy" | contains("compact")
          retention: .config."cleanup.policy" | contains("delete")
          deleteRetentionTime: .config."delete.retention.ms"
          partitionsMetadata: .partitions
          config: .config
        relations:
          cluster: .cluster_name
          brokers: '[.cluster_name + "_" + (.partitions[].replicas[] | tostring)] | unique'
- kind: consumer_group
  selector:
    query: 'true'
  port:
    entity:
      mappings:
        identifier: .cluster_name + "_" + .group_id
        title: .group_id
        blueprint: '"kafkaConsumerGroup"'
        properties:
          state: .state
          members: '[.members[].client_id]'
          coordinator: .coordinator.id
          partition_assignor: .partition_assignor
          is_simple_consumer_group: .is_simple_consumer_group
          authorized_operations: .authorized_operations
        relations:
          cluster: .cluster_name
Mapping & selectors per resource
Examples of blueprints and the relevant integration configurations:
{
  "identifier": "kafkaCluster",
  "title": "Cluster",
  "icon": "Kafka",
  "schema": {
    "properties": {
      "controllerId": {
        "title": "Controller ID",
        "type": "string"
      }
    }
  }
}
createMissingRelatedEntities: false
deleteDependentEntities: true
resources:
  - kind: cluster
    selector:
      query: "true"
    port:
      entity:
        mappings:
          identifier: .name
          title: .name
          blueprint: '"kafkaCluster"'
          properties:
            controllerId: .controller_id
Monitoring and sync status
To learn more about how to monitor and check the sync status of your integration, see the relevant documentation.